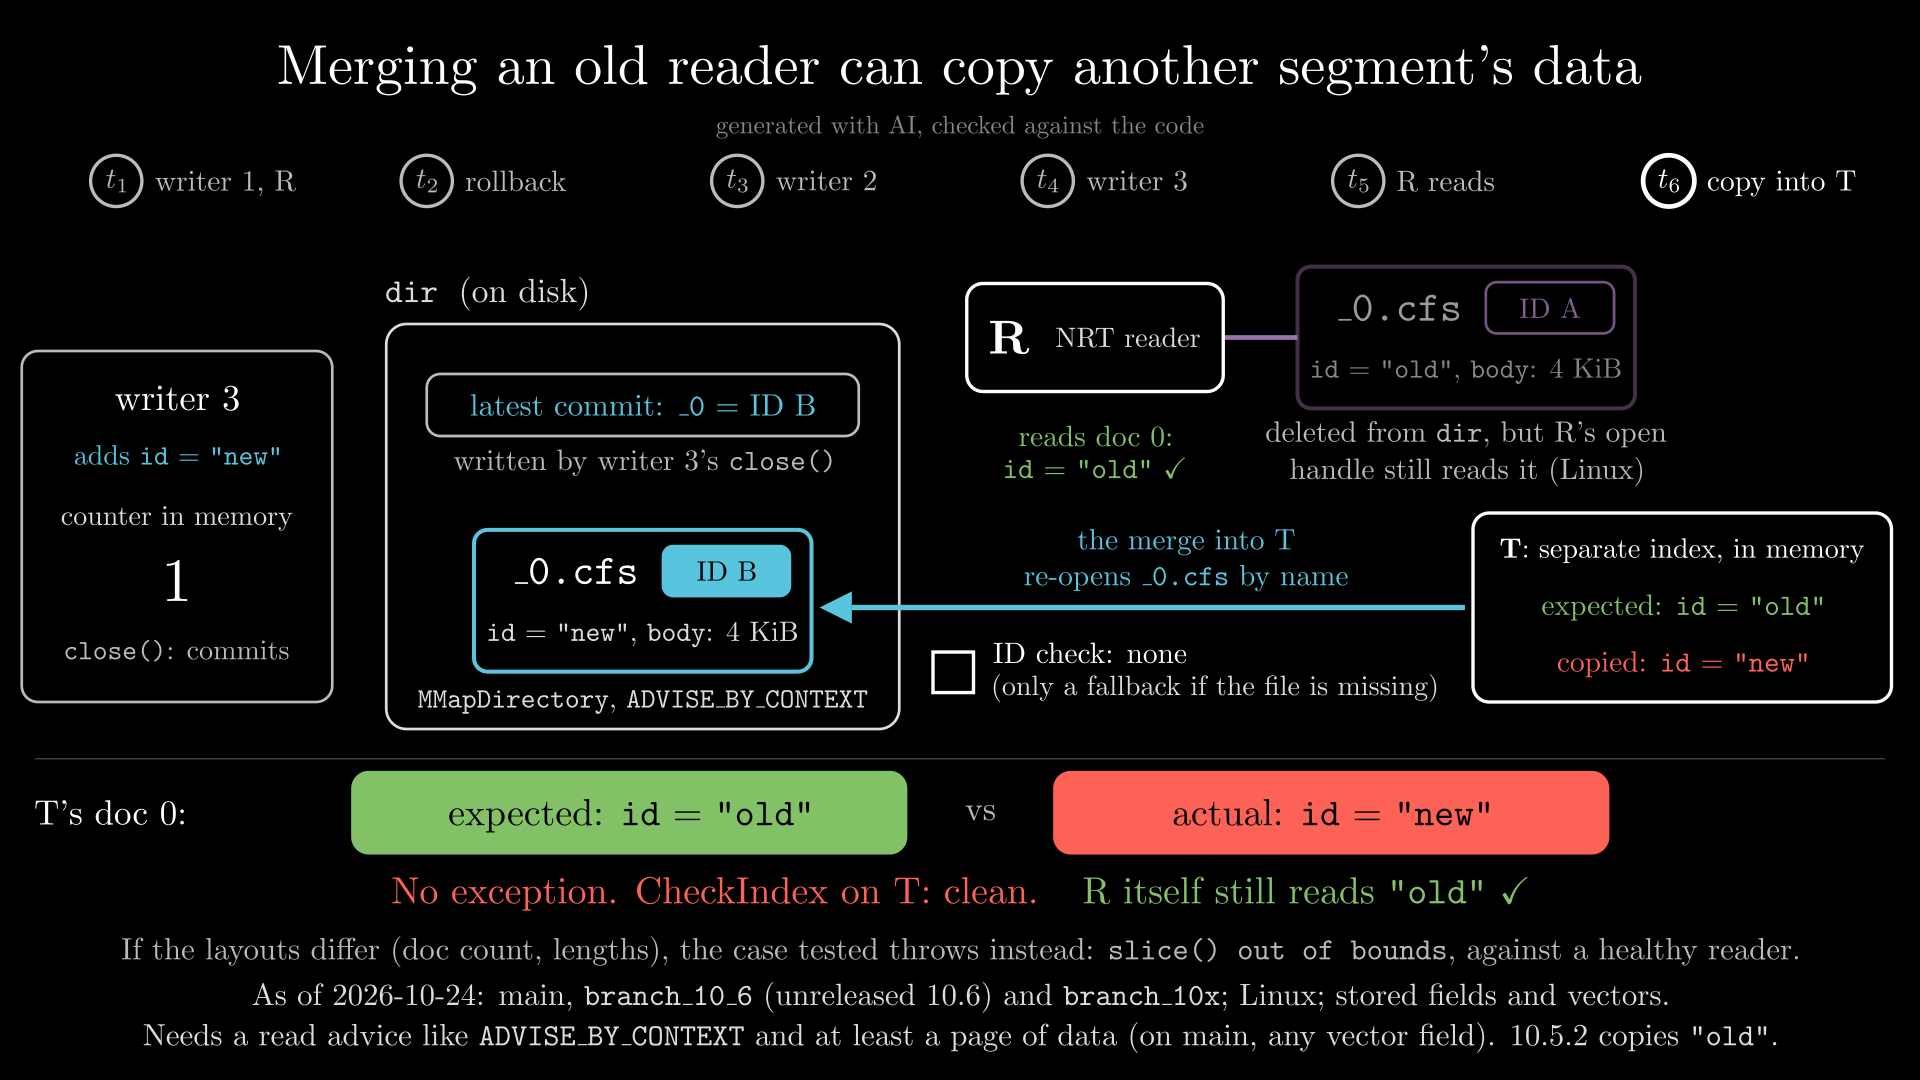
_0.cfs file and its one non-default setting (ADVISE_BY_CONTEXT), and the old reader R with the target index T, in steps t1 to t6. Select the still to open it at full size. Generated with AI, checked against the code.- Use an
MMapDirectorywithsetReadAdvice(ADVISE_BY_CONTEXT). Writer 1 adds a document with storedidoldand a 4096-letterbody, opens an NRT reader R on segment_0and rolls back; R stays open. - Writer 2 opens the directory, deletes
_0's leftover files (no commit refers to them) and rolls back, so its raised counter is never saved. Writer 3 writes a different segment, also named_0:newplus 4096 other letters, the same sizes. On Linux R still reads its deleted files through its open handle. - You copy R into a target index with
addIndexesand expectold, as 10.5.2 copies under the same setting. - Instead the merge opens
_0.cfsagain by name, with no segment-ID check, and copies writer 3's document:newand its letters. No exception,CheckIndexon the target is clean, and R itself still readsold. - With different layouts (files of at least a page), the tested case throws instead (
slice() _0.fdt out of bounds). With the default advice, or under a page, nothing is opened again and the copy is right.
10.6.0 (released 2026-10-29, branch_10_6) and unreleased main and branch_10x, with an unwrapped MMapDirectory input, advice such as ADVISE_BY_CONTEXT and a file of at least 4 KiB (on main any vector field), and a rare sequence: an NRT reader outlives two writer sessions ending without a commit, a third reuses its segment name, and the reader is merged. No Lucene production code sets that advice.
Mechanism, terms and numbers789 words
In the 10.6 code, released in 10.6.0 on 2026-10-29, the readers for stored fields, raw vectors and compound files can open their data file a second time, by name, when a merge or another sequential read needs it. Nothing checks that the file is still theirs. After a rollback, a later writer can reuse the same segment name, so merging an old reader, for example with addIndexes, copies the other segment's stored fields and vectors, silently when the layouts match (otherwise the merge throws). Since #16883 (2026-10-24) this needs MMapDirectory with read advice such as ADVISE_BY_CONTEXT and files of at least one page.
- Segment: a write-once part of the index, named
_0,_1, ... from a counter that is saved only when a commit writes asegments_Nfile. - Segment ID: a unique 16-byte value, made fresh for every new segment and stored in the header of each of its files. A reader checks it when it opens a file, so it knows the file belongs to its segment.
- Data files:
_0.fdt(stored fields),_0.vec(raw float vectors),_0.cfs(the compound file that packs a small segment's files; on by default). - Merge instance: the reader a merge reads through (
getMergeInstance()). Normal merges,IndexWriter.addIndexes(CodecReader...)andCheckIndex.testStoredFieldsall use one.
- New in the 10.6 cycle. A merge reads front to back and a search reads at random, and with memory-mapped files the read-ahead advice applies to a whole mapping. So three PRs made the merge read open the data file a second time, by name, with merge-friendly advice: #16749 for raw vectors (
.vec), #16684 for stored fields (.fdt) and #16796 for compound files (.cfs). Up to 10.5.2 the merge read through the input the reader already had open, which had passed the segment-ID check. - The second open checks nothing. It does not compare the segment ID. Its only fallback is for a file that is gone; the comment says "an open reader outlives its files, so read through the input it already holds". There is no fallback for a file that was replaced by another file with the same name.
- A name can be reused while an old reader is open. This part is older, and also true on 10.5.2: writer 1 flushes segment
_0for an NRT reader and ends without a commit, and the reader stays open; writer 2 opens the directory, deletes_0's leftover files (no commit refers to them), raises its counter in memory and ends without a commit, so the raised counter is never saved; writer 3 starts from the saved counter and writes a different segment, also named_0. A flush is enough. On Linux a deleted file stays readable through handles already open, so the old reader still reads its own_0, but the name_0.*now means writer 3's files. - Result.
addIndexes(oldLeaf)opens_0.fdt/_0.vec/_0.cfsagain by name and copies writer 3's stored fields and vectors into the target index. With the same layout (same document count and lengths) it is silent: no exception,CheckIndexon the target is clean atLevel.MAX_VALUE, and because terms still come from the old reader,TermQuery(key:old)finds the copied document but it returns writer 3's stored fields. With different layouts the merge throws against a healthy reader, for exampleIllegalArgumentException: slice() _0.fdt out of bounds; on the merged heads only for a file or inner file of at least a page (the small different-layout cases of the earlier checks, such as an inner.fdtof 458 bytes, no longer throw). The old reader's own searches stay right.
#16883 kept the second open by name and its file-gone-only fallback, but put a condition in front of it: a reader now opens its file again only if the input it holds is not "efficient" for a sequential read (IndexInput#isEfficientFor). On the merged heads the wrong copy needs all of these:
- an unwrapped mmap input:
MMapDirectory(orFSDirectory.openon a 64-bit JVM) on Linux or macOS (only Linux aarch64 was run), not wrapped in aFilterIndexInput; - an advice function that gives RANDOM to the reader's open and SEQUENTIAL to the sequential re-read, as
MMapDirectory.ADVISE_BY_CONTEXTdoes for readers not opened by a merge; - a data file, or compound inner file, of at least one OS page (4096 bytes here); on main any vector field qualifies, because vector data is page-aligned;
- the four-step sequence above, with the reader's first sequential read after the name was reused.
With the default advice nothing is opened again, on any directory type and at any size.
Exposure and likelihood341 words
- Silent wrong data in 10.6.0 (released 2026-10-29), main and
branch_10x. On main,branch_10_6andbranch_10xthe committed tests and the shortest test fail, and a plain-Java program copies the wrong document whileCheckIndexon the target stays clean. 10.5.2 copies right under the same setting. - The setting is public and built in.
MMapDirectory.ADVISE_BY_CONTEXTis the one built-in function under which #16883's second open does anything, and #16883's own tests use it. So every user the optimization helps runs the unchecked open. "A page" is 4 KiB, so any segment with more than about 4 KiB of stored fields qualifies, and on main every vector field. - A second public path.
KnnVectorsReader#getFloatVectorValues(field, DataAccessHint.SEQUENTIAL), new in #16883, returned writer 3's vector on the stale reader, outside any merge. No Lucene caller passes SEQUENTIAL yet. - What makes it rare. It needs that non-default advice and an unusual sequence: an NRT reader kept open across two writer sessions that end without a commit (
rollback(), orclose()withsetCommitOnClose(false)), then a merge of that reader. No Lucene production code setsADVISE_BY_CONTEXT. The call itself is real: Solr'sSolrIndexSplittercallsaddIndexeson wrapped leaves of a live searcher. - Downstream (read from code, not run, low confidence). Neither Elasticsearch nor OpenSearch built on a Lucene with #16883 as of 2026-10-24. Elasticsearch wraps every input in a
FilterIndexInputsubclass, so its shards would not reach the re-open; OpenSearch setsADVISE_BY_CONTEXTfor hybridfs (its default on 64-bit) and mmapfs and does not wrap inputs, so it would reach the re-open once it moves to such a Lucene. No code read here merges a reader that outlived its files. - Before 24 October it needed no setting at all: on the pre-#16883 heads the default configuration copied the wrong data with every directory type tested (
FSDirectory.open, which isMMapDirectoryhere,NIOFSDirectoryandByteBuffersDirectory). - Platforms. On-disk directories on Windows cannot hit it, because an open file cannot be deleted (not run on real Windows);
NIOFSDirectoryandByteBuffersDirectoryno longer reach it on the merged heads.
The test shows that addIndexes(CodecReader) of a stale NRT reader on MMapDirectory with ADVISE_BY_CONTEXT copies the stored fields of a later segment that reused the name _0, because the merge instance re-opens the file by name.
package org.apache.lucene.index;

import java.io.IOException;
import java.util.Random;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.StoredField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.MMapDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.LuceneTestCase.SuppressFileSystems;
import org.apache.lucene.tests.util.TestUtil;

@SuppressFileSystems("WindowsFS")
public class TestMergeInstanceReopenByName extends LuceneTestCase {

  public void testAddIndexesCopiesTheReadersOwnStoredFields() throws IOException {
    try (MMapDirectory dir = new MMapDirectory(createTempDir());
        Directory target = new ByteBuffersDirectory()) {
      dir.setReadAdvice(MMapDirectory.ADVISE_BY_CONTEXT);
      IndexWriter w1 = new IndexWriter(dir, config());
      w1.addDocument(doc("old"));
      DirectoryReader reader = DirectoryReader.open(w1);
      w1.rollback();
      new IndexWriter(dir, config()).rollback();
      try (IndexWriter w3 = new IndexWriter(dir, config())) {
        w3.addDocument(doc("new"));
      }
      try (IndexWriter t = new IndexWriter(target, config())) {
        t.addIndexes((CodecReader) getOnlyLeafReader(reader));
      }
      reader.close();
      try (DirectoryReader copy = DirectoryReader.open(target)) {
        // expected: the reader's own "old"; actual: "new" from the later segment that reused the name _0
        assertEquals("old", copy.storedFields().document(0).get("id"));
      }
    }
  }

  private static IndexWriterConfig config() {
    return new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec());
  }

  private static Document doc(String id) {
    byte[] pad = new byte[4096];
    new Random(0).nextBytes(pad);
    Document doc = new Document();
    doc.add(new StoredField("id", id));
    doc.add(new StoredField("pad", pad));
    return doc;
  }
}
# in a copy of this finding's repro folder (repro/LFV-004/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestMergeInstanceReopenByName
- Expected vs actual
- Expected: the copy has the reader's own id "old". Actual: org.junit.ComparisonFailure: expected:<[old]> but was:<[new]> (main 645d4fe, -ea and -da). 10.5.2 passes.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[old]> but was:<[new]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.index.TestMergeInstanceReopenByName.testAddIndexesCopiesTheReadersOwnStoredFields(TestMergeInstanceReopenByName.java:35)- Readers that outlive their writer are documented as usable, and
addIndexespromises to merge the reader's own data. - The 10.6 code already falls back to the reader's own input when the file is gone; only a replaced file was missed.
- Lucene guards the same name reuse elsewhere (
ReplicaNode.fileIsIdentical), and every release tested, 8.11.4 to 10.5.2, copies right.
The full argument232 words
- Readers that outlive their writer are documented as usable. The NRT javadoc on
DirectoryReader.openIfChanged(DirectoryReader, IndexWriter)says "Once the writer is closed, any outstanding readers may continue to be used."rollback()is a close ("Close the IndexWriter without committing ..."), andclose()withsetCommitOnClose(false)callsrollback(). - Writer 2 deleting the leftovers is the designed path.
StandardDirectoryReader.doClose: "our original writer was closed before we were ... The next time IW is opened on the index, it will delete them." - The contracts promise the reader's own data.
addIndexes(CodecReader...): "Merges the provided indexes into this index."StoredFieldsReader.getMergeInstance(): "Returns an instance optimized for merging." - The 10.6 code itself means to read the reader's own data after its files are gone: the fallback comment, #16796's PR body ("If the compound file is gone, merge opens fall back to the reader's mapping.") and a dedicated test,
TestLucene90CompoundFormat.testFallBackToTheReaderMappingWhenTheFileIsGone. Only "file replaced" was missed. - Lucene already knows names get reused and guards against it elsewhere.
ReplicaNode.fileIsIdenticalcompares header (segment ID included) and footer, with the comment "Segment name was reused! This is rare but possible and otherwise devastating".StandardDirectoryReadercompares segment IDs before it reuses an oldSegmentReaderof the same name, and throws anIllegalStateExceptionon a mismatch. - Every release tested handles the same sequence correctly: the name is reused, but the copy is right (8.11.4 to 10.5.2; 10.5.2 also under
ADVISE_BY_CONTEXT).
The devil's-advocate check182 words
The intended-behaviour checker found no doc, javadoc, CHANGES entry, PR discussion or SECURITY.md clause that makes this sequence unsupported. Verdict: a bug, not intended. The strongest counter-argument is about where to put the blame: the file-format docs promise "File names are never re-used. That is, when any file is saved to the Directory it is given a never before used filename." (lucene104/package-info.java:202). A committer can argue that the 10.6 re-open is correct under that rule, and that the real defect is the older name reuse after rollback (the study's finding L).
The answer: Lucene itself breaks the rule through public API calls; its own replicator says reuse happens and guards against it with the same kind of check as the proposed fix; 10.5.2 survives the reuse, and the 10.6 re-open is the first code that turns it into wrong data. Suggested framing: one issue about the wrong copy that names the name reuse as its precondition. Not a security issue: SECURITY.md puts it out of scope (the trigger is the application's own call sequence), so a public issue is fine.
Recommended Check the re-opened file's identity, fall back to the reader's own input
After each re-open, compare the new input's length and full index header (segment ID included) with the reader's input; on a mismatch, close it and use the reader's validated input, as 10.5.2 did. One CodecUtil helper at three sites: 167 tests, 0 failures on merged main; branches need a hand backport (not run). It does not fix the name reuse.
All options and trade-offs5 options · 565 words
The checks validated an identity check after each re-open; the other options come from the brief's list for the PR author.
Check the re-opened file's identity, fall back to the reader's own input (validated by the checks) (recommended)
A new CodecUtil.reopenedIfSameFile(IndexInput reopened, IndexInput original) (public static, @lucene.internal): if the lengths are equal and the full index headers are byte-equal (codec name, version, 16-byte segment ID, suffix) it returns reopened; otherwise it closes reopened and returns original, the reader's validated input, as 10.5.2 did. Each of the three sites wraps its existing directory.openInput(...) in it; the file-gone fallback is unchanged.
For the merged code use the port on local branch r106-merge-instance-reopen-by-name-pr16883-test (9d6362a4a2): 4 files, CodecUtil +30, the compound reader and the stored-fields and flat-vectors readers.
Trade-offs
- It adds a public
@lucene.internalmethod toCodecUtilduring the feature freeze; the alternative is three private copies of the helper. - Cost: it reads 46 bytes (
.cfs), 54 bytes (.fdt) or about 82 bytes (.vec) of header from both inputs, once per reader and file on the merged code (after a mismatch the ported compound reader keeps no copy, so a later conflicting open of an inner file checks again, only in this rare case). - On a mismatch the reader keeps its random-advice input for later sequential reads (only in this rare case).
- It does not apply as is to
branch_10_6orbranch_10x: twocatchlines differ, so a backport needs them adapted by hand; not built or run there. - Style: it uses a
boolean ... try/finallypattern that open PR #16888 is removing from these readers; #16571 editsCodecUtilin another hunk. - Not tested: a direct unit test of the helper, files with different layouts but the same length, Faiss. It does not fix the name reuse itself.
What the checks validated
- On merged main
ea57360912the port applies cleanly and, with the v3 class, both probes, TestStoredFieldsMergeReadAdvice, TestVectorsMergeReadAdvice, TestLucene90CompoundFormat, TestMMapDirectory and TestCodecUtil, gives 167 tests and 0 failures (:lucene:core:checknot run on it). - On the #16883 PR head it kept #16883's own tests green.
- The older fix commits (pre-#16883 code): 56 tests in 4 classes; 76 tests in 5 classes on main; reverting any one file makes exactly that site's test fail;
org.apache.lucene.codecs.*plus 12 index classes, 1,756 tests, 0 failures; every plain-Java harness copies right, quantized HNSW included.
Use checkIndexHeader with the reader's segment ID and suffix instead of comparing bytes with the original input. ReplicaNode.fileIsIdentical is Lucene's own precedent for an identity check by header and footer.
Trade-offs
Each site needs the expected ID and suffix at hand; otherwise the same cost as the byte comparison.
Open it while the name still identifies the reader's file.
Trade-offs
A second mapping per reader whenever the advice conflicts, which #16883 moved away from (it opens lazily).
Revert the optimization.
Trade-offs
The largest change, and it undoes most of #16883.
Persist or skip the counter so a rolled-back segment's name is never handed out again, which restores the documented "File names are never re-used" rule.
Trade-offs
Not a 10.6-sized change, and it does not cover wipe-and-rebuild under an open reader. A good follow-up either way.
Randomized model-based testing (non-formal): an AI tool's harness ran random IndexWriter and NRT operations against a reference model on pre-#16883 main; in its first 15-minute hunt checkReader on an old NRT reader failed. The shrinker cut it to 9 operations, two of them rollbacks; AI verifiers reproduced it. TLA+, Alloy and the JBMC slice could not express it.
The method in full278 words
Method: randomized model-based testing (the study's run-1 testing baseline, "non-formal"; not a formal-methods find).
- On 2026-10-22 an AI tool wrote a harness of about 2,400 lines that runs random sequences of IndexWriter and NRT operations, single-threaded (
SerialMergeScheduler), against a reference model, withCheckIndexandcheckReaderchecks, on main7cecf79523(which already had #16684, #16749, #16769, #16796 and #16622, but not #16883). - In its first full 15-minute hunt (seed DEADBEEF),
TestUtil.checkReaderon an old NRT reader failed with aCorruptIndexExceptiontwice: at 67 s on a compound segment, and at 161 s (Corrupted: docID=0, docBase=0, chunkDocs=12, numDocs=1 ... file=_9.fdt). The shrinker cut the second to 9 operations, including twoROLLBACKs and aCHECK_READERof the old reader, and no commit. - The AI tool then wrote a deterministic JUnit repro and traced it to
mergeFieldsStream()(#16684). The task text listedrollbackandaddIndexes(CodecReader...)among the operations; runningcheckReaderon old NRT readers, which is what fired, was the AI tool's own choice. Nothing in the task mentioned merge instances, re-opening files or name reuse. - Separate AI verifiers reproduced it with their own tests and found the vectors and compound sites by reading the code; the 2026-10-23 checkers found the quantized-format extension (#16622) by running it.
- The P model reached it only after its task text listed the testing baseline's bug classes and it added an explicit "merge instance re-opens by name" flag: the bug re-encoded, not found. TLA+, Alloy and the JBMC slice could not express it.
That hunt ran on pre-#16883 code with the default advice; on today's heads the same harness would need ADVISE_BY_CONTEXT and larger values to see it (inferred, not run).
No report or fix of the wrong copy found in GitHub issues and PRs (65 queries), review threads, all 410 open PRs or the mailing lists, searched 2026-10-23 and re-checked 2026-10-24. #16883 narrowed it but did not remove it; open PR #16888 edits the same readers.
Searches6 searches
No report or fix of the wrong copy was found. #16883 narrowed the bug but did not remove it, and PR #16888 (still open on 2026-10-24) edits the same readers.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene) | 2026-10-23 | 65 gh search issues --include-prs queries with no date filter (titles, bodies, comments), for example "segment name" reused, "outlives its files", getMergeInstance reopen, mergeFieldsStream, addIndexes stale, reopen by name, isEfficientFor, ADVISE_BY_CONTEXT merge; all 147 items created since 2026-10-01 and 154 updated since 2026-10-16 listed | only the introducing PRs, #16883 and design threads (#16767 and others) |
| Migrated JIRA issues (in the GitHub search) | 2026-10-23 | the same searches | context, not duplicates: #6993 (LUCENE-5931, where the reader's segment-ID check was discussed) and #6636 (LUCENE-5574, the existing test class) |
| Review threads | 2026-10-23 | comments and reviews of #16684, #16749, #16769, #16796, #16883, #16767, #16797, #16802, #16427, #13920, #16898, #16850, #16622, grepped for reuse, same name, identity, segment id, rollback, replaced, stale, header | nobody raises a re-opened name pointing at another segment's file |
| Open PRs | 2026-10-23 | file lists of all 410 open PRs | #16883 (then open) rewrote the 3 sites without an identity check; #16888 edits next to them; #16571 edits CodecUtil |
| Mailing lists (lists.apache.org) | 2026-10-23 | dev@, java-user@, issues@, builds@, commits@ | nothing about it |
| Re-checks | 2026-10-23; 2026-10-24 | 5 queries by the claim re-check; 5 more for v3 ("outlives its files", isEfficientFor, FilterIndexInput isEfficientFor, addIndexes / reopen / name since 10-20, "segment name" reused) and every item created since a recent cutoff | the claim re-check's 5: 0 hits; the v3 5: nothing but #16883 and old unrelated issues; #16901-#16904, the only items created since a recent cutoff, unrelated; no comment on #16883 since its merge |
Introduced by #16749 (vectors) and #16684 (stored fields), both merged 2026-10-01, and #16796 (compound files, 2026-10-11); #16622 extends it to the quantized formats. #16883 (merged 2026-10-24) narrowed it to advice such as ADVISE_BY_CONTEXT and files of a page or more. Every release tested, 8.11.4 to 10.5.2, reuses the name but copies right; bisected on branch_10_6.
Versions tested6 rows
Introduced by three PRs by @jimczi, approved by @ChrisHegarty, all in milestone 10.6.0: #16749 "Let a merge read the vectors through its own mapping" (merged 2026-10-01 07:29, main c95aa21a7b), #16684 "Let merges read stored fields sequentially without disturbing searches" (2026-10-01 07:55, fe67d20e9e) and #16796 "Merges read compound files through a mapping of their own" (2026-10-11 08:30, f94888d85c). #16622 (@john-mlika) routes the quantized formats' raw vectors through the vectors site; #16769 reworked that site but changed no outcome. Narrowed by #16883 "Open files twice for sequential reads only when it helps" (@jimczi; merged 2026-10-24, main ea57360912, backports 2763db11b0 and 1309534296). The name reuse itself (finding L) is older and also on 10.5.2.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912, branch_10_6 2763db11b0, branch_10x 1309534296 | affected with ADVISE_BY_CONTEXT | with ADVISE_BY_CONTEXT and a file of at least a page: 7 run, 4 fail (the 3 committed tests and the shortest test); the plain-Java program copies the wrong document; with the default advice every directory type copies right |
main b83101cdd2, branch_10_6 d04ee73177, branch_10x f8964e2bdb (before #16883) | affected | the default config already copies wrong data: 24 of 24 reused cases wrong in the 48-case matrix; target CheckIndex clean 48/48 |
| branch_10_6 bisect | commit by commit | before #16749 (87fbf07178) right; #16749 vectors wrong (non-compound); #16684 stored fields too; #16622 quantized raw vectors too; #16769 no change; from #16796 (077cf9cabd) compound segments too |
#16883 PR head d992cbeb51 | advice only | default advice right (8/8); ADVISE_BY_CONTEXT: the 3 committed tests fail |
| 8.11.4, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.1, 10.5.2 (sha1 = Maven Central) | not affected | the name is reused (24 of 48 cases) but every copy is right; 10.5.2 also with ADVISE_BY_CONTEXT and a 4096-letter value |
fix 57e4cffbe3 and port 9d6362a4a2 | not affected | 0 wrong copies in every harness |
Independent AI checkers checked brief v1 and a claim re-check re-checked the disputed claims; after #16883 merged, a freshness pass re-ran the tests and a new probe on the three merged heads: narrowed, still real. The study's AI verifiers each reproduced it on pre-#16883 code.
Checks and verdicts323 words
Independent AI checkers checked brief v1 on 2026-10-23 and a claim re-check re-checked the disputed claims (v2). After #16883 merged, a freshness pass re-ran the committed tests, the minimal test and a new probe on the three merged heads (the earlier plain-Java harnesses were not re-run), and brief v3 applies it.
| Check | Verdict | What it found |
|---|---|---|
| exec-current | confirmed | The tests fail on both pre-#16883 heads (main b83101cdd2, branch_10_6 d04ee73177) on several seeds and with assertions off; its own 64-configuration repro (indexed key, target reopened, CheckIndex at MAX level): every equal-layout case silently wrong, every different-layout case throws; 10.5.2 64/64 right; the fix and the #16883 port pass. |
| exec-versions | confirmed, with corrections | Releases back to 8.11.4 copy right; the bisect shows #16769 introduced nothing and #16622 extends it to quantized HNSW; branch_10x is affected; more exception types for different layouts. |
| code-history | confirmed, with corrections | Citations, PR facts, root cause and fix hold; flagged a wrong javadoc attribution and a wrong CheckIndex citation; added the "file names are never re-used" counterpoint. |
| intended-behavior | a bug, not intended | No document makes the sequence unsupported; the open question is blame (the name reuse), not whether it is a bug. |
| dups-policy | no duplicates | 65 queries, thread scans, all open PRs, mailing lists; showed that a flush by writer 3 is enough. |
| Claim re-check | status ready | Its own probe: 0/8 right on both heads before #16883, 8/8 on 10.5.2 and the fix; 33 claim verdicts; reproduced by 6 independent harnesses (pre-#16883). |
| Freshness re-check | narrowed, still real | On the merged heads: needs an unwrapped mmap input, ADVISE_BY_CONTEXT-like advice and at least a page; the committed tests still fail; the port applies to merged main. |
| study verifiers | new bug | model-based testing verifier and P-model verifier each reproduced it with their own test, on pre-#16883 code; the default-config verify repro no longer fails on merged main. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 368 KB
Finding record, Lucene and upstream sources, repro files and diagram notes678 words
- Registry title
- Merge instances re-open segment files by name, so merging an old reader after a name reuse can copy another segment's data
- Area
- codecs / merge instances
- Priority
- Low, rank 903: It can silently copy another segment's data, but since #16883 it needs ADVISE_BY_CONTEXT, a stale reader kept across two uncommitted sessions and segment-name reuse, so it heads the low durability rows that LFV-331 and LFV-191 place after it.
- Impact class
- data corruption
- Impact note
- Code new in 10.6.0 (released 2026-10-29); since #16883 (merged 2026-10-24) only with an unwrapped MMapDirectory input, a read-advice function that differs for search and merge (e.g. MMapDirectory.ADVISE_BY_CONTEXT) and data of at least one 4 KiB page, plus a rolled-back segment-name reuse and a stale reader being merged.
- Summary
- You keep an old NRT reader open, roll back writers until a later writer reuses its segment name, and then merge that reader, for example with addIndexes(CodecReader...). You expect the merge to copy the old reader's own stored fields and vectors. Instead its merge instance opens the file again by name and copies the newer segment's data, silently (CheckIndex on the target is clean) or, for compound files of another layout, with a loud exception.
- Introduced
- #16684 (fe67d20e9e, stored fields), #16749 (c95aa21a7b, vectors), #16796 (f94888d85c, compound files); #16622 (cbad01e83e) extends it to the quantized HNSW format; narrowed by #16883 (ea57360912) (2026-10-01 (#16684, #16749 merged); 2026-10-11 (#16796 merged))
- First affected version
- 10.6.0 (released 2026-10-29); also unreleased main and branch_10x
- Affected versions
- before #16883: main b83101cdd2, branch_10_6 d04ee73177 and branch_10x in the default config [exec]; at main ea57360912, a9779ef3c193 and 645d4fe14a2 / branch_10_6 2763db11b0 / branch_10x 1309534296 and 657014b3c579: only with ADVISE_BY_CONTEXT-style advice and >= 4 KiB files [exec; -ea and -da on 645d4fe14a2 and 657014b3c579]; 10.5.2 and the releases tested back to 8.11.4 copy correctly [exec]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed in the earlier formal verification study by independent AI checks and a rerun on Lucene main; not yet triaged by a person.
- Found by
- non-formal baseline: randomized/MBT; also reached by P
- Upstream and prior reports
- none found (2026-10-23: 65 gh queries without a date filter plus mailing lists; claim re-check re-ran 5); #16883 (merged 2026-10-24) narrows but does not remove it; open #16888 edits the same readers; #16905 (merged 2026-10-26: main 49483e82b35, branch_10_6 940768fb0cd, branch_10x 657014b3c579) restores IOContext.merge() for the re-open but still re-opens by name, so it does not fix this; #16888 is still open (checked 2026-10-29)
- Lucene commit tested
- the merged heads main
ea57360912(the hunt's main), branch_10_62763db11b0and branch_10x1309534296(freshness re-check pass and v3 runs, 2026-10-24); before #16883: mainb83101cdd2, branch_10_6d04ee73177, branch_10xf8964e2bdb(2026-10-23 checks); releases 8.11.4, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.1 and 10.5.2 (not affected).
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/StandardDirectoryReader.java:275-284 (ID compare, throws IllegalStateException)
- How it was found
a Lucene clone (git merge-base --is-ancestor: c95aa21a7b, fe67d20e9e, dba8f5e953, f94888d85c, cbad01e83e are ancestors of 7cecf79523; ea57360912 is not)
- TestMergeInstanceReopenByName.java (JUnit test):
repro/LFV-004/src/org/apache/lucene/index/TestMergeInstanceReopenByName.java(52 lines)
A structural picture: the current writer's counter on the left, the directory dir with its _0.cfs file box (name, segment-ID tag, the stored document) and its one non-default setting (MMapDirectory, ADVISE_BY_CONTEXT) in the centre, and the old reader R with its open handle and the target index T on the right, with steps t1 to t6.
These files are revision 7 (2026-10-24). It redraws the example with ADVISE_BY_CONTEXT and a 4096-letter body, because the earlier 3-letter example copies right since #16883; its byte sizes match the files here. The picture is the program: VisualExample.java (among the repro files) runs the same sequence and copies the wrong document on all three merged heads, and right on 10.5.2.
assets/LFV-004/bug.png(368 KB)