A ParallelLeafReader joins indexes that hold the same documents in the same order. When two of them have a field with the same name, the first one passed in owns it.
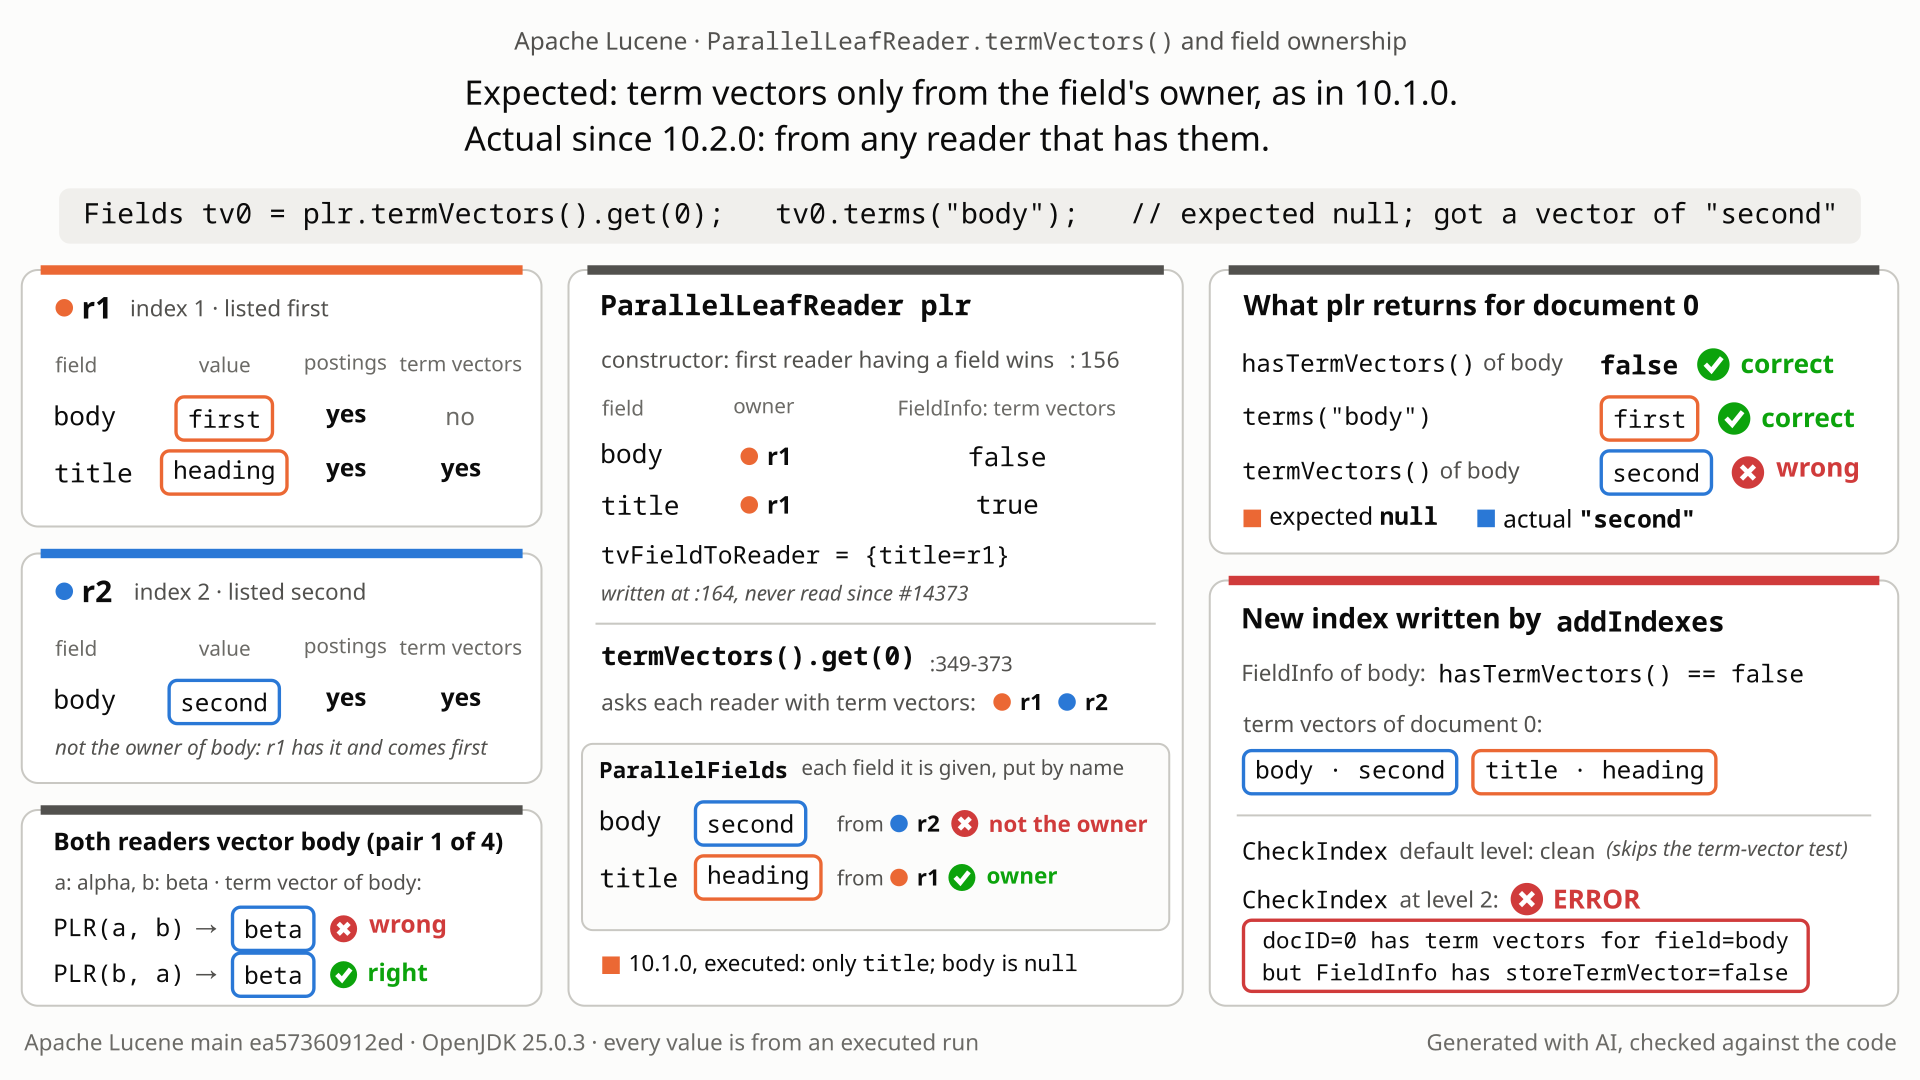
termVectors().get(0) taking body from r2, the addIndexes copy that CheckIndex rejects at level 2, and the both-readers case. Every value is from an executed run on main. Select the still to open it at full size. Generated with AI, checked against the code.- Glue two one-document indexes with
new ParallelLeafReader(false, r1, r2). Both have a fieldbody: r1 indexes"first"without term vectors, r2 indexes"second"with them. r1 is listed first, so it ownsbody:getFieldInfos()says no term vectors andterms("body")givesfirst. - You expect
termVectors().get(0).terms("body")to benull, as on 10.1.0: the owner has no vectors, andTermVectors.getreturns null "if term vectors were not indexed". - Since 10.2.0 you get r2's vector, the term
second. Copied withaddIndexes(SlowCodecReaderWrapper.wrap(plr)), the new index stores it understoreTermVector=false:CheckIndexat level 2 rejects it, while the default levels report it clean. - If both readers vector
body, the winner is decided by identity hash codes, not by reader order: 4 of 8 reader orders returned the other reader's vector. - The cause: #14373, an optimization, made
get()collect every field of every reader and stopped reading the owner maptvFieldToReader.
Users of ParallelLeafReader or ParallelCompositeReader (opt-in, expert API) whose indexes share a field name where an index other than the first stores term vectors for it, as after a schema change; Lucene's own TestDemoParallelLeafReader allows such overlap. Default codec; one document is enough. MoreLikeThis and other direct readers of term vectors get the other index's content.
Mechanism, terms and numbers1,179 words
Glue two indexes together with a ParallelLeafReader and, when both have a field called body, the first one owns it: the reader reports its FieldInfo and searches its postings. Since Lucene 10.2.0, termVectors() ignores that owner. If the owner has no term vectors for body and the other index has them, you get the other index's vector (second instead of null in the repro), although the same reader says body has no term vectors. If both have vectors, the winner is decided by identity hash codes, not by the order the readers were passed in (4 of 8 reader orders wrong in the runs). Copy such a reader with addIndexes and the new index fails CheckIndex at level 2 (only at level 3 when both have vectors), while the default levels report it clean. The cause is #14373, an optimization that stopped looking up the field's owner. Opt-in API, default codec, released in 10.2.0 through 10.6.0 (10.6.0 by reading).
- ParallelLeafReader: a reader that glues together several indexes holding the same documents in the same order. Document 0 of the parallel reader is document 0 of every index, with the union of their fields. The class javadoc's use case: large fields that rarely change in one index, small fields that change often in another.
- The owner of a field: when two of the glued indexes have a field with the same name, the first index passed in that has the field owns it. The parallel reader reports the owner's
FieldInfo, searches the owner's postings and reads the owner's doc values. - Term vectors: an optional per-document copy of one field's terms (optionally with positions and offsets), stored when the field is indexed with
setStoreTermVectors(true). Highlighters and MoreLikeThis read them.FieldInfo.hasTermVectors()says whether a field has them.
Two indexes with one document each, glued with new ParallelLeafReader(false, reader1, reader2):
| field | reader 1 (passed first) | reader 2 |
|---|---|---|
body | "first", indexed, no term vectors | "second", indexed with term vectors |
title | "heading", with term vectors | - |
Reader 1 owns body. Ask the parallel reader about document 0:
plr.getFieldInfos().fieldInfo("body").hasTermVectors();   // false: the owner has none
plr.terms("body");                                         // the owner's postings: "first"
plr.termVectors().get(0).terms("body"); // ?null: the owner has no term vectors for body, the reader's own FieldInfo says so, and TermVectors.get returns "null if term vectors were not indexed". Lucene 10.1.0 returns null.
Reader 2's vector, the term second. The same reader now says three things about body: it has no term vectors, its text is first, and here is a term vector for second. Three checks, with the program in the repro section:
| check | Lucene 10.1.0 | Lucene 10.5.2 and main |
|---|---|---|
1. termVectors().get(0).terms("body") | null | second |
2. copy plr into a new index with addIndexes(SlowCodecReaderWrapper.wrap(plr)), then CheckIndex level 1 / level 2 | clean / clean | clean / not clean: docID=0 has term vectors for field=body but FieldInfo has storeTermVector=false |
3. both readers vector body (alpha, beta): 4 pairs, each glued in both orders; how many return the second reader's vector | 0 of 8 | 4 of 8 in every run of the program, one order of each pair |
In check 3, which order of a pair is wrong is decided by identity hash codes. In the runs it changed with the test seed, the -ea/-da flag and the Lucene version, while identical re-runs gave the same order.
All lines are in ParallelLeafReader.java at ea57360912ed.
- The constructor records the owner (154-172): 'first reader having a given field "wins"' (156). For term vectors it adds the field to the map
tvFieldToReaderonly if the owner has term vectors for it ("only add these if the reader responsible for that field name is the current", 160;putat 164). Here that map is {title: reader 1};bodyis not in it. termVectors()collects every reader that has any term vectors in anIdentityHashMap(330-336): here both readers.get(docID)takes every field of every one of those readers (349-373): oneget(docID)per reader, then each returned field goes into aTreeMapwithput(363-368, 219-221), so a later reader replaces an earlier one. It never looks attvFieldToReader, which is now written and read nowhere (that is what the static analyzer flagged). The comment above the loop, "Step 3: Aggregate only required fields" (362), is not implemented.
| step | what the code does | result |
|---|---|---|
| constructor | body: first seen in reader 1, owner = reader 1, no term vectors, so no entry; title: owner = reader 1, with term vectors; reader 2's body is skipped (157) | tvFieldToReader = {title: reader 1} |
get(0), reader 1 | its vectors for document 0: title | adds title = heading |
get(0), reader 2 | its vectors for document 0: body | adds body = second: the bug |
Why the winner depends on object identity. When both readers vector body, the last put wins, and the loop visits the readers in the IdentityHashMap's slot order: a reader's slot comes from System.identityHashCode, not from the order the readers were passed in. JDK 25's default IdentityHashMap has 32 slots; a reader whose slot is taken goes to the next one, and the readers are inserted in the order passed in. So for a pair a, b:
- Different slots (the usual case):
PLR(a, b)andPLR(b, a)visit the two readers in the same order, the same reader wins in both, and exactly one order is wrong. - The same slot (about 1 pair in 32 if hashes are uniform), unless it is the last: the reader passed second wins in both orders, so both are wrong.
- The same last slot (about 1 pair in 1,024): the second reader wraps around to slot 0 and the first wins in both orders.
Measured on main over three runs of 4,000 pairs: 117-120 shared a slot, 114-117 had both orders wrong, 2-4 had both right. So "4 of 8" is typical (about 88% of 4-pair runs), not certain.
What 10.1.0 did. get(docID) looped over tvFieldToReader and asked each field's owner for that one field. body had no entry, so no vector came back.
How it reaches disk. SlowCodecReaderWrapper hands the reader's termVectors() to addIndexes and merges (SlowCodecReaderWrapper.java:345-376). With the default codec, the term-vectors writer calls addAllDocVectors per document for such a reader (Lucene90CompressingTermVectorsWriter.java:927-929), and addAllDocVectors writes every field it is given without checking hasTermVectors() (TermVectorsWriter.java:235 and below). This happens only when the parallel reader has some field with term vectors (title here), because the merge skips term vectors otherwise (SegmentMerger.java:170-171). CheckIndex compares term vectors with the field infos only from level 2, and with the postings only at level 3 (CheckIndex.java:1114, 1130-1132, 4360); the command-line default is level 1 (:4673), and a CheckIndex without setLevel runs at level 0. Those levels check only the files' checksums.
Exposure and likelihood420 words
- Who is exposed. Users of
ParallelLeafReader, and ofParallelCompositeReader, which builds oneParallelLeafReaderper leaf (ParallelCompositeReader.java:133), whose glued indexes share a field name where an index other than the first stores term vectors for it. Opt-in, expert API; default codec; no special settings. - When names overlap. The javadoc's use case normally gives disjoint fields, but overlap is a defined case: Lucene's own
TestDemoParallelLeafReaderputs a derived index first "so if there are field name overlaps, because changes to the schema overwrote existing field names, it wins" (:178-180). A schema change that re-indexesbodywithout term vectors in the derived index, while the original still has them, is check 1. - Read path: another index's content. A consumer that reads term vectors without checking the field's
FieldInfofirst gets the other index's version of the field:MoreLikeThisand the highlighter'sTokenSourcescalltermVectors().getdirectly.UnifiedHighlighteruses term vectors only whenFieldInfo.hasTermVectors()is true, so it would skip the leaked vector when the owner has none, but not when both indexes vector the field (by code reading; not run). - Write path: an inconsistent index.
addIndexes(SlowCodecReaderWrapper.wrap(plr))(executed), or a merge policy whosewrapForMergereturns aParallelLeafReaderas inTestDemoParallelLeafReader(:645-651), writes a segment that CheckIndex rejects: at level 2 or 3 when the owner has no term vectors for the field, and only at level 3 when both indexes vector it (the vectors then disagree with the postings). In that merge pattern, with both indexes vectoring the field, the study saw 14 of 24 merges produce such a segment, checked at level 3, and 0 of 24 with either fix control. CheckIndex's own message says-exorcisewould drop the segment with its documents (not run). The input indexes are not modified. - Silent. No exception on read or write. The default CheckIndex levels (1 on the command line, 0 without
setLevel) verify the files' checksums but skip the term-vector consistency checks. - Depends on object identity. When several indexes vector the field, the winner is decided by identity hash codes. In the runs it changed with the test seed, the
-ea/-daflag and the Lucene version (identical re-runs gave the same result), so an unrelated change can flip it. - Scale. None: one document per index is enough.
- How common. Unknown. No report in the 18 months since 10.2.0 (tagged 2025-04-10). Lucene's randomized test wrapping never overlaps fields:
LuceneTestCase.wrapReaderbuilds aParallelLeafReaderover one reader or over twoFieldFilterLeafReaderhalves with disjoint fields (LuceneTestCaseParent.java:2372-2405).
The test shows that ParallelLeafReader.termVectors() returns a term vector from the second reader for a field that the first reader owns ("first reader having a given field wins") and indexes without term vectors.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestParallelLeafReaderTermVectorsOwner extends LuceneTestCase {

  private static DirectoryReader oneDocIndex(Directory dir, String body, FieldType type)
      throws IOException {
    try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      Document doc = new Document();
      doc.add(new Field("body", body, type));
      w.addDocument(doc);
    }
    return DirectoryReader.open(dir);
  }

  public void testTermVectorsOnlyFromFirstReaderHavingTheField() throws IOException {
    FieldType withVectors = new FieldType(TextField.TYPE_NOT_STORED);
    withVectors.setStoreTermVectors(true);
    try (Directory d1 = new ByteBuffersDirectory();
        Directory d2 = new ByteBuffersDirectory();
        DirectoryReader first = oneDocIndex(d1, "first", TextField.TYPE_NOT_STORED);
        DirectoryReader second = oneDocIndex(d2, "second", withVectors);
        ParallelLeafReader reader =
            new ParallelLeafReader(false, getOnlyLeafReader(first), getOnlyLeafReader(second))) {
      Fields vectors = reader.termVectors().get(0);
      Terms body = vectors == null ? null : vectors.terms("body");
      // expected: none, the first reader owns "body" and has no vectors; actual: the second's
      assertNull(
          "term vector of body", body == null ? null : body.iterator().next().utf8ToString());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-018/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestParallelLeafReaderTermVectorsOwner
- Expected vs actual
- Expected: no term vector for
body(getFieldInfos() and terms() come from the first reader, which has none). Actual: the second reader's vector (termsecond).
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: term vector of body expected null, but was:<second>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotNull(Assert.java:756)
       org.junit.Assert.assertNull(Assert.java:738)
org.apache.lucene.index.TestParallelLeafReaderTermVectorsOwner.testTermVectorsOnlyFromFirstReaderHavingTheField(TestParallelLeafReaderTermVectorsOwner.java:52)- The constructor records a term-vector owner only for the reader owning the field (
:156-164); up to 10.1.0get()used it. - #14373 was an optimization, "verified via existing tests"; no test overlaps fields, and nothing announced a change.
- The result contradicts the reader's own
FieldInfo, and anaddIndexescopy fails CheckIndex. The public javadoc states the rule for searching only.
The full argument339 words
- The class says the first index wins, for searching.
ParallelLeafReader.java:38-40: "Each document contains the union of the fields of all documents with the same document number. When searching, matches for a query term are from the first index added that has the field."ParallelCompositeReader.java:30says the same. - The constructor applies that rule to term vectors on purpose. 'first reader having a given field "wins"' (
:156) and "only add these if the reader responsible for that field name is the current" (:160), directly abovetvFieldToReader.put(:164). - What is not promised publicly. No public javadoc states the rule for term vectors. For them it comes from the constructor's comments and owner map, from every release up to 10.1.0, and from consistency with
getFieldInfos(). The constructor keeps the alternative only as a TODO: "consider populating 1st leaf with vectors even if the field name has been seen on a previous leaf" (:161-162). So the non-owner vector rests on the implementation and its history; the CheckIndex failure and the identity-hash winner do not depend on that question. - The API contracts.
TermVectors.get: "Returns term vectors for this document, or null if term vectors were not indexed" (TermVectors.java:47). CheckIndex rejects "has term vectors for field=... but FieldInfo has storeTermVector=false" (CheckIndex.java:4349-4357). - Lucene's own demo relies on it.
TestDemoParallelLeafReader.java:178-180puts the derived index first so that it wins on overlapping names. - The change was an optimization. #14373 (DivyanshIITB; approved and merged by vigyasharma on 2025-03-24): "Replaces per-field term vector fetching with a single call per reader ... Verified via existing tests." The review covered formatting, the CHANGES entry and a null check; no test was added. It closed #7926 (LUCENE-6868), which asked only to stop loading the same vectors once per field.
CHANGES.txt:1956lists it under 10.2.0 "Optimizations". Up to 10.1.0,get()looped overtvFieldToReader. - No test covers the case. No upstream test has a term-vector field in two glued indexes; the five parallel-reader suites pass with and without the fix.
The devil's-advocate check281 words
The strongest case for "intended": (1) the javadoc rule is phrased for searching ("When searching, matches for a query term ..."), and reading term vectors is not searching (the cross-model reviewer's best argument); (2) storedFields() does not apply the owner rule either, it visits every stored-fields reader (:291-296), so the real semantics could be a union; (3) in 2017 (LUCENE-7500, #8551) dsmiley argued that a later reader with term vectors should supply them when the first has none, and mikemccand wrote that "the fields users pass to it should be orthogonal across sub-readers and we really should enforce that".
Why it fails: the constructor still builds the term-vector owner map with a comment that states the rule, 10.1.0 used it, and #14373 dropped the lookup in a change described as a pure optimization. Stored fields are a union in reader order, every value delivered; term vectors keep one value per name, picked by identity hash codes, which no documented semantics would choose. The result contradicts the same reader's getFieldInfos() and terms(), and once written out breaks a CheckIndex invariant. dsmiley's 2017 change was reverted to "functionality identical" in that same issue, and would anyway need the merged FieldInfo to say storeTermVector=true, so checks 2 and 3 stay bugs under any reading. mikemccand's "should enforce" was never implemented, and overlap is used by Lucene's own demo. Verdict: not intended, a regression. An independent reviewer from another model family (OpenAI GPT-5.6) rated the intended-behaviour argument "weak" (verdict real, confidence high); a later fact check by the same model family rated it moderate for the non-owner vector alone, weak for the CheckIndex failure and the identity-hash winner, and weak overall.
Recommended A. Keep one get() per reader, but add only the fields that reader owns
Option A: keep #14373's single get(docID) per reader, but add a field only when tvFieldToReader names that reader as its owner, and create ParallelFields only when a field is added (+7/-5 lines). The repro passes 3 of 3 and 112 nearby tests pass; the full core suite was not run.
All options and trade-offs4 options · 535 words
One fix was validated with gradle and the repro runner. The other options come from the study, the version-history runs and the 2017 discussion.
A. Keep one get() per reader, but add only the fields that reader owns (validated by the checks) (recommended)
Patch (+7/-5 in ParallelLeafReader.java, the study's "ownerfilter" control): skip a field unless tvFieldToReader.get(fieldName) is the current reader, and create ParallelFields only when a field is added.
if (docFields != null) {
  // Step 3: Aggregate only the fields this reader owns (first reader having a field wins)
  for (String fieldName : docFields) {
    if (tvFieldToReader.get(fieldName) != entry.getKey()) {
      continue;
    }
    Terms vector = docFields.terms(fieldName);
    if (vector != null) {
      if (fields == null) {
        fields = new ParallelFields();
      }
      fields.addField(fieldName, vector);
    }
  }
}
Trade-offs
- Keeps #14373's single
get(docID)per reader, the O(n) fetch #7926 asked for. get()returnsnullwhen no owned field has a vector, as in 10.1.0. With the owner filter, creatingParallelFieldsas soon as a reader returns anyFields(as the #14373 code does) would return an empty, non-nullFieldsfor a document whose only vectors belong to non-owners.- Still reads, and
prefetchstill touches, the vectors of readers whose fields are all owned by others. Option B removes that. - Not run: the full core suite, highlighter or MoreLikeThis tests, any benchmark.
What the checks validated
- Gradle in a scratch worktree at
ea57360912ed(JDK 25, removed after): the repro passes 3 of 3 (stock: 3 of 3 fail);TestParallel*,TestDemoParallelLeafReader,TestTermVectors*,TestAddIndexesandTestCheckIndex: 11 suites, 112 tests, 0 failures (stock: 112 tests, 3 failures, all in the repro); the repro with seed1234ABCD, 10 iterations: 30 of 30 pass (meant to run with assertions off; the command line was not saved);checkGoogleJavaFormatpasses. - The repro runner with the patched class shadowed: the repro passes 3 of 3 with
-eaand-da(also re-run by the fact check); the cross-model reviewer's own two tests pass; the plain program prints the 10.1.0 results.
Fill readerToTermVectors only with readers in tvFieldToReader.values() (the study's suggested variant).
Trade-offs
Avoids reading and prefetching vectors that are thrown away. The owner check in get() is still needed, because the owner of one field can also have vectors for a field another reader owns. Not run.
Loop over tvFieldToReader and ask each owner for its field, as in 10.1.0.
Trade-offs
Correct (as a control on main: the probe passes 5 of 5 with -ea, and the JUnit 3 of 3 with -ea and -da; the study's revert control passed its 6 tests and 29 upstream tests), but it brings back the per-field get(docID, field) calls that #7926 described as O(n^2) in the number of fields.
Let a later reader supply vectors when the owner has none (dsmiley, 2017), or reject overlapping field names (mikemccand, 2017).
Trade-offs
Both are behaviour changes for their own issue. The first also needs the merged FieldInfo to say storeTermVector=true; the second breaks TestDemoParallelLeafReader and users of the documented first-index rule. Neither fixes the regression alone.
Static analysis: an AI tool ran CodeQL's java/unused-container query over Lucene, and it flagged tvFieldToReader as written but never read. An independent AI verifier confirmed the bug with its own tests; the hunt reproduced it on current main and pinned it to #14373 by commit-level runs.
The method in full182 words
Method: static analysis (CodeQL java/unused-container), the study's non-formal baseline tier, run 1, main 7cecf79523 (2026-10-21/22).
- An AI tool ran CodeQL over Lucene. The query flagged
ParallelLeafReader.tvFieldToReaderas a container that is written but never read. The attribution table records it as a blind find: the AI tool was not pointed at this class. - A separate, independent AI verifier read the experiment's test only for its sequence and wrote its own 6 tests (leaf and composite reader, both orders,
TestUtil.checkReader,addIndexes; 4 are deterministic and the 2 both-orders tests could pass by chance only in a rare hash-slot case) plus a probabilisticwrapForMergetest, all failing on main; a revert control and an owner-filter control made them pass, and 29 upstream tests passed in all three variants. - On 2026-10-25 the hunt re-ran a minimal 3-test JUnit on
ea57360912ed(-ea,-da, 25 iterations) and on 10.5.2, 10.2.0 and 10.1.0, built the release matrix and the commit-level A/B runs, searched for prior reports, and obtained a cross-model refute review. For this page, the fix was validated with gradle.
No report found (GitHub issues and PRs, commits, mailing lists, the JIRA archive, the web; 2026-10-25), and upstream has not fixed it. A 2017 review (#8551) foresaw the inconsistency for a draft patch that was never committed.
Searches3 searches
No report of this bug was found, and upstream has not fixed it: termVectors() is unchanged on main, branch_10x and branch_10_6 since #14373, and no open PR touches it. The closest item is a 2017 review (LUCENE-7500, #8551) that foresaw the inconsistency for a draft patch that was never committed: mikemccand warned it "could lead to cases where the FieldInfos returned by ParallelReader disagrees with what the terms(String) and term vectors APIs provide", and the patch was made "functionality identical" before it landed. That is design context, eight years before #14373 introduced the bug, not a report of it. The cross-model fact check argued that a strict reading of the hunt's novelty rule makes the bug "known" because of this overlap; the hunt keeps "new", because no one has reported or discussed the bug that exists today.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs, commits, downstream repos, mailing lists, JIRA archive, web (a scripted prior-report search) | 2026-10-25 | 134 queries: 60 GitHub issue/PR, 6 commit, 4 downstream, 48 mailing-list (dev@, java-user@, issues@, commits@), 10 JIRA, 6 web; terms: ParallelLeafReader, ParallelCompositeReader, ParallelAtomicReader, ParallelFields, termVectors, getTermVectors, tvFieldToReader, readerToTermVectors, the code comments, the CheckIndex message, symptom phrasings | 1,630 distinct hits; the expected #7926 and #14373; no report |
| Manual GitHub and list searches | 2026-10-25 | 33 GitHub searches (incl. created:>2025-03-19 and outside apache/lucene), 3 commit searches, commit listings by path on main, branch_10x and branch_10_6, the changed files of all 412 open PRs, 21 dated list queries (incl. builds@), 6 JIRA queries, 1 web query | #8551 (2017 design discussion), #4810 (origin of tvFieldToReader); open PRs #16847 and #13342 touch the file but not termVectors(); no report |
| Earlier searches | 2026-10-22 and 2026-10-25 | the study's verifier (gh search, 12 phrasings) and the candidate step (a scripted prior-report search, 45 queries) | only the cause #14373 and the issue it closed, #7926 |
Introduced by #14373 (9272d4d29a1, backport 555efca2819, 2025-03-24): 10.2.0 to 10.5.2 and main fail; 9.5.0, 9.12.3, 10.0.0 and 10.1.0 pass. Pinned by runs at each commit and its parent on both branches, and by a revert control.
Versions tested7 rows
Introduced by #14373, "Optimize ParallelLeafReader to improve term vector fetching efficiency" (DivyanshIITB, merged by vigyasharma on 2025-03-24): 9272d4d29a1 on main, which is in no release tag, and the branch_10x backport 555efca2819 (the same ParallelLeafReader.java diff; only the main commit also adds the CHANGES.txt line), which git tag --contains places in exactly 10.2.0 through 10.6.0. The rows below ran a plain-Java probe with three bug scenarios and two controls on SHA-1-checked Maven Central jars (seed DEADBEEF, -ea; -da re-run on 10.1.0, 10.2.0, 10.5.2 and main with identical results). The commit rows compiled lucene-core from source at each commit. Releases before 9.5.0 were not run (the probe needs IndexReader.termVectors()).
git log -L of termVectors() gives 9272d4d29a1 as its last change; nothing since has touched it.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed (unreleased 11.0) | affected | 3 bug scenarios fail, controls pass; JUnit 3 of 3 fail (-ea, -da, gradle, 25 iterations) |
| 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 | affected | the same 3 bug scenarios fail; JUnit 3 of 3 fail on 10.2.0 and 10.5.2 |
| 9.5.0, 9.12.3, 10.0.0, 10.1.0 | not affected | all 5 scenarios OK; JUnit 3 of 3 pass on 10.1.0 |
main: 2e87de1333d (parent) vs 9272d4d29a1 (#14373) | bisect | the parent passes; #14373 fails the 3 bug scenarios |
branch_10x: ac6dcf94dde (parent) vs 555efca2819 (backport) | bisect | the parent passes; the backport fails the 3 bug scenarios |
main with only the pre-#14373 get() loop restored | revert check | probe 5 of 5 OK (-ea); JUnit 3 of 3 pass (-ea and -da) |
main ea57360912ed with fix option A | fix | JUnit 3 of 3 pass (gradle and the repro runner, -ea and -da); 112 nearby tests pass |
An independent verifier, a public-list rerun, the hunt's re-runs and a cross-model refute review confirmed it. Fact checks (one cross-model) and a diagram check found precision errors, which were fixed; the novelty call was kept, with the reason given.
Checks and verdicts455 words
Each check worked from the code or its own runs. The study found and verified the bug; the hunt re-verified it on the current main, dated it, searched for reports, had it reviewed across model families and validated a fix.
| Check | Verdict | What it found |
|---|---|---|
| Study verifier (static-analysis) | new bug, regression from #14373 | Own 6 tests fail on 5 of 5 seeds (4 deterministic; the 2 both-orders tests could pass by chance only in a rare hash-slot case); revert and owner-filter controls pass; wrapForMerge merges broken 14 of 24 on main (CheckIndex level 3), 0 of 24 with each control. |
| Public-list rerun | reproduces on b83101cdd2 | 6 tests, 6 failures, the same tests as the study. |
| Hunt verification | real | Main ea57360912ed fails 3 of 3 with -ea and -da and in 75 of 75 iterated runs; 10.5.2 and 10.2.0 fail; 10.1.0 passes. Corrected the registry wording: the copy fails CheckIndex only at level 2 or 3 (only at level 3 when both readers vector the field). |
| Cross-model refute review, run 1 | no verdict | Ended without a final answer; superseded by run 2. |
| Cross-model refute review, run 2 | real, high confidence | An independent reviewer from another model family (OpenAI GPT-5.6) wrote and ran its own selection and persistence tests and rated the intended-behaviour argument weak. The hunt re-ran those tests: they fail on main (-ea, -da), 10.5.2 and 10.2.0, and pass on 10.1.0 and with the fix. |
| History follow-up | introduced by #14373, first released in 10.2.0 | Ran 14 releases and main and the A/B commit pairs on both branches, plus a revert control on main. |
| Prior-report follow-up | new | 202 queries; found the 2017 design discussion (#8551) but no report. |
| This page's own runs | fix validated | The plain program on main, 10.5.2, 10.1.0 and main with the fix; gradle in a scratch worktree: stock fails 3 of 3, the fix passes 112 of 112 nearby tests and the format check. |
| Independent fact check | real; 3 precision errors, fixed | Re-ran the gradle command, the runner (main -ea/-da, 10.2.0, 10.5.2, 10.1.0, the fix) and the plain program. Found the hash-slot collision case, the level-3-only CheckIndex failure when both readers vector the field, and overstated run-to-run variation; all fixed. |
| Cross-model fact check | real; precision fixes | An independent reviewer from another model family (OpenAI GPT-5.6): 5 errors, 7 overclaims, 5 missing caveats. All fixed except the novelty call ("known" under a strict reading of the novelty rule), which was kept at "new". |
| Diagram check | pass, 8 polish items | Every on-screen value matched the code and the executed trace. The title, the default-level note, two code comments and the label contrast were then changed and re-rendered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 415 KB
Finding record, Lucene and upstream sources, repro files and diagram notes586 words
- Registry title
- ParallelLeafReader.termVectors() no longer honours 'the first reader having the field wins'
- Area
- index / readers
- Priority
- Medium, rank 117: Raised within Medium: a 10.2 regression makes ParallelLeafReader return term vectors from the wrong reader, and addIndexes from it writes an index that fails CheckIndex, a cheap fix that stays narrow because it needs overlapping term-vector fields in an opt-in wrapper.
- Impact class
- data corruption
- Impact note
- Users of the opt-in ParallelLeafReader over readers that share a term-vector field; released 10.2.0-10.6.0 (10.6.0 by reading).
- Summary
- You wrap several readers in a ParallelLeafReader where more than one has term vectors for the same field. You expect term vectors from the first reader that has the field, as documented. Instead, since #14373, they come from the wrong reader, and an index written from it with addIndexes fails CheckIndex.
- Introduced
- #14373 (9272d4d29a1) (2025-03-24)
- First affected version
- 10.2.0
- Affected versions
- 10.2.0-10.5.2 and main [exec]; 10.6.0 [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed in the earlier formal verification study by independent AI checks and a rerun on Lucene main; also a cross-model review that agreed; not yet triaged by a person.
- Found by
- non-formal baseline: static analysis
- Upstream and prior reports
- none found (study searches 2026-10-22; public-list check 2026-10-20..23)
- Lucene commit tested
- main
ea57360912ed(2026-10-25/26): the JUnit repro through the repro runner (-ea,-da, 25 iterations) and through gradle in a scratch worktree, stock and with fix option A (the worktree was removed after the runs); the plain-Java program on main, 10.5.2, 10.1.0 and main with the fix. A plain-Java probe ran on the Maven Central jars 9.5.0, 9.12.3, 10.0.0, 10.1.0 and every release from 10.2.0 to 10.5.2 (SHA-1 checked), and on lucene-core built at the introducing commits and their parents on main and branch_10x. The study reproduced it on7cecf79523and the public-list rerun onb83101cdd2;ParallelLeafReader.javais byte-identical at all three main commits. The fact checks of 2026-10-26 re-ran the gradle command, the runner and the plain program, and measured the hash-slot cases.
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:154-172, 214-237, 326-375 (constructor, ParallelFields, termVectors)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/TermVectors.java:47; SlowCodecReaderWrapper.java:345-376; CheckIndex.java:499, 1114-1132, 4349-4357, 4673, 4738-4757Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/codecs/TermVectorsWriter.java:197-261; codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:896-935, 953-956OpenJDK 25.0.3 sources, java.base/java/util/IdentityHashMap.java:160, 266, 306-316, 435-463, 735-736 (32 slots, linear probing, iteration from slot 0)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/SegmentMerger.java:170-171; CheckIndex.java:4360, 4393-4402
- Who is affected
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/ParallelCompositeReader.java:133; lucene/core/src/test/org/apache/lucene/index/TestDemoParallelLeafReader.java:178-180, 645-651; lucene/test-framework/src/java/org/apache/lucene/tests/util/LuceneTestCaseParent.java:2372-2405Lucene main ea57360912ed: lucene/queries/src/java/org/apache/lucene/queries/mlt/MoreLikeThis.java:714-733; lucene/highlighter/src/java/org/apache/lucene/search/highlight/TokenSources.java:116, 144, 205; lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:696-708Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1064, 1114-1132, 4360; CodecReader.java:347 (checksums at every level)
- Why it looks unintended
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:38-40, 156-164 (TODO at 161-162), 291-296; ParallelCompositeReader.java:30; TermVectors.java:47; CheckIndex.java:4349-4357Lucene main ea57360912ed: lucene/CHANGES.txt:1807, 1908, 1956 (10.2.0 Optimizations); TestDemoParallelLeafReader.java:178-180
- TestParallelLeafReaderTermVectorsOwner.java (JUnit test):
repro/LFV-018/src/org/apache/lucene/index/TestParallelLeafReaderTermVectorsOwner.java(56 lines)
Re-rendered on 2026-10-26 after the fact checks: the title card now says which reader owns a field and that the copy can fail CheckIndex at level 2, the default-level note says that level skips the term-vector test, two code comments say "a vector holding the term" instead of a bare string, and the labels are darker. The alt text was checked against the new final frame.
assets/LFV-018/bug.png(415 KB)