BooleanScorer.scoreWindow computes the window end as Math.min(max, windowBase + 4096) in int. In the last window below 2^31 the sum is exactly 2^31 and wraps to Integer.MIN_VALUE, so the window is empty, nothing advances and score() asks for the same window again, forever.
- A
BooleanQueryof onlySHOULDclauses, run by a collector that needs every match (a count, a sort, facets), is scored byBooleanScorer. The default relevance top-k search uses a different scorer. BooleanScorerworks in windows of 4,096 doc IDs. It finds the window of the next match,windowBase = doc & ~4095, and ends it atwindowMax = min(max, windowBase + 4096).- It collects every clause's matches below
windowMax, then moves to the window of the next match, until no clause has a match left.
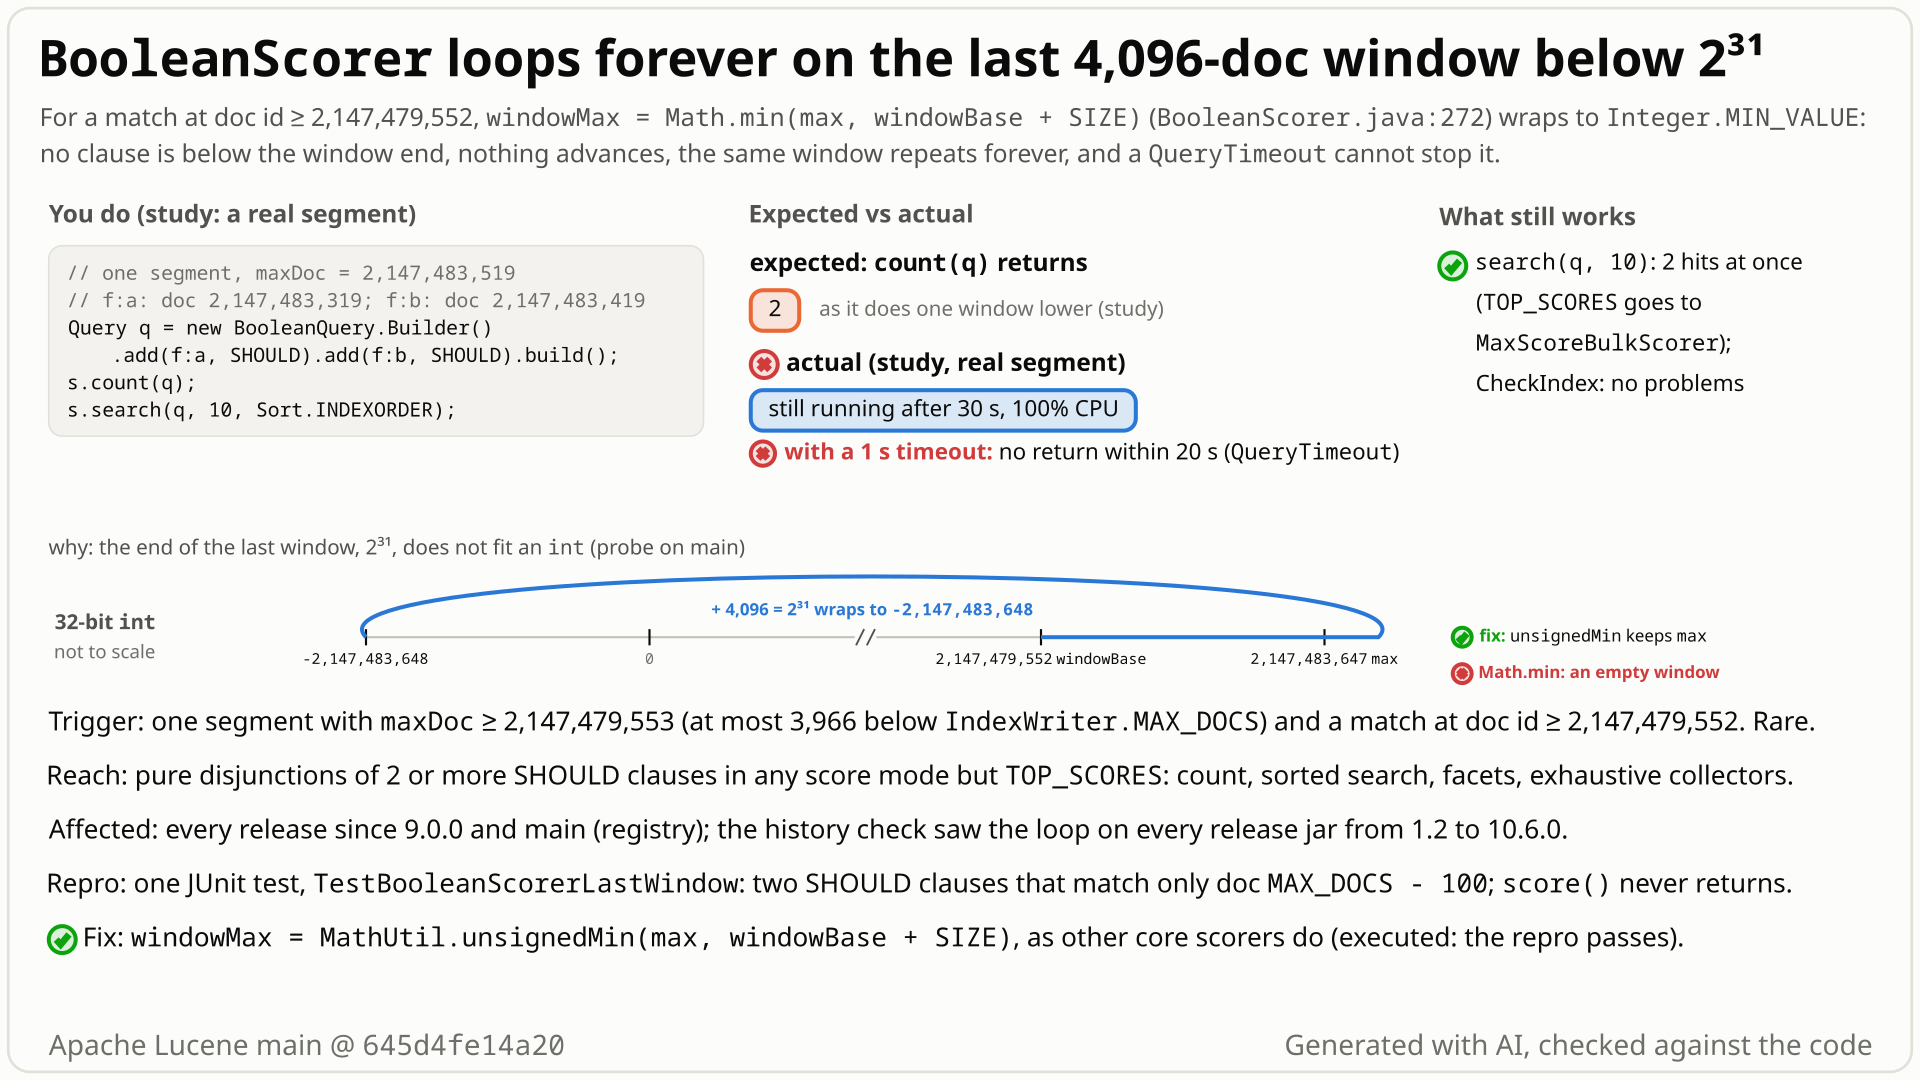
int. With a negative end the window is empty, nothing advances, and the scorer re-enters it forever. Select the still to open it at full size. Generated with AI, checked against the code.- Index
IndexWriter.MAX_DOCS= 2,147,483,519 documents with the default config into one segment: a plainaddDocumentloop of empty documents andcommitgave one 30 MB segment thatCheckIndexreports clean. Doc 2,147,483,319 hasf:a, doc 2,147,483,419 hasf:b. - Run
searcher.count(f:a OR f:b), twoSHOULDterm clauses. You expect 2 at once; the relevance searchsearch(q, 10)on the same index returns both docs in 0.015 s. - Instead
countnever returns (still running after 20 s, one core busy), and neither doessearch(q, 10, Sort.INDEXORDER). With a 1 sQueryTimeoutset, the count is still running after 20 s. With a one-line fix,countreturns 2 in 0.006 s. - Why: these searches use
BooleanScorer, which works in windows of 4,096 doc IDs. The window of doc 2,147,483,419 starts at 2,147,479,552, so its end is 2^31 = 2,147,483,648, one more than anintholds: it wraps to -2,147,483,648. No doc is below a negative end, so nothing is collected, no iterator moves, and the scorer re-enters the same window forever.
Only indexes with one segment of more than 2,147,479,552 documents, at most 3,966 below Lucene's hard limit. There, every pure SHOULD disjunction run as a count, sort, facet or other exhaustive collection that matches a document at doc ID 2,147,479,552 or above hangs a search thread. Default relevance top-k and single-term queries are safe.
Mechanism, terms and numbers925 words
BooleanScorer, the bulk scorer for pure disjunctions in every score mode except TOP_SCORES (with minShouldMatch > 1 only for dense clauses), scores a segment in windows of 4,096 doc IDs. For the window of the next match it computes windowMax = Math.min(max, windowBase + SIZE) in int. For a match at doc ID 2,147,479,552 (2^31 - 4096) or above, the sum is 2^31 and wraps to Integer.MIN_VALUE, so the window is empty: nothing is collected, no iterator advances, and score() gets the same window back forever. IndexWriter.MAX_DOCS is 2,147,483,519, so 3,967 legal doc IDs sit in that window, and a segment with maxDoc of at least 2,147,479,553 and a match there is enough. On a real, CheckIndex-clean segment of MAX_DOCS documents written with nothing but addDocument and commit, IndexSearcher.count(f:a OR f:b), an index-order sort and a count under a 1 s QueryTimeout were all still running after 20 s, while search(q, 10) returned in 0.015 s; the timeout cannot help because TimeLimitingBulkScorer checks it only between calls. The one-line fix Math.min -> MathUtil.unsignedMin, the helper the other windowed bulk scorers in core's search package use, makes all three return correct results. The unguarded sum is as old as BooleanScorer; every published release jar loops on the same layout.
BooleanScorer.java on main 645d4fe14a20: SIZE = 1 << 12 = 4,096 and MASK = SIZE - 1 (:33-35); in scoreWindow (:270-272):
final int windowBase = top.doc & ~MASK; // find the window that the next match belongs to
final int windowMin = Math.max(min, windowBase);
final int windowMax = Math.min(max, windowBase + SIZE);
For any doc in the last window, windowBase is 2,147,479,552 and windowBase + SIZE is 2,147,479,552 + 4,096 = 2^31, which as an int is Integer.MIN_VALUE.
| match at doc ID | windowBase | windowBase + SIZE in int | outcome |
|---|---|---|---|
| below 2,147,479,552 | a multiple of 4,096 | correct, at most 2,147,479,552 | window scored, scorer moves on |
| 2,147,479,552 ... 2,147,483,518 (3,967 legal IDs) | 2,147,479,552 | -2,147,483,648 | empty window, endless loop |
score()(:295-303) advances the clauses to the doc and loopswhile (top.doc < max) top = scoreWindow(...).windowMaxisInteger.MIN_VALUE, sohead.top().doc < windowMaxis never true (:277): one lead only.- With
minShouldMatch == 1that takes the single-scorer path (:281-286). Thereend = Math.max(windowMax, Math.min(max, nextWindowBase))is 2,147,479,552, the other clause's window base (:247-248), which is not above the doc: the collect loop runs zero times and the clause stays put (:256-261). It goes back into the queue. score()gets the same top back and callsscoreWindowagain. The only work per round is twosetScorercalls and a priority-queue pop and insert.- With
minShouldMatch > 1the multiple-scorer path testscandidate.doc < windowMax(:211), which is never true either; nothing is scored (run in the study's direct tests). Needing scores does not change the path: withminShouldMatch == 1the single-scorer path of step 3 is taken with or without scores, becausemaxFreqis always 1 in this window.
TimeLimitingBulkScorerchecksqueryTimeout.shouldExit()before each call to the wrappedscore(TimeLimitingBulkScorer.java:70-86); the call that enters the last window never returns (run). Its smaller per-callmax(:73) does not help:Math.minof any positivemaxandInteger.MIN_VALUEis stillInteger.MIN_VALUE.ExitableDirectoryReaderchecks when doc values iterators move (ExitableDirectoryReader.java:110-331, check at:486-497), when vectors are searched or iterated (:333-479,:499-703), when points are visited (:705-942) and when terms are enumerated (:944-1018); the loop reads nothing from the index (by reading).- The loop does no I/O and checks no interrupt flag, so
Thread.interrupt()does not stop it (by reading).
BooleanScorer is built in one place, BooleanScorerSupplier.optionalBulkScorer (:337), used when the query has no MUST or FILTER clause (:210-232): always with minShouldMatch <= 1 (cost threshold -1), with minShouldMatch > 1 only for dense clauses (cost >= maxDoc / 3). TOP_SCORES goes to MaxScoreBulkScorer instead (with minShouldMatch > 1 to the fallback scorer; :315-328). Every other mode builds BooleanScorer: TotalHitCountCollector (COMPLETE_NO_SCORES), TopFieldCollector for a non-relevance sort (TOP_DOCS or COMPLETE...), FacetsCollector (COMPLETE or COMPLETE_NO_SCORES), and relevance top-k with exact hit counting (COMPLETE; by reading). With MUST_NOT clauses, ReqExclBulkScorer wraps it when the positive cost is above 0.3% of maxDoc (by reading, not run).
IndexSearcher.count first tries a two-term shortcut (IndexSearcher.java:506-520): with no deletions and two TermQuery clauses, if one count is 0 or below 10% of the other, it counts without BooleanScorer. Otherwise, and for 3+ clauses, non-term clauses or a reader with deletions, it collects with a TotalHitCountCollector (:525-528), which asks Weight.count for each leaf (TotalHitCountCollector.java:48). That is -1 for two clauses that each match some but not all docs, so the leaf is collected with BooleanScorer. In every run here both terms match one doc. Sorts and facets have no shortcut.
The other windowed bulk scorers in core's search package guard the same sum with MathUtil.unsignedMin (ConstantScoreBulkScorer, DisjunctionMaxBulkScorer, MaxScoreBulkScorer, DenseConjunctionBulkScorer, BlockMaxConjunctionBulkScorer, TimeLimitingBulkScorer, and BitSetDocIdStream, which BooleanScorer itself uses for its window) or a long cast (ReqExclBulkScorer). Outside core, DrillSidewaysScorer in the facet module has the same unguarded window sum (a separate bug, LFV-383).
Exposure and likelihood268 words
- Who. Applications with one segment of more than 2,147,479,552 documents. The whole index is capped at
IndexWriter.MAX_DOCS= 2,147,483,519, so that means an index at most 3,966 documents below the hard limit with almost all of it in one segment. A plainaddDocumentloop of empty documents under the default config produced one (a single flushed segment; with real documents the writer would flush many segments, an inference);forceMerge(1), the general route, does too, because TieredMergePolicy drops its segment-size cap for a single-segment forced merge, and so doesaddIndexes(the study's segment). - Settings. Default codec,
IndexWriterConfigandIndexSearcher. Only the size is unusual. - Queries. Pure
SHOULDdisjunctions of 2 or more clauses with a match in the last window, run as a count, an index-order or field sort, a facet collection or any other exhaustive collection. Not affected: default relevance top-k (search(q, n),TOP_SCORES, with the default hit-count threshold), single-term queries, andFILTER+SHOULDqueries (another scorer). - Effect. The call never returns and keeps one core busy. Hits before the last window are collected first, then the loop starts. No exception was thrown in any run, the loop logs nothing (by reading), and
IndexSearcher#setTimeoutdoes not help (run). Every such request takes a search thread for good (an inference, not run). The index is not touched. - Likelihood: contrived. Almost no deployment holds 2.1 billion documents in one segment; one that does hits it on every such query, deterministically.
- Mitigation until fixed (by reading, not run): keep segments at or below 2,147,479,552 documents, for example do not
forceMerge(1)an index near the limit.
One JUnit test in org.apache.lucene.search (it builds the package-private BooleanScorer, as Lucene's own TestBooleanOr does): two clauses that both match only doc 2,147,483,419 (MAX_DOCS - 100). The collector fails after 100 setScorer calls instead of hanging; a correct run needs 1.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBooleanScorerLastWindow extends LuceneTestCase {

  public void testTwoClausesInLastWindow() throws Exception {
    int doc = IndexWriter.MAX_DOCS - 100;
    List<Scorer> clauses = new ArrayList<>();
    for (int i = 0; i < 2; i++) {
      DocIdSetIterator it = DocIdSetIterator.range(doc, doc + 1);
      clauses.add(new ConstantScoreScorer(1f, ScoreMode.COMPLETE_NO_SCORES, it));
    }
    List<Integer> collected = new ArrayList<>();
    LeafCollector collector =
        new LeafCollector() {
          int setScorerCalls;

          @Override
          public void setScorer(Scorable scorer) {
            assertTrue(
                "score() makes no progress: expected to collect [" + doc + "], got " + collected,
                ++setScorerCalls < 100);
          }

          @Override
          public void collect(int d) {
            collected.add(d);
          }
        };
    // expected: collects [doc] and returns; actual: loops forever, its window end 2^31 overflows
    new BooleanScorer(clauses, 1, false)
        .score(collector, null, 0, DocIdSetIterator.NO_MORE_DOCS);
    assertEquals(List.of(doc), collected);
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestBooleanScorerLastWindow -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
score()collects doc 2,147,483,419 and returns.- Observed
AssertionError: score() makes no progress: expected to collect [2147483419], got [], fromBooleanScorer.scoreWindowSingleScorer(line 255), with assertions on and off.
More files, environment, full output503 words
One test class, one method, single thread, nothing random. It sits in org.apache.lucene.search because BooleanScorer and its constructor are package-private; upstream TestBooleanOr builds it the same way. Everything else is public API. Two ConstantScoreScorer clauses over DocIdSetIterator.range(doc, doc + 1) stand in for a segment of about 2^31 documents, which takes minutes to build.
BooleanScorer calls setScorer twice per round of the loop, so the collector's bound of 100 calls turns the endless loop into a failure in about a second. Pass -Ptests.asserts explicitly, because Lucene's build picks it at random from the seed; the result is the same both ways.
Formatting: before committing, run ./gradlew tidy; google-java-format joins the two-line new BooleanScorer(...).score(...) call onto one line. With that the test passes core's format, ECJ and forbidden-apis checks, still fails on stock main and passes with the fix.
Regression test: this same test, as its own class or as a method of TestBooleanOr. It drives only the minShouldMatch = 1 single-scorer path, so a fix made only in scoreWindowSingleScorer would pass it too; the one-line fix is in scoreWindow, which both paths share, and the study's direct tests cover minShouldMatch 2 with and without scores.
At real scale (public API only, not the repro): one thread, default IndexWriterConfig, 2,147,483,519 addDocument calls (all empty except doc 2,147,483,319 with f:a and doc 2,147,483,419 with f:b), commit: one segment, 29.8 MB, 424 s, CheckIndex -level 2 clean. Then count, search(q, 10, Sort.INDEXORDER) and a count under a 1 s QueryTimeout on f:a OR f:b, each with a 20 s watchdog.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; 10.6.0 and 10.5.2: fail; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the arithmetic is plain int) |
cp $REPRO/TestBooleanScorerLastWindow.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestBooleanScorerLastWindow -Ptests.seed=DEADBEEF -Ptests.asserts=true
# same failure with -Ptests.asserts=false
# gradle, main 645d4fe14a20, seed DEADBEEF, -Ptests.asserts=true (identical with false)
TestBooleanScorerLastWindow > testTwoClausesInLastWindow FAILED
    java.lang.AssertionError: score() makes no progress: expected to collect [2147483419], got []
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:E8B115C49A9AE21D]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.search.TestBooleanScorerLastWindow$1.setScorer(TestBooleanScorerLastWindow.java:40)
        at org.apache.lucene.search.BooleanScorer.scoreWindowSingleScorer(BooleanScorer.java:255)
        at org.apache.lucene.search.BooleanScorer.scoreWindow(BooleanScorer.java:285)
        at org.apache.lucene.search.BooleanScorer.score(BooleanScorer.java:300)
        at org.apache.lucene.search.TestBooleanScorerLastWindow.testTwoClausesInLastWindow(TestBooleanScorerLastWindow.java:52)
1 test completed, 1 failed

# releases 10.6.0 and 10.5.2: the same message with assertions on and off, at BooleanScorer.java:284 <- :314 <- :329

# real segment, public API, main 645d4fe14a20, -da (the same with -ea)
segments=1 maxDoc=2147483519 numDocs=2147483519 leaf=_0(11.0.0):c2147483519
[search(f:a OR f:b, 10) [TOP_SCORES]] returned in 0.015 s: totalHits=2 hits docs=2147483319 2147483419
[count(f:a OR f:b)] HUNG: still running after 20000 ms; stack:
    at org.apache.lucene.search.BooleanScorer.scoreWindow(BooleanScorer.java:286)
    at org.apache.lucene.search.BooleanScorer.score(BooleanScorer.java:300)
    at org.apache.lucene.search.IndexSearcher.searchLeaf(IndexSearcher.java:852)
[search(f:a OR f:b, 10, Sort.INDEXORDER)] HUNG: still running after 20000 ms (same frames)
[count(f:a OR f:b) with a 1 s QueryTimeout] HUNG: still running after 20000 ms; stack:
    at org.apache.lucene.search.BooleanScorer.score(BooleanScorer.java:300)
    at org.apache.lucene.search.TimeLimitingBulkScorer.score(TimeLimitingBulkScorer.java:83)
    at org.apache.lucene.search.IndexSearcher.searchLeaf(IndexSearcher.java:852)
# same index, BooleanScorer with the fix
[count(f:a OR f:b)] returned in 0.006 s: 2
[search(f:a OR f:b, 10, Sort.INDEXORDER)] returned in 0.009 s: totalHits=2 hits docs=2147483319 2147483419
[count(f:a OR f:b) with a 1 s QueryTimeout] returned in 0.001 s: 2IndexWriter.MAX_DOCS(2,147,483,519) is the only documented document limit, and Lucene's own@Monstertest builds and searches a segment of exactly that size.BulkScorer.scoremust collect the matches in[min, max)and return; this call never returns.- Core's other windowed bulk scorers guard the same window sum with
MathUtil.unsignedMinor alongcast;BooleanScorernever had a guard.
The full argument229 words
- The only documented limit is
MAX_DOCS. "Hard limit on the maximum number of documents that may be added to the index" (IndexWriter.java:201-208). LUCENE-5843 added it so that adding more throws "instead of silently creating an unusable index" (CHANGES.txt).IndexReader.maxDoc()is "one greater than the largest possible document number", so doc ID 2,147,483,518 is legal. No search-side limit is documented. - Lucene's own test builds this state.
TestIndexWriterMaxDocs.testExactlyAtTrueLimit(@Monster) adds exactlyMAX_DOCSdocuments, searches them before and afterforceMerge(1), and asserts that docMAX_DOCS - 1comes first in a reverse doc-ID sort. It uses a singleTermQuery, which never reachesBooleanScorer. - The
BulkScorercontract.score"Collects matching documents in a range and return[s] an estimation of the next matching document which is on or aftermax"; the return value "must be >=max". - The project treats this overflow as a defect. #14750 (2025) added
MathUtil#unsignedMinbecause dividing the doc ID space into windows "is prone to integer overflows if the size of the window is greater thanInteger.MAX_VALUE - windowStart". The scorers it touched already hadlongcasts that it replaced;BooleanScorernever had a guard and was not in it. - Nothing describes the hang. No comment, test,
CHANGESorMIGRATEentry; no commit message on the file mentions overflow; the LUCENE-6184 discussion does not discuss it.
The devil's-advocate check136 words
The strongest case for "not a bug": the scale is absurd (one segment of 2.1 billion documents), BooleanScorer is package-private and the minimal test builds it directly, and the cross-model refute review (OpenAI GPT-5.6) returned "not real".
Why it fails: the size is legal by Lucene's own documentation and its own @Monster test; the hang shows through IndexSearcher.count, Sort.INDEXORDER and a timed count on a real index written with plain addDocument, and the one-line fix makes all three return. The cross-model verdict was procedural: it could not open any file or run anything and saw only the claim's text, and it gave low confidence; its one substantive point, that "only its package-private direct test is visible in the supplied text", is answered by the real-index run. Scale argues for low priority, not for intent.
Recommended Compute the window end with MathUtil.unsignedMin
In BooleanScorer.scoreWindow, compute the window end with MathUtil.unsignedMin(max, windowBase + SIZE) instead of Math.min, the helper the other windowed bulk scorers in core's search package use. The wrapped sum then counts as larger than any max, so the last window ends at max. With it the repro and all 2,340 core search tests pass, with assertions on and off.
import org.apache.lucene.util.MathUtil;
...
// BooleanScorer.scoreWindow, instead of: Math.min(max, windowBase + SIZE)
final int windowMax = MathUtil.unsignedMin(max, windowBase + SIZE);
All options and trade-offs4 options · 406 words
One fix was built and validated through gradle in a scratch worktree of 645d4fe14a20, and the same line on the real segment; the long form is equivalent; clamping max alone does not help.
BooleanScorer.java:272 plus one import, +2/-1 lines.
import org.apache.lucene.util.MathUtil;
...
// BooleanScorer.scoreWindow, instead of: Math.min(max, windowBase + SIZE)
final int windowMax = MathUtil.unsignedMin(max, windowBase + SIZE);
Trade-offs
Integer.MIN_VALUEis 2^31 as an unsigned value, above any legalmax(at mostNO_MORE_DOCS= 2^31 - 1), so the last window ends atmax; every other window is unchanged. Exhausted clauses sit atNO_MORE_DOCS, which is not below that end.- Cost: one unsigned compare per 4,096-doc window.
- The same helper and pattern as
ConstantScoreBulkScorer,DisjunctionMaxBulkScorerandMaxScoreBulkScorer.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle--offline, OpenJDK 25.0.3, seed DEADBEEF. Stock: the repro fails with assertions on and off. - With the fix: the 9 core
TestBoolean*suites, the repro included, run 140 tests with 0 failures; all coreorg.apache.lucene.search.*tests (215 suites, 2,340 tests, includingTestTimeLimitingBulkScorerandTestTotalHitCountCollector) pass; both with assertions on and off. Core'scheckGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestpass. Other modules and the full core suite were not run. - On the real 2,147,483,519-document segment the same line makes
countreturn 2 in 0.006 s, the index-order sort both docs in 0.009 s and the timed count 2 in 0.001 s.
final int windowMax = (int) Math.min((long) max, (long) windowBase + SIZE);, the form ReqExclBulkScorer uses.
Trade-offs
Same behaviour; the recommended form reuses the helper.
What the checks validated
Not run on main. The version-history runs computed each era's window-end line in long on 1.2, 2.4.1, 4.10.4, 5.0.0 and 5.1.0, and the probe then finished.
The direction of open PR #16952 (pass the leaf maxDoc instead of NO_MORE_DOCS).
Trade-offs
The sum overflows whatever max is: Math.min(max, Integer.MIN_VALUE) is Integer.MIN_VALUE for every max.
What the checks validated
Run on 645d4fe14a20: the repro with max = IndexWriter.MAX_DOCS fails the same way.
Keep segments at or below 2,147,479,552 documents, for example do not forceMerge(1) an index near the limit.
Trade-offs
By reading only, not run.
A service that relies on IndexSearcher#setTimeout to bound slow requests is not protected here: the stuck call never reaches a timeout check, so each such request keeps a search thread busy.
A study of integer overflows near Lucene's size limits used CodeQL to list every unguarded int window sum in the search code, and flagged windowBase + SIZE in BooleanScorer. A Z3 bit-vector query found the wrap in 0.011 s and proved the window correct below 2^31 - 4,096; a test and a run on a real segment confirmed the hang.
The method in full210 words
Method: formal (a static inventory, then SMT queries, then dynamic checks).
- Inventory. A CodeQL query listed every
intsum "x + C" (C >= 64) in the search, util, codecs and index code that is not wrapped inunsignedMinor alongcast: 63 rows. One waswindowBase + SIZEinBooleanScorer.scoreWindow. - SMT. A Z3 bit-vector query with the documented limit
maxDoc <= IndexWriter.MAX_DOCSas the precondition found a counterexample in 0.011 s (topDoc = 2147480836); a second query provedwindowMax > topDocfor everytopDoc < 2^31 - 4096, and a third that in the overflow case the single-scorer path collects nothing. cvc5 agreed. - Confirmation. A direct JUnit failed on main; an independent study verifier wrote 16 tests (12 through
IndexSearcherwith aFilterLeafReaderreportingmaxDoc = MAX_DOCSand 4 directBooleanScorertests; 10 bug tests and 6 controls in all) and built a real 2,147,483,519-document segment withaddIndexes, on which count and the index-order sort hung and the fix returned at once. - Then a main refresh, a current-main reproducer, a cross-model review (OpenAI GPT-5.6, which could not run), a tie-breaker who built a segment with plain
addDocument, a history sweep over every release jar, a prior-report search and a repro-minimization step followed.
No prior report found (2026-10-31: 98 tool queries over GitHub, the JIRA archive, mailing lists, downstream trackers and the web, 26 manual GitHub searches and the files of all 410 open PRs). #14750 guarded the same overflow in other scorers only; open PR #16952 does not fix it.
Searches2 searches
Verdict new: the recorded searches found no issue, PR, commit, JIRA entry, list thread, downstream report or web page that describes the windowBase + SIZE wrap or a disjunction hang near 2^31 documents. Related, not reports: #14750 (unsignedMin, BooleanScorer.java not in it); #16952 (open, 2026-10-30, leaf maxDoc as the bulk-scoring bound; does not touch BooleanScorer.java); #16856/#16855 (another scorer's window bound, a slowdown without overflow); #16847 (open draft, more than 2^31 documents per index; segments stay capped at MAX_DOCS); LUCENE-700 (#1775, 2006, an old bucket-list loop, "Cannot Reproduce"); a 2013 downstream thread with threads at 100% CPU in BooleanScorer.score, caused by a downstream child scorer. Open PRs #16851, #16542 and #14357 touch nearby code but not scoreWindow.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene incl. the migrated JIRA archive), Apache JIRA | 2026-10-22 | the study verifier: about 25 phrasings (e.g. "BooleanScorer overflow", "BooleanScorer infinite loop", "BooleanScorer MAX_DOCS", "unsignedMin") plus JIRA JQL | no report; related: #14750, #15324, #16847, #16511, LUCENE-700 |
| GitHub issues, PRs and commits (apache/lucene; Elasticsearch, OpenSearch, Solr), dev@/java-user@/issues@/commits@ lists, the JIRA archive, the web | 2026-10-31 | scripted prior-report search (98 queries, 246 hits), 26 manual apache/lucene queries, 12 downstream, 9 list and 8 web queries, the changed files of all 410 open PRs, git log -S and --grep in the full history | no report; related: #14750, #16952, #16856/#16855, #16847, LUCENE-700 |
As old as BooleanScorer: the window end has been an unguarded int sum since the 2001 import (release 1.0.1); LUCENE-6184 (5.1.0, 2015) wrote today's line. A direct probe loops on all 164 published release jars from 1.2 to 10.6.0 and on main. Not fixed upstream.
Versions tested7 rows
Introduced by bd3948c539ec "Initial revision" (2001-09-18, svn r149570), the import of the Lucene sources into the Apache repository: the window end was already an unguarded int sum. Later rewrites kept it, among them 6f8347c6fef (2004, end += BucketTable.SIZE), 10a852570a1 (LUCENE-6179, 5.0.0), cb3ec682d41 / branch_5x 5c9b5e7ea4e (LUCENE-6184, 2015-01-19, today's windowMax = Math.min(max, windowBase + SIZE), first released in 5.1.0), and #13931 (10.1.0, same line). #13605 (2024; 8d4f7a6e99d on main, backport 24de36cc28c in 9.12.0) raised the window from 2,048 to 4,096 IDs, which moved the trigger from the last 1,919 legal IDs to the last 3,967.
Reach through IndexSearcher differs by era (by reading): 8.0.0 on, every score mode except TOP_SCORES; 5.0.0-7.7.3, every score mode; 1.9-2.4.1, opt-in only. Whether old IndexWriters could build such a segment was not checked.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; 10.6.0; 10.5.2 | affected | minimal test: no progress after 100 setScorer calls, nothing collected, with assertions on and off |
main 645d4fe14a20, real segment | public API | 2,147,483,519 docs: count, Sort.INDEXORDER and a count with a 1 s timeout still running after 20 s; with the fix 0.006 s, 0.009 s and 0.001 s |
| 9.12.3 | IndexSearcher | the study's reader wrapper (maxDoc = MAX_DOCS), assertions off: 7 bug tests fail, including count and the timeout case; 5 controls pass |
| 1.2-10.6.0 (164 release jars) | direct probe | the per-era probe loops on every jar with assertions off; the same layout 4,096 IDs lower finishes; with the window end in long it finishes (1.2, 2.4.1, 4.10.4, 5.0.0, 5.1.0) |
5.1.0-5.3.2 with -ea | fails loudly | Lucene's own assert scorer.next < max trips on the wrapped end first (run on 5.1.0, 5.2.1, 5.3.0 and 5.3.2); with -da it loops; from 5.4.0 -ea loops too |
| 1.0.1, 1.4, 1.9 | read | no published jar; the same unguarded form |
upstream main 2f424fd428da | read | the same BooleanScorer.java as 645d4fe14a20 |
Reproduced by the study verifier, a current-main reproducer, a tie-breaker who built a real 2,147,483,519-document segment with plain addDocument, the history sweep, the repro-minimization step and this doc. The cross-model refute review (OpenAI GPT-5.6) could not start any command and returned a procedural, low-confidence "not real".
Checks and verdicts341 words
Every reproduction ran on stock builds; the fix checks ran with the patched BooleanScorer. The cross-model reviewer itself executed nothing; a separate run executed the repro on 10.5.2 with assertions off, and it failed as claimed.
| Check | Verdict | What it found |
|---|---|---|
| Study finder (CodeQL inventory, Z3 bit-vector queries) | candidate | Counterexample in 0.011 s; window proved correct below 2^31 - 4096; a direct JUnit fails on main with and without -ea, and its control one window lower passes. |
| Study verifier | real, new | 16 tests: 12 through IndexSearcher with a FilterLeafReader wrapper (7 bug tests fail, 5 controls pass) and 4 direct BooleanScorer tests (3 bug tests fail: msm 2, msm 2 with scores, msm 1 with scores; 1 control passes); real segment via addIndexes: count and index-order sort hang, TOP_SCORES returns; with the fix 16/16. |
| Main refresh (a9779ef3c193) | still reproduces | The study tests: 16 run, 10 failed, the same set. |
| Current-main reproducer | real | Minimal test fails on 645d4fe14a20 and 10.5.2 with -ea and -da; the fix passes. |
| Cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real (low, procedural) | It could not open any file or run anything and saw only the claim's text. Its notes call the arithmetic "internally plausible". Not a refutation. A separate run executed the minimal test on 10.5.2 with -da: it failed as claimed. |
| Tie-breaker | real (high) | Real segment from plain addDocument: count, index-order sort and timed count hang with -ea and -da, the fix returns all three; 10.6.0 and 10.5.2 fail; 9.12.3 via the study wrapper. |
| History follow-up | every release affected | Per-era probe on 164 release jars and main: all loop, all controls pass; long fix checks on 5 releases. |
| Repro minimization (2026-10-29) | verified | The one-test repro fails on 645d4fe14a20 with -ea and -da; the fix passes. |
| This doc (2026-10-31) | reproduced, fix validated | Gradle on 645d4fe14a20: the repro fails both ways; with the fix 2,340 core search tests and core lint pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 442 KB
Finding record, Lucene and upstream sources, repro files and diagram notes941 words
- Registry title
- BooleanScorer loops forever on the last 4096-doc window of a segment of about 2^31 documents, and a query timeout cannot stop it
- Area
- search / scoring
- Priority
- Low, rank 968: BooleanScorer loops forever, and timeouts cannot stop it, on the last window of a segment holding about 2^31 docs, severe, but at an extreme scale that almost no deployment reaches.
- Impact class
- hang
- Impact note
- Holders of one segment filled to within 3,967 docs of IndexWriter.MAX_DOCS (for example a read-only shard force-merged to one segment) that run count, index-order or field-sorted, facet or other exhaustive disjunction queries; default configuration otherwise; deterministic once such a segment exists; every release from 1.0.1 (1.2 the oldest executed) to 10.6.0 and main.
- Summary
- You run a pure disjunction of two or more SHOULD clauses as a count, an index-order or field sort, or a facet collection (any score mode other than TOP_SCORES) on a segment with maxDoc >= 2,147,479,553 and a match in its last 3,967 doc ids. You expect the search to return. Instead windowMax = Math.min(max, windowBase + 4096) wraps to Integer.MIN_VALUE, no iterator advances and the thread spins at 100% CPU forever: on a real, CheckIndex-clean segment of 2,147,483,519 docs, count(f:a OR f:b) and an index-order sort hung while search(q, 10) returned at once.
- Introduced
- bd3948c539ec1065db8b05b433ea55dbf844ff27 ('Initial revision', svn r149570, 2001-09-18), the import of the Lucene sources into the Apache repository: BooleanScorer's window end was already an unguarded int sum (currentDoc = Math.min(currentDoc+BucketTable.SIZE, maxDoc)); every later rewrite kept an unguarded form, and LUCENE-6184 (cb3ec682d41 on trunk, 5c9b5e7ea4e on branch_5x, 2015-01-19, first released in 5.1.0) wrote today's line windowMax = Math.min(max, windowBase + SIZE) [read: git log, git blame and the BooleanScorer.java blob at each release tag; exec: the per-era probe loops on every published release jar from 1.2 to 10.6.0, including 5.0.0, the release before LUCENE-6184] (2001-09-18 (the import of the Lucene sources); today's text of the line 2015-01-19 (LUCENE-6184))
- First affected version
- 1.0.1 [read: no 1.0.1 jar is published; its BooleanScorer.java is the same blob as in bd3948c539e and in 1.2]; the earliest release executed is 1.2 [exec, -ea and -da: the probe loops, its control 4,096 ids lower finishes, and the window end computed in long finishes]; no older release is in the repository
- Affected versions
- every release from 1.0.1 to 10.6.0 (167 releases) and main 645d4fe14a20 [exec: a per-era direct probe loops on all 164 published release jars from 1.2 to 10.6.0 and on main with -da (25 representative targets also with -ea; on 5.1.0-5.3.2 Lucene's own assert trips first with -ea), while the same layout 4,096 ids lower finishes; the minimal test fails on 10.1.0, 10.5.2, 10.6.0 and main with -ea and -da; through IndexSearcher on 9.12.3 (the study's reader wrapper) and on a real 2,147,483,519-document segment on main; read: 1.0.1, 1.4 and 1.9 have no published jar]; the trigger window was 1,024 ids before 1.9 and 2,048 from 1.9 to 9.11.1 (4,096 since #13605, 9.12.0), and reach through IndexSearcher differs by era (opt-in only in 1.9-2.4.1) [read]; not fixed upstream (main 2f424fd428da, 2026-10-30)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed in the earlier formal verification study by independent AI checks and a rerun on Lucene main; also a cross-model review that could only read the code (its low-confidence “not real” is procedural); not yet triaged by a person.
- Found by
- formal: Z3
- Upstream and prior reports
- none found (study searches 2026-10-22; public-list check 2026-10-20..23)
- Lucene commit tested
- main
645d4fe14a20(2026-10-31): the minimal test fails through gradle in a scratch worktree with assertions on and off; with the recommended fix it passes, and the coreTestBoolean*suites (140 tests) and all coreorg.apache.lucene.search.*tests (215 suites, 2,340 tests) pass with assertions on and off, as do core's format, ECJ and forbidden-apis checks. Releases 10.6.0 and 10.5.2 fail the minimal test both ways. The public-API runs on a real segment of 2,147,483,519 documents were done on645d4fe14a20by the tie-breaker, with assertions on and off. A per-era probe ran on all 164 published release jars from 1.2 to 10.6.0.
- Finding record
SECURITY.md:38, 50 (threat model)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/BooleanScorer.java:33-35, 151, 205-216, 247-248, 255-264, 270-292, 295-303a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/BooleanScorerSupplier.java:198-266, 308-337, 339-375a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TimeLimitingBulkScorer.java:70-86; search/IndexSearcher.java:506-528, 643, 846-852, 1097-1099a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/ExitableDirectoryReader.java:110-331, 333-479, 486-497, 499-703, 705-942, 944-1018a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TotalHitCountCollector.java:37-38, 48; search/TopFieldCollector.java:342-353; search/TopScoreDocCollector.java:58-60; search/BooleanWeight.java:167-171, 255-269a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/FacetsCollector.java:96-97a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/ConstantScoreBulkScorer.java:131-132; search/DisjunctionMaxBulkScorer.java:90; search/MaxScoreBulkScorer.java:216, 360, 407, 424; search/DenseConjunctionBulkScorer.java:198, 214; search/BlockMaxConjunctionBulkScorer.java:102; search/TimeLimitingBulkScorer.java:73; search/BitSetDocIdStream.java:34; search/ReqExclBulkScorer.java:61a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSidewaysScorer.java:479, 539, 562-564 (unguarded window sum, LFV-383)
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208; index/TieredMergePolicy.java:790-791a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/BooleanScorerSupplier.java:315-328 (TOP_SCORES), 339-375 (FILTER + SHOULD)
- Minimal repro
a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/search/TestBooleanOr.java:244 (upstream builds BooleanScorer directly)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208; index/IndexReader.java:300-305; search/BulkScorer.java:30-76a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:12045-12049 (LUCENE-5843)a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/index/TestIndexWriterMaxDocs.java:46-90
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/util/MathUtil.java:196-199; search/ReqExclBulkScorer.java:61
- Diagrams
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/BooleanScorer.java:33-35, 270-272, 295-303
- TestBooleanScorerLastWindow.java (one test class):
repro/LFV-048/src/org/apache/lucene/search/TestBooleanScorerLastWindow.java(55 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed runs.
assets/LFV-048/bug.png(442 KB)