LRUQueryCacheremembers, per segment, which documents a filter query matched, so repeating the query on that segment is a lookup instead of a search.- Caching costs memory, so it decides per segment. It skips the whole index if five bit sets of its size would not fit its share of the RAM budget, and it skips segments that are small compared with the others.
- With
new LRUQueryCache(maxSize, maxRamBytesUsed)the second rule isMinSegmentSizePredicate(10000): cache a segment with at least 10,000 documents and more than half the average number of documents per segment.
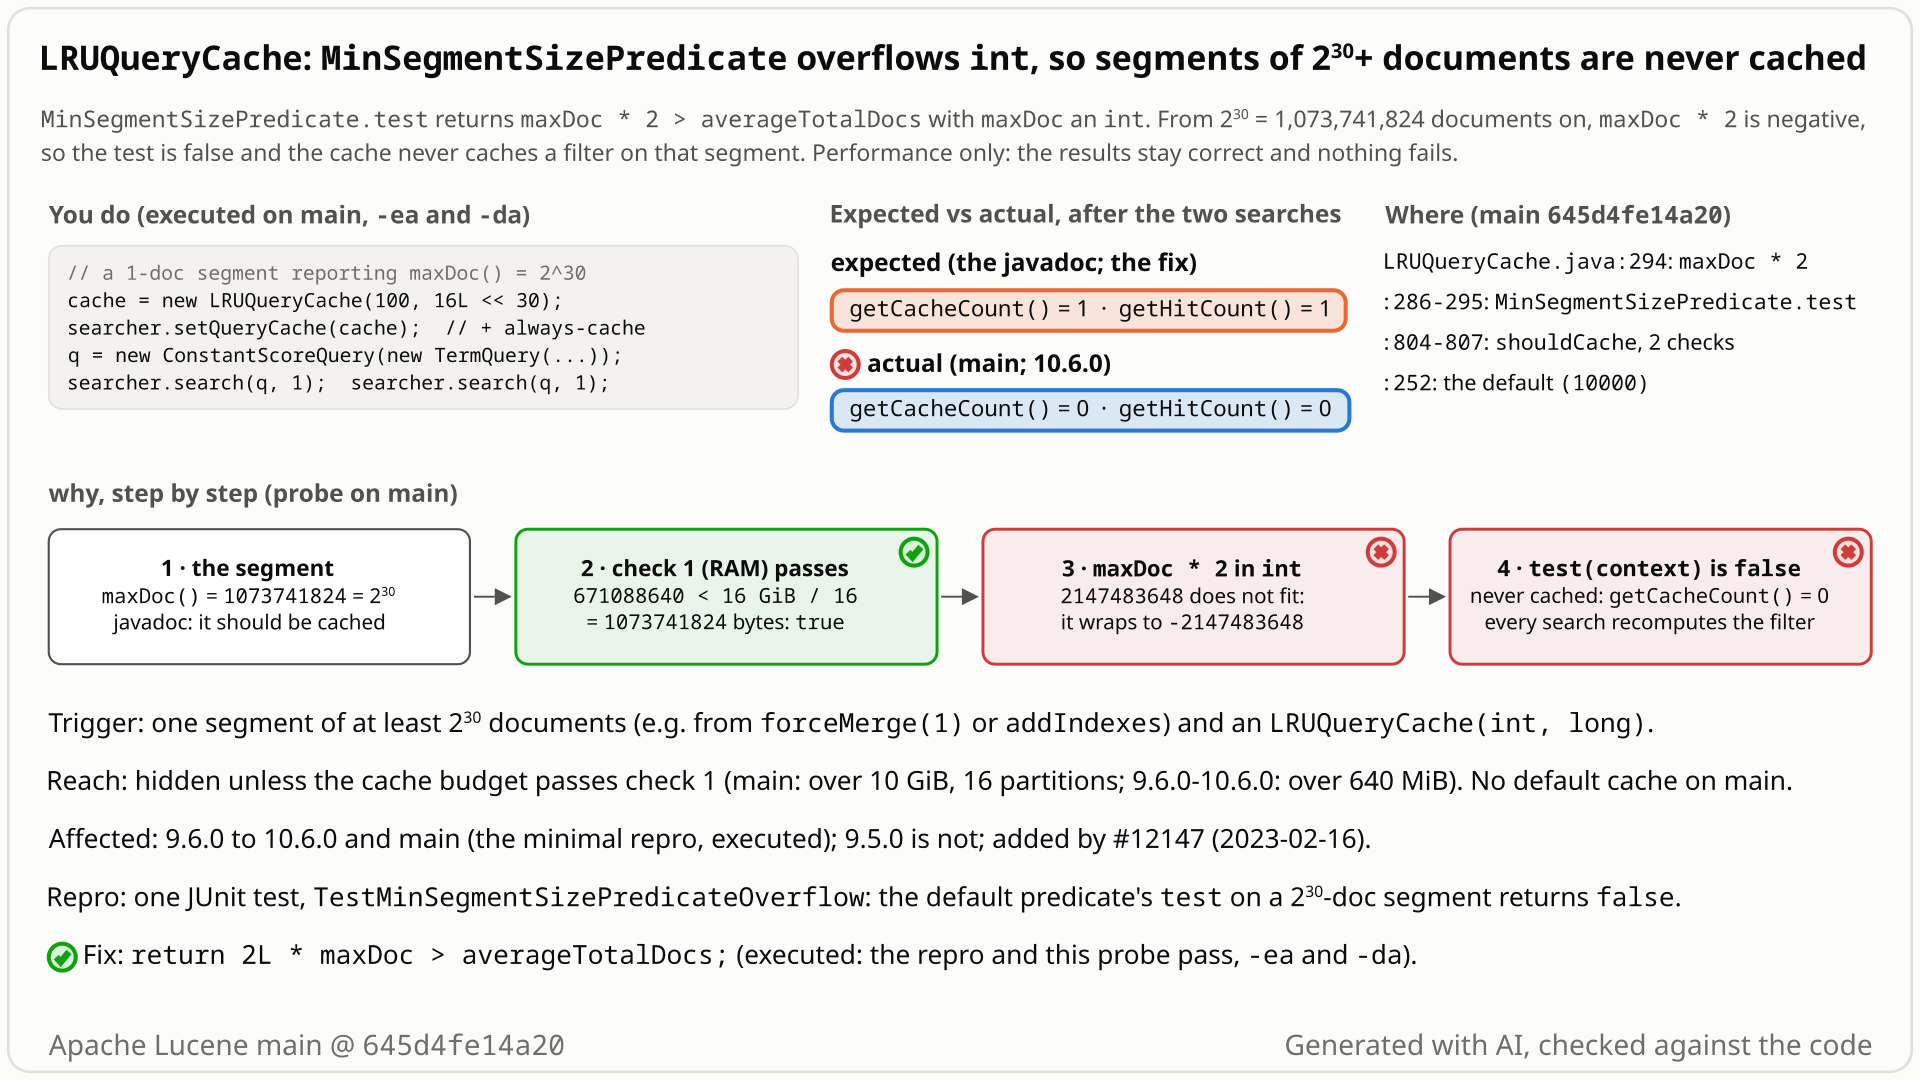
int gives -2,147,483,648, which is not more than the average, so the predicate says no and the segment is never cached; one document fewer gives 2,147,483,646 and is cached. Select the still to open it at full size. Generated with AI, checked against the code.- Put 1,073,741,824 (2^30) documents in one segment, for example with
forceMerge(1)orIndexWriter.addIndexes, and enablenew LRUQueryCache(100, 64 GiB)with a caching policy that caches every query. - You expect the segment to be cached: it has more than 10,000 documents, and as the only segment it is the average, more than the required half of it. The second search should be a cache hit.
- Instead the check computes
maxDoc * 2as anint: 1,073,741,824 x 2 = 2,147,483,648 does not fit (the maximum is 2,147,483,647), wraps to -2,147,483,648, and that is not more than 1,073,741,824. The answer is no. - So the segment is never cached: after two searches
cacheCount=0 hitCount=0 missCount=0. With one document fewer, 1,073,741,823, the same searches givecacheCount=1 hitCount=1. Every segment from 2^30 documents up to the 2,147,483,519 limit is affected.
Users who enable caching with new LRUQueryCache(maxSize, maxRamBytesUsed) and have one segment of 2^30 or more documents, for example after forceMerge(1) of a 1.1 billion document index. The defaults hide it: the budget must admit such an index at all, over 640 MiB on 9.6.0-10.6.0 and over 10 GiB on main.
Mechanism, terms and numbers511 words
LRUQueryCache(int maxSize, long maxRamBytesUsed) installs MinSegmentSizePredicate(10000) as its rule for which segments to cache. Its javadoc says items are cached on leaves that have more than 10k documents and more than half of the average documents per leaf, which "should guarantee that all leaves from the upper TieredMergePolicy tier will be cached". The predicate checks "more than half of the average" as return maxDoc * 2 > averageTotalDocs; with maxDoc an int. For every segment of 2^30 documents or more (a real segment holds at most IndexWriter.MAX_DOCS = 2,147,483,519) the product is negative, so the comparison is false whatever the average, and the segment is never cached, however large the cache. The rule came with #12147 (9.6.0), the fix for #12140, where the largest segments of an index were never cached; the overflow brings that symptom back for the very largest segments. Search results stay correct, and the segment is counted neither as a cache hit nor as a miss. The fix is 2L * maxDoc.
- Leaf / segment: a part of the index with its own documents, numbered 0 to
maxDoc() - 1. Anintholds at most 2,147,483,647;IndexWriter.MAX_DOCSis 2,147,483,519. leavesToCache: thePredicate<LeafReaderContext>thatLRUQueryCacheasks before it caches anything on a segment. The two-argument constructor usesMinSegmentSizePredicate(10000); the four- and six-argument constructors take your own.- RAM gate: before the predicate, the cache checks that five dense bit sets for the whole index (
maxDoc / 8bytes each) fit in the budget (on main, in a sixteenth of it, one of 16 partitions).
MinSegmentSizePredicate.testreads the segment'smaxDocas anint, returns false below 10,000, computesaverageTotalDocs = topLevel.maxDoc() / leaves.size(), and returnsmaxDoc * 2 > averageTotalDocs(LRUQueryCache.java:287-294on main).- For
maxDocfrom 2^30 on (up toMAX_DOCSfor a real segment; anyintup to 2^31 - 1 behaves the same) the product2 * maxDocis at least 2^31 and wraps to2 * maxDoc - 2^32, between -2,147,483,648 and -2. The average is never negative, so the answer is always false, whatever the other segments are. It never errs the other way. CachingWrapperWeight.shouldCacheis the RAM gate&&this predicate (:804-808).scorerSupplierandcountcheck it (:823,:910) and, when it is false, run the query uncached, before the cache lookup and before the caching policy is asked (:834,:838). No policy can override it, and since no lookup happens, no miss is counted.
One real segment of exactly 1,073,741,824 documents, built through the public API, LRUQueryCache(100, 64 GiB), an always-cache policy, ConstantScoreQuery(TermQuery) searched twice: 256 of 256 hits (correct) and cacheCount=0 hitCount=0 missCount=0, on main and on 10.5.2, with assertions on and off. With 1,073,741,823 documents (one of the 256 copies has one document fewer): cacheCount=1 hitCount=1 missCount=1. With 2L * maxDoc: cacheCount=1 hitCount=1. Driven directly, the predicate accepts a single segment of 10,000, 2^29 and 2^30 - 1 documents and rejects 2^30, 2^30 + 1, 2,000,000,000 and 2,147,483,519.
Exposure and likelihood245 words
- Who is hit. Users who enable query caching with
LRUQueryCache(int, long), the form in the class javadoc example and inMIGRATE.md("To enable caching back ..."), and have a segment of 2^30 or more documents. Every otherwise cache-eligible query runs uncached on that segment, on every search: cached filters never help on exactly the biggest, most expensive segment. - Default vs opt-in. Main has no default query cache (GITHUB#14187). In 9.6.0-10.6.0 the default is
LRUQueryCache(1000, min(32 MiB, heap / 20)), whose RAM gate already refuses any index above 53,687,095 documents. So it takes an opt-in cache with a large budget: for an index of exactly 2^30 documents more than 671,088,640 bytes (640 MiB) on 9.6.0-10.6.0, and at least 10,737,418,256 bytes (just over 10 GiB) on main, where each of 16 partitions gets a sixteenth. Bigger indexes need more. - How such a segment arises.
forceMerge(1)of a large index (maxNumSegmentswins over the merge policy's size cap),addIndexes(CodecReader...)(one merged segment by default), a raisedsetMaxMergedSegmentMB, or a custom merge policy. The default 5 GiB cap is in bytes, so it only stops this for documents averaging more than about 5 bytes on disk. Lucene's own@MonstertestTestIndexWriterMaxDocs.testExactlyAtTrueLimitforce-mergesMAX_DOCSdocuments into one segment. - Visibility. None: no exception, and the segment adds nothing to the hit, miss and cache counts (they count the whole cache; in the fresh-cache runs all three stay 0).
- Not affected. Caches built with their own
leavesToCachepredicate.
One JUnit test in org.apache.lucene.search, because the predicate is package-private (upstream TestLRUQueryCache does the same). A FilterLeafReader over a real one-document segment reports maxDoc() = 2^30; the predicate reads nothing else, so this answers like a real 2^30-document segment. The result does not depend on the seed; the test itself runs in about 0.15 s.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.FilterLeafReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LeafReader;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMinSegmentSizePredicateOverflow extends LuceneTestCase {

  public void testSingleSegmentOf2Pow30Docs() throws IOException {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        w.addDocument(new Document());
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        LeafReader leaf =
            new FilterLeafReader(reader.leaves().get(0).reader()) {
              @Override
              public int maxDoc() {
                return 1 << 30;
              }

              @Override
              public CacheHelper getCoreCacheHelper() {
                return null;
              }

              @Override
              public CacheHelper getReaderCacheHelper() {
                return null;
              }
            };
        assertTrue(
            "expected true for the only segment (2^30 docs >= 10000 and > half the average 2^30),"
                + " got false",
            new LRUQueryCache.MinSegmentSizePredicate(10000).test(leaf.getContext()));
      }
    }
  }
}
cp TestMinSegmentSizePredicateOverflow.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestMinSegmentSizePredicateOverflow -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
MinSegmentSizePredicate(10000).test(...)returns true for the only segment (2^30 documents, average 2^30).- Observed
- It returns false, because
2^30 * 2wraps to -2^31 inint; the same with assertions off.
More files, environment, full output260 words
The predicate reads only the leaf's maxDoc(), the top-level reader's maxDoc() and the number of leaves (LRUQueryCache.java:286-294). The wrapped leaf is its own top-level reader, so the average is 2^30: the smallest single-segment input that wraps. The two cache helpers return null only because FilterLeafReader requires them. The same answer was checked on a real single segment of 2^30 documents, built with IndexWriter.addIndexes(CodecReader...) of 256 copies of a 2^22-document segment and searched through LRUQueryCache(100, 64 GiB) (about 6 s and 15 MB of disk), on main and 10.5.2; that probe is evidence, not the proposed test.
As the regression test: the same test, for example as a new method in TestLRUQueryCache.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also fails on 9.6.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0; 9.5.0 not affected |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestMinSegmentSizePredicateOverflow.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestMinSegmentSizePredicateOverflow -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
# gradle, main 645d4fe14a20, seed DEADBEEF (assertions on; the same with -Ptests.asserts=false)
TestMinSegmentSizePredicateOverflow > testSingleSegmentOf2Pow30Docs FAILED
    java.lang.AssertionError: expected true for the only segment (2^30 docs >= 10000 and > half the average 2^30), got false
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:211FF782ABBD45E1]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.search.TestMinSegmentSizePredicateOverflow.testSingleSegmentOf2Pow30Docs(TestMinSegmentSizePredicateOverflow.java:55)

# with `return 2L * maxDoc > averageTotalDocs;`: the test passes (assertions on and off)

# real single segment, LRUQueryCache(100, 64 GiB), always-cache policy, ConstantScoreQuery searched twice
maxDoc=1073741824 (2^30):      hits=256/256 cacheCount=0 hitCount=0 missCount=0   (main and 10.5.2, -ea and -da)
maxDoc=1073741823 (2^30 - 1):  hits=256/256 cacheCount=1 hitCount=1 missCount=1
maxDoc=1073741824 with 2L fix: hits=256/256 cacheCount=1 hitCount=1 missCount=1- The javadoc says the rule "should guarantee that all leaves from the upper TieredMergePolicy tier will be cached"; a lone 2^30-document segment is that tier.
- The rule came from #12147, the fix for #12140, where the largest segments were never cached.
- The float-ratio rule it replaced had no cutoff, and
2L * maxDocrestores caching.
The full argument198 words
- Javadoc of
LRUQueryCache(int, long)(LRUQueryCache.java:243-250): "Items will only be cached on leaves that have more than 10k documents and have more than half of the average documents per leave of the index. This should guarantee that all leaves from the upper TieredMergePolicy tier will be cached." A single 2^30-document segment meets both conditions and is the upper tier. - History. #12140 (
type:bug, by dnhatn) reported an index of 34 segments of 5 GB that was never cached under the old 3% rule. In that thread jpountz proposed the current rule: "maybe it should even be half the average segment size to make sure it includes all segments from the upper tier?" #12147 (type:bug) implemented it; its commit message: "This change adjusts the cache policy to ensure that all segments in the max tier to be cached." Nothing there excludes very large segments. - The old rule had no cutoff. 9.5.0 compared
(float) maxDoc / topLevelMaxDocwith.03f, which cannot overflow. - No documented limit. Nothing in the class,
MIGRATE.mdorCHANGES.txtmentions a size cap other than the separate RAM gate. - No test covers it. Upstream
TestLRUQueryCache.testMinSegmentSizePredicateuses segments of at most 55 documents.
The devil's-advocate check228 words
The strongest case for "intended" (a reviewer from another model family, OpenAI GPT-5.6, rated it "moderate"): LRUQueryCache is @lucene.experimental; caching is an optional optimisation, off by default on main; "will only be cached on leaves that ..." is a necessary condition, not a promise that every such leaf is cached, and other gates can reject entries too; and a maintainer could accept extra misses at this scale, "especially for unusually large cache entries". A related practical objection: a dense cached entry for a 2^30-document segment is about 128 MiB and can evict many smaller entries.
Why it fails: the javadoc's next sentence states the design goal ("This should guarantee that all leaves from the upper ... tier will be cached"), and the issue and PR it came from say the same; every stated condition is met here, and the predicate says no only because of the wrap; @lucene.experimental allows the API to change, not the arithmetic to be wrong; the scale is legal and exercised by Lucene's own tests; and entry size already has its own policy, the RAM gate, which admits the index only when its share of the budget has room for five worst-case entries, so the predicate is not the place that limits it. These arguments limit severity, not validity. The same reviewer noted that "the exact signed-overflow boundary has no plausible policy rationale".
Recommended Widen the product to long: 2L * maxDoc
Widen the product to long: return 2L * maxDoc > averageTotalDocs; (one line, no API or format change). With it the repro passes with assertions on and off, a real 2^30-document segment is cached again, and the core test classes that use LRUQueryCache pass.
-      return maxDoc * 2 > averageTotalDocs;
+      return 2L * maxDoc > averageTotalDocs;
All options and trade-offs3 options · 373 words
Two equivalent one-line fixes; both were run through gradle in a scratch worktree of 645d4fe14a20.
In MinSegmentSizePredicate.test (LRUQueryCache.java:294).
-      return maxDoc * 2 > averageTotalDocs;
+      return 2L * maxDoc > averageTotalDocs;
Trade-offs
No correctness, API or format trade-off found: the same answer as today for every segment below 2^30 documents and "more than half of the average" for every legal size; one long multiply per segment per caching decision. By design it starts caching on such segments: a dense entry for 2^30 documents is about 128 MiB and can evict other entries, within the existing RAM, entry-count and LRU limits.
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20: without the fix the repro fails with assertions on and off. - With the fix: it passes with assertions on and off (
-Ptests.asserts=false). - Closest suites: every core test class that uses
LRUQueryCache(TestLRUQueryCache, includingtestMinSegmentSizePredicate,TestUsageTrackingFilterCachingPolicy,TestBooleanScorer,TestDocValuesOrdinalSetIterator): 4 classes, 88 tests, 0 failures, 3 skipped (@AwaitsFix). ./gradlew :lucene:core:check -x test(google-java-format, ecj lint, forbidden APIs) passes with the repro test in place. The full test suite was not run.- Earlier, shadowed into the stock main jars: the minimal test passes with assertions on and off, and the real 2^30-document segment is cached (
cacheCount=1 hitCount=1).
Stays in int and cannot overflow.
-      return maxDoc * 2 > averageTotalDocs;
+      return maxDoc > averageTotalDocs / 2;
Trade-offs
For non-negative integers 2 * m > a holds exactly when m > floor(a / 2), so it gives the same answers as the long product for every input. Slightly less direct to read as "more than half of the average".
What the checks validated
Gradle in the same scratch worktree: the repro and TestLRUQueryCache pass with assertions on (41 tests, 0 failures, 3 skipped as @AwaitsFix). Assertions off, the other suites and the static checks were not run for this option.
Detects the overflow instead of avoiding it.
Trade-offs
Turns the silent miss into an ArithmeticException on every search of such a segment. Not tried.
Only the two-argument constructor's default rule is affected: products that pass their own leavesToCache predicate to LRUQueryCache keep their own behaviour.
Non-formal: during a formal-verification study of Lucene, a reviewer reading LRUQueryCache while checking other findings noticed the int product. Follow-up tests drove the predicate with reported sizes around 2^30 and end to end through the cache; later a real 2^30-document segment, built through the public API, confirmed it.
The method in full111 words
Method: non-formal (code reading, then executed tests). In the 2026-10-22 study, a verifier saw the int multiplication as a side observation. The study's follow-up wrote three tests: the package-private predicate driven directly with a FilterLeafReader that reports a large maxDoc (single leaf, and a 2^30-document leaf next to a 20,000-document one), and an end-to-end search through LRUQueryCache(100, 64 GB) with an always-cache policy. All three fail with assertions on and off. The hunt then cut it to one test, re-ran it on current main and on release jars, and a tie-breaker built a real single segment of exactly 2^30 documents with IndexWriter.addIndexes to rule out an artefact of the reader wrapper.
No prior report found in GitHub issues, PRs and commits, open PRs, the JIRA archive, the Lucene lists, downstream trackers or the web (2026-11-01); not fixed upstream.
Searches4 searches
Closest items, none a report of this bug: #12147 and #12140 (the origin; the review and the thread discuss averages, medians and tier layouts of up to 1M documents per segment, never overflow); the backports #12163 and #12164; #8290 / LUCENE-7235 (introduced the predicate in 2016 with a float ratio); #14187 (default cache off on main); open PRs #16952, #16757 and #16306 touch query-cache files but not the predicate. Limits: GitHub search does not index code or diffs; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues and PRs (incl. the migrated JIRA issues) and commits | 2026-11-01 | the hunt's prior-report tool (16 issue/PR and 3 commit queries) plus 14 own phrasings, phrase searches for "maxDoc * 2" LRUQueryCache and "2L * maxDoc", an in:comments search; the reproducer's 8 and the tie-breaker's 4 phrasings | no report; MinSegmentSizePredicate and averageTotalDocs give 0 issues, PRs and commits |
| Open PRs | 2026-11-01 | changed files of all 410 open PRs; diffs of the three that touch query-cache files | none changes the predicate |
| JIRA archive, mailing lists, downstream trackers, web | 2026-11-01 | 4 JIRA queries; 20 queries over dev@, java-user@, issues@ and commits@; 2 downstream-repository queries and own searches of the Elasticsearch, OpenSearch and Solr trackers; 6 web queries | no report |
| Upstream main | 2026-11-01 | file contents of LRUQueryCache.java at 2f424fd428da (2026-10-30) | still return maxDoc * 2 > averageTotalDocs; |
Introduced in 9.6.0 by #12147 (8e15c665be9, 2023-02-16), which brought the average-based rule and the int product together. 9.6.0 to 10.6.0 and main fail; 9.5.0 is not affected.
Versions tested6 rows
Introduced by #12147 "Ensure caching all leaves from the upper tier" (closes #12140): main commit 8e15c665be9 (2023-02-16), branch_9x backport 57e1a4a40ef (2023-02-20), the only change to LRUQueryCache.java between the 9.5.0 and 9.6.0 tags. A pickaxe search for the expression finds only these two commits; the line is unchanged since. 9.5.0 compared a float ratio, which cannot overflow.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal repro fails with assertions on and off (standalone and gradle); a real 2^30-document segment is never cached; passes with the fix |
| 10.6.0 | affected | minimal repro fails with assertions on and off |
| 10.5.2 | affected | minimal repro fails with assertions on and off; a real 2^30-document segment is never cached |
| 10.0.0, 9.12.3 | affected | minimal repro fails with assertions off |
| 9.6.0 | first affected | minimal repro fails with assertions on and off |
| 9.5.0 | float ratio | the same check with the 9.5.0 constructor passes; a 2^30-document leaf is cached |
Verified real with high confidence: the study's tests, a current-main reproducer and a tie-breaker that built a real 2^30-document segment all reproduce it. A reviewer from another model family, unable to run code, agreed with the root cause.
Checks and verdicts175 words
Nobody found it intended; all agree it is performance only, with correct results.
| Check | Verdict | What it found |
|---|---|---|
| study follow-up | reproduced | Three tests (single leaf, two leaves, end to end) fail 3/3 with assertions on and off; re-run unchanged on main b83101cdd2, a9779ef3c193 and 645d4fe14a20: still 3/3. |
| minimisation | verified | The one-test repro fails on main with assertions on and off and with two seeds; passes with 2L * maxDoc. |
| current-main reproducer | real | Fails on main and 10.5.2 (assertions on and off), 10.6.0, 9.12.3 and 9.6.0; the fix passes. |
| cross-model review (OpenAI GPT-5.6, refute lens, read-only) | not real, low confidence (procedural) | It could not write or run code, so it could not reproduce; it agreed with the root cause, found the inputs legal, and rated the intended-behaviour argument moderate. |
| tie-breaker | real, high | Re-ran the minimal test and the fix; a real 2^30-document segment is never cached on main and 10.5.2, a 2^30 - 1 one is, and the fix caches the 2^30 one. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 472 KB
Finding record, Lucene and upstream sources, repro files and diagram notes649 words
- Registry title
- LRUQueryCache MinSegmentSizePredicate overflows maxDoc * 2, so segments of 2^30+ docs are never cached
- Area
- search / query cache
- Priority
- Low, rank 1034: LRUQueryCache's MinSegmentSizePredicate overflows so segments of 2^30 or more docs are never cached, performance only at extreme scale with a large non-default cache.
- Impact class
- minor
- Impact note
- Query-cache users with the default MinSegmentSizePredicate and segments of 2^30 or more documents; performance only; released since 9.6.0 (#12147).
- Summary
- You use the query cache with its MinSegmentSizePredicate on a segment of 2^30 or more documents. You expect large segments to be cacheable. Instead maxDoc * 2 overflows int, the predicate rejects them from 2^30 docs on, and such a segment is never cached.
- Introduced
- 8e15c665be9 (#12147) (2023-02-16)
- First affected version
- 9.6.0 [exec 2026-11-01: the minimal test fails on the 9.6.0 release jars (SHA-1 checked against Maven Central) with -ea and -da, and the same check with the 9.5.0 constructor passes on 9.5.0; 9.6.0 has #12147 through the branch_9x backport 57e1a4a40ef]
- Affected versions
- every release from 9.6.0 through 10.6.0 and main 645d4fe14a20 (
maxDoc * 2 > averageTotalDocsis in LRUQueryCache.java at every tag from 9.6.0 on [read]); the minimal test fails on main (-ea and -da) and on the 9.6.0 (-ea and -da), 9.12.3 (-da), 10.0.0 (-da), 10.5.2 (-ea and -da) and 10.6.0 (-ea and -da) release jars (SHA-1 checked against Maven Central) [exec 2026-11-01]; 9.5.0 and earlier are not affected (a float ratio; the same check with the 9.5.0 constructor passes) [exec]; not fixed upstream (main 2f424fd428da, 2026-10-30) [read] - Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real and a prior-report search; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-22, the study's read-only gh searches; 2026-11-01, a prior-report search over GitHub issues, PRs and commits, the changed files of all 410 open PRs, the JIRA archive, the dev@, java-user@, issues@ and commits@ lists, downstream trackers and the web: verdict new); not fixed upstream (main 2f424fd428da still has the line)
- Lucene commit tested
- main
645d4fe14a20(the minimal repro with assertions on and off, as a standalone JUnit run and through gradle; a real single segment of 2^30 documents through the public API); the SHA-1-checked release jars 9.5.0 (not affected), 9.6.0, 9.12.3, 10.0.0, 10.5.2 (also the real 2^30-document segment) and 10.6.0; the fix in a scratch worktree of645d4fe14a20. Earlier, the study's three tests on mainb83101cdd2anda9779ef3c193.
- Finding record
a Lucene clone tag releases/lucene/10.5.2: lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:196
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:251-253, :277-296, :792-808, :823, :834, :838, :910 (at 645d4fe14a20)
- Who is affected
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:82, :145-151, :251-253, :792-801 (at 645d4fe14a20)lucene/MIGRATE.md:227-236; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:82-84; lucene/CHANGES.txt:343 (GITHUB#14187)a Lucene clone tag releases/lucene/10.5.2: IndexSearcher.java:96-99, LRUQueryCache.java:787lucene/core/src/java/org/apache/lucene/index/TieredMergePolicy.java:52-59, :77; IndexWriter.java:208, :3264-3267lucene/core/src/test/org/apache/lucene/index/TestIndexWriterMaxDocs.java:47-48, :85
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:117, :243-250 (at 645d4fe14a20)a Lucene clone tag releases/lucene/9.5.0: LRUQueryCache.java:170-171lucene/core/src/test/org/apache/lucene/search/TestLRUQueryCache.java:1717-1761https://github.com/apache/lucene/issues/12140 (labels; issuecomment-1426119587 by jpountz, 2023-02-10; read-only GET 2026-11-01)https://github.com/apache/lucene/pull/12147 (label type:bug; merged 2023-02-16); git show 8e15c665be9 (commit message)
- History
a Lucene clone: git show 8e15c665be9, 57e1a4a40ef; git log releases/lucene/9.5.0..releases/lucene/9.6.0 -- LRUQueryCache.java
- TestMinSegmentSizePredicateOverflow.java (JUnit, one test):
repro/LFV-081/src/org/apache/lucene/search/TestMinSegmentSizePredicateOverflow.java(62 lines)
Made in parallel with this doc from the code at 645d4fe14a20. The numbers are the predicate's arithmetic and a separate probe (a FilterLeafReader reporting maxDoc 2^30 over a 1-document segment, LRUQueryCache(100, 16 GiB)), which match the real-segment runs; the Trigger and Affected lines of the summary card follow this doc.
assets/LFV-081/bug.png(472 KB)