FieldExistsQuery finds the documents that have a value for a field. Its count() shortcut is exact for keyword fields, but not for a norms-free text field whose value produces no tokens.
- One field name can carry several structures: indexed terms (for search), norms (per-document length, optional) and doc values (a per-document column for sorting and faceting).
FieldExistsQuery(f)matches the documents that have a value forf: it reads the norms if the field has them, else the vectors, else the doc values.Weight#countletsIndexSearcher#countanswer from index statistics without visiting documents. It must return the exact number of matching live documents, or -1 for "unknown, scan".
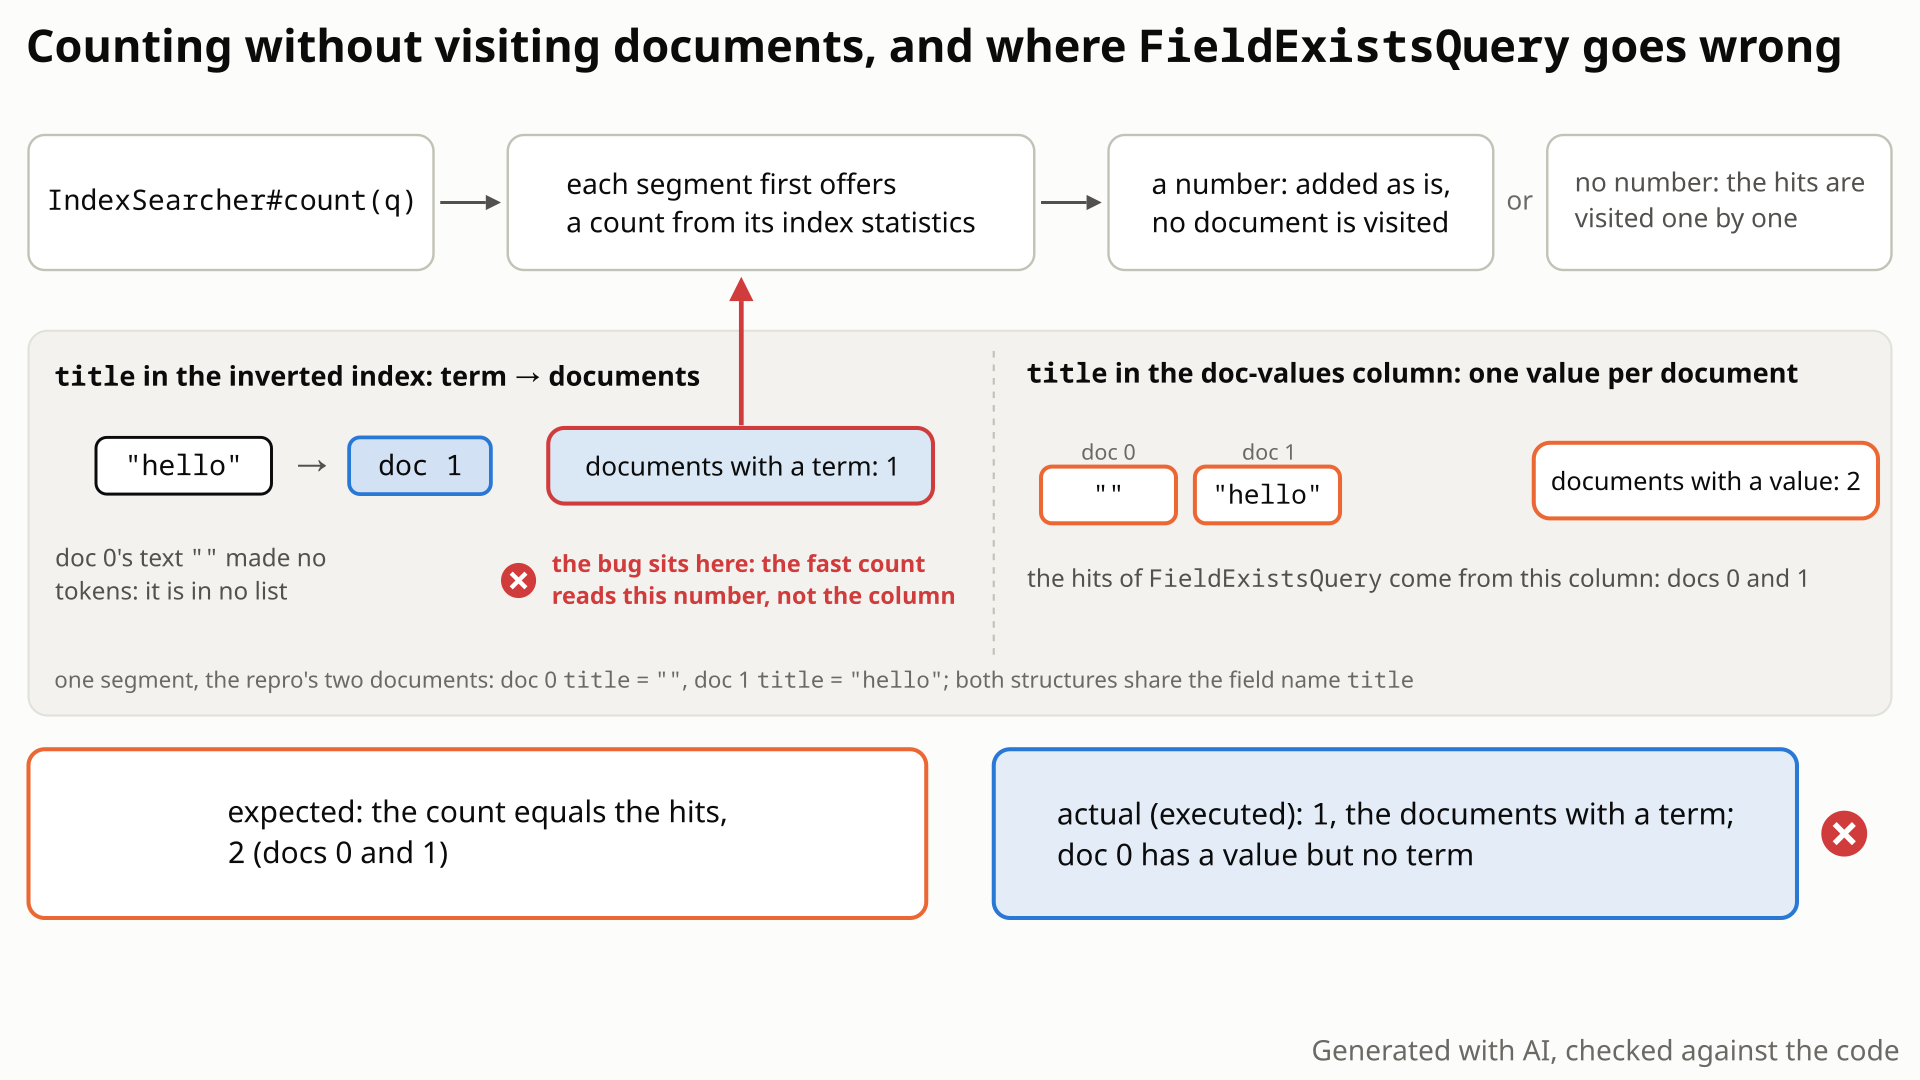
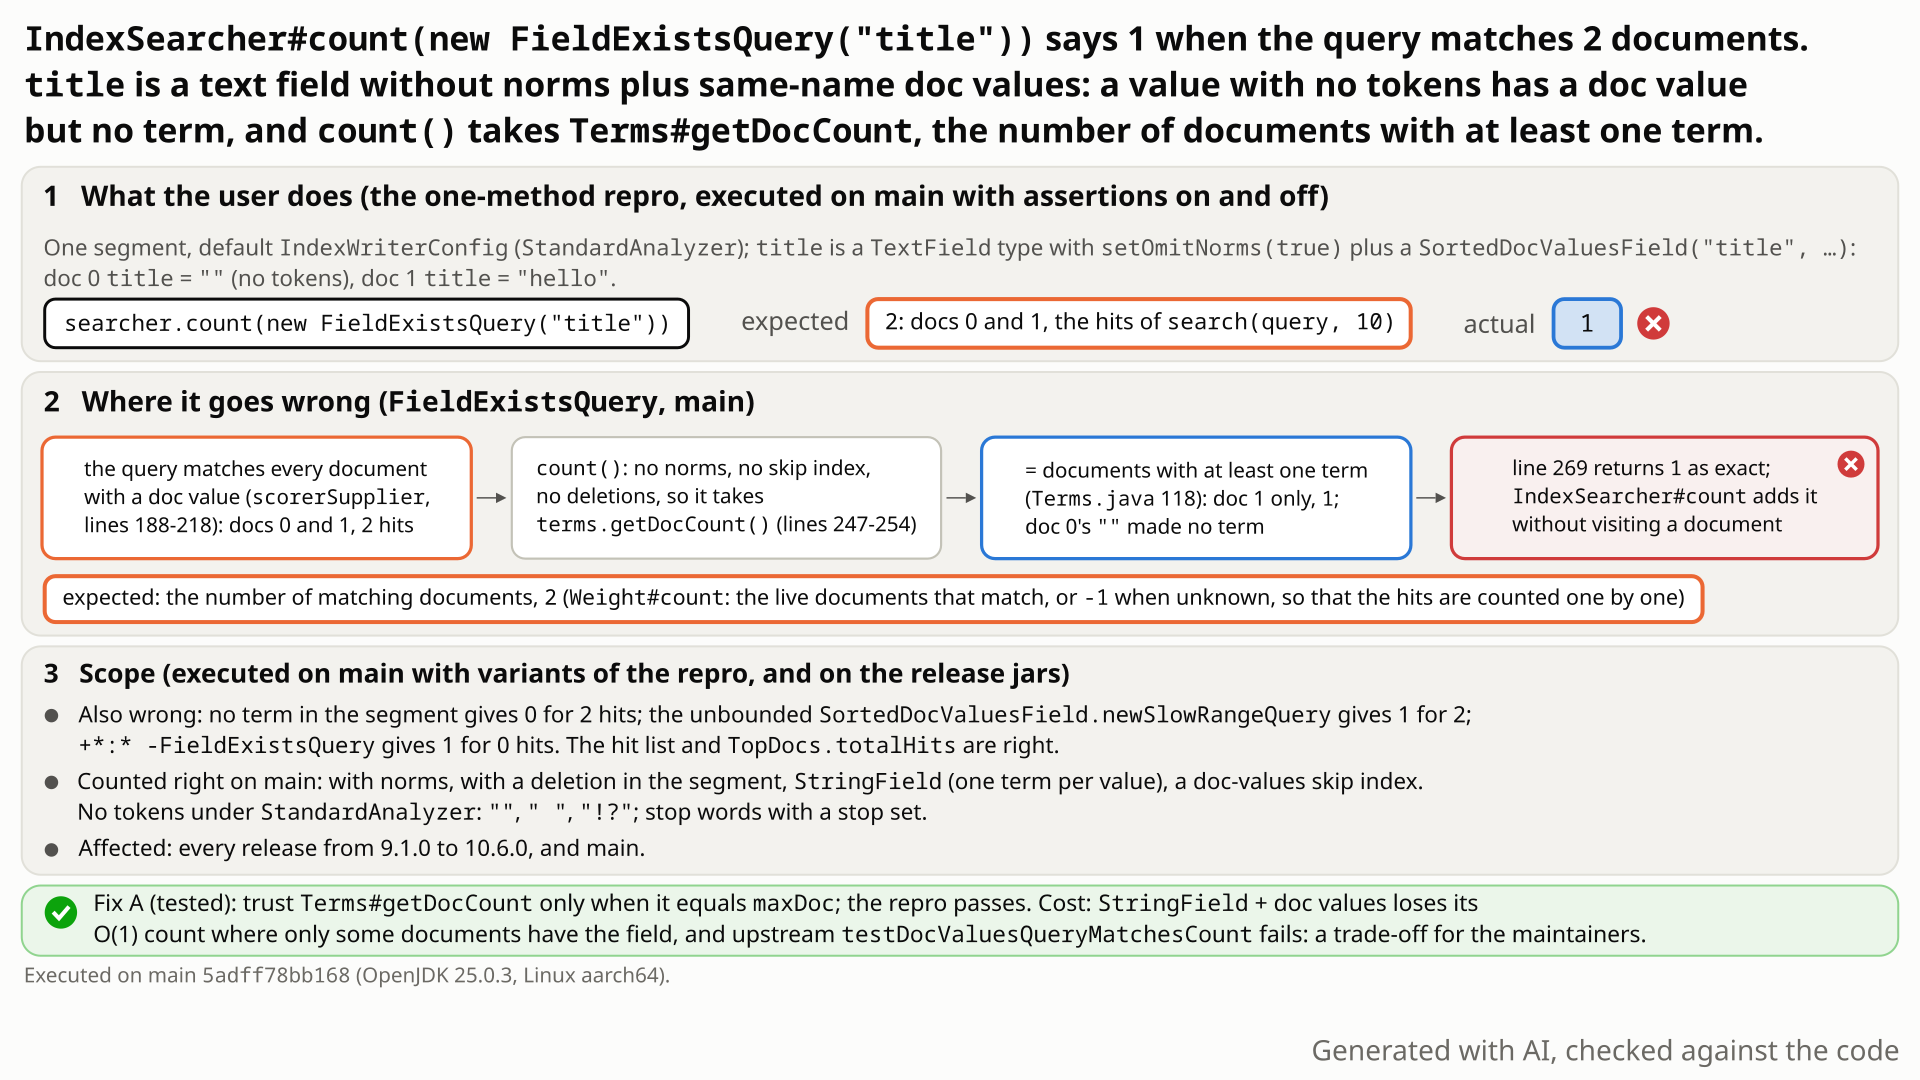
count() reads (1). Select the still to open it at full size. Generated with AI, checked against the code.- Index two documents with a text field
titlewhose norms are turned off, plus aSortedDocValuesFieldalso namedtitle: one with title""(no tokens), one with"hello". Default config, one segment, no deletions. searcher.search(new FieldExistsQuery("title"), 10)returns both documents: without norms the query matches every document that has a doc value.- You expect
searcher.count(query)to be 2 as well. - It is 1. On a segment without deletions
count()takes a shortcut and returnsTerms#getDocCount, the number of documents with at least one term, and the empty title has a doc value but no term. If no document of the segment has a term, the count is 0. - Only counts are wrong:
IndexSearcher#count,TotalHitCountCollectorand Boolean counts built from the clause (underMUST_NOTthey come out too high). Hits, top-ktotalHitsandCheckIndexare fine.
Applications that index a tokenized field with norms omitted plus a same-name doc-values field without a skip index, where some values analyze to no tokens (empty, punctuation-only, stop-words-only). Otherwise default config. Counts on segments without deletions come out too low (0 when no document has a term); hits stay correct.
Mechanism, terms and numbers569 words
FieldExistsQuery's Weight#count uses the number of documents with at least one indexed term as the number of documents with a doc value. For a tokenized field with norms omitted that shares its name with a doc-values field, a value that analyzes to no tokens (an empty, punctuation-only or stop-words-only text) gives a document that matches the query but is not counted. IndexSearcher#count then reports 1 for 2 hits, or 0 for 1 hit when no document of the segment has a term. Released since 9.1.0; not fixed upstream.
- What the query matches. For a field without norms or vectors,
scorerSupplieriterates the field's doc values (FieldExistsQuery.java:170-219, the doc-values switch at:188-209), so every document with a doc value is a hit. The class javadoc says the query matches documents that contain "a field that indexes norms or doc values" (:38-41). - What
count()returns.count(:222-274) checks norms first and uses only the safe shortcut there (getDocCount(field) == maxDoc,:231-237). For a doc-values field without a skip index on a leaf without deletions (:247), the code says "No deletions: we can use points or terms doc count as a proxy for doc values" (:248) and an indexed field takescount = (terms == null ? 0 : terms.getDocCount())(:252-255). Thencount == 0returns 0,count == maxDocreturnsnumDocs, and any other count of 0 or more is returned as exact ("The computed count can be trusted",:261-270). - Why the shortcut is wrong here.
Terms#getDocCountis "the number of documents that have at least one term for this field" (Terms.java:117-121). A tokenized value that produces no tokens adds no term, but the document's doc value of the same name is there; the indexing chain handles a field that "exists in this document, but it did not have any indexed tokens" on purpose (IndexingChain.java:1930-1931). When no document of the leaf has a term,Termsis null and the result is 0. - Where the wrong number goes.
IndexSearcher#countruns aTotalHitCountCollectorManager(IndexSearcher.java:491-529), whose leaf collector takesweight.count(context)whenever it is not -1 (TotalHitCountCollector.java:48).BooleanWeight#countcomposes clause counts: a FILTER clause's 0 makes the conjunction 0 (BooleanWeight.java:206-231), and underMUST_NOTthe resultnumDocs - prohibitedCountcomes out too high (:196). - What is sound. The points shortcut (every point field instance indexes a point), the skip-index branch (
:244-246, an exactDocValuesSkipper#docCount), and the rewrite toMatchAllDocsQuery(:140-154, only when, on every leaf, the terms, points or skip-index doc count equalsmaxDoc). An untokenized value (StringField) always yields exactly one term, so the shortcut is exact for keyword fields, the shape it was written for.
Two documents, title = "" and title = "hello", each with a SortedDocValuesField("title", ...), norms omitted: 2 hits, count 1. When the only titled document of the segment is blank: 1 hit, count 0. The unbounded range SortedDocValuesField.newSlowRangeQuery("title", null, null, true, true) rewrites to the exists query: 2 hits, count 1. Stop-words-only values over 3 segments: 6 hits, count 3. #exists #id:1 on a segment where no document has a term: 1 hit, count 0. +*:* -exists over "", "hello" and a document without a title: 1 hit, count 2.
Exposure and likelihood254 words
- Who is hit. A tokenized indexed field with
omitNorms(true)and a doc-values field of the same name (SortedDocValuesField,SortedSetDocValuesField,NumericDocValuesField, ...) without a skip index, for example to sort or facet on the same name. Values that analyze to no tokens are ordinary data: empty strings, whitespace or punctuation only, stop words only with a stop filter. DefaultIndexWriterConfig, codec andIndexSearcher. The field shape is an opt-in choice. - What is wrong. Counts only:
IndexSearcher#count,TotalHitCountCollector(Manager),BooleanQuerycounts built from the clause (too low under FILTER, too high underMUST_NOT), and unbounded doc-values range queries that rewrite toFieldExistsQuery. Hit lists, top-ktotalHitsandCheckIndexare fine. - Scale. Per segment without deletions the count misses every zero-token document; a segment whose titled documents are all empty counts 0. Segments with deletions scan and are right.
- Not affected. Fields with norms (from 9.2.0), keyword fields such as
StringField, point fields, and doc values with a skip index from 10.5.0. - Workarounds today. Keep norms on the text field; or give the doc-values field a skip index (10.5.0 and later; that branch runs first and is exact); or use different names for the text field and the doc-values field (a doc-values-only field has no terms shortcut and is scanned; from the code, not run).
- Elsewhere. Elasticsearch hit the same mechanism in its own count shortcut (elastic/elasticsearch#89760: 3 total hits for 4 hits on an exists query with an empty string) and fixed it there in #90341.
One JUnit test, one method, public API: two documents with the default IndexWriterConfig and codec, one segment, no deletions. It compares count with the number of hits. It fails on main and on the 10.6.0, 10.5.2, 9.12.3 and 9.2.0 jars, with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements. See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License. You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestFieldExistsQueryCountNoTokens extends LuceneTestCase {

  public void testCountIncludesValueWithNoTokens() throws Exception {
    FieldType textWithoutNorms = new FieldType(TextField.TYPE_NOT_STORED);
    textWithoutNorms.setOmitNorms(true);
    try (Directory dir = newDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      for (String title : new String[] {"", "hello"}) { // "" analyzes to no tokens
        Document doc = new Document();
        doc.add(new Field("title", title, textWithoutNorms));
        doc.add(new SortedDocValuesField("title", new BytesRef(title)));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query query = new FieldExistsQuery("title");
        assertEquals(2, searcher.search(query, 10).scoreDocs.length);
        assertEquals(2, searcher.count(query));
      }
    }
  }
}
cd $LUCENE
cp $REPRO/TestFieldExistsQueryCountNoTokens.java lucene/core/src/test/org/apache/lucene/search/
./gradlew :lucene:core:test --tests org.apache.lucene.search.TestFieldExistsQueryCountNoTokens -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false
- Expected
searcher.count(new FieldExistsQuery("title"))is 2, the number of hits.- Observed
countis 1 (expected:<2> but was:<1>) while the search returns 2 hits.
More files, environment, full output185 words
The test sits in org.apache.lucene.search like Lucene's own tests but uses only public API. new IndexWriterConfig() brings StandardAnalyzer, which turns "" into no tokens; whitespace, punctuation-only or stop-words-only values behave the same. Single thread, deterministic: the two documents land in one segment and nothing is deleted. It compiles from 9.2.0 on (FieldExistsQuery and the org.apache.lucene.tests packages). For a release, compile and run the same file against that release's lucene-core, lucene-codecs and lucene-test-framework jars.
Line 47 (2 hits) passes; line 48 (count) fails. The same test is the suggested regression test; it passes with the recommended fix.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT), 10.6.0, 10.5.2, 9.12.3, 9.2.0: fail |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
# gradle, main 5adff78bb168, seed DEADBEEF (codec Lucene104), assertions on
TestFieldExistsQueryCountNoTokens > testCountIncludesValueWithNoTokens FAILED
    java.lang.AssertionError: expected:<2> but was:<1>
        at org.junit.Assert.assertEquals(Assert.java:633)
        at org.apache.lucene.search.TestFieldExistsQueryCountNoTokens.testCountIncludesValueWithNoTokens(TestFieldExistsQueryCountNoTokens.java:48)

# JUnit runner, seed DEADBEEF: the same failure on main (-ea and -da), 10.6.0 (-ea and -da), 10.5.2, 9.12.3 and 9.2.0
# main, 20 iterations with random method seeds: 20 of 20 fail
# main with the recommended fix: passes (-ea and -da)Weight#countmust return "the number of live documents that match"; here the same query scores 2 documents and counts 1.- Lucene dropped the same shortcut from the norms branch in #477 because empty-token documents "don't show up in Reader.getDocCount(field)".
- Nothing limits the count to untokenized fields, and the index passes
CheckIndex.
The full argument297 words
- Contract.
Weight#count: "Counts the number of live documents that match a givenWeight#parentQueryin a leaf"; overrides should "provide other accurate sub-linear implementations (that actually return the count)" (Weight.java:181-198).IndexSearcher#count: "Count how many documents match the given query" (IndexSearcher.java:491-494).Terms#getDocCount: "the number of documents that have at least one term for this field" (Terms.java:117-121). - The query disagrees with itself. The match set is the query's own doc-values iterator (
FieldExistsQuery.java:188-209), not an outside idea of what "exists" means. - The twin was treated as a bug. In #477 (LUCENE-10263, 2021, eleven days after #445) jpountz pointed out that zero-token values get a norm "while they wouldn't count as part of
Terms#getDocCountwhich only includes documents that have at least one term", and the norms shortcut was limited todocCount == maxDoc. The upstream test still says "docs that have a text field that analyzes to an empty token stream still have a recorded norm value but don't show up in Reader.getDocCount(field), so we can't use the shortcut for these fields" (TestFieldExistsQuery.java:577-580) and asserts -1 there. The doc-values branch from #445 was not revisited. - History. #445's issue based the shortcut on per-field schema consistency (#10374, LUCENE-9334); the review suggested it "for keyword fields"; its test covers the terms shortcut only with
StringField+SortedDocValuesField(and the points shortcut withLongPoint+NumericDocValuesField). Nothing in #445 discusses tokenized fields or values without tokens. In #16111 (2026) the author raised the empty-token caveat ("docs can have norms without postings when analyzer produces empty token stream") and concluded "the unified logic works for vectors/docValues/points/terms, but norms still only use the maxDoc shortcut". - Legal input.
IndexWriteraccepts the field shape and the values, and the index passesCheckIndex.
The devil's-advocate check158 words
The strongest case for "intended": the shortcut was a reviewed optimization for keyword fields; LUCENE-9334 makes a field use the same data structures in every document; in #477 a maintainer argued that zero-token values are an analysis-chain problem ("If you want tokens, index your data correctly"); and testDocValuesQueryMatchesCount (TestFieldExistsQuery.java:347) pins the O(1) count, so maintainers could document a limit instead. The works-as-designed reviewer rated this "moderate".
Why it fails: LUCENE-9334 checks which data structures a field uses per document, not that each document produces a term, and the indexing chain handles the zero-token case on purpose; no javadoc, CHANGES or MIGRATE entry limits the count to untokenized fields; the same argument did not keep the norms shortcut in #477; and in 2019 jpountz wrote that this optimization is unsafe unless the indexed and the doc-valued documents are the same (elastic/elasticsearch#37475). What is left is a fix trade-off, not an intent argument. Verdict: not intended, a defect.
Recommended A. Trust the terms doc count only when it equals maxDoc (validated)
Use the terms doc count only when it equals maxDoc (every document has a term), like the norms branch, and scan otherwise: 6 lines in FieldExistsQuery.java. The repro then passes, and so does org.apache.lucene.search (2,351 tests) after one testDocValuesQueryMatchesCount assertion is relaxed. Trade-off: keyword fields that only some documents have lose the O(1) count.
} else if (fieldInfo.getIndexOptions() != IndexOptions.NONE) {
  // Terms#getDocCount only counts documents that have at least one term, but a document
  // can have a doc value and no term (a tokenized value that produced no tokens). So it
  // can only show that every document has the field, like the norms shortcut above.
  Terms terms = reader.terms(field);
  if (terms != null && terms.getDocCount() == reader.maxDoc()) {
    count = reader.maxDoc();
  }
}
All options and trade-offs4 options · 503 words
Four options. A was built and validated on main 5adff78bb168; B was run only as a cause check; C and D were not built.
In the doc-values branch, use Terms#getDocCount only to show that every document of the leaf has the field, the rule the norms branch already follows since #477. Otherwise count stays -1 and IndexSearcher#count collects the hits. The points and skip-index branches are unchanged.
} else if (fieldInfo.getIndexOptions() != IndexOptions.NONE) {
  // Terms#getDocCount only counts documents that have at least one term, but a document
  // can have a doc value and no term (a tokenized value that produced no tokens). So it
  // can only show that every document has the field, like the norms shortcut above.
  Terms terms = reader.terms(field);
  if (terms != null && terms.getDocCount() == reader.maxDoc()) {
    count = reader.maxDoc();
  }
}
Trade-offs
- On deletion-free segments where only some documents have a keyword field (
StringField+ same-name doc values), the count becomes a scan of the doc-values iterator instead of O(1). Segments where every document has the field keep O(1); users can get O(1) back with a doc-values skip index (10.5.0 on). No benchmark was run. - One assertion of an upstream test changes, so this is the maintainers' call.
What the checks validated
- Gradle in a clean scratch worktree of
5adff78bb168, OpenJDK 25.0.3, seed DEADBEEF: stock, the repro fails; with the fix it passes with assertions on and off. - With the source change alone,
TestFieldExistsQueryhas 1 failure in 30 tests:testDocValuesQueryMatchesCount, whoseassertSameCount(..., "string", ...)(TestFieldExistsQuery.java:374) expects the O(1)Weight#countfor aStringFieldthat only some documents have. The failure readsexpected:<-1> but was:<44>because the helper passes its arguments in reverse (:888-890). - With that assertion changed to check
searcher.countonly, the wholeorg.apache.lucene.searchpackage passes: 216 test classes, 2,351 tests, 0 failures, 49 skipped. :lucene:core:check -x test(format, ecj lint, forbidden APIs) passes.- An equivalent earlier sketch passed the original 4-test repro (4/4) and an independent 7-test repro (7/7) on
ea57360912ed.
Delete the three-line branch. As a cause check this made all four tests of the original repro pass on main and on 9.1.0.
Trade-offs
Also drops the safe == maxDoc case: strictly more de-optimization than A.
FieldInfo does not record whether a field is tokenized, so a read-time fix cannot tell StringField from a norms-free TextField. Recording per segment that every document with the field produced a term, or the number of documents with a doc value, would keep the shortcut exactly where it is sound.
Trade-offs
Needs a format or API change; not built.
Would keep StringField (indexed with DOCS) on the O(1) path.
Trade-offs
Not sound: a tokenized field can also be indexed with DOCS and produce no tokens (from the code, not run).
From reading Solr's code (not run): SortableTextField indexes analyzed text plus same-name sorted doc values and Solr maps field:* to FieldExistsQuery for doc-values fields, so a SortableTextField with omitNorms may report counts that are too low.
Code reading while modelling FieldExistsQuery#count's shortcuts in Alloy 6.2 (semi-formal). The model's soundness check has a counterexample at 4 documents only for a tokenized, norms-free field with doc values, and none up to 5 documents once that shape is excluded. An end-to-end JUnit test confirmed it; a differential count-versus-hits check on random indexes finds it too.
The method in full100 words
Method: semi-formal. The hypothesis came from reading FieldExistsQuery#count while building an Alloy 6.2 model of its shortcuts against the query's match set (the scorer's iterator).
check countSound(4 documents, 5-bit integers) is satisfiable: the counterexample's field is indexed, tokenized, has doc values and no norms.check countSoundWithoutTokenizedNoNorms(5 documents) is unsatisfiable: with that shape excluded, every shortcut is exact in scope.- Vacuity runs show all three exact branches (terms, points, norms) are reachable.
- An end-to-end JUnit test on the real jars then reproduced it, and a differential check that compares
IndexSearcher#countwith the collected hits on random indexes rediscovers it.
New: no Lucene issue, PR, JIRA entry, list thread or commit, and nothing downstream, describes this defect (re-checked 2026-11-03). Related items are about other defects: #477 fixed the twin pitfall in the norms branch, #16111 judged doc values unaffected, and Elasticsearch fixed the same mechanism in its own code (#89760).
Searches3 searches
No report of this defect (re-checked 2026-11-03 in two independent passes, and again for this doc). Related prior items, none of them this defect:
- #16111 (merged 2026-06, 10.5.0, the PR that gave
count()its current shape): its author raised the empty-token-stream caveat for this method and concluded that only norms were affected. It is about the norms branch and a new with-deletions shortcut; it does not report the doc-values undercount. - #477 / #11299 (LUCENE-10263, 2021): the same
Terms#getDocCountpitfall found and fixed in the sibling norms branch. Different code; the doc-values branch was left as it was. - elastic/elasticsearch#89760, fixed by #90341 (2022): an exists query on a text field with an empty string reported 3 total hits for 4 hits, caused by Elasticsearch's own count shortcut; the fix is in Elasticsearch's code, not in this Lucene code.
- elastic/elasticsearch#37475 (2019): a general warning that this optimization is unsafe unless the indexed and the doc-valued documents are the same; it predates LUCENE-9334 and names no Lucene defect.
- History, not reports: #445 / #11123 (origin of the shortcut), #767 / #11472 (merged into
FieldExistsQuery), #11794 (null guard), #14830 (skip index), #11307 (open: norms vs postings for zero-token documents), #10374 (LUCENE-9334). - Open PRs #16816, #16847 and #14475 touch
FieldExistsQuery.javabut leave the shortcut. #16816 would rewrite constant-scorefield:*automata toFieldExistsQuery, which would widen the reach (from reading its diff). Merged #16582 (2026-09, in 10.6.0) already rewrites sorted-numeric doc-values range queries that cover every value toFieldExistsQuery, another route into this count (from reading its diff, not run).
| Where | When | How | Found |
|---|---|---|---|
| GitHub apache/lucene issues, PRs and commits (incl. the migrated JIRA archive); dev@, java-user@, issues@, commits@; JIRA; Elasticsearch, OpenSearch and Solr trackers; web | 2026-10-25 | the scripted prior-report search, 4 runs, 172 queries; 34 manual GitHub searches; 7 web queries; full reads of 15 related threads | only the related items above |
| Open PRs | 2026-10-25 | the changed files of all 412 open apache/lucene PRs | #16816, #16847, #14475 touch FieldExistsQuery.java; none changes the shortcut |
| Re-check for this doc: GitHub issues, PRs and commits, downstream trackers, the four lists, JIRA | 2026-11-03 | the scripted prior-report search, 45 queries (16 GitHub, 3 commit, 2 downstream, 20 list, 4 JIRA), 3,221 hits; open PRs naming FieldExistsQuery; the latest commits to the file on main; issues and PRs created since 2026-10-25 | nothing new; the last change to the file on main is bfe5c847d3c4 (2026-07-27, fp16 vectors) |
Introduced by #445 (LUCENE-10085, merged 2021-11-19), first released in 9.1.0, and copied into FieldExistsQuery by #767 (9.2.0). Every release run from 9.1.0 to 10.6.0 fails, and so does main; 9.0.0 and 8.11.4 count correctly. Not fixed upstream.
Versions tested10 rows
Introduced by apache/lucene#445, "LUCENE-10085: Implement Weight#count on DocValuesFieldExistsQuery" (issue #11123), merged 2021-11-19: main merge commit 1a869c185b69, branch_9x commit 631d1ad74940 (the commit released in 9.1.0). #767 (LUCENE-10436, 9.2.0) merged the exists queries into FieldExistsQuery and copied the branch unchanged; #11794 (9.4.0) added the terms == null ? 0 guard; #14830 (10.3.0) added a skip-index branch after it; #16111 (10.5.0) moved the skip index first and kept the terms shortcut. Weight#count itself exists only since 9.0.0 (LUCENE-9620).
| Version or commit | Verdict | Result |
|---|---|---|
| 8.11.4, 9.0.0 | not affected | count correct (no Weight#count before 9.0.0; 9.0.0 does not override it) |
branch_9x ee56d314257 vs 631d1ad7494 (#445) | bisect | the parent passes 4/4; #445 fails 4/4 (one class compiled over the 9.1.0 jars) |
| 9.1.0 | wider | fields with norms undercount too; NullPointerException when no document has a term |
| 9.2.0, 9.3.0 | affected | norms-free fields only: 1 for 2 hits; NullPointerException when no document has a term |
| 9.4.0 to 9.12.3 (17 releases) | affected | 1 for 2 hits; 0 for 1 hit when no document has a term |
| 10.0.0 to 10.4.0 (9 releases) | affected | the same; doc values with a skip index undercount too (run on 10.0.0, 10.2.2, 10.3.0 and 10.4.0) |
| 10.5.0, 10.5.1, 10.5.2 | affected | the same; skip-index fields now count correctly (#16111) |
| 10.6.0 | affected | the minimal repro fails, assertions on and off |
main 5adff78bb168 | affected | the minimal repro fails, assertions on and off, 20 of 20 iterations |
main 5adff78bb168 + fix A | not affected | the repro passes; org.apache.lucene.search passes (with one test assertion relaxed) |
A cross-model refute review (OpenAI GPT-5.6), an independent reproducer, a works-as-designed adversary (GPT-5.6) and a devil's-advocate verifier each rated it real with their own tests; the adjudication confirmed it (high confidence). This doc's runs reproduced it on main 5adff78bb168 and four releases and validated the fix.
Checks and verdicts277 words
The reviews, verifiers and judge ran on main ea57360912ed; FieldExistsQuery.java is unchanged between that commit and 5adff78bb168 (its last change upstream is bfe5c847d3c4, 2026-07-27). A re-verification on e1faeba08bde (2026-11-02) and this doc's runs on 5adff78bb168 reproduced it.
| Check | Verdict | What it found |
|---|---|---|
| finder | found | Alloy model (counterexample at 4 documents, sound once the shape is excluded), then a 4-test JUnit repro: 3 fail under assertions on and off, the with-norms control passes; the fix sketch passes 4/4. |
| refute review (OpenAI GPT-5.6, executed) | real (high) | Own test: 2 hits, count 1; root cause agreed; found that the fix sketch breaks testDocValuesQueryMatchesCount. |
| independent reproducer | real | Own public-API test with two oracles (the query's scorer and a doc-values scan): 5 of 7 fail on main with assertions on and off; 25 iterations with random method seeds (seed 1234ABCD, one codec): the 4 bug tests fail every time, the 2 controls always pass; 10.5.2, 9.12.3 and 9.2.0 reproduce. |
| works-as-designed adversary (OpenAI GPT-5.6, executed) | real (high) | Own test fails on main, 10.5.2 and 9.12.3; rated the intended-behaviour argument moderate. |
| devil's-advocate verifier | real | The trigger index passes CheckIndex; stop-words-only values over 3 segments: count 3 for 6 hits on main and 10.5.2. |
| adjudication | confirmed (high) | Re-ran the independent test with a new seed (5EED1234): 5 of 7 fail under assertions on and off; both controls pass. |
| this doc | reproduced; fix validated | One-method repro fails on main 5adff78bb168 (gradle and the JUnit runner, assertions on and off, 20 of 20 iterations) and on the 10.6.0, 10.5.2, 9.12.3 and 9.2.0 jars; fix A passes it and the org.apache.lucene.search package. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 477 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,057 words
- Registry title
- FieldExistsQuery#count undercounts documents whose norms-free text field analyzes to no tokens but still has a doc value, so IndexSearcher#count is too low
- Area
- search / FieldExistsQuery count
- Priority
- Medium, rank 75: Default config since 9.1: FieldExistsQuery#count silently undercounts documents whose norms-free text value analyzes to no tokens while a same-name doc value exists, realistic data that Elasticsearch hit and fixed in its own code, limited to count paths and an uncommon field layout.
- Impact class
- silent wrong results
- Impact note
- Applications that index a tokenized field with norms omitted plus a doc-values field of the same name (no doc-values skip index) and have at least one value that analyzes to no tokens (empty string, whitespace or stop words only); default IndexWriterConfig, codec and searcher; ordinary scale; only count paths are wrong (IndexSearcher#count, TotalHitCountCollector(Manager), BooleanQuery counts built from the clause) and only on segments without deletions, while hit lists and top-k totalHits are correct; released since 9.1.0.
- Summary
- You index a text field with norms turned off together with a doc-values field of the same name, some document's text analyzes to no tokens (for example an empty string), and you call IndexSearcher#count(new FieldExistsQuery(field)). You expect the count to equal the number of documents the query returns, because the query matches every document that has a doc value. Instead, on a segment without deletions, Weight#count returns Terms#getDocCount, which counts only documents with at least one term, so the count is 1 for 2 hits, or 0 for 1 hit when no document in the segment has a term.
- Introduced
- apache/lucene#445 (LUCENE-10085, 'Implement Weight#count on DocValuesFieldExistsQuery'): branch_9x 631d1ad74940 (the commit released in 9.1.0) and main merge commit 1a869c185b69 [read: git show; exec: commit-level A/B over the 9.1.0 jars, parent ee56d314257 passes 4/4 and 631d1ad7494 fails 4/4]; the doc-values branch was carried unchanged into FieldExistsQuery by #767 (LUCENE-10436, 9.2.0) (2021-11-19)
- First affected version
- 9.1.0 (through DocValuesFieldExistsQuery; FieldExistsQuery itself first ships in 9.2.0)
- Affected versions
- every release from 9.1.0 to 10.5.2 (32 releases: 9.1.0, 9.2.0-9.12.3, 10.0.0-10.5.2), 10.6.0 (released 2026-10-29; executed 2026-11-03, -ea and -da: the one-method repro counts 1 for 2 hits) and main ea57360912ed [exec, hunt repro on each release jar]; 9.0.0 and 8.11.4 count correctly [exec] (no count() override in 9.0.0; Weight#count does not exist before 9.0.0 [read]); not fixed upstream [read]. Variations [exec]: in 9.1.0 a tokenized field with norms also undercounts; in 9.1.0-9.3.0 a segment where no document has a term throws NullPointerException from count() instead of returning a wrong 0 (changed by #11794 in 9.4.0); doc-values fields with a skip index also undercount before 10.5.0 (executed on 10.0.0, 10.2.2, 10.3.0 and 10.4.0) and count correctly from 10.5.0 on, a side effect of #16111
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check and a prior-report search; not yet triaged by a person.
- Found by
- semi-formal: Alloy, code reading; also reached by fuzzing/PBT
- Upstream and prior reports
- related items only, no report of this defect (re-checked 2026-11-03). Searched 2026-10-25 (a scripted prior-report search, 4 runs with 172 queries over GitHub issues/PRs and commits, downstream repos, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 34 manual GitHub searches on apache/lucene, Solr, OpenSearch and Elasticsearch; 7 web queries; file lists of all 412 open apache/lucene PRs): no issue, PR, list thread or JIRA entry reports this undercount, no upstream fix, no open PR fixes it. Related: #16111 (2026-06, the PR that gave count() its current shape; its author raised the empty-token-stream caveat for this method and concluded it affects only norms); #477 / #11299 (LUCENE-10263, 2021-11; the same Terms#getDocCount pitfall found and fixed in the sibling norms branch); elastic/elasticsearch#89760, fixed by #90341 (2022; same symptom and mechanism in Elasticsearch's own count shortcut, not in Lucene); elastic/elasticsearch#37475 (2019; a general warning that this optimization is unsafe unless indexed and doc-valued documents coincide). Related history: #445 / #11123 (origin), #767, #11794, #14830, #11307 (open, norms vs postings); open #16816, #16847 and #14475 touch FieldExistsQuery.java but leave the proxy unchanged
- Lucene commit tested
- main
5adff78bb168(gradle in a scratch worktree and the JUnit runner, assertions on and off) and the released 10.6.0, 10.5.2, 9.12.3 and 9.2.0 jars, 2026-11-03. Earlier runs: mainea57360912edande1faeba08bde; 8.11.4, 9.0.0 and every release from 9.1.0 to 10.5.2; the introducing commit and its parent.
- Finding record
lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:170-219 (scorerSupplier: without norms or vectors the query iterates the doc values), :222-274 (count), :247-256 (no skip index, no deletions: points or terms doc count used as the doc-values count; terms == null -> 0), :261-269 (count == 0 -> 0; count == maxDoc -> numDocs; count >= 0 and no deletions -> count), :140-153 (rewrite to MatchAllDocsQuery only when the terms doc count == maxDoc, sound)lucene/core/src/java/org/apache/lucene/search/Weight.java:181-198 (count: 'the number of live documents that match', -1 when unknown, overrides must be accurate)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:490-495 (count: 'Count how many documents match the given query')lucene/core/src/java/org/apache/lucene/index/Terms.java:117-121 (getDocCount: 'the number of documents that have at least one term for this field')lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1875-1876 ('the field exists in this document, but it did not have any indexed tokens')lucene/core/src/test/org/apache/lucene/search/TestFieldExistsQuery.java:577-581 (norms branch: empty token stream means 'we can't use the shortcut'), :347 (testDocValuesQueryMatchesCount pins the O(1) count for StringField + SortedDocValuesField)SECURITY.md:28, 50 (threat model)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:38-41, (at 5adff78bb168) :170-219 (:188-209), :222-274 (:231-237, :244-256, :261-270), :140-154lucene/core/src/java/org/apache/lucene/index/Terms.java:117-121 (at 5adff78bb168)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1926-1932 (at 5adff78bb168)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:491-529; (at 5adff78bb168) TotalHitCountCollector.java:48; BooleanWeight.java:196, :206-231
- Who is affected
lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:244-256 (at 5adff78bb168) (skip index first; terms shortcut only for indexed fields)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/Weight.java:181-198; (at 5adff78bb168) IndexSearcher.java:491-494lucene/core/src/java/org/apache/lucene/index/Terms.java:117-121 (at 5adff78bb168)lucene/core/src/test/org/apache/lucene/search/TestFieldExistsQuery.java:347, (at 5adff78bb168) :577-581
- Suggested fix
lucene/core/src/test/org/apache/lucene/search/TestFieldExistsQuery.java:347-386, (at 5adff78bb168) :884-891
- Diagrams
lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:188-209, (at 5adff78bb168) :247-270
- TestFieldExistsQueryCountNoTokens.java (one test method):
repro/LFV-086/TestFieldExistsQueryCountNoTokens.java(52 lines)
A walk-through of the one-method repro above (its two documents), made from the code at 5adff78bb168 and a diagram probe executed on the repro's index and on variants of it; the PNG is the summary still.
assets/LFV-086/bug.png(477 KB)