addOrdinalTuples opens the new document before it reads and checks the ordinal. If a document's first tuple is rejected, that document stays open with 0 values, and the next value for the field, from a later document, records it with a value count of 0. The flush code does not allow a count of 0.
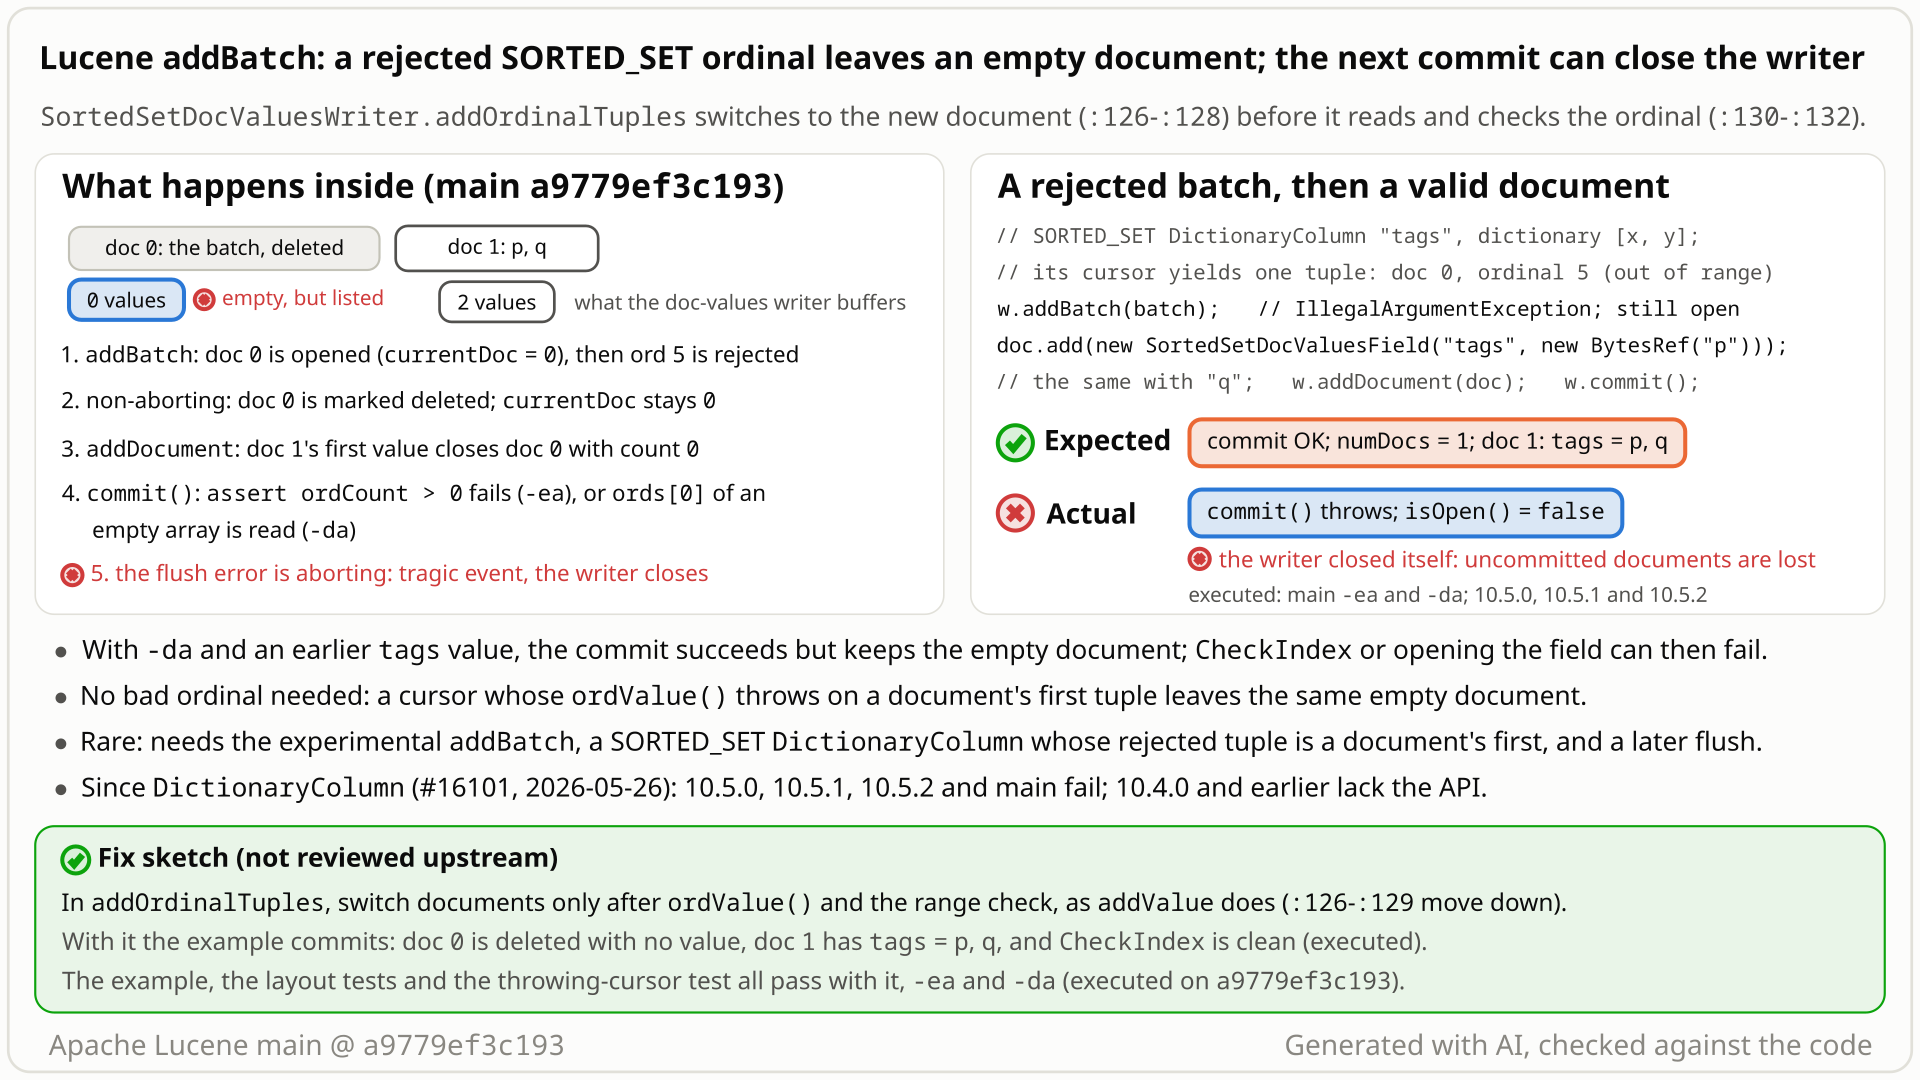
- With the experimental
IndexWriter#addBatch, add a one-document batch whose SORTED_SETDictionaryColumn"tags" has a 2-entry dictionary[x, y]and one tuple: doc 0, ordinal 5. One document is already committed and 5 more are buffered. - Lucene rejects the batch:
IllegalArgumentException: ordinal 5 is out of range [0, 2). The writer stays open with no tragic exception, as after any rejected document. You expect it to leave only consistent state behind (at most a deleted document). - Add a valid document with tags
pandq, then callcommit(). You expect the commit to succeed, with 7 documents in the index. - Instead
commit()throws (AssertionErrorwith assertions on,ArrayIndexOutOfBoundsExceptionwith them off, because no earlier document in this segment hastags), and the writer closes itself. The reopened index has 1 of 7 documents. The doc-values writer had opened the batch's document before it checked the ordinal, so the flush met a document with 0 values. - With assertions off, when an earlier document in the segment already has a
tagsvalue, the commit succeeds instead but keeps the empty document. Example: a 1-value document, the rejected batch, then a 2-value document; openingtagsthrowsNullPointerException. Other layouts failCheckIndex, or show nothing. A cursor whoseordValue()throws, with every ordinal valid, does the same as a bad ordinal.
Users of the experimental IndexWriter#addBatch with a doc-values-only SORTED_SET DictionaryColumn, when a document's first tuple is rejected or throws and they keep indexing. With assertions on, and with them off only if that document comes first in its segment, the writer closes and loses uncommitted documents. Otherwise the commit can leave a field that fails CheckIndex or cannot open.
Mechanism, terms and numbers900 words
IndexWriter#addBatch (experimental, since 10.5.0) indexes documents column by column. For a SORTED_SET DictionaryColumn, Lucene range-checks the ordinal of every (docID, ordinal) tuple. It rejects an ordinal outside the dictionary with IllegalArgumentException, treats that as a non-aborting exception (the batch's documents are marked deleted) and leaves the writer open.
But SortedSetDocValuesWriter.addOrdinalTuples switches to the new document before it reads and checks the ordinal. When the rejected tuple is the first one of a document, that document stays open with no values, and the next value for the field, from a later document, records it with a value count of 0.
With assertions on, the next commit always fails (AssertionError). With them off it can fail only when the rejected document is the segment's first with the field, as in the repro, where it fails with ArrayIndexOutOfBoundsException. A failed flush is a tragic event, so the writer closes and every uncommitted document is lost: 1 of 7 survives in the repro. Otherwise, with assertions off, the commit succeeds but keeps the empty document: the field then throws NullPointerException on open or fails CheckIndex, or, when no document has more than one value, shows nothing. A cursor whose ordValue() throws on a document's first tuple, with every ordinal valid, does the same.
The single-valued SORTED path validates first. The fix is to switch documents after the check, as addValue already does.
addBatch:IndexWriter#addBatch(ColumnBatch)(experimental, since 10.5.0) adds N documents given as columns, one field at a time.DictionaryColumn: a column of string values given as a fixed dictionary plus, per document, ordinals into it. For SORTED_SET doc values itsOrdinalsTupleCursoryields(docID, ordinal)pairs; a document with 3 values yields 3 pairs with the same docID.- The doc-values writer (
SortedSetDocValuesWriter) buffers one in-memory segment's values. It keeps one open document (currentDoc) and its values. When a value for another document arrives,finishCurrentDoc()records the open one: its value count and its doc ID indocsWithField. - Non-aborting exception: an exception that rejects the document(s) being added but keeps the writer and its buffered documents. Lucene marks the rejected documents deleted. An aborting exception, such as any failure during a flush, is tragic: the writer rolls back to the last commit and closes.
- Every SORTED_SET
DictionaryColumn, dense or sparse, goes toSortedSetDocValuesWriter.addOrdinalTuples(IndexingChain.java:1244-1248). Only sparse columns were executed. A column that is also stored or indexed reads every ordinal in the row pass first (ColumnFieldAdapter.java:79-81), so an out-of-range ordinal fails there and never reaches this loop: doc-values-only columns are the exposed ones. - For each tuple the loop first switches documents:
if (docID != currentDoc) { finishCurrentDoc(); currentDoc = docID; }(SortedSetDocValuesWriter.java:126-129). Only then does it callcursor.ordValue()(:130) and range-check the ordinal (:131-140). - When the first tuple of a document is rejected, or
ordValue()throws,currentDocalready names the new document, which has 0 values. - The exception is non-aborting.
DocumentsWriterPerThread.updateBatchonly marks the batch's documents deleted (:349-354), and the writer'scurrentDocstays where it is. - The next value for the field, from any later document, calls
finishCurrentDoc(). That records the rejected document with a count of 0 (:162-193). - At flush,
BufferedSortedSetDocValues.nextDocassertsordCount > 0(:360), so with assertions on every layout fails. With assertions off, the Lucene90 consumer reads a value that is not there (Lucene90DocValuesConsumer.java:403, 1005), but only when the empty document is the first with the field in the segment; otherwise the flush succeeds (see the numbers below). - Any exception during a flush is aborting (
DocumentsWriterPerThread.java:585-587, 594-604), so a failed flush closes the writer.
addValue, the per-document and BinaryColumn path into the same writer, validates first and switches after (:84-105). The single-valued SortedDocValuesWriter.addOrdinalTuples also records the document only after it translates the ordinal (SortedDocValuesWriter.java:139-142).
Default IndexWriterConfig and codec. 1 committed document, 5 buffered, a rejected 1-document batch (dictionary [x, y], ordinal 5), then a document with tags p, q:
commit()throwsAssertionError(-ea) orArrayIndexOutOfBoundsException: Index 0 out of bounds for length 0(-da);isOpen()is false;- the reopened index has 1 of 7 documents.
With -da and NoMergePolicy, take a 1-value document, the rejected batch, then a 2-value document. The commit succeeds and keeps the 0-value document. The writer has written the field as multi-valued, but omitted the ord addresses, because 3 values = 3 documents (Lucene90DocValuesConsumer.java:924-933). Opening the field then throws NullPointerException: Cannot read field "numBlocks" because "meta" is null (Lucene90DocValuesProducer.java:2303). With 3 values in the last document, CheckIndex fails instead ("docValueCount=0 for docID=1"); an integrity-level CheckIndex also fails for [2] | rejected | [2] and [1] | rejected | [2, 2, 2]. With 1 value in every document nothing is visible: the field is written as single-valued, and the deleted document gets a stale copy of the previous document's ordinal (SortedSetSelector.java:165-168). So -da does not always fail. The hunt's sweep read back the live data of 589 of 605 -da layouts exactly, and the other 16, its cells where the rejected document came first, failed at commit; its CheckIndex ran without a level set and skipped the doc-values check, so the 589 do not show a clean index.
Exposure and likelihood280 words
- Who is hit.
- Applications that call
IndexWriter#addBatchwith a SORTED_SETDictionaryColumnthat only feeds doc values, when the first tuple of some document is rejected (an ordinal outside the dictionary) or itsordValue()throws, and that catch the exception and keep indexing. - Default
IndexWriterConfigand codec; dense and sparse columns take the same path (only sparse ones were executed). A column that is also stored or indexed reads every ordinal in the row pass first, so an out-of-range ordinal fails there instead. - SORTED
DictionaryColumns andBinaryColumns that feed SORTED_SET are not affected, nor is a bad tuple after a valid tuple of the same document.
- Applications that call
- Why it bites.
- The rejection looks clean:
isOpen()is true andgetTragicException()is null. - The damage shows up at the next flush or commit. Its exception, an
AssertionErrororArrayIndexOutOfBoundsExceptioninside the codec, does not point back at the batch. - The rollback discards every document since the last commit, from every thread that shares the writer.
- The rejection looks clean:
- Persisted damage with
-da, the production default. When an earlier document in the segment already has the field, the commit succeeds and keeps the 0-value document.- Some layouts then commit a segment whose SORTED_SET field cannot be opened, sorted on or merged. An independent probe saw a later writer's
forceMerge(1)fail on it and report an unrecoverable error. - Other layouts fail
CheckIndex(integrity level); when no document has more than one value, nothing is visible.
- Some layouts then commit a segment whose SORTED_SET field cannot be opened, sorted on or merged. An independent probe saw a later writer's
- How likely. Rare: an opt-in experimental API, an error path, and no known downstream user. A read-only code search of Elasticsearch, OpenSearch and Solr found no SORTED_SET
DictionaryColumnbuilder; Elasticsearch uses the column package throughBinaryColumn, which is not affected.
The test shows that after IndexWriter#addBatch rejects a SORTED_SET DictionaryColumn whose only tuple has an out-of-range ordinal, committing a later ordinary document with two SORTED_SET values fails.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.SortedSetDocValuesField;
import org.apache.lucene.document.column.Column;
import org.apache.lucene.document.column.ColumnBatch;
import org.apache.lucene.document.column.DictionaryColumn;
import org.apache.lucene.document.column.OrdinalsTupleCursor;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.BytesRef;

public class TestRejectedSortedSetOrdinalBreaksCommit extends LuceneTestCase {

  public void testCommitAfterRejectedOrdinal() throws Exception {
    DictionaryColumn column =
        new DictionaryColumn(
            "tags",
            SortedSetDocValuesField.TYPE,
            Column.Density.SPARSE,
            List.of(new BytesRef("x"))) {
          @Override
          public OrdinalsTupleCursor tuples() {
            return new OrdinalsTupleCursor() {
              int doc = -1;

              @Override
              public int nextDoc() {
                doc = doc == -1 ? 0 : DocIdSetIterator.NO_MORE_DOCS;
                return doc;
              }

              @Override
              public int ordValue() {
                return 1;
              }
            };
          }
        };
    ColumnBatch batch =
        new ColumnBatch() {
          @Override
          public int numDocs() {
            return 1;
          }

          @Override
          public Iterable<Column> columns() {
            return List.of(column);
          }
        };
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      // ordinal 1 is out of range: expected a rejection that leaves no trace; actual: commit fails
      expectThrows(IllegalArgumentException.class, () -> w.addBatch(batch));
      Document doc = new Document();
      doc.add(new SortedSetDocValuesField("tags", new BytesRef("p")));
      doc.add(new SortedSetDocValuesField("tags", new BytesRef("q")));
      w.addDocument(doc);
      try {
        w.commit();
      } catch (Throwable t) {
        throw new AssertionError("expected commit to succeed after the rejection, got " + t, t);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-094/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestRejectedSortedSetOrdinalBreaksCommit
- Expected vs actual
- Expected: the commit succeeds (the rejected batch leaves no trace); actual: the rejected document was already opened and is flushed with zero values, so commit throws (AssertionError
ordCount > 0with -ea, ArrayIndexOutOfBoundsException with -da).
More files, environment, full output45 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected commit to succeed after the rejection, got java.lang.AssertionError
       org.apache.lucene.index.TestRejectedSortedSetOrdinalBreaksCommit.testCommitAfterRejectedOrdinal(TestRejectedSortedSetOrdinalBreaksCommit.java:84)
     Caused by: java.lang.AssertionError
       org.apache.lucene.index.SortedSetDocValuesWriter$BufferedSortedSetDocValues.nextDoc(SortedSetDocValuesWriter.java:360)
       org.apache.lucene.codecs.lucene90.Lucene90DocValuesConsumer.isSingleValued(Lucene90DocValuesConsumer.java:961)
       org.apache.lucene.codecs.lucene90.Lucene90DocValuesConsumer.addSortedSetField(Lucene90DocValuesConsumer.java:977)
       org.apache.lucene.codecs.perfield.PerFieldDocValuesFormat$FieldsWriter.addSortedSetField(PerFieldDocValuesFormat.java:127)
       org.apache.lucene.index.SortedSetDocValuesWriter.flush(SortedSetDocValuesWriter.java:301)
[...]- Lucene itself checks the ordinal and rejects it as a non-aborting
IllegalArgumentException, leaving the writer open and usable. - Non-aborting exceptions must leave consistent state (the
DocumentsWriterdesign note); upstream tests require indexing to continue after a cursor throws mid-batch. - The SORTED version of the same test passes, and a cursor that throws with valid ordinals hits the same bug.
The full argument232 words
- Lucene validates this input on purpose.
- The range check is in the code (
SortedSetDocValuesWriter.java:131-140). - The dense cursor documents it: "The indexing path validates this on every call and throws IllegalArgumentException on violation" (
OrdinalsCursor.java:50-52). TestColumnBatchDictionaryColumn#testOutOfRangeOrdSparseThrowsasserts the rejection on the sparse tuple path, but only for SORTED (:391-407). Re-typed to SORTED_SET, itsclose()fails.
- The range check is in the code (
- The design note. Non-aborting exceptions "can still partially update the index structures. These updates are consistent, ... we immediately mark the document as deleted so that the document is always atomically ("all or none") added to the index" (
DocumentsWriter.java:76-79).addDocumentpromises that after an Exception "the index will be consistent" (IndexWriter.java:1465);addBatch's short javadoc (:1528-1536) does not restate it. - Recovery tests. The four
TestColumnBatchIndexing#*ThrowMidBatchRecoverstests (:682, 740, 794, 841) commit and keep indexing after a cursor throws mid-batch. - Siblings validate first.
SortedSetDocValuesWriter.addValue(:84-105).SortedDocValuesWriter.addOrdinalTuples(:123-146), added by the same commit.- That commit (#16101) also gave
SortedDocValuesWriter.addDenseOrdinalValuesatry/finallythat keeps the writer consistent when the cursor throws (:169-182).
- History.
- #16101 has one approving review and no discussion of the order.
- #16553 (2026-09-01) fixed the same class of defect in stored fields: a non-aborting exception left per-document state, and the next flush failed.
- In #16734, a reviewer asked that the dense vector path record doc IDs only after validation.
The devil's-advocate check169 words
The strongest case for "intended". OrdinalsTupleCursor says only that each ordinal "must be in" range (OrdinalsTupleCursor.java:26, 46-47), without the dense cursor's "validates and throws" sentence. addBatch and the cursor are @lucene.experimental. So, the argument goes, the caller broke a precondition, and what follows is undefined. An independent reviewer from another model family (OpenAI GPT-5.6) rated this "moderate" and still judged the bug real (high).
Why it fails.
- Lucene does not treat the ordinal as undefined behaviour: it checks it, throws a non-aborting exception and keeps the writer open.
- A cursor whose
ordValue()throws with every ordinal valid breaks no precondition, and hits the same defect. - The SORTED version of the same test passes.
- No javadoc, CHANGES or MIGRATE entry says that a failed
addBatchneedsrollback().
One honest limit: the upstream recovery tests throw from nextDoc() or the dense fill, not from ordValue(), and none uses a DictionaryColumn. So the ordValue() case rests on the general non-aborting contract, not on a word-for-word test.
Recommended A. Switch documents only after ordValue() and the range check (recommended)
In addOrdinalTuples, read and range-check the ordinal first, and switch documents only after that, as addValue does (+6/-4 lines, the same statements reordered). With it, the new test passes 6 of 6, and 11 test classes, including the new one, pass (254 tests, 0 failures), with assertions on and off.
      assert docID >= currentDoc;
      // Read and validate the ordinal before switching documents, like addValue: if ordValue()
      // throws or the ordinal is rejected, no document may be left open without values.
      int ord = cursor.ordValue();
      if (ord < 0 || ord >= dictionary.size()) {
        throw new IllegalArgumentException(/* ... is out of range [0, n) */);
      }
      if (docID != currentDoc) {
        finishCurrentDoc();
        currentDoc = docID;
      }
All options and trade-offs3 options · 579 words
Option A is the recommended fix and was run through gradle. B is a design alternative that was not run. C is a safety net, run against the new test only.
A. Switch documents only after ordValue() and the range check (recommended) (validated by the checks)
Move if (docID != currentDoc) { finishCurrentDoc(); currentDoc = docID; } below the range check in SortedSetDocValuesWriter.addOrdinalTuples. A rejected or throwing first tuple then leaves currentDoc on the previous, complete document. A rejected later tuple leaves the open document with at least one value: a consistent, deleted document.
      assert docID >= currentDoc;
      // Read and validate the ordinal before switching documents, like addValue: if ordValue()
      // throws or the ordinal is rejected, no document may be left open without values.
      int ord = cursor.ordValue();
      if (ord < 0 || ord >= dictionary.size()) {
        throw new IllegalArgumentException(/* ... is out of range [0, n) */);
      }
      if (docID != currentDoc) {
        finishCurrentDoc();
        currentDoc = docID;
      }
Trade-offs
- No extra work per tuple; the same statements in a different order.
- It covers both triggers, the rejected ordinal and a throwing
ordValue(). After the switch the loop still callsdictionary.get(ord),hash.addandArrayUtil.grow. For a dictionary that theDictionaryColumnconstructor checked and that is not changed later, these fail only at hard size limits (ArithmeticExceptionat the byte pool's 2 GB limit,IllegalArgumentExceptionbeyond the maximum array length). Those are non-aborting too and could still leave a document open; option C covers that case. - It does not add the missing tuple doc-ID checks of a separate bug in the same loop, which needs its own change.
What the checks validated
- Scratch worktree of main
a9779ef3c193, gradle, seed DEADBEEF,-Ptests.asserts=trueand=false. - The new test passes 6 of 6.
- 11 classes, 254 tests, 0 failures, 3 skipped:
org.apache.lucene.document.column.*(7 classes, includingTestColumnBatchDictionaryColumnand the new test),TestColumnBatchIndexing,TestDocValuesIndexing,TestIndexWriterExceptionsandTestDocValues. - Static checks pass:
ecjLintMain,ecjLintTest,forbiddenApisandcheckGoogleJavaFormat. - Earlier, the same reordering made the finder's, the independent reproducers', the cross-model reviewer's and the security probe's tests pass, with
-eaand-da. - Not run: the full
./gradlew check, other modules, x86 and benchmarks.
Wrap the loop body in try/finally, like SortedDocValuesWriter.addDenseOrdinalValues (SortedDocValuesWriter.java:169-182). When a tuple fails while the open document has no values, leave the writer with no open document.
Trade-offs
Broader: it covers any exception after the switch. The "no open document" state already exists: currentDoc == -1, which finishCurrentDoc() skips (SortedSetDocValuesWriter.java:163-165). Since the previous document has already been recorded, B sets currentDoc back to -1; setting it back to the previous document would record that document twice. More code than A. Not run.
In finishCurrentDoc(), return early when currentUpto == 0. Then docsWithField and the value counts never list an empty document, whatever left it open (+5 lines).
Trade-offs
One more branch per document. It hides the wrong order instead of fixing it: currentDoc still names the rejected document. Good as defence in depth next to A, weaker on its own.
What the checks validated
run on its own, without A: the new test 6 of 6 and TestColumnBatchDictionaryColumn 25 of 25 pass with assertions on and off; the wider suites of A were not run for C
An application that fills a SORTED_SET DictionaryColumn from request data, or decodes it lazily in a cursor that can throw, can avoid it by checking every ordinal and decoding fully before addBatch; no downstream product is known to build such columns.
Semi-formal. While modelling the addBatch doc-values writers, a hunting AI tool saw the order in the code. A small Z3 model showed that a document with 0 ordinals after a rejected one is reachable. A failure-injection sweep on the real jar then hit it in all 605 layouts with assertions on.
The method in full140 words
- The hunt unit. It covered the column-oriented
addBatchpass. Its AI tool modelled the commit state of the column-pass doc-values writers in Z3 (dense_commit.py). Check W4 asked whether a document can be registered with 0 ordinals after a rejected ordinal: reachable (sat). - The sweep. A failure-injection sweep on the real jar, "dict SORTED_SET sparse bad ordinal", varied the layout around one bad ordinal over 605 grid points. With
-eaall 605 failed. With-da, 16 failed at commit withArrayIndexOutOfBoundsException, and in 589 the live data read back exactly. ItsCheckIndexran without a level set and skipped the doc-values check, so the 589 do not show a clean index. - The candidate. The AI tool then wrote the JUnit repro and the fix sketch. An independent reproducer found the
-daunreadable-field layouts and the throwing-cursor trigger.
No prior report found (searched 2026-10-26): 51 tool queries over GitHub, the mailing lists, the JIRA archive and the web; full-text scans of every PR and issue since the API landed; 13 manual searches including Elasticsearch, OpenSearch and Solr. Related, not this bug: #16101 (introduced it), #16553 (same class, stored fields).
Searches5 searches
No issue, PR, review comment, list post, JIRA entry or downstream report describes this bug, and no open PR touches addOrdinalTuples. DictionaryColumn was merged on 2026-05-26, so any report must fall after that date. A search cannot prove that something was never reported.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; dev@, java-user@, issues@, commits@; JIRA archive; web | 2026-10-26 | a search tool, 51 queries (16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list, 4 JIRA-archive, 6 web), plus the finder's earlier 21-query run | only #16101 and its commit as high overlap |
| GitHub (GraphQL, independent of search ranking) | 2026-10-26 | changed files of all 412 open PRs and of 650 closed PRs updated since 2026-05-02; full text of 800 PRs and 240 issues updated since 2026-05-20 | no report; no open PR touches addOrdinalTuples |
| GitHub manual searches (apache/lucene, Elasticsearch, OpenSearch, Solr) | 2026-10-26 | 13 searches, e.g. addOrdinalTuples, OrdinalsTupleCursor, "SORTED_SET" ordinal addBatch, DictionaryColumn, ColumnBatch exception | no report |
| lists.apache.org | 2026-10-26 | dev@ and java-user@ (columnar, addBatch, DictionaryColumn; the whole "[DISCUSS] Column-oriented indexing API for IndexWriter" thread); builds@, issues@, commits@ | no report |
| Related items (read) | 2026-10-26 | bodies, reviews and comments | #16101 (introduced it; one LGTM, no discussion), #16228 (last change, order kept), #16734 (a reviewer asked to record doc IDs only after validation in the vector path), #16553 and #7111 / LUCENE-6049 (same class, other code) |
Introduced by #16101, which added DictionaryColumn (merged 2026-05-26, first released in 10.5.0); the method's first version already had the wrong order. 10.5.0, 10.5.1, 10.5.2 and main fail with -ea and -da; 10.4.0 and earlier have no addBatch.
Versions tested5 rows
Introduced by e79c6780627f (#16101 "Add DictionaryColumn for SORTED / SORTED_SET dvs", by Tim-Brooks, merged 2026-05-26, milestone 10.5.0; branch_10x backport 8a9e55f254d1). git blame, git log -L and git log -S show that the method's first version already switched documents before the check. The only later change, #16228 (scratch array), keeps the order. No build was made at the commit or its parent, which lacks the API; the releases bracket it. branch_10_6 (10.6.0, released 2026-10-29) and the unreleased branch_10x and branch_10_5 have the same code (read-only check of the branch heads, 2026-10-24).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's JUnit through gradle: 4 of 6 fail with assertions on and off, the 2 controls pass; the finder's JUnit fails |
main ea57360912ed | affected | the finder's JUnit fails with -ea and -da; the -da unreadable-field layout reproduces |
| 10.5.0, 10.5.1, 10.5.2 | affected | the finder's JUnit fails with -ea (AssertionError) and -da (ArrayIndexOutOfBoundsException); the -da unreadable-field layout reproduces on 10.5.0 and 10.5.2 |
| 10.4.0, 9.12.3 | API absent | compile errors: no org.apache.lucene.document.column package and no IndexWriter#addBatch |
fix option A on a9779ef3c193 | fix | 6 of 6, and 254 tests in 11 classes, pass with assertions on and off |
Independent reproducers and a cross-model reviewer (OpenAI GPT-5.6) each called it real and reproduced it with their own tests, with assertions on and off; the adjudication re-ran the first reproducer's tests and confirmed it (high). Other cross-model reviews ended without a verdict. This doc's gradle runs reproduce it on main a9779ef3c193.
Checks and verdicts322 words
All checks before this doc ran on main ea57360912ed. The refute and root-cause reviews by OpenAI GPT-5.6 stopped without a final answer. The finder re-ran the refute reviewer's own test: the invalid-first-tuple case fails, and its control passes.
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | The JUnit fails 1 of 1 with -ea and -da, also on 10.5.2; the fix sketch passes. First take: crash. |
| Cross-model reviews, refute and root-cause lenses (OpenAI GPT-5.6) | no verdict | The refute reviewer's own test, re-run by the finder: the invalid-first-tuple case fails, the invalid-second-tuple control passes, and both pass with the fix. |
| Independent reproducer | real | Its own public-API tests fail 3 of 5 with -ea and -da, 40 of 40 executions (20 iterations of 2 tests), also on 10.5.0 and 10.5.2. It found the -da unreadable-field and CheckIndex layouts and the throwing-cursor trigger. Its own fix passes. |
| Works-as-designed review (OpenAI GPT-5.6) | real (high) | Rated the "must be in range" argument moderate; its own recovery test and fix test reproduce on main with -ea and -da. |
| Devil's advocate | real | The upstream test re-typed to SORTED_SET fails at close(). Default-config tragic test: the writer closes and the reopened index keeps 1 document. The fix passes 5 of 5. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's tests (3 of 5 fail with -ea and -da) and the -da layout test (3 of 4 fail); the fix passes all. Impact class: data corruption. |
| Follow-up and security probe | release bracket; not security-sensitive | 10.5.0-10.5.2 fail; 10.4.0 and 9.12.3 lack the API. In the probe, a later writer's forceMerge(1) fails on the damaged segment; all pass with the fix. |
| This doc's gradle runs | reproduced; fix A validated | On main a9779ef3c193: 4 of 6 fail with assertions on and off, and the controls pass. With fix A, 6 of 6 pass, and so do 254 tests in 11 classes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 512 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,240 words
- Registry title
- A SORTED_SET DictionaryColumn tuple that addBatch rejects (out-of-range ordinal, or ordValue() throws) leaves an empty document in the doc-values buffer, so the next flush fails and closes the IndexWriter, or with -da commits a segment whose field cannot be read
- Area
- index / columnar addBatch (DictionaryColumn SORTED_SET doc values, SortedSetDocValuesWriter)
- Priority
- Medium, rank 153: A rejected SORTED_SET DictionaryColumn tuple in addBatch looks clean but makes the next flush close the writer and lose uncommitted docs, or with -da commit an unreadable field, an error path of the experimental addBatch API.
- Impact class
- data corruption
- Impact note
- Hits only applications that call the experimental IndexWriter#addBatch (first released in 10.5.0) with a SORTED_SET DictionaryColumn and have the first tuple of some document rejected (an ordinal outside the dictionary) or have their own cursor's ordValue() throw there; default IndexWriterConfig, codec and directory, ordinary scale (one bad tuple); the rejection itself looks clean, but the next flush or commit of that in-memory segment closes the writer as a tragic event and loses every uncommitted buffered document (with -ea and -da), and with assertions disabled some value layouts instead commit a segment whose SORTED_SET field cannot be opened, sorted on or merged, or that fails CheckIndex; no downstream product is known to build SORTED_SET DictionaryColumns.
- Summary
- You add a batch with IndexWriter#addBatch whose SORTED_SET DictionaryColumn gives the first value of some document an ordinal outside the dictionary (or whose cursor throws while returning that ordinal); Lucene rejects the batch with an IllegalArgumentException, the writer stays open with no tragic exception, and you keep indexing. You expect the rejected batch to leave no trace, as Lucene promises for non-aborting exceptions (the batch's documents are marked deleted and the index stays consistent), so a later document with two SORTED_SET values commits and reads back normally. Instead the doc-values writer had already opened the rejected document before it checked the ordinal and records it with zero values, so the next commit fails (AssertionError with -ea, ArrayIndexOutOfBoundsException with -da), closes the writer and loses all uncommitted documents, or, with -da and some value layouts, succeeds but writes a segment whose field throws NullPointerException when opened or fails CheckIndex.
- Introduced
- e79c6780627f (#16101 'Add DictionaryColumn for SORTED / SORTED_SET dvs', main; branch_10x backport 8a9e55f254d1, contained in releases 10.5.0-10.5.2), which added SortedSetDocValuesWriter.addOrdinalTuples with the document switch before the ordinal check [read: git blame, git log -L and git log -S in the full-history clone; the defect is in the method's first version, and its only later change (#16228, scratch array) keeps the order; releases bracket it: 10.4.0 cannot compile the repro, 10.5.0 fails (exec); no build at the commit or at its parent, which lacks the API] (2026-05-26 (#16101 merged))
- First affected version
- 10.5.0 [exec]
- Affected versions
- 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed [exec: the finder repro fails on each with -ea and -da; the independent reproduction's tests fail on 10.5.0 and 10.5.2 with -ea and -da; the unreadable-segment layout test fails on 10.5.0, 10.5.2 and main with -da]; branch_10_6 (10.6.0, released 2026-10-29), branch_10x and branch_10_5 have the same code [read: read-only GitHub contents check of the branch heads, 2026-10-26]; not applicable: 10.4.0 and every earlier release, including 9.12.3 (no org.apache.lucene.document.column package and no IndexWriter#addBatch; the repro does not compile) [exec]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3, code reading
- Upstream and prior reports
- none found (2026-10-26: a scripted prior-report search, 51 queries (16 GitHub issue/PR, 3 commit, 2 downstream-repo, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA-archive, 6 web) plus the finder's earlier 21-query run; 13 manual read-only gh searches, including Elasticsearch, OpenSearch and Solr; a GraphQL scan of the changed files of all 412 open PRs and 650 closed PRs updated since 2026-05-02 and of the full text of 800 PRs and 240 issues updated since 2026-05-20; lists.apache.org dev@, java-user@, builds@, issues@ and commits@); related prior items, none of them this bug: #16101 (introduced it; one approving review, no comments; its out-of-range tests use SORTED only), #16228 (last change to the method, order unchanged), #16734 (merged 2026-10-26 as a9779ef3c19; on main and branch_11x, not on branch_10_6; a reviewer asked for the same 'record doc IDs only after validation' rule in the dense vector fill path; does not touch doc values), #16553 (same bug class in stored fields, fixed 2026-09-01), #7111 / LUCENE-6049 (2014, same class, different code); no open PR touches addOrdinalTuples
- Lucene commit tested
- main
a9779ef3c193(2026-10-26, tested 2026-10-27): this doc's 6-test JUnit through gradle with-Ptests.asserts=trueand=false. On stock main 4 tests fail and the 2 controls pass. With fix option A the test passes 6 of 6, and 11 test classes pass (254 tests, 0 failures, 3 skipped); the static checks pass too. Option C: run on its own, without A: the new test 6 of 6 and TestColumnBatchDictionaryColumn 25 of 25 pass with assertions on and off; the wider suites of A were not run for C. Also re-run: the finder's JUnit, which still fails (repro harness with-ea; the diagram's re-run with-eaand-da). Mainea57360912edand the releases 10.5.0, 10.5.1 and 10.5.2 fail through the repro harness with-eaand-da; 10.4.0 and 9.12.3 lack the API. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/core/src/java/org/apache/lucene/index/SortedSetDocValuesWriter.java:84-105 (addValue validates before it switches documents), :115-159 (addOrdinalTuples: document switch :126-129 before ordValue() :130 and the range check :131-140), :162-193 (finishCurrentDoc records the opened document with its count), :360 (assert ordCount > 0)lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:123-145 (the SORTED tuple path translates the ordinal before it records the document) and :156-183 (addDenseOrdinalValues try/finally at :176)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1221-1245 (processDictionaryColumn: every SORTED_SET DictionaryColumn goes through addOrdinalTuples)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:314-358 (updateBatch; deleteLastDocs on a non-aborting exception at :349-354)lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:67-79 (non-aborting exceptions: 'These updates are consistent', the document is marked deleted)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1465 (addDocument: 'the index will be consistent'), :1528-1539 (addBatch, @lucene.experimental)lucene/core/src/java/org/apache/lucene/document/column/OrdinalsTupleCursor.java:26, 28, 46 ('must be in' range; @lucene.experimental) and OrdinalsCursor.java:49-52 ('The indexing path validates this on every call and throws IllegalArgumentException on violation')lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesProducer.java:2302-2303 (getSortedSet reads ordsEntry.addressesMeta, which is null when the writer omitted the addresses)lucene/core/src/test/org/apache/lucene/document/column/TestColumnBatchDictionaryColumn.java:391-406 (testOutOfRangeOrdSparseThrows: SORTED only, then close()) and lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:681, 739, 793, 840 (the four *ThrowMidBatchRecovers tests; none for DictionaryColumn)lucene/CHANGES.txt:900 (GITHUB#16101 in the 10.5.0 section)SECURITY.md:28, 32, 42, 50 (threat model)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/SortedSetDocValuesWriter.java:84-105, 115-159 (switch :126-129, ordValue :130, check :131-140), 162-193, 226-229, 356-373lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:123-146lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1223-1257 (SORTED_SET :1244-1248)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:314-358 (deleteLastDocs :349-354), 585-587, 594-604lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:398-403, 919-933, 955-969, 971-1005lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesProducer.java:2302-2303lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1114-1135; search/SortedSetSelector.java:165-168; document/column/ColumnFieldAdapter.java:57-62, 79-81; index/IndexingChain.java:791-794
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1158-1165, 1203-1208 (BinaryColumn SORTED_SET uses addValue), 1244-1248
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/document/column/OrdinalsCursor.java:50-52; OrdinalsTupleCursor.java:26, 28, 46-47lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:67-79; index/IndexWriter.java:1465, 1528-1539, 1575-1590lucene/core/src/test/org/apache/lucene/document/column/TestColumnBatchDictionaryColumn.java:391-407lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:682, 740, 794, 841lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:123-146, 156-183
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:169-182; index/SortedSetDocValuesWriter.java:162-193lucene/core/src/java/org/apache/lucene/document/column/DictionaryColumn.java:64-88; util/ByteBlockPool.java:199; util/ArrayUtil.java:145-150
- History
lucene/CHANGES.txt:911, 916 (10.5.0 section)
- TestRejectedSortedSetOrdinalBreaksCommit.java (JUnit test):
repro/LFV-094/src/org/apache/lucene/index/TestRejectedSortedSetOrdinalBreaksCommit.java(88 lines)
Summary card (bug.png): a rejected one-document batch, then a document with two values, then commit(). Made in parallel with this doc from the executed runs.
assets/LFV-094/bug.png(512 KB)