Lucene creates a segment's term-vector writer only when a document finishes indexing. The column API registers a batch's fields before it indexes any row, so a batch without rows can register a term-vector field and never create the writer.
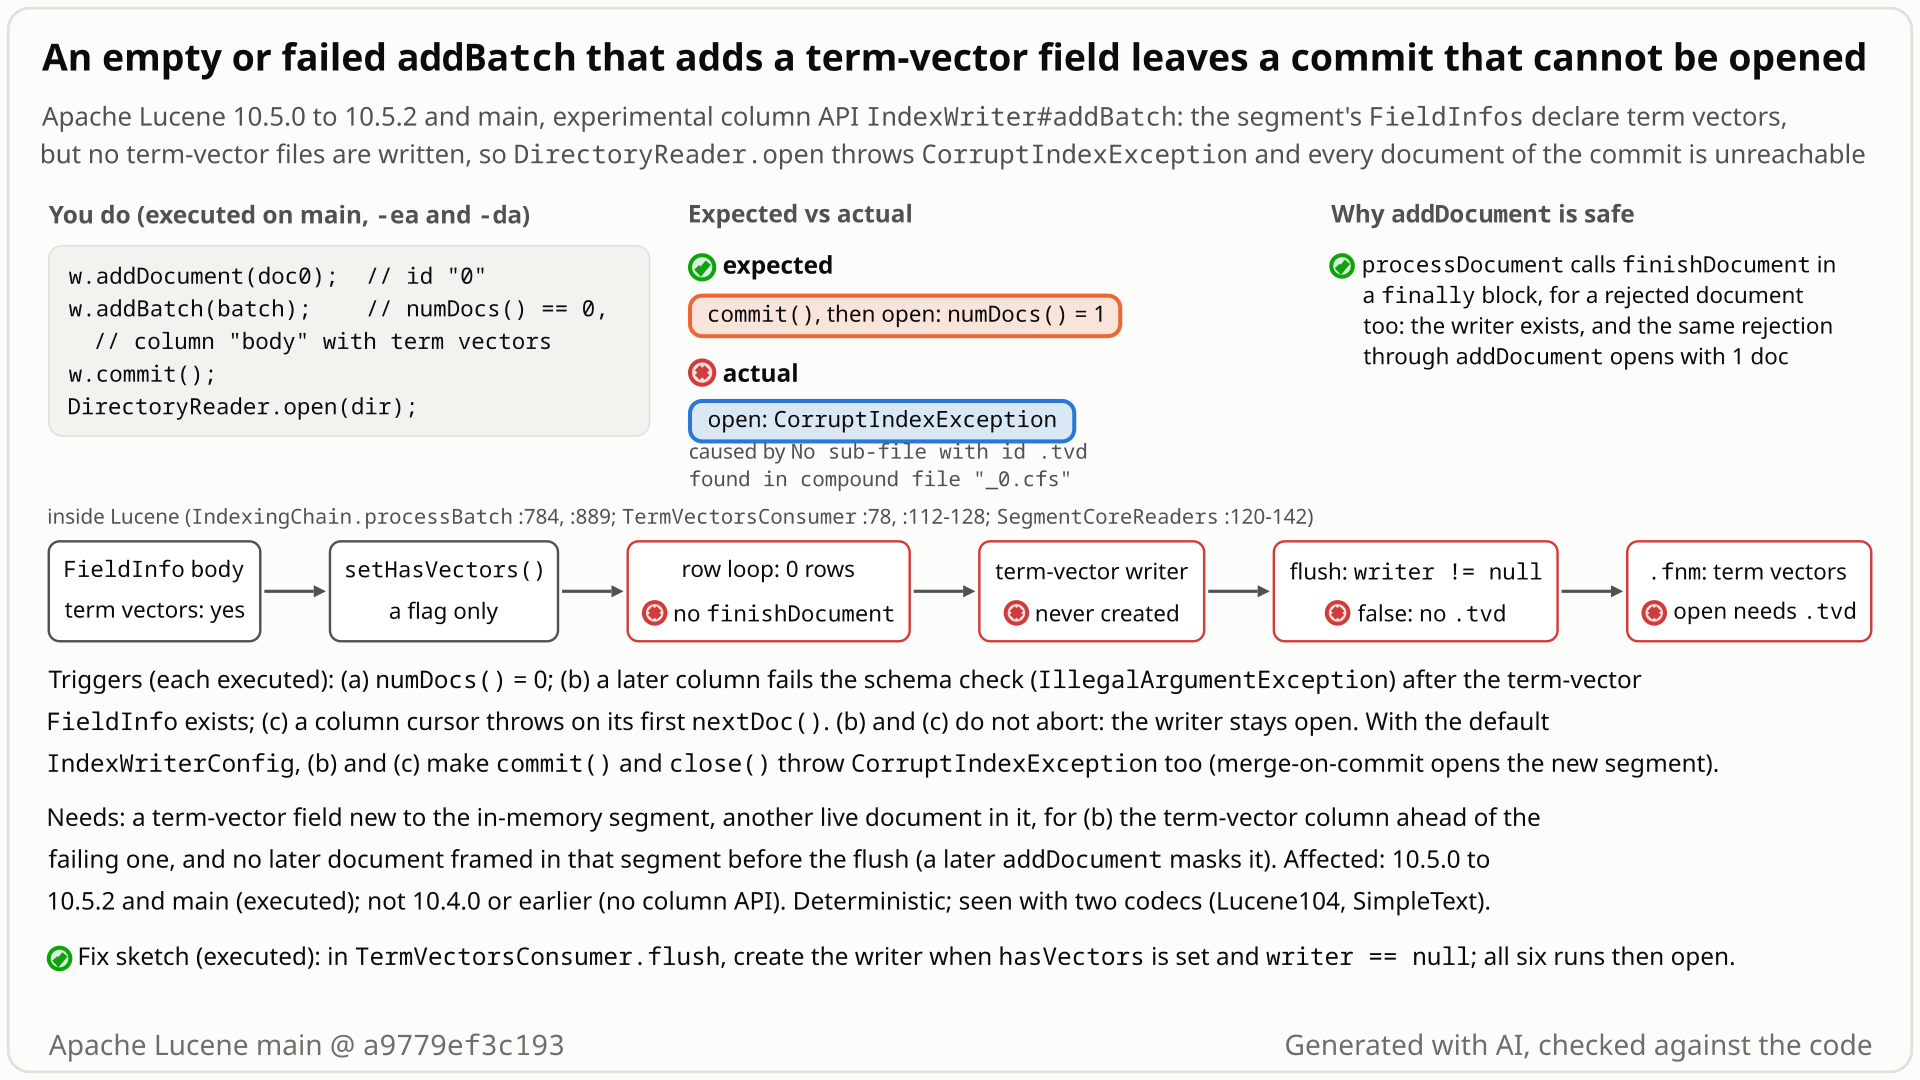
addBatch with 0 rows and a term-vector column body, flush, commit and open; it ends on a summary card. Select the still to open it at full size. Generated with AI, checked against the code.- Add 1 document with
addDocument, then calladdBatchwith a batch ofnumDocs() == 0whose only column,body, is a text field with term vectors that this segment has not seen yet. - You expect the empty batch to change nothing: after
commit(),DirectoryReader.openreturns 1 document, as it does when the same new field arrives throughaddDocument. - Instead
commit()succeeds andDirectoryReader.openthrowsCorruptIndexException, caused by "No sub-file with id .tvd found in compound file _0.cfs". The segment's FieldInfos saybodyhas term vectors; its compound file holds 12 entries, norms forbodyamong them, but no term-vector file. - Why:
addBatchregistersbody("has term vectors") before it indexes any row. The term-vector writer is created only when a document finishes, and flush writes term-vector files only if that writer exists. No row, no writer, no files. - The same happens when the batch is rejected (a later column conflicts with the schema:
IllegalArgumentException) or its cursor throws on the first value. With the default config,commit()and thenclose()throw instead.
Users of the experimental column API (addBatch, updateDocuments with a ColumnBatch; 10.5.0 to main), with the default config and codec. It takes a batch that declares a term-vector field new to the in-memory segment and indexes no row, another document already in that segment, and no later document indexed there before the flush.
Mechanism, terms and numbers635 words
IndexWriter#addBatch (the experimental column API, 10.5.0 and later) registers the field of every column in the segment's FieldInfos before it indexes any row. For a field with term vectors that only sets a flag; the term-vectors writer is created when the first document finishes, and flush writes term-vector files only if that writer exists. A batch that indexes no row (numDocs() == 0, a later column rejected by the schema check, or a cursor that throws on its first nextDoc()) therefore leaves FieldInfos that declare term vectors and no .tvd/.tvx/.tvm files. A document already in the same in-memory segment is flushed into that segment, and the commit cannot be opened: DirectoryReader.open throws CorruptIndexException, or, with the default config and the two failure triggers, commit() and close() throw. The per-document path is safe because it always finishes the document it started.
- FieldInfos: the per-segment list of fields and what each one stores (postings, norms, term vectors, doc values, points, vectors). A reader opens one file set per feature that FieldInfos declare.
- Term vectors: an optional per-document copy of a field's terms (
FieldType#setStoreTermVectors), stored in.tvd,.tvxand.tvmfiles. addBatch/ColumnBatch: the experimental column-oriented indexing API (10.5.0). A batch hasnumDocs()documents and a list of columns, one per field feature; each column hands out a cursor over (doc, value) pairs.- In-memory segment: the documents an
IndexWriterthread has buffered since its last flush; a flush or commit writes them as one segment.
IndexingChain.processBatch(IndexingChain.java:717) first loops over the columns (:726-780), then callsinitAndValidateFields(:782-785). In column order, that creates the FieldInfo of each new field (:692-693) or checks an existing field's schema (assertSameSchema,:695, which throwsIllegalArgumentExceptionon a conflict).- Creating an indexed field calls
PerField.setInvertState()(:1415-1416). For a field with term vectors it callstermVectorsWriter.setHasVectors()(:1916-1918), which only sets a flag (TermVectorsConsumer.java:112-114). - The term-vectors writer is created only in
TermVectorsConsumer.finishDocument(:117-128), when a document finishes.flushwrites term vectors onlyif (writer != null)(:78-89). - The batch path finishes documents only in its row loop (
IndexingChain.java:889,termsHash.finishDocumentat:937), and asks each row column for its first document before that loop (:875). No document is finished when (a)numDocs()is 0, (b) step 1 threw for a later column, afterbodywas created, or (c) the cursor throws at:875. - For (a)
reserveDocsreturns at once (DocumentsWriterPerThread.java:226-230); for (b) and (c)updateBatchtreats the exception as non-aborting and marks the batch's reserved documents deleted (:349-354). The writer keeps going, and the earlier document is flushed into the same segment. SegmentCoreReadersopens the term-vectors reader whenever FieldInfos declare term vectors (SegmentCoreReaders.java:120-128) and turns the missing file intoCorruptIndexException(:141-144).
The per-document path is safe: processDocument calls termsHash.startDocument() (IndexingChain.java:598) before it creates any FieldInfo and termsHash.finishDocument in its finally block (:662-681), so even a rejected document creates the writer, and flush fills empty entries.
Default codec, NoMergePolicy, one document (id = "0"), then the batch. Right after the batch the in-memory state is body(tv=true), hasVectors=true, writer=null. The committed segment _0 has maxDoc 1 (empty batch), 2 (rejected batch, 1 deleted) or 4 (cursor fails, 3 deleted), 1 live document, and 12 or 16 compound sub-files: postings, norms (also for body), stored fields, FieldInfos and, for (b), doc values, but no term vectors. DirectoryReader.open throws. The same rejection through addDocument creates the writer, writes .tvd, .tvm and .tvx, and opens with 1 document.
Exposure and likelihood444 words
- Who. Applications on
IndexWriter#addBatch(@lucene.experimental,IndexWriter.java:1535) orupdateDocuments(Term|Query, ColumnBatch), which reaches the same code (IndexWriter.java:1554,:1570; by code reading, not executed). Released in 10.5.0, 10.5.1, 10.5.2 and, by reading, 10.6.0 (branch_10_6 has the same code). - What it needs. A batch that declares a term-vector field new to the in-memory segment and indexes no row: empty, rejected by a later column's schema check, or a cursor that fails on its first value. At least one other live document in that segment. For a rejected batch, the term-vector column must be checked before the failing one. Default
IndexWriterConfigand codec (also SimpleText, run with the empty batch only); deterministic; any scale. That another live document is needed was run for the empty batch; for the other two triggers it is read from the code. The three triggers are examples: any exception after the batch's FieldInfos are created and before its first row is finished does the same (code reading). - What masks it. A later document indexed in the same segment before it flushes creates the writer and repairs the segment: an
addDocument(run) or, by code reading, a batch with an inverted column and a row. A later doc-values-only batch does not, and an index sort does not either (run with the empty batch). - What it does.
NoMergePolicy, or the default config with an empty batch:commit()succeeds and writes a commit no reader can open; with the default deletion policy it replaces the previous good commit.- Default config, rejected or failing-cursor batch:
commit()throwsCorruptIndexException(merge-on-commit opens the new segment); the writer stays open and not tragic; one moreaddDocumentpluscommit()fails again, andclose()throws; on a new index nothing is ever committed. Only these two fail insidecommit()because they leave the segment 50% and 75% deleted, so the default merge policy merges it at commit, which opens it (code reading). After an earlier good commit,rollback()closes the writer; a new writer opens the previous commit, without the document added since. - NRT:
DirectoryReader.open(writer)throws the same exception. - CheckIndex reports the segment broken (
numBadSegments=1,totLoseDocCount=1);-exorcisewould drop it with its documents.
- Loud, not silent. No wrong results; every failure is an exception (
CorruptIndexException, orIndexNotFoundExceptionwhen a new index never got a commit). Postings, stored fields and doc values of the documents are written; only the term-vector files are missing. - How likely. Rare in steady state: a pipeline whose batches always carry the term-vector column with rows heals itself. It sits on the error path, where one bad batch becomes an unopenable commit instead of one rejected batch.
The test shows that an IndexWriter#addBatch with an empty batch (numDocs() == 0) that declares a new term-vector field, after one addDocument, commits a segment whose FieldInfos declare term vectors but that has no term-vector files.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.document.column.BinaryColumn;
import org.apache.lucene.document.column.Column;
import org.apache.lucene.document.column.ColumnBatch;
import org.apache.lucene.document.column.ObjectTupleCursor;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.BytesRef;

public class TestEmptyColumnBatchTermVectors extends LuceneTestCase {

  public void testEmptyBatchWithTermVectorField() throws Exception {
    FieldType withTermVectors = new FieldType(TextField.TYPE_NOT_STORED);
    withTermVectors.setStoreTermVectors(true);
    Column body =
        new BinaryColumn("body", withTermVectors, Column.Density.SPARSE) {
          @Override
          public ObjectTupleCursor<BytesRef> tuples() {
            return new ObjectTupleCursor<>() {
              @Override
              public int nextDoc() {
                return DocIdSetIterator.NO_MORE_DOCS;
              }

              @Override
              public BytesRef value() {
                throw new IllegalStateException();
              }
            };
          }
        };
    ColumnBatch emptyBatch =
        new ColumnBatch() {
          @Override
          public int numDocs() {
            return 0;
          }

          @Override
          public Iterable<Column> columns() {
            return List.of(body);
          }
        };
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
        w.addDocument(new Document());
        w.addBatch(emptyBatch);
      }
      // expected: the commit opens with 1 doc; actual: CorruptIndexException, no term-vector files
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        assertEquals(1, reader.numDocs());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-096/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestEmptyColumnBatchTermVectors
- Expected vs actual
- Expected
DirectoryReader.opento open the commit with 1 document; actual:CorruptIndexExceptioncaused byNo sub-file with id .tvd found in compound file "_0.cfs", with-eaand-da.
More files, environment, full output65 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.apache.lucene.index.CorruptIndexException: Problem reading index from ByteBuffersDirectory@f9f34a6 lockFactory=org.apache.lucene.store.SingleInstanceLockFactory@1437f163 (resource=ByteBuffersDirectory@f9f34a6 lockFactory=org.apache.lucene.store.SingleInstanceLockFactory@1437f163)
       org.apache.lucene.index.SegmentCoreReaders.<init>(SegmentCoreReaders.java:142)
       org.apache.lucene.index.SegmentReader.<init>(SegmentReader.java:95)
       org.apache.lucene.index.StandardDirectoryReader.createOrReuseSegmentReader(StandardDirectoryReader.java:296)
       org.apache.lucene.index.StandardDirectoryReader.createSegmentReaders(StandardDirectoryReader.java:239)
       [...]
     Caused by: java.io.FileNotFoundException: No sub-file with id .tvd found in compound file "_0.cfs" (fileName=_0.tvd files: [.nvd, .fnm, .nvm, .fdx, .fdt, .fdm])
       org.apache.lucene.codecs.lucene90.Lucene90CompoundReader.openInput(Lucene90CompoundReader.java:184)
       org.apache.lucene.codecs.lucene90.compressing.Lucene90CompressingTermVectorsReader.<init>(Lucene90CompressingTermVectorsReader.java:152)
       org.apache.lucene.codecs.lucene90.compressing.Lucene90CompressingTermVectorsFormat.vectorsReader(Lucene90CompressingTermVectorsFormat.java:96)
       org.apache.lucene.index.SegmentCoreReaders.<init>(SegmentCoreReaders.java:125)
[...]- Empty batches are legal and tested upstream (
testEmptyBatch), and batch failures are designed to leave a usable writer (test*ThrowMidBatchRecovers). - The per-document path writes term-vector files even for a rejected document, and the same code writes norms "even if no documents actually succeed".
- #13369 fixed the same FieldInfo-without-file state for points as a bug.
The full argument255 words
- Commit contract.
IndexWriter#commit: "Commits all pending changes ... such that a reader will see the changes" (IndexWriter.java:4189-4190). - Empty batches are legal.
ColumnBatch#numDocsonly requires doc ids "in the range [0, numDocs())" (ColumnBatch.java:28-31);reserveDocsreturns at once forn == 0(DocumentsWriterPerThread.java:228-230); upstreamTestColumnBatchIndexing#testEmptyBatch(:924) adds an empty batch and checks that the "Writer still functions for follow-up work" (its batch has no columns). - Batch failures are non-aborting by design.
updateBatch: "the iterator threw an exception that is not aborting / go and mark all docs from this block as deleted" (DocumentsWriterPerThread.java:350-353); #16270 aligned it withupdateDocuments; upstreamtest*ThrowMidBatchRecovers(TestColumnBatchIndexing.java:682,:740,:794,:841) throw from cursors and assert the writer recovers.addDocument's javadoc: after an exception "the index will be consistent" (IndexWriter.java:1465). - The rule in the same code.
setInvertState: "Even if no documents actually succeed in setting a norm, we still write norms for this segment" (IndexingChain.java:1912-1913). The broken segment does have norms forbody; only term vectors lack the guarantee, and only on the batch path. - Precedent. #13369 (9.11.0, closing #13353): "Fix NRT opening failure when soft deletes are enabled and the document fails to index before a point field is written", the same FieldInfo-without-file state for points, fixed as a bug.
- Untested corner. No upstream test combines term vectors with column batches (none of the 8 test files that use
ColumnBatch). The #15990 review never mentions term vectors.
The devil's-advocate check201 words
The strongest case for "intended" (a cross-model reviewer rated it moderate): Lucene deliberately avoids term-vector files until a document uses them. LUCENE-2776 (2010) stopped creating the term-vector writer at flush when no document had used it, and at first let the reader tolerate exactly this state: "If all documents flushed in a segment had hit non-aborting exceptions, it's possible that FieldInfos.hasVectors returns true yet the term vector files don't exist." The API is @lucene.experimental, an empty batch with columns is odd, and a failing cursor is the caller's code.
Why it fails: LUCENE-2811 removed that reader tolerance 17 days later ("it should only be opened if they exist"), and today a missing term-vector file is corruption. Since then the per-document path has kept the invariant by finishing every document it starts, including rejected ones. Empty batches and non-aborting batch failures are accepted and tested upstream. @lucene.experimental allows API changes, not a commit that cannot be opened. Before LUCENE-2776, flush created the writer for exactly this case ("all documents seen in this segment hit non-aborting exceptions"); fix option A restores that guard, keyed on hasVectors. Verdict: a defect (the independent reproducer, cross-model reviews, the devil's advocate and the adjudication agree).
Recommended A. TermVectorsConsumer.flush creates the writer when term vectors are declared (validated)
Recommended and validated: in TermVectorsConsumer.flush, create the term-vector writer when FieldInfos declare term vectors but no document created it, so flush writes an empty entry per document (5 lines). It fixes all three triggers; the repro and 305 tests in 18 related classes pass with assertions on and off.
// TermVectorsConsumer.flush, before "if (writer != null) {"
if (writer == null && hasVectors) {
  // A field with term vectors was registered (e.g. by an empty or rejected column batch) but no
  // document finished afterwards: still write (empty) term vectors, FieldInfos declare them.
  initTermVectorsWriter();
}
All options and trade-offs5 options · 600 words
Option A was applied in a scratch worktree of a9779ef3c193 and run; options B and D are design alternatives that were not run; C is not sufficient on its own.
A. TermVectorsConsumer.flush creates the writer when term vectors are declared (validated) (recommended)
If hasVectors is set and no document created the writer, create it in flush; the existing fill(numDocs) then writes an empty entry for every document. This is what the per-document path already writes after a rejected document. With an index sort, SortingTermVectorsConsumer.flush calls super.flush and overrides initTermVectorsWriter, so the same lines create its temporary writer.
// TermVectorsConsumer.flush, before "if (writer != null) {"
if (writer == null && hasVectors) {
  // A field with term vectors was registered (e.g. by an empty or rejected column batch) but no
  // document finished afterwards: still write (empty) term vectors, FieldInfos declare them.
  initTermVectorsWriter();
}
Trade-offs
- A segment that registered a term-vector field but has no document with term vectors now gets small term-vector files with empty entries, instead of none. Format and reader are unchanged.
flush'sassert numDocs > 0still holds: a thread state with no documents is never flushed (guards atDocumentsWriterFlushControl.java:367,:584; asserts atDocumentsWriterPerThread.java:428,:444).- Open draft PR #16269 refactors
TermVectorsConsumerand keeps thewriter != nullguard; a patch may need a rebase if it lands first.
What the checks validated
- Scratch worktree of
a9779ef3c193(removed afterwards), gradle, seed DEADBEEF, assertions on and off../gradlew :lucene:core:tidyleaves the patch unchanged. - The repro (3/3) and the independent reproducer's 6 tests and 4 controls pass: 13/13 with assertions on and off (stock: 9 of 13 fail).
- 18 test classes, 305 tests, 0 failures, 3 skipped, with assertions on and off:
TestTermVectors,TestTermVectorsReader,TestTermVectorsWriter,TestColumnBatchIndexing, the 6 classes oforg.apache.lucene.document.column,TestIndexWriterExceptions,TestIndexWriterExceptions2,TestCheckIndex,TestLucene90TermVectorsFormat,TestCompressingTermVectorsFormatand this bug's 3 test classes (the repro, the independent reproducer's tests and its controls). - Extra check (one document, an empty term-vector batch, commit; then 1 document,
termVectors().get(0) == nulland a clean CheckIndex; once plain and once with an index sort, which usesSortingTermVectorsConsumer): stock 2 of 2 fail, option A 2 of 2 pass with assertions on and off. - Earlier hunt runs: the finder's, the independent reproduction's and separate tests and the 5-test security probe pass with it; shadowed over 10.5.0, 10.5.2 and the commit-built jar it passes the three scenarios.
Call initTermVectorsWriter() from setHasVectors(), or from processBatch right after initAndValidateFields when a term-vector field was registered.
Trade-offs
setInvertState() does not throw IOException today, so it needs plumbing; the batch-only variant fixes this caller and leaves the invariant implicit for the next one; term-vector outputs open at field registration instead of at flush.
Skips the empty batch before any field is registered.
Trade-offs
Fixes trigger (a) only: the rejected-batch and failing-cursor triggers stay broken. Only useful combined with A or B.
Create FieldInfos only once the row pass starts, or roll them back when the batch fails.
Trade-offs
A much larger change to processBatch, whose column pass needs the per-field state; field numbers are shared index-wide; and it would differ from the per-document path, which keeps the FieldInfo of a rejected document.
What LUCENE-2776 did in 2010.
Trade-offs
LUCENE-2811 removed that tolerance; it would hide real corruption.
Not a security issue (the application builds the batch), but a service that forwards client-supplied batches to addBatch can turn one empty or malformed batch into a commit that no reader can open.
A bounded-exhaustive harness indexed every small single-column batch shape both through addBatch and row by row and compared the two indexes: 29,408 scenarios, 32 of which left an index that could not be opened, all with a term-vector column, zero rows and one document before the batch. The other two triggers came from reading the code.
The method in full185 words
Method: bounded-exhaustive translation validation (the hunt's semi-formal tier) on the real jar, a hunt unit (columnar addBatch).
- Scope A: one column, 26 column specs (long, binary, dictionary, float and byte vector and token-stream columns; stored, inverted with every index option and term vectors with positions, offsets and payloads, every doc-values type, skip index, 1-D and 2-D points), dense and every sparse pattern for
numDocs0 to 3, a document before and/or after the batch, 4 writer configurations (default, index sort, parent field, soft deletes). Each scenario was indexed throughaddBatchand through the row-by-row reference, and the indexes were compared; with assertions on and off. - Result: 29,408 scenarios; 32 corrupt indexes on the batch side, exactly the term-vector specs with
numDocs = 0and one document before the batch. A mutant (a +1 on one value) was caught (256 mismatches), so the comparison is not vacuous. - The finder minimised it by hand into a JUnit; the rejected-batch and failing-cursor triggers came from reading
processBatchafterwards. An independent reproducer, cross-model reviews (OpenAI GPT-5.6) and an intended-behaviour devil's advocate checked it before the adjudication confirmed it.
No prior report: 5 search-tool runs (GitHub, commits, downstream repositories, four mailing lists, the JIRA archive, the web), 72 manual GitHub searches, 6 JIRA queries and the files of all 412 open PRs, 2026-10-25/26. Closest: #13369 (the points analogue) and LUCENE-2776 (2010 background).
Searches6 searches
No upstream issue, PR, commit, list thread, JIRA entry or downstream report describes this bug. Related items are listed below; none of them is this bug.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), via the search tool | 2026-10-25/26 | 5 runs: 90 issue/PR, 12 commit and 8 downstream-repository queries (class and method names, symptom phrasing such as "No sub-file with id .tvd", batch-failure wording) | no report; column-API PRs (#15990, #16066, #16115, #16117, #16168, #16219, #16270) and old term-vector issues |
| Manual read-only GitHub searches | 2026-10-25/26 | 53 by the follow-up (apache/lucene, all of GitHub, Elasticsearch, OpenSearch, Solr, luceneutil) plus 15 by a verifier and 4 by the adjudication | no report; Elasticsearch's columnar indexing PRs call addBatch without term vectors |
| Open PRs | 2026-10-26 | the changed-file lists of all 412 open PRs | draft #16269 (TermVectorsConsumer refactor, keeps the writer != null guard, no behaviour change) and draft #16116 (processBatch); neither fixes it |
| Mailing lists (dev@, java-user@, issues@, commits@) | 2026-10-25/26 | 80 queries; the 9-mail dev@ design thread of the column API read in full | no report; term vectors appear only as future work |
| JIRA archive | 2026-10-25/26 | 16 tool queries and 6 manual JQL queries; LUCENE-2776, LUCENE-2811 and LUCENE-2984 read in full | 2010-2011 history of the lazy writer (background, not this bug) |
| Git history | 2026-10-26 | TermVectorsConsumer.java and IndexingChain.java on main, branch_10x, branch_10_6 and branch_10_5 | no fix of this path |
Introduced with the column API itself, #15990 (3d89568155799, merged 2026-05-14) and its backport #16066; first released in 10.5.0. Affects 10.5.0, 10.5.1, 10.5.2, 10.6.0 (by reading) and main; not a regression.
Versions tested6 rows
Introduced by #15990, "Add experimental columnar indexing api" (author @Tim-Brooks, merged by @ChrisHegarty on 2026-05-14 as 3d89568155799 on main), backported the same day by #16066 (3ec3bff01b15, branch_10x), which ships in 10.5.0. It combines two older pieces that were safe on their own: the flush that writes term vectors only when a document created the writer (LUCENE-2776, 2010; its if (writer != null) form from the LUCENE-2621 rewrite, 2011) and the setHasVectors() call at FieldInfo creation (LUCENE-9334, first released in 9.0.0). #15990 brought back a state the current per-document path no longer reaches: FieldInfos created without a finished document. On main, git blame of the up-front field creation points at the refactor #16219; the bug is older and reproduces at 3d89568155799. branch_10_6 and branch_10x have the same code (compared by content), so 10.6.0, released 2026-10-29, is affected.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | 3 of 3 fail with assertions on and off (gradle and the repro harness) |
main ea57360912ed | affected | 3 of 3 fail with assertions on and off |
| 10.5.0, 10.5.1, 10.5.2 | affected | 3 of 3 fail (release jars; 10.5.0 and 10.5.2 also with assertions off) |
3d89568155799 (#15990) | introducing commit | a jar built from the commit fails all three scenarios (a main() form, assertions on and off) |
| 10.4.0, 9.12.3 | no column API | not applicable: the repro does not compile; the same rejection through addDocument works |
option A on a9779ef3c193, 10.5.0, 10.5.2 and 3d89568155799 | fix | all three scenarios pass |
Confirmed by an adjudication (high confidence) after an independent reproducer with its own test, cross-model reviews (OpenAI GPT-5.6) that ran their own tests, and an intended-behaviour devil's advocate; this doc re-ran it through gradle on main and validated the fix.
Checks and verdicts242 words
Every check reproduced it; nobody dissented.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own JUnit written from the claim only: 6 of 6 fail (3 triggers x 2 configurations) on main, 10.5.2 and 10.5.0, assertions on and off; 60 of 60 over 10 iterations; 4 controls pass; CheckIndex shows the segment declaring term vectors with no term-vector files; its own fix passes. |
| Refute review (OpenAI GPT-5.6) | real, high | Its own empty-batch test without compound files fails with assertions on and off and with a second seed; its one-row and later-addDocument controls pass; the fix passes its test and TestTermVectorsWriter. |
| Intended-lens review (OpenAI GPT-5.6) | real, high | Rated the LUCENE-2776 argument moderate, then rejected it; its own test fails with the default and the SimpleText codec; the fix passes all three triggers. |
| Intended-behaviour devil's advocate | real | No intended argument survives; its default-config test fails 2 of 2, including a sequence of column batches only; its per-document control passes. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with new seeds (6 of 6 fail, assertions on and off), the independent reproduction's controls (4 of 4 pass) and the finder's repro (3 of 3 fail); the fix passes. |
| This doc's gradle run | reproduces; fix validated | Stock main a9779ef3c193: 13 run, 9 fail (the 4 controls pass), assertions on and off; option A: 13 of 13 pass, and 18 classes (305 tests) pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 494 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,196 words
- Registry title
- An addBatch that registers a new term-vector field but frames no rows leaves a segment whose FieldInfos declare term vectors with no term-vector files, so the committed index cannot be opened
- Area
- index / columnar addBatch (term vectors)
- Priority
- Medium, rank 152: An empty, rejected or failing addBatch that declares a new term-vector field can leave a commit that DirectoryReader.open rejects, catastrophic but loud and an unusual edge sequence on an experimental API.
- Impact class
- index unusable
- Impact note
- Applications on the experimental column API (IndexWriter#addBatch, 10.5.0 and later) that send a batch which declares a term-vector field new to the in-memory segment but frames no row (numDocs()==0, a batch rejected by the schema check of a later column, or a column cursor that throws before the first row) while that segment holds another live document and no later document is framed in it before the flush; default IndexWriterConfig and codec, ordinary scale, deterministic; then DirectoryReader.open fails for the whole index, or (default config, rejected-batch and failing-cursor triggers) commit() and close() keep throwing CorruptIndexException; released 10.5.0-10.5.2, and 10.6.0 by reading.
- Summary
- You add a document, then call IndexWriter#addBatch with a column batch that declares a new text field with term vectors but adds no row: the batch is empty, or it is rejected with IllegalArgumentException because a later column conflicts with the existing schema, or its column cursor throws before the first row. You expect the earlier document to commit and the index to open, as it does when the same rejection happens through addDocument. Instead the segment's FieldInfos say the field has term vectors but no term-vector files were written, so DirectoryReader.open on the commit throws CorruptIndexException ('No sub-file with id .tvd found in compound file'), or, with the default IndexWriterConfig, commit() itself throws.
- Introduced
- 3d89568155799 (#15990 'Add experimental columnar indexing api', main), released through its branch_10x backport 3ec3bff01b15 (#16066) [exec: a lucene-core jar built from 3d89568155799 fails all three scenarios with -ea and -da and passes with the fix; read: git show, git log --all --diff-filter=A on ColumnBatch.java, git tag --contains]; not a regression: the defect is in the column API's first version. It combines two older pieces that were safe on their own: the lazily created term-vectors writer with the 'if (writer != null)' flush guard (873f19992445, LUCENE-2621, 2011) and the setHasVectors() call made when a term-vector FieldInfo is created (d03662c48bfc, LUCENE-9334, first released in 9.0.0) [read] (2026-05-14 (#15990 merged into main; backport #16066 merged into branch_10x the same day))
- First affected version
- 10.5.0 [exec]
- Affected versions
- 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed [exec; 10.5.0, 10.5.2 and main also with -da], and the introducing commit 3d89568155799 [exec, main() form, -ea and -da]; not applicable to 10.4.0 and earlier, including 9.12.3 (no column API, the repro does not compile) [exec]; branch_10_6 (10.6.0, released 2026-10-29) and branch_10x have the same TermVectorsConsumer blob 832f0275fa9 and the same processBatch structure [read, heads of 2026-10-24; at the 10.6.0 tag 4ae946e5a9b the same blob and an identical processBatch, read 2026-10-31], so 10.6.0 (released 2026-10-29) is affected [read]; not fixed upstream as of main ea57360912ed [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by code reading
- Upstream and prior reports
- none found (2026-10-25/26: a scripted prior-report search, 5 runs (the finder's, the intended-behaviour check's lists and JIRA run, and follow-up runs A-C) with 90 GitHub issue/PR, 12 commit, 8 downstream-repo, 80 mailing-list (dev@, java-user@, issues@, commits@), 16 JIRA-archive and 19 web queries; 53 manual read-only gh searches over apache/lucene, all of GitHub, Elasticsearch, OpenSearch, Solr and luceneutil, plus the intended-behaviour check's 15 and the adjudication's 4; 6 manual JQL queries; commit history of TermVectorsConsumer.java and IndexingChain.java on main, branch_10x, branch_10_6 and branch_10_5; the changed-file lists of all 412 open PRs; the #15990 review thread and the 9-mail dev@ design thread read in full); related prior items, none of them this bug: #15990 (introduced it; its review never mentions term vectors), #16066 (its backport, ships in 10.5.0), #13353 and #13369 (the points precedent: the same FieldInfo-without-file invariant, fixed as a bug in 2024), #3850 (LUCENE-2776, 2010: made the writer lazy and briefly let the reader tolerate this state for the old per-document code) and #3885 (LUCENE-2811, removed that tolerance), #16553 (nearest fixed bug in the same code: stored-fields framing; in 10.5.2, which still fails), open PR #16269 (refactors TermVectorsConsumer, keeps the writer != null guard, no behaviour change; read from its diff only), open draft #16116 (touches processBatch, does not change this case)
- Lucene commit tested
- main
a9779ef3c193(2026-10-26): the 3-test JUnit, an independent reproducer's 6-test JUnit and its 4 controls through gradle with assertions on and off, stock (9 of 13 fail, the 4 controls pass) and with fix option A (13 of 13 pass); 18 test classes (305 tests) with option A, assertions on and off; an extra check of option A with CheckIndex and an index sort; the repro harness ona9779ef3c193,ea57360912ed, 10.5.0, 10.5.1, 10.5.2 and a jar built from the introducing commit3d89568155799; a step-by-step probe of the in-memory state ona9779ef3c193. 10.4.0 and 9.12.3 are not applicable (no column API).
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:715-716 (processBatch), :720-778 (first loop: column-type validation), :780-783 (initAndValidateFields before the row pass), :789-792 (row pass), :873 (first cursor nextDoc() before the row loop), :887-894 (row loop frames documents with termsHash.startDocument), :922-938 (finally: termsHash.finishDocument), :1850-1864 (setInvertState: norms comment at :1857-1858, setHasVectors at :1861-1863)lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumer.java:72-90 (flush writes only if writer != null), :95-101 (fill), :103-110 (initTermVectorsWriter), :112-114 (setHasVectors sets a flag), :117-128 (finishDocument creates the writer)lucene/core/src/java/org/apache/lucene/index/SegmentCoreReaders.java:120-125 (term-vectors reader opened whenever FieldInfos declare term vectors), :141-144 (missing file -> CorruptIndexException)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:226-230 (reserveDocs returns early for n == 0), :314-358 (updateBatch; :350-353 marks the reserved docs deleted after a non-aborting exception)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1528-1539 (addBatch javadoc, @lucene.experimental at :1535)lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:885 (testEmptyBatch), :681, :739, :793, :840 (test*ThrowMidBatchRecovers)Lucene git history (read-only, 2026-10-31): 4ae946e5a9b:lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumer.java is blob 832f0275fa9, as on main ea57360912ed; IndexingChain.processBatch is identical at 4ae946e5a9b and ea57360912ed
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java at a9779ef3c193 (:583-682, :685-699, :717-794, :862-944, :1372-1418, :1905-1919)lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumer.java at a9779ef3c193 (:72-128)lucene/core/src/java/org/apache/lucene/index/SegmentCoreReaders.java at a9779ef3c193 (:120-144)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java at a9779ef3c193 (:226-230, :314-359)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java at a9779ef3c193 (:1528-1590)lucene/core/src/java/org/apache/lucene/index/TieredMergePolicy.java at a9779ef3c193 (:82, :598) and IndexWriterConfig.java (:102, :108)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java at a9779ef3c193 (:1465, :4189-4190)lucene/core/src/java/org/apache/lucene/document/column/ColumnBatch.java at a9779ef3c193 (:28-31)lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java at a9779ef3c193 (:682, :740, :794, :841, :924)lucene/CHANGES.txt at a9779ef3c193 (:2911-2912)git history: commit 57a7862f829 (LUCENE-2776, 2010-11-26; TermVectorsTermsWriter.flush) and 1ca059706ee (LUCENE-2811, 2010-12-13)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/SortingTermVectorsConsumer.java at a9779ef3c193 (:53-94)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java at a9779ef3c193 (:428, :444)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterFlushControl.java at a9779ef3c193 (:367, :584)
- History
lucene/CHANGES.txt at a9779ef3c193 (:911, 10.5.0 API Changes)
- TestEmptyColumnBatchTermVectors.java (JUnit test):
repro/LFV-096/src/org/apache/lucene/index/TestEmptyColumnBatchTermVectors.java(80 lines)
assets/LFV-096/bug.png(494 KB)