Lucene buffers a field's doc values in pages of 256 and registers a dense batch's documents only after the whole bulk copy returns. A cursor that throws after a page was filled leaves that page's values counted but registers no documents for them, and flush pairs documents with values by position.
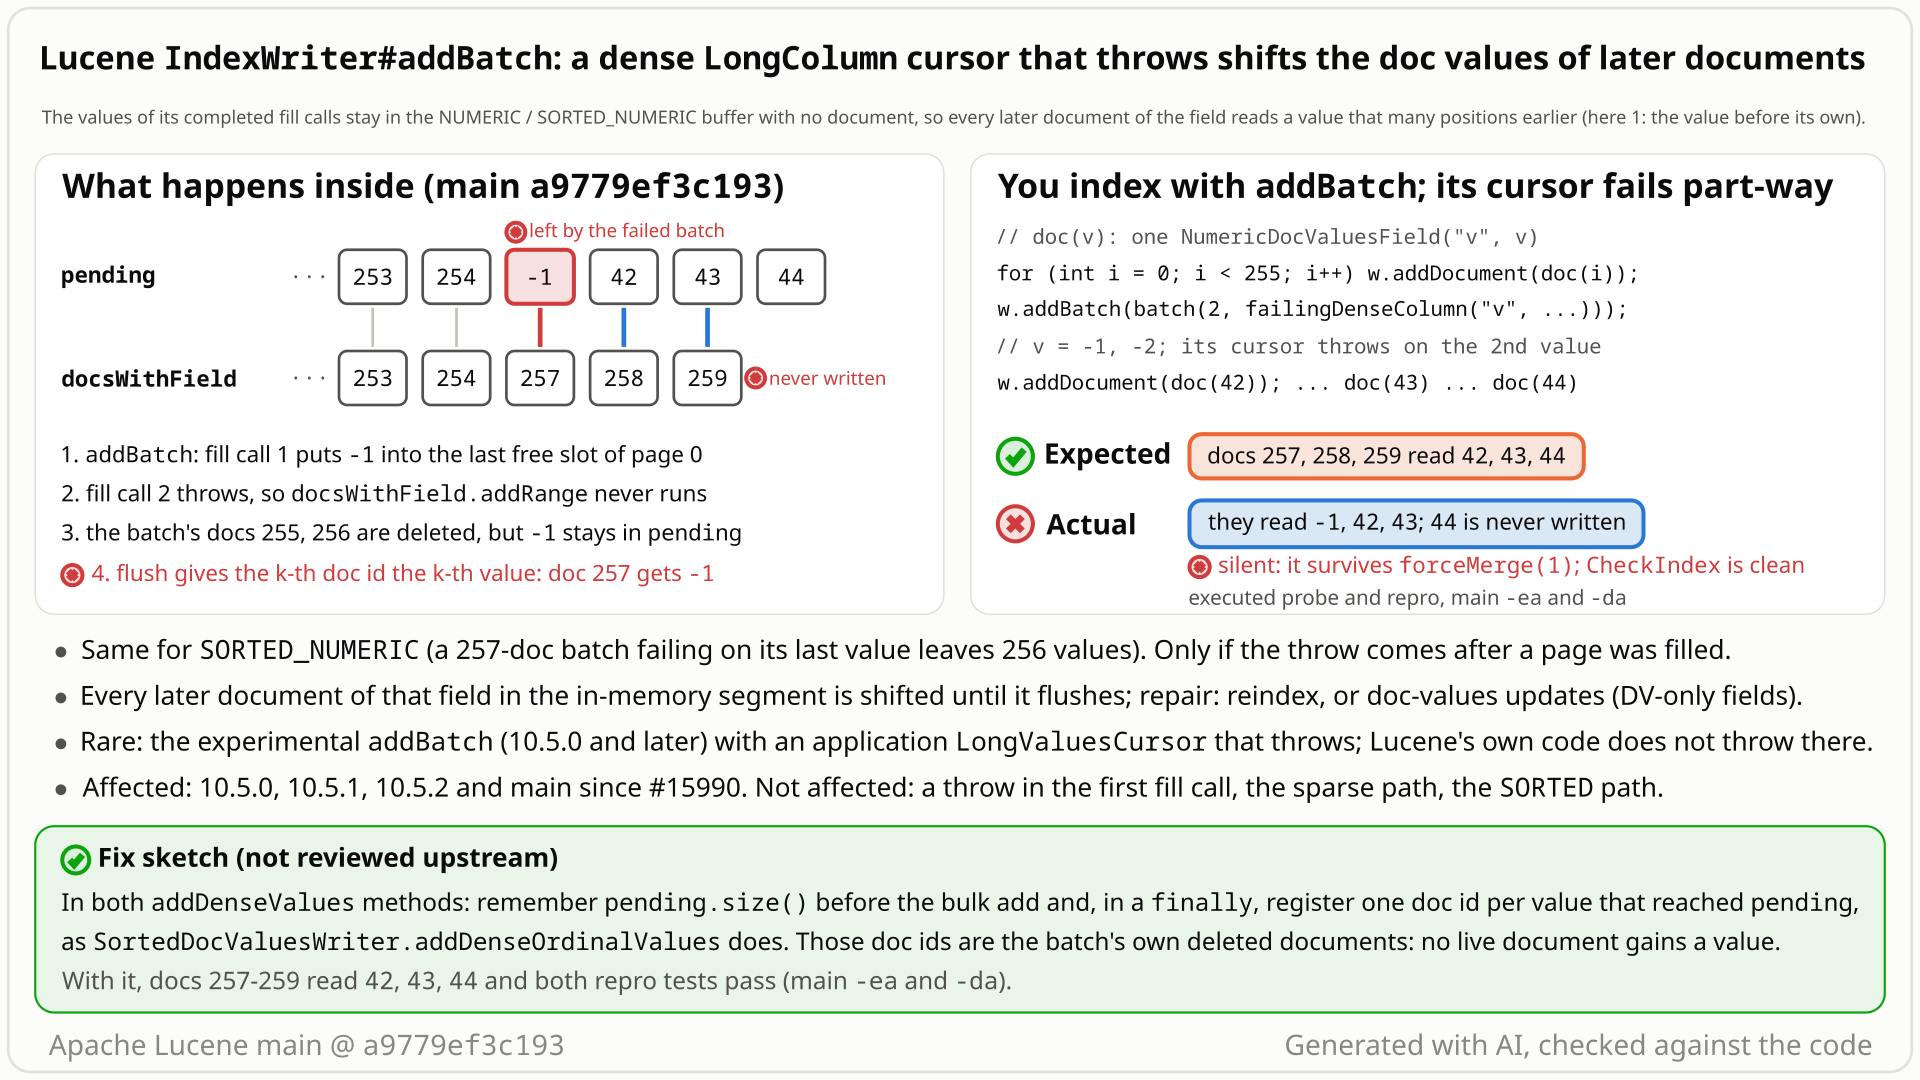
- Add 255 documents with a NUMERIC doc value
v= 0 to 254 (defaultIndexWriterConfigand codec). Doc values are buffered in pages of 256 values, so the current page has one free slot. - Call
addBatchwith 2 documents: a denseLongColumn"v" whoseLongValuesCursorreturns -1, then throws on its 2nd value. The exception propagates and the 2 batch documents are deleted, as expected. - Add a document with
v= 42. You expect it to read back 42, as Lucene's own recovery test asserts for documents indexed after a throwing cursor. - Instead it reads -1. The -1 filled the page's last slot and stayed buffered with no document, so each later document gets the value one position earlier: 42, 43, 44 read back as -1, 42, 43.
- No error:
CheckIndexis clean and the wrong values survive commit,forceMerge(1)and reopen. Reproduced on 10.5.0, 10.5.1, 10.5.2 and main; turning assertions off changes nothing.
Applications that use the experimental IndexWriter#addBatch (10.5.0 and later) with a dense LongColumn feeding NUMERIC or SORTED_NUMERIC doc values, whose own cursor throws mid-batch, and that keep indexing into the same writer. Default configuration and codec. Lucene's own code never throws there, so it is rare; the one known downstream user has its batch path off by default.
Mechanism, terms and numbers637 words
IndexWriter#addBatch (experimental, since 10.5.0) copies a dense LongColumn into the field's NUMERIC or SORTED_NUMERIC doc-values buffer in bulk, one 256-value page at a time, and registers the batch's documents only after the whole copy has returned. If the application's LongValuesCursor throws after at least one page was filled during the call, the batch is rejected correctly (the exception propagates, the writer stays open, the batch's documents are deleted), but the values of the filled pages stay buffered with no document. At flush the k-th document with the field is paired with the k-th buffered value, so every later document of that field in the same in-memory segment is stored with the value of a document that many positions earlier (for a SORTED_NUMERIC field with an earlier multi-valued document: the counts stay right, the values come from other documents). Nothing throws, CheckIndex is clean, and the values survive commit, reopen and forceMerge(1). Default configuration and codec; it needs an application cursor that throws, so it is rare. The sibling dense SORTED path and the stock flat writer of the new dense vector path (#16734) keep documents and values aligned; the fix is a few lines of bookkeeping.
- Columnar
addBatch.IndexWriter#addBatch(ColumnBatch)(experimental, 10.5.0) indexes a batch column by column. A DENSELongColumnhas a value for every document and hands it over through aLongValuesCursorthat the application writes (LongColumn.values(),document/column/LongColumn.java:79-88). - The doc-values buffer.
NumericDocValuesWriterandSortedNumericDocValuesWriterkeep the values of the in-memory segment in aPackedLongValues.Builder(pages of 256 values,PackedLongValues.java:34,:66) and the documents that have the field in adocsWithFieldset. - Non-aborting exception. An exception that rejects the current documents but keeps the writer and the in-memory segment for later documents.
IndexingChain.processDenseLongColumnruns the doc-values pass first and callsaddDenseValueson the field's writer (IndexingChain.java:1076-1093).addDenseValuescallspending.add(cursor)and only after it returns registers the batch's documents:docsWithField.addRange,lastDocID/currentDoc, andpendingCountsfor SORTED_NUMERIC (NumericDocValuesWriter.java:81-94,SortedNumericDocValuesWriter.java:73-102).PackedLongValues.Builder.add(LongValuesCursor)packs a full page, asks the cursor for at most the rest of the current page withfillDocValues, then advancespendingOffandsize(PackedLongValues.java:265-279). When a laterfillDocValuescall throws, the values of the earlier calls stay counted.DocumentsWriterPerThread.updateBatchtreats the exception as non-aborting: it deletes the batch's documents and keeps the segment (DocumentsWriterPerThread.java:349-354,:399-409).- The NRT reader, the flush and the index sorter read the buffer through
BufferedNumericDocValues, which takes the next document ofdocsWithFieldand the next buffered value (NumericDocValuesWriter.java:192-198; single-valued SORTED_NUMERIC uses it too,SortedNumericDocValuesWriter.java:192-199). With k left-over values every later document gets the value k positions earlier (up to the first k get the rejected batch's values); the last k values are never read, so nothing throws. Once an earlier document of a SORTED_NUMERIC field was multi-valued, the per-document counts stay right but the values are read from the same shifted stream (SortedNumericDocValuesWriter.java:192-199,:279-289).
Writer state from an executed probe: after documents 0-254, 255 values and 255 documents. The 2-document batch: fill call 1 (offset 255, length 1) returns -1, the page is packed, fill call 2 (offset 0, length 1) throws: 256 values, still 255 documents. Documents 257-259 (42, 43, 44) are then paired with -1, 42 and 43; the good document's 44, the last buffered value, is never read. Other executed cases: a 257-document SORTED_NUMERIC batch failing on its last value leaves 256 values (the next document reads -1 instead of 42); a 600-document batch failing at value 520 leaves 512 (42, 43, 44 read -1, -2, -3). Not affected: a throw inside the first fill call, the sparse (tuple) long path, the dictionary SORTED dense path, and a flush right after the failure.
Exposure and likelihood338 words
- Who is hit. Users of the experimental
addBatch/updateBatchwith a DENSELongColumnfor NUMERIC or SORTED_NUMERIC doc values (including aLongField-style schema with points plus SORTED_NUMERIC; the doc-values pass runs first), whoseLongValuesCursorthrows aRuntimeExceptionafter the batch crossed a 256-value page boundary of the field's buffer, and who keep adding documents with that field before the segment flushes.updateBatchkeeps the writer and the in-memory segment for that, and Lucene's own recovery test indexes more documents afterwards (after acommit()); the publicaddBatchcontract says nothing about unchecked exceptions. - Default or opt-in. Default
IndexWriterConfigand codec, no assertions needed; reproduced withNoMergePolicy, the defaultTieredMergePolicyand the randomized test configuration. The opt-in part is the experimental API and a cursor that throws: Lucene ships noLongValuesCursoroutside tests, so the cursor is application code, for example one that decodes or validates its source lazily and fails on a bad row. - Scale. 255 earlier documents and a 2-document batch are enough. The shift equals the number of values in the completed fill calls: 1, 256 and 512 in the executed cases.
- The damage. Documents whose own add calls succeeded carry another document's value: sorting, doc-values queries, facets and aggregations on that field, and an index sort (probe: the good document reads -1 with the sort on the field itself or on another field). Points stay correct, so points and doc values of one field disagree;
LongField.newExactQuerycan return wrong hits whenIndexOrDocValuesQueryruns on doc values.CheckIndexis clean; the values survive commit, reopen andforceMerge(1). Repair means finding and reindexing the affected documents; for a doc-values-only field that is not an index-sort field,updateNumericDocValue/updateSortedNumericDocValuecan also rewrite them (IndexWriter.java:1962,:2037), but not for aLongField-style field with points. - Exposure today. The API shipped in 10.5.0 (June 2026). The only downstream user found, Elasticsearch's batch-indexing path, is unreleased, behind a feature flag and a setting that defaults to off, with no known throw site here.
The test shows that when a dense NUMERIC LongColumn's values cursor throws during addBatch after 255 earlier documents of the field, the value it already delivered stays buffered with no document, so the next document of the field is stored with that value.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.column.Column;
import org.apache.lucene.document.column.ColumnBatch;
import org.apache.lucene.document.column.LongColumn;
import org.apache.lucene.document.column.LongTupleCursor;
import org.apache.lucene.document.column.LongValuesCursor;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestDenseLongColumnFailure extends LuceneTestCase {

  public void testFailedDenseBatchShiftsLaterValues() throws Exception {
    Column failing =
        new LongColumn("v", NumericDocValuesField.TYPE, Column.Density.DENSE) {
          @Override
          public LongTupleCursor tuples() {
            throw new UnsupportedOperationException();
          }

          @Override
          public LongValuesCursor values() {
            return new LongValuesCursor(2) {
              int pos = 0;

              @Override
              public long nextLong() {
                if (pos++ == 1) {
                  throw new IllegalStateException("data source failed");
                }
                return -1;
              }
            };
          }
        };
    ColumnBatch batch =
        new ColumnBatch() {
          @Override
          public int numDocs() {
            return 2;
          }

          @Override
          public Iterable<Column> columns() {
            return List.of(failing);
          }
        };
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      for (int i = 0; i < 255; i++) {
        Document doc = new Document();
        doc.add(new NumericDocValuesField("v", i));
        w.addDocument(doc);
      }
      expectThrows(IllegalStateException.class, () -> w.addBatch(batch));
      Document good = new Document();
      good.add(new NumericDocValuesField("v", 42));
      w.addDocument(good);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        LeafReader leaf = getOnlyLeafReader(reader);
        NumericDocValues values = leaf.getNumericDocValues("v");
        assertTrue(values.advanceExact(leaf.maxDoc() - 1));
        // expected: the last document reads its own value 42; actual: -1 from the failed batch
        assertEquals(42, values.longValue());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-097/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestDenseLongColumnFailure
- Expected vs actual
- Expected the document added after the failed batch to read back its own value 42; actual:
expected:<42> but was:<-1>(-1 is the failed batch's value), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<42> but was:<-1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.junit.Assert.assertEquals(Assert.java:633)
org.apache.lucene.index.TestDenseLongColumnFailure.testFailedDenseBatchShiftsLaterValues(TestDenseLongColumnFailure.java:86)- Lucene's design note: a non-aborting exception may partially update the index, but "These updates are consistent".
- Lucene's own recovery test throws from a dense cursor and asserts exact later values; its 6-value batch never fills a page, and it commits right after the failure.
- The dense SORTED path and the stock flat vector writer (#16734) keep documents and values aligned.
The full argument410 words
- Design note (
DocumentsWriter.java:76-79): "All other exceptions ("non-aborting exceptions") can still partially update the index structures. These updates are consistent, but, they represent only a part of the document seen up until the exception was hit. When this happens, we immediately mark the document as deleted so that the document is always atomically ("all or none") added to the index."updateBatchfollows it (DocumentsWriterPerThread.java:349-354).addDocument: "if an Exception is hit ... then the index will be consistent" (IndexWriter.java:1465). TheaddBatchjavadoc (:1528-1536), the column javadocs, CHANGES and MIGRATE never ask for a flush after a failed batch. - Lucene's tests deliberately throw from a dense cursor and check the writer afterwards.
ColumnBatchTestUtilhas throwing-cursor helpers "so tests can exercise the failure-cleanup path in DocumentsWriterPerThread#updateBatch" (:589-591), includingThrowingDenseLongColumn(:638-642).TestColumnBatchIndexing#testLongValuesCursorThrowMidBatchRecovers(:740-792) asserts 777, 111 and 222 for the documents indexed afterwards. That shows intent to keep the writer usable, not a written contract for same-segment recovery. It misses the bug because its 6 values throw inside the first fill call and because it commits right after the failure (:760-762, "so the cleanup-induced fully-deleted segment is pruned"). With a 300-value batch failing at 280 the test passes with thatcommit()and fails without it:expected:<777> but was:<1>. - Two sibling paths do it right.
SortedDocValuesWriter.addDenseOrdinalValues(:156-182, #16101) registers exactly theprocesseddocuments in afinally; a Z3 model that counts values and documents found no batch of up to 4096 values where the counts differ after a throw. The dense vector path merged in #16734 writes the rule down: "The cursor may throw while it is being consumed ... the writer must remain in a consistent state: every doc ID it has recorded must have its vector ... record doc IDs and vectors only afterfillhas returned" (KnnFieldVectorsWriter.java:46-50), and its new test keeps the failed and the recovery batch in one segment on purpose (TestColumnBatchIndexing.java:886-922). That holds for the stock flat writer; LFV-579, a separate defect, shows HNSW and scalar-quantized wrappers over a custom flat writer that fall out of step. - History. #16270 made batch exception handling match
updateDocuments. #16553, backported to 10.5.2, is a precedent: a non-aborting exception left indexing-chain state inconsistent (a stored-fields frame left open), so that a later flush failed; reviewers called it a corruption issue and pulled it into the 10.5.2 release candidate.
The devil's-advocate check208 words
The strongest case for "works as designed" (independent checkers, both still concluding "real"): the API, LongColumn and LongValuesCursor are experimental; the cursor "produces exactly size() values" (LongValuesCursor.java:22-23), so a cursor that throws within range is a broken producer; PackedLongValues.Builder promises no atomicity; addBatch declares only IOException; and the upstream test flushes before indexing again, as if only post-flush recovery were intended.
Why it fails: the documents that end up wrong are later ones whose own add calls succeeded, and no contract lets a successful add store another document's value. The same javadoc requires implementations to throw on overrun (:25-26, :57-58), so exceptions belong to the cursor protocol (that javadoc covers overrun, not an in-range failure, so the contract stays ambiguous), and Lucene's own helper throws in range on purpose. updateBatch keeps the segment and nothing says to flush; the test's commit() is there, by its comment, to prune the deleted segment. A stale comment in testDenseColumnCountMismatchThrows ("avoid the partially-written DV entries", TestColumnBatchIndexing.java:291-292) dates from a PR revision that wrote values and documents together, so it is about values on deleted documents, not misalignment. Verdict: a defect (a correctness bug of an experimental API; a maintainer may still label it an enhancement).
Recommended Register exactly the values that reached the buffer (validated)
Remember pending.size() before the bulk add and, in a finally, register that many of the batch's own (already deleted) documents and pendingCounts entries, as the dense SORTED path does. With it the 3 tests pass, and so do the 20 other closest test classes, all 8,892 core-module tests and :lucene:core:check -x test.
final long sizeBefore = pending.size();
try {
  pending.add(cursor);
} finally {
  // Register a doc for every value that reached the buffer, even if the cursor threw part-way,
  // so that values stay aligned with docsWithField.
  final int added = Math.toIntExact(pending.size() - sizeBefore);
  if (added > 0) {
    docsWithField.addRange(firstDocID, firstDocID + added);
    lastDocID = firstDocID + added - 1;
  }
  updateBytesUsed();
}
All options and trade-offs4 options · 621 words
One fix was built and validated through gradle; the others are design alternatives that were not built.
In both addDenseValues methods, remember pending.size() before the bulk add and, in a finally, register as many documents (and, for SORTED_NUMERIC, pendingCounts entries) as values were added, like SortedDocValuesWriter.addDenseOrdinalValues. The registered doc ids are the batch's own documents, which updateBatch deletes right after, so no live document gains a value. +34/-23 lines in two files; the snippet is the NumericDocValuesWriter half.
final long sizeBefore = pending.size();
try {
  pending.add(cursor);
} finally {
  // Register a doc for every value that reached the buffer, even if the cursor threw part-way,
  // so that values stay aligned with docsWithField.
  final int added = Math.toIntExact(pending.size() - sizeBefore);
  if (added > 0) {
    docsWithField.addRange(firstDocID, firstDocID + added);
    lastDocID = firstDocID + added - 1;
  }
  updateBytesUsed();
}
Trade-offs
- The rejected batch's deleted documents keep values until a merge drops them, as with the per-document path; nothing reads them through live docs.
- Cost: constant bookkeeping per non-empty dense batch (two
size()reads, a subtraction, aMath.toIntExactand a branch); no added work per value on the success path and no extra copy. - It relies on
Builder.size()counting exactly the completed fill calls, whichadd(LongValuesCursor)does by construction (PackedLongValues.java:274-276). - The
finallyalso runsupdateBytesUsed()after a failure; the stock code skips it, so the in-memory segment's RAM accounting misses the kept values until the writer's next successful update.
What the checks validated
- stock, the test, seed DEADBEEF, assertions on: 1 classes, 3 tests, 3 failures, 0 errors, 0 skipped (the 3 tests fail).
- stock, the test, assertions off: 1 classes, 3 tests, 3 failures, 0 errors, 0 skipped.
- stock, :lucene:core:check -x test: BUILD SUCCESSFUL.
- fix, the test, assertions on: 1 classes, 3 tests, 0 failures, 0 errors, 0 skipped.
- fix, the test, assertions off: 1 classes, 3 tests, 0 failures, 0 errors, 0 skipped.
- fix, the test, seed CAFEBABE, tests.iters=10: 1 classes, 30 tests, 0 failures, 0 errors, 0 skipped.
- fix, closest suites, assertions on: 21 classes, 909 tests, 0 failures, 0 errors, 62 skipped.
- fix, closest suites, assertions off: 21 classes, 909 tests, 0 failures, 0 errors, 62 skipped.
- fix, :lucene:core:check -x test: BUILD SUCCESSFUL.
- fix, all of :lucene:core:test, seed DEADBEEF: 749 classes, 8,892 tests, 0 failures, 0 errors, 322 skipped.
- Repro harness, fix shadowed on main
a9779ef3c193: the finder repro 2 of 2 pass, the paste-ready test 3 of 3, the index-sort probe 2 of 2. - Earlier: the finder's fix check, the independent reproduction's 6 tests (judge re-run), the cross-model reviewers' tests with 77 and 72 relevant existing tests, the security-probe tests and the finder repro at the introducing commit all pass with the fix.
- The cross-model review's own persistence test, run by this doc's fact check on main
a9779ef3c193(assertions on): stock 1 of 2 fail (expected:<7> but was:<1000>), with the fix shadowed 2 of 2 pass.
On a throw, restore size, pendingOff and the packed pages.
Trade-offs
Not built. Harder than it looks: the loop may already have packed a page that also holds earlier documents' values, so a rollback has to undo a pack or keep a copy.
Copy the whole batch out of the cursor before touching the buffer.
Trade-offs
Not built. Atomic and simple, but every value is copied once more, which gives up the point of the bulk path.
Discard the in-memory segment.
Trade-offs
Not recommended: it drops every document since the last flush, against updateBatch's non-aborting handling (#16270) and the recovery Lucene's own test checks.
Not a security issue, since only the application's own cursor can throw there, but a multi-tenant service that builds such a cursor from request data could see doc-values filters and sorts apply rejected values to whichever documents are indexed next.
Semi-formal. A hunt AI tool modelling the columnar dense writers suspected the page loop. A bounded Z3 model found the smallest failing case (255 values in the page, a 2-document batch failing on its 2nd value) and none for batches fitting the page's free slots. A failure-injection sweep on the real jar and a JUnit repro confirmed it.
The method in full208 words
Method: SMT (Z3) model of the dense doc-values page loop, then failure injection on the real jar.
- The hunt unit covered the columnar
addBatchpath. Reading the dense writers while modelling them raised the hypothesis; the model (dense_commit.py) encodesPackedLongValues.Builder.add(LongValuesCursor)and the writers' bookkeeping. Property W1, "dense long DV page loop failure-atomic", is violated (sat) with the smallest witness 255 values already in the page and a 2-document batch failing on its 2nd value (1 value kept, 0 documents); no violation for batches that fit in the current page's free slots (unsat). Property W3 found no violation for the dictionary SORTED dense path (batches up to 4096 values). The model is bounded (W1: up to 4 pages, 1,024 values) and counts values and documents only, not buffer contents or RAM accounting. - A failure-injection sweep on the stock jar then threw from the cursor at every point of a grid: 301 of 605 points violated for dense NUMERIC and for dense SORTED_NUMERIC, with assertions on and off; 0 of 605 for the sparse long paths.
- The finder wrote the 2-test JUnit repro and a fix; verifiers then reproduced it with their own tests, and an adjudication re-ran their tests and the finder's with new seeds (Independent checks).
No prior report of the long doc-values defect (searched 2026-10-26, re-checked 2026-10-27). Closest: #16734, merged 2026-10-26, which states the same rule for the new dense vector path only.
Searches5 searches
No issue, PR, list thread, JIRA entry or downstream report describes this bug. #16734 states the invariant; because its review discussed the same failure mode for the vector path, a maintainer may see this as a known pattern.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repositories (Elasticsearch, OpenSearch, Solr) | 2026-10-26 | a scripted prior-report search, 4 runs (71 queries in the main run); 24 manual searches; the changed files of all 412 open PRs and of 624 closed PRs since 2026-04-15 (follow-up count) | no report; no open PR changes the dense long path |
| Review threads | 2026-10-26 | #15990 (7 comments, 11 reviews, 20 inline comments) and #16101 read in full | no discussion of a throwing dense long cursor |
| Mailing lists (dev@, java-user@, issues@, commits@), JIRA archive, web | 2026-10-26 | 20 list queries, 4 JIRA queries, 6 recorded web queries, direct lists.apache.org searches | no report; the column-API design thread does not discuss exceptions |
| GitHub issues and PRs (apache/lucene) | 2026-10-27 | re-check: LongValuesCursor, "addBatch doc values", "addBatch exception", "columnar addBatch"; commits to the three files | no new item; no commit to the three files since 2026-06-14 |
| Related items | 2026-10-26 | read | #16734 (the same rule for vectors, requested in review), #15990 / #16066 (introduced it), #16101 (sibling done right), #16553 (precedent), #16270 (batch exception handling) |
Introduced with the columnar API by #15990 (3d89568, 2026-05-14) and released in 10.5.0 through its backport #16066; the three methods are unchanged since. Affects 10.5.0 to 10.5.2, 10.6.0 (by reading) and main.
Versions tested6 rows
Introduced by 3d89568155799e2e1efe132f67967d9725f4bd60, "Add experimental columnar indexing api (#15990)" (Tim-Brooks, merged 2026-05-14; parent 227255fdb08a), released through the branch_10x backport 3ec3bff01b15 (#16066, same day; the same diff of the three files, git patch-id --stable b091896e1e7b). The method bodies are identical at 3d89568 and at a9779ef3c193. branch_10x, branch_10_5 and branch_10_6 carry the same code (read 2026-10-26).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | paste-ready JUnit 3 of 3 fail through gradle and the harness, assertions on and off; index-sort probe 2 of 2 |
main ea57360912ed | affected | finder repro 2 of 2 fail, assertions on and off |
| 10.5.0, 10.5.1, 10.5.2 | affected | finder repro 2 of 2 fail (10.5.0 and 10.5.2 also with assertions off); paste-ready JUnit 3 of 3 on each (10.5.2 also with assertions off) |
3d89568 (#15990) | introducing commit | finder repro 2 of 2 fail, assertions on and off; 0 of 2 with the fix (javac-built jars of a git archive snapshot with substituted test-framework dependencies, run with main's dependency graph) |
227255fdb08a (parent), 10.4.0, 9.12.3 | no API | the columnar API does not exist; the test does not compile |
fix (scratch worktree of a9779ef3c193) | not affected | the paste-ready test, the closest suites, all of :lucene:core:test and :lucene:core:check -x test pass |
Confirmed by an adjudication (high confidence, no dissent) after an independent reproducer, a cross-model reviewer (OpenAI GPT-5.6) with the works-as-designed lens, a devil's-advocate verifier and a root-cause review, which all ran their own tests; the adjudication re-ran them with new seeds. This doc re-ran it through gradle on main.
Checks and verdicts311 words
Every check that ran Java reproduced it; the refute-lens review gave no verdict, and its own test, re-run by the finder, fails on main and passes with the fix.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own tests written from the claim: 3 of 6 fail on main (assertions on and off), 10.5.0 and 10.5.2 (600-document batch failing at 520: [42, 43, 44] read [-1, -2, -3]); the 3 controls pass; CheckIndex clean; the fix passes 6 of 6. |
| Works-as-designed review (OpenAI GPT-5.6, the cross-model review) and its re-run | real, high | Rated the intended-behaviour case moderate but insufficient; its test fails on main and 10.5.2, a sparse sibling passes; the re-run added a persistence test (the good document reads 1000 instead of 7 after commit, close and reopen). |
| Intended-behaviour devil's advocate | real, high | No intended argument survives; showed that the upstream recovery test passes only because of its commit() (expected:<777> but was:<1> without it). |
| Root-cause review (OpenAI GPT-5.6) | real, high | Agrees with the root cause and fix site; its tests fail on main (including SORTED_NUMERIC with pendingCounts active); the fix passes them and 77 existing tests. |
| Refute review (OpenAI GPT-5.6) | no verdict | Its own test, re-run by the finder, fails on main at the page boundary and passes with the fix once an over-strict assertion is relaxed. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's tests with a new seed (3 of 6 fail, 6 of 6 pass with the fix) and the finder repro (2 of 2 fail). |
| This doc | reproduced, fix validated | Paste-ready test 3 of 3 fail through gradle on main with assertions on and off; with the fix it passes, as do the 21 closest classes including it (909 tests) and all of the core module (8,892 tests), and :lucene:core:check -x test is clean. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 492 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,207 words
- Registry title
- When a dense LongColumn's values cursor throws during addBatch, the NUMERIC/SORTED_NUMERIC doc values it already delivered stay buffered with no document, so later documents of that field in the same segment are stored with another document's value
- Area
- index / columnar addBatch doc values (dense NUMERIC and SORTED_NUMERIC writers)
- Priority
- Medium, rank 150: A throwing dense LongColumn cursor leaves values buffered so every later document of that field in the segment is silently stored with another document's value, surviving merges with CheckIndex clean, but it is an error path of an experimental API whose one known downstream user keeps it off.
- Impact class
- data corruption
- Impact note
- Hits applications that use the experimental IndexWriter#addBatch (10.5.0 and later) with a dense LongColumn feeding NUMERIC or SORTED_NUMERIC doc values (LongField's schema included) whose own values cursor throws a RuntimeException after the field's buffer has completed a 256-value page during the call, and that keep indexing into the same writer before the next flush, the non-aborting recovery path that Lucene's own recovery test exercises; default IndexWriterConfig and codec, ordinary scale (255 earlier documents plus a 2-document batch suffice); every later document of that field in the in-memory segment is then persisted with a wrong value, CheckIndex stays clean, and only reindexing the affected documents repairs it.
- Summary
- You index a dense LongColumn as NUMERIC or SORTED_NUMERIC doc values with IndexWriter#addBatch, its values cursor throws part-way (for example after 255 earlier documents, a 2-document batch whose cursor fails on its 2nd value), and you keep adding documents to the same writer. You expect what Lucene's own recovery test asserts: the exception propagates, the batch's documents are deleted, and a document added afterwards with value 42 reads back 42. Instead the values the cursor delivered before the throw stay in the doc-values buffer with no document attached, so the good document reads back -1 (a value of the rejected batch) and every later document of that field in the segment is shifted by the same number of values, which survives commit, reopen and forceMerge(1) while CheckIndex finds nothing wrong.
- Introduced
- 3d89568155799e2e1efe132f67967d9725f4bd60 (#15990 'Add experimental columnar indexing api', main; parent 227255fdb08a), released through the branch_10x backport 3ec3bff01b15 (#16066), whose patch for the three methods is the same (git patch-id b091896e1e7b) [exec: the finder repro fails 2 of 2 at 3d89568 with -ea and -da and passes there with the fix shadowed; it does not compile at the parent, which has no columnar API; read: git log -S / -L and blame attribute every line of NumericDocValuesWriter.addDenseValues, SortedNumericDocValuesWriter.addDenseValues and PackedLongValues.Builder.add(LongValuesCursor) to this commit, unchanged since]. The bug is as old as the API. (2026-05-14 (#15990 merged into main, #16066 into branch_10x))
- First affected version
- 10.5.0 [exec, -ea and -da]
- Affected versions
- 10.5.0, 10.5.1 and 10.5.2 (latest 10.5.x release) [exec: finder repro fails 2 of 2; 10.5.0 and 10.5.2 also with -da]; main from 3d89568 (2026-05-14) through ea57360912ed [exec at both ends, -ea and -da]; the unreleased branch_10x and branch_10_5, and branch_10_6 (10.6.0, released 2026-10-29), carry the same code for the three methods [read, 2026-10-26]; not applicable: every release before 10.5.0, including 10.4.0 and 9.12.3, where the columnar API does not exist (compile error) [exec]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3, code reading
- Upstream and prior reports
- none found (2026-10-26: a scripted prior-report search, 4 runs (finder, verifier, two follow-up runs) over GitHub issues, PRs and commits of apache/lucene, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 24 manual read-only gh searches on apache/lucene plus downstream-repository searches; the review threads of #15990 (7 comments, 11 reviews, 20 inline comments) and #16101 read in full; the changed-file lists of all 412 open apache/lucene PRs and of 624 closed PRs since 2026-04-15; direct lists.apache.org searches; 8 web queries; search gaps: builds@ full text and private channels); related prior items, none of them this bug: #16734 (merged 2026-10-26 as a9779ef3c19; on main and branch_11x, not on branch_10_6; dense vector path for addBatch: a reviewer asked that the writer 'should only record doc IDs after fill returns', and the PR documents and implements that rule for vectors only; the long doc-values path is neither mentioned nor changed; different fix site; the item that states the invariant), #15990 and its backport #16066 (introduced it; no review discussion of a throwing dense cursor), #16101 (sibling SORTED dense path, written with try/finally), #16553 (precedent: a non-aborting exception left stored-fields chain state inconsistent, treated as corruption and backported to 10.5.2), #16270 (aligned batch exception handling with the document path)
- Lucene commit tested
- main
a9779ef3c193, runs of 2026-10-27: the 3-test paste-ready JUnit through gradle in a scratch worktree, with assertions on and off (3 of 3 fail), and through the repro harness on main (assertions on and off), 10.5.0, 10.5.1 and 10.5.2 (10.5.2 also with assertions off) (3 of 3 fail); the finder's 2-test repro on main with assertions on and off (2 of 2 fail) and with the fix shadowed (0 of 2); an index-sort probe (2 of 2 fail, 0 of 2 with the fix); the fix through gradle (section Suggested fix). Earlier, by the hunt and the follow-up: the introducing commit3d89568, 10.5.0, 10.5.1, 10.5.2 and mainea57360912ed, with assertions on and off.
- Finding record
lucene/core/src/java/org/apache/lucene/util/packed/PackedLongValues.java:261-279 (Builder.add(LongValuesCursor): packIfFull, fillDocValues, then pendingOff/size advance per chunk)lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:81-94 (addDenseValues: pending.add(cursor) before docsWithField.addRange and lastDocID), :176-200 (BufferedNumericDocValues.nextDoc pairs the next docsWithField doc with iter.next())lucene/core/src/java/org/apache/lucene/index/SortedNumericDocValuesWriter.java:73-102 (addDenseValues: pending.add(cursor) before pendingCounts, docsWithField.addRange and currentDoc)lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:156-182 (addDenseOrdinalValues: try/finally registers exactly the processed docs)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1066-1102 (processDenseLongColumn: the DV pass runs before the points pass)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:314-359 (updateBatch: a processBatch exception is non-aborting, deleteLastDocs marks the batch deleted, the DWPT is kept)lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:67-79 (non-aborting exceptions 'can still partially update the index structures. These updates are consistent')lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1529-1539 (addBatch javadoc, @lucene.experimental, no exception-state statement)lucene/core/src/java/org/apache/lucene/document/column/LongValuesCursor.java:22-25, 35, 58 ('produces exactly size() values'; implementations must throw on overrun)lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:739-790 (testLongValuesCursorThrowMidBatchRecovers: 6-value batch, w.commit() at :761 right after the failure, exact later values asserted)lucene/core/src/test/org/apache/lucene/document/column/ColumnBatchTestUtil.java:513 (throwing-cursor helpers 'to exercise the failure-cleanup path in DocumentsWriterPerThread#updateBatch'), :566 (ThrowingDenseLongColumn)SECURITY.md:28, 42, 50 (threat model)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:969-972, 1068-1104 (dense dispatch; DV pass first)lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:81-94 (addDenseValues), 176-200 (BufferedNumericDocValues)lucene/core/src/java/org/apache/lucene/index/SortedNumericDocValuesWriter.java:73-102 (addDenseValues), 192-199, 215-217 (single-valued read path)lucene/core/src/java/org/apache/lucene/util/packed/PackedLongValues.java:34, 66, 265-289 (page size; add(LongValuesCursor); packIfFull)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:314-359, 392-409 (updateBatch; deleteLastDocs does not flush)lucene/core/src/java/org/apache/lucene/document/column/LongColumn.java:79-88 (values() must be implemented for DENSE)
- Who is affected
lucene/core/src/java/org/apache/lucene/document/column/LongColumn.java:79-88; grep of lucene/*/src/java for LongValuesCursor implementations (none)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1950-1978, 2020-2056 (doc-values updates: doc-values-only fields, not index-sort fields)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:67-80lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1462-1468, 1528-1539lucene/core/src/java/org/apache/lucene/document/column/LongValuesCursor.java:21-67lucene/core/src/test/org/apache/lucene/document/column/ColumnBatchTestUtil.java:588-700lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:278-300, 740-792, 886-922lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:149-182lucene/core/src/java/org/apache/lucene/codecs/KnnFieldVectorsWriter.java:40-63; lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99FlatVectorsWriter.java:506-512
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:156-182
- TestDenseLongColumnFailure.java (JUnit test):
repro/LFV-097/src/org/apache/lucene/index/TestDenseLongColumnFailure.java(90 lines)
The alt text follows the scene's summary-card text.
assets/LFV-097/bug.png(492 KB)