The column pass turns each tuple's batch doc id into a segment doc id. It range-checks that id for every column kind except a doc-values-only DictionaryColumn, whose writer only checks that ids increase. So batch doc numDocs becomes the segment number of the next document you add, and that document gets the value.
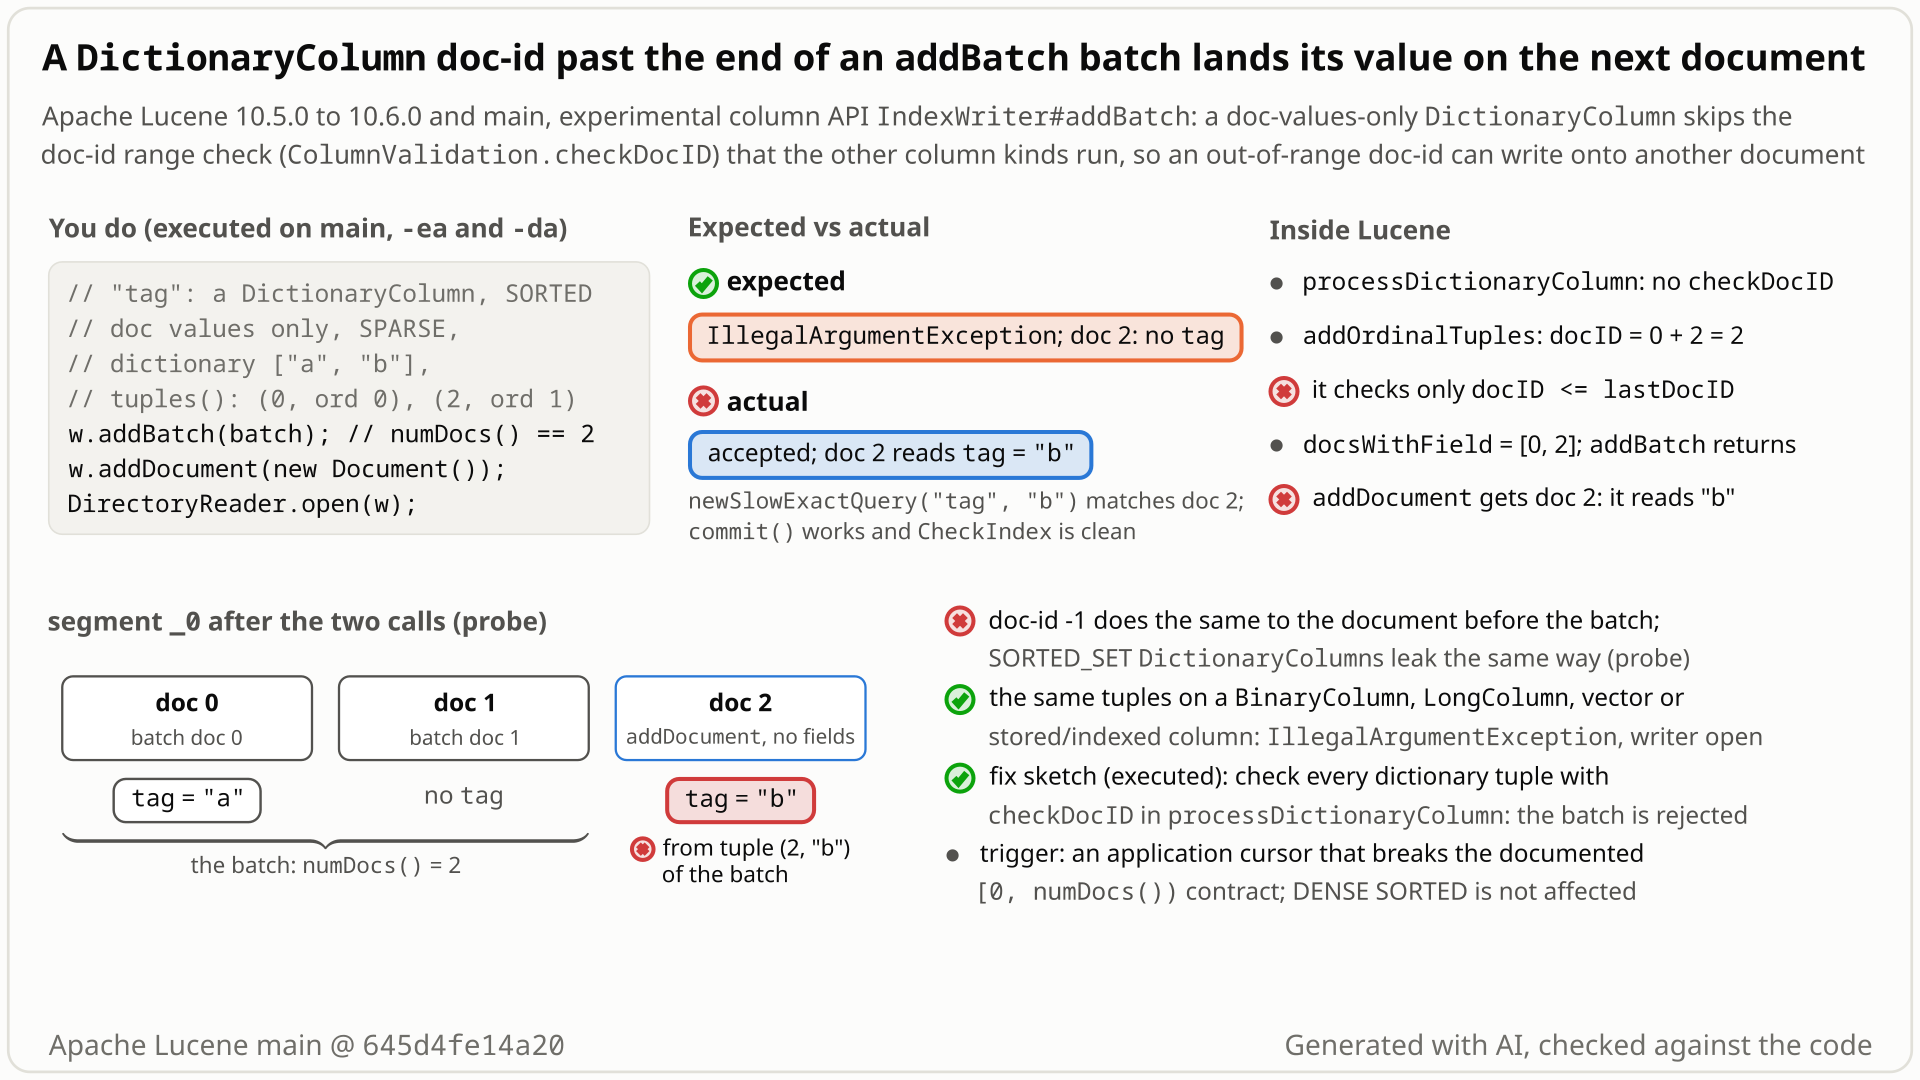
IndexWriter#addBatch(ColumnBatch)(experimental, since 10.5.0) adds a batch of documents column by column. A batch hasnumDocs()documents, numbered 0 tonumDocs() - 1inside the batch.- Each column carries one field. A sparse column gives Lucene (doc id, value) pairs through a tuple cursor that the application writes; a
DictionaryColumngives each value as an ordinal into its dictionary, for SORTED or SORTED_SET doc values. - Lucene appends the batch to the in-memory segment: batch doc i becomes segment doc
baseDocID + i, and the next document added after the batch gets the next segment number,baseDocID + numDocs.
- Build a
ColumnBatchwithnumDocs() == 2and one doc-values-only SORTEDDictionaryColumn"tag" (dictionarya,b) whose own cursor returns (doc 0,a) and (doc 2,b). Doc 2 is one past the end: an off-by-one in your cursor. - Call
writer.addBatch(batch), thenwriter.addDocument(new Document())with no "tag" field, and open an NRT reader: 3 documents. - You expect
addBatchto throwIllegalArgumentException("returned batch doc-id 2 which is out of range [0, 2)"), as it does for aLongColumnorBinaryColumnwith the same mistake, or at least the new document to have no tag. - Instead
addBatchreturns normally and the new document, segment doc 2, reads tag =b. The dictionary path skips the range check, and its writer only checks that doc ids increase, so it stores a value for a document that does not exist yet. - The same happens with SORTED_SET columns, and doc id -1 can land on the document added just before the batch, when there is one. No error with assertions on or off, on 10.5.0, 10.6.0 and main.
Applications that use the experimental addBatch (10.5.0 and later) with a doc-values-only SORTED or SORTED_SET DictionaryColumn whose own cursor is off by one at either end. Default config, a 2-document batch, assertions on or off. A document added through plain addDocument silently gains a value, and sorting, faceting or doc-values filters on that field see it.
Mechanism, terms and numbers927 words
IndexWriter#addBatch(ColumnBatch) (experimental, since 10.5.0) indexes a batch column by column; the application writes the tuple cursors that say which batch document gets which value, and ColumnBatch#numDocs says "All column doc-ids must be in the range [0, numDocs())". The column pass enforces that rule with ColumnValidation.checkDocID on every LongColumn, BinaryColumn and vector tuple, and the row pass enforces it for stored and indexed columns, but IndexingChain.processDictionaryColumn hands a doc-values-only DictionaryColumn's tuples straight to the SORTED / SORTED_SET writers, which check only that ids increase (SORTED) or only assert it (SORTED_SET). So in a 2-document batch a tuple for doc 2 is accepted, stored for segment doc baseDocID + 2, and the next document added with plain addDocument silently reads that value; doc id -1 can land on the document added just before the batch, if there is one. No error with assertions on or off. Every trigger is a caller cursor that breaks the documented contract of an experimental API, so the priority is low and maintainers will likely call the fix hardening; but the same mistake is rejected on every other column kind, and here a document outside the batch changes. A related gap, fixed by the same patch: on SORTED_NUMERIC and SORTED_SET columns the only check that tuple doc ids never decrease is a Java assert. It is in 10.5.0 to 10.6.0 and main; a cursor wrapper that calls checkDocID fixes it and passes all 8,898 core tests.
// IndexingChain.java:1223-1257 (processDictionaryColumn), added by #16101, unchanged since
case SORTED -> {
  SortedDocValuesWriter writer = (SortedDocValuesWriter) pf.docValuesWriter;
  if (column.density() == Column.Density.DENSE) {
    OrdinalsCursor cursor = column.values();
    ColumnValidation.checkDenseCount(column, cursor.size(), numDocs);   // :1238
    writer.addDenseOrdinalValues(baseDocID, dict, cursor);
  } else {
    writer.addOrdinalTuples(baseDocID, dict, column.tuples());          // :1241  no checkDocID
  }
}
case SORTED_SET -> {
  SortedSetDocValuesWriter writer = (SortedSetDocValuesWriter) pf.docValuesWriter;
  OrdinalsTupleCursor cursor = column.tuples();                         // dense or sparse
  writer.addOrdinalTuples(baseDocID, dict, cursor);                     // :1247  no checkDocID
}

// SortedDocValuesWriter.java:131-144 (addOrdinalTuples)
while ((batchDocID = cursor.nextDoc()) != DocIdSetIterator.NO_MORE_DOCS) {
  int docID = baseDocID + batchDocID;
  if (docID <= lastDocID) { throw new IllegalArgumentException("... appears more than once ..."); } // :133
  int ord = cursor.ordValue();
  int id = lookupOrTranslate(ord, dictionary, ordToHash);   // the ordinal IS range-checked (:186)
  pending.add(id);
  docsWithField.add(docID);
  lastDocID = docID;
}- Every other tuple loop checks the batch doc id first:
ColumnValidation.checkDocID(column, batchDocID, numDocs)(ColumnValidation.java:296-307, "Throws if batchDocID is outside [0, numDocs)") atIndexingChain.java:982,:990,:1017,:1026,:1038(LongColumn),:1125,:1136,:1149,:1162(BinaryColumn),:1280,:1293,:1306(vectors). The row pass rejects out-of-order (:903-909) and out-of-range (:948-958) ids of stored and indexed columns. processDictionaryColumndoes not, for sparse SORTED and for every SORTED_SET column. The writers do not check the range either: the SORTED writer checks only that ids increase (SortedDocValuesWriter.java:133), the SORTED_SET writer only asserts it (SortedSetDocValuesWriter.java:125).- So segment doc
baseDocID + numDocsgets a value although that document does not exist yet. The next document added to the in-memory segment takes that number; if it has no value for the field, nothing notices, and the flush writes the value as its own. Doc id -1 gives segment docbaseDocID - 1, the document added just before the batch, if the in-memory segment has one. For SORTED_SET the value is added to that document's set, because the writer keeps its last document open until the next one or the flush; SORTED accepts it only if that document has no value for the field (otherwise the order check at:133rejects it, as it does when the batch starts the segment). The executed -1 runs (a SORTED_SET test of the study, a SORTED case of the diagram probe) each had one earlier document without a value. - No error with the default codec, assertions on or off, when a later document fills the slot. With no later document, one exploration run (assertions off, default codec; a single observation, not a general result) committed a 2-document segment that read back
0=a 1=b(batch doc 1 had no value) andCheckIndexreported it clean; with the test framework's asserting codec the flush can instead fail an assertion. - Not affected: DENSE SORTED dictionary columns (the dense path counts values,
:1236-1239) and stored or indexed dictionary columns (the row pass rejects the id first).
SortedNumericDocValuesWriter.addValue (:63), SortedSetDocValuesWriter.addValue (:85) and SortedSetDocValuesWriter.addOrdinalTuples (:125) check that doc ids never decrease only with assert docID >= currentDoc;. The two addValue asserts were written in 2016 (LUCENE-7474) for the per-document chain, which generates the ids itself, and #15990 routed caller tuple ids into them; #16101 wrote addOrdinalTuples with a copy of the same assert; the cursor javadoc says the ids are "emitted in non-decreasing order". With tuples (1, v) then (0, v') on a SORTED_NUMERIC LongColumn or SORTED_SET column: with assertions on, an AssertionError escapes addBatch and the writer closes as a tragic event (IndexWriter.java:1581-1589); with assertions off (production) the batch is accepted and a later valid addDocument with that field is rejected with Out of order doc ids: last=1, next=0; the study also saw a later document read a batch value ([20] instead of [40]) and, for SORTED_SET, the next commit fail and close the writer. NUMERIC, BINARY/SORTED and SORTED dictionary columns already reject backwards ids, through the single-valued writers' "appears more than once in this document" check. The one-test repro covers the range gap only.
Exposure and likelihood213 words
- Who is hit. Callers of the experimental
IndexWriter#addBatch(alsoupdateDocuments(Term|Query, ColumnBatch)), new in 10.5.0, with a doc-values-onlyDictionaryColumn(SORTED sparse; SORTED_SET sparse or dense) and a tuple cursor of their own that returnsnumDocsor -1. Lucene ships only abstract columns and cursors, so every caller writes its own cursor. - No special setup. Default
IndexWriterConfig, codec and directory; a 2-document batch with one boundary tuple; deterministic; assertions on or off. Far-out ids were not run. - What goes wrong. A document outside the batch, which the caller added with plain
addDocument, silently gets a SORTED or SORTED_SET value it never had (for SORTED_SET, an extra value in its set), and anything that reads that field's doc values sees it. With no later document, a document inside the batch can get the value instead, andCheckIndexcalled the result clean (one exploration run, default codec). - What does not go wrong. Correct cursors are unaffected; DENSE SORTED, stored and indexed dictionary columns are checked; nothing outside doc values is touched. The one downstream user found (Elasticsearch, by code reading) builds no
DictionaryColumn, and its tuple cursors take doc ids from a bounded row counter. - Impact class: data corruption, likelihood contrived (it needs a buggy caller cursor on an experimental API); priority low.
One JUnit test on the public API: default codec, ByteBuffersDirectory, a 2-document batch and 1 later document, single thread, deterministic. It accepts a rejection and checks only that the later document has no tag, so it fails with assertions on and off. Put it next to the existing column tests in lucene/core and run it with gradle.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.document.column;

import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LeafReader;
import org.apache.lucene.index.SortedDocValues;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.BytesRef;

public class TestDictionaryColumnDocIdOutOfRange extends LuceneTestCase {

  public void testDocIdEqualToNumDocsDoesNotReachNextDocument() throws Exception {
    int[] docs = {0, 2};
    int[] ords = {0, 1};
    DictionaryColumn tag =
        new DictionaryColumn(
            "tag",
            SortedDocValuesField.TYPE,
            Column.Density.SPARSE,
            List.of(new BytesRef("a"), new BytesRef("b"))) {
          @Override
          public OrdinalsTupleCursor tuples() {
            return new OrdinalsTupleCursor() {
              int i = -1;

              @Override
              public int nextDoc() {
                return ++i < docs.length ? docs[i] : DocIdSetIterator.NO_MORE_DOCS;
              }

              @Override
              public int ordValue() {
                return ords[i];
              }
            };
          }
        };
    ColumnBatch batch =
        new ColumnBatch() {
          @Override
          public int numDocs() {
            return 2;
          }

          @Override
          public Iterable<Column> columns() {
            return List.of(tag);
          }
        };

    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      try {
        w.addBatch(batch);
      } catch (IllegalArgumentException rejectingIsFine) {
      }
      w.addDocument(new Document());
      try (DirectoryReader r = DirectoryReader.open(w)) {
        LeafReader leaf = getOnlyLeafReader(r);
        SortedDocValues dv = leaf.getSortedDocValues("tag");
        int next = leaf.maxDoc() - 1;
        String value =
            dv != null && dv.advanceExact(next) ? dv.lookupOrd(dv.ordValue()).utf8ToString() : null;
        // expected: doc-id 2 >= numDocs never reaches the next document; actual: it reads "b"
        assertNull("tag of the document added after the batch", value);
      }
    }
  }
}
cp TestDictionaryColumnDocIdOutOfRange.java $LUCENE/lucene/core/src/test/org/apache/lucene/document/column/
cd $LUCENE
./gradlew :lucene:core:test --tests TestDictionaryColumnDocIdOutOfRange -Ptests.seed=DEADBEEF
# assertions off (production-like): add -Ptests.asserts=false
- Expected
addBatchthrowsIllegalArgumentException, or the document added after the batch has no tag value.- Observed
addBatchreturns normally and that document reads tagb:tag of the document added after the batch expected null, but was:<b>.
More files, environment, full output227 words
The test subclasses DictionaryColumn and ColumnBatch through their public and protected constructors, sets the default codec explicitly (TestUtil.getDefaultCodec()) and uses no randomness; a second seed (5EED0098, gradle, assertions on) gives the same failure. It accepts any IllegalArgumentException and does not check its message, the live-doc count, or the deleted documents a rejected batch leaves behind. Use this one test as the regression test too.
The same failure, by the hunt repro harness: main 645d4fe14a20, 10.6.0 and 10.5.0, assertions on and off. It does not compile against 10.4.0, which has no column API. The SORTED_SET, doc id -1 and order cases come from the study's other tests and are supporting evidence, not part of the repro.
| lucene | main 645d4fe14a20, 10.6.0 and 10.5.0: reproduced, assertions on and off; 10.5.1 and 10.5.2: reproduced by the study's 6-test class; 10.4.0 and earlier: no column API |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 |
# gradle, main 645d4fe14a20, seed DEADBEEF, assertions on
TestDictionaryColumnDocIdOutOfRange > testDocIdEqualToNumDocsDoesNotReachNextDocument FAILED
    java.lang.AssertionError: tag of the document added after the batch expected null, but was:<b>
        at org.apache.lucene.document.column.TestDictionaryColumnDocIdOutOfRange.testDocIdEqualToNumDocsDoesNotReachNextDocument(TestDictionaryColumnDocIdOutOfRange.java:90)
1 test completed, 1 failed

# gradle, same, -Ptests.asserts=false: the same failure and message
# repro harness, the same message: main 645d4fe14a20, 10.6.0 and 10.5.0, -ea and -da (1 run, 1 failed each)
# with the fix: the test passes (gradle, assertions on and off)- The same
addBatchrejects the same out-of-range id withIllegalArgumentExceptionon every other column kind, with upstream tests. - The other rule of the same cursor javadoc, ordinals in range, is checked on this very path; the doc-id rule is not.
- #16101 added the dictionary path without the check #15990 gave the others, and the value lands outside the batch.
The full argument246 words
- The same boundary rejects the same mistake everywhere else.
ColumnValidation.checkDocIDruns on every Long, Binary and vector tuple, and the row pass rejects bad ids for stored and indexed columns. Upstream tests assert it:TestColumnBatchIndexing#testRowColumnOutOfRangeDocIdThrowsand#testRowColumnOutOfOrderDocIdThrows,TestColumnBatchVectorColumn#testVectorOutOfRangeDocIDFailsand#testDecreasingDocIDFails. The study's parity probe: out-of-range ids onBinaryColumnSORTED,LongColumnNUMERIC and a storedDictionaryColumnare rejected withIllegalArgumentExceptionand the writer stays open. - The other clause of the same javadoc is enforced.
OrdinalsTupleCursorsays ids are "batch-local (0 to numDocs - 1)" and each ordinal "must be in [0, dictionary.length)"; the ordinal rule is checked on this path and tested (TestColumnBatchDictionaryColumn#testOutOfRangeOrdSparseThrows,#testOutOfRangeOrdDenseThrows), the doc-id rule is not. - History shows an omission, not a decision.
checkDocIDcame with the API (#15990, 2026-05-14). #16101 (2026-05-26) addedDictionaryColumnwithout it, with one approving review and no comments; its tests cover out-of-range ordinals only. The reviewed history (both PRs and their review threads, the 9 mails of the dev@ DISCUSS thread) and the code comments give no sign that the omission was deliberate. - Precedents. #16708 (merged 2026-09-28; CHANGES.txt lists it under 10.6.0 "Improvements", not "Bug Fixes") closed another
addBatch-vs-addDocumentvalidation gap, vector values; the API author's open #16116 adds doc-id order and upper-bound checks for a new column-pass consumer. Both support consistency; #16708's label also points toward a "hardening" label for this one. - The damage leaves the batch: the value lands on a document the caller added separately, through
addDocument.
The devil's-advocate check240 words
Strongest case for "intended" (caller misuse, so the fix is hardening): the rule is a caller obligation. ColumnBatch#numDocs says "All column doc-ids must be in the range [0, numDocs())", the cursors say ids are batch-local and non-decreasing, the API is @lucene.experimental, and addBatch declares only IOException, so nothing promises an IllegalArgumentException. Breaking the precondition is undefined behaviour. (Built by the study's intended-behaviour checker and an independent reviewer from another model family, OpenAI GPT-5.6, which rated it moderate.)
Why it fails: (1) Lucene treats the range part of that precondition as something to enforce: every other column-pass tuple loop range-checks its doc ids, since the API's first commit, with tests, and the neighbouring ordinal clause of the same javadoc is enforced on this very path (order is enforced less uniformly: three sibling paths only assert it). (2) The range check is two int comparisons per tuple, which every sibling path already pays; fix A adds one order comparison and one wrapper call per dictionary tuple. (3) The failure is silent and lands outside the caller's batch. (4) #16708 and #16116 show the project fixing exactly this kind of gap. What remains is the label, bug or hardening, which sets the low priority, not the verdict. A maintainer may also cite the dev@ proposal's goal of "less redundant field validation"; the study's intended-behaviour checker read that as schema checks once per column, not per-tuple doc-id checks. Verdict: not intended.
Recommended A. Check the dictionary tuples in processDictionaryColumn, and turn the order asserts into exceptions
In processDictionaryColumn, wrap the tuple cursor so every doc id goes through ColumnValidation.checkDocID (plus an order check), and turn the three assert docID >= currentDoc order checks into IllegalArgumentException. The repro passes, as do 14 closest suites (784 tests, assertions on and off) and all 8,898 core tests.
All options and trade-offs3 options · 641 words
A is validated and recommended; its checkedTuples wrapper is what fixes this bug, and the writer changes close the related order gap. B is the range part alone. A separate finding about a rejected out-of-range ordinal on a SORTED_SET DictionaryColumn has a different root cause, but its fix edits the same addOrdinalTuples loop. Workaround for users today: in your own cursor, check 0 <= doc && doc < numDocs, and that ids never decrease, before returning a doc id from nextDoc().
A. Check the dictionary tuples in processDictionaryColumn, and turn the order asserts into exceptions (validated by the checks) (recommended)
The study's fix, formatted with the build's google-java-format, +61/-6 in IndexingChain, SortedNumericDocValuesWriter and SortedSetDocValuesWriter. Shown: the wrapper that both dictionary branches now use (writer.addOrdinalTuples(baseDocID, dict, checkedTuples(column, numDocs))). The writer changes replace assert docID >= currentDoc; with if (docID < currentDoc) throw new IllegalArgumentException("field \"...\": doc ids must be added in non-decreasing order; got " + docID + " after " + currentDoc).
private static OrdinalsTupleCursor checkedTuples(DictionaryColumn column, int numDocs) {
  final OrdinalsTupleCursor in = column.tuples();
  return new OrdinalsTupleCursor() {
    int last = -1;

    @Override
    public int nextDoc() {
      int doc = in.nextDoc();
      if (doc != DocIdSetIterator.NO_MORE_DOCS) {
        ColumnValidation.checkDocID(column, doc, numDocs);
        if (doc < last) {
          throw new IllegalArgumentException(
              "DictionaryColumn \""
                  + column.name()
                  + "\" returned out-of-order batch doc-id "
                  + doc);
        }
        last = doc;
      }
      return doc;
    }

    @Override
    public int ordValue() {
      return in.ordValue();
    }
  };
}
Trade-offs
Callers with a buggy cursor now get an IllegalArgumentException from addBatch, as on the other column kinds. Cost: three int comparisons (two in checkDocID, one for order) and one wrapper call per dictionary tuple (no benchmark run). The writer checks also sit on the per-document path (addValue runs for every SORTED_NUMERIC / SORTED_SET value of addDocument, where ids are always in order); an if replaces an assert there. Not a rollback: the exception comes after updateBatch has reserved the batch's doc ids, and earlier tuples may already be buffered; the batch's documents are then marked deleted (DocumentsWriterPerThread.java:339-354), not erased. In the diagram probe's fix run the rejected batch left 2 deleted documents in RAM and tuple (0, a) buffered; the readers then showed one live document with no tag, and CheckIndex was clean. What was tested is a usable writer and no spill onto the next document.
What the checks validated
- Scratch worktree of main
645d4fe14a20(removed afterwards), seed DEADBEEF: stock, the test fails through gradle with assertions on and off; with A it passes. - Closest suites with A,
-Ptests.asserts=trueandfalse: the repro,org.apache.lucene.document.column.*(TestColumnBatchBinaryColumn,TestColumnBatchDictionaryColumn,TestColumnBatchLongColumn,TestColumnBatchMultiColumnField,TestColumnBatchTokenStreamColumn,TestColumnBatchVectorColumn),TestColumnBatchIndexing, and the doc-values writer usersTestDocValuesIndexing,TestDocValues,TestMultiDocValues,TestIndexSorting,TestLucene90DocValuesFormat*: 784 tests in 15 classes, 55 skipped, 0 failures each time. - All of
:lucene:core:testwith A (assertions on): 8,898 tests in 749 classes, 322 skipped, 0 failures;:lucene:core:checkGoogleJavaFormatpasses on the formatted patch. The same results before and after formatting. - The study's 6-test class (range and order cases) fails 6 of 6 on stock
645d4fe14a20and passes 6 of 6 with A, assertions on and off.
Keep only the checkDocID call in the wrapper. A check inside the two addOrdinalTuples loops would need more: both take only (int baseDocID, List<BytesRef>, OrdinalsTupleCursor), so they would have to gain numDocs and the column for checkDocID(Column, int, int), or carry their own range check.
Trade-offs
Fixes this bug; leaves the order gap assert-only. Use it if the order gap is fixed separately.
Document that out-of-range ids are undefined behaviour.
Trade-offs
Leaves a silent write onto another document, and keeps the dictionary path inconsistent with every other column kind.
Only the application's own cursor chooses these doc ids; a product that maps client-sent row positions to them without its own check could see a doc-values value land on a neighbouring document.
Fuzzing the columnar addBatch API: a fuzz target that checks the writer after random batches found a dense SORTED_SET dictionary batch for 7 documents whose last tuple named doc 7, one past the end; it was accepted and changed the next document. A code check showed that only the dictionary path skips the range check.
The method in full181 words
- Method (non-formal): fuzzing in a hunt unit on the columnar
addBatchAPI. A Jazzer target built random column batches and checked a writer-consistency property after everyaddBatch. Its smoke run found a dense SORTED_SETDictionaryColumnfornumDocs= 7 whose 8 tuples had doc ids 0 to 7 (the target numbers dense tuples 0, 1, 2, ...), so the last was doc id 7 =numDocs, one past the end;addBatchaccepted it and it changed the next document's values ("recovery doc lost its SORTED_SET value for field a (batch threw=false)"). The tuple count alone is not the fault: a dense SORTED_SET column needs at least one value per document, and this path counts nothing. - Diagnosis. A read-only check showed that every column-pass tuple loop calls
checkDocIDexcept the dictionary path. The order gap was found separately, by code reading while modelling the column pass: the 2016 per-document asserts now receive caller tuple ids. - Reduction. The finder wrote public-API JUnit tests (6 tests, range and order); a later minimization kept only the 2-document SORTED case as the one-test repro.
No prior report: two scripted prior-report search runs (60 GitHub issue/PR, 40 mailing-list, 8 JIRA-archive and 12 web queries), manual GitHub searches, all 412 open PRs and the review threads of the two PRs that added the code (2026-10-25/26), refreshed 2026-10-31. Related: #16708 and open #16116 add similar checks elsewhere.
Searches2 searches
Nearest items, none this bug: #16101 (added the dictionary path without the range check; one LGTM review), #15990 and its backport #16066 (defined the contract and checkDocID), #16708 / backport #16732 (vector values validated in addBatch; CHANGES.txt lists #16708 under 10.6.0 "Improvements"), open #16116 (the API author adds doc-id order and upper-bound checks for a new column-pass consumer; it does not touch processDictionaryColumn), #16734 (vectors only, merged 2026-10-26). Four Elasticsearch PRs use addBatch; none mentions the gap. Limits: keyword search cannot prove absence; GitHub search handles camelCase identifiers inconsistently; private channels are invisible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repositories, JIRA archive, mailing lists, web | 2026-10-25/26 | two scripted prior-report search runs (60 GitHub issue/PR, 6 commit, 4 downstream, 40 mailing-list, 8 JIRA-archive and 12 web queries); 12 manual GitHub searches (addBatch, ColumnBatch, DictionaryColumn, addOrdinalTuples, processDictionaryColumn, checkDocID, ...); changed-file lists of all 412 open PRs; every review comment of #15990 and #16101; the 9 mails of the dev@ column-API DISCUSS thread | no report of this gap; precedents #16708 and #16116 |
| Refresh: GitHub issues, PRs and commits (read-only API) | 2026-10-31 | DictionaryColumn (all time); processDictionaryColumn, checkDocID, addOrdinalTuples, ColumnBatch, columnar addBatch (created since 2026-10-20); addBatch (updated since 2026-10-26); commits to the five involved files since 2026-10-20 | nothing new: DictionaryColumn matches #16101, #16225, #16227 only; #16734 (vectors) is the only recent change |
Introduced by #16101 (merged 2026-05-26), which added DictionaryColumn without the range check that #15990 gave every other column kind; first released in 10.5.0. The repro fails on 10.5.0, 10.6.0 and main; 10.4.0 has no column API. Not fixed upstream.
Versions tested6 rows
Introduced by #16101 "Add DictionaryColumn for SORTED / SORTED_SET dvs" (Tim-Brooks, merged 2026-05-26 as e79c6780627 on main; branch_10x cherry-pick 8a9e55f254d). All 35 lines of processDictionaryColumn (IndexingChain.java:1223-1257) still blame to it at 645d4fe14a20. checkDocID is older: #15990 (3d895681557, 2026-05-14) added it to every column path that existed then. The order gap entered with #15990 (SORTED_NUMERIC LongColumn, SORTED_SET BinaryColumn) and #16101 (SORTED_SET DictionaryColumn); the two addValue asserts are from LUCENE-7474 (d50cf97617c, 2016), the addOrdinalTuples one (SortedSetDocValuesWriter.java:125) from #16101 (e79c6780627). Both commits first shipped in 10.5.0. Builds at the introducing commits were prepared but never run, so the commit attribution rests on git history and code reading. Still unchanged on upstream main 2f424fd428da (2026-10-30).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the one test fails (gradle and harness, -ea and -da) |
| 10.6.0 | affected | the one test fails (-ea and -da) |
| 10.5.0 | affected | the one test fails (-ea and -da); first release with the column API |
| 10.5.1, 10.5.2 | study's tests | the study's 6-test class fails 6 of 6 (-ea and -da) |
| 10.4.0, 9.12.3 | API absent | no column API: the tests do not compile |
fix A on 645d4fe14a20 | not affected | the one test passes (-ea and -da); 8,898 core tests pass |
An independent reproducer, an intended-behaviour devil's advocate, an independent reviewer from another model family (OpenAI GPT-5.6) that ran its own tests, an adjudication (confirmed, high) and a credibility audit all found it real; earlier cross-model reviews ended without a verdict. They expect maintainers to call the fix hardening.
Checks and verdicts297 words
Each check had its own lens; the cross-model reviews ended without a verdict. The study's four repro files were later replaced by the one test.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Own public-API 8-test class written from the claim only: 8 of 8 fail on main, 10.5.0 and 10.5.2 with assertions on and off (80 of 80 over 10 random seeds); pass with the fix. Its exploration run found the clean commit and clean CheckIndex; it narrowed the scope to doc-values-only columns. |
| intended-behaviour devil's advocate | real | Built the strongest "caller misuse" case and rejected it; its parity probe shows the sibling column kinds reject the same ids and keep the writer open; added the SORTED_SET dictionary order case. |
| cross-model reviewer, works-as-designed lens | real, medium | OpenAI GPT-5.6, executed: its own tests fail on main and 10.5.2 and pass with the fix; 61 existing DictionaryColumn and LongColumn tests pass with the fix; rated the intended argument moderate and rejected it. |
| reviews (refute, root cause) | no verdict | Both ended without a final answer; the root-cause reviewer's own test, re-run by the finder, fails on main and passes with the fix. |
| adjudication | confirmed, high | Re-ran the reproducer's tests with a new seed (8 of 8 fail, both modes; pass with the fix) and the finder's tests; framing: missing and inconsistent validation in an experimental API. |
| credibility audit | real, priority lowered | Re-ran the finder's tests with a fresh seed (6 of 6 fail, both modes); kept the data-corruption class but lowered the priority for the opt-in API and the off-contract input; noted that it is not index corruption. |
| minimization | verified | One test on main 645d4fe14a20: fails with assertions on and off, passes with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 446 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,396 words
- Registry title
- IndexWriter#addBatch does not validate tuple doc-ids on some doc-values column paths: a doc-values-only SORTED/SORTED_SET DictionaryColumn accepts a doc-id outside [0, numDocs) and writes the value onto a neighbouring document, and SORTED_NUMERIC/SORTED_SET columns check doc-id order only with a Java assert, so decreasing doc-ids close the writer (-ea) or are accepted and break later documents and commits (-da)
- Area
- index / columnar addBatch (column pass: DictionaryColumn, SORTED_NUMERIC and SORTED_SET doc-values writers)
- Priority
- Low, rank 886: AddBatch skips doc-id validation on some doc-values column paths, so an off-by-one in a caller's cursor silently lands a value on a neighbouring document, but only buggy callers of an experimental API hit it.
- Impact class
- data corruption
- Impact note
- Hits only applications that call the experimental IndexWriter#addBatch (first released in 10.5.0) with a tuple cursor of their own that breaks the documented doc-id contract, either a doc-id of -1 or >= numDocs on a doc-values-only SORTED or SORTED_SET DictionaryColumn or decreasing doc-ids on a SORTED_NUMERIC LongColumn, SORTED_SET BinaryColumn or SORTED_SET DictionaryColumn, which is input that every sibling column path rejects with IllegalArgumentException; default IndexWriterConfig, codec and directory, ordinary scale (one bad tuple); the damage reaches documents outside the batch (a value silently attached to the previous or next document, surviving commit with a clean CheckIndex, or a writer that closes and loses uncommitted documents), and the one downstream user found (Elasticsearch, code reading) builds no DictionaryColumn and the tuple cursors read there take doc-ids from a bounded row counter, so they are in order by construction.
- Summary
- You add a batch with IndexWriter#addBatch whose doc-values-only DictionaryColumn (SORTED or SORTED_SET) has a tuple cursor that returns a batch doc-id equal to numDocs or -1, or whose SORTED_NUMERIC or SORTED_SET column returns doc-ids in decreasing order, for example (1, v) then (0, v'). You expect an IllegalArgumentException with the writer still open and no other document touched, which is what the same addBatch call does for LongColumn, BinaryColumn, vector and stored or indexed (row-pass) columns that break the same documented contract. Instead the out-of-range value is silently attached to the document indexed just before or just after the batch (it survives commit, and CheckIndex reports a clean index), and the out-of-order tuples either throw an AssertionError that closes the writer (-ea) or are accepted (-da), after which a later valid addDocument is rejected with 'Out of order doc ids: last=1, next=0', another later document reads a value from the batch, and the next commit can fail and close the writer.
- Introduced
- Two commits by Tim-Brooks, both first released in 10.5.0. Part (b), order on SORTED_NUMERIC LongColumn and SORTED_SET BinaryColumn: 3d895681557 (#15990 'Add experimental columnar indexing api', main; branch_10x backport 3ec3bff01b1, #16066), which started passing caller tuple doc-ids to SortedNumericDocValuesWriter.addValue and SortedSetDocValuesWriter.addValue, whose only order check is 'assert docID >= currentDoc' from d50cf97617c (LUCENE-7474, 2016, written for the per-document path where the writer assigns the ids), and added only the range check (checkDocID) on those loops. Part (a), range, plus the SORTED_SET DictionaryColumn order case: e79c6780627 (#16101 'Add DictionaryColumn for SORTED / SORTED_SET dvs', main; branch_10x cherry-pick 8a9e55f254d), whose processDictionaryColumn never calls checkDocID and whose SortedSetDocValuesWriter.addOrdinalTuples has only the assert [read: git log -S/-L, git blame and ancestry in the full-history clone; exec: release boundary only, 10.4.0 cannot compile the repro and 10.5.0 fails; builds at the two commits were prepared but not run]; not a regression of any release (2026-05-14 (part b, #15990 merged) / 2026-05-26 (part a, #16101 merged))
- First affected version
- 10.5.0 [exec]
- Affected versions
- 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed [exec: the finder repro fails 6/6 on each with -ea and -da; the independent reproduction's repro fails 8/8 on 10.5.0, 10.5.2 and main with -ea and -da; the intended-behaviour check replayed 10.5.0 and 10.5.2 with -ea; the cross-model review's expected-behaviour test fails on 10.5.2 with -da]; the heads of branch_10_5 (2026-10-04), branch_10_6 and branch_10x (2026-10-24) have the same code [read], and 10.6.0 (released 2026-10-29) fails [exec: the one-test repro, -ea and -da, 2026-10-31]; not applicable: 10.4.0 and every earlier release, including 9.12.3 (no org.apache.lucene.document.column package and no IndexWriter#addBatch; the repro does not compile) [exec]; not fixed upstream as of main ea57360912ed [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-25 and 2026-10-26: scripted prior-report searches A-range and B-order with 60 GitHub issue/PR, 6 commit, 4 downstream-repo, 40 mailing-list (dev@, java-user@, issues@, commits@), 8 JIRA-archive and 12 distinct web queries, plus the finder's earlier 21-query run and the intended-behaviour check's 31-query run with the lists; 12 manual read-only gh searches and 6 downstream issue and code searches; the changed-file lists of all 412 open PRs; all review comments of #15990 and #16101 and the 9 mails of the dev@ '[DISCUSS] Column-oriented indexing API for IndexWriter' thread; the four Elasticsearch PRs that use addBatch); related prior items, none of them this bug: #16101 (introduced the range gap; one approving review, no comments; its tests cover out-of-range ordinals only), #15990 and its backport #16066 (defined the doc-id contract and checkDocID), #16708 and its backport #16732 (merged: a different addBatch validation gap, vector values, fixed as a defect), open #16116 (the API author adds doc-id range and order checks to a new column-pass consumer), #16734 (vectors only; merged 2026-10-26 as a9779ef3c19; on main and branch_11x, not on branch_10_6); no open PR touches processDictionaryColumn or the three writers' order checks; the minimal repro still fails on main e1faeba08bd (2026-11-02, -ea and -da)
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the one-test repro through gradle in a scratch worktree (assertions on and off; removed afterwards) and through the hunt repro harness (assertions on and off, seed DEADBEEF; a later gradle run with seed 5EED0098 fails the same way); the fix through gradle (the repro and 14 closest suites, 784 tests, assertions on and off; all of:lucene:core:test, 8,898 tests, assertions on; the google-java-format check); the study's 6-test class (range and order), stock and with the fix, both modes. The release jars 10.6.0 and 10.5.0 with the one-test repro, both modes; 10.4.0 (no column API). The study ran on mainea57360912ed(the sameprocessDictionaryColumn) and on 10.5.0, 10.5.1 and 10.5.2. Upstream main2f424fd428da(2026-10-30) has no commit to the involved files since645d4fe14a20. OpenJDK 25.0.3, Linux aarch64 (the only platform run).
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1221-1255 (processDictionaryColumn passes column.tuples() to addOrdinalTuples with no checkDocID; DENSE SORTED uses values() + checkDenseCount), :980, :988, :1015, :1024, :1036, :1123, :1134, :1147, :1160, :1273, :1287, :1301 (checkDocID in every other column-pass loop), :901-906 (row pass rejects out-of-order ids)lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:133 (addOrdinalTuples checks only docID <= lastDocID); SortedSetDocValuesWriter.java:84-85 (addValue: assert docID >= currentDoc) and :122-127 (addOrdinalTuples: the same assert); SortedNumericDocValuesWriter.java:62-63 (addValue: the same assert)lucene/core/src/java/org/apache/lucene/document/column/ColumnBatch.java:20-32 ('All column doc-ids must be in the range [0, numDocs())', @lucene.experimental); LongTupleCursor.java:23, :35, ObjectTupleCursor.java:23, :37, OrdinalsTupleCursor.java:23, :37 (non-decreasing order); ColumnValidation.java:297 (checkDocID), :325 (checkVectorDocIDStrictlyIncreasing)lucene/core/src/java/org/apache/lucene/index/DocsWithFieldSet.java:46-60 ('Out of order doc ids' IllegalArgumentException; new FixedBitSet(docID + 1)); IndexWriter.java:1537 (addBatch), :1581-1583 (catch Throwable, onTragicEvent)
- The finding in 30 seconds
a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1223-1257 (processDictionaryColumn; :1236-1239 dense SORTED, :1241, :1245-1247), :982, :990, :1017, :1026, :1038, :1125, :1136, :1149, :1162, :1280, :1293, :1306 (checkDocID calls), :903-909, :948-958 (row pass)a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:123-146 (addOrdinalTuples; :133), :185-195 (lookupOrTranslate ordinal check)a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/SortedSetDocValuesWriter.java:84-85, :115-127; a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/SortedNumericDocValuesWriter.java:62-63a Lucene main checkout lucene/core/src/java/org/apache/lucene/document/column/ColumnValidation.java:296-307 (checkDocID); a Lucene main checkout lucene/core/src/java/org/apache/lucene/document/column/ColumnBatch.java:28-31; OrdinalsTupleCursor.java:21-47a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1537 (addBatch), :1575-1590 (updateBatch: Error -> onTragicEvent); DocsWithFieldSet.java:46-50
- Who is affected
a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1528-1572 (addBatch, updateDocuments(Term|Query, ColumnBatch), @lucene.experimental)
- Why it looks unintended
a Lucene main checkout lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:519-550; a Lucene main checkout lucene/core/src/test/org/apache/lucene/document/column/TestColumnBatchVectorColumn.java:451-485; TestColumnBatchDictionaryColumn.java:391-424a Lucene main checkout lucene/core/src/java/org/apache/lucene/document/column/OrdinalsTupleCursor.java:36-37, :46; ColumnBatch.java:29-30; a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:185-195
- History
GitHub commits API, 2026-10-31: no commit to IndexingChain.java, SortedDocValuesWriter.java, SortedSetDocValuesWriter.java, SortedNumericDocValuesWriter.java or ColumnValidation.java after a9779ef3c193 (#16734) up to main 2f424fd428da
- TestDictionaryColumnDocIdOutOfRange.java (one test):
repro/LFV-098/src/org/apache/lucene/document/column/TestDictionaryColumnDocIdOutOfRange.java(94 lines)
assets/LFV-098/bug.png(446 KB)