Quantized vector formats store each vector relative to a centroid, the average vector of the segment. A merge recomputes the centroid from every source segment, and the code assumes that a segment without the field answers null. SortingCodecReader, the documented way to re-sort an index, does not.
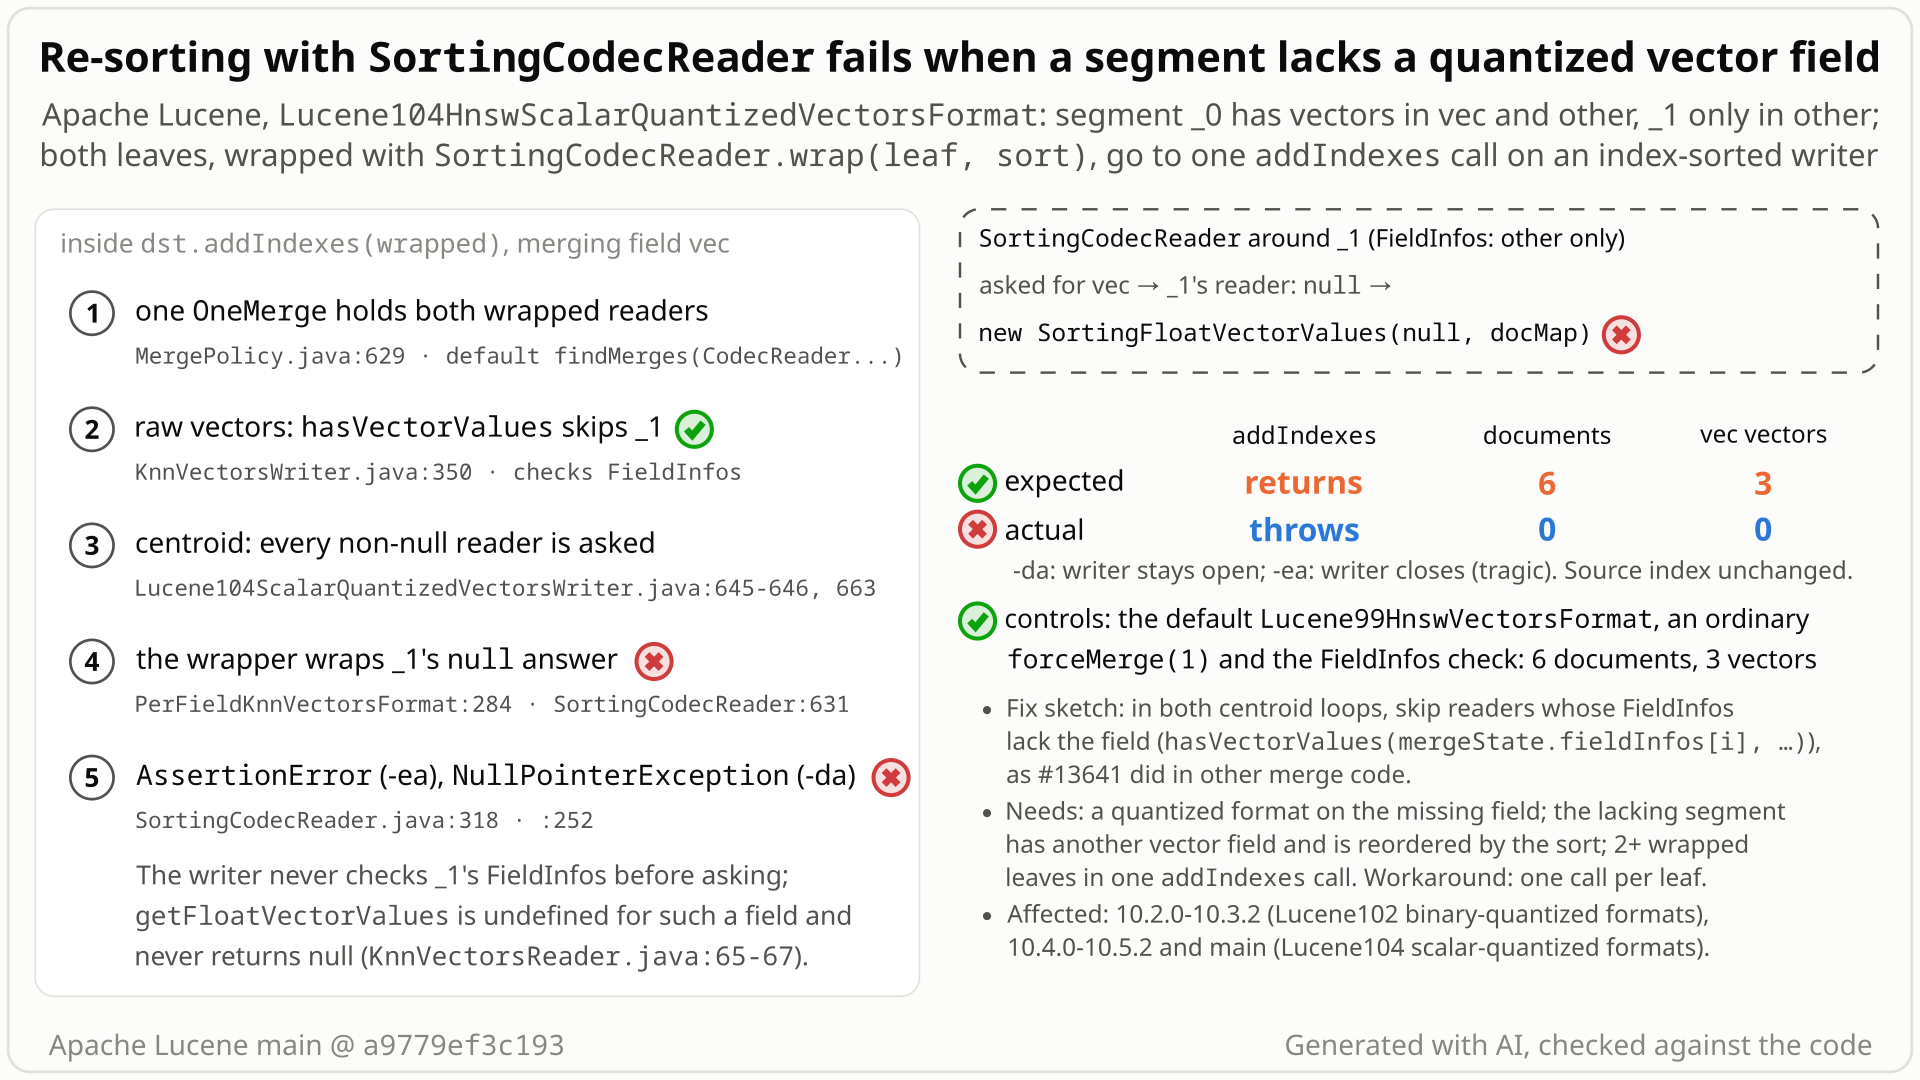
vec; the segment without it answers through SortingCodecReader, which wraps the null, and addIndexes fails with 0 of 6 documents added. Select the still to open it at full size. Generated with AI, checked against the code.- Your codec stores field
vecwithLucene104HnswScalarQuantizedVectorsFormat. Segment 1 has 3 documents with a float vectorvecand a byte vectorother; segment 2 has 3 documents with onlyother. - You re-sort as the
SortingCodecReaderjavadoc says: wrap both segments withSortingCodecReader.wrap(reader, sort)and pass them in oneaddIndexescall to a fresh writer withsetIndexSort(sort). You expect 6 documents, 3 with avecvector, as the defaultLucene99HnswVectorsFormatgives on the same index. - Instead the quantized writer recomputes the centroid of
vecby asking every segment for itsvecvectors, without checking whether that segment has the field. A plain segment answersnulland is skipped;SortingCodecReaderwraps thenullinstead. addIndexesthrowsNullPointerException(AssertionErrorwith-ea) and adds 0 of 6 documents. The source index is unchanged; oneaddIndexescall per segment works.
Applications that re-sort an index with SortingCodecReader and one addIndexes call over several segments, using a quantized vector format on a float field that a reordered segment lacks while it has another vector field. The default format, ordinary flushes, merges and queries are not affected; one addIndexes call per segment avoids it.
Mechanism, terms and numbers929 words
SortingCodecReader's javadoc describes how to re-sort an existing index: wrap all its readers and add them to a fresh IndexWriter with addIndexes(CodecReader...). With a quantized vector format (Lucene104[Hnsw]ScalarQuantizedVectorsFormat on 10.4+ and main, the Lucene102 BBQ formats on 10.2-10.3) this fails when one segment has vectors for some other field but none for a float32 or fp16 field that uses the quantized format (byte fields skip the centroid code). To recompute the merged centroid, Lucene104ScalarQuantizedVectorsWriter asks every source reader for the field and skips a source only when the answer is null; it never checks that source's FieldInfos, although KnnVectorsReader#getFloatVectorValues is undefined for such a field and "never null". The per-field reader of a plain segment happens to answer null, so ordinary merges pass, but SortingCodecReader wraps the null and fails: NullPointerException at SortingCodecReader.java:252 with assertions off, AssertionError at :318 with assertions on (fp16 fields: the NullPointerException either way). addIndexes throws and adds nothing; the source index is unchanged. It is a new instance of the bug class #13641 fixed for the other vector writers in 9.12.0. Introduced in 10.2.0 by #14078; affects 10.2.0 to 10.6.0 (10.6.0 by reading) and main.
- Centroid: the quantized formats (
Lucene104ScalarQuantizedVectorsFormat,Lucene104HnswScalarQuantizedVectorsFormat; on 10.2-10.3 the Lucene102 BBQ formats) quantize each vector relative to the segment's average vector. When segments merge, the writer computes the merged segment's centroid from the source segments. - Re-sort recipe:
SortingCodecReader's javadoc: "This can be used to re-sort and index after it's been created by wrapping all readers of the index with this reader and adding it to a fresh IndexWriter via IndexWriter#addIndexes(CodecReader...)".addIndexesmerges all the readers into one segment by default. - FieldInfos: each segment's list of fields. A segment where no document has
vechas novecentry. - The reader contract:
KnnVectorsReader#getFloatVectorValues: "The behavior is undefined if the given field doesn't have KNN vectors enabled on its FieldInfo. The return value is never null." So a merge must check the source'sFieldInfosfirst; the generic merge and the Lucene99 writers do (MergedVectorValues.hasVectorValues, added by #13641).
Lucene104ScalarQuantizedVectorsWriter.mergeOneFlatVectorFieldcallsmergeAndRecalculateCentroidsfor a float32 or fp16 field (Lucene104ScalarQuantizedVectorsWriter.java:351-360).- Its first loop asks every source through
floatingPointVectorValuesand skips a source only when the reader or its answer isnull(:597-605). ASortingCodecReader-wrapped source has no stored centroid (:569-575), so the loop stops and recalculates (:614-617,:625):calculateCentroidskips only anullreader (:642-646),accumulateCentroidonly anullanswer (:663-666). Neither loop looks atmergeState.fieldInfos[i]; the helper's javadoc states the assumption, it returns "null when the field is absent from this reader" (:577-591). - A plain segment's reader is
PerFieldKnnVectorsFormat.FieldsReader, which returnsnullfor a field not in itsFieldInfos(PerFieldKnnVectorsFormat.java:280-287, fp16:311-318). That is why ordinary flushes and merges pass. SortingCodecReader's vectors reader wraps the answer unconditionally:new SortingFloatVectorValues(delegate.getFloatVectorValues(field), docMap)(SortingCodecReader.java:631; byte:636, fp16:641). The constructor assertsdelegate != null(:318), theniteratorSuppliercallsvalues.iterator()(:252).SortingFloat16VectorValueshas no assertion (:402-406), so fp16 fields get theNullPointerExceptioneven with-ea. For points the same class passes anullthrough (:602-607).- When the lacking segment comes first, the first loop fails (
:602); otherwisecalculateCentroiddoes (:646). Both were executed.
- a quantized format on a float32 or fp16 field that some segment lacks (quantized only on a field every segment has passes; a byte field skips the centroid code,
Lucene104ScalarQuantizedVectorsWriter.java:356-358); - the lacking segment goes into one
addIndexescall as aSortingCodecReader, with at least one other segment that has the field. In the javadoc recipe every segment is wrapped, so that means two or more wrapped segments; strictly only the lacking one must be wrapped, and the destination needs no index sort (executed: wrapping only the lacking segment fails, wrapping only the other passes); - the lacking segment has some other vector field (executed: byte, float32, or float32 in the non-quantized format all fail; other encodings by reading), so it has a vectors reader; a segment with no vector field at all has none and is skipped;
- the sort reorders that segment; an already sorted segment (for example a one-document segment) is wrapped in a plain
FilterCodecReader(SortingCodecReader.java:458-460), which answersnull.
IndexWriter's own reorder paths (one SortingCodecReader over a single SlowCompositeCodecReaderWrapper, IndexWriter.java:3561-3564, :5557-5576) and BpVectorReorderer.reorderIndexDirectory (one addIndexes per segment) are not affected by code reading; they were not executed.
Segment 1: 3 documents with vec (3 dimensions) and other (byte). Segment 2: 3 documents with only other. Sort by a long doc-values field, inserted in descending order so the sort reorders both segments.
format of vec | expected | main a9779ef3c193 |
|---|---|---|
Lucene99HnswVectorsFormat (default, control) | 6 docs, 3 vec | 6 docs, 3 vec |
Lucene104ScalarQuantizedVectorsFormat | 6 docs, 3 vec | NullPointerException (-ea: AssertionError), 0 of 6 docs added |
Lucene104HnswScalarQuantizedVectorsFormat | 6 docs, 3 vec | the same; also with the lacking segment first |
Lucene104HnswScalarQuantizedVectorsFormat, fp16 vec | 6 docs, 3 vec | NullPointerException with and without -ea |
With assertions off the writer stays open (a commit after the failure shows 0 of 6 documents); with assertions on, a float32 field's AssertionError closes it as a tragic event, so the target gets no commit, while an fp16 field's NullPointerException leaves it open. With the default ConcurrentMergeScheduler, the merge thread also reports the exception as an uncaught MergeException.
Exposure and likelihood348 words
- Who. Applications that re-sort an existing index with the documented recipe (for example to add or change an index sort, or to reorder documents) and use a quantized vector format for a field that some segment lacks while that segment has another vector field. Realistic shapes: a second embedding field added later, so old segments have only the first; or an optional embedding that a whole segment happens to lack.
- Default vs opt-in. The default codec uses the non-quantized
Lucene99HnswVectorsFormat, which is not affected; the quantized formats are opt-in. From 10.4.0 the older int8 formats, which have the check, are read-only legacy, so every writable quantized format in core is affected.SortingCodecReaderand the Lucene104 quantized formats are@lucene.experimental. - Scale. No size threshold: 3 documents per segment are enough, as long as the sort reorders the lacking segment. The failure is deterministic (10 of 10 runs; the compact test also fails the same 4 tests in each of 5 iterations with another seed).
- Effect. A loud failure:
addIndexesthrows, nothing is added, nothing is corrupted, and the source index is unchanged. With assertions off the writer stays open, and each failed attempt leaves its partly written files in the target directory until the writer is closed (measured: 25 failed attempts, up to 326 files and 281,850 bytes, removed at close). With assertions on, a float32 field'sAssertionErrorcloses the writer as a tragic event; an fp16 field'sNullPointerExceptionleaves it open in both modes. - One way to lose data. An in-place re-sort (
OpenMode.CREATEon the source directory, all segments in one call) that closes the writer after the failure with the defaultcommitOnClosecommits an empty index over the original (measured: 40 to 0 documents). That is documentedclose()behaviour applied to any failure in that pattern, not something Lucene commits wrongly. - Workaround. One
addIndexescall per segment (measured: the in-place per-segment re-sort keeps all 40 documents, as 2 segments rather than one merged segment). Writing into a separate directory does not avoid the exception; it only protects the source from the in-place outcome above.
The test shows that re-sorting with SortingCodecReader.wrap plus one addIndexes call (as the class javadoc describes) fails with Lucene104ScalarQuantizedVectorsFormat when one re-sorted segment lacks one of two vector fields, because the quantized writer's centroid merge asks every source reader for the field without checking its FieldInfos.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.codecs.Codec;
import org.apache.lucene.codecs.lucene104.Lucene104ScalarQuantizedVectorsFormat;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.search.Sort;
import org.apache.lucene.search.SortField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestResortQuantizedMissingVectorField extends LuceneTestCase {

  private static Document doc(long sortValue, String vectorField) {
    Document doc = new Document();
    doc.add(new NumericDocValuesField("sort", sortValue));
    doc.add(new KnnFloatVectorField(vectorField, new float[] {1, 2}));
    return doc;
  }

  public void testResortSegmentLackingQuantizedField() throws Exception {
    Codec codec = TestUtil.alwaysKnnVectorsFormat(new Lucene104ScalarQuantizedVectorsFormat());
    Sort sort = new Sort(new SortField("sort", SortField.Type.LONG));
    try (Directory src = new ByteBuffersDirectory();
        Directory dst = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(
              src,
              new IndexWriterConfig().setCodec(codec).setMergePolicy(NoMergePolicy.INSTANCE))) {
        w.addDocument(doc(0, "a"));
        w.commit();
        w.addDocument(doc(2, "b"));
        w.addDocument(doc(1, "b"));
      }
      try (DirectoryReader reader = DirectoryReader.open(src);
          IndexWriter w =
              new IndexWriter(
                  dst,
                  new IndexWriterConfig()
                      .setCodec(codec)
                      .setIndexSort(sort)
                      .setMergeScheduler(new SerialMergeScheduler()))) {
        CodecReader[] sorted = new CodecReader[reader.leaves().size()];
        for (int i = 0; i < sorted.length; i++) {
          sorted[i] = SortingCodecReader.wrap((CodecReader) reader.leaves().get(i).reader(), sort);
        }
        // expected: all 3 docs are added; actual: NullPointerException (-da) or AssertionError (-ea)
        w.addIndexes(sorted);
        assertEquals(3, w.getDocStats().maxDoc);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-100/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestResortQuantizedMissingVectorField
- Expected vs actual
- Expected
addIndexesto add all 3 documents; actual:AssertionErroratSortingCodecReader.java:318with-ea,NullPointerExceptionatSortingCodecReader.java:252with-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError
       org.apache.lucene.index.SortingCodecReader$SortingFloatVectorValues.<init>(SortingCodecReader.java:318)
       org.apache.lucene.index.SortingCodecReader$5.getFloatVectorValues(SortingCodecReader.java:631)
       org.apache.lucene.codecs.lucene104.Lucene104ScalarQuantizedVectorsWriter.floatingPointVectorValues(Lucene104ScalarQuantizedVectorsWriter.java:584)
       org.apache.lucene.codecs.lucene104.Lucene104ScalarQuantizedVectorsWriter.mergeAndRecalculateCentroids(Lucene104ScalarQuantizedVectorsWriter.java:602)
       org.apache.lucene.codecs.lucene104.Lucene104ScalarQuantizedVectorsWriter.mergeOneFlatVectorField(Lucene104ScalarQuantizedVectorsWriter.java:360)
       org.apache.lucene.codecs.lucene104.Lucene104ScalarQuantizedVectorsWriter.mergeOneFlatVectorField(Lucene104ScalarQuantizedVectorsWriter.java:335)
       org.apache.lucene.codecs.hnsw.FlatVectorsWriter.mergeOneField(FlatVectorsWriter.java:63)
       org.apache.lucene.codecs.perfield.PerFieldKnnVectorsFormat$FieldsWriter.mergeOneField(PerFieldKnnVectorsFormat.java:132)
       org.apache.lucene.codecs.KnnVectorsWriter.merge(KnnVectorsWriter.java:141)
[...]- The getter's contract: "undefined" for a field missing from the segment's FieldInfo, and "never null". The caller that breaks it is Lucene's own writer.
- #13641 made the check a merge rule ("we must verify that a given field has vectors and exists"); the other vector writers follow it.
- The trigger is the documented re-sort recipe.
The full argument239 words
- Contract.
KnnVectorsReader#getFloatVectorValues: "The behavior is undefined if the given field doesn't have KNN vectors enabled on its FieldInfo. The return value is never null" (KnnVectorsReader.java:64-69; the byte and fp16 getters say the same,:82-87,:89-94). The application never calls the getter; the writer does. - The stated rule. #13641 (
74e3c44063a, 2024-09-11): "During segment merge we must verify that a given field has vectors and exists. The typical knn format checks assume the per-field format is used and thus only check fornull. But we should check for field existence in the field info and verify it has dense vectors". CHANGES 9.12.0: "Unify how KnnFormats handle missing fields and correctly handle missing vector fields when merging segments". It addedKnnVectorsWriter.MergedVectorValues.hasVectorValues, used by the generic merge (KnnVectorsWriter.java:350),Lucene99HnswVectorsWriter(:520) and the int8 writer. - Documented use.
SortingCodecReader's javadoc prescribes exactly this re-sort (SortingCodecReader.java:47-51); nothing requires every segment to carry every vector field. - History. #14078 (10.2.0) wrote the BBQ centroid loops six months after #13641, with the null-only check; #15169 (10.4.0) copied them byte for byte; #16473 (main) routed fp16 through them. None of the reviews discusses absent fields or
SortingCodecReader. - Tests.
TestSortingCodecReaderuses a single vector field.BaseKnnVectorsFormatTestCase.testMergingWithDifferentKnnFieldsasserts that such merges work, but passes for these formats because their own readers answernull. No CHANGES or MIGRATE entry, documentation or discussion accepts the crash.
The devil's-advocate check209 words
The intended-behaviour verifier, a review by a model from another family and the cross-model fact check of this doc built the strongest case for "works as designed": the contract makes the lookup undefined, so SortingCodecReader's assertion is allowed; SortingCodecReader and the formats are @lucene.experimental; the format is opt-in, the path uncommon and the failure loud with the source unchanged; and the writer documents its own assumption ("null when the field is absent from this reader"), which holds for the per-field reader and the raw Lucene104 reader.
Why it still is a bug: the undefined-behaviour clause binds the caller, and the caller is the writer, not the application, which follows the documented recipe. @lucene.experimental lowers severity, not validity. The helper's javadoc contradicts the abstract contract and #13641's rule; it explains how the bug arose, not that the crash is intended. Which class owns the fix is genuinely open: the writer breaks the caller precondition #13641 made a merge rule, while SortingCodecReader turns the null its delegate actually gives into an exception, unlike its own points path. Both fixes are validated. Verdict: a defect (the earlier verifiers and reviews rated the intended-behaviour argument weak; the cross-model fact check rated it moderate, mainly over which class should own the fix).
Recommended A: skip a source whose FieldInfos lack the field, in both centroid loops
Skip a source segment whose FieldInfos have no vectors for the field, in both centroid loops of Lucene104ScalarQuantizedVectorsWriter, with the hasVectorValues check #13641 added elsewhere (+7/-2). All 15 repro tests and 257 tests of the 9 closest suites pass with assertions on and off; guarding only one loop is not enough.
import static org.apache.lucene.codecs.KnnVectorsWriter.MergedVectorValues.hasVectorValues;
...
// in mergeAndRecalculateCentroids and in calculateCentroid
KnnVectorsReader knnVectorsReader = mergeState.knnVectorsReaders[i];
if (knnVectorsReader == null
    || hasVectorValues(mergeState.fieldInfos[i], fieldInfo.name) == false) {
  continue;
}
All options and trade-offs4 options · 629 words
Two fixes were applied in a scratch worktree at a9779ef3c193 and run through gradle (seed DEADBEEF) with the four repro classes and the closest upstream suites. They fix the bug at different sites; A follows the rule #13641 stated. Which one, or both, is the maintainers' call. Both fix only this defect: other registered bugs on the same re-sort recipe (LFV-112 with document blocks, LFV-278 and LFV-404 with a reordering merge policy) are separate.
A: skip a source whose FieldInfos lack the field, in both centroid loops (validated by the checks) (recommended)
In Lucene104ScalarQuantizedVectorsWriter.mergeAndRecalculateCentroids and calculateCentroid, skip a source when KnnVectorsWriter.MergedVectorValues.hasVectorValues(mergeState.fieldInfos[i], fieldInfo.name) is false, as #13641 did for the generic merge and the Lucene99 writers. One file, +7/-2.
import static org.apache.lucene.codecs.KnnVectorsWriter.MergedVectorValues.hasVectorValues;
...
// in mergeAndRecalculateCentroids and in calculateCentroid
KnnVectorsReader knnVectorsReader = mergeState.knnVectorsReaders[i];
if (knnVectorsReader == null
    || hasVectorValues(mergeState.fieldInfos[i], fieldInfo.name) == false) {
  continue;
}
Trade-offs
- Matches #13641 and the sibling writers; up to two
FieldInfoslookups per source and field per merge (one in each centroid loop). - It does not change what
SortingCodecReaderreturns, so any other caller that asks it for an absent field would still fail (none known in Lucene). - The 10.2/10.3 line needs the same two lines in
Lucene102BinaryQuantizedVectorsWriter(the release shadow runs show the guard fixes 10.2.0 and 10.3.2); on main the Lucene102 formats in backward-codecs are read-only, and their test-only writer copy has the same null-only checks. Open PR #16839 (ready for review since 2026-10-26) and draft PR #16819, which rewrite this code, would need it too. - Not done: the full core suite,
check, a CHANGES entry.
What the checks validated
- Stock: the 4 repro classes run 15 tests with 9 failures, assertions on and off.
- With A: 15 of 15 pass, and so do the 9 closest suites (core
TestLucene104ScalarQuantizedVectorsFormat,TestLucene104HnswScalarQuantizedVectorsFormat,TestLucene104ScalarQuantizedMergeScorer,TestQuantizedVectorValuesPrefetch,TestSortingCodecReader,TestFilterReadersForwardVectorPrefetch,TestIndexSorting,TestAddIndexes; miscTestBpVectorReorderer): 13 classes, 272 tests, 4 skipped (2 nightlytestRecall, 2 assumptions that apply only to other formats), 0 failures, with assertions on and with assertions off. - Both loops are needed: with the guard only in
calculateCentroid,testHnswScalarQuantizedLackingSegmentFirststill fails, in the first loop. checkGoogleJavaFormat,forbiddenApisMain,forbiddenApisTest,ecjLintMainandecjLintTestoflucene/corepass with A and the compact test.- Earlier, on main
ea57360912ed: the same guard passed the finder's test and 128 upstream tests, the reproducer's 7 tests, and the cross-model reviews' tests plus 125 Lucene104 format tests; in each release's own writer it turns 10.2.0, 10.3.2, 10.4.0 and 10.5.2 into passes.
In SortingCodecReader.getVectorReader(), return null when the delegate answers null for float32, byte and fp16 values, as getPointsReader already does. One file, +9/-3.
FloatVectorValues values = delegate.getFloatVectorValues(field);
return values == null ? null : new SortingFloatVectorValues(values, docMap); // same for byte and fp16
Trade-offs
- Fixes every caller that relies on a
nullanswer, including, by reading, a downstream copy of the BBQ writer. - Makes a reader return
nullwhere theKnnVectorsReaderjavadoc says "never null" (the per-field reader already does). - Leaves the writer's precondition violation in place: a wrapper or reader that does not answer
nullfor an absent field would still fail.
What the checks validated
- With B: 15 of 15 repro tests pass, and the same 13 classes run 272 tests, 4 skipped, 0 failures, with assertions on and with assertions off.
- Not format- or lint-checked.
A as the fix that follows the stated rule, B as hardening of the wrapper.
Trade-offs
Each was validated on its own; the combination was not run.
Say that the re-sort recipe does not support quantized fields that a segment lacks.
Trade-offs
Leaves the documented recipe broken; not recommended.
Elasticsearch's own copy of the BBQ writer has the same null-only check (read, not run), but a GitHub code search found no SortingCodecReader use in the default branches of Elasticsearch, OpenSearch, OpenSearch k-NN or Solr (2026-10-28, best effort).
A randomized differential test, not a formal method. It indexed the same documents three ways (index-time sort, re-sort through SortingCodecReader and addIndexes, pre-sorted insertion) with random vector formats and compared them; the re-sort path hit an AssertionError in SortingCodecReader. The stack trace led to the centroid code, then to a minimal JUnit.
The method in full133 words
Method: randomized differential testing (non-formal tier), in a hunt unit on index sorting.
- The harness builds the same documents with
IndexWriterConfig.setIndexSort, throughSortingCodecReader.wrapplusaddIndexes, and in pre-sorted order, with randomized vector formats, and compares the three per stored id. - Its assertions-on hunt hit an
AssertionErroratSortingCodecReader.java:318viaLucene104ScalarQuantizedVectorsWriter.floatingPointVectorValues. - The finder read the failing frames, found the missing
FieldInfoscheck, minimised it to a 3-test JUnit on the stock jar, ran it on main and released versions, and wrote a fix sketch. - Found 2026-10-25 on main
ea57360912ed; then checked by an independent reproducer, a devil's-advocate verifier, reviews by a model from another family (OpenAI GPT-5.6) that ran their own tests, an adjudication, a follow-up (history, prior reports, security), the registration check and a re-run on maina9779ef3c193.
No prior report found (2026-10-25/26) in GitHub issues, PRs and commits, four mailing lists, the JIRA archive, downstream repositories or the open PRs that touch these classes. Closest: #13626 / #13641, the same mistake in other merge code, fixed in 2024 before this code existed.
Searches4 searches
Verdict new. A maintainer may fairly call this "#13626 again in the new writers".
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits | 2026-10-25, 2026-10-26 | the hunt's prior-report tool (74 GitHub issue/PR queries, 9 commit queries: identifiers, behaviour phrasings, the NullPointerException text), 16 manual gh searches, a title sweep of the 490 issues and PRs updated since 2026-09-01, and the review comments of #14078, #15169, #16473 and #16764 | no report; related: #13626 / #13641 (same class, other writers, fixed 2024), #14123 / #14125 / #14128 (SortingCodecReader with a null vectors reader, fixed; added the assertion), #16762 / #16764 / #16800 (deleted docs in the same centroid methods, fixed) |
| Open apache/lucene PRs | 2026-10-26 (PR states re-checked 2026-10-28) | the file lists of 95 vector-, codec- and merge-related open PRs; the diffs of the 13 that touch the affected classes | #16839 (open, ready for review since 2026-10-26) and #16819 (draft) rewrite this centroid code and keep the unguarded lookup; #16879 and #16871 touch the same files without it |
| Mailing lists (dev@, java-user@, issues@, commits@) and the JIRA archive | 2026-10-25, 2026-10-26 | 44 list queries and 12 JIRA queries | no report; the JIRA archive predates the code |
| Downstream (Elasticsearch, OpenSearch, OpenSearch k-NN, Solr) and the web | 2026-10-26; code search re-run 2026-10-28 | 11 tool queries, 4 GitHub code searches, 6 web queries; on 2026-10-28 a GitHub code search for SortingCodecReader in elastic/elasticsearch, OpenSearch, OpenSearch k-NN and apache/solr (positive control: apache/lucene) | no report and no SortingCodecReader use downstream; Elasticsearch's own BBQ writer copy has the same null-only skip (read); apache/solr#4644 (closed, not merged) used the same re-sort recipe without vectors |
Introduced in 10.2.0 by #14078 (the BBQ formats, 2025-03-04), copied into the Lucene104 OSQ writer by #15169 (10.4.0) and extended to fp16 on main by #16473. All releases from 10.2.0 to 10.5.2 and main fail; 9.12.0 to 10.1.0 pass. Not fixed upstream.
Versions tested8 rows
Introduced by #14078 "Binary vector format for flat and hnsw vectors" (@benwtrent, reviewed by @mayya-sharipova; merged 2025-03-04; main 8856a5f4eb7, branch_10x backport 39e7f0973ec), which added the BBQ centroid loops with null-only checks. Carried into the current code by #15169 (OSQ, @mccullocht, co-authored by @benwtrent; merged 2025-09-17; 594eeb7e637, backport 07033dcd84c; first release 10.4.0), which copied both methods byte for byte, and extended to fp16 fields on main by #16473 (50c1e6acb7f, 2026-08-26). It reintroduces the defect class that #13641 (74e3c44063a, 9.12.0 and 10.0.0) fixed in the generic merge and the Lucene99 writers.
Adding only the FieldInfos guard to each release's own writer turns 10.2.0, 10.3.2, 10.4.0, 10.5.2 and main into passes, and removing only #13641's two guards from the 9.12.3 int8 writer makes it fail the same way. No parent-commit build was made: the writers did not exist before their introducing commits. branch_10_6 and branch_10x have the same loops (read, not executed); the three affected files are unchanged on upstream main 20ced71c1e6 (2026-10-27). Every release ran with assertions on; assertions off was also run on 9.11.1, 9.12.0, 9.12.3, 10.1.0, 10.2.0, 10.3.2, 10.4.0, 10.5.2 and main, with the same results. Releases before 9.11.1 were not tested (on 9.9.0 and 9.10.0 the history test does not compile).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the compact test fails 4 of 5 through gradle, assertions on and off; the control passes |
main ea57360912ed | affected | the finder's test 2 of 3, the reproducer's 3 of 7, the adjudication's re-run 3 of 7 fail; controls pass |
| 10.4.0, 10.5.0, 10.5.1, 10.5.2 | affected | both Lucene104 OSQ formats fail; the control passes |
| 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2 | affected | both Lucene102 BBQ formats fail; int8 and the control pass |
| 9.12.0, 9.12.3, 10.0.0, 10.1.0 | not affected | only the guarded int8 and the non-quantized writers exist |
| 9.11.1 | older bug | both formats the test could run there (int8 HNSW and the non-quantized control) fail, through the older generic-merge defect #13626; not this bug |
| release writers + the guard (shadow builds) | cause | 10.2.0, 10.3.2, 10.4.0, 10.5.2 and main pass; the 9.12.3 int8 writer without its guards fails |
fix A / fix B (scratch worktree at a9779ef3c193) | not affected | A and B each: 15 of 15 repro tests and 257 suite tests pass, assertions on and off; A in one loop only: 1 test still fails |
An independent reproducer, a devil's-advocate verifier and reviews by a model from another family wrote their own tests and called it real; the adjudication confirmed it with high confidence and no dissent. This doc's gradle runs reproduced it on main a9779ef3c193 and validated two fixes.
Checks and verdicts366 words
Each executing check wrote or re-ran its own JUnit on stock code; every control passed, and every check's tests pass with the fix.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real, wider scope | Own 7-test JUnit with a production codec: 3 fail on main with assertions on and off, 4 controls pass, deterministic over 5 iterations; added the fp16 case and the release matrix (10.2.0, 10.3.2, 10.5.2 fail; int8 passes); the writer stays open with assertions off. |
| devil's advocate | real; intended argument weak | Built the strongest "intended" case and showed why it fails; a test-framework-free repro fails whether the lacking segment's other vector field is byte, float or non-quantized float; noted that the fix site is debatable. |
| cross-model reviews (refute, intended) | real, high (both) | An independent reviewer from another model family (OpenAI GPT-5.6) ran its own tests: they fail on main with assertions on and off, controls pass, and the fix passes them plus 125 existing Lucene104 format tests. Both rated the intended-behaviour argument weak and pointed to #13641. |
| adjudication | confirmed, high | Re-ran the independent reproduction's tests with a new seed: 7 run, 3 failed with assertions on and off; controls pass. |
| this doc's gradle runs | fails on stock, passes with each fix | On stock main a9779ef3c193 the compact test fails 4 of 5 (with the finder's and the reproducer's tests: 15 run, 9 failed), assertions on and off. With fix A or fix B all 15 pass, and 257 tests of the 9 closest suites pass; fix A in one loop only leaves 1 failure. |
| fact checks of this doc (independent; cross-model) | real; findings fixed | Both re-checked the brief and this doc against the code and the evidence. The independent check re-ran the gradle repro with assertions on and off, a second seed over 5 iterations, the test from another package, both fixes and the 0-of-6 count; its one error (a PR's draft status) and its minor findings are fixed. The cross-model check (OpenAI GPT-5.6) found the bug real and strongly evidenced, rated the intended-behaviour argument moderate, and its corrections (workaround, trigger, title, field types and others) are applied; see an unpublished file. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 516 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,482 words
- Registry title
- Quantized vector merge asks every source reader for a field's vectors without checking that reader's FieldInfos, so re-sorting with SortingCodecReader and addIndexes fails with NullPointerException (AssertionError with -ea) when one segment lacks one of several vector fields
- Area
- codecs / quantized vector formats merge (Lucene104 OSQ, Lucene102 BBQ) with index / SortingCodecReader
- Priority
- Medium, rank 255: Bottom of Medium: the documented SortingCodecReader plus addIndexes re-sort recipe fails with NPE on quantized vector formats when one segment lacks one of several vector fields, but it is loud, nothing is corrupted and per-leaf addIndexes avoids it.
- Impact class
- crash
- Impact note
- Hits only applications that re-sort an index with the documented SortingCodecReader recipe (IndexWriter.addIndexes with two or more SortingCodecReader-wrapped leaves) when a field that uses a non-default quantized vector format (Lucene104 scalar or HNSW-scalar OSQ on 10.4+ and main, Lucene102 BBQ on 10.2-10.3) is missing from a source segment that has some other vector field and the sort reorders that segment; addIndexes then throws and adds nothing (with -da the writer stays open, with -ea the AssertionError closes it as a tragic event), ordinary flushes and merges are unaffected, any scale, released since 10.2.0, and one addIndexes call per leaf avoids it.
- Summary
- You re-sort an index the way the SortingCodecReader javadoc describes: wrap every segment with SortingCodecReader.wrap(reader, sort) and pass them all to IndexWriter.addIndexes on a fresh index-sorted writer, with a codec that uses a quantized vector format (for example Lucene104HnswScalarQuantizedVectorsFormat), where one segment has vectors for field b but none for field a. You expect the re-sort to succeed, as it does with the default non-quantized HNSW format and as an ordinary merge of the same segments does. Instead the quantized writer's centroid code asks every source reader for field a without checking that reader's FieldInfos, SortingCodecReader wraps the missing (null) values, and addIndexes fails with a NullPointerException at SortingCodecReader.java:252 (an AssertionError at :318 with -ea), so nothing is added.
- Introduced
- 8856a5f4eb7 (#14078 'Binary vector format for flat and hnsw vectors', main; branch_10x backport 39e7f0973ec, first released in 10.2.0), which added Lucene102BinaryQuantizedVectorsWriter.mergeAndRecalculateCentroids and calculateCentroid with null-only checks [read: git log and git blame; exec: release matrix 10.1.0 pass / 10.2.0 fail, and adding only the FieldInfos guard to the release's own writer turns 10.2.0, 10.3.2, 10.4.0 and 10.5.2 into passes; no build at a parent commit, because the BBQ and OSQ writers did not exist before their introducing commits]; carried byte for byte into the current Lucene104ScalarQuantizedVectorsWriter by 594eeb7e637 (#15169, backport 07033dcd84c, first released in 10.4.0) and extended to FLOAT16 fields on main by 50c1e6acb7f (#16473) [read]; a reintroduction of the defect class that #13641 (74e3c44063a main / ab262f917d4 branch_9x, 9.12.0 and 10.0.0) fixed in the generic merge and the Lucene99 writers [exec: removing only the two #13641 guards from the 9.12.3 int8 writer makes both int8 formats fail the same way] (2025-03-04 (#14078 merged); current Lucene104 code from 2025-09-17 (#15169 merged); fp16 variant from 2026-08-26 (#16473, main only))
- First affected version
- 10.2.0 [exec] (Lucene102 BBQ formats); 10.4.0 for the Lucene104 OSQ formats [exec]
- Affected versions
- 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1 and 10.3.2 (Lucene102HnswBinaryQuantizedVectorsFormat, Lucene102BinaryQuantizedVectorsFormat) and 10.4.0, 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed (Lucene104HnswScalarQuantizedVectorsFormat, Lucene104ScalarQuantizedVectorsFormat) [exec: follow-up history test with -ea on every listed release, with -da also on 10.2.0, 10.3.2, 10.4.0, 10.5.2 and main; the independent reproduction independently on 10.2.0, 10.3.2, 10.5.2 and main; the finder on 10.2.0, 10.3.2, 10.5.2 and main]; the FLOAT16 (fp16) variant on main only [exec on main; its start at #16473 is read]; branch_10_6 (10.6.0, released 2026-10-29) and the unreleased branch_10x [read: same null-only loops, not executed]; not affected: 9.12.0, 9.12.3, 10.0.0 and 10.1.0, where only the guarded int8 and the non-quantized writers exist [exec pass]; 9.11.1 and earlier fail for every vector format, including the non-quantized control, through the older generic merge defect GITHUB#13626 that #13641 fixed, which is not this bug [exec on 9.11.1]; not fixed upstream as of main ea57360912ed and branch_10_6 2763db11b0a [read, 2026-10-26]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, all read-only: a scripted prior-report search with 74 GitHub issue/PR, 9 commit, 11 downstream-repo, 44 mailing-list (dev@, java-user@, issues@, commits@) and 12 JIRA-archive queries; 16 manual gh issue/PR searches, 4 GitHub code searches and 6 web queries; a title sweep of the 490 apache/lucene issues and PRs updated since 2026-09-01; the file lists of 95 vector-, codec- and merge-related open PRs, with the diffs of the 13 that touch the affected classes read; the review comments of #14078, #15169, #16473 and #16764); related prior items, none of them this bug: #13626 and #13641 (the same bug class in the generic merge and the Lucene99 writers, fixed in 9.12.0 and 10.0.0 before this code existed; #13641 states the FieldInfos rule; the precedent), #14123, #14125 and #14128 (SortingCodecReader with a null vectors reader, fixed; added the assertion this bug trips under -ea), #16762, #16764 and #16800 (deleted docs in the same centroid methods, fixed), open draft PRs #16839 and #16819 (rewrite the centroid merge but keep the unguarded per-reader lookup), open PRs #16879 and #16871 (touch SortingCodecReader or the writer, not this lookup), #14078, #15169 and #16473 (introduced the code); downstream, the Elasticsearch BBQ copy (ES818BinaryQuantizedVectorsWriter.mergeAndRecalculateCentroids) has the same null-only skip, with no report found [read, not executed]
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): a compact JUnit on the public Lucene API (5 tests) with the finder's and the independent reproducer's tests through gradle in a scratch worktree, assertions on and off, stock and with two alternative fixes, plus the closest upstream suites with each fix (2026-10-28); the registry's re-run ona9779ef3c193(2026-10-26); an independent fact check and a cross-model fact check of this doc, with their own runs (2026-10-28). Earlier, on mainea57360912ed: the finder, an independent reproducer, a devil's-advocate verifier, reviews by a model from another family that ran their own tests, the adjudication, and the follow-up's history test on release jars 9.11.1 to 10.5.2 with single-file guard swaps. OpenJDK 25.0.3, Linux aarch64. The three affected files are unchanged on upstream main20ced71c1e6(2026-10-27).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104ScalarQuantizedVectorsWriter.java:576-590 (floatingPointVectorValues; javadoc 'null when the field is absent from this reader'), :592-605 (first centroid loop: skips only a null reader or a null answer), :636-646 (calculateCentroid: skips only a null reader), :659-664 (accumulateCentroid: skips only a null answer)lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:47-55 (class javadoc: the re-sort recipe; @lucene.experimental), :252 (iteratorSupplier dereferences the values), :316-320 (SortingFloatVectorValues: assert delegate != null), :455-460 (an already sorted reader is not remapped), :629-641 (the vectors reader wraps the delegate's answer for float32, byte and float16)lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsReader.java:64-69 (getFloatVectorValues: 'The behavior is undefined if the given field doesn't have KNN vectors enabled on its FieldInfo. The return value is never null')lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsWriter.java:331-337 (MergedVectorValues.hasVectorValues(FieldInfos, String)), :350 (the generic merge checks it before asking a reader); lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java:518-522 (the same guard)lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldKnnVectorsFormat.java:278-286 (the per-field reader returns null for an absent field, which is why ordinary merges pass)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java:123 (the default vectors format is the non-quantized Lucene99HnswVectorsFormat)lucene/backward-codecs/src/test/org/apache/lucene/backward_codecs/lucene102/Lucene102BinaryQuantizedVectorsWriter.java:384-385, :425 (the same null-only checks in the test-only Lucene102 writer on main)SECURITY.md:28, 42, 50 (threat model)
- The finding in 30 seconds
a Lucene main checkout lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104ScalarQuantizedVectorsWriter.java:351-360, 569-575, 577-591, 593-635, 637-658, 660-680a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:47-55, 252, 316-320, 398-406, 445-460, 590-615, 618-641a Lucene main checkout lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsReader.java:64-69, 82-87, 89-94a Lucene main checkout lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldKnnVectorsFormat.java:280-287, 311-318a Lucene main checkout lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsWriter.java:331-337, 350; codecs/lucene99/Lucene99HnswVectorsWriter.java:520a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3264-3267, 3561-3564, 3589, 5557-5576; lucene/misc/src/java/org/apache/lucene/misc/index/BpVectorReorderer.java:684-695
- Who is affected
a Lucene main checkout lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java:123 (default vectors format); Lucene104ScalarQuantizedVectorsFormat.java:97, Lucene104HnswScalarQuantizedVectorsFormat.java:47, index/SortingCodecReader.java:54 (@lucene.experimental)a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1344-1346 (close javadoc: commitOnClose)
- Why it looks unintended
a Lucene main checkout lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsReader.java:64-69, 82-87, 89-94a Lucene main checkout lucene/CHANGES.txt:2693-2694 (9.12.0, GITHUB#13641), 1861-1863 (10.2.0, GITHUB#14078), 1345-1347 (10.4.0, GITHUB#15169), 174 (11.0.0, GITHUB#16473)a Lucene main checkout lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsWriter.java:331-337, 350; codecs/lucene99/Lucene99HnswVectorsWriter.java:520; index/SortingCodecReader.java:47-51a Lucene main checkout lucene/core/src/test/org/apache/lucene/index/TestSortingCodecReader.java:179; lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseKnnVectorsFormatTestCase.java:285
- Suggested fix
a Lucene main checkout lucene/backward-codecs/src/test/org/apache/lucene/backward_codecs/lucene102/Lucene102BinaryQuantizedVectorsWriter.java:384-385, 425a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:590-615 (points pass null through)a Lucene main checkout lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene102/Lucene102BinaryQuantizedVectorsFormat.java:122-123 (fieldsWriter throws "Old codecs may only be used for reading")gh pr view 16839 / 16819 --repo apache/lucene, 2026-10-28 (read-only): #16839 OPEN, isDraft false, head 5e7d497a28d; #16819 OPEN, isDraft true
- History
a Lucene clone (read-only): git diff a9779ef3c193 origin/main (20ced71c1e6) of the three affected files: empty
- TestResortQuantizedMissingVectorField.java (JUnit test):
repro/LFV-100/src/org/apache/lucene/index/TestResortQuantizedMissingVectorField.java(72 lines)
A step-by-step picture of the repro's example, made in parallel with this doc.
assets/LFV-100/bug.png(516 KB)