TopSuggestDocs.merge combines the suggestion lists of several shards into one top list. It reserves room for topN results before it counts what the shards hold, so a "no limit" topN fails even when there is nothing to merge.
- The document suggester (
SuggestIndexSearcherover aSuggestField) returns completions as aTopSuggestDocs: aTopDocswhose hits also carry the completion text. - An application with several indexes (shards) asks each for its top
nsuggestions and combines the lists with the static helperTopSuggestDocs.merge(topN, shards), the suggest counterpart ofTopDocs.mergefor ordinary hits. TopDocs.mergereturns at most the hits it received, sotopN=Integer.MAX_VALUEthere simply means "all of them".
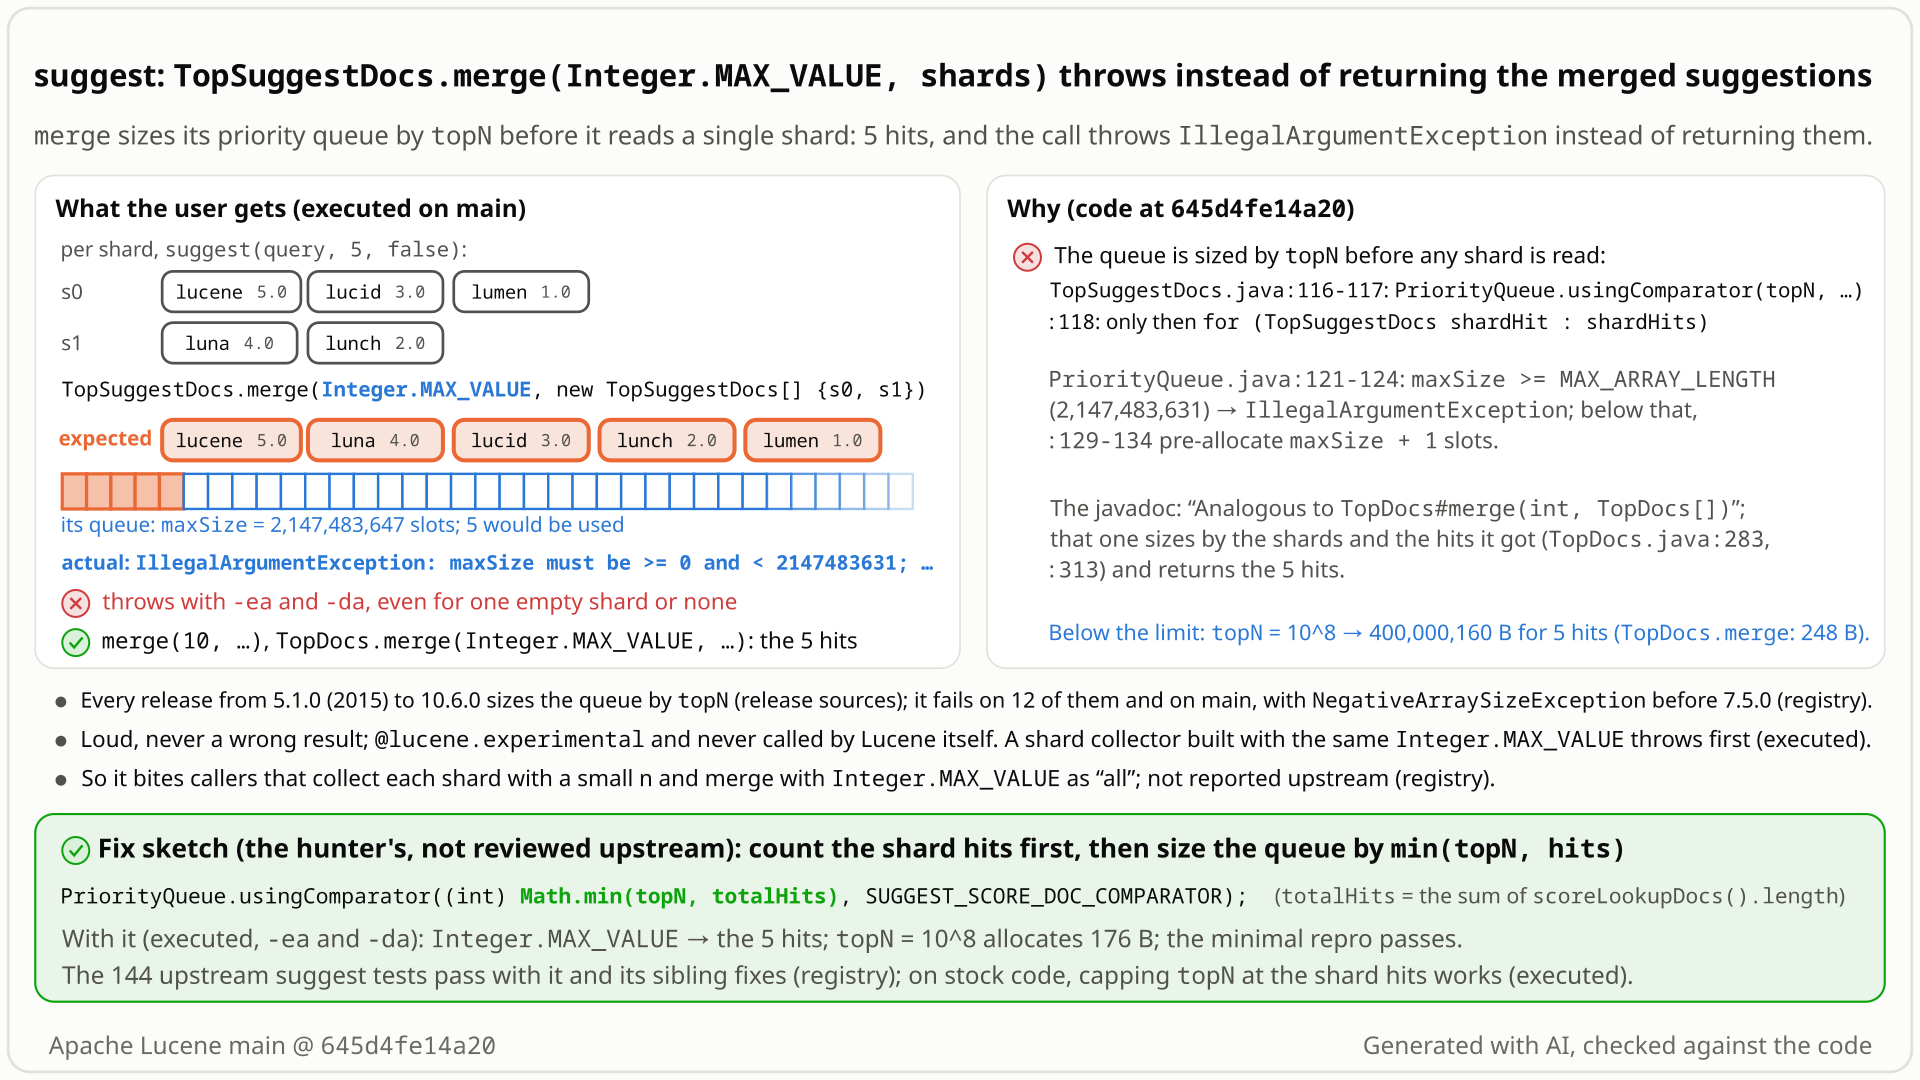
merge(Integer.MAX_VALUE, shards): the queue is sized by topN before any shard is read and refuses the size; TopDocs.merge sizes by the hits it received; the fix sizes by min(topN, hits). Select the still to open it at full size. Generated with AI, checked against the code.- Two shards each answer a prefix query
luwithsuggest(query, 5, false):lucene(5),lucid(3),lumen(1) andluna(4),lunch(2). You combine them withTopSuggestDocs.merge(Integer.MAX_VALUE, shards)to keep every suggestion. - You expect the 5 suggestions, best first.
merge(10, shards)returns them, the javadoc puts no limit ontopNand calls the method "Analogous to TopDocs#merge", andTopDocs.merge(Integer.MAX_VALUE, shards)returns all 5. - You get
IllegalArgumentException: maxSize must be >= 0 and < 2147483631; got: 2147483647, also for one empty shard or no shards at all (5.1.0 to 7.4.0:NegativeArraySizeException). - Why: before it reads any shard,
mergecreates a priority queue oftopNslots. The queue allocatesmaxSize + 1slots up front and refuses 2,147,483,631 or more (the limit on the tested JVM).TopDocs.mergesizes by the hits it received instead. - Below that limit the call can succeed, but memory follows
topN, not the hits: merging the 5 hits withtopN= 100,000,000 allocates 400,000,160 bytes;TopDocs.mergeallocates 248.
Code that merges per-shard document-suggester results itself with TopSuggestDocs.merge (an experimental helper Lucene never calls) and passes a topN above the per-shard n, typically Integer.MAX_VALUE for "all". If the shards were collected with that same huge n, the collector throws first. The failure is loud, and this bug never returns wrong results.
Mechanism, terms and numbers577 words
TopSuggestDocs.merge(int topN, TopSuggestDocs[] shardHits) combines per-shard document-suggester results into one top list; its javadoc calls it "Analogous to TopDocs#merge(int, TopDocs[])" and sets no bound on topN. It creates its PriorityQueue with topN slots before it looks at any shard, and PriorityQueue pre-allocates maxSize + 1 slots and refuses maxSize >= 2147483631 (on the tested JVM). So merge(Integer.MAX_VALUE, shards) ("keep them all") throws IllegalArgumentException: maxSize must be >= 0 and < 2147483631; got: 2147483647 for two one-hit shards and even for a single empty shard (5.1.0 to 7.4.0: NegativeArraySizeException), while TopDocs.merge(Integer.MAX_VALUE, ...) returns the hits, because it sizes its queue by the number of shards and its result by the hits it received. Below the limit a large topN can succeed but allocates topN + 1 slots whatever the hit count (about 400 MB at topN = 10^8). The method has been like this since it was added in 5.1.0 (2015); Lucene itself never calls it; this bug never returns wrong results (merge either throws or over-allocates) and the failure is loud. If the shards were collected with the same huge n, the per-shard collector throws first, so only a merge topN above the per-shard n, or hand-built shard results, reach it.
- Contract.
TopSuggestDocs.java:107-113: "Returns a new TopSuggestDocs, containing topN results across the provided TopSuggestDocs, sorting by score. Each TopSuggestDocs instance must be sorted. Analogous to TopDocs#merge(int, TopDocs[]) for TopSuggestDocs". No bound ontopN, no validation. The class is@lucene.experimental(:30). - The pre-size.
PriorityQueue.usingComparator(topN, SUGGEST_SCORE_DOC_COMPARATOR)(TopSuggestDocs.java:116-117), before the loop that inserts each shard's hits (:118-124). - The queue.
PriorityQueue"pre-allocates an array of length maxSize+1" (PriorityQueue.java:34-35,@lucene.internalat:39) and, "to prevent confusing OOME", throwsIllegalArgumentExceptionformaxSize >= ArrayUtil.MAX_ARRAY_LENGTH(:121-124), which isInteger.MAX_VALUEminus the JVM's array header size (ArrayUtil.java:33-34): 2147483631 with compressed object pointers, as on the tested JVM, 2147483623 without; otherwise it allocatesnew Object[maxSize + 1](:129,:134). - The analogue.
TopDocs.merge(int topN, TopDocs[])(TopDocs.java:203) sizes its queue by the number of shards (:283,:286), counts the hits it received (:303) and sizes its resultMath.min(size, availHitCount - start)(:313): Michael McCandless's rule from commit4e92af15376(2011), "when merging TopDocs, the most hits we can produce is the sum of how many hits we actually received". - The per-shard side.
SuggestIndexSearcher.suggest(query, n, ...)buildsnew TopSuggestDocsCollector(n, ...)(SuggestIndexSearcher.java:52), which also createsPriorityQueue.usingComparator(num, ...)(TopSuggestDocsCollector.java:81). A shard collected withn = Integer.MAX_VALUEtherefore fails beforemergeruns. - No caller. Nothing in Lucene calls
merge, tests included.
| call | result |
|---|---|
merge(10, shards), 5 real hits (3 + 2) | 5 hits |
merge(Integer.MAX_VALUE, shards) | IllegalArgumentException (5.1.0-7.4.0: NegativeArraySizeException) |
merge(Integer.MAX_VALUE, {EMPTY}) and merge(Integer.MAX_VALUE, {}) | the same exception |
merge(2147483630, shards) | OutOfMemoryError: Java heap space at -Xmx2g |
merge(100_000_000, shards) | 5 hits, 400,000,160 bytes allocated |
TopDocs.merge(Integer.MAX_VALUE, shards) (control) | 5 hits; 248 bytes at topN = 10^8 |
new TopSuggestDocsCollector(Integer.MAX_VALUE, false) | the same IllegalArgumentException |
Bytes are allocated by the calling thread for one merge after a warm-up (not retained heap), with 4-byte object references (compressed object pointers); with 8-byte references the topN + 1 slots take about twice as much. With -Xmx256m, merge(100_000_000, 3 hits) ends in OutOfMemoryError at TopSuggestDocs.java:117; the out-of-memory part depends on the heap, the topN + 1 slots do not.
Exposure and likelihood264 words
- Who is hit. Applications that keep document suggestions in several indexes and combine the per-shard
TopSuggestDocsthemselves, passing a mergetopNlarger than thentheir shards were collected with (an independent check: real shards collected withn = 5, merged withInteger.MAX_VALUE, throw), or that merge hand-builtTopSuggestDocs. "All" means every hit in the shards passed in: shards collected withsuggest(query, 5, false)hold at most 5 each. - Reach caveat. In the plain reduce pattern (per-shard
TopSuggestDocsCollector(n), thenmerge(n, ...)with the samen),Integer.MAX_VALUEalready fails in the collector, somergeis never reached. The one public caller found, nrtsearch'sMyTopSuggestDocsCollectorManager.reduce, uses that symmetric pattern. - Default vs opt-in. Calling
mergeneeds no setting, but the API is@lucene.experimental, and realTopSuggestDocscome from aSuggestField, whose index needs a completion postings format in the codec. - What goes wrong. On the tested JVM every
mergewithtopN >= 2147483631throws, even with no hits, andmerge(Integer.MAX_VALUE, ...)threw on every release tested since 5.1.0. The message namesmaxSize, a parameter of an internal class rather thanmerge'stopN, and the internal array limit 2147483631; only itsgot:value is the caller's. A legal largetopNcoststopN + 1reference slots per call, whatever the hit count. - Scale. None: two one-hit shards, or one empty shard, are enough.
- Workaround. Cap
topNat the total number of shard hits before callingmerge; this works on stock code. - How likely. Rare: loud and immediate, no caller in Lucene, no earlier public report found.
One JUnit test, public API: merge two hand-built one-hit shards with topN = Integer.MAX_VALUE. No index, one thread, fixed input; it fails with every seed tried, with assertions on and off. With the fix it passes unchanged, so it doubles as the regression test.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.document;

import org.apache.lucene.search.TotalHits;
import org.apache.lucene.search.suggest.document.TopSuggestDocs.SuggestScoreDoc;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTopSuggestDocsMergeAllHits extends LuceneTestCase {

  private static TopSuggestDocs shard(String key, float score) {
    return new TopSuggestDocs(
        new TotalHits(1, TotalHits.Relation.EQUAL_TO),
        new SuggestScoreDoc[] {new SuggestScoreDoc(0, key, null, score)});
  }

  public void testMergeWithTopNMaxValue() {
    TopSuggestDocs[] shards = {shard("a", 1f), shard("b", 2f)};
    try {
      assertEquals(2, TopSuggestDocs.merge(Integer.MAX_VALUE, shards).scoreLookupDocs().length);
    } catch (IllegalArgumentException e) {
      // expected: both hits, as with topN = 10 and as TopDocs.merge returns; actual: the queue is pre-sized by topN
      throw new AssertionError("expected the 2 merged suggestions for topN = Integer.MAX_VALUE, but got " + e, e);
    }
  }
}
cp $REPRO/TestTopSuggestDocsMergeAllHits.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/suggest/document/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.suggest.document.TestTopSuggestDocsMergeAllHits -Ptests.seed=DEADBEEF
- Expected
mergereturns the 2 suggestions,bthena.- Observed
IllegalArgumentException: maxSize must be >= 0 and < 2147483631; got: 2147483647fromTopSuggestDocs.merge.
More files, environment, full output245 words
Copy the test into lucene/suggest/src/test/org/apache/lucene/search/suggest/document/ of a Lucene checkout and run the command below. It sits in that package only because the module's tests live there; it uses public constructors only. The catch only turns the exception into an assertion failure that states expected vs actual, with the original as the cause.
Seeds DEADBEEF, 5EED1234 and 1002FACE each fail on main with -ea and with -da, and C0FFEE42 with -da. Two lines are longer than 100 characters: before committing the test in a PR, run ./gradlew tidy, which rewraps the comment and the throw line and changes nothing else.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; also fails on the 10.5.2 and 10.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the only platform it ran on) |
cp $REPRO/TestTopSuggestDocsMergeAllHits.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/suggest/document/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.suggest.document.TestTopSuggestDocsMergeAllHits -Ptests.seed=DEADBEEF
# gradle, fresh worktree at main 645d4fe14a20, -Ptests.seed=DEADBEEF (module prefixes trimmed)
TestTopSuggestDocsMergeAllHits > testMergeWithTopNMaxValue FAILED
    java.lang.AssertionError: expected the 2 merged suggestions for topN = Integer.MAX_VALUE, but got java.lang.IllegalArgumentException: maxSize must be >= 0 and < 2147483631; got: 2147483647
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:E1AAF9DB920CFC30]:0)
        at org.apache.lucene.search.suggest.document.TestTopSuggestDocsMergeAllHits.testMergeWithTopNMaxValue(TestTopSuggestDocsMergeAllHits.java:37)

        Caused by:
        java.lang.IllegalArgumentException: maxSize must be >= 0 and < 2147483631; got: 2147483647
            at org.apache.lucene.util.PriorityQueue.<init>(PriorityQueue.java:123)
            at org.apache.lucene.util.PriorityQueue.<init>(PriorityQueue.java:80)
            at org.apache.lucene.util.PriorityQueue.usingComparator(PriorityQueue.java:63)
            at org.apache.lucene.search.suggest.document.TopSuggestDocs.merge(TopSuggestDocs.java:117)
            at org.apache.lucene.search.suggest.document.TestTopSuggestDocsMergeAllHits.testMergeWithTopNMaxValue(TestTopSuggestDocsMergeAllHits.java:34)

# standalone runner (tests_run=1 failures=1 each)
main 645d4fe14a20  -ea and -da, seeds DEADBEEF, 5EED1234, 1002FACE   the same exception at TopSuggestDocs.java:117
10.6.0, 10.5.2 -da, seed DEADBEEF the same exception, via SuggestScoreDocPriorityQueue.<init> at TopSuggestDocs.java:105- The javadoc sets no bound on
topNand callsmerge"Analogous to TopDocs#merge", which returns every hit for the same call. TopDocs.mergesizes by what it received on purpose (Michael McCandless, 2011): "the most hits we can produce is the sum of how many hits we actually received".mergealready holds every input, yet fails with nothing to merge.
The full argument200 words
- Contract.
TopSuggestDocs.java:107-113promises "topN results across the provided TopSuggestDocs" and states only a sortedness precondition. The pre-allocation note sits on the@lucene.internalqueue (PriorityQueue.java:34-35,:39); core documents pre-allocation where it applies, on its collector managers (TopScoreDocCollectorManager.java:45,:83), andmergehas no such note. - Lucene's precedents put the cap in the code that sizes the queue. LUCENE-504 (#1581): Nadav Har'El, "It is the caller's duty to create a priority queue with a sensible size", with Mark Miller agreeing; Uwe Schindler fixed
FuzzyQuery, the caller. LUCENE-2119:IndexSearchercapsnatmaxDoc(IndexSearcher.java:721,:729). SOLR-5661: Michael McCandless, "somewhere it should limit the size it passes to the PQ constructor?". - The guard is not a public bound. It exists "to prevent confusing OOME" (
PriorityQueue.java:122); it came with SOLR-5661 (2014) and was made to work forInteger.MAX_VALUEin4c646dab3fb(2018, Mike McCandless, "thanks rsaavedraf", who diagnosed the overflow in lucene-solr PR #411). - History. No issue, test, commit message or review comment says the pre-size is intended. In the LUCENE-6339 review (#7400) Michael McCandless proposed a
TopSuggestDocs.mergemethod; none of the 35 comments discusses its queue size. #14817 (2025) only swapped the queue class.
The devil's-advocate check270 words
The strongest case for "works as designed" (first raised by reviewers from another model family, OpenAI GPT-5.6, then developed by an intended-behaviour devil's advocate): "Analogous" may describe only the purpose, since merge also differs from TopDocs.merge in totalHits, tie-breaking and the missing start; the document suggester pre-sizes by n everywhere, and TopSuggestDocsCollector rejects Integer.MAX_VALUE the same way; Lucene's answer to Integer.MAX_VALUE queues reached through Solr's shard merge was exactly this clean exception (SOLR-5661), which Shalin Shekhar Mangar judged enough there; Cassandra Targett closed SOLR-5674, whose item 3 is this fix idea for Solr's code, as "a set of improvement requests"; and Adrien Grand's LUCENE-8542 comment that Lucene targets top-k "for some reasonable value of k" predicts the same answer. The queue's own refusal is also tested on purpose (TestPriorityQueue.testMaxIntSize, TestPriorityQueue.java:378-382), though that test says nothing about how merge sizes its queue. The cross-model fact check (OpenAI GPT-5.6, reading only) went further and judged the bug noise: an absurd capacity request that fails loudly, on an experimental API with no caller in Lucene and a trivial caller-side workaround.
Why it fails: those decisions concern Solr's code or core collectors, not this method; the guard (and its test) protects an internal class, and Lucene's own precedents fix the code that sizes the queue, here merge; the analogue it names already follows the "at most what you received" rule; and a collector must size before it sees matches, while merge already holds them all. The argument bears on reach and on the likely reply ("improvement, not a bug", "document the limit" or "remove merge"), hence priority Low.
Recommended Count the hits first and size the queue by min(topN, hits)
Count the shard hits first and size the queue by min(topN, hits), the rule TopDocs.merge follows (Raintung Li proposed the same for Solr's merge in SOLR-5674). Results do not change; with it the test and the suggest module's 237 tests pass, and a merge of 3 hits at topN = 100,000,000 allocates 1,216 bytes instead of 400,001,208.
public static TopSuggestDocs merge(int topN, TopSuggestDocs[] shardHits) {
  long availHitCount = 0;
  for (TopSuggestDocs shardHit : shardHits) {
    availHitCount += shardHit.scoreLookupDocs().length;
  }
  // The result holds at most the hits received, as in TopDocs#merge, so do not size the queue
  // by topN alone: it may be far larger, e.g. Integer.MAX_VALUE for "all hits"
  int queueSize = (int) Math.min(topN, availHitCount);
  PriorityQueue<SuggestScoreDoc> priorityQueue =
      PriorityQueue.usingComparator(queueSize, SUGGEST_SCORE_DOC_COMPARATOR);
All options and trade-offs3 options · 653 words
Three options; A was validated with gradle in a fresh scratch worktree at 645d4fe14a20, B and C were not executed. Credit where the fix is presented: the sizing rule is Michael McCandless's (TopDocs.merge, 4e92af15376, 2011); Raintung Li first proposed it for Solr's merge (SOLR-5674 item 3, 2014: "Create the PriorityQueue after check all shard return sizes"); Nik Everett diagnosed and fixed the same failure, with the same message, in an Elasticsearch reduce step (elastic/elasticsearch#76492, reported by deathcave; fix #76578). Not part of this report: TopSuggestDocsCollector also pre-sizes by num (TopSuggestDocsCollector.java:81), but a collector must size before it sees matches, so it needs a different fix.
In TopSuggestDocs.merge (:116-117) sum scoreLookupDocs().length over the shards in a long and pass (int) Math.min(topN, availHitCount) to PriorityQueue.usingComparator. +8/-1 lines in one file; two of the added lines are a comment.
public static TopSuggestDocs merge(int topN, TopSuggestDocs[] shardHits) {
  long availHitCount = 0;
  for (TopSuggestDocs shardHit : shardHits) {
    availHitCount += shardHit.scoreLookupDocs().length;
  }
  // The result holds at most the hits received, as in TopDocs#merge, so do not size the queue
  // by topN alone: it may be far larger, e.g. Integer.MAX_VALUE for "all hits"
  int queueSize = (int) Math.min(topN, availHitCount);
  PriorityQueue<SuggestScoreDoc> priorityQueue =
      PriorityQueue.usingComparator(queueSize, SUGGEST_SCORE_DOC_COMPARATOR);
Trade-offs
- No change in results. When
topNis at most the hit count the queue size istopN, as before; when it is larger, a queue of exactly the hit count never rejects a hit, and neither did the larger queue. - For non-null input,
topN = 0and negativetopNbehave as before:0returnsEMPTY, a negative value still throws fromPriorityQueue. No hits gives a size-0 queue, whichPriorityQueueaccepts (PriorityQueue.java:117-119). - Null input still throws, but the exception can change: the counting loop reads every shard before the queue exists, so
merge(-1, shards with a null entry), for example, throwsNullPointerExceptionwhere it threwIllegalArgumentExceptionbefore. - Cost: one extra pass over the shard array, reading each array's length. The
longsum cannot overflow.
What the checks validated
- Fresh scratch worktree at
645d4fe14a20, JDK 25.0.3, gradle with-Ptests.seed=DEADBEEF(2026-10-30): without the fix the minimal test fails; withfix.diffapplied,:lucene:suggest:testpasses: 32 suites, 237 tests, 7 skipped, 0 failures, including the minimal test and thedocumentpackage'sTestSuggestField(20),TestContextQuery(15),TestPrefixCompletionQuery(9),TestContextSuggestField(6),TestRegexCompletionQuery(5) andTestFuzzyCompletionQuery(3). :lucene:suggest:checkGoogleJavaFormatpasses for the fix (it flagged only the copied test's two long lines; aftertidyrewrapped them, the fix byte-identical, the check and the test pass).- The standalone runner passes the test with the fixed class shadowed,
-eaand-da; an allocation test (3 hits,topN= 100,000,000,-da) drops from 400,001,208 to 1,216 bytes. - The finder's earlier version of the same idea passed its 3-test JUnit (including the empty-shard case) and the minimal test with
-eaand-da. - An edge-case probe gives the same results with and without the fix for every legal
topN(including 4 hits with a three-way score tie, attopN1 to 100),EMPTYfortopN0 and for an empty merge, andIllegalArgumentExceptionfortopN-1. These cases stay out of the regression test, which is the one minimal test.
Collect the hits and sort them, or use a growable heap. Not executed.
Trade-offs
Same results, more code, and no gain over A: merge already knows how many hits it holds.
Add a javadoc note or a clear IllegalArgumentException for large topN. Not executed.
Trade-offs
Keeps the topN + 1 allocation for large legal values and makes the "keep them all" call a documented error, although TopDocs.merge handles it (its result holds at most the hits it received, TopDocs.java:313). Not recommended.
Elasticsearch's and OpenSearch's completion suggesters do not call merge; the one public caller found (nrtsearch) merges with the same n its collectors use, where the collector already fails first.
A probe built from two earlier grouping findings of the same pattern called top-N APIs outside grouping with Integer.MAX_VALUE and compared each with its documented analogue: TopSuggestDocs.merge threw where TopDocs.merge returned the hits. A finder turned it into a JUnit with that control and found the queue line by reading the code.
The method in full136 words
Method: executed differential testing (no formal model), in a hunt round on numeric limits of public API arguments, on the stock main jars.
- First signal. A planning probe generalised two earlier findings in the grouping module (a shard-merge helper and a grouping search, both pre-sized by an unbounded limit) to top-N APIs outside grouping. On main
a9779ef3c193, 10.5.2 and the 10.6 release candidate (2026-10-28) it printedFAIL TopSuggestDocs.merge(MAX, {empty shard})with the controlTopDocs.merge(MAX, {empty shard}) -> 0. - Hunt. A finder re-ran it as a differential check against
TopDocs.merge, wrote a 3-test JUnit with that control (2 of 3 fail), located the pre-size by reading the code and wrote the fix sketch. - Checks. Independent reproducers, an intended-behaviour devil's advocate and an adjudication confirmed it; the single test shown here is the audited reduction.
No earlier report found (searched 2026-10-29, re-checked 2026-10-30). Related only: the same pattern handled elsewhere, in Solr's shard merge (SOLR-5661, SOLR-5674), IndexSearcher (LUCENE-2119) and an Elasticsearch reduce step.
Searches4 searches
Related, not this bug: SOLR-5661 and SOLR-5674 (Solr's shard merge with rows = Integer.MAX_VALUE), #1581 (LUCENE-504, a FuzzyQuery queue sized by Integer.MAX_VALUE, fixed in the caller), LUCENE-2119 (the IndexSearcher cap), #9588 (LUCENE-8542, open: core per-slice collectors pre-sized by numHits), elastic/elasticsearch#76492 (the identical message in an Elasticsearch reduce step, fixed there), #7400 (LUCENE-6339, which added merge; no comment on its queue size). The only open PR touching the file, draft #16847, changes doc-id types only. No maintainer has commented on this bug.
| Where | When | How | Found |
|---|---|---|---|
| Search tool (GitHub issues/PRs/commits incl. the JIRA archive; dev@, java-user@, issues@, commits@; Elasticsearch, OpenSearch, Solr) | 2026-10-29 | two runs, each 16 GitHub issue/PR, 3 commit, 2 downstream, 20 list and 4 JIRA queries: class, method and symptom terms, then the queue pre-sizing pattern | no report of this bug |
| GitHub (apache/lucene, Elasticsearch, OpenSearch, Solr, nrtsearch, all of GitHub), JIRA, lists, web | 2026-10-29 | own searches for the exact message and for TopSuggestDocs.merge; a code search for callers; JIRA and list reads; 143 recorded queries in all | related items only (above); one public caller, nrtsearch |
| Open PRs | 2026-10-29 | changed files of all 414 open apache/lucene PRs, then of the 48 PRs among the 61 issues and PRs updated in the 48 h before the recheck | only #16847 touches TopSuggestDocs.java, for doc-id types |
| GitHub, re-check | 2026-10-30 | TopSuggestDocs issues/PRs, "suggest merge topN", "maxSize must be >= 0", every issue and PR updated since 2026-10-29, the newest commit on the file, the #16847 patch | nothing new; the file unchanged on upstream main 2f424fd428da; #16847 changes only int doc to long doc; re-run by the fact check with the same results |
No regression: the method was written this way in 5.1.0 (2015, LUCENE-6339). Every release since fails, with NegativeArraySizeException up to 7.4.0 and IllegalArgumentException from 7.5.0, through 10.6.0 and main.
Versions tested6 rows
Introducing commits: b7adb6ac770 (trunk, 2015-03-27) and its branch_5x copy 40e94c39ad3 (2015-03-28, in 5.1.0), LUCENE-6339 "Near real time Document Suggester" (#7400, Areek Zillur), as new SuggestScoreDocPriorityQueue(topN). 8e2c6aa1d58 (#14817, Simon Cooper, 2025, main only) switched to PriorityQueue.usingComparator(topN, ...) and kept the size; 10.6.0 and branch_10_6 still have the old queue class (TopSuggestDocs.java:105 there), as did branch_10x until it was retired on 2026-10-29 (#16911). The exception type follows PriorityQueue's guard: before 7.5.0 it computed maxSize + 1 first, which wraps for Integer.MAX_VALUE, hence NegativeArraySizeException: -2147483648; 4c646dab3fb (2018, main; 7.5.0 has its branch_7x copy 154952f47d8) fixed that. The topN + 1 allocation is in every version.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle; standalone -ea and -da): IllegalArgumentException |
| 10.6.0, 10.5.2 (release jars) | affected | the minimal test fails: IllegalArgumentException |
| 7.5.0 to 10.5.2 | 8 releases | a release-faithful probe fails on 7.5.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2: IllegalArgumentException; the TopDocs.merge control returns 3 hits |
| 5.1.0 to 7.4.0 | 4 releases | the probe fails on 5.1.0, 5.5.5, 6.6.6 and 7.4.0: NegativeArraySizeException: -2147483648 |
| 5.0.0 | not affected | TopSuggestDocs does not exist |
fix A (scratch worktree at 645d4fe14a20) | not affected | the minimal test and the suggest module's 237 tests pass |
An independent reproducer, an intended-behaviour devil's advocate, an adjudication, a history sweep, a credibility audit and a fresh-seed re-run confirm it; reading-only reviews by another model family agree on the root cause (one gave a procedural "not real": it could not run Java). This doc re-ran the test and validated the fix with gradle.
Checks and verdicts461 words
All cross-model reviews (two before this doc, a fact check of it) ran reading only and could not run Java; no executing cross-model review exists. The cross-model fact check judged the bug noise; the independent fact check disagreed (see "Why it is not intended").
| Check | Verdict | What it found |
|---|---|---|
| finder (differential check) | candidate | 3-test JUnit fails 2 of 3 on main (-ea, -da), the 10.6 RC, 10.5.2 and 9.12.3; the TopDocs.merge control passes; the fix passes 3 of 3. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | procedural "not real" (low) | Agreed on the root cause and that the inputs are in contract; raised "analogous may mean purpose only" (moderate). A separate run re-ran the repro with -da: 2 of 3 fail. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | "Exposing it here appears to be an undocumented implementation accident"; re-run with -da: 2 of 3 fail. |
| independent reproducer | real, Low | Own 4-test JUnit fails 2 of 4 on main, 10.5.2 and 9.12.3; main() variant fails on 8.11.4 and 8.0.0; measured 400 MB for 3 hits at topN = 10^8. |
| intended-behaviour devil's advocate | real (medium) | Built the strongest intended case and rejected it; reach cases: the collector fails first with the same n, real shards collected with n = 5 and merged with Integer.MAX_VALUE fail, a caller cap works. |
| adjudication | confirmed (medium) | Re-ran the independent reproducer's test with a new seed, -ea and -da: 2 of 4 fail. |
| history sweep | not a regression | Release-faithful probe fails on 12 releases from 5.1.0 and on main. |
| credibility audit | downgrade, kept | Fresh seed: 2 of 3 fail; impact lowered for the experimental API and the completion-format path. |
| minimal-repro audit | verified | The one test fails on main (-ea, -da, two seeds) and passes with the fix. |
| this doc | reproduced, fix validated | The test fails on main (-ea, -da), 10.5.2 and 10.6.0; gradle in a fresh 645d4fe14a20 worktree fails without the fix and passes with fix A, with the suggest module's 237 tests and the format check. |
| fact check of this doc | reproduced; two wording errors, corrected | Re-ran the test on main (-ea, -da, three seeds), 10.5.2 and 10.6.0 and the doc's gradle command in a fresh clone, without and with fix A (237 tests pass); an edge-case probe backs every trade-off of fix A. The fix size (+8/-1) and the error-message sentence were corrected. |
| cross-model fact check (OpenAI GPT-5.6, reading only) | facts sound; judged noise | Found the core failure real and the brief broadly sound; its wording corrections are applied. Judged the bug noise (absurd parameter, loud failure, defensible). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 525 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,449 words
- Registry title
- TopSuggestDocs.merge, documented as analogous to TopDocs.merge, sizes its priority queue by topN before it reads any shard, so merging with topN = Integer.MAX_VALUE ('all') throws IllegalArgumentException 'maxSize must be >= 0 and < 2147483631' even for 3 hits or no shards (NegativeArraySizeException before 7.5.0), while TopDocs.merge returns the hits; a large legal topN allocates topN + 1 queue slots for a few hits
- Area
- suggest / document suggester: TopSuggestDocs.merge (merging per-shard suggestion results)
- Priority
- Low, rank 653: TopSuggestDocs.merge sizes its queue by topN, so it fails loudly on the Integer.MAX_VALUE 'all' idiom and never returns wrong results, the same shard-merge pre-size class as SearchGroup.merge LFV-958 but in an experimental suggest API that Lucene never calls.
- Impact class
- crash
- Impact note
- Hits only applications that combine per-shard document-suggester results themselves with the public, @lucene.experimental static TopSuggestDocs.merge (Lucene itself never calls it) and pass a merge topN of 2147483631 or more, typically Integer.MAX_VALUE as 'all', that is larger than the n their shards were collected with (with the same huge n, TopSuggestDocsCollector throws the same exception first); every such merge then throws, even with no hits, in every release from 5.1.0 to 10.6.0 and on main, and a legal large topN allocates topN + 1 queue slots whatever the hit count (about 400 MB for 3 hits at topN = 10^8, an OutOfMemoryError on a 256 MB heap); no setting or index size is needed, the failure is loud, and the results are correct whenever the call succeeds.
- Summary
- You collect suggestions from two index shards (for example SuggestIndexSearcher.suggest(query, 5, false) on each, giving 3 and 2 hits) and combine them with TopSuggestDocs.merge(Integer.MAX_VALUE, shards) to keep them all; its javadoc calls it 'Analogous to TopDocs#merge(int, TopDocs[])' and sets no bound on topN, so you expect the 5 hits that merge(10, ...) returns and that TopDocs.merge(Integer.MAX_VALUE, ...) returns for ordinary hits. Instead merge throws IllegalArgumentException 'maxSize must be >= 0 and < 2147483631; got: 2147483647', even for a single empty shard, because it creates its PriorityQueue with topN slots before it looks at any shard (TopSuggestDocs.java:116-117), while TopDocs.merge sizes its queue by the number of shards and its result by the hits it received. Below that limit, a large topN such as 10^8 makes merge allocate topN + 1 slots for a handful of hits.
- Introduced
- b7adb6ac7704a7e6364ee0d831bf77cf849f2090 (trunk, svn r1669698) and its branch_5x copy 40e94c39ad3b0f018ae9647b7d30bd0cfe341d86 (svn r1669715, the commit in 5.1.0): LUCENE-6339 'Near real time Document Suggester' (apache/lucene#7400; Areek Zillur; Subversion-era patch, no pull request), which added merge with new SuggestScoreDocPriorityQueue(topN). Michael McCandless proposed a TopSuggestDocs.merge method in that review; none of the 35 comments discusses its queue size [read: git log and blame in the history clone, the #7400 thread; exec: 5.0.0 lacks the API, 5.1.0 fails]. 8e2c6aa1d58 (#14817, Simon Cooper, author date 2025-06-27, main only) replaced the queue class with PriorityQueue.usingComparator(topN, ...) and kept the size (git blame of main lines 116-117 points there). Not a regression. (2015-03-27 (b7adb6ac770, trunk); 2015-03-28 (40e94c39ad3, branch_5x))
- First affected version
- 5.1.0 [exec] (tagged 2015-04-13; 5.0.0 has no TopSuggestDocs: the history probe does not compile there [exec])
- Affected versions
- Every release from 5.1.0 through 10.5.2, the branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) and main a9779ef3c193. [exec] The follow-up's release-faithful main() probe fails on 5.1.0 (-ea and -da), 5.5.5, 6.6.6, 7.4.0, 7.5.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da): merge(Integer.MAX_VALUE) and merge(Integer.MAX_VALUE, {EMPTY}) throw, while the TopDocs.merge control returns 3 hits; the finder's JUnit fails 2 of 3 on main (-ea, -da), the 10.6 RC, 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 2 of 4 on main (-ea, -da), 10.5.2 and 9.12.3, and its main() variant fails on 8.11.4 and 8.0.0. Only the exception changed over time: NegativeArraySizeException -2147483648 in 5.1.0-7.4.0, IllegalArgumentException from 7.5.0 on (the PriorityQueue guard fix 4c646dab3fb, 2018, thanks rsaavedraf). The topN + 1 allocation is in every version (400,000,896 to 400,000,944 bytes for 3 hits at topN = 10^8, against about 1 KB for TopDocs.merge). [read] Not fixed: upstream main 645d4fe14a20 still sizes the queue by topN (line 117, checked 2026-10-29), and branch_10x and branch_10_6 still use new SuggestScoreDocPriorityQueue(topN) (#14817 was not backported; the file is unchanged there since 2021).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (the prior-report record verdict new, confidence medium-high, searched 2026-10-29, read-only, 143 recorded queries: two scripted prior-report searches, each of 16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list (dev@, java-user@, issues@, commits@) and 4 JIRA-archive queries; own gh searches over apache/lucene, all of GitHub for the exact message and for TopSuggestDocs.merge, Elasticsearch, OpenSearch, Solr and nrtsearch; a code search for callers; the changed files of all 414 open apache/lucene PRs; JIRA REST and list reads; web searches. Recheck 2026-10-29: all 61 apache/lucene issues and PRs updated in the last 48 h and the changed files of the 48 PRs among them (none touches TopSuggestDocs.java; #14673, a closed branch-merge PR, touches only other suggest files), the newest commit on TopSuggestDocs.java per branch (main dfd536186fe, author date 2026-04-01, cosmetic #15889; branch_10x and branch_10_6 2021), the queue line on upstream main 645d4fe14a20 (still topN) and 4 searches). Related, not reports of this bug: #7400 (LUCENE-6339, added merge; no comment on its queue size), SOLR-5661 and SOLR-5674 (Solr's shard merge with rows = Integer.MAX_VALUE; SOLR-5674 item 3 proposed creating the merge queue after checking the shard result sizes, for Solr's code, closed Won't Fix in 2018), #1581 (LUCENE-504: the caller should size the queue), lucene-solr PR #411 (the PriorityQueue Integer.MAX_VALUE guard), #9588 (LUCENE-8542, open: per-slice collectors pre-sized by numHits), elastic/elasticsearch#76492 (the same message in an Elasticsearch reduce step, fixed there in #76578), #14817 and the open draft #16847 (touch the file, not the sizing).
- Lucene commit tested
- main
645d4fe14a20(11.0.0-SNAPSHOT): the minimal test with gradle in a fresh scratch worktree, 2026-10-30 (fails without the fix; with fix A it passes together with the suggest module's 237 tests and the format check), and the standalone runner with-eaand-da(seeds DEADBEEF, 5EED1234, 1002FACE); an allocation test without and with the fix; the 10.5.2 and 10.6.0 release jars (the minimal test fails). The hunt ran on maina9779ef3c193, where the suggest module,PriorityQueue.javaandTopDocs.javaare identical; the history sweep ran a release-faithful probe on 12 releases from 5.1.0 to 10.5.2 and on main.TopSuggestDocs.javais unchanged on upstream main2f424fd428da(2026-10-30).
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/TopSuggestDocs.java:30 (at a9779ef3c193) (@lucene.experimental), :107-113 (merge javadoc: 'containing topN results ... Each TopSuggestDocs instance must be sorted. Analogous to TopDocs#merge(int, TopDocs[])'; no bound on topN), :115-117 (PriorityQueue.usingComparator(topN, SUGGEST_SCORE_DOC_COMPARATOR) before the shard loop), :128 (totalHits = number of merged results)lucene/core/src/java/org/apache/lucene/util/PriorityQueue.java:34-35 (at a9779ef3c193) (NOTE: pre-allocates maxSize+1), :39 (@lucene.internal), :121-124 ('Throw exception to prevent confusing OOME', 'maxSize must be >= 0 and < ...'); lucene/core/src/java/org/apache/lucene/search/TopDocs.java:203 (merge(int topN, TopDocs[])), :278-315 (mergeAux: queue sized by shardHits.length at :283/:286, result new ScoreDoc[Math.min(size, availHitCount - start)] at :313); lucene/suggest/.../TopSuggestDocsCollector.java:76-81 (pre-sizes the same queue by num; only num > 0 checked)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/document/TopSuggestDocs.java:30, :107-113, :115-117, :118-124, :125-131a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/util/PriorityQueue.java:34-35, :39, :61-64, :117-134a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TopDocs.java:196-205, :278-287, :291, :303, :313a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestIndexSearcher.java:50-55; lucene/suggest/src/java/org/apache/lucene/search/suggest/document/TopSuggestDocsCollector.java:76-81grep 'merge(' over lucene/suggest/src at 645d4fe14a20: declaration and javadoc onlya Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/util/ArrayUtil.java:33-34; lucene/core/src/java/org/apache/lucene/util/RamUsageEstimator.java:124-133 (array header 16 bytes with compressed object pointers, 24 without)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/document/TopSuggestDocs.java:30, :107-113, :127-128; lucene/core/src/java/org/apache/lucene/util/PriorityQueue.java:34-35, :39, :122a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TopScoreDocCollectorManager.java:45, :83; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:721, :729; lucene/core/src/java/org/apache/lucene/search/TopDocs.java:296, :313a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/util/TestPriorityQueue.java:378-382 (testMaxIntSize)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/document/TopSuggestDocs.java:116-124; lucene/core/src/java/org/apache/lucene/util/PriorityQueue.java:117-124; lucene/suggest/src/java/org/apache/lucene/search/suggest/document/TopSuggestDocsCollector.java:40-41, :81
- History
a Lucene clone tag releases/lucene/10.6.0 (4ae946e5a9b9): TopSuggestDocs.java:104-105
- TestTopSuggestDocsMergeAllHits.java (lucene/suggest, package org.apache.lucene.search.suggest.document, 1 test):
repro/LFV-1002/src/org/apache/lucene/search/suggest/document/TestTopSuggestDocsMergeAllHits.java(40 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and an executed probe on the stock main jars (two real shards, -ea and -da, with and without the finder's form of the fix). The fix lines drawn are the finder's form, which has the same logic as option A.
assets/LFV-1002/bug.png(525 KB)