A documentation defect on main: counting a shared query's RAM once is intended, but both callbacks' javadoc still describes one fixed amount per entry.
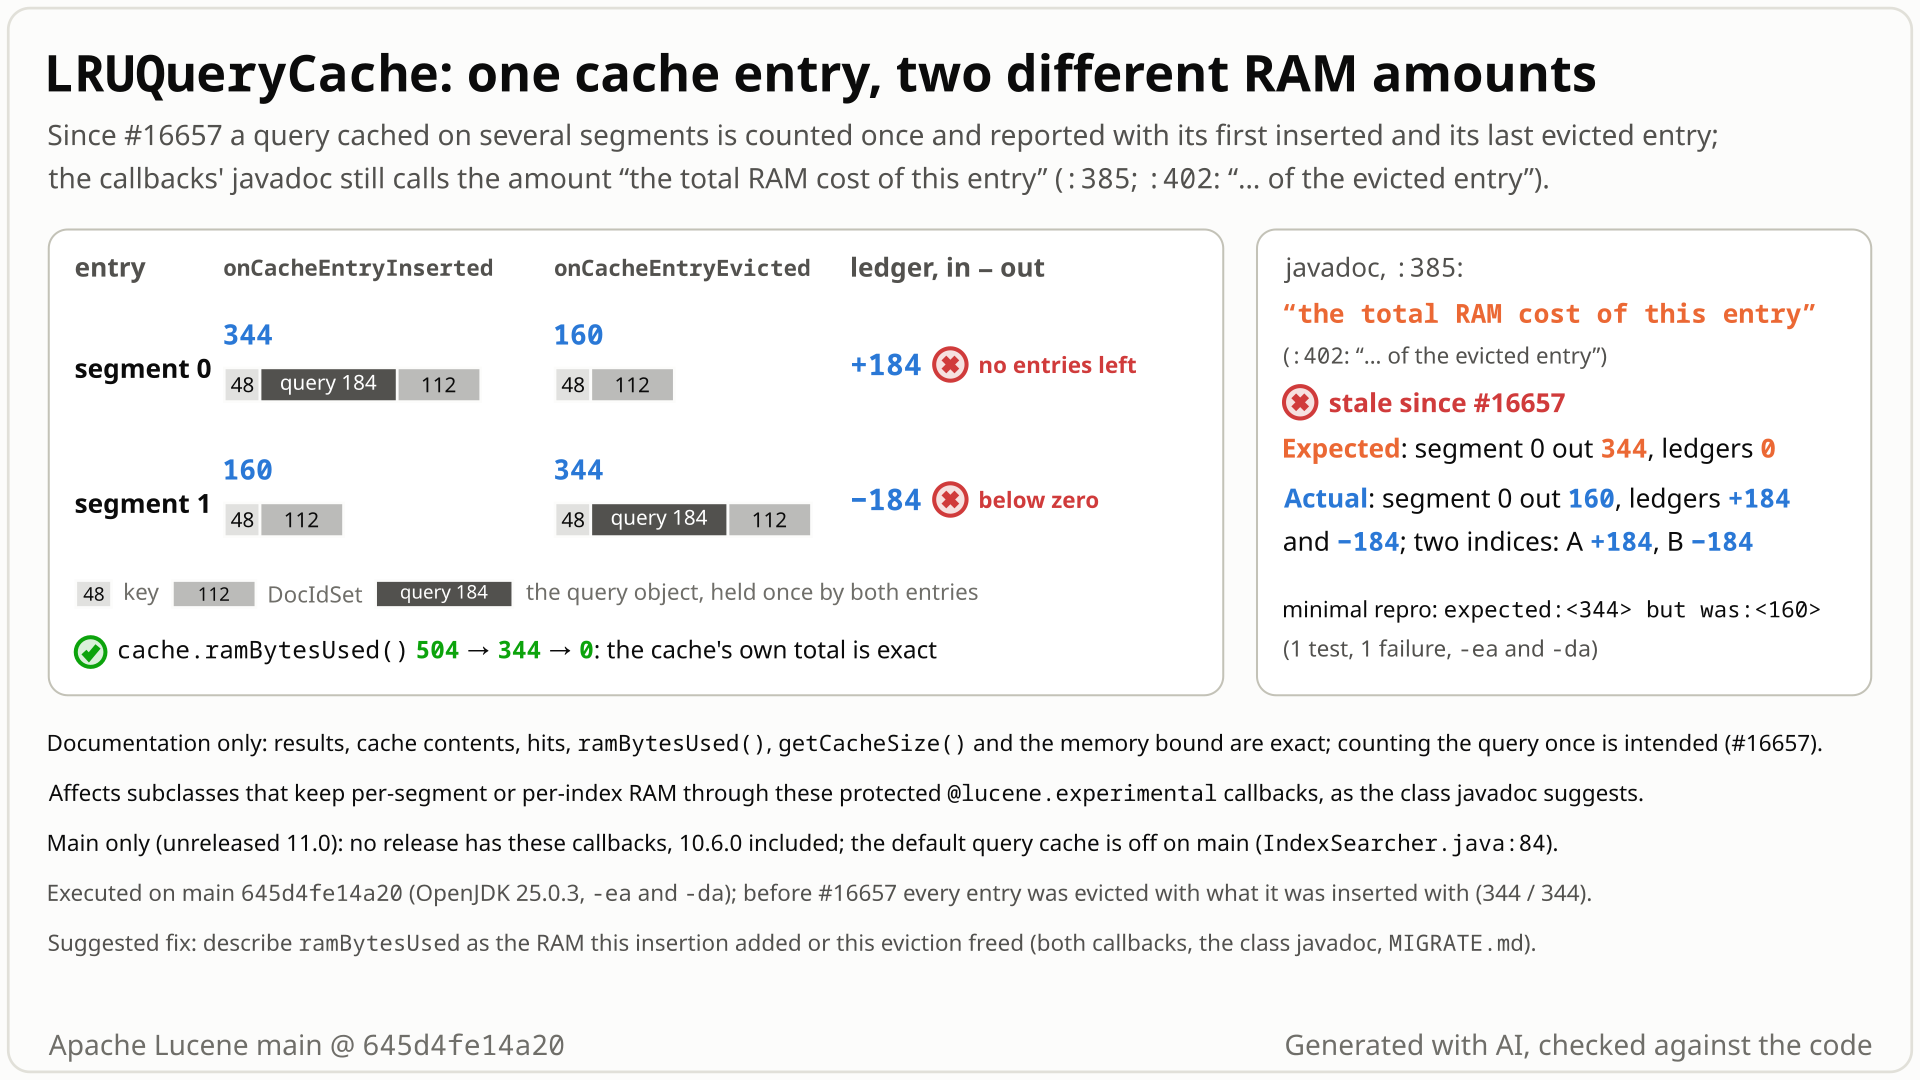
LRUQueryCachecaches, per segment, the documents a filter matches; each (segment, query) pair is one entry. For per-index statistics its javadoc says to override callbacks, preferablyonCacheEntryInserted/onCacheEntryEvicted(main only), which get the segment, the query andramBytesUsed.- An entry's RAM has three parts. In the repro: the per-entry key, 48 bytes; the cached doc id set and its table slot, 112 bytes; the query object itself, 184 bytes.
- Before #16657 every entry counted the query's bytes, although the entries of one search share one query object: one filter on two segments took 688 bytes. #16657 lets all entries of a query share one query object and counts it once: 504 bytes.
- You subclass
LRUQueryCacheto keep RAM per index, as its javadoc suggests: addramBytesUsedinonCacheEntryInserted, subtract it inonCacheEntryEvicted. Both javadocs call it "the total RAM cost of this entry". - You cache one filter,
color:red, on an index with two segments, then close segment 0 (the next cache cleanup removes its entry). You expect its entry to leave with the 344 bytes it came in with, and its count to return to 0. - It leaves with 160. Both entries share one 184-byte query object, counted once since #16657: its bytes come with the first insertion and go with the last eviction. Events: insert 344, insert 160, evict 160, evict 344.
- With two indices sharing one cache, index A keeps +184 bytes after it is closed and index B ends at -184, while the cache itself correctly reports 0. Each shared filter whose first and last entries are in different indices adds its query size.
- The count-once accounting is correct; the javadoc, written when every entry's amount included the query's bytes, was never updated. Main only; no release has these callbacks.
Only main and branch_11x (the coming 11.0). It takes an application's own LRUQueryCache subclass that keeps per-segment or per-index RAM from the unified callbacks, as the class javadoc suggests; the query cache is off by default on main. One filter on two segments is enough. Results, cache contents and the memory bound stay correct.
Mechanism, terms and numbers660 words
LRUQueryCache invites subclasses to keep "per-index or per-query-class statistics" through its callbacks and to prefer the unified onCacheEntryInserted / onCacheEntryEvicted, "which provide the full context (segment key, query, total RAM)". Both callbacks' javadoc says ramBytesUsed is "the total RAM cost of this entry" (of "the evicted entry"), "including both the query key overhead and the cached DocIdSet value". That matched the code when #15558 wrote it, because every entry's amount then included the query's bytes (double-counting a query shared by several entries, which #16657 fixed).
#16657 made all entries of a query share one canonical query object and count its RAM once. The query's bytes now come with the insertion of its first entry and with the eviction of its last entry, often entries of different segments or indices. So one entry is inserted with 344 bytes and evicted with 160, and with two indices sharing one cache a per-index ledger kept through the callbacks ends at +184 for one index and -184 for the other while the cache reports 0. The count-once accounting is intended and every amount is the exact change of the cache's own ramBytesUsed(); the defect is that the javadoc still describes one fixed amount per entry, and the MIGRATE.md advice added after #16657, which points to these callbacks, says nothing about shared bytes. Search results, cache contents, hit counts, ramBytesUsed(), getCacheSize() and the memory bound are correct.
onCacheEntryInserted (LRUQueryCache.java:385-386, :390 at 645d4fe14a20): "The ramBytesUsed parameter reflects the total RAM cost of this entry, including both the query key overhead and the cached DocIdSet value." / "@param ramBytesUsed total RAM bytes used by this cache entry". onCacheEntryEvicted (:402-403): "the total RAM cost of the evicted entry, including both the query key overhead and the cached DocIdSet value"; its @param (:407) says "total RAM bytes freed by this eviction". The class javadoc (:91-99) offers the callbacks for "per-index or per-query-class statistics" and says to prefer the unified ones, "which provide the full context (segment key, query, total RAM)". MIGRATE.md:521-522: "Prefer onCacheEntryInserted / onCacheEntryEvicted."
- A query goes to partition
query.hashCode() & (numberOfPartitions - 1)(:1277-1278), so all its entries share one partition, whoseuniqueQueriesmap holds one canonical instance per distinct query (:954). putIfAbsent(:1085-1137): the per-entry amount isQueryCacheKey.ramBytesUsed(), "Per-entry overhead only" (:1096,:1346-1350). "Account the query object only on the first entry that references it in this partition":queryBytes = perEntryBytes + (firstReference ? ref.queryBytes : 0)(:1111,:1120-1121), thenonCacheEntryInserted(cacheKey, canonical, queryBytes + cachedValueBytesUsed)(:1126-1127).remove(:1155-1189): "reclaim the query bytes on the last reference" (:1176-1177);releaseQueryreturns the query's bytes only when its count drops to 0, else 0 (:1001-1017); thenonCacheEntryEvicted(..., queryBytes + docIdSetBytes)(:1183-1184).
| event | amount | cache ramBytesUsed() after |
|---|---|---|
| insert segment 0 (the query's first entry) | 344 | 344 |
| insert segment 1 | 160 | 504 |
| evict segment 0 (segment 1 still holds the query) | 160 | 344 |
| evict segment 1 (the query's last entry) | 344 | 0 |
344 = 48 (key) + 112 (doc id set with its table slot) + 184 (query); 160 = 48 + 112. With #16657's parent shadowed, every event is 344 and the cache holds 688 with both entries. Two indices A and B sharing one cache, the same filter, readers closed in turn: the unified-callback ledger ends at A = +184, B = -184 with ramBytesUsed() = 0 and getCacheSize() = 0; the deprecated per-core onDocIdSetCache / onDocIdSetEviction ledger ends at A = 0, B = 0. The drift depends on order: with segment 1 cleared before segment 0 (the query's first and last entry in the same segment) the events are 344, 160, 160, 344 and both ledgers end at 0.
Exposure and likelihood304 words
- Who is hit. Applications on 11.0 (main and branch_11x today) that subclass
LRUQueryCacheand keep per-segment, per-index or per-shard RAM fromonCacheEntryInserted/onCacheEntryEvicted. Their ledgers drift silently: one index stays positive with no entries left, another goes negative, and the error grows with every shared filter whose first and last entries are in different segments or indices (the devil's-advocate verifier ran 50 shared filters: index A ended above its live RAM by the sum of their query sizes and index B below it by the same sum, at a negative value; the fact check's probe, searching A then B and closing A first, got A = +9200 and B = -9200). When a filter's first and last entries are in the same segment, its ledger balances. - Default vs opt-in. Opt-in: the query cache is off by default on main (
IndexSearcher.java:84,DEFAULT_QUERY_CACHE = null), and only a subclass that overrides these protected@lucene.experimentalcallbacks is affected. No in-tree subclass outside the tests overrides them, and a GitHub code search (indexed public code) found no implementer outside apache/lucene. - Scale. The most ordinary trigger, one cached filter on an index with two segments, already makes the per-segment amounts differ; no concurrency, no
clear(), no unusual parameters. - Not affected. Search results, cache contents, hit and miss counts,
ramBytesUsed(),getCacheSize(), the memory bound (eviction uses the partition's own accounting,LRUQueryCache.java:1128), and every release, 10.6.0 included. - Workarounds for subclass authors. Remember each entry's inserted amount and subtract that at eviction: it balances per index, but while a shared query is still held the per-index sum is below
ramBytesUsed()by the query's size. Or keep the deprecated per-coreonDocIdSetCache/onDocIdSetEviction, which still balance per core on main but "will be removed in a future release" (:361,:373).
One JUnit test, public API plus the two protected callbacks: two one-document segments, one cached filter, then segment 0's entries are cleared (clearCoreCacheKey plus cleanUp(), what closing it and the next cleanup do). It asserts the per-entry reading of the javadoc: segment 0's entry leaves with the bytes it came in with. Single-threaded; fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.util.HashMap;
import java.util.Map;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestLRUQueryCacheEntryCallbackBytes extends LuceneTestCase {

  public void testEvictedEntryReportsItsInsertedBytes() throws Exception {
    Map<Object, Long> inserted = new HashMap<>();
    Map<Object, Long> evicted = new HashMap<>();
    LRUQueryCache cache =
        new LRUQueryCache(100, 1 << 20, leaf -> true, 10f) {
          @Override
          protected void onCacheEntryInserted(Object readerCoreKey, Query query, long ramBytes) {
            inserted.put(readerCoreKey, ramBytes);
          }

          @Override
          protected void onCacheEntryEvicted(Object readerCoreKey, Query query, long ramBytes) {
            evicted.put(readerCoreKey, ramBytes);
          }
        };
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
        Document doc = new Document();
        doc.add(new StringField("color", "red", Field.Store.NO));
        w.addDocument(doc);
        w.commit();
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        searcher.setQueryCache(cache);
        searcher.setQueryCachingPolicy(
            new QueryCachingPolicy() {
              @Override
              public void onUse(Query query) {}

              @Override
              public boolean shouldCache(Query query) {
                return true;
              }
            });
        searcher.search(new ConstantScoreQuery(new TermQuery(new Term("color", "red"))), 1);
        IndexReader.CacheKey segment0 =
            reader.leaves().get(0).reader().getCoreCacheHelper().getKey();
        cache.clearCoreCacheKey(segment0);
        cache.cleanUp();
        // javadoc: both callbacks report "the total RAM cost of this entry", so the amounts match
        assertEquals(
            "segment 0 entry: onCacheEntryInserted vs onCacheEntryEvicted ramBytesUsed",
            inserted.get(segment0),
            evicted.get(segment0));
      }
    }
  }
}
./gradlew :lucene:core:test --tests TestLRUQueryCacheEntryCallbackBytes -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- Segment 0's entry is evicted with the 344 bytes it was inserted with, "the total RAM cost of this entry".
- Observed
AssertionError: segment 0 entry: onCacheEntryInserted vs onCacheEntryEvicted ramBytesUsed expected:<344> but was:<160>.
More files, environment, full output189 words
The test asserts the per-entry reading of the current javadoc (one entry, one amount), so its failure shows that the javadoc no longer matches the code. It is not a regression test: the documentation fix changes no code and leaves it failing, by design.
Only segment 0 is cleared, so the outcome does not depend on the order in which cleanUp() removes entries. NoMergePolicy keeps the two segments; the always-cache policy caches the filter on both. Controls, executed: with #16657's parent LRUQueryCache.java (shadowed, or as an exact-commit build) it passes; on 10.5.2 and 10.6.0 it does not compile, because the callbacks and the public cleanUp() do not exist there.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT) |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
cp $REPRO/TestLRUQueryCacheEntryCallbackBytes.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestLRUQueryCacheEntryCallbackBytes -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fail the same way: -Ptests.asserts=false
TestLRUQueryCacheEntryCallbackBytes > testEvictedEntryReportsItsInsertedBytes FAILED
    java.lang.AssertionError: segment 0 entry: onCacheEntryInserted vs onCacheEntryEvicted ramBytesUsed expected:<344> but was:<160>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:2D824F39DC672]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:120)
        at org.apache.lucene.search.TestLRUQueryCacheEntryCallbackBytes.testEvictedEntryReportsItsInsertedBytes(TestLRUQueryCacheEntryCallbackBytes.java:79)

1 test completed, 1 failed

# the same with -Ptests.asserts=false, and with the documentation fix applied (by design)- Both javadocs call the amount the entry's total RAM cost; the first entry's 344 also carries the 184-byte shared query.
- That matched the code when #15558 wrote it (every event 344); #16657 changed the amounts, not the text.
- The class javadoc offers the callbacks for per-index statistics and, like
MIGRATE.md, points to the unified pair; neither mentions shared bytes.
The full argument244 words
- The contract text names one per-entry quantity with two components, at both events (
LRUQueryCache.java:385-386,:390,:402-403). On main the 184-byte query object is neither component:QueryCacheKey.ramBytesUsed()is "Per-entry overhead only" (:1347), 48 bytes, and a structurally identical second entry reports 160. - History. #15558 (
d50fb36d9af3, 2026-04-14) wrote the text when each entry's key included the query's bytes; all fiveLRUQueryCache.javaversions from #15558 to #16657's parent pass the repro (assertions on). #16657 (fadd63e0eb4e) left the javadoc and the class javadoc byte-identical (the class javadoc's per-index sentence,:91-93, is older,2d6ad2fee6df, 2020;:94-99is from #15558); its PR body and 13 comments never discuss what the callbacks report.CHANGES.txt:281-282says only that a query's RAM is accounted once. - The class javadoc offers the callbacks for per-index statistics (
:91-93), and it andMIGRATE.mdpoint to the unified pair (:97-99;MIGRATE.md:521-522, #16756), while the deprecated per-core pair, the only one that still balances per index, is marked for removal. - Tests. No upstream test checks per-entry or per-segment amounts:
testUnifiedCacheEntryCallbacks(TestLRUQueryCache.java:2725) forces one segment, where a query's first and last entry coincide, and checks aggregate balance;testFineGrainedStats(:954) keeps RAM only cache-wide. - Precedent (weaker than it reads). #12614 (2023) fixed an earlier, different insert/evict amount mismatch in the predecessor
onQueryCache/onQueryEvictionpair as a bug; there it also broke the cache's own total, here it does not.
The devil's-advocate check304 words
The strongest case for "works as designed" (the executing refute review by OpenAI GPT-5.6, verdict not real, high confidence, and the devil's-advocate verifier): each amount is the actual cache-wide RAM change of its event, and the eviction @param says exactly that ("total RAM bytes freed by this eviction"); nothing promises that an entry's two amounts are equal; a shared query's RAM cannot be split per index without double counting; upstream tests pin the aggregate balance and the count-once accounting (testQueryRamAccountedOncePerDistinctQuery, testCanonicalQueryInstanceSharedAcrossSegments); in 10.x onQueryCache also reported a query's RAM once per distinct query, so folding it into one insertion is the faithful sum of the pair the unified callback replaces; the hooks are experimental and unreleased.
Why it fails: it defeats a code-bug claim, which is why none is made. It does not make the text right. The insertion javadoc has no "added by this insertion" wording at all, and its two named components do not cover the 184 bytes the first insertion carries. The eviction sentence repeats the per-entry wording, and its "freed by this eviction" @param fits the per-event reading, but was written when that was the same number as the per-entry total, so it does not show that one entry's two amounts were meant to differ. The class javadoc offers the callbacks for per-index statistics, and it and MIGRATE.md point to the unified pair, with no word on shared bytes. The reviewer itself wrote that "a clarification could make the javadoc less susceptible to this interpretation". Verdict (tie-break): a documentation defect, not a code bug. The cache-wide-delta reading is the cross-model reviewer's and the intended-behaviour check's; their correct points belong in the fix text. The second cross-model fact check (OpenAI GPT-5.6) also rates the intended-behaviour case strong and calls "clarify the attribution" the strongest version of the claim.
Recommended A: describe the per-event amounts in the javadoc and MIGRATE.md (recommended, validated)
Documentation only: describe ramBytesUsed as the RAM this insertion added or this eviction freed; a shared query's own RAM comes with its first insertion and last eviction, so one entry's two amounts can differ and per-segment sums need not return to zero; clear() reports only onClear(). Same note for the class javadoc's "total RAM" and MIGRATE.md.
// onCacheEntryInserted
 * <p>The {@code ramBytesUsed} parameter is the RAM that this insertion added to the cache: the
 * per-entry key overhead and the cached {@link DocIdSet} value, plus the RAM of the query object
 * itself when no other entry of the same query is cached. All entries of a query share one query
 * object, which is accounted once: its RAM is reported with the insertion of the query's first
 * entry and with the eviction of its last entry (see {@link #onCacheEntryEvicted}), and these
 * often belong to different segments. The amounts reported for one entry at insertion and at
 * eviction can therefore differ, and sums of these amounts kept per segment or per index need not
 * return to zero once that segment's or index's entries are gone.
 * @param ramBytesUsed RAM bytes added to this cache by this insertion
// onCacheEntryEvicted: "the RAM that this eviction freed ... plus the RAM of the query object itself
// when this was the last cached entry of the same query"; "Entries dropped by {@link #clear()} are not
// reported here; {@link #clear()} calls {@link #onClear()} instead."; class javadoc: "RAM added or freed";
// MIGRATE.md: the same note in the #15558 section
All options and trade-offs3 options · 740 words
One option was built and checked (A); B is a question for maintainers; C should be avoided.
The finder's wording with the adjudication's corrections: both callbacks, the class javadoc's "total RAM" sentence and one paragraph in the #15558 section of MIGRATE.md (+26/-8 lines). The finder's sentence "the sum of all inserted amounts minus all evicted amounts equals ramBytesUsed()" is dropped, because it fails when an insertion runs concurrently with clear() (LFV-991). After the fact checks one sentence was added to the eviction javadoc and to MIGRATE.md: entries dropped by clear() are not reported as evictions, clear() calls onClear() instead (LRUQueryCache.java:455-460, :1191-1201).
// onCacheEntryInserted
 * <p>The {@code ramBytesUsed} parameter is the RAM that this insertion added to the cache: the
 * per-entry key overhead and the cached {@link DocIdSet} value, plus the RAM of the query object
 * itself when no other entry of the same query is cached. All entries of a query share one query
 * object, which is accounted once: its RAM is reported with the insertion of the query's first
 * entry and with the eviction of its last entry (see {@link #onCacheEntryEvicted}), and these
 * often belong to different segments. The amounts reported for one entry at insertion and at
 * eviction can therefore differ, and sums of these amounts kept per segment or per index need not
 * return to zero once that segment's or index's entries are gone.
 * @param ramBytesUsed RAM bytes added to this cache by this insertion
// onCacheEntryEvicted: "the RAM that this eviction freed ... plus the RAM of the query object itself
// when this was the last cached entry of the same query"; "Entries dropped by {@link #clear()} are not
// reported here; {@link #clear()} calls {@link #onClear()} instead."; class javadoc: "RAM added or freed";
// MIGRATE.md: the same note in the #15558 section
Trade-offs
- Documents the intended accounting instead of changing it: no runtime cost, #16657's count-once design stays.
- It does not give subclasses balanced per-index numbers; it tells them why they are not balanced. The workarounds (remember each entry's inserted amount, or the deprecated per-core pair) could be added if maintainers want.
- The class-javadoc sentence is the one LFV-1000's fix also rewrites ("under a lock"), and LFV-1000's fix also inserts a
MIGRATE.mdparagraph at the same place, so the two edits overlap. The eviction@param("total RAM bytes freed by this eviction") is accurate and stays. - A leaves the class javadoc's other stale sentence,
:66-68(one query's entries "may reside in different partitions"; since #16657 they share one), which is LFV-054's documentation point.
What the checks validated
- Stock
645d4fe14a20: the minimal test fails with assertions on and off, 344 vs 160. - With A (v1, before the
clear()sentence was added), in a scratch worktree with gradle::lucene:core:checkGoogleJavaFormat,ecjLintMainandrenderJavadocpass;TestLRUQueryCachepasses (40 tests, 3 skipped, 0 failures, seed DEADBEEF, assertions on; the log's "eclint tool location is not set" line is the separate editorconfig lint, notecjLintMain). With assertions off (seed C0FFEE),TestLRUQueryCacheplus the minimal test: 41 tests, 1 failure, the minimal test, as expected, because A changes no code. - The current diff (v2, comment text added):
git apply --checkon pristine645d4fe14a20files, google-java-format 1.37.0 (Lucene's version and options) leaves it unchanged, andjavac -Xdoclint:all/protected -Werrorpasses (a broken{@link}fails it). Gradle was not re-run for this version; the change is comment-only. - The diff applies cleanly to a pristine
645d4fe14a20(git apply --check). No regression test: a documentation fix has nothing to assert.
Give the unified callbacks a stable per-entry amount (key overhead plus doc id set) and report the query object's RAM through a separate per-query notification or an extra parameter.
Trade-offs
Per-entry and per-index sums would balance and a subclass could still rebuild ramBytesUsed(), but it adds API surface to hooks that are new in 11.0. Not built.
Restore the pre-#16657 accounting, so every event of one entry carries the query's bytes.
Trade-offs
Makes the javadoc true again (shadowed parent: every event 344) but counts the query twice, 688 instead of 504 bytes for one filter on two segments, which is the bug #16657 fixed. The devil's-advocate verifier showed that no per-entry split of a shared query's bytes balances both per entry and cache-wide.
Downstream: elastic/elasticsearch#163523 (open) tracks adapting Elasticsearch's per-shard query-cache statistics to the new cache, names these callbacks as the replacement hooks and does not mention how a shared query's RAM is attributed; its Lucene 11 branch still uses the deprecated pairs.
Bounded-exhaustive checking of the real jar: a probe ran every short sequence of cache operations on the stock main jar and checked that each entry's insertion and eviction amounts balance; 12,819 to 15,089 of 46,650 sequences did not. The finder ran a reference model in lockstep with the cache (0 mismatches) and reduced the failure to one test.
The method in full162 words
Method: semi-formal, bounded-exhaustive checking of the real jar. A probe enumerated every operation sequence up to a small bound against the stock main LRUQueryCache and checked per-entry and per-core callback balance: 12,819 of 46,650 sequences violated on a9779ef3c193 with assertions off; on 645d4fe14a20 15,089 with assertions off and 12,819 with them on (the count varies with identity-hash order in cleanUp()).
The finder (a hunt unit) then ran an independent reference model of the partitioned cache in lockstep with the real one: every sequence of length 1-6 over 8 operations and 9 configurations, 2,696,328 sequences and 16,353,259 event checks, 0 model mismatches; per-entry balance failed in 1,511,830 sequences and per-core balance in 973,900, the other six properties held. It read the root cause off putIfAbsent / remove and wrote a public-API JUnit. It was then reduced to the one test above.
The independent cross-model reviewer (OpenAI GPT-5.6) and the devil's-advocate verifier then framed it as stale documentation rather than a code bug.
No prior report: GitHub issues and PRs (with the JIRA archive), commits, mailing lists, Elasticsearch, OpenSearch, Solr and the web, searched 2026-10-29 and again 2026-11-01. Nearest: #16657 (the change), #15558 (the javadoc), #16756 (MIGRATE.md) and #12614, an earlier, different insert/evict mismatch in the predecessor pair, fixed as a bug in 2023.
Searches2 searches
Nobody has reported that the unified callbacks report a shared query's bytes only with its first inserted and last evicted entry, or that their "total RAM cost of this entry" javadoc and the class javadoc's "total RAM" are stale since #16657 and the MIGRATE.md recommendation says nothing about shared bytes. Every query quoting the javadoc returned 0 hits. Not fixed upstream: upstream main f815e679bf6c and branch_11x have the same LRUQueryCache.java (2026-11-01).
- #16657 (the introducing change): its discussion never covers what the callbacks report.
- #15558: wrote the callbacks and the per-entry javadoc, then exact. #16756: added the
MIGRATE.mdrecommendation. - #16169: made the upstream callback test single-segment, where a query's first and last entry coincide.
- #12614 (2023): an earlier insert/evict amount mismatch in the predecessor
onQueryCache/onQueryEvictionpair, which broke the cache's own total, fixed as a bug; different code and cause. - #16113, #10081: general RAM-attribution and concurrency discussions. Open PRs #16757, #16847, #16952 touch
LRUQueryCache.java, other methods. - Downstream: elastic/elasticsearch#163523 tracks adapting to the new cache and names the unified callbacks as the replacement hooks.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the JIRA archive), downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the web | 2026-10-29 | the scripted prior-report search (65 queries, 354 distinct hits), 36 manual apache/lucene and 13 downstream searches, a code search for implementers, the changed files of the 149 open PRs updated since #16657, the #16657, #15558 and #16756 threads read in full | no report; nearest #16657, #15558, #16756, #12614 |
| GitHub, commits, lists, JIRA archive, web | 2026-11-01 | the scripted prior-report search again (77 queries, 419 distinct hits), 40 manual GitHub searches, a code search for both callback names, the changed files of the 144 open PRs updated since #16657, the titles of all 81 items updated since 2026-10-28 | no report; open PRs #16757, #16847, #16952 touch other methods |
Introduced on main by #16657 (fadd63e0eb4e, merged 2026-09-29); the javadoc dates from #15558 (2026-04-14), when it was exact, and the MIGRATE.md advice from #16756. Executed: main and fadd63e0eb4e fail, its parent and four earlier versions pass; no release has these callbacks, 10.6.0 included.
Versions tested5 rows
Introduced by #16657 "Fix LRUQueryCache hashCode/equals contract and account query RAM once per distinct query" (Sagar Upadhyaya, approved and merged by Michael Froh), fadd63e0eb4e, 2026-09-29, milestone 11.0.0; in production code it changed only LRUQueryCache.java. The javadoc comes from #15558 (d50fb36d9af3, 2026-04-14), the MIGRATE.md recommendation from #16756 (120b3bc18dac, javanna, 2026-10-07). None of the 98 release tags that have LRUQueryCache.java (34 releases/lucene/*, 9.0.0 to 10.6.0, and 64 releases/lucene-solr/*, 5.1.0 to 8.x) has onCacheEntryInserted; branch_11x has the same file as main (read, not executed).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | 344 vs 160; the minimal test fails with assertions on and off (gradle and the standalone runner) |
fadd63e0eb4e (#16657) | introducing commit | exact-commit build: fails, 344 vs 160, assertions on and off |
1adb280101d9 (its parent) | bisect | exact-commit build: passes, assertions on and off |
d50fb36d9af3 (#15558) to 1adb280101d9 | shadowed | each of the five LRUQueryCache.java versions passes over the main build (assertions on; the parent's version also with assertions off) |
| 10.6.0, 10.5.2 | not applicable | the test does not compile: the callbacks and the public cleanUp() do not exist |
The finder, an independent reproducer, a devil's-advocate verifier, an adjudication, a credibility audit, a current-main reproducer, a tie-break and this doc's gradle runs all saw 344 vs 160. An executing refute review by OpenAI GPT-5.6 reproduced it too but called the behaviour intended; the tie-break agreed about the code and kept the documentation defect.
Checks and verdicts378 words
Every check ran on a main build with the same LRUQueryCache.java (blob ca5854c7: 645d4fe14a20, a9779ef3c193, ea57360912ed or 7cecf795236c) with OpenJDK 25.0.3 on Linux aarch64. The early cross-model lenses could only read; the 2026-11-01 refute review executed Java.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit: probe, reference model, JUnit) | candidate | JUnit fails 2 of 3 (the single-segment control passes), 40 of 40 two-segment runs over 20 iterations; the pre-#16657 class shadowed passes; reference model 0 mismatches. |
| Independent reproducer | real (documentation) | Own JUnit from the claim alone: 344 vs 160 and per-index A = +184, B = -184; passes with the pre-#16657 class. |
| Devil's advocate | real (documentation), medium | Built the eight-point intended case and confirmed it by execution (amounts are exact RAM deltas); kept only the documentation defect; 50 shared filters drive one index's ledger negative. |
| Cross-model lenses (OpenAI GPT-5.6, read-only) | intended: real; root cause: real; refute: not real (low, procedural) | Gave the cache-wide-delta reading and framed the defect as stale documentation. |
| Adjudication | confirmed, medium; documentation, minor, low | Re-ran the independent reproduction's JUnit with a new seed: same numbers; corrected the fix text. |
| Credibility audit | confirmed | Re-ran the minimal test (fail, 344 vs 160) and re-read the mechanism. |
| Current-main reproducer | real | Fails on 645d4fe14a20 with assertions on and off; 10.5.2 not applicable. |
| Refute review (OpenAI GPT-5.6, executed) | not real, high | Reproduced it with its own test (336 vs 160) and agreed on the root cause; read the amounts as per-event deltas and called that intended. |
| Second adjudication | real (documentation) | Re-ran both sides' tests and a semantics probe (events 344/160/160/344; A = +184, B = -184); the per-event reading fits the code but not the insertion javadoc. |
| Fact checks of this doc (independent; cross-model OpenAI GPT-5.6; diagram) | real (documentation); wording fixes applied | The independent check re-ran the gradle repro (344 vs 160, assertions on and off), its own probe and fix A, and found six minor wording, attribution and count errors. The cross-model check rated the intended-behaviour case strong and asked for a "clarify the attribution" framing and a clear() caveat in the fix. The diagram check found a misquote and an order-dependent "drifts". All were fixed or answered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 409 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,638 words
- Registry title
- On main, LRUQueryCache's onCacheEntryInserted/onCacheEntryEvicted javadoc still calls ramBytesUsed 'the total RAM cost of this entry', but since #16657 a query's shared RAM is reported only with its first inserted entry and its last removed entry, so one entry is inserted and evicted with different amounts and per-segment or per-index RAM kept through these callbacks drifts (one index stays positive, another goes negative) (documentation defect, main only)
- Area
- search / query cache (LRUQueryCache unified callback javadoc and MIGRATE.md)
- Priority
- Low, rank 1267: This main-only stale javadoc in the core LRUQueryCache misleads subclass authors: following the documented per-index use gives silently drifting RAM ledgers in a deterministic, single-threaded case while results, cache contents and the memory bound stay exact.
- Impact class
- minor
- Impact note
- Documentation only, on unreleased main (11.0): an application that subclasses LRUQueryCache and keeps per-segment or per-index RAM through the unified callbacks, as the class javadoc and MIGRATE.md recommend, gets ledgers that never return to zero once a query is cached on two or more segments (in the repro one index keeps +184 bytes with no entries left and another ends at -184; the drift grows with every shared filter), while search results, cache contents, hits, the cache's own ramBytesUsed()/getCacheSize() and its memory bound stay exact; the default query cache is off on main, no public subclass uses these callbacks yet, and every release, 10.6.0 (released 2026-10-29) included, lacks the API.
- Summary
- You subclass LRUQueryCache to keep per-index RAM statistics in onCacheEntryInserted/onCacheEntryEvicted, whose javadoc says ramBytesUsed is 'the total RAM cost of this entry' (and of the evicted entry), so you expect each entry to give back at eviction what it added at insertion and an index's total to return to 0 once its entries are gone. Since #16657 the cache deliberately counts a query's own RAM once per distinct query and reports it only with the query's first inserted entry and with the entry that drops its last reference, usually entries of different segments or indices: in a two-segment index one entry is inserted with 344 bytes and evicted with 160, and with two indices sharing one cache index A keeps +184 bytes after it is closed while index B ends at -184. The dedup and the cache's own accounting are correct; the defect, as the independent cross-model reviewer and the devil's-advocate verifier framed it, is that both callbacks' per-entry javadoc (written in #15558, when it was true) was left unchanged and that the class javadoc and MIGRATE.md recommend these callbacks for per-index statistics without saying how a shared query's bytes are attributed.
- Introduced
- fadd63e0eb4e (GITHUB#16657 'Fix LRUQueryCache hashCode/equals contract and account query RAM once per distinct query', by Sagar Upadhyaya (sgup432), approved and merged by Michael Froh (msfroh); putIfAbsent adds the query bytes only on the first reference and releaseQuery/remove return them only on the last, and the callback javadoc was left unchanged) [exec: one-file bisection, since #16657 changed only LRUQueryCache.java in production code: the parent's LRUQueryCache.java (1adb280101d9) shadowed over the 645d4fe14a20 build passes 3 of 3 with -ea and -da and over the 7cecf795236c build with -ea, while the stock builds fail]. The 'total RAM cost of this entry' javadoc and the class-javadoc recommendation of the unified callbacks come from d50fb36d9af3 (GITHUB#15558, sgup432, 2026-04-14), when they matched the code (all five LRUQueryCache.java versions from d50fb36d9af3 to 1adb280101d9 pass the repro when shadowed) [exec]; the MIGRATE.md recommendation 'Prefer onCacheEntryInserted / onCacheEntryEvicted' came later from 120b3bc18dac (GITHUB#16756, javanna, 2026-10-07), without a note on the attribution [read] (2026-09-29 (fadd63e0eb4e, author and commit date 2026-09-29T20:56:09Z; PR opened 2026-09-10); callback javadoc 2026-04-14 (#15558); MIGRATE.md recommendation 2026-10-07 (#16756))
- First affected version
- unreleased (11.0.0: main since fadd63e0eb4e, 2026-09-29, and branch_11x; no release has the unified callbacks: every release up to 10.5.2, 10.6.0 (released 2026-10-29; branch_10_6 4ae946e5a9b) and branch_10x lack onCacheEntryInserted/onCacheEntryEvicted [exec: the repro does not compile on 10.5.2 and 9.12.3, javap of the 10.6 RC core jar lists no onCacheEntry* method; read: none of the 33 release tags with lucene/core LRUQueryCache.java, nor branch_10x, branch_10_6 or branch_10_5, contains onCacheEntryInserted])
- Affected versions
- main from fadd63e0eb4e (2026-09-29) to 645d4fe14a20 [exec: the finder's JUnit fails 2 of 3 (the single-segment control passes) with -ea and -da on 645d4fe14a20 (seed DEADBEEF; 40 of 40 two-segment runs over 20 iterations, control 20 of 20 pass) and with -ea on the stock builds 7cecf795236c, ea57360912ed and a9779ef3c193; the independent reproduction's own JUnit fails 2 of 3 with -ea and -da; the adjudication's re-run (seed 5EED1406) fails 2 of 3 with -ea and -da; the re-runs (seed 5EED0406) fail 2 of 3 with -da and 1 of 1 for the single minimal test with -ea]; branch_11x [read: same LRUQueryCache.java blob ca5854c7 as main, newest commit to the file fadd63e0eb4e; not executed]; upstream main [read 2026-10-29: last commit to LRUQueryCache.java still fadd63e0eb4e, to MIGRATE.md 8476457b8752 (2026-10-15)]. Not affected [exec]: the parent 1adb280101d9 and the four earlier LRUQueryCache.java versions back to d50fb36d9af3 (#16178, #16081, #15965, #15558), each shadowed over the 645d4fe14a20 build (3 of 3 pass). Not applicable: 10.5.2 and 9.12.3 [exec: compile error, the callbacks and public cleanUp() do not exist], the 10.6 RC branch_10_6 4ae946e5a9b [exec: javap], branch_10x and every release tag [read]. On main the deprecated per-core pair onDocIdSetCache/onDocIdSetEviction still balances per core [exec: finder model, the intended-behaviour check]. All runs JDK 25.0.3 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-29; recheck 2026-10-29): a scripted prior-report search over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web (65 queries, 354 distinct hits, none the same bug; every query for the quoted javadoc text returned 0), 36 manual apache/lucene searches and 13 downstream searches (elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr), a GitHub code search for implementers of the unified callbacks (only apache/lucene itself), the changed files of the 149 open apache/lucene PRs updated since #16657 was merged, all issues and PRs updated since 2026-10-26, the commits API by author date, and the #16657, #15558 and #16756 threads read in full; the recheck repeated 10 searches (including items created or updated since 2026-10-27) and checked the files of the 39 open apache/lucene PRs updated since 2026-10-27 (none touches LRUQueryCache.java; the MIGRATE.md hunks of #16857 and #16816 do not touch the query-cache section). Nearest items, not this bug: #16657 (the introducing change; its 13 comments never discuss what the callbacks report and mention onCacheEntryEvicted only as a possible hook for a cache-wide unique-query map, a design not taken); #15558 (added the callbacks and the per-entry javadoc while each entry carried its own query bytes); #16756 (added the MIGRATE.md recommendation, nothing on the amounts); #12614 (2023, gtroitskiy: an earlier insert/evict amount mismatch in these hooks that left 'ghost bytes' in the cache-wide total, fixed as a bug; different code and root cause); #16169 (made the upstream unified-callback test single-segment, where a query's first and last entry coincide); #10081, #16113, #16847, #16757, #16918. Downstream context only: elastic/elasticsearch#163523 (javanna, opened 2026-10-27, open) plans to move Elasticsearch's per-shard query-cache statistics to the new cache and its unified callbacks and does not mention the attribution. Not fixed upstream: upstream main's last commit to LRUQueryCache.java is still fadd63e0eb4e (author date 2026-09-29). Tracking issue #16937 has no query-cache item
- Lucene commit tested
- main
645d4fe14a20(gradle in a scratch worktree, 2026-11-01: the minimal test fails with assertions on and off, before and after the documentation fix; the doc fix passes the format, lint and javadoc checks andTestLRUQueryCache); a standalone runner on645d4fe14a20with assertions on and off (fail), exact-commit builds offadd63e0eb4e(fail) and its parent1adb280101d9(pass), and five earlierLRUQueryCache.javaversions from #15558 on, shadowed over the main build (pass, assertions on). 10.5.2 and 10.6.0 do not have the callbacks (compile error). Upstream mainf815e679bf6cand branch_11x have the sameLRUQueryCache.java(read 2026-11-01).
- Finding record
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:88-101 (class javadoc: per-index statistics through the callbacks; 'Prefer the newer unified callbacks ... which provide the full context (segment key, query, total RAM)'), :380-411 (onCacheEntryInserted / onCacheEntryEvicted javadoc: 'total RAM cost of this entry', '@param ramBytesUsed total RAM bytes used by this cache entry', 'total RAM bytes freed by this eviction'), :1000-1016 (releaseQuery returns the query bytes only on the last reference), :1110-1128 (putIfAbsent: 'Account the query object only on the first entry that references it in this partition'), :1174-1185 (remove: 'reclaim the query bytes on the last reference', then onCacheEntryEvicted); IndexSearcher.java:84 (DEFAULT_QUERY_CACHE = null); lucene/MIGRATE.md:514-543 (the #15558 section: 'Prefer onCacheEntryInserted / onCacheEntryEvicted', no note on the attribution)SECURITY.md (In-scope reports; Other out-of-scope reports; Reporting out-of-scope issues publicly)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:91-99, :385-411, :954, :1001-1017, :1085-1137, :1155-1189, :1277-1278, :1346-1350 @645d4fe14a20; lucene/MIGRATE.md:514-542 @645d4fe14a20
- Who is affected
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:84 @645d4fe14a20; lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:356-378, :1128 @645d4fe14a20
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:91-99, :385-411, :1346-1350 @645d4fe14a20; lucene/CHANGES.txt:281-282; lucene/MIGRATE.md:514-542lucene/core/src/test/org/apache/lucene/search/TestLRUQueryCache.java:954, :2725, :2918, :2949 @645d4fe14a20
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:455-460, :1191-1201 @645d4fe14a20 (clear() calls only onClear())
- History
git -C a Lucene clone: release tags with lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java (98: 34 releases/lucene/*, 64 releases/lucene-solr/*; none has onCacheEntryInserted), re-counted 2026-11-01
- TestLRUQueryCacheEntryCallbackBytes.java (one JUnit test):
repro/LFV-1008/src/org/apache/lucene/search/TestLRUQueryCacheEntryCallbackBytes.java(86 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed minimal test and event table; re-rendered after the diagram check (the summary card's :402 quote and the order-dependent wording of the drift).
assets/LFV-1008/bug.png(409 KB)