All the facet sets of one field go into one byte array. create sizes that array from the first set alone, but every set then writes as many bytes as it needs.
- A
FacetSetis a small tuple of values per document, for example (year, month).FacetSetsField.create(name, sets...)packs the sets it is given into one binary doc-values field; a field of that name can be added to a document only once. - Each set writes its own bytes with
packValues(buf, start), which returns how many it wrote, and reports its size withsizePackedBytes(). The built-inInt/FloatandLong/DoubleFacetSetalways use 4 or 8 bytes per value. - You may write your own
FacetSetwith your own encoding, for example a compressed one, plus a matchingFacetSetDecoderthatMatchingFacetSetsCountsuses to count.
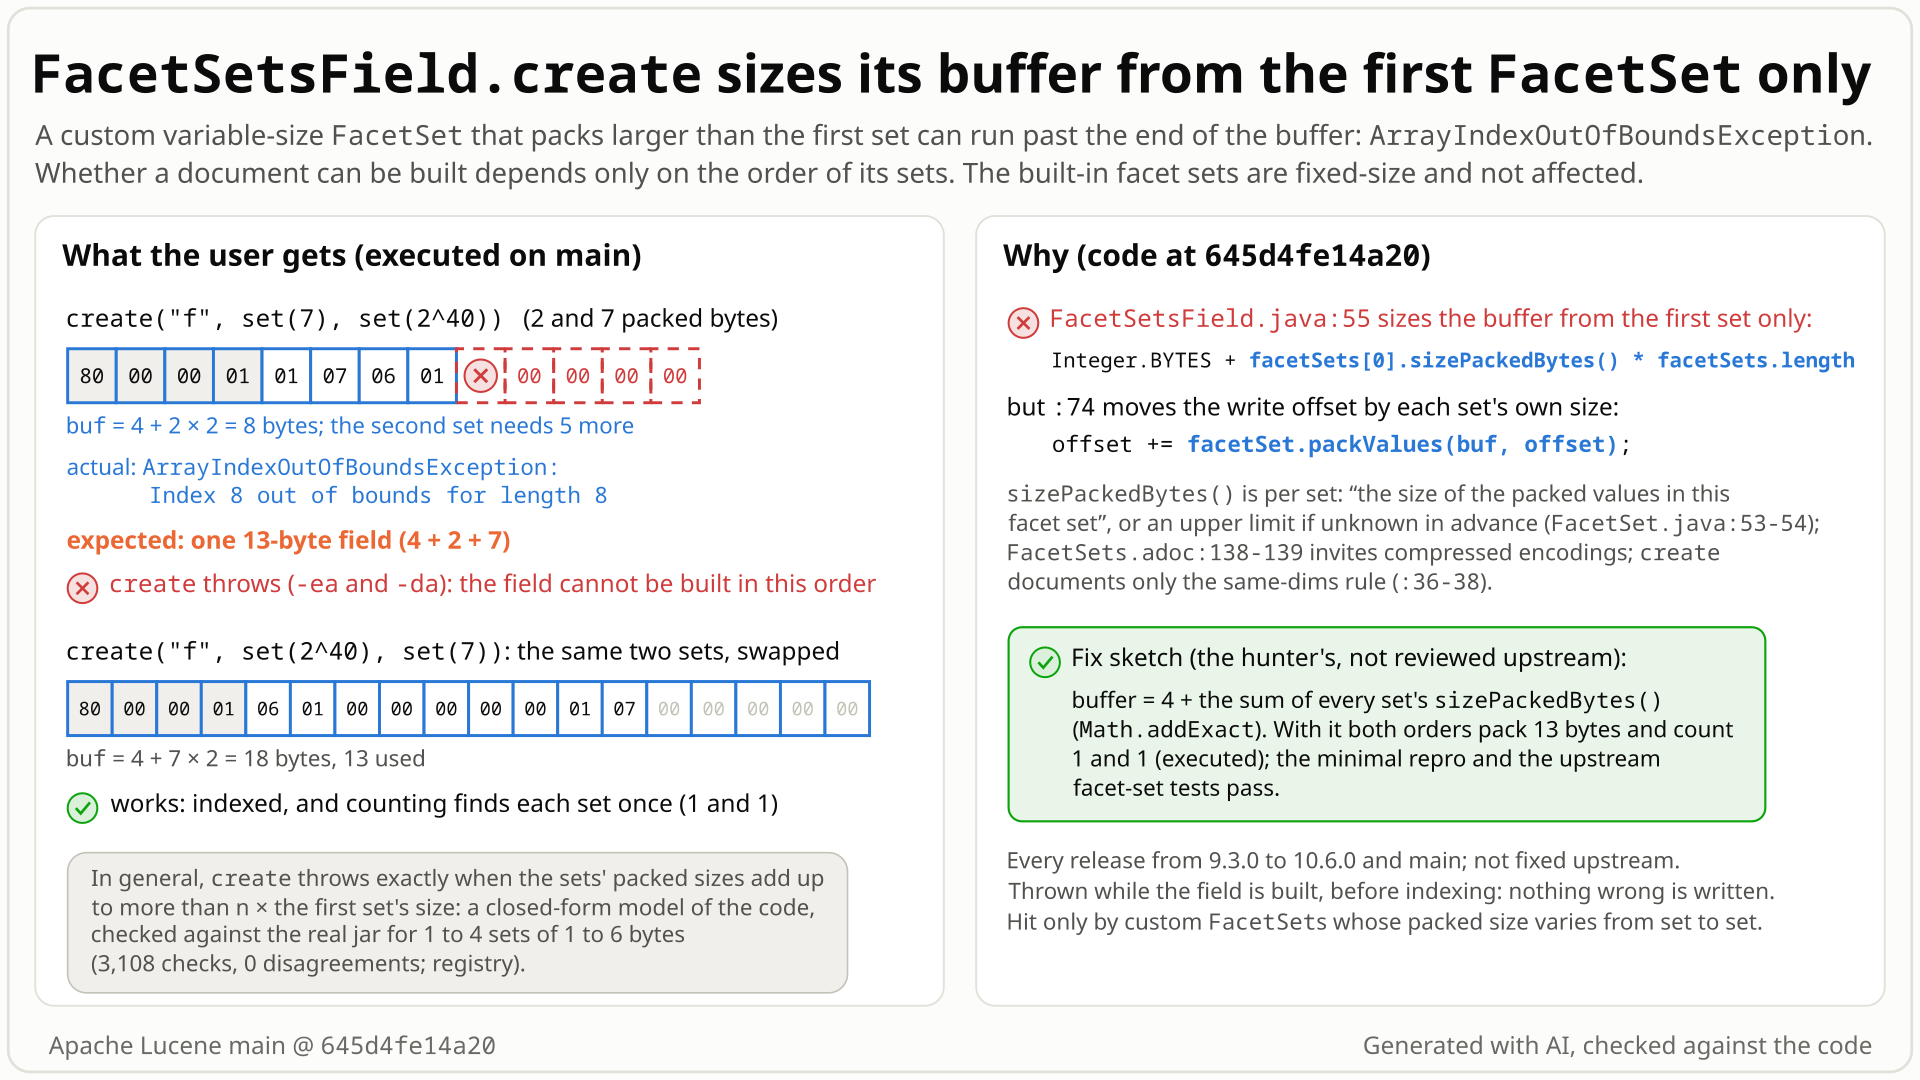
create sizing the buffer from the first set (8 bytes for 13) and the write past the end, the swapped order that works, and the fix that adds up every set's own size. Select the still to open it at full size. Generated with AI, checked against the code.- Write a one-dimension
FacetSetthat compresses its value: one length byte plus the value's significant bytes, withsizePackedBytes()returning that exact size. The value 7 packs to 2 bytes, the value 2^40 to 7 bytes. - Build the field for a document with both:
FacetSetsField.create("f", set(7), set(2^40)). You expect a field of 4 + 2 + 7 = 13 bytes: same class, same dimensions, so none ofcreate's documented errors applies. - Instead
createallocates 4 + 2 × 2 = 8 bytes, sized from the first set only, while each set writes its own bytes. The second set's write reaches byte 8:ArrayIndexOutOfBoundsException: Index 8 out of bounds for length 8. - Swap the order and it works:
create("f", set(2^40), set(7))allocates 4 + 7 × 2 = 18 bytes, keeps 13, and the document indexes and counts 1 and 1. In general it fails whenever the sets' average size exceeds the first set's.
Only applications with their own FacetSet whose packed size differs per instance (a compressed or variable-length encoding, which the docs invite) that pass a smaller set before a larger one. That document cannot be built in that order; nothing wrong is written. Every release since 9.3.0, any codec, assertions on or off. No such public FacetSet was found.
Mechanism, terms and numbers676 words
FacetSetsField.create(name, sets...) packs the facet sets of one field into one binary doc-values value. It allocates Integer.BYTES + facetSets[0].sizePackedBytes() * facetSets.length bytes (FacetSetsField.java:55 on main 645d4fe14a20) and then advances its write offset by what each set's packValues really writes (:74). FacetSet.sizePackedBytes() is per instance ("the size of the packed values in this facet set"; an upper limit is allowed when the size is unknown in advance, FacetSet.java:52-58), and FacetSets.adoc:137-139 invites custom encodings "e.g. by compressing them". So a custom compressed set that packs larger than the first set can overrun the buffer: create("f", set(7), set(2^40)) with sets of 2 and 7 bytes allocates 8 bytes for 13 and throws ArrayIndexOutOfBoundsException: Index 8 out of bounds for length 8, while the same two sets with the larger first pack, index and count correctly. Packing fails exactly when the sets' mean packed size exceeds the first set's (726 of 1,554 lists of 1-4 sets of 1-6 bytes, checked exhaustively on the real jar). The built-in Int/Long/Float/DoubleFacetSet are fixed-size and cannot trigger it. The exception is thrown while the field is built, so nothing wrong is indexed. Present since facet sets were added in 9.3.0 (#841); a fix that sums every set's size (a four-line loop) passes the repro and the whole facet module.
- FacetSet (
FacetSet.java,@lucene.experimental): a set ofdimsvalues per document.packValues(byte[] buf, int start)"Packs the dimension values into the givenbyte[]and returns the number of packed-values bytes ... you can override to implement your own scheme" (:39-43).sizePackedBytes(): "Returns the size of the packed values in this facet set. If the value is unknown in advance (e.g. if the values are compressed), this method can return an upper limit." (:52-58). - FacetSetsField (
FacetSetsField.java): aBinaryDocValuesFieldwhose value is the number of dimensions (anint, 4 bytes) "followed by each set's values" (:23-27).createrequires that all sets "must have the same number of dimensions" and throwsIllegalArgumentException"if the field name is null or the given facet sets are invalid" (:32-39); the code also requires the same class (:66-73). - FacetSetDecoder / MatchingFacetSetsCounts: at search time a decoder reads one set and "returns the number of bytes read" (
FacetSetDecoder.java:54-58); the counter advances by that value (MatchingFacetSetsCounts.java:124-125). So counting already handles sets of different sizes, given a matching decoder; the stockdecodeLongsanddecodeIntsare fixed-width, like the built-in sets (FacetSetDecoder.java:37-52).
FacetSetsField.java:55:byte[] buf = new byte[Integer.BYTES + facetSets[0].sizePackedBytes() * facetSets.length];sizes the buffer from the first set only.:74:offset += facetSet.packValues(buf, offset);advances by what each set really wrote.- The writes need
4 + sum(sizes)bytes; the buffer has4 + n * sizes[0]. It overflows exactly whensum(sizes) > n * sizes[0], that is when the sets' mean size exceeds the first set's; for two sets, when the second is larger. - The buffer is a fresh Java array, so the JVM's bounds check throws
ArrayIndexOutOfBoundsExceptionfrom inside the set'spackValues, out ofcreate, before any document reachesIndexWriter.
Bytes printed by an executed probe on main: the dims int is 80 00 00 01, set(7) packs 01 07, set(2^40) packs 06 01 00 00 00 00 00. Smaller first: buffer 8 bytes, holds 80 00 00 01 01 07 06 01, and the next write, at index 8, throws. Larger first: buffer 18 bytes, the field keeps 13 (80 00 00 01 06 01 00 00 00 00 00 01 07), and MatchingFacetSetsCounts counts 1 document for each value. With three sets of 2, 2 and 7 bytes the buffer is 10 bytes and the write fails at index 10. A bounded-exhaustive check (1 to 4 sets, sizes 1 to 6, 3,108 checks) found 726 of 1,554 lists failing, exactly those the formula predicts, and 0 failures when all sizes are equal or every set returns one class-wide bound.
Exposure and likelihood283 words
- Who is exposed. Applications that write their own
FacetSetsubclass whose packed size differs from one instance to the next (compressed, varint or length-prefixed) and return each set's exact size fromsizePackedBytes(), as the javadoc describes. The four built-in sets (IntFacetSet,FloatFacetSet:dims * 4;LongFacetSet,DoubleFacetSet: the defaultdims * 8) and the demo'sTemperatureReadingFacetSet(a constant size,CustomFacetSetExample.java:353-355) cannot trigger it. - Opt-in API. Facet sets are an
@lucene.experimentalpart of the facet module. Within it the failure does not depend onIndexWriterConfig, the codec or assertions: it happens while the field is built. - Effect. The field cannot be built with its sets in that order, so the document cannot be indexed with it. The field "can be added to a document only once, so you will need to construct all the facet sets in advance" (
FacetSets.adoc:98-99), so all the sets for that field go through this one call (an application may still add otherFacetSetsFields under other names). The exception comes from a fresh, bounds-checked Java array while the field is built, before anything reachesIndexWriter: no corrupt data, no wrong counts. - Scale. Any
createcall with two or more sets whose mean packed size exceeds the first set's: in the bounded check, 726 of 1,554 lists of 1 to 4 sets. - Workarounds today. Pass the largest-packing set first (then
n * sizes[0] >= sum(sizes)), or return one bound valid for every instance fromsizePackedBytes(). - How likely: rare. A public code search for
sizePackedBytes "extends FacetSet"found 39 files, all copies of Lucene's own sets; no outside variable-sizeFacetSetwas found, and nobody has reported it since 9.3.0.
One JUnit test on the public API: two sets of a one-dimension, length-prefixed FacetSet (2 and 7 packed bytes), smaller first. It fails on main, 10.6.0, 10.5.2 and 9.3.0 with assertions on and off, and passes unchanged with the fix, so it is also the regression test.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet.facetset;

import org.apache.lucene.tests.util.LuceneTestCase;

public class TestFacetSetsFieldVariableSizeSets extends LuceneTestCase {

  private static FacetSet lengthPrefixed(long value) {
    int n = Math.max(1, (Long.SIZE - Long.numberOfLeadingZeros(value) + 7) / 8);
    return new FacetSet(1) {
      @Override
      public long[] getComparableValues() {
        return new long[] {value};
      }

      @Override
      public int packValues(byte[] buf, int start) {
        buf[start] = (byte) n;
        for (int i = 0; i < n; i++) {
          buf[start + 1 + i] = (byte) (value >>> (8 * (n - 1 - i)));
        }
        return 1 + n;
      }

      @Override
      public int sizePackedBytes() {
        return 1 + n;
      }
    };
  }

  public void testSmallerSetFirst() {
    // expected: create() packs 2 + 7 bytes; actual: ArrayIndexOutOfBounds (buffer = 4 + 2 * 2)
    FacetSet small = lengthPrefixed(7);
    FacetSet large = lengthPrefixed(1L << 40);
    try {
      FacetSetsField.create("f", small, large);
    } catch (ArrayIndexOutOfBoundsException e) {
      throw new AssertionError(
          "expected a field for sets of "
              + small.sizePackedBytes()
              + " and "
              + large.sizePackedBytes()
              + " packed bytes, got "
              + e,
          e);
    }
  }
}
cp $REPRO/TestFacetSetsFieldVariableSizeSets.java $LUCENE/lucene/facet/src/test/org/apache/lucene/facet/facetset/
cd $LUCENE && ./gradlew :lucene:facet:test --tests org.apache.lucene.facet.facetset.TestFacetSetsFieldVariableSizeSets -Ptests.seed=DEADBEEF -Ptests.asserts=true
# fails the same way with -Ptests.asserts=false
- Expected
FacetSetsField.create("f", set(7), set(2^40))returns a field holding 4 + 2 + 7 = 13 bytes.- Observed
ArrayIndexOutOfBoundsException: Index 8 out of bounds for length 8fromFacetSetsField.toPackedValues(FacetSetsField.java:74).
More files, environment, full output300 words
TestFacetSetsFieldVariableSizeSets (64 lines with the license header) sits in package org.apache.lucene.facet.facetset next to the upstream facet-set tests but uses only public API. Both sets come from one factory method, so they are instances of one anonymous class and create's same-class check passes. The input is fixed and the test is single-threaded and needs no index; LuceneTestCase still randomizes its environment, and every seed tried fails (DEADBEEF and 5EED1009 for this test, 5EED4413 and C0FFEE01 for the finder's equivalent one). The file passes the facet module's google-java-format, ecjLint and forbiddenApis checks.
The test only builds the field. Indexing and counting are not needed: the exception is thrown inside create. The larger-first control (index, commit, count 1 and 1 with MatchingFacetSetsCounts) was run by the finder on every version and is not part of the minimal repro.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also the 10.6.0, 10.5.2 and 9.3.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the only platform run; the code path is plain Java) |
cp $REPRO/TestFacetSetsFieldVariableSizeSets.java $LUCENE/lucene/facet/src/test/org/apache/lucene/facet/facetset/
cd $LUCENE && ./gradlew :lucene:facet:test --tests org.apache.lucene.facet.facetset.TestFacetSetsFieldVariableSizeSets -Ptests.seed=DEADBEEF -Ptests.asserts=true
# gradle, clean main 645d4fe14a20 + the test, -Ptests.seed=DEADBEEF -Ptests.asserts=true (the same with =false)
TestFacetSetsFieldVariableSizeSets > testSmallerSetFirst FAILED
    java.lang.AssertionError: expected a field for sets of 2 and 7 packed bytes, got java.lang.ArrayIndexOutOfBoundsException: Index 8 out of bounds for length 8
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:86C9314D31A6E643]:0)
        at org.apache.lucene.facet.facetset.TestFacetSetsFieldVariableSizeSets.testSmallerSetFirst(TestFacetSetsFieldVariableSizeSets.java:58)

        Caused by:
        java.lang.ArrayIndexOutOfBoundsException: Index 8 out of bounds for length 8
            at org.apache.lucene.facet.facetset.TestFacetSetsFieldVariableSizeSets$1.packValues(TestFacetSetsFieldVariableSizeSets.java:35)
            at org.apache.lucene.facet.facetset.FacetSetsField.toPackedValues(FacetSetsField.java:74)
            at org.apache.lucene.facet.facetset.FacetSetsField.create(FacetSetsField.java:45)
            at org.apache.lucene.facet.facetset.TestFacetSetsFieldVariableSizeSets.testSmallerSetFirst(TestFacetSetsFieldVariableSizeSets.java:52)
:lucene:facet:test (FAILURE): 1 test, 1  failure

# standalone JUnit runner on the built jars, seed DEADBEEF
main 645d4fe14a20  -ea   tests_run=1 failures=1
main 645d4fe14a20  -da   tests_run=1 failures=1   (also seed 5EED1009)
10.6.0             -ea   tests_run=1 failures=1
10.5.2             -da   tests_run=1 failures=1
9.3.0              -ea   tests_run=1 failures=1
=> the same AssertionError and cause frames (FacetSetsField.java:74 <- :45)sizePackedBytes()is per instance, "the size of the packed values in this facet set", and may be an upper limit "if the value is unknown in advance"; nothing requires a class-wide bound.- The docs invite compressed encodings; counting advances by each set's decoded length.
createdocuments only a same-dimensions rule, yet the same two sets work or crash by order.
The full argument400 words
- Contract.
FacetSet.java:52-58: "Returns the size of the packed values in this facet set. If the value is unknown in advance (e.g. if the values are compressed), this method can return an upper limit." An instance method about "this facet set". It permits an upper limit when the size is unknown in advance; it does not say that a set whose exact size is known must return a bound shared by its whole class. Its own example of an unknown size is compressed values, which a maintainer may read as pointing to such a bound (see the strongest case below).packValues"returns the number of packed-values bytes ... you can override to implement your own scheme" (:39-43). - The docs invite variable sizes.
FacetSets.adoc:137-139: "If you implement your ownFacetSetand choose to encode the values differently (e.g. by compressing them), you should provide a corresponding implementation of aFacetSetDecoder." The class javadoc ofFacetSetsFielddescribes the value as the dimensions "followed by each set's values" (:23-27), with no uniform per-set size. - The generic path handles variable sizes. The field keeps only the bytes written (
new BytesRef(buf, 0, offset),:76);FacetSetDecoder.decodereturns "the number of bytes read" andMatchingFacetSetsCountsadvances by it (:124-125). The stock decoders are fixed-width, like the built-in sets, so a variable-size set brings its own decoder, asFacetSets.adoc:137-139says. Insidecreate, only:55assumes that every set has the first set's size. - No documented precondition.
createdocuments the same-dimensions rule and anIllegalArgumentExceptionfor invalid sets (:32-39). A size rule would be checked there, not left to an order-dependent array overrun inside the user'spackValues. - No test pins it. The facet-set tests use only the fixed-size built-in sets; no
CHANGES.txtentry orMIGRATE.mdnote mentions sizes. - History. The line and the javadoc arrived together in
f6bb9d218c0e(#841, 2022-06-25). Inside #841, PR commit40e2992e25(shaie, 2022-06-15) summed every set's size,new byte[4 + Arrays.stream(facetSets).mapToInt(FacetSet::sizePackedBytes).sum()]; PR commitab0d4e1624("Finish FacetSets.adoc", shaie, 2022-06-19) replaced it with today's line, in the same hunk that added the same-class check. So:55has been in tension with a per-instance reading of the javadoc from the start. The only review remark on the line (gsmiller, 2022-06-15: "Maybe useInteger.BYTESinstead of4here?") predates the switch; nobody discussed it (25 commits, 169 review comments, 62 issue comments read).
The devil's-advocate check188 words
Strongest case for "works as designed". The switch from the per-set sum to first-set-times-count was a deliberate edit, made together with the same-class check, so the authors pictured "one class, one size". Read that way, the "upper limit" clause is the hook for compressed encodings: a compressed set should return a class-wide worst case. Every shipped set is fixed-size, and the API is experimental.
Why we still read it as a bug. None of that is written down. The javadoc speaks of "this facet set" and offers an upper limit "if the value is unknown in advance"; it does not require a class-wide bound, so a set that knows its exact size and returns it is a natural reading. create documents no size rule and checks none, the same two sets work in one order and crash in the other with an undocumented ArrayIndexOutOfBoundsException, the generic counting loop advances per set, and the PR's own first version summed per-set sizes.
How strong the other reading is: moderate. The compressed-values example in the same javadoc sentence does support a class-wide-bound reading, and the switch in #841 was deliberate.
Recommended Size the buffer by the sum of every set's sizePackedBytes()
Size the buffer as 4 plus the sum of every set's sizePackedBytes() (a four-line loop with Math.addExact), the per-set-sum strategy of an earlier #841 commit by Shai Erera. Validated: the repro passes, and so do the whole facet module (307 tests) and its static checks.
int sizePackedBytes = 0;
for (FacetSet facetSet : facetSets) {
  sizePackedBytes = Math.addExact(sizePackedBytes, facetSet.sizePackedBytes());
}
byte[] buf = new byte[Integer.BYTES + sizePackedBytes];
All options and trade-offs3 options · 690 words
One fix was built and validated with gradle; two alternatives were not built. A maintainer may prefer option C, which documents a class-wide bound instead.
Replace line 55 of FacetSetsField.java with a loop that adds up every set's sizePackedBytes(). This restores the per-set-sum strategy of #841 PR commit 40e2992e25 by Shai Erera (shaie; it used Arrays.stream(...).sum()), with overflow-checked accumulation: Math.addExact turns an int overflow of the sum into an ArithmeticException. A cross-model review suggested checked accumulation; Math.addExact is the finder's way of doing it.
int sizePackedBytes = 0;
for (FacetSet facetSet : facetSets) {
  sizePackedBytes = Math.addExact(sizePackedBytes, facetSet.sizePackedBytes());
}
byte[] buf = new byte[Integer.BYTES + sizePackedBytes];
Trade-offs
- One extra pass of
nsizePackedBytes()calls per document, negligible next to packing; not measured. - For the fixed-size built-in sets the allocation is byte-for-byte the same as today (
nequal sizes sum ton * size). - Sets that return an upper limit still work: the field keeps only the written bytes.
- The final
Integer.BYTES + sizePackedBytesaddition is not checked, so a sum aboveInteger.MAX_VALUE - 4still wraps to a negative array size. Today's uncheckedsizes[0] * ncan wrap too: at the same point when all sizes are equal, and never later for a list that works today (those haven * sizes[0] >= sum). - The new loop calls every set's
sizePackedBytes()before the existing same-dimensions and same-class checks (:59-73). Valid lists behave as described; for an invalid mixed list, an unusualsizePackedBytes()of a set of another class (negative, or large enough to overflow) could now throw before the documentedIllegalArgumentException. Running the checks in the summing loop would keep today's order (not built). - It still trusts each set: a negative
sizePackedBytes(), or apackValuesthat writes more bytes than itssizePackedBytes()reports, still fails, as it does today. - A "Bug Fixes"
CHANGES.txtline would be usual; none is drafted.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle: the repro fails on the clean tree (assertions on and off) and passes with the fix. :lucene:facet:test --tests "org.apache.lucene.facet.facetset.*" -Ptests.seed=DEADBEEF(assertions off by the seed): 4 suites, 15 tests, 0 failed, 1 skipped (it needs assertions).:lucene:facet:test -Ptests.seed=DEADBEEF -Ptests.asserts=true: the whole facet module, 307 tests, 0 failed, 7 skipped (the gradle summary line). The suite count, 40 (39 upstream plus the new one), and the skip reasons (5 nightly-only, 1 monster, 1 without a message) were transcribed from the JUnit XML, which was not kept; the independent fact check re-ran the module in its own worktree and its JUnit XML gave the same 40 suites, 307 tests and 7 skips.:lucene:facet:check -x test(google-java-format, ecjLint, forbiddenApis): passes. The separate EditorConfig linter (eclint) is not configured on this machine and did not run.- Standalone runner with the fix shadowed in: 1 of 1 passes (
-ea,-da); an executed probe then packs the smaller-first case as the 13 bytes80 00 00 01 01 07 06 01 00 00 00 00 00and counts 1 and 1. - Earlier, by the hunt: the finder's 2-test JUnit and the upstream facet-set suites (3 + 6 + 5 tests) pass with the same fix; an independent reproducer's own sum fix passes its own test.
- Not run: nightly tests, a benchmark.
Start from 4 + sizes[0] and call buf = ArrayUtil.grow(buf, offset + facetSet.sizePackedBytes()) before :74.
Trade-offs
One pass and also correct, but more code and possibly several array copies for many sets; no advantage over the sum for the small set counts facet sets are meant for.
Change the sizePackedBytes() javadoc to require a bound that holds for every instance of the class, and in toPackedValues throw IllegalArgumentException when a set's sizePackedBytes() exceeds the first set's.
Trade-offs
Keeps today's allocation and turns the order-dependent crash into the documented exception, but narrows a documented extension point and still rejects lists the sum accepts; compressed encodings would have to return their worst case.
Downstream products that feed end-user values into their own variable-length FacetSet could see a user's document fail to index depending on the order of its values; Lucene's built-in sets cannot trigger it.
Code reading while checking multi-dimension doc-values fields that trust their first element (siblings of #16919): create sizes everything from facetSets[0]. A closed-form model (it fails iff the sizes sum to more than n times the first) was checked exhaustively on the real jar, 3,108 cases with 0 disagreements, then reduced to one JUnit.
The method in full161 words
Method: semi-formal (the hunt's hunt unit for binary doc-values multi-dimension fields that trust the first element's shape, 2026-10-29, main 645d4fe14a20).
- Lead. While modelling the unit's "trusts
facetSets[0]" pattern, the finder read that line 55 sizes the buffer from the first set while line 74 advances by each set's real size. - Model. Writes are cumulative and every size is positive, so packing overflows iff
sum(sizes) > n * sizes[0]. - Bounded-exhaustive translation validation on the stock main jar: n = 1 to 4 sets, packed sizes 1 to 6, two size policies (exact per-instance size; one class-wide upper limit), 3,108 checks. With exact sizes, 726 of 1,554 javadoc-legal lists throw, and the observed failure set equals the model's (0 disagreements). Vacuity: 0 failures with the class-wide limit and 0 when all sizes are equal; assertions on and off identical.
- Reduction. A public-API JUnit with a failing test and a larger-first control (index, commit, count), then minimized to the single failing test.
No prior report found (searched 2026-10-29, rechecked twice on 2026-10-30): GitHub issues, PRs and commits, four mailing lists, the JIRA archive, downstream projects and the web. Only the introducing PR #841 mentions FacetSetsField or sizePackedBytes, and no open PR touches the file.
Searches4 searches
Related, not reports of this bug: #841 / #981 (introduced the code; its review never discussed per-instance sizes), #11742 (a different facet-set bug in getTopChildren, fixed by #11764), #13948 (open, read-side decoding change). Hunt neighbours with other fix sites: LFV-405 (MatchingFacetSetsCounts ignores BytesRef.offset) and LFV-351 (FacetSets.adoc says documents where the code counts sets). Tracking issue #16937 does not mention facet sets.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), mailing lists, JIRA archive, downstream, web | 2026-10-29 | three runs of a scripted prior-report search: 153 queries over issues and PRs, commits, downstream repositories, dev@, java-user@, issues@ and commits@, the JIRA archive and the web | no report; the only high-scoring hit is #841, the introducing PR |
| GitHub, manual | 2026-10-29 | 32 manual searches (27 on apache/lucene), for example FacetSetsField, sizePackedBytes, toPackedValues; Elasticsearch, OpenSearch and Solr | FacetSetsField and sizePackedBytes return only #841; toPackedValues nothing; 0 downstream hits |
| Open PRs and #841 | 2026-10-29 | the changed files of all 415 open apache/lucene PRs; all 25 commits, 169 review comments and 62 issue comments of #841; LUCENE-10274's comments | only #13948 and #12862 touch the facetset package (read side); nobody discussed per-instance packed sizes |
| GitHub (rechecks) | 2026-10-30 (twice) | FacetSetsField, sizePackedBytes, toPackedValues, "FacetSet ArrayIndexOutOfBoundsException"; items mentioning facet updated, or FacetSet created, since 2026-10-29; open PRs mentioning FacetSetsField; the file's blob on upstream main | nothing new; upstream main 2f424fd428da still has the same FacetSetsField.java |
Present since facet sets were added in 9.3.0 (#841, f6bb9d218c0e, 2022-06-25); the line and the javadoc it is in tension with came in the same commit, so it is not a regression. The file is unchanged in every release since. Executed: 9.3.0, 9.4.0, 9.12.3, 10.0.0, 10.5.2, 10.6.0 and main fail; 9.2.0 has no facet sets.
Versions tested8 rows
Introduced by f6bb9d218c0e "LUCENE-10274: Add FacetSets faceting capabilities (#841)" (PR by mdmarshmallow, merged 2022-06-25; 9.3.0 CHANGES.txt credits Shai Erera, Marc D'Mello and Greg Miller), branch_9x backport 0e1502c12ba9 (#981, by shaie). git blame of FacetSetsField.java:40-78 and git log --all -S on line 55 find only these two commits. FacetSetsField.java is byte-identical (blob b2f2db7bb1fd) in all 31 release tags from 9.3.0 to 10.6.0 (30 up to 10.5.2, plus 10.6.0), on main 645d4fe14a20, on branch_10_6 and on upstream main of 2026-10-30.
Not fixed: the newest commit on the facetset package is a7704f5242d6 (2025-06-18, unrelated).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle and the standalone runner, assertions on and off, two seeds) |
| 10.6.0 | affected | fails (release jars, assertions on) |
| 10.5.2 | affected | fails (assertions on and off) |
| 10.0.0 | affected | fails (assertions off; the 9.x variant of the finder's test) |
| 9.12.3, 9.4.0 | affected | fail (9.12.3 assertions on and off, 9.4.0 off) |
| 9.3.0 | first release | fails (assertions on and off); the larger-first control passes |
| 9.2.0 | API absent | no facetset package: the repro does not compile |
| main + fix | not affected | the minimal test passes; the facet module, 307 tests, 0 failed |
An independent reproducer with its own varint FacetSet, an intended-behaviour devil's advocate, an adjudication and a credibility audit re-ran the repros and agree; reviews by another model family (OpenAI GPT-5.6) could only read code and agree on the root cause. The brief re-ran it with gradle and validated the fix.
Checks and verdicts489 words
The cross-model reviews were reading-only: they could not run Java. The refute-lens review returned a procedural "not real, medium" (it votes not real on what it could not reproduce) while agreeing on the root cause; a separate re-run failed as stated.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Closed-form model checked on the stock jar (3,108 checks, 0 disagreements, vacuity clean); JUnit fails on main (-ea, -da), 10.5.2, 9.12.3 and 9.4.0 with the larger-first control passing; the fix passes with the upstream facet-set suites. |
| cross-model review, refute lens | not real, medium (procedural, reading-only) | OpenAI GPT-5.6; root cause agrees, inputs in contract, intended argument weak; suggested checked (overflow-safe) accumulation, which the fix does with Math.addExact. A separate run re-ran the repro: 1 of 2 fail (-da). |
| Independent reproducer | real | Own varint FacetSet test outside Lucene's packages fails on main (-ea, -da), 10.5.2 and 9.12.3 with "Index 6 out of bounds for length 6" (buffer 4 + 1 × 2); control passes; own sum fix passes. |
| Cross-model review, intended lens | real, medium (reading-only) | OpenAI GPT-5.6; rated the works-as-designed case weak because nothing documents it. A separate run re-ran the repro: 1 of 2 fail (-da). |
| Intended-behaviour devil's advocate | real, medium-high | Built the strongest intended case from the #841 PR commits and answered it; re-ran on main (-ea, -da) and 10.5.2. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test (-ea) and the finder's (-da) with a fresh seed: both fail as stated, controls pass; not noise. |
| Registration check and credibility audit | keep | The failing test alone fails 1 of 1 (-da, fresh seed) and passes with the fix; a fourth re-run on main (-ea) fails the same way. |
| minimal-repro audit | verified | Reduced to the single failing test; fails on main (-ea, -da), passes with the fix. |
| brief | reproduced, fix validated | Gradle on the clean tree (fails, assertions on and off) and with the fix (passes; facet module 307 tests; check -x test); standalone runner on main, 10.6.0, 10.5.2 and 9.3.0. |
| independent fact check | ok, 0 errors | Re-ran the gradle command in its own worktree (fails 1 of 1, assertions on and off, byte-identical output), the fix (facet module 307 tests, 0 failed), the release jars and its own probe; four wording nits, fixed. |
| cross-model fact check | 4 errors: 3 fixed, 1 rejected (reading-only) | OpenAI GPT-5.6. Confirmed code, bytes, counts, releases and history; two overbroad phrases and an overflow comparison fixed, overclaims softened and caveats added; one error mistook the unconfigured EditorConfig linter for ecjLint. Rated the works-as-designed case moderate. |
| diagram check | ok, 0 errors | Every value, line number and step on screen checked against the code and the probe; the minor wording items were fixed in a re-render. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 509 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,236 words
- Registry title
- FacetSetsField.create sizes its buffer from the first FacetSet's sizePackedBytes(), so a list of custom variable-size facet sets (e.g. compressed, which the FacetSet javadoc and FacetSets.adoc allow) throws ArrayIndexOutOfBoundsException when a later set packs to more bytes than the first, and whether a document can be built depends only on the order of its sets
- Area
- facet / facet sets (FacetSetsField packing of custom FacetSet encodings)
- Priority
- Low, rank 659: A loud ArrayIndexOutOfBoundsException that needs a hand-written variable-size FacetSet in the experimental facet-sets module, so it sits with LFV-606, where a custom implementation the javadoc permits causes a crash.
- Impact class
- crash
- Impact note
- Only applications that write their own FacetSet subclass whose packed size differs from one instance to the next (a compressed or variable-length encoding, invited by FacetSets.adoc, with sizePackedBytes() returning each set's exact size) and pass a smaller-packing set before a larger-packing one to FacetSetsField.create hit it, on every release from 9.3.0 to 10.5.2, on 10.6.0 (by reading) and on main, with any IndexWriterConfig or codec and with -ea or -da; the exception is thrown while the Field is built, so that document cannot be indexed in that order, but nothing wrong is written and the built-in Int/Long/Float/DoubleFacetSet are not affected.
- Summary
- You write a FacetSet subclass that compresses its value (one length byte plus the value's significant bytes, so sizePackedBytes() is 2 for the value 7 and 7 for 2^40) with a matching FacetSetDecoder, and you expect FacetSetsField.create("f", set(7), set(2^40)) to work just like the same call with the two sets swapped. Instead create allocates 4 + the first set's sizePackedBytes() times the number of sets (8 bytes) and then writes each set's own packed bytes (13 needed), so the second set's packValues throws ArrayIndexOutOfBoundsException 'Index 8 out of bounds for length 8'. With the larger set first the same two sets pack, index and count correctly.
- Introduced
- f6bb9d218c0e8315d86d2aa2ac1f5c7313925a7a (apache/lucene#841, LUCENE-10274 'Add FacetSets faceting capabilities', Marc D'Mello and Shai Erera; branch_9x backport 0e1502c12ba9, #981) [read: git blame of FacetSetsField.java:40-78 and git log --all -S on the line find only these two commits; the parent has no facetset package]. Inside #841, PR commit 40e2992e25 (2022-06-15) sized the buffer as 4 + the sum of every set's sizePackedBytes(); PR commit ab0d4e1624 (2022-06-19, 'Finish FacetSets.adoc') replaced that with the first set's size times the count, with no review comment on the change. Not a regression: the line and the javadoc it breaks were added together. (2022-06-25)
- First affected version
- 9.3.0 [exec: the finder's JUnit fails with -ea and -da] (the first release with facet sets, LUCENE-10274 in its CHANGES.txt); 9.2.0 has no facetset package [exec: compile error, API absent]
- Affected versions
- every release from 9.3.0 to 10.5.2 and 10.6.0 (by reading) [read: FacetSetsField.java is byte-identical, git blob b2f2db7bb1fd, in all 30 release tags 9.3.0..10.5.2, main 645d4fe14a20, branch_10_6 and branch_10x]; [exec] the finder's JUnit fails on 9.3.0 (-ea, -da), 9.4.0 (-da), 9.12.3 (-ea, -da), 10.0.0 (-da), 10.5.2 (-ea, -da) and main 645d4fe14a20 (-ea, -da), always ArrayIndexOutOfBoundsException from FacetSetsField.toPackedValues:74 with the larger-first control passing; the independent reproduction's own JUnit fails on main (-ea, -da), 10.5.2 and 9.12.3; branch_10_6 / 10.6.0 RC1 4ae946e5a9b and branch_10x 657014b3c57 [read: same blob; the RC jar set has no facet jar, so not executed]; not fixed upstream (upstream main head 645d4fe14a20, author date 2026-10-28; newest commit on the facetset package a7704f5242d6, 2025-06-18, unrelated; no open PR touches FacetSetsField.java or FacetSet.java). JDK 25.0.3 for all versions.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-29, read-only; the prior-report record, verdict new, plus the finder's run and the independent reproduction's, the intended-behaviour check's and the adjudication's searches): three runs of the scripted prior-report search (153 queries over GitHub issues/PRs, commits, downstream repos, dev@, java-user@, issues@ and commits@, the JIRA archive and the web; the only high-scoring hit is #841, the introducing PR, which is not a report), 32 manual GitHub searches (27 on apache/lucene) ('FacetSetsField' and 'sizePackedBytes' return only #841, 'toPackedValues' nothing), Elasticsearch, OpenSearch and Solr (0 each), the changed files of all 415 open PRs (only #13948 and #12862 touch the facetset package, read side; none touches FacetSetsField.java or FacetSet.java), all 25 commits, 169 review comments and 62 issue comments of #841 and LUCENE-10274's comments and worklog (nobody discusses per-instance packed sizes). Recheck (2026-10-29): 'FacetSetsField' and 'sizePackedBytes' still return only #841; no apache/lucene item mentioning FacetSet updated since 2026-10-27 and none mentioning facet updated since 2026-10-28; none of the 13 issues and PRs created since 2026-10-28 (up to #16938) concerns facet sets; upstream main head is still 645d4fe14a20 and the newest facetset commit a7704f5242d6 (2025-06-18). Closest items, not reports: #841 / #981 (introduced the code), #11742 (a different facet-set bug, getTopChildren, fixed by #11764), #13948 (open, read-side decode change).
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; tested 2026-10-29 and 2026-10-30) through gradle in a scratch worktree (assertions on and off) and through the standalone JUnit runner (-ea,-da, seeds DEADBEEF and 5EED1009); the Maven Central release jars 9.3.0, 9.4.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0 (SHA-1 checked); 9.2.0 has no facet sets. The fix was validated in the scratch worktree: the repro, the wholelucene/facetmodule (307 tests, assertions on) and:lucene:facet:check -x test.
- Finding record
lucene/facet/src/java/org/apache/lucene/facet/facetset/FacetSetsField.java:23-29 (at 645d4fe14a20) (class javadoc: the dims int 'followed by each set's values'; @lucene.experimental), :32-46 (create javadoc: all sets 'must have the same number of dimensions', IllegalArgumentException for a null name or invalid sets; toPackedValues called at :45), :55 ('byte[] buf = new byte[Integer.BYTES + facetSets[0].sizePackedBytes() * facetSets.length];'), :59-73 (same-dims and same-class checks), :74 ('offset += facetSet.packValues(buf, offset);'), :76 (new BytesRef(buf, 0, offset))lucene/facet/src/java/org/apache/lucene/facet/facetset/FacetSet.java:38-50 (at 645d4fe14a20) (packValues 'returns the number of packed-values bytes', 'you can override to implement your own scheme'), :52-61 (sizePackedBytes: 'Returns the size of the packed values in this facet set. If the value is unknown in advance (e.g. if the values are compressed), this method can return an upper limit.')lucene/facet/docs/FacetSets.adoc:131-139 (at 645d4fe14a20) ('If you implement your own FacetSet and choose to encode the values differently (e.g. by compressing them), you should provide a corresponding implementation of a FacetSetDecoder.'); lucene/facet/src/java/org/apache/lucene/facet/facetset/FacetSetDecoder.java:54-58 (decode returns the number of bytes read); lucene/facet/src/java/org/apache/lucene/facet/facetset/MatchingFacetSetsCounts.java:125 (the counter advances by decode()'s return)
- The finding in 30 seconds
lucene/facet/src/java/org/apache/lucene/facet/facetset/FacetSetsField.java:23-29, (at 645d4fe14a20) :32-46, :52-77lucene/facet/src/java/org/apache/lucene/facet/facetset/FacetSet.java:39-61 (at 645d4fe14a20)lucene/facet/src/java/org/apache/lucene/facet/facetset/FacetSetDecoder.java:54-58; (at 645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/facetset/MatchingFacetSetsCounts.java:124-125lucene/facet/docs/FacetSets.adoc:96-99, (at 645d4fe14a20) :137-139
- Who is affected
lucene/facet/src/java/org/apache/lucene/facet/facetset/IntFacetSet.java:53-54, (at 645d4fe14a20) FloatFacetSet.java:56-57, FacetSet.java:59-61; lucene/demo/src/java/org/apache/lucene/demo/facet/CustomFacetSetExample.java:353-355lucene/facet/docs/FacetSets.adoc:98-99 (at 645d4fe14a20)
- Why it looks unintended
lucene/facet/src/java/org/apache/lucene/facet/facetset/FacetSet.java:39-61; (at 645d4fe14a20) FacetSetsField.java:23-39, :55, :66-76; FacetSetDecoder.java:54-58; MatchingFacetSetsCounts.java:124-125lucene/facet/docs/FacetSets.adoc:137-139 (at 645d4fe14a20)
- Suggested fix
lucene/facet/src/java/org/apache/lucene/facet/facetset/FacetSetsField.java:55-76 (at 645d4fe14a20) (order of the sizing and the checks)
- TestFacetSetsFieldVariableSizeSets.java (lucene/facet, public API, 1 test):
repro/LFV-1009/src/org/apache/lucene/facet/facetset/TestFacetSetsFieldVariableSizeSets.java(64 lines)
It is made in parallel with this doc; every byte and result on screen comes from the code or the diagram's executed probe.
assets/LFV-1009/bug.png(509 KB)