The dense points path appends each 4 KiB chunk of point bytes to the buffer inside its loop but counts the points only after the loop, with no finally. A failure after the first chunk leaves uncounted bytes that the next points of the field are paired with.
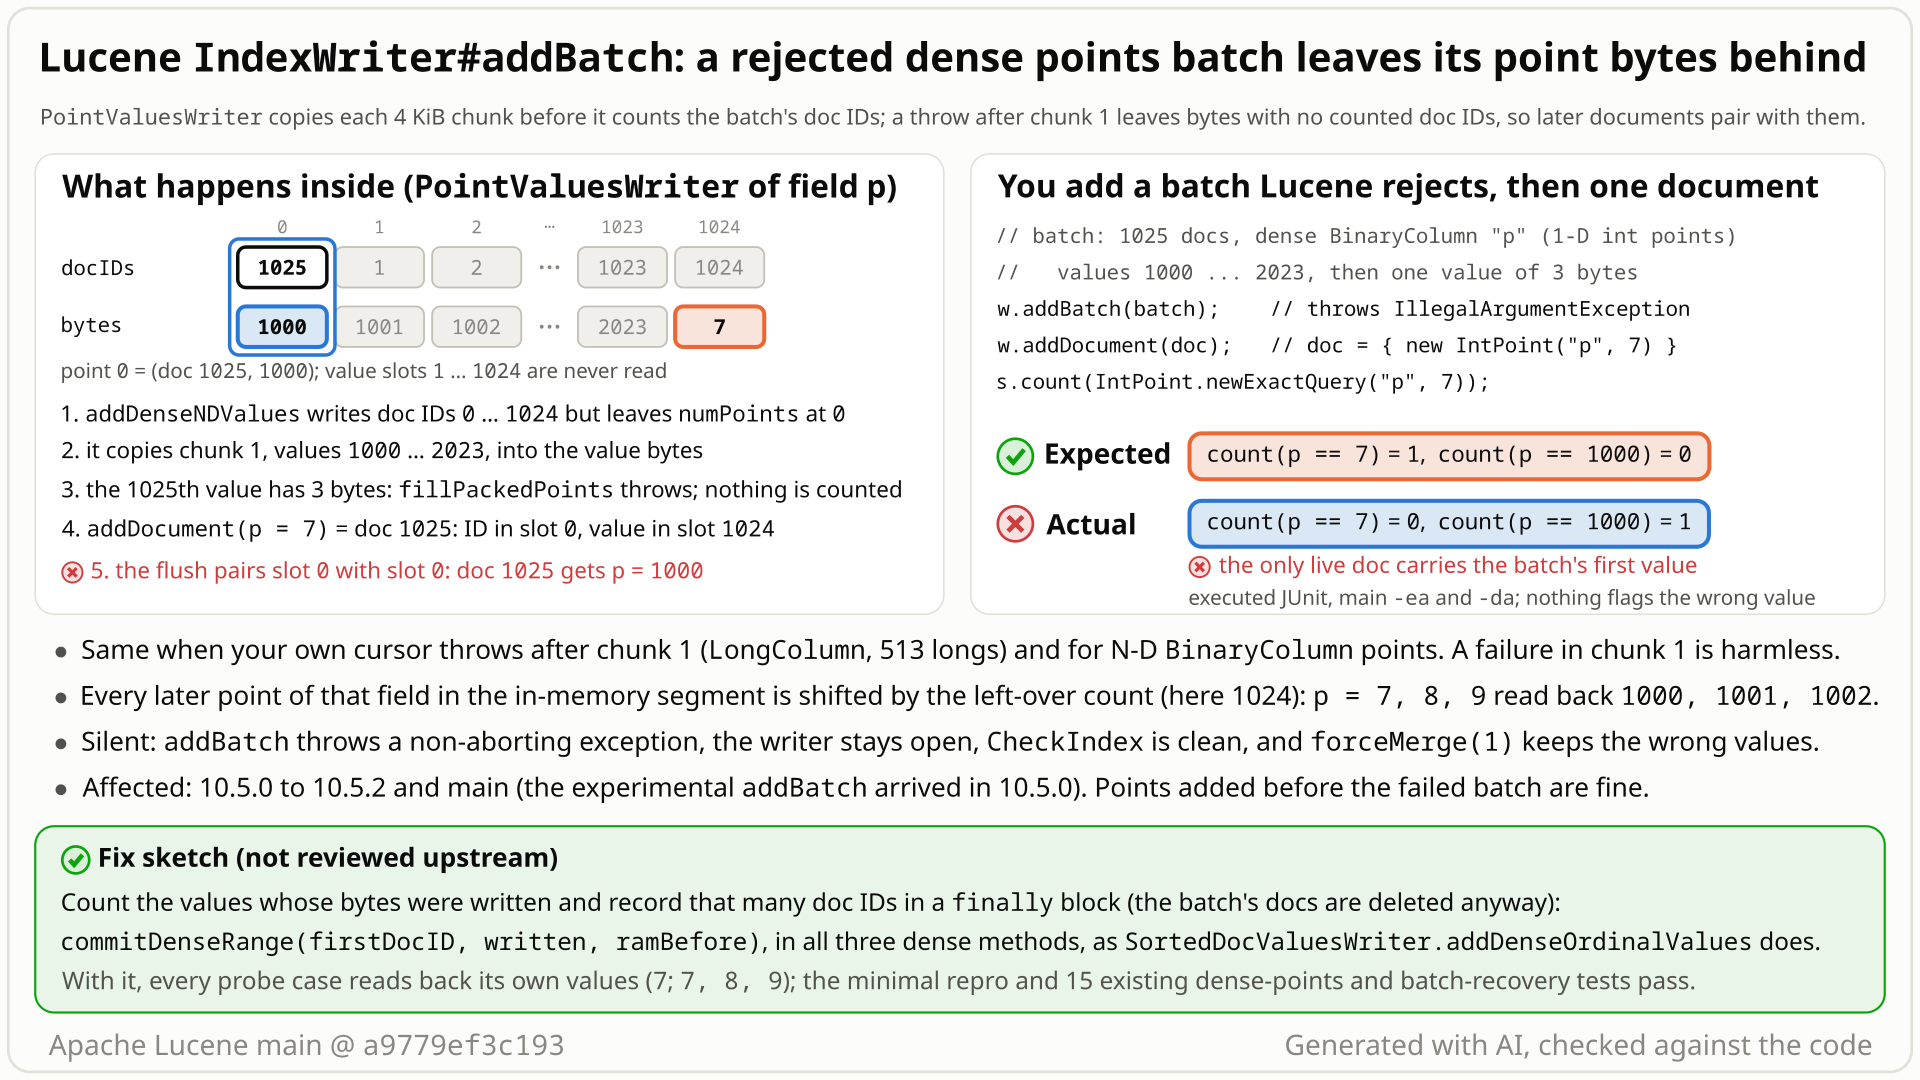
- Call
addBatchwith 1025 documents and a dense int points columnpholding 1000 to 2024. Value 1025 fails: your cursor throws, or it has 3 bytes and Lucene's own width check rejects it. - Lucene has already copied the first 1024 values (one 4 KiB chunk) into the field's points buffer. It rejects the batch, deletes its 1025 documents and keeps the writer open.
- You add 3 documents with
IntPointp = 7, 8, 9 and expect them to read back 7, 8, 9, as they do when the failure hits value 1024, inside the first chunk. - Instead they read back 1000, 1001, 1002. The buffer still holds the 1024 rejected values, but the writer counted none of them, so each new point is paired with the bytes 1024 places earlier;
p == 7matches nothing. - No error: the writer stays open,
CheckIndexis clean and merges keep the wrong values. Every later point ofpin that in-memory segment is shifted until the segment flushes.
Applications that use the experimental column API (10.5.0 and later) with a dense points column of more than one 4 KiB chunk (1025 ints, 513 longs) and keep indexing after a rejected batch; default config otherwise. Point queries on later documents silently return wrong results. Rare: the batch must fail after its first chunk.
Mechanism, terms and numbers783 words
IndexWriter#addBatch copies a dense points column (a LongColumn with points, or a BinaryColumn with point dimensions) into the field's in-memory points buffer one 4 KiB chunk at a time, and counts the copied points only after the last chunk. If the batch fails after the first chunk, because the application's cursor throws or because Lucene's own width check rejects a value, Lucene rejects the batch as a non-aborting failure and keeps the writer open, but the copied bytes stay in the buffer uncounted. Every later point of that field in the same in-memory segment is then read back with the value written k places earlier (k = the values left behind; with one point per document, the first k later documents get the rejected batch's values): in the repro, 3 documents added with p = 7, 8, 9 after a rejected 1025-value batch read back 1000, 1001, 1002. Nothing reports it: CheckIndex is clean and merges keep the wrong values. The same failure inside the first chunk leaves no point bytes behind, and the later documents keep their values. It shipped with the experimental column API in 10.5.0.
- Column API.
IndexWriter#addBatch(ColumnBatch)(@lucene.experimental, since 10.5.0) indexes a batch of documents field by field instead of document by document. A dense column has one value per document of the batch and hands its values over through a values cursor (LongValuesCursor,BytesRefValuesCursor). - Points buffer. While a segment is in memory,
PointValuesWriterkeeps, per points field, the packed point bytes in one append-only buffer and the doc ID of each point in a parallel array; point i of the buffer belongs to doc ID i of the array.numPointssays how many entries are valid. - Non-aborting exception. A failure that only rejects the current document or batch: its documents are marked deleted and the in-memory segment stays in use. The
DocumentsWriterjavadoc promises that the partial updates such a failure leaves "are consistent".
- A dense
LongColumnwith points goes toaddDense1DIntValuesoraddDense1DLongValues, a denseBinaryColumnwith point dimensions toaddDenseNDValues(IndexingChain.java:1094-1103,:1215-1220). - Each method writes the batch's doc IDs into the array (
reserveDenseRange,:173-185) but leavesnumPointsunchanged. - Its loop fills one chunk from the cursor and appends it to the buffer at once (
fillIntPointsthenbytesOut.writeBytes,:113-118; long:131-136; N-D:150-155). A chunk is the 4 KiB shared scratch (SharedIndexingScratch.java:33): 1024 ints, 512 longs or 4096/width N-D values. - Only after the loop does
commitDenseRangeadvancenumPoints,numDocsandlastDocIDand count the bytes in the RAM counter (:187-192). There is notry/finally. - The cursor throws while filling chunk 2: the application's cursor fails, or Lucene's default
BytesRefValuesCursor#fillPackedPoints, which "validates each length", throwsIllegalArgumentException: dense point value has length=3 but should be 4(BytesRefValuesCursor.java:67-80). The 1024 values of chunk 1 stay in the buffer;numPointsis still 0. DocumentsWriterPerThread.updateBatchtreats it as non-aborting: it marks the 1025 documents deleted and keeps the in-memory segment (DocumentsWriterPerThread.java:342-355).- The next document with p = 7 appends its 4 bytes after the 1024 orphaned values (
:93) but records its doc ID at array positionnumPoints= 0 (:95). At flush, point i gets docdocIDs[i]and the bytes at offset i × 4 (:242-250): the new document gets 1000, the next ones 1001 and 1002, and the bytes of 7, 8 and 9 are never read.
With k orphaned values, the j-th later point of the field reads the value at buffer position j: the first k later points get the rejected batch's values in order (the first k later documents, with one point per document as in the repro), later ones the value of the point k earlier; a second rejected batch before the flush adds its own left-over values, so k grows (read from the code, not executed). In the repro k = 1024 and 3 documents follow: [7, 8, 9] reads back as [1000, 1001, 1002]. The threshold is one value more than a chunk: 1025 int, 513 long or 4096/width + 1 N-D values. Points indexed before the failed batch are unaffected, and the damage ends when the segment flushes. Side effect: the orphaned bytes are missing from the RAM counter until that flush (a probe with 20,000 values of 128 bytes: 2,555,904 point bytes kept per rejected batch, while ramBytesUsed grew by 185,624, 92,808 and 92,816 bytes over three rejected batches, each measured after one small successful document because the failed update does not refresh the counter).
Exposure and likelihood304 words
- Who is exposed. Users of the experimental
IndexWriter#addBatch(andupdateDocuments(Term|Query, ColumnBatch), which share the code) with a DENSELongColumnthat indexes points (INT, FLOAT, LONG, DOUBLE) or a DENSEBinaryColumnwith point dimensions, in 10.5.0, 10.5.1, 10.5.2, 10.6.0 (by reading) and main. - Default or opt-in. The column API is opt-in; nothing else is:
new IndexWriterConfig()with only the codec set, to the production default codec, and the default directory reproduce it, with assertions on and off. - What it takes. More values than one chunk (1025 4-byte, 513 8-byte or 4096/width + 1 N-D values; ordinary batch sizes: the API author's motivating workload was batches of 1000), a failure at or after the first chunk boundary (a throwing cursor or a wrong-width value), and more points of the same field added to the same in-memory segment before it flushes.
- What breaks. Exact and range queries on the field, and any filter built on them, match the wrong documents. Their doc values keep the right values, so points and doc values disagree: a probe matched 5 later documents indexed with
level = 5withIntPoint.newRangeQuery("level", 0, 3)while their doc values said 5. - Silent and lasting. No tragic exception, the writer stays open,
CheckIndexis clean, andforceMerge(1)keeps the wrong values. - Not affected. A failure inside the first chunk; documents added after a
commit()that followed the failure (they go to a new segment); the sparse points path; the row API (addDocument) with the same bad value. - How likely. Rare. Real callers usually build and validate point bytes before the call; the only downstream adopter found keeps this path behind an off-by-default flag and validates values first. With concurrent indexing threads, a
commit()after the failure is not a full guard (another thread may add to the same segment first; not executed).
The test shows that when IndexWriter#addBatch rejects a 1025-value dense points BinaryColumn because the last value is 3 bytes instead of 4, the first chunk's 1024 point values stay in the in-memory points buffer, so a document added next gets the rejected batch's value.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.IntPoint;
import org.apache.lucene.document.column.BinaryColumn;
import org.apache.lucene.document.column.BytesRefValuesCursor;
import org.apache.lucene.document.column.Column;
import org.apache.lucene.document.column.ColumnBatch;
import org.apache.lucene.document.column.ObjectTupleCursor;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.BytesRef;

public class TestRejectedDensePointsBatch extends LuceneTestCase {

  public void testRejectedBatchLeavesNoPointValues() throws Exception {
    int numDocs = 1025;
    FieldType type = new FieldType();
    type.setDimensions(1, Integer.BYTES);
    type.freeze();
    BinaryColumn column =
        new BinaryColumn("p", type, Column.Density.DENSE) {
          BytesRef bytes(int i) {
            return i < numDocs - 1 ? IntPoint.pack(1000) : new BytesRef(new byte[3]);
          }

          @Override
          public ObjectTupleCursor<BytesRef> tuples() {
            return new ObjectTupleCursor<>() {
              int doc = -1;

              @Override
              public int nextDoc() {
                return ++doc < numDocs ? doc : DocIdSetIterator.NO_MORE_DOCS;
              }

              @Override
              public BytesRef value() {
                return bytes(doc);
              }
            };
          }

          @Override
          public BytesRefValuesCursor values() {
            return new BytesRefValuesCursor(numDocs) {
              int i = 0;

              @Override
              public BytesRef nextValue() {
                return bytes(i++);
              }
            };
          }
        };
    ColumnBatch batch =
        new ColumnBatch() {
          @Override
          public int numDocs() {
            return numDocs;
          }

          @Override
          public Iterable<Column> columns() {
            return List.of(column);
          }
        };
    IndexWriterConfig iwc = new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec());
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      expectThrows(IllegalArgumentException.class, () -> w.addBatch(batch));
      Document doc = new Document();
      doc.add(new IntPoint("p", 7));
      w.addDocument(doc);
      try (DirectoryReader r = DirectoryReader.open(w)) {
        IndexSearcher s = new IndexSearcher(r);
        assertEquals(
            "live docs matching p=7, p=1000",
            List.of(1, 0),
            List.of(
                s.count(IntPoint.newExactQuery("p", 7)), s.count(IntPoint.newExactQuery("p", 1000))));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-101/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestRejectedDensePointsBatch
- Expected vs actual
- Expected the only live document (added with
IntPointp=7) to match p=7 and not p=1000; actual:live docs matching p=7, p=1000 expected:<[1, 0]> but was:<[0, 1]>, with-eaand-da.
More files, environment, full output40 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: live docs matching p=7, p=1000 expected:<[1, 0]> but was:<[0, 1]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
org.apache.lucene.index.TestRejectedDensePointsBatch.testRejectedBatchLeavesNoPointValues(TestRejectedDensePointsBatch.java:99)- The same API documents the rule for dense vectors: a cursor may throw, and "the writer must remain in a consistent state" (
KnnFieldVectorsWriter.java:46-50). - Lucene's own width check rejects the value as a non-aborting failure, whose partial updates must be "consistent" (
DocumentsWriter.java:76-79). - The outcome flips between 1024 and 1025 values, an internal buffer size.
The full argument329 words
- The rule is written down for the API's dense vectors writer.
KnnFieldVectorsWriter#addDenseValues, merged ina9779ef3c193(#16734): "The cursor may throw while it is being consumed, for example when a vector fails validation. In that case the documents of the whole batch are marked as deleted, but the writer must remain in a consistent state: every doc ID it has recorded must have its vector. ... record doc IDs and vectors only afterfillhas returned." (KnnFieldVectorsWriter.java:46-50). The flat vectors writer follows it (Lucene99FlatVectorsWriter.java:507-531), andtestDenseVectorValidationFailureRecoverskeeps the failed and the recovery batch in one segment "so flush checks that the vectors writer was left consistent" (TestColumnBatchIndexing.java:886-922). It is written for vectors; for points it is a strong analogy, not a documented contract. The dense numeric doc-values writers break it too (LFV-097). - Non-aborting failures must leave consistent state.
DocumentsWriter: non-aborting exceptions "can still partially update the index structures. These updates are consistent" and the document is marked deleted (DocumentsWriter.java:76-79);IndexWriter#addDocument: after an exception "the index will be consistent" (IndexWriter.java:1465); #16270 alignedupdateBatch's exception handling withupdateDocuments. - Lucene raises the failure itself. The default
fillPackedPoints"validates each length" and throws (BytesRefValuesCursor.java:67-80); the sparse path checks before writing (PointValuesWriter.java:78-86), and the row API rejects the same 3-byte value cleanly. - Upstream tests inject throwing dense cursors.
ThrowingDenseLongColumn(ColumnBatchTestUtil.java:642-701) andtestLongValuesCursorThrowMidBatchRecovers(TestColumnBatchIndexing.java:740-792) assert recovery; they miss this because they use doc-values fields, 6-document batches and acommit()before the recovery documents. - Sibling code keeps alignment.
SortedDocValuesWriter.addDenseOrdinalValuescommits only the processed values in afinallyblock (SortedDocValuesWriter.java:168-182). - Buffer-size dependent. A bad last value in a 1024-value batch recovers; in a 1025-value batch it corrupts the next documents. Before #16227 the chunk was 1 KiB, and 129 long values sufficed.
- No document accepts it. No javadoc, CHANGES or MIGRATE entry, test or issue describes poisoned same-segment state after a rejected batch.
The devil's-advocate check239 words
The strongest case for "not a bug" (the cross-model reviews, an independent reviewer from another model family, OpenAI GPT-5.6, voted "not real" on it): both triggers break documented cursor preconditions. The cursor "produces exactly size() values" (LongValuesCursor.java:22, BytesRefValuesCursor.java:22), BinaryColumn callers are "responsible for producing sort-encoded bytes of the correct total length" (BinaryColumn.java:28-29), addBatch is @lucene.experimental and, unlike addDocuments, does not point to addDocument's consistency note (IndexWriter.java:1528-1539 vs :1510-1511), and #16227 chose the 4 KiB staging for throughput.
Why it fails: Lucene checks the width itself and turns it into a non-aborting rejection, so it must leave the writer consistent; the vectors writer of the same API now documents that a cursor may throw and the writer must stay consistent; upstream's own tests inject throwing dense cursors; the damage lands on later, valid documents, not on the rejected batch; and the fix keeps the 4 KiB staging. The reviews agreed on the root cause and that the fix removes it, and the intended-lens review recommended that maintainers accept the fix; the independent reproducer, the devil's-advocate verifier and the adjudication rejected the argument. The rebuttal is not airtight: Lucene checking the width does not make a malformed value valid input, and the vectors rule is an analogy for points, not a documented points or addBatch contract. Verdict: not intended in the adjudication's and the verifiers' view; expect "hardening" as a possible label.
Recommended Commit the values already written, in a finally block (validated)
In the three dense methods of PointValuesWriter, count the values whose bytes were appended and commit that many doc IDs in a finally block, as SortedDocValuesWriter.addDenseOrdinalValues does (+39/-21). The test, 11 closest suites and all 8,892 tests of :lucene:core:test pass with it.
int written = 0;
try {
  while (written < size) {
    int chunk = Math.min(POINTS_BUFFER_INT_VALUES, size - written);
    cursor.fillIntPoints(buffer, 0, chunk);
    bytesOut.writeBytes(buffer, 0, chunk * Integer.BYTES);
    written += chunk;
  }
} finally {
  // keep docIDs aligned with the bytes already written, even if the cursor threw
  if (written > 0) {
    commitDenseRange(firstDocID, written, ramBefore);
  }
}
All options and trade-offs4 options · 489 words
One fix was built and validated (option A); options B to D are alternatives that were not run.
In addDense1DIntValues, addDense1DLongValues and addDenseNDValues, count the values whose bytes were appended and commit that many doc IDs even when the cursor throws, as SortedDocValuesWriter.addDenseOrdinalValues does. The failed batch's documents are deleted anyway. The same change in all three methods, +39/-21 lines; applies with git apply on a9779ef3c193.
int written = 0;
try {
  while (written < size) {
    int chunk = Math.min(POINTS_BUFFER_INT_VALUES, size - written);
    cursor.fillIntPoints(buffer, 0, chunk);
    bytesOut.writeBytes(buffer, 0, chunk * Integer.BYTES);
    written += chunk;
  }
} finally {
  // keep docIDs aligned with the bytes already written, even if the cursor threw
  if (written > 0) {
    commitDenseRange(firstDocID, written, ramBefore);
  }
}
Trade-offs
- Keeps the 4 KiB staging and one
writeBytesper chunk; also closes the RAM-accounting gap, because the written bytes are counted. - The deleted documents of the failed batch keep up to
writtenpoint values until a merge drops them (or until the flush drops the segment, if all its documents are deleted), like the points of any deleted document; that segment's point statistics (count, min/max) include them. - No benchmark was run; the change adds one
try/finallyper call, not per chunk.
What the checks validated
- Gradle, scratch worktree of
a9779ef3c193(removed afterwards), 2026-10-27, seed DEADBEEF: the paste-ready test passes with assertions on and off (3 tests, 0 failures; stock: 2 failures). - 11 closest suites (
org.apache.lucene.document.column.*,TestColumnBatchIndexing,TestPointValues,TestPointQueries,TestIndexWriterExceptions,TestIndexWriterExceptions2): 296 tests, 0 failures, 5 skipped, assertions on and off (the same on stock, assertions on). :lucene:core:check -x testwith the test file passes; all of:lucene:core:test: 749 classes, 8,892 tests, 0 failures, 0 errors, 322 skipped.- Earlier, on the jar: the finder's repro, the independent reproducer's 5 tests, the intended-lens reviewer's 2 recovery-contract tests and 15 existing dense-points and recovery tests, and the security probe all pass with it; the same fix at the introducing commit
3d8956815579passes.
Fill all values into a temporary buffer and append once, after the cursor has returned.
Trade-offs
Atomic, but needs size * width extra heap per call and undoes the 4 KiB staging of #16227. Not run.
Remember the buffer position before the loop and truncate to it in a catch.
Trade-offs
bytesOut is a PagedBytes.PagedBytesDataOutput, which can only append (writeByte, writeBytes) and report getPosition (PagedBytes.java:376-428); neither it nor PagedBytes can truncate or rewind the written bytes (only the read-side PagedBytesDataInput has setPosition, :321), so it needs a new method. Not run.
Abort the in-memory segment instead of rejecting only the batch.
Trade-offs
Discards every document buffered since the last flush, far more than the rejected batch. Not recommended; not run.
Not a security issue (it needs invalid input to an experimental low-level API), but a service that filters on a point field, such as a visibility level, would mis-filter documents indexed after another caller's rejected batch in the same segment.
Semi-formal: while writing a Z3 model of the failure atomicity of addBatch's dense column writers, the finder read the gap from the code; the model reported it violated for 4-, 8-, 16- and 32-byte points, and a failure-injection sweep on the real jar hit every dense points mode and never the sparse path.
The method in full158 words
Method: an SMT (Z3) model of the dense column-pass writers, then failure injection on the jar (semi-formal: the hypothesis came from code reading while modelling).
- The hunt unit modelled the column-pass writers of
addBatch(model/dense_commit.py). Obligation W2, "dense points failure-atomic", is VIOLATED for point widths 4, 8, 16 and 32 bytes; the smallest batch is one chunk plus one value (1025, 513, 257 and 129 values), leaving 1024, 512, 256 and 128 orphan values. - A failure-injection sweep on the stock jar (
harness/FailureInjectionSweep.java, 605 grid points per mode, assertions on and off) found violations in every dense points mode: dense binary 16-byte points with a throwing cursor 168 and with a wrong-length value 168, dense long INT points 18, dense long LONG points 78; the sparse long points control 0. - The finder turned it into a JUnit on the stock jar; an independent reproducer, cross-model reviewers and a devil's-advocate verifier then wrote their own tests.
No prior report found: 232 queries and reads over GitHub, the mailing lists, JIRA, downstream projects and the web, all 412 open PRs and 21 column-API review threads (2026-10-26), refreshed on 2026-10-27. Closest: #16734, which writes the same rule for dense vectors only.
Searches5 searches
No issue, PR, review comment, list post, JIRA entry or downstream report describes this bug, and no open PR touches the dense points methods. Related items are in the table; none is this bug.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repositories, the web | 2026-10-26 | a scripted prior-report search, 4 runs: 56 issue/PR, 6 commit, 4 downstream and 14 web queries (PointValuesWriter, addDense1DIntValues, addDense1DLongValues, addDenseNDValues, commitDenseRange, fillPackedPoints, addBatch / updateBatch failure phrasings, ThrowMidBatchRecovers, ThrowingDenseLongColumn); 68 manual gh, GitHub API and list reads, including Elasticsearch, OpenSearch and Solr | no report; top hits are the introducing PRs #15990 and #16227 |
| Open apache/lucene PRs and column-API review threads | 2026-10-26 | changed files of all 412 open PRs; the review threads of 21 column-API PRs read directly (GitHub search does not index review comments) | #12658 and #486 touch PointValuesWriter in unrelated flush-time code; #16734 (then open, merged 2026-10-26) states the consistency rule for dense vectors only |
| Mailing lists (dev@, java-user@, issues@, commits@, builds@) and the JIRA archive | 2026-10-26 | 76 list queries and 8 JIRA queries; the 9-mail dev@ design thread for the column API; snippets of all 888 builds@ mails since 2026-05-14 | the design thread does not discuss failures; builds@ column-test failures are unrelated flakes; JIRA hits are old points issues |
| Refresh (GitHub) | 2026-10-27 | 9 gh searches (addBatch, ColumnBatch, column batch, PointValuesWriter, addDenseNDValues, commitDenseRange and three phrasings) and every issue and PR created since 2026-10-25; re-run later that day and saved: the same 9 searches, the 13 issues and PRs created since 2026-10-25, upstream HEAD a95c754ee003 and the last PointValuesWriter commit | nothing new; upstream PointValuesWriter unchanged since #16387 (2026-07-14) |
| Related items (read) | 2026-10-26 | the PRs and issues named here | #16209 (closed competing dense N-D points PR, same loop), #16101 (the try/finally the fix copies), #16270, and #7049 / LUCENE-5987, #7111 / LUCENE-6049, #10080 / LUCENE-9037 (the same bug class in other code, fixed) |
Introduced by #15990 (3d8956815579, merged 2026-05-14), the experimental column API; #16227 (8a77a334aea5) copied it into the N-D path and raised the chunk to 4 KiB. First released in 10.5.0; 10.5.0 to 10.5.2 and main fail; earlier releases have no column API.
Versions tested7 rows
Introduced by 3d8956815579 (#15990 "Add experimental columnar indexing api", by Tim-Brooks, merged 2026-05-14; branch_10x backport 3ec3bff01b1, #16066), which added the 1-D dense points methods with the write-in-loop, count-after-loop structure. Extended by 8a77a334aea5 (#16227 "Add dense indexing path for BinaryColumn", merged 2026-06-12; cherry-pick 7a0042427ff): the same structure in addDenseNDValues, the throwing default width check, and the chunk raised from 1 KiB to 4 KiB. Neither PR discusses a failure part-way. First release 10.5.0 (2026-06-25). branch_10x, branch_10_6 and branch_10_5 have the same code (read only). Not fixed. The commit-level runs used plain javac builds of those commits; the release and main runs back the version range on their own.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193, ea57360912ed | affected | this doc's test: 3 run / 2 fail, assertions on and off; the finder's repro 2 of 2 fail |
| 10.5.0, 10.5.2 | affected | this doc's test 3 run / 2 fail; the finder's repro 2 of 2 fail (-ea and -da); the independent reproducer 5 run / 3 fail |
| 10.5.1 | affected | this doc's test 3 run / 2 fail (-ea); the finder's repro 2 of 2 fail |
8a77a334aea5 (#16227) | bisect | the finder's repro 2 of 2 fail; long variant fails at 513 values only (4 KiB chunk) |
3d8956815579 (#15990), 7c587afd540 | bisect | long variant fails at 513 and 129 values, passes at 128 (1 KiB chunk); the binary path still validated first and recovered |
227255fdb08 (parent of #15990), 10.4.0, 9.12.3 | not affected | no column API; the repro does not compile |
main + fix A; 3d8956815579 + the same fix | not affected | passes |
Confirmed by an adjudication (high confidence) after an independent reproducer (real), an intended-behaviour devil's advocate (real) and cross-model reviews (OpenAI GPT-5.6), which reproduced it with their own tests and agreed on the cause and the fix but voted "not real" on contract scope; a credibility audit kept it.
Checks and verdicts338 words
Every check ran Java on main and reproduced the behaviour; the disagreement is only about whether the API promises recovery after invalid input.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own public-API tests outside the Lucene packages: 5 run / 3 fail on main (-ea, -da), 10.5.0 and 10.5.2 (int, long, 2-D binary); both controls pass; CheckIndex clean; wrong values survive forceMerge(1); the finder's fix makes all 5 pass. |
| Refute review (OpenAI GPT-5.6) | reproduced; not real on contract scope (high) | Its own 1025-int test fails on main with -ea and -da (the in-first-chunk control passes) and passes with the fix; agrees on the root cause; argues both triggers break cursor preconditions. |
| Intended-lens review (OpenAI GPT-5.6) | reproduced; not real on contract scope (medium) | Reproduced with a fully default config on main and 10.5.2; its recovery-contract tests fail on main and pass with the fix, as do 15 existing dense-points and recovery tests; recommends that maintainers accept the fix. |
| Intended-behaviour devil's advocate | real | No intended argument survives; controls: the row API and a 1024-value batch recover, a 1025-value batch corrupts the next document. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's tests at a new seed (5 run / 3 fail, -ea and -da); the contract-scope argument judged substantive but not convincing; impact class data corruption. |
| This doc's re-run | reproduced | The paste-ready test through gradle on a9779ef3c193 (3 run / 2 fail, -ea and -da) and through the harness on 10.5.0, 10.5.1 and 10.5.2; the fix validated (see Suggested fix). |
| Fact checks of this doc (2026-10-27) | bug confirmed; wording fixed | An independent fact check (re-ran the test on main -ea/-da, on 10.5.2 and with the fix: 3 run / 2 fail, and 3 run / 0 fail), a cross-model fact check (OpenAI GPT-5.6, read-only) and a diagram check all confirmed the bug, the repro and the fix. Their wording errors (a line count, the diagram caption, the 'one dense writer' sentence and five smaller ones) are fixed;. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 529 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,505 words
- Registry title
- When IndexWriter#addBatch fails part-way through a dense points column, the point bytes it already copied stay in the points buffer, so documents added later to the same in-memory segment are silently indexed with the rejected batch's point values
- Area
- index / columnar addBatch (dense points, PointValuesWriter)
- Priority
- Medium, rank 151: An addBatch error-path bug for dense points columns, silently giving later documents in the segment the rejected batch's point values, but callers usually validate point bytes before the call.
- Impact class
- data corruption
- Impact note
- Hits only applications that call the experimental IndexWriter#addBatch (first released in 10.5.0) with a DENSE LongColumn or BinaryColumn that indexes points and holds more values than one 4 KiB staging chunk (at least 1025 4-byte, 513 8-byte or 4096/width + 1 N-D values), and whose batch then fails after the first chunk (a wrong-width value rejected by Lucene's own check, or an exception from the application's own cursor); default IndexWriterConfig, codec and directory, with -ea and -da, ordinary scale; the rejection looks clean (the writer stays open, no tragic exception), but every later point of that field added to the same in-memory segment before it flushes is indexed with a shifted value, the first ones with the rejected batch's values, CheckIndex does not detect it and merges keep it; the only downstream user found keeps this path behind an off-by-default flag and validates values first.
- Summary
- You add a batch with IndexWriter#addBatch whose dense points column (a LongColumn, or a BinaryColumn with point dimensions) has more values than fit in one 4 KiB chunk, and the batch fails after the first chunk, because Lucene's own length check rejects a value of the wrong width or because your cursor throws; Lucene rejects the batch with a non-aborting exception, the writer stays open, and you keep indexing. You expect the rejected batch to leave no trace, as Lucene promises for non-aborting exceptions and as its own ThrowMidBatchRecovers tests assert, so a document you add next with IntPoint p=7 matches p == 7. Instead the dense path had already copied the first chunk's point bytes into the field's buffer without recording doc IDs for them, so the next document is paired with the rejected batch's first value (the only live document, added with p=7, matches p == 1000 instead), every later point of that field in the segment is shifted, CheckIndex stays clean and the wrong values survive merges.
- Introduced
- 3d8956815579 (#15990 'Add experimental columnar indexing api', main, merged 2026-05-14; branch_10x backport 3ec3bff01b1 via #16066), which added PointValuesWriter.addDense1DIntValues / addDense1DLongValues with each staged chunk written inside the loop and numPoints / numDocs / lastDocID advanced only after it, with no try/finally; 8a77a334aea5 (#16227 'Add dense indexing path for BinaryColumn', merged 2026-06-12; branch_10x cherry-pick 7a0042427ff) copied the structure into addDenseNDValues, added the default BytesRefValuesCursor#fillPackedPoints length check that throws part-way, and raised the chunk from 1 KiB to 4 KiB [read: git blame, git log -L and git show in the full-history clone; exec: a LongColumn variant fails at 3d8956815579 and at 7c587afd540 (parent of #16227), the candidate repro fails at 8a77a334aea5, and the parent 227255fdb08 has no column API (compile error); commit-level jars are javac builds, not gradle builds] (2026-05-14 (#15990, LongColumn variant); 2026-06-12 (#16227, BinaryColumn variant))
- First affected version
- 10.5.0 [exec]
- Affected versions
- 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed [exec: the candidate repro fails 2 of 2 on each with -ea, and with -da on 10.5.0, 10.5.2 and main; the independent reproduction's tests fail 3 of 5 on 10.5.0 (-ea) and 10.5.2 (-ea and -da); the intended-behaviour check's run fails on 10.5.2]; main since 3d8956815579 (2026-05-14) [exec at 3d8956815579, 7c587afd540, 8a77a334aea5 and ea57360912ed; before 8a77a334aea5, never released, only the LongColumn variant existed and the chunk was 1 KiB, so 129 long values sufficed]; branch_10x, branch_10_6 (10.6.0, released 2026-10-29) and branch_10_5 have the same dense-path code [read: read-only GitHub API check, 2026-10-26]; not applicable: 10.4.0 and every earlier release, including 9.12.3 (no column API; the repro does not compile) [exec]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3, code reading
- Upstream and prior reports
- none found (2026-10-26, read-only, 232 queries and reads: a scripted prior-report search 164 (56 GitHub issue/PR, 6 commit, 4 downstream-repo, 76 mailing-list over dev@, java-user@, issues@, commits@ and builds@, 8 JIRA-archive, 14 web) plus 68 manual gh, GitHub API and lists.apache.org reads, including Elasticsearch, OpenSearch and Solr; the changed-file lists of all 412 open PRs; the review threads of 21 column-API PRs; the 9-mail dev@ design thread; all 888 builds@ mails since 2026-05-14 by snippet; plus the finder's 21-query run and the independent reproduction's and the intended-behaviour check's searches); related prior items, none of them this bug: #15990 and #16227 (introduced it; no review discussion of a failure part-way), #16734 (merged 2026-10-26 as a9779ef3c19; on main and branch_11x, not on branch_10_6; states the same 'record doc IDs only after fill has returned' rule for the dense vector path, added at a committer's review request; does not touch PointValuesWriter), #16209 (closed competing dense N-D points PR with the same loop), #16101 (SortedDocValuesWriter.addDenseOrdinalValues try/finally, the pattern the fix copies), #16270, and #7049 / LUCENE-5987, #7111 / LUCENE-6049, #10080 / LUCENE-9037 (same bug class in other code); no open PR touches the dense points methods; the minimal repro still fails on main e1faeba08bd (2026-11-02, -ea and -da)
- Lucene commit tested
- main
a9779ef3c193(2026-10-26): the 3-test JUnit through gradle with assertions on and off (the 2 bug tests fail, the control passes) and through the repro harness; 10.5.0, 10.5.1 and 10.5.2 through the harness (3 run / 2 fail each). Earlier: the finder's repro on mainea57360912ed, 10.5.0, 10.5.1, 10.5.2 and the introducing commits; an independent reproducer's public-API tests on main, 10.5.0 and 10.5.2. The recommended fix was validated through gradle in a scratch worktree ofa9779ef3c193.
- Finding record
lucene/core/src/java/org/apache/lucene/index/PointValuesWriter.java:73-101 (addPackedValue validates the length before it writes), :104-157 (the three dense methods: bytesOut.writeBytes inside the loops at :116, :134, :153; commitDenseRange after them at :119, :137, :156), :173-185 (reserveDenseRange writes docIDs without advancing numPoints), :187-192 (commitDenseRange), :242-250 (flush: getDocID(i) = docIDs[ords[i]], getValue reads offset packedBytesLength * ords[i])lucene/core/src/java/org/apache/lucene/index/SharedIndexingScratch.java:33 (BYTES_SCRATCH_SIZE = 4 * 1024)lucene/core/src/java/org/apache/lucene/document/column/BytesRefValuesCursor.java:22 ('produces exactly size()' values), :63-80 (default fillPackedPoints 'validates each length' and throws IllegalArgumentException 'dense point value has length=... but should be ...'); LongValuesCursor.java:22; BinaryColumn.java:28-29 ('responsible for producing sort-encoded bytes of the correct total length')lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1092-1100 (dense LongColumn points dispatch to addDense1DIntValues / addDense1DLongValues), :1213-1217 (dense BinaryColumn points dispatch to addDenseNDValues)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:314-358 (updateBatch; deleteLastDocs on a non-aborting exception at :351-353; the DWPT is kept)lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:76-79 (non-aborting exceptions: 'These updates are consistent', the document is marked deleted)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1465 (addDocument: 'the index will be consistent'), :1528-1539 (addBatch, @lucene.experimental)lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:168-182 (addDenseOrdinalValues commits only the processed values in a finally block)lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:290-291 (testDenseColumnCountMismatchThrows: 'use a different field to avoid the partially-written DV entries from the failed batch'), :681, :739, :793, :840 (the four *ThrowMidBatchRecovers tests) and lucene/core/src/test/org/apache/lucene/document/column/ColumnBatchTestUtil.java:566 (ThrowingDenseLongColumn)lucene/CHANGES.txt:895, 904 (GITHUB#15990 and GITHUB#16227 in the 10.5.0 section)SECURITY.md:28, 38, 50 (threat model)
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/PointValuesWriter.java:73-102, :104-157, :173-192, :242-250a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1094-1103, :1215-1220a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/SharedIndexingScratch.java:33a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/document/column/BytesRefValuesCursor.java:67-80a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:314-358a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:76-79
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/codecs/KnnFieldVectorsWriter.java:46-50a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99FlatVectorsWriter.java:507-531a Lucene main checkout (a9779ef3c193) lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:740-792, :886-922, :291-292a Lucene main checkout (a9779ef3c193) lucene/core/src/test/org/apache/lucene/document/column/ColumnBatchTestUtil.java:642-701a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:76-79; IndexWriter.java:1465, :1510-1511, :1528-1539a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/document/column/LongValuesCursor.java:22; BytesRefValuesCursor.java:22, :67-80; BinaryColumn.java:28-29a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:168-182
- Suggested fix
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/util/PagedBytes.java:299-321 (PagedBytesDataInput, setPosition), :376-428 (PagedBytesDataOutput: writeByte, writeBytes, getPosition only)a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/SortedDocValuesWriter.java:168-182
- History
a Lucene main checkout (a9779ef3c193) lucene/CHANGES.txt:911, :920 (10.5.0 section, header :881)
- TestRejectedDensePointsBatch.java (JUnit test):
repro/LFV-101/src/org/apache/lucene/index/TestRejectedDensePointsBatch.java(107 lines)
A summary card (bug.png): a 1025-document batch whose dense BinaryColumn p (1-D int points) holds 1000 ... 2023 and then one 3-byte value, which Lucene's width check rejects with IllegalArgumentException, followed by ONE document with p = 7 (doc 1025: its ID in slot 0, its value in slot 1024). Expected count(p == 7) = 1, count(p == 1000) = 0; executed: count(p == 7) = 0, count(p == 1000) = 1. This is the input of testWrongLengthValueAfterFirstChunk with one later document instead of three. Every value on screen was printed by the diagram's own probe JUnit.
assets/LFV-101/bug.png(529 KB)