ICUTokenizersplits text into words with ICU break rules, one rule set per script (Latin, Cyrillic, Thai, ...). Its factory, SPI nameicu, can replace the rules of a script with your own file:rulefiles="Latn:latin.rbbi".- The factory reads each rule file once, when the analyzer is set up (
inform(ResourceLoader)). TheResourceLoaderopens the file (from disk withFilesystemResourceLoader, from the classpath withClasspathResourceLoader) and hands the stream to the factory.
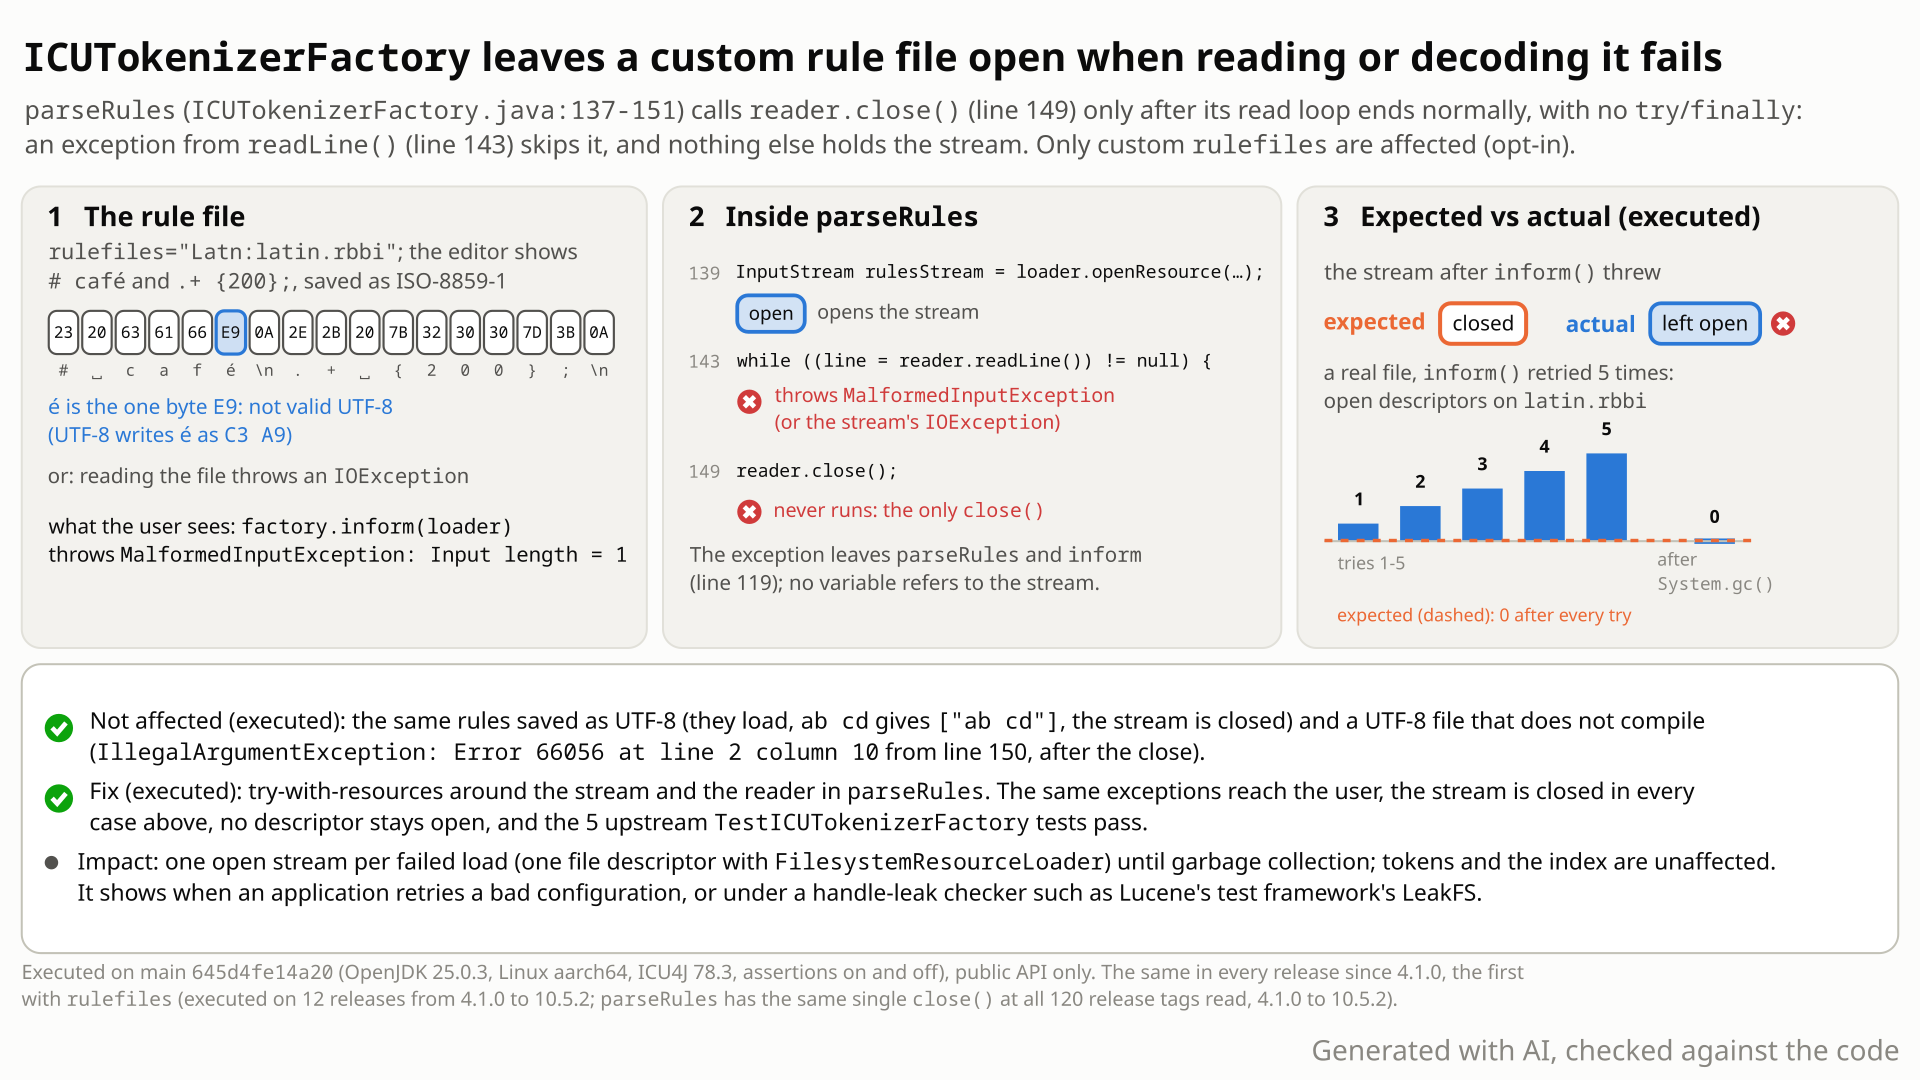
parseRules opens it, readLine() throws on byte E9, the only close() never runs, and each failed try leaves one more descriptor open until GC. Select the still to open it at full size. Generated with AI, checked against the code.- You configure
ICUTokenizerFactorywithrulefiles="Latn:latin.rbbi". The rule file is 17 bytes,# caféand the rule.+ {200};, saved as ISO-8859-1, soéis the single byte0xE9: not valid UTF-8. - You expect
inform()to fail, because Lucene reads rule files with a strict UTF-8 decoder, and to close the file it opened, as it does for a valid file and as Lucene's stopword loader does with the same decoder. - You get
MalformedInputException: Input length = 1, but the stream'sclose()is never called.parseRulescloses the reader only after its read loop ends normally, and the exception jumps past that line. - With a real file on disk, five failed
inform()calls leave 5 file descriptors open (1, 2, 3, 4, 5 after each try) untilSystem.gc()brings the count back to 0; Lucene's test filesystem reportsfile handle leaks. An I/O error during the read leaks the same way.
Only applications that set rulefiles (custom per-script ICU rules), directly, through CustomAnalyzer or a search-server schema, and whose rule file cannot be read to the end: a file saved in a legacy encoding such as ISO-8859-1 with a non-ASCII character, or an I/O error. Each failed load leaves one stream open until GC. Tokens and the index are unaffected.
Mechanism, terms and numbers562 words
ICUTokenizerFactory can load custom ICU break rules per script from files (rulefiles="Latn:latin.rbbi"). In inform(), parseRules opens each file through the ResourceLoader, reads it line by line through Lucene's strict UTF-8 decoding reader, and calls reader.close() only after the read loop has finished normally. When the file is not valid UTF-8 (for example saved as ISO-8859-1 with é in a comment) or the stream throws an IOException mid-read, inform() fails with that exception, as it should, but the close is skipped and the stream stays open until it is garbage-collected. With FilesystemResourceLoader that is an open file handle, which Lucene's own LeakFS test filesystem reports as a leak. The default configuration (no rulefiles) opens no rule file through the ResourceLoader, a rule file that decodes but does not compile is closed before compiling, and tokens and the index are unaffected. It has been there since rulefiles arrived in 4.1.0; a try-with-resources around the stream and the reader fixes it.
rulefiles: a comma-separated list ofcode:rulefilepairs, a four-letter ISO 15924 script code and a resource path, each compiled by ICU'sRuleBasedBreakIterator(class javadoc,ICUTokenizerFactory.java:49-66at645d4fe14a20).- Decoding reader:
IOUtils.getDecodingReader(stream, UTF_8)reports malformed input instead of replacing it (CodingErrorAction.REPORT,IOUtils.java:192-199); its javadoc says it is "useful to load configuration files, stopword lists or synonym files to detect character set problems".
inform()callsparseRules(resourcePath, loader)once per pair (ICUTokenizerFactory.java:116-120, call at:119); withoutrulefilesit opens nothing through theResourceLoader(:111-112; the bundledDefault.brkandMyanmarSyllable.brkcome from the jar, read once byDefaultICUTokenizerConfig's static initializer,DefaultICUTokenizerConfig.java:81-84,:144-153).parseRulesopens the stream (loader.openResource(filename),:139), wraps it in aBufferedReaderover the decoding reader (:140-141), reads line by line (:143-148) and callsreader.close()at:149, with notry/finally. It then compiles the rules (:150).- A byte that is not valid UTF-8 makes
readLine()throwMalformedInputException; a failing stream makes it throwIOException. Either leaves the method before:149. - Within Lucene,
parseRulesis the only holder of the stream andinform()returns nothing, so no Lucene code can close it later (the stockFilesystemResourceLoaderandClasspathResourceLoaderkeep no reference either). What it holds is released only if the stream's own cleanup runs when the garbage collector reclaims it: for a real file, the probe saw the descriptor released after a forcedSystem.gc(). With several pairs, the files read before the failing one were already closed at:149; only the failing stream stays open.
| rule file | inform() | stream |
|---|---|---|
# café / .+ {200}; as UTF-8 (control) | succeeds | closed |
the same 17 bytes as ISO-8859-1 (é = 0xE9) | MalformedInputException: Input length = 1 | left open |
valid file, stream throws IOException after 8 bytes | IOException | left open |
openResource throws | that exception | none opened |
| valid UTF-8 that does not compile | IllegalArgumentException from ICU | closed (before compiling) |
Fault injection on a 76-byte valid rule file: an IOException at each of the 77 read positions (offsets 0-76) and an 0xFF byte at each of offsets 0-75 all leak (153 of 153), as does a failing second rule file; a failing openResource and a file that does not compile do not. With the fix, 0 of 157 runs leak.
Exposure and likelihood253 words
- Who is hit. Users of the analysis-icu module who opt in to
rulefiles: on the factory directly, throughCustomAnalyzerwith the SPI nameicu, or through a search-server schema (the class javadoc's examples are such schemas). The default factory, withoutrulefiles, opens no rule file through theResourceLoader. - What it takes. A rule file that cannot be read to the end: not valid UTF-8 (a file saved in a legacy encoding such as ISO-8859-1, where one non-ASCII character anywhere, even in a comment, becomes a byte that is not valid UTF-8) or an I/O error while reading. No scale, no unusual parameters; the same with assertions on and off.
- What happens.
inform()fails loudly, as it should, and oneInputStreamper failed load stays open until it is garbage-collected: one file handle withFilesystemResourceLoader, one resource stream withClasspathResourceLoader. An application that keeps retrying a bad configuration leaks one more each time until the next GC: five failed calls on a real file left 1, 2, 3, 4, 5 descriptors open, and 0 only afterSystem.gc()(0 after every call with the fix). Lucene'sLeakFStest filesystem fails a test that does this. - What does not happen. No wrong tokens, no index change, no data exposure. Not measured and not claimed: running out of file descriptors, or an open handle blocking replacement of the file on platforms that lock open files.
- How likely. Rare: no report since 4.1.0, and the leak hides behind the loud setup failure.
One JUnit test on the public API: a ResourceLoader that hands out one 17-byte ISO-8859-1 rule file and records close(). It expects inform() to throw CharacterCodingException and the stream to be closed. Deterministic, single thread; it fails the same way with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.icu.segmentation;

import java.io.ByteArrayInputStream;
import java.io.InputStream;
import java.nio.charset.CharacterCodingException;
import java.nio.charset.StandardCharsets;
import java.util.HashMap;
import java.util.Map;
import java.util.concurrent.atomic.AtomicBoolean;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.ResourceLoader;

public class TestICUTokenizerFactoryRuleFileClosed extends LuceneTestCase {

  public void testRuleFileClosedWhenNotUtf8() throws Exception {
    byte[] latin1 = "# café\n.+ {200};\n".getBytes(StandardCharsets.ISO_8859_1);
    AtomicBoolean closed = new AtomicBoolean();
    ResourceLoader loader =
        new ResourceLoader() {
          @Override
          public InputStream openResource(String resource) {
            return new ByteArrayInputStream(latin1) {
              @Override
              public void close() {
                closed.set(true);
              }
            };
          }

          @Override
          public <T> Class<? extends T> findClass(String cname, Class<T> expectedType) {
            throw new UnsupportedOperationException();
          }
        };
    ICUTokenizerFactory factory =
        new ICUTokenizerFactory(new HashMap<>(Map.of("rulefiles", "Latn:latin.rbbi")));
    expectThrows(CharacterCodingException.class, () -> factory.inform(loader));
    assertTrue(
        "expected inform() to close the rule file stream it opened after failing; actual: left open",
        closed.get());
  }
}
cp $REPRO/src/org/apache/lucene/analysis/icu/segmentation/TestICUTokenizerFactoryRuleFileClosed.java $LUCENE/lucene/analysis/icu/src/test/org/apache/lucene/analysis/icu/segmentation/
cd $LUCENE && ./gradlew :lucene:analysis:icu:test --tests org.apache.lucene.analysis.icu.segmentation.TestICUTokenizerFactoryRuleFileClosed -Ptests.seed=DEADBEEF
# with this seed assertions are on; add -Ptests.asserts=false to turn them off: same result
- Expected
inform()throwsMalformedInputExceptionand closes the rule-file stream it opened.- Observed
inform()throwsMalformedInputException: Input length = 1and the stream is never closed:expected inform() to close the rule file stream it opened after failing; actual: left open.
More files, environment, full output279 words
The test lives in the factory's package only to sit next to TestICUTokenizerFactory; it uses public API only (ICUTokenizerFactory, ResourceLoader). It imports org.apache.lucene.tests.util.LuceneTestCase, so as written it compiles on 9.1.0 and later; older releases were checked with a release-agnostic main() harness. The same test is the suggested regression test.
It checks only the contract-backed behaviour: inform() fails with the decoder's CharacterCodingException (unchanged by the fix) and the stream it opened is closed. The I/O-error variant and the real-file LeakFS test have the same root cause and are left out of the repro.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the test also fails on the 10.6.0, 10.5.2 and 9.1.0 release jars; the bug is in every release from 4.1.0 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 |
cp $REPRO/src/org/apache/lucene/analysis/icu/segmentation/TestICUTokenizerFactoryRuleFileClosed.java $LUCENE/lucene/analysis/icu/src/test/org/apache/lucene/analysis/icu/segmentation/
cd $LUCENE && ./gradlew :lucene:analysis:icu:test --tests org.apache.lucene.analysis.icu.segmentation.TestICUTokenizerFactoryRuleFileClosed -Ptests.seed=DEADBEEF
# with this seed assertions are on; add -Ptests.asserts=false to turn them off: same result
# gradle, main 645d4fe14a20, seed DEADBEEF (assertions on, the seed's default); the same with -Ptests.asserts=false; verbatim excerpt
TestICUTokenizerFactoryRuleFileClosed > testRuleFileClosedWhenNotUtf8 FAILED
    java.lang.AssertionError: expected inform() to close the rule file stream it opened after failing; actual: left open
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:981894AD4EC96D8F]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at junit@4.13.2/org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.analysis.icu.segmentation.TestICUTokenizerFactoryRuleFileClosed.testRuleFileClosedWhenNotUtf8(TestICUTokenizerFactoryRuleFileClosed.java:54)
:lucene:analysis:icu:test (FAILURE): 1 test, 1  failure

# with the fix (assertions on and off)
:lucene:analysis:icu:test (SUCCESS): 1 test

# supporting checks, not part of the repro: a real file under LeakFS (independent reproducer, -ea and -da)
java.lang.RuntimeException: file handle leaks: [InputStream(.../icu-rules-001/latin.rbbi)]

# five inform() calls on a real file: open descriptors on latin.rbbi after each try, then after System.gc()
FD name=malformed loader=FilesystemResourceLoader tries=5 exc=java.nio.charset.MalformedInputException openAfterEachTry=1,2,3,4,5 afterGc=0
FD name=control loader=FilesystemResourceLoader tries=5 exc=none openAfterEachTry=0,0,0,0,0 afterGc=0parseRulesopens the stream and closes it on success; after a failure no Lucene code can close it.- Lucene's stopword loader (the same strict decoder) and the other factory loaders close on failure; OpenNLP's lemma dictionary never closes (a separate bug, LFV-461).
- Upstream fixed the same leak class as bugs: GITHUB#14727 (10.3.0, the same close-only-on-success pattern), LUCENE-7547 and LUCENE-8188.
The full argument318 words
- Ownership.
parseRulesopens the stream (ICUTokenizerFactory.java:139), is the only Lucene code that holds it and closes it after a successful read (:149). As Uwe Schindler put it on LUCENE-4165 (#5237): "of course we close streams, but only if we open them". Here Lucene opens it. - A designed failure path.
IOUtils.getDecodingReaderreports charset problems on purpose: "Decoding readers are useful to load configuration files, stopword lists or synonym files to detect character set problems" (IOUtils.java:185-186). A rule file in the wrong charset is an expected outcome of the readerparseRuleschose. - The sibling loaders close on failure, with one known exception.
WordlistLoader.getLines(the stopword loader, the same decoding reader, try-with-resources atWordlistLoader.java:297-299),AbstractAnalysisFactory.getSnowballWordSet(:322),JapaneseTokenizerFactory(:144), the Korean, Morfologik, Word2Vec, Hunspell and hyphenation factories, and the six OpenNLP model loaders. The exception is OpenNLP's lemma dictionary:OpenNLPOpsFactory.getLemmatizerDictionaryhands the stream to OpenNLP'sDictionaryLemmatizer(OpenNLPOpsFactory.java:162), which never closes it, on success or failure; that is a separate leak, LFV-461 (LUCENE-10171 undid the LUCENE-8188 fix there). An executed probe with injected read failures over 18 analysis-factory configurations (OpenNLP not among them) found leaks only in the ICUrulefilesruns (5 of 54 runs). - Accepted bug fixes of the same class (
lucene/CHANGES.txt, Bug Fixes): LUCENE-7547 "JapaneseTokenizerFactory was failing to close the dictionary file it opened" (6.4.0, 5.5.4); LUCENE-8188, OpenNLPOpsFactory "InputStreams fetched from the ResourceLoader to be leaked" (7.3.0); GITHUB#14727 "Fix several resource leaks" (10.3.0), which replaced aclose()at the end of the success path with try-with-resources in smartcn'sBigramDictionaryandWordDictionary. - Tests and history. Upstream
TestICUTokenizerFactoryhas 5 tests; the three that load rule files use valid ones, and none covers a failing one.parseRulesis unchanged in behaviour since SOLR-4123 (2012), whose 21-comment thread covers therulefilessyntax, resource paths and rule syntax errors but never mentions closing the stream or a failed read.
The devil's-advocate check137 words
The strongest case for "intended" (built by reviewers): no javadoc says who closes the stream after a failed inform() (ResourceLoader.openResource says only "Opens a named resource"); invalid UTF-8 is a configuration error that already fails loudly; the JDK reclaims the handle at GC; and DefaultICUTokenizerConfig.readBreakIterator closes Lucene's bundled .brk files the same close-on-success way (DefaultICUTokenizerConfig.java:144-153).
Why it fails. The contract's silence is answered by ownership: Lucene opened the stream and no Lucene code can reach it after the failure. GC timing is unbounded, which is why Lucene's own test framework fails tests that leave handles open. The sibling loaders and three accepted bug fixes show the project's intent. The bundled-resource reader handles known-good resources inside Lucene's own jar, so it is a side note (optional hygiene, not part of this claim), not a counter-example.
Recommended A. Open the stream and the reader in a try-with-resources in parseRules
Open the stream and the reader in a try-with-resources in parseRules (9 lines added, 9 removed); the rules are still compiled after the close. With it the repro passes with assertions on and off, and the analysis-icu module's 159 tests and static checks pass.
-    InputStream rulesStream = loader.openResource(filename);
-    BufferedReader reader =
-        new BufferedReader(IOUtils.getDecodingReader(rulesStream, StandardCharsets.UTF_8));
+    try (InputStream rulesStream = loader.openResource(filename);
+        BufferedReader reader =
+            new BufferedReader(IOUtils.getDecodingReader(rulesStream, StandardCharsets.UTF_8))) {
       // read loop unchanged, indented one level
     }
-    reader.close();
     return new RuleBasedBreakIterator(rules.toString());
All options and trade-offs2 options · 402 words
One option was run through gradle in a scratch worktree of 645d4fe14a20; the alternative is the same idea in older style.
A. Open the stream and the reader in a try-with-resources in parseRules (validated by the checks) (recommended)
Move the read loop into try (InputStream rulesStream = loader.openResource(filename); BufferedReader reader = ...) { ... } and drop the explicit reader.close(); the rules are compiled after the block, as before. 9 lines added, 9 removed, ICUTokenizerFactory.java only.
-    InputStream rulesStream = loader.openResource(filename);
-    BufferedReader reader =
-        new BufferedReader(IOUtils.getDecodingReader(rulesStream, StandardCharsets.UTF_8));
+    try (InputStream rulesStream = loader.openResource(filename);
+        BufferedReader reader =
+            new BufferedReader(IOUtils.getDecodingReader(rulesStream, StandardCharsets.UTF_8))) {
       // read loop unchanged, indented one level
     }
-    reader.close();
     return new RuleBasedBreakIterator(rules.toString());
Trade-offs
- Success path unchanged: the stream is still closed before ICU compiles the rules, so a rule file that does not compile still leaves nothing open.
- On failure the caller sees the same exception, with any exception from
close()attached as suppressed; on success a failingclose()propagates, as the explicitclose()at:149does today. The stream is its own resource, so it is also closed if wrapping it in the decoding reader fails. Closing the stream after the reader is a harmless second close. - The same idiom as
WordlistLoader.getLinesand GITHUB#14727. LFV-719 (a byte order mark kept as rule text) changes the same loop; the two fixes do not conflict.
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20(2026-11-01): the repro fails on stock and passes with the fix, with assertions on and off. - The whole
:lucene:analysis:icu:testtask with the repro in place: 17 test classes, 159 tests (10 skipped), 0 failures, including the 5TestICUTokenizerFactorytests. :lucene:analysis:icu:check -x test(google-java-format, ecj lint, forbidden APIs) passes with the fix and the test in place.- Earlier checks: the finder's 4 tests pass, fault injection finds 0 leaks in 157 checks (156 fault points and a fault-free baseline), and five failed tries on a real file leave 0 descriptors open.
Keep the code as is and close the reader (or the stream) in a finally block, for example with IOUtils.closeWhileHandlingException.
Trade-offs
Same effect in older style, with more lines; no reason to prefer it. Care is needed: a plain finally with IOUtils.close lets a failing close replace the read exception, so closeWhileHandlingException belongs on the failure path only (the usual success flag idiom). Not run.
OpenSearch's ICU plugin and Lucene.NET read rule files with their own code, which closes the file on failure (source read), so the leak is specific to Lucene's ICUTokenizerFactory and the applications that configure it.
Non-formal first signal: an executed probe injected read failures into 18 analysis-factory configurations, and only the ICU rulefiles runs left a stream open. A TLA+ model of the load and fault injection at every byte of a real rule file then confirmed it, and it was cut to one public-API test.
The method in full131 words
Method: non-formal first signal, then formal characterization. On 2026-10-28 an exception-safety probe (FactoryInformLeakProbe) gave 18 analysis-factory configurations a close-tracking ResourceLoader with a read failure injected at byte 0 or 3 and a malformed file: 54 runs, 5 leaking, all on ICUTokenizerFactory rulefiles read or decode failures; the other configurations and an ICU rule file that does not compile closed every stream. The hunt unit then wrote a TLA+ model of the load's resource lifecycle (TLC: 14 traces break the release invariant, all at the read step; the fixed variant holds) and ran model-based fault injection on the real jar (157 checks, 156 fault points and a fault-free baseline: 154 leak, 0 mismatches with the model, 0 leaks with the fix), and reduced it to a public-API JUnit test.
No prior report found in GitHub issues, PRs and commits (incl. the JIRA archive), all open PRs, the mailing lists, downstream trackers or the web (2026-10-29, refreshed 2026-11-01). LUCENE-7547, LUCENE-8188 and GITHUB#14727 fixed the same leak class elsewhere. Not fixed upstream.
Searches4 searches
Closest items, none a report of this bug: elastic/elasticsearch#13651 (2016: a review remark suggested try-with-resources for Elasticsearch's own port of parseRules, on code that already closed the reader in a finally: a style comment on another code base); elastic/elasticsearch#162579 (open, another defect in their rule-file port); SOLR-4123 (the origin of the code; its thread covers the rulefiles syntax, resource paths and rule syntax errors, never closing the stream); #7747 (LUCENE-6689, names rulefiles, unrelated). Precedents of the same leak class at other fix sites: #8598 (LUCENE-7547) and its duplicate #9179 (LUCENE-8131), #9236 (LUCENE-8188), #5237 (LUCENE-4165), GITHUB#14727. Related finding: LFV-719, the same method with another root cause. Limits: keyword search only; unmerged forks and private channels are not visible.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits (incl. the migrated JIRA issues), mailing lists, downstream trackers, web | 2026-10-29 | two scripted prior-report searches (51 and 56 queries: ICUTokenizerFactory, parseRules, rulefiles, rbbi, leak, close, MalformedInputException, openResource, file-handle leaks in factories) | 478 and 1972 hits; none is this bug |
| GitHub (apache/lucene, apache/solr, apache/lucenenet, Elasticsearch, OpenSearch, global) and JIRA (LUCENE, SOLR) | 2026-10-29 | 28 direct searches; 10 JQL queries with the full SOLR-4123 thread | no report; elastic/elasticsearch#13651 is a style remark on their own port |
| Open PRs | 2026-10-29, refreshed 2026-11-01 | changed files of all 415 open apache/lucene PRs (2026-10-29); the 15 PRs created since 2026-10-29 (2026-11-01) | only the branch_10x decommission (#16911, since merged) lists the file; none of the 15 touches analysis/icu |
| Upstream main | 2026-11-01 | commit list of ICUTokenizerFactory.java at main 2f424fd428da | newest commit 378ca8d1bbf (2026-01-15, javadoc only): unchanged since 645d4fe14a20 |
Born with rulefiles in 4.1.0 (SOLR-4123, 2012); the method's failure handling never changed, so every release from 4.1.0 to 10.6.0 and main has it. Not a regression.
Versions tested7 rows
Introduced by SOLR-4123 "ICUTokenizerFactory - per-script RBBI customization": trunk commit 6024e1465e02 (Steven Rowe, 2012-12-03, svn era, no PR), on the release line through the branch_4x merge 9a23a0799e5e, first released in 4.1.0. It added rulefiles and parseRules with a single reader.close() after the loop. The only later commits on the method, LUCENE-5560 (2014, a charset constant) and LUCENE-9570 (2021, formatting), changed no failure handling. All 121 release tags in the history clone that have parseRules, 4.1.0 to 10.6.0, have one reader.close() and no try/finally (re-scanned 2026-11-01).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails (gradle and standalone, assertions on and off); passes with the fix |
| 10.6.0 | affected | minimal test fails with -ea and -da (release jars) |
| 10.5.2 | affected | minimal test fails with -ea and -da; history harness leaks on both failure paths |
| 9.1.0 | first with the test's imports | minimal test fails with -ea and -da |
| 9.12.3, 10.0.0 | affected | history harness leaks; the finder's JUnit fails 3 of 4 |
| 4.1.0 to 9.0.0 | first: 4.1.0 | history harness leaks on 4.1.0, 4.3.1, 4.4.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4 and 9.0.0; the valid control is closed |
| 4.0.0 | no rulefiles | not applicable: the factory has no rulefiles and never opens a rule file |
Confirmed, high confidence: the finder, an independent reproducer, an intended-behaviour devil's advocate and an adjudication reproduced it. A reviewer from another model family, unable to run code, returned a procedural "not real" while agreeing on the root cause.
Checks and verdicts304 words
Everyone agrees on the root cause and that the impact is small: one stream per failed load, held until GC.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit fails 3 of 4 on main (assertions on and off, 20 of 20 iterations), 10.5.2 and 9.12.3, and a main() variant on 8.11.2 and 7.7.3; the valid control passes; TLA+ model and fault injection agree; the fix passes 4/4 and the 5 upstream TestICUTokenizerFactory tests. |
| cross-model review, refute lens (OpenAI GPT-5.6, read-only) | not real, low (procedural) | Could not run code, so its verdict is procedural; it called the static evidence strongly in favour of a genuine, minor defect. It agreed on the root cause and found the inputs in contract. A separate re-run: 3 of 4 fail. |
| independent reproducer | real | Its own public-API JUnit and a real-file LeakFS test fail on main (assertions on and off), 10.5.2 and 9.12.3, and a main() variant on 8.11.2; LeakFS names the open site parseRules:139; its own fix passes. |
| cross-model review, works-as-designed lens (OpenAI GPT-5.6, read-only) | real, medium | Rated the intended case (no ownership javadoc, a loud configuration error, GC reclaims the handle) weak. |
| intended-behaviour devil's advocate | real, high | Built and rejected the intended case; found the GITHUB#14727 precedent and the LUCENE-4165 ownership remark; re-ran on main with assertions on and off. |
| adjudication | confirmed, high | Re-ran the reproducer's tests with a new seed, assertions on and off: 3 of 4 fail, the control passes. It rated the impact as one descriptor per failed load, reclaimed at GC. |
| Registration check, credibility audit and this doc | confirmed | The minimal test fails alone on main and passes with the fix; on 2026-11-01 it also failed on the 10.6.0, 10.5.2 and 9.1.0 jars, and the fix was validated through gradle. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 492 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,542 words
- Registry title
- ICUTokenizerFactory leaves a custom per-script rule file (rulefiles) open when reading or decoding it fails: parseRules closes its reader only after a successful read loop, so a rule file that is not valid UTF-8, or an I/O error while reading it, leaves the stream the ResourceLoader opened unclosed until garbage collection (every release since 4.1.0)
- Area
- analysis / ICU (ICUTokenizerFactory per-script rule files: rulefiles, parseRules)
- Priority
- Low, rank 1117: ICUTokenizerFactory leaks one rule-file stream only when an opt-in custom rulefiles file fails to load, which is narrower than the every-call leaks LFV-461 and LFV-624.
- Impact class
- minor
- Impact note
- Only applications that opt in to custom per-script ICU rule files (the rulefiles argument of ICUTokenizerFactory, analysis-icu module, directly or through CustomAnalyzer 'icu') are hit, and only when a rule file cannot be read to the end at analyzer setup, because it is not valid UTF-8 (for example saved as ISO-8859-1 with a non-ASCII character in a comment) or because its stream throws an IOException; inform() then fails loudly with that exception and one InputStream (with FilesystemResourceLoader, one file descriptor) stays open until it is garbage collected, so an application that keeps retrying a bad configuration accumulates them; tokens and index contents are unaffected, a rule file that decodes but does not compile is not affected, no scale is needed, and it is the same with -ea and -da in every release from 4.1.0 to 10.6.0 [exec].
- Summary
- You configure ICUTokenizerFactory with rulefiles="Latn:latin-rules.rbbi" and the rule file cannot be read to the end, because it is not valid UTF-8 (for example saved as ISO-8859-1 with an accented letter in a comment) or because reading it throws an IOException; you expect inform() to fail with that exception and to close the stream it opened, as it does after a successful read and as the other Lucene analysis factories do. Instead parseRules calls reader.close() only after its read loop has finished normally, so the exception skips the close and the InputStream returned by the ResourceLoader stays open: a tracking loader still holds it after inform() threw, and with a real file read through FilesystemResourceLoader the test framework's LeakFS reports 'file handle leaks: [InputStream(.../latin-rules.rbbi)]'. The descriptor is released only when the stream is garbage collected; a rule file that decodes but does not compile is closed before compiling and does not leak.
- Introduced
- 9a23a0799e5e678d0233430b6e683d9b91ce6030 (branch_4x merge, svn r1416629, 2012-12-03T18:32Z, the first commit any release tag contains: 4.1.0) of trunk commit 6024e1465e02302a0c1402127a6f407194365cd8 (svn r1416617, author Steven Rowe, 2012-12-03T18:21Z): SOLR-4123 'ICUTokenizerFactory - per-script RBBI customization' (Subversion and JIRA era, no PR; first patch by Robert Muir, final patches and commit by Steven Rowe; none of its 21 JIRA comments discusses closing the stream or a failed read). It added the rulefiles argument and parseRules with openResource, a read loop and a single reader.close() after the loop, with no try/finally [read: git log -S 'private BreakIterator parseRules' --all, git log -L over the method, git blame on 645d4fe]. The only later commits on the method changed no failure handling: 2f8192f3c5a (LUCENE-5560, 2014, charset constant) and 7f8b7ffbcad (LUCENE-9570, 2021, formatting) [read]. Born with the feature, not a regression [exec: 4.0.0 has no rulefiles API, 4.1.0 leaks] (2012-12-03)
- First affected version
- 4.1.0 [exec] (the first release with rulefiles; 4.0.0 has no inform(ResourceLoader) in this factory and never opens a rule file [exec: not applicable])
- Affected versions
- Every release from 4.1.0 to 10.6.0 and main 645d4fe14a20; never fixed. [exec] a history main() harness (public API, a java.lang.reflect.Proxy ResourceLoader whose streams record close(); a valid UTF-8 control, the same rules as ISO-8859-1, a stream that throws after 8 bytes), -da: both failure paths leak and the control is closed on 4.1.0, 4.3.1, 4.4.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main; the finder's JUnit fails 3 of 4 on 9.1.0, 9.12.3, 10.0.0, 10.5.2 (-da) and main (-ea and -da); the finder also ran 10.5.2 and 9.12.3 (-ea) and a pre-9 main() variant on 7.7.3 and 8.11.2; the independent reproduction's own JUnit fails on 10.5.2 and 9.12.3 (-ea and -da) and its main() variant on 8.11.2. The bundled ICU4J versions from 49.1 to 78.3 all behave the same. [read] parseRules has no try/finally and one reader.close() at all 120 release tags of the history clone (4.1.0..8.8.1 and 9.0.0..10.5.2; 8.8.2..8.11.4 untagged there, 8.11.4 executed); branch_10_6 4ae946e5a9b and branch_10x carry the same file blob as 10.5.2, upstream main and branch_11x the same blob as 645d4fe (2026-10-29). The one-test minimal repro fails on the 10.6.0 release jars, analysis-icu included (SHA-1 checked against Maven Central), with -ea and -da (2026-11-01) [exec]; not new in 10.6. Not affected: 4.0.0 and older (no rulefiles feature). All runs JDK 25 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by TLA+/TLC, exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-29, read-only: two scripted prior-report searches with 51 and 56 queries (32 GitHub issue/PR, 6 commit, 4 downstream, 45 mailing-list over dev@, java-user@, issues@, commits@ and solr-user@, 8 JIRA-archive and 12 web queries; 478 and 1972 distinct hits, 1 high and 22 medium, the comments of the top candidates read; the one high hit is #6531, a hunspell memory issue, and none is this bug), 28 direct GitHub searches on apache/lucene, apache/solr, apache/lucenenet, Elasticsearch, OpenSearch and global (including PRs created or updated in the last 72 h), 10 JQL queries over LUCENE and SOLR with the full SOLR-4123 thread, lists.apache.org queries on the Solr user and dev lists, 14 web queries, and the changed files of all 415 open apache/lucene PRs (only #16911, the branch_10x decommission, lists ICUTokenizerFactory.java); the finder's 52 queries and the independent reproduction's, the intended-behaviour check's and the adjudication's searches also found nothing; refresh 2026-10-29: upstream main head is still 645d4fe14a20, the newest commit on the file is 378ca8d1bbf (author date 2026-01-15, javadoc only), none of the 13 PRs created since 2026-10-27 touches analysis/icu (file lists read), and searches for ICUTokenizerFactory, parseRules, rulefiles, 'ICUTokenizerFactory leak', 'ICUTokenizerFactory close', 'rule file not closed', 'rbbi close' and 'ICU rule file leak' return nothing related). Related, not reports of this bug: SOLR-4123 (origin of the code; its thread covers rulefiles syntax and resource paths only); elastic/elasticsearch#13651 (2015-16, Elasticsearch's own port of parseRules; a review remark suggesting try-with-resources was made on code that already closed the reader in a finally block, a style comment on another code base); elastic/elasticsearch#162579 (open, 2026-10-19, another defect in their rule-file port); #8598 (LUCENE-7547), #9179 (LUCENE-8131), #9236 (LUCENE-8188), #5237 (LUCENE-4165) and GITHUB#14727: the same leak class fixed in other factories and dictionaries, never in ICU; #7747 (LUCENE-6689, open, names rulefiles, unrelated). Sibling finding LFV-719 (kept UTF-8 BOM) is in the same method with another root and fix.
- Lucene commit tested
- main
645d4fe14a20(the minimal test through gradle with assertions on and off and standalone with-eaand-da; the fix in a scratch worktree with every analysis-icu test class and the module's static checks); the minimal test on the 10.6.0, 10.5.2 and 9.1.0 release jars (-eaand-da, 2026-11-01); the study's history harness on 12 releases from 4.1.0 to 10.5.2. Upstream main2f424fd428da(2026-10-30) has the same file: its newest commit is still378ca8d1bbf(2026-01-15, javadoc only) (read).
- Finding record
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:36-69 (at 645d4fe14a20) (class javadoc: rulefiles is a comma-separated list of code:rulefile pairs, 'a resource path' compiled by the ICU RuleBasedBreakIterator; @lucene.spi icu), :108-135 (inform calls parseRules once per rulefiles pair, :119), :137-151 (parseRules: loader.openResource at :139, BufferedReader over IOUtils.getDecodingReader(rulesStream, UTF_8) at :140-141, readLine loop at :143-148, reader.close() at :149 with no try/finally, new RuleBasedBreakIterator after the close at :150)lucene/core/src/java/org/apache/lucene/util/IOUtils.java:180-200 (at 645d4fe14a20) (getDecodingReader uses CodingErrorAction.REPORT for malformed and unmappable input; 'useful to load configuration files, stopword lists or synonym files to detect character set problems')lucene/core/src/java/org/apache/lucene/util/ResourceLoader.java:22-26 (at 645d4fe14a20) ('Opens a named resource'; no statement on who closes the stream)
- The finding in 30 seconds
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:49-66, :108-135, :137-151 (at 645d4fe14a20)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/DefaultICUTokenizerConfig.java:81-84, :144-153 (static initializer reads the bundled .brk files; at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/ClasspathResourceLoader.java:59-71; lucene/analysis/common/src/java/org/apache/lucene/analysis/util/FilesystemResourceLoader.java:84-90 (return the stream, keep no reference; at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/IOUtils.java:180-199 (getDecodingReader, at 645d4fe14a20)
- Who is affected
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:42-66 (javadoc examples), :111-112 (default path) (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/util/FilesystemResourceLoader.java:84-90 (Files.newInputStream at :86) (at 645d4fe14a20)
- Why it looks unintended
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:137-151 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/IOUtils.java:180-199; lucene/core/src/java/org/apache/lucene/util/ResourceLoader.java:22-26 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:297-299; lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:322; lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseTokenizerFactory.java:144 (at 645d4fe14a20)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/DefaultICUTokenizerConfig.java:144-153 (at 645d4fe14a20)lucene/CHANGES.txt:1765 (GITHUB#14727, 10.3.0 Bug Fixes), :7673 (LUCENE-8188, 7.3.0), :8679 and :9569 (LUCENE-7547, 6.4.0 and 5.5.4) (at 645d4fe14a20)lucene/analysis/icu/src/test/org/apache/lucene/analysis/icu/segmentation/TestICUTokenizerFactory.java (5 tests; the three with rulefiles, :43-125, load valid files) (at 645d4fe14a20)
- TestICUTokenizerFactoryRuleFileClosed.java (JUnit, one test):
repro/LFV-1010/src/org/apache/lucene/analysis/icu/segmentation/TestICUTokenizerFactoryRuleFileClosed.java(58 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and a probe executed for it (public API, assertions on and off, and with the fix).
assets/LFV-1010/bug.png(492 KB)