BulkScorer.java:57 calls scorer.advance(min) and :63 calls scorer.nextDoc(). Today Scorer extends Scorable and offers docID() and iterator(), but no advance or nextDoc: those live on the DocIdSetIterator that scorer.iterator() returns.
- A
Scorerwalks the documents that match a query in one segment, in increasing doc id order, and scores them. - A
BulkScorerscores a whole range of doc ids at once:score(collector, acceptDocs, min, max)must ignore docs beforeminand return a value>= max. Lucene wraps a default one around everyScorer; only queries with a faster way to score a range write their own. - Up to 5.4, a
Scorerwas itself a doc id iterator, withadvance(target)andnextDoc(). Since 5.5.0 it hands one out instead:scorer.iterator().
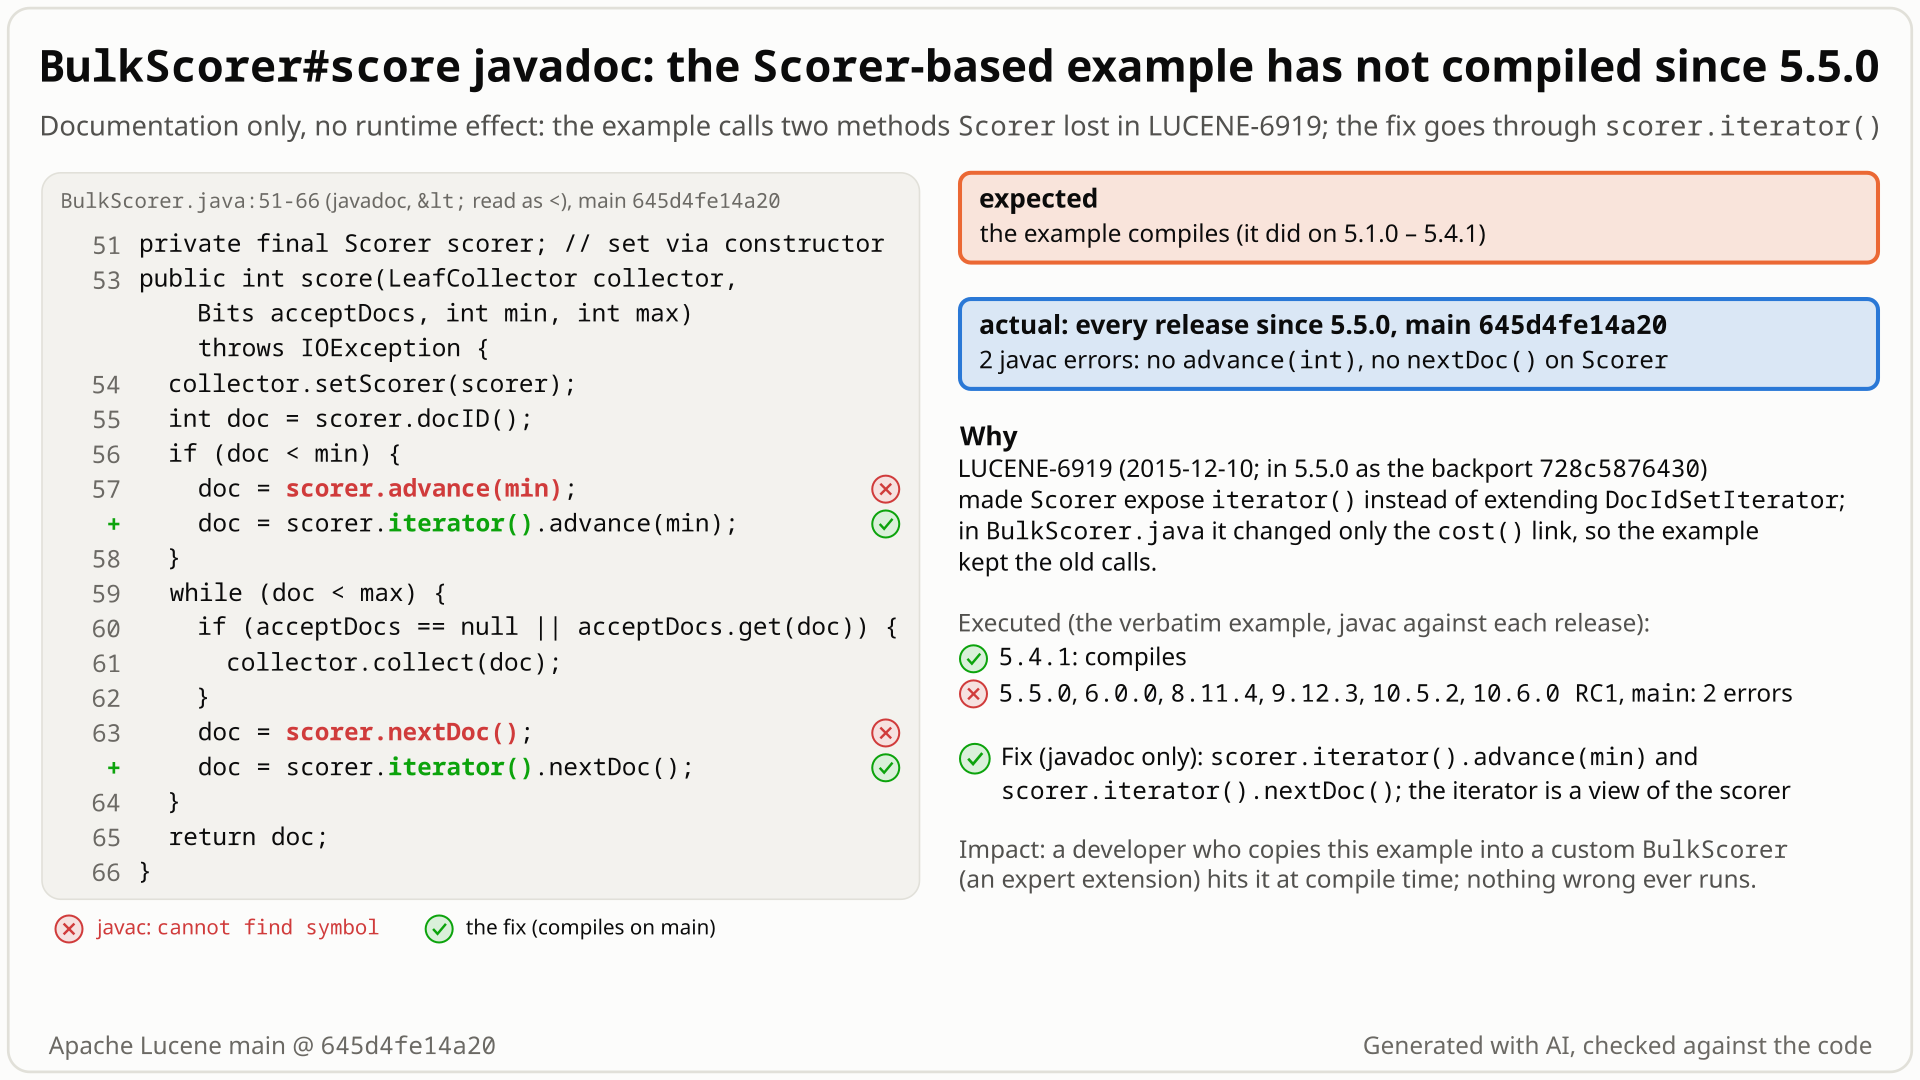
advance(min) and nextDoc() on the Scorer itself; since 5.5.0 those methods live on the iterator that scorer.iterator() returns. Select the still to open it at full size. Generated with AI, checked against the code.- You write a custom
BulkScorerand start from the example in thescore()javadoc ("a Scorer-based implementation could look like below"), adding the constructor its comment names. - You expect it to compile and to honour the window: on a 20-doc index where docs 0, 3, 6, ..., 18 match,
score(collector, null, 4, 13)should collect docs 6, 9 and 12 and return a value >= 13. - Instead javac stops with 2 errors on
variable scorer of type Scorer:cannot find symbol: method advance(int)andcannot find symbol: method nextDoc(). - Why: the example dates from early 2015, when
ScorerextendedDocIdSetIterator. Lucene 5.5.0 (LUCENE-6919) moved iteration toscorer.iterator()and updated a link in this same file, but not the example. - With
scorer.iterator().advance(min)andscorer.iterator().nextDoc()the example compiles and collects 6, 9, 12, then 15, 18 andNO_MORE_DOCS.
Developers who write a custom BulkScorer, an expert extension point, and start from this example: two compile errors on every release since 5.5.0, about ten years. Nothing in Lucene runs the example, so no search result, index or default path changes.
Mechanism, terms and numbers437 words
The javadoc of BulkScorer#score(LeafCollector, Bits, int, int) states the window contract (ignore documents before min, return a value >= max) and then shows "a Scorer-based implementation" in 16 lines of Java. Two of them call scorer.advance(min) and scorer.nextDoc(). Scorer has had neither method since LUCENE-6919 (5.5.0) made it expose iterator() instead of extending DocIdSetIterator, so the example fails with two cannot find symbol errors on every release from 5.5.0 to 10.6.0 and on main.
The example was valid when it was written: up to 5.4.1 Scorer extended DocIdSetIterator (compiled here at 5.4.1). LUCENE-6919 changed one line of BulkScorer.java, the cost() javadoc link, and left the example, whose block ends 12 lines above that link, as it was. Nothing runs the example, so no search result changes; the fix changes two lines: scorer.iterator().advance(min) and scorer.iterator().nextDoc().
// :48  "For instance, a {@link Scorer}-based implementation could look like below:"
private final Scorer scorer; // set via constructor

public int score(LeafCollector collector, Bits acceptDocs, int min, int max) throws IOException {
  collector.setScorer(scorer);
  int doc = scorer.docID();
  if (doc < min) {
    doc = scorer.advance(min);          // :57  Scorer has no advance(int)
  }
  while (doc < max) {
    if (acceptDocs == null || acceptDocs.get(doc)) {
      collector.collect(doc);
    }
    doc = scorer.nextDoc();             // :63  Scorer has no nextDoc()
  }
  return doc;
}- What
Scoreroffers today.public abstract class Scorer extends Scorable(Scorer.java:28).Scorablehasscore(),smoothingScore(int),setMinCompetitiveScore(float)andgetChildren();ScoreraddsdocID()(:31) anditerator()(:43), among others, but noadvance(int)and nonextDoc().iterator()documents that "The returned iterator is a view: calling this method several times will return iterators that have the same state" (:40-41). - Why it compiled once. At the 5.4.1 tag
Scorer.java:42readspublic abstract class Scorer extends DocIdSetIterator; at the 5.5.0 tag it readspublic abstract class Scorer, withpublic abstract DocIdSetIterator iterator()at:123. The example text is the same in both. - How it was missed. LUCENE-6919 (
ddb3a97678f) changed exactly one line ofBulkScorer.java:{@link Scorer#cost()}became{@link DocIdSetIterator#cost()}in thecost()javadoc. The configured checks did not reject the example: doclint validates{@link}targets but does not compile code inside<pre>, and ErrorProne'sInvalidSnippetcheck is about{@snippet}tags, which this block does not use (an intended-behaviour checker's reading of the build configuration, not a run). - Nothing else depends on it. No other source under
lucene/callsscorer.advance(...)orscorer.nextDoc(); the only other text hit is a code comment inFunctionRangeQuery.java:155.
Exposure and likelihood169 words
- Who.
BulkScoreris public with no@lucene.internalor@lucene.experimentaltag; it is whatWeight#bulkScorerreturns (Weight.java:170-178) through the public, overridableScorerSupplier#bulkScorer()(ScorerSupplier.java:44). The class javadoc says only queries that "have a more optimized means of scoring across a range of documents need to override this" (BulkScorer.java:23-26), and the package docs call custom queries "an expert level task" (package-info.java:388-391). The audience is small and expert. - Default vs opt-in. No runtime path: no Lucene code runs the example, and Lucene's own Scorer-backed bulk scorers use the iterator (
Weight.java:240,:265-271;BatchScoreBulkScorer.java:45-46). - Scale and age. Every release from 5.5.0 (released 2016-02-22) to 10.6.0, branch_10x and main. The failure is deterministic and loud: two javac errors that name the missing methods.
- What a reader loses. This is the only code in the
score()javadoc that shows how to honourmin,maxandacceptDocstogether, and it teaches an API shape (aScorerthat is its own iterator) that no longer exists.
One JUnit test, one method, deterministic: it compiles the example, copied verbatim from the javadoc, with javax.tools against the test class path. It adds only imports, an abstract BulkScorer subclass and the constructor the example's comment names.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.net.URI;
import java.util.List;
import javax.tools.DiagnosticCollector;
import javax.tools.JavaFileObject;
import javax.tools.SimpleJavaFileObject;
import javax.tools.ToolProvider;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBulkScorerJavadocExample extends LuceneTestCase {

  // Expected: the BulkScorer#score javadoc example compiles; actual: javac cannot find Scorer.advance(int) and Scorer.nextDoc().
  public void testScoreJavadocExampleCompiles() throws Exception {
    String source =
        """
        import java.io.IOException;
        import org.apache.lucene.search.*;
        import org.apache.lucene.util.Bits;
        abstract class Example extends BulkScorer {
          Example(Scorer scorer) {
            this.scorer = scorer;
          }
        private final Scorer scorer; // set via constructor

        public int score(LeafCollector collector, Bits acceptDocs, int min, int max) throws IOException {
          collector.setScorer(scorer);
          int doc = scorer.docID();
          if (doc < min) {
            doc = scorer.advance(min);
          }
          while (doc < max) {
            if (acceptDocs == null || acceptDocs.get(doc)) {
              collector.collect(doc);
            }
            doc = scorer.nextDoc();
          }
          return doc;
        }
        }
        """;
    JavaFileObject unit =
        new SimpleJavaFileObject(URI.create("string:///Example.java"), JavaFileObject.Kind.SOURCE) {
          @Override
          public CharSequence getCharContent(boolean ignoreEncodingErrors) {
            return source;
          }
        };
    DiagnosticCollector<JavaFileObject> diagnostics = new DiagnosticCollector<>();
    List<String> options =
        List.of(
            "-classpath", System.getProperty("java.class.path"),
            "-d", createTempDir().toString(),
            "-proc:none");
    boolean compiled =
        ToolProvider.getSystemJavaCompiler()
            .getTask(null, null, diagnostics, options, null, List.of(unit))
            .call();
    assertTrue(diagnostics.getDiagnostics().toString(), compiled);
  }
}
cp $REPRO/TestBulkScorerJavadocExample.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE
./gradlew :lucene:core:test --tests org.apache.lucene.search.TestBulkScorerJavadocExample -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure; the defect is at compile time)
- Expected
- The example from the
BulkScorer#scorejavadoc compiles against the current API. - Observed
- javac:
cannot find symbol: method advance(int)andcannot find symbol: method nextDoc()onvariable scorer of type Scorer.
More files, environment, full output285 words
- Faithful copy. A script compares the embedded block with the javadoc block at
645d4fe14a20line for line (entities decoded): they match. Lines 14 and 20 of the compiledExample.javaare the lines copied fromBulkScorer.java:57and:63. - Assertions do not matter (it is a compile error); both modes were run and fail the same way.
- Releases. The same file fails unchanged on the 10.6.0, 10.5.2 and 9.12.3 release jars. Before 9.0
LuceneTestCaselives inorg.apache.lucene.util; an equivalent verifier test with only that import changed fails on 5.5.0, 6.0.0 and 8.11.4 and passes on 5.4.1. - As the regression test: this same method with the two corrected lines, in
lucene/core/src/test/org/apache/lucene/search/. It guards a copy of the example, not the javadoc itself (it catches API drift, not a later edit of the block), so a reviewer may prefer no test for a javadoc-only change; andcheckGoogleJavaFormatasks for two re-wraps in it (shown by the format check).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also fails on the 10.6.0, 10.5.2 and 9.12.3 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp $REPRO/TestBulkScorerJavadocExample.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE
./gradlew :lucene:core:test --tests org.apache.lucene.search.TestBulkScorerJavadocExample -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure; the defect is at compile time)
# gradle, main 645d4fe14a20, seed DEADBEEF, -Ptests.asserts=true
TestBulkScorerJavadocExample > testScoreJavadocExampleCompiles FAILED
    java.lang.AssertionError: [/Example.java:14: error: cannot find symbol
        doc = scorer.advance(min);
                    ^
      symbol:   method advance(int)
      location: variable scorer of type org.apache.lucene.search.Scorer, /Example.java:20: error: cannot find symbol
        doc = scorer.nextDoc();
                    ^
      symbol:   method nextDoc()
      location: variable scorer of type org.apache.lucene.search.Scorer]
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:980D89C6B13FE5A5]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.search.TestBulkScorerJavadocExample.testScoreJavadocExampleCompiles(TestBulkScorerJavadocExample.java:75)
1 test completed, 1 failed
# -Ptests.asserts=false: the same two errors
# with fix A or B: BUILD SUCCESSFUL, 1 test- The javadoc introduces it as "a Scorer-based implementation" and gives the exact signature of the method it documents.
- It was valid when written (
ScorerextendedDocIdSetIteratorup to 5.4.1); LUCENE-6919 updated thecost()link in this same file, but not the example. - Lucene's own code uses the iterator:
BatchScoreBulkScorerwritesscorer.iterator().advance(min). Upstream has fixed stale examples before (LUCENE-6112, #12693).
The full argument168 words
- The text presents it as an implementation. "For instance, a {@link Scorer}-based implementation could look like below:" (
BulkScorer.java:48), then a<pre><code class="language-java">block with real Lucene types and the exact signature of the abstract method (:53vs:76). - It was correct when written. LUCENE-6184 (#7246) added it on 2015-01-19 while
ScorerextendedDocIdSetIterator(trunkcb3ec682d41; the same-day branch_5x backport5c9b5e7ea4eis the commit released in 5.1.0); LUCENE-6553 (#7611) added theacceptDocslines (trunkd671dd8d890, branch_5xc00996c54a3, first in 5.3.0). Later edits are mechanical:2d6ad2fee6d(reformatting, 2020) and378ca8d1bbf(#15573, 2026-01-15, the<pre>wrapper only). - The rest of Lucene teaches
iterator().Scorer's class javadoc ("AScorerexposes aniterator()over documents"); the package docs (package-info.java:404-406,:473-475);BatchScoreBulkScorer.java:46;CHANGES.txt:9706-9708records LUCENE-6919 as an API change in 5.5.0. - Precedent.
CHANGES.txt:11625"LUCENE-6112: Fix compile error in FST package example code" (as the cross-model intended-lens review pointed out);6fde1db2281(#12693, Analyzer example);d1163450b6a(LUCENE-9046, TermInSetQuery example);62f55c073c2(LUCENE-8957, CustomAnalyzer examples).
The devil's-advocate check152 words
Strongest case for "leave it" (a separate intended-behaviour checker and a cross-model reviewer, OpenAI GPT-5.6): "could look like below" marks an illustrative sketch; the block already omits its class, constructor and cost(); BulkScorer is an expert extension point most queries never implement, since the default bulk scorer does this job; Lucene does not compile javadoc snippets; and the error is loud, so nobody is misled at run time.
Why it fails: the omitted parts are the ones the reader is meant to supply (the comment says where the field comes from); the two broken lines are the core of what the example teaches and name methods that do not exist. It went stale by oversight in a commit that edited the same file, and upstream has fixed the same kind of example before. The cross-model lenses rated the argument weak; every verifier and the adjudication called it a real documentation defect.
Recommended A. Call the iterator in place
Change the two calls to scorer.iterator().advance(min) and scorer.iterator().nextDoc() (BulkScorer.java:57, :63). Validated: the test fails before and, regenerated from the patched javadoc, passes after, with assertions on and off; TestBooleanScorer, the format check and javadoc rendering pass.
   *   if (doc < min) {
-  *     doc = scorer.advance(min);
+  *     doc = scorer.iterator().advance(min);
   *   }
   *   while (doc < max) {
   *     if (acceptDocs == null || acceptDocs.get(doc)) {
   *       collector.collect(doc);
   *     }
-  *     doc = scorer.nextDoc();
+  *     doc = scorer.iterator().nextDoc();
   *   }
All options and trade-offs2 options · 469 words
Two validated options, both applied in a scratch worktree of main 645d4fe14a20 and run with gradle. Not in scope: compiling javadoc examples in the build (for example external, compiled {@snippet} sources), which would prevent the whole class of defect but is a tooling change discussed only generically upstream (#14257, #15225). Also out of scope: modernising the example; like the original, both fixes ignore Scorer#twoPhaseIterator() and LeafCollector#competitiveIterator(), which Weight.DefaultBulkScorer handles (Weight.java:238-243, :255).
Two changed lines in the BulkScorer#score javadoc example.
   *   if (doc < min) {
-  *     doc = scorer.advance(min);
+  *     doc = scorer.iterator().advance(min);
   *   }
   *   while (doc < max) {
   *     if (acceptDocs == null || acceptDocs.get(doc)) {
   *       collector.collect(doc);
   *     }
-  *     doc = scorer.nextDoc();
+  *     doc = scorer.iterator().nextDoc();
   *   }
Trade-offs
- The smallest change, and the same form as
BatchScoreBulkScorer.java:46. In contract:Scorer#iterator()says repeated calls return views with the same state (Scorer.java:40-41). - It calls
iterator()once per document; fine for an example, while a real implementation would cache it, as option B andWeight.DefaultBulkScorerdo.
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, seedDEADBEEF: the minimal test fails before the change and, with its example regenerated mechanically from the patchedBulkScorer.java(byte-identical to the hunt's fix check), passes after it, with-Ptests.asserts=trueandfalse. TestBooleanScorer(20 tests, covers the default bulk scorer) passes;:lucene:core:checkGoogleJavaFormatand:lucene:core:renderJavadocpass on the patched file, and the renderedBulkScorer.htmlshows the two corrected calls.- Semantics: the hunt unit's control runs the corrected example on a 20-doc index (window
[4, 13)collects 6, 9, 12, then 15, 18 andNO_MORE_DOCS) with assertions on and off; a cross-model reviewer's own semantic test passed too. - Not run:
gradlew checkor other modules (the change is inside a javadoc comment).
Four changed lines: DocIdSetIterator iterator = scorer.iterator(); after collector.setScorer(scorer);, then iterator.docID(), iterator.advance(min) and iterator.nextDoc().
   *   collector.setScorer(scorer);
-  *   int doc = scorer.docID();
+  *   DocIdSetIterator iterator = scorer.iterator();
+  *   int doc = iterator.docID();
   *   if (doc < min) {
-  *     doc = scorer.advance(min);
+  *     doc = iterator.advance(min);
   *   }
   ...
-  *     doc = scorer.nextDoc();
+  *     doc = iterator.nextDoc();
Trade-offs
Reads like Lucene's own Weight.DefaultBulkScorer (Weight.java:240, :265-271), which keeps the iterator instead of calling iterator() per document. A style choice, not a correctness one (an intended-behaviour checker and the adjudication said the same). The cross-model fact check of this doc preferred B: it mirrors DefaultBulkScorer, avoids an iterator() call on every pass and reads better as teaching code.
What the checks validated
Gradle, seed DEADBEEF: the minimal test regenerated from the patched javadoc passes with -Ptests.asserts=true and false. Not run for B: the format check, javadoc rendering and the semantic control.
Non-formal. A hunt unit compiled the code examples in the javadocs of core search, index and geo classes against main, and this one failed. It then scanned 159 Lucene core jars for the methods the example calls (present up to 5.4.1, absent from 5.5.0) and wrote the one-test repro.
The method in full101 words
- Lead. A first probe compiled javadoc code blocks against the stock main
645d4fe14a20jars and got both errors (2026-10-29); a hunt unit re-ran it and extracted the block mechanically from the source. - API scan. A
java.lang.classfilescan of 159 core jars (1.9.1 to main) foundScorer.advance(int)andScorer.nextDoc()in every build from 2.9.0 to 5.4.1 and in none from 5.5.0 on; javac cross-checked the boundary. - Verification. An independent reproducer with its own test, cross-model lenses (OpenAI GPT-5.6, refute and intended), an intended-behaviour devil's advocate and an adjudication all called it real; an impact audit kept it as a Low documentation defect.
No prior report found (searched 2026-10-29, 106 queries; rechecked 2026-11-01): GitHub issues and PRs incl. the JIRA archive, commits, mailing lists, downstream projects, the web and the changed files of all open PRs. LUCENE-6919, which left the example stale, never mentions it.
Searches4 searches
Read, not the same bug: LUCENE-6919 (#7977; its 16 comments never mention the example); LUCENE-6184 (#7246, wrote it, valid then); #15573 (a markup sweep that edited the block and kept the calls); #13542 and #13794 (other changes to the file); open draft PR #12446 (the only open PR on the file; it adds setTargetCost() at the end of the class); #14257, #15225 and LUCENE-3550 (#4624) (generic discussions of javadoc snippets that name no file); #16821 and #16922 (outside reports of the same kind of defect in other files). Tracking issue #16937 does not name it. Gaps: keyword search only (GitHub search does not index PR diffs, hence the changed-file scans); the web leg was 8 queries.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, incl. migrated JIRA) | 2026-10-29 and 2026-11-01 | a scripted prior-report search and manual searches: exact phrases ("scorer.advance(min)", "Scorer-based implementation", "could look like below"), BulkScorer javadoc/example/stale, recency windows; the comment threads of LUCENE-6919 and LUCENE-6184 | no report; the only phrase hit, #10375, is unrelated |
| Open PRs | 2026-10-29 and 2026-11-01 | the changed files of all 415 open apache/lucene PRs, then of the 40 and the 100 most recent | only the old draft #12446 touches BulkScorer.java, not the example |
| Mailing lists and the JIRA archive | 2026-10-29 | dev@, java-user@, issues@, commits@ (20 scripted queries, thread reads); direct JQL | nothing about this example |
| Downstream projects and the web | 2026-10-29 | Elasticsearch, OpenSearch, Solr; 8 web queries | no report |
Written for 5.1.0 (LUCENE-6184, 2015-01) when Scorer extended DocIdSetIterator; broken by LUCENE-6919 (2015-12-10; trunk ddb3a97678f, released in 5.5.0 through its branch_5x backport 728c5876430). 5.4.1 compiles the example; every release from 5.5.0 to 10.6.0 and main fails. Not fixed upstream.
Versions tested7 rows
- Introduced:
ddb3a97678f"LUCENE-6919: Make Scorer expose an iterator instead of extending DocIdSetIterator." (jpountz, 2015-12-10, migrated as #7977); its branch_5x backport728c5876430is the commit released in 5.5.0 (git tag --contains: 5.5.0 and later, not 5.4.1). - The example: written by LUCENE-6184 (2015-01-19; trunk
cb3ec682d41, released in 5.1.0 through the branch_5x backport5c9b5e7ea4e),acceptDocsadded by LUCENE-6553 (2015-06-25; trunkd671dd8d890, branch_5xc00996c54a3, first in 5.3.0); valid until LUCENE-6919. Its Java lines are identical in all 95 release tags from 5.3.0 to 10.6.0 and on main; only the surrounding javadoc markup changed. - Upstream: main
f815e679bf6c(2026-11-01) still has both lines; the last commit to the file is #15573 (2026-01-15), which kept them. branch_11x and branch_10_6 still have them (2026-11-01); branch_10x had them on 2026-10-29 and was decommissioned upstream that day (#16911).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, gradle and standalone, assertions on and off; passes with fix A or B |
| 10.6.0 | affected | minimal test fails 1/1, assertions on and off (release jars) |
| 10.5.2, 9.12.3 | affected | minimal test fails 1/1 (release jars) |
branch_10x 657014b3c579 | affected | the finder's test fails |
| 5.5.0, 6.0.0, 8.11.4 | pre-9.0 port | an equivalent verifier test (import-only port) fails with the same two errors |
| 5.4.1 | not affected | the verbatim example compiles (Scorer extends DocIdSetIterator) |
| 5.0.0 and earlier | not affected | no such example and no min/max window method (5.0.0 has score(LeafCollector) and the abstract score(LeafCollector, int max)) |
Every check calls it real: the finder, an independent reproducer, cross-model lenses (OpenAI GPT-5.6), an intended-behaviour devil's advocate, an adjudication, an impact audit and this doc's gradle runs.
Checks and verdicts227 words
The cross-model reviews ran on main ea57360912ed, whose BulkScorer.java is byte-identical to 645d4fe14a20; everything else ran on 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | reproduced | One-test repro fails on main (assertions on and off), a build of the 10.6.0 RC1 commit 4ae946e5a9b (later tagged as the 10.6.0 release), branch_10x, 10.5.2 and 9.12.3; fix check passes. |
| cross-model review, refute lens | real, high | OpenAI GPT-5.6, executing: own test reproduced both errors; own semantic test of the corrected example passed; TestBooleanScorer#testDefaultBulkScorer* 5/5 with the patched javadoc. |
| independent reproducer | real | Own test fails on main, 10.5.2 and 9.12.3; passes with the two iterator() calls; plain javac: 5.4.1 compiles, 5.5.0 fails. |
| cross-model review, intended lens | real, high | OpenAI GPT-5.6, reading only; intended argument weak; surfaced the LUCENE-6112 precedent. |
| devil's advocate | real, high | Built and rejected the strongest intended case; explained why doclint missed it; proposed the hoisted local (option B). |
| adjudication | confirmed, high, minor | Re-ran the independent reproduction's test on main with assertions on and off: exactly the two errors. |
| impact audit | real, Low | Real but minor: a removed-API call with copy-paste impact, not a wording slip. |
| this doc's runs (2026-11-01) | reproduced; fix validated | Gradle before/after for options A and B in a scratch worktree; release jars 10.6.0, 10.5.2, 9.12.3; upstream recheck. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 444 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,219 words
- Registry title
- BulkScorer#score's javadoc example ('a Scorer-based implementation could look like below') calls scorer.advance(min) and scorer.nextDoc(), which Scorer has not had since LUCENE-6919 made it expose iterator() instead of extending DocIdSetIterator, so the example does not compile on any release since 5.5.0 (documentation defect)
- Area
- core / search (BulkScorer#score javadoc example)
- Priority
- Low, rank 1247: The stale BulkScorer#score example in core has failed loudly at compile time for many releases and has no runtime effect.
- Impact class
- minor
- Impact note
- Documentation only, with no runtime effect: a developer who writes a custom BulkScorer (an expert extension point; the class javadoc says only queries with a more optimized way to score a range of documents need one) and starts from the Scorer-based example in the score() javadoc gets two compile errors on every release since 5.5.0 and has to find Scorer#iterator() on their own; no configuration, scale or special input is involved.
- Summary
- The javadoc of BulkScorer#score(LeafCollector, Bits, int, int) explains the window contract (ignore documents before min, return a value >= max) and then shows 'a Scorer-based implementation could look like below'. Copied into code on any release since 5.5.0 the example does not compile, because it calls scorer.advance(min) and scorer.nextDoc(): Scorer stopped extending DocIdSetIterator in LUCENE-6919 and now offers those methods only through scorer.iterator(). With scorer.iterator().advance(min) and scorer.iterator().nextDoc() the example compiles and honours the contract, so only the javadoc is wrong.
- Introduced
- ddb3a97678f (trunk, svn r1719081; LUCENE-6919 'Change the Scorer API to expose an iterator instead of extending DocIdSetIterator', migrated as #7977, by Adrien Grand (jpountz), author date 2015-12-10; the branch_5x backport 728c5876430, svn r1719124, the same day, is the one released in 5.5.0): it changed 'public abstract class Scorer extends DocIdSetIterator' to a Scorer with 'public abstract DocIdSetIterator iterator()', and in BulkScorer.java it changed only the cost() javadoc link ({@link Scorer#cost()} to {@link DocIdSetIterator#cost()}), leaving the score() example's 'doc = scorer.advance(min);' and 'doc = scorer.nextDoc();' as they were. The example was written by cb3ec682d41 (LUCENE-6184, #7246, 2015-01-19, first released in 5.1.0), when Scorer still extended DocIdSetIterator, so it was valid then; its acceptDocs lines come from d671dd8d890 (LUCENE-6553, #7611, 2015-06-25, 5.3.0); the later edits are mechanical (2d6ad2fee6d, LUCENE-9570 reformatting, 2020-12-23; 378ca8d1bbf, #15573, 2026-01-15, markup only) [read: git log, git show, git blame and git tag --contains in the full-history clone; exec: release runs, see affected_versions] (2015-12-10 (ddb3a97678f and its branch_5x backport 728c5876430, author date, svn import; the 5.4.0 tag commit is from earlier the same day and does not contain it))
- First affected version
- 5.5.0 [exec] (the verbatim example compiles against 5.4.1 [exec] and fails on 5.5.0 with the same two errors as on main)
- Affected versions
- every release from 5.5.0 to 10.6.0 (RC1 4ae946e5a9b), branch_10x 657014b3c579 and main 645d4fe14a20; not affected: 5.1.0-5.4.1 (the example compiled, Scorer extended DocIdSetIterator) and every release before 5.1.0 (no such example: 5.0.0 has only score(LeafCollector, int max)). Not fixed upstream: main, branch_10x and branch_10_6 still carry both stale lines (read 2026-10-29; branch_11x too); the last commit touching BulkScorer.java, 378ca8d1bbf3 (#15573, 2026-01-15), kept them. [exec: 5.4.1 passes; 5.5.0, 6.0.0 and 8.11.4 fail (an import-only pre-9.0 port of the independent reproduction's test); 9.12.3, 10.5.2, jars built at the 10.6.0 RC1 revision, branch_10x and main (-ea and -da) fail with 'cannot find symbol: method advance(int)' and 'method nextDoc()'] [read: a bytecode scan of 159 core jars finds Scorer.advance(int) and Scorer.nextDoc() in every build from 2.9.0 to 5.4.1 and in none from 5.5.0 to main, including the 8.9-8.11 releases by their published jars; the example code text is identical (same md5) in every release tag from 5.3.0 to 10.5.2 and on main]. Caveat: all runs used JDK 25 on Linux aarch64.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (searched 2026-10-29; the finder's, the independent reproduction's and the intended-behaviour check's searches and the adjudication's recheck agree): 106 queries in all: scripted searches over GitHub issues, PRs and commits, three downstream search-engine repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web, plus manual GitHub searches ('"scorer.advance(min)"', '"Scorer-based implementation"', '"could look like below"', 'BulkScorer javadoc', 'BulkScorer example', 'scorer.iterator().advance', ...), JQL queries, lists.apache.org thread reads, the changed files of all 415 open apache/lucene PRs (finder) and of the 40 most recently updated ones (follow-up), the issue and PR streams of this week's outside javadoc-fix authors, and the comment threads of LUCENE-6919 and LUCENE-6184. Read but not the same bug: LUCENE-6919 (#7977, the change that left the example stale; its 16 comments never mention it), LUCENE-6184 (#7246, wrote the example, valid then), #15573 (a markup sweep that edited this block and kept the stale calls), #13542 and #13794 (later BulkScorer.java changes that do not touch the example), open PR #12446 (the only open PR that changes BulkScorer.java; it adds setTargetCost() at the end of the class), #14257 and #15225 (generic discussions of javadoc snippet tooling and quality that name no file), LUCENE-3550 (#4624, a generic proposal for compiled example code), and the parallel outside reports of stale examples at other sites (#16821, #16922). Recheck: upstream main HEAD still 645d4fe14a20; no apache/lucene issue or PR updated since a recent cutoff; GitHub search for BulkScorer items updated since 2026-10-28 and for '"scorer.advance(min)"' returns 0; none of the 48 PRs updated since 2026-10-27 changes BulkScorer.java; main, branch_10x and branch_10_6 still carry both stale lines; the file's latest commit by author date is 378ca8d1bbf3 (#15573, 2026-01-15). Tracking issue #16937 does not name it.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test through gradle with assertions on and off, before and after fixes A and B, in a scratch worktree (2026-11-01), plusTestBooleanScorer,checkGoogleJavaFormatandrenderJavadocwith fix A; standalone, the minimal test on the 10.6.0 (assertions on and off), 10.5.2 and 9.12.3 release jars, and an equivalent verifier test on 5.4.1 (passes), 5.5.0, 6.0.0 and 8.11.4 (fail). Upstream mainf815e679bf6c(2026-11-01) still has both lines.
- Finding record
lucene/core/src/java/org/apache/lucene/search/BulkScorer.java lines 22-28 (class javadoc: 'Only queries that have a more optimized means of scoring across a range of documents need to override this'), 30-74 (score() javadoc; :48 'For instance, a {@link Scorer}-based implementation could look like below:', :50-67 the example, :57 'doc = scorer.advance(min);', :63 'doc = scorer.nextDoc();'), :76 (abstract score), :79 (cost() javadoc linking DocIdSetIterator#cost()); Scorer.java :23 ('Expert'), :28 ('public abstract class Scorer extends Scorable'), :40-43 (iterator(), 'The returned iterator is a view'); lucene/CHANGES.txt:9706 (5.5.0, LUCENE-6919); Lucene main ea57360912ed BulkScorer.java is byte-identical (cmp)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/BulkScorer.java:22-28, 48-67, 76, 79 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/Scorer.java:22-43 and Scorable.java:28-61 (at 645d4fe14a20)build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/JavacConfigurationPlugin.java:108-110, RenderJavadocPlugin.java:552, ErrorPronePlugin.java:531
- Who is affected
lucene/core/src/java/org/apache/lucene/search/BulkScorer.java:22-28; Weight.java:170-178, 230-290; ScorerSupplier.java:36-46; BatchScoreBulkScorer.java:37-46; package-info.java:388-391 (at 645d4fe14a20)dev-tools/doap/lucene.rdf:751-752 (lucene-5.5.0, created 2016-02-22)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/BulkScorer.java:48-76; Scorer.java:22-26; package-info.java:400-412, 470-477; BatchScoreBulkScorer.java:45-46 (at 645d4fe14a20)lucene/CHANGES.txt:9706-9708, 11625
- Diagrams
lucene/core/src/java/org/apache/lucene/search/BulkScorer.java:48-67 and Scorer.java:28-43 (at 645d4fe14a20)
- TestBulkScorerJavadocExample.java:
repro/LFV-1026/TestBulkScorerJavadocExample.java(77 lines)
assets/LFV-1026/bug.png(444 KB)