BooleanQuery.rewrite applies k3 only when it merges duplicate clauses into one boosted clause. It merges duplicate SHOULD clauses only when minimumNumberShouldMatch is at most 1, because merging changes how many clauses a document matches. In between, the duplicates stay separate clauses with weight 1 and add up linearly.
- k3. Opt-in since #15818 (unreleased 11.0.0):
new BM25Similarity(k1, b, discountOverlaps, k3), andStableTflSimilaritywith k3, weight a term repeated n times in a query((k3 + 1) * n) / (k3 + n). With k3 = 8 that is 1.8 for n = 2 and 2.45 for n = 3. The default constructor keeps k3 off. - Where it is applied.
BooleanQuery.rewritemerges equal clauses into one clause boosted bySimilarity#computeQueryTermWeight(n): SHOULDa,abecomesa^1.8. That merge is the only place the weight is applied. - minimumNumberShouldMatch (msm). A document must match at least msm of the SHOULD clauses, and duplicates count separately: a document with only
amatches(a a b)~2. Merging the twoaclauses would change that, so the SHOULD merge is skipped when msm is 2 or more (LUCENE-7925, 2017). - msm = number of SHOULD clauses. Then every SHOULD clause becomes a MUST clause, and MUST duplicates are always merged.
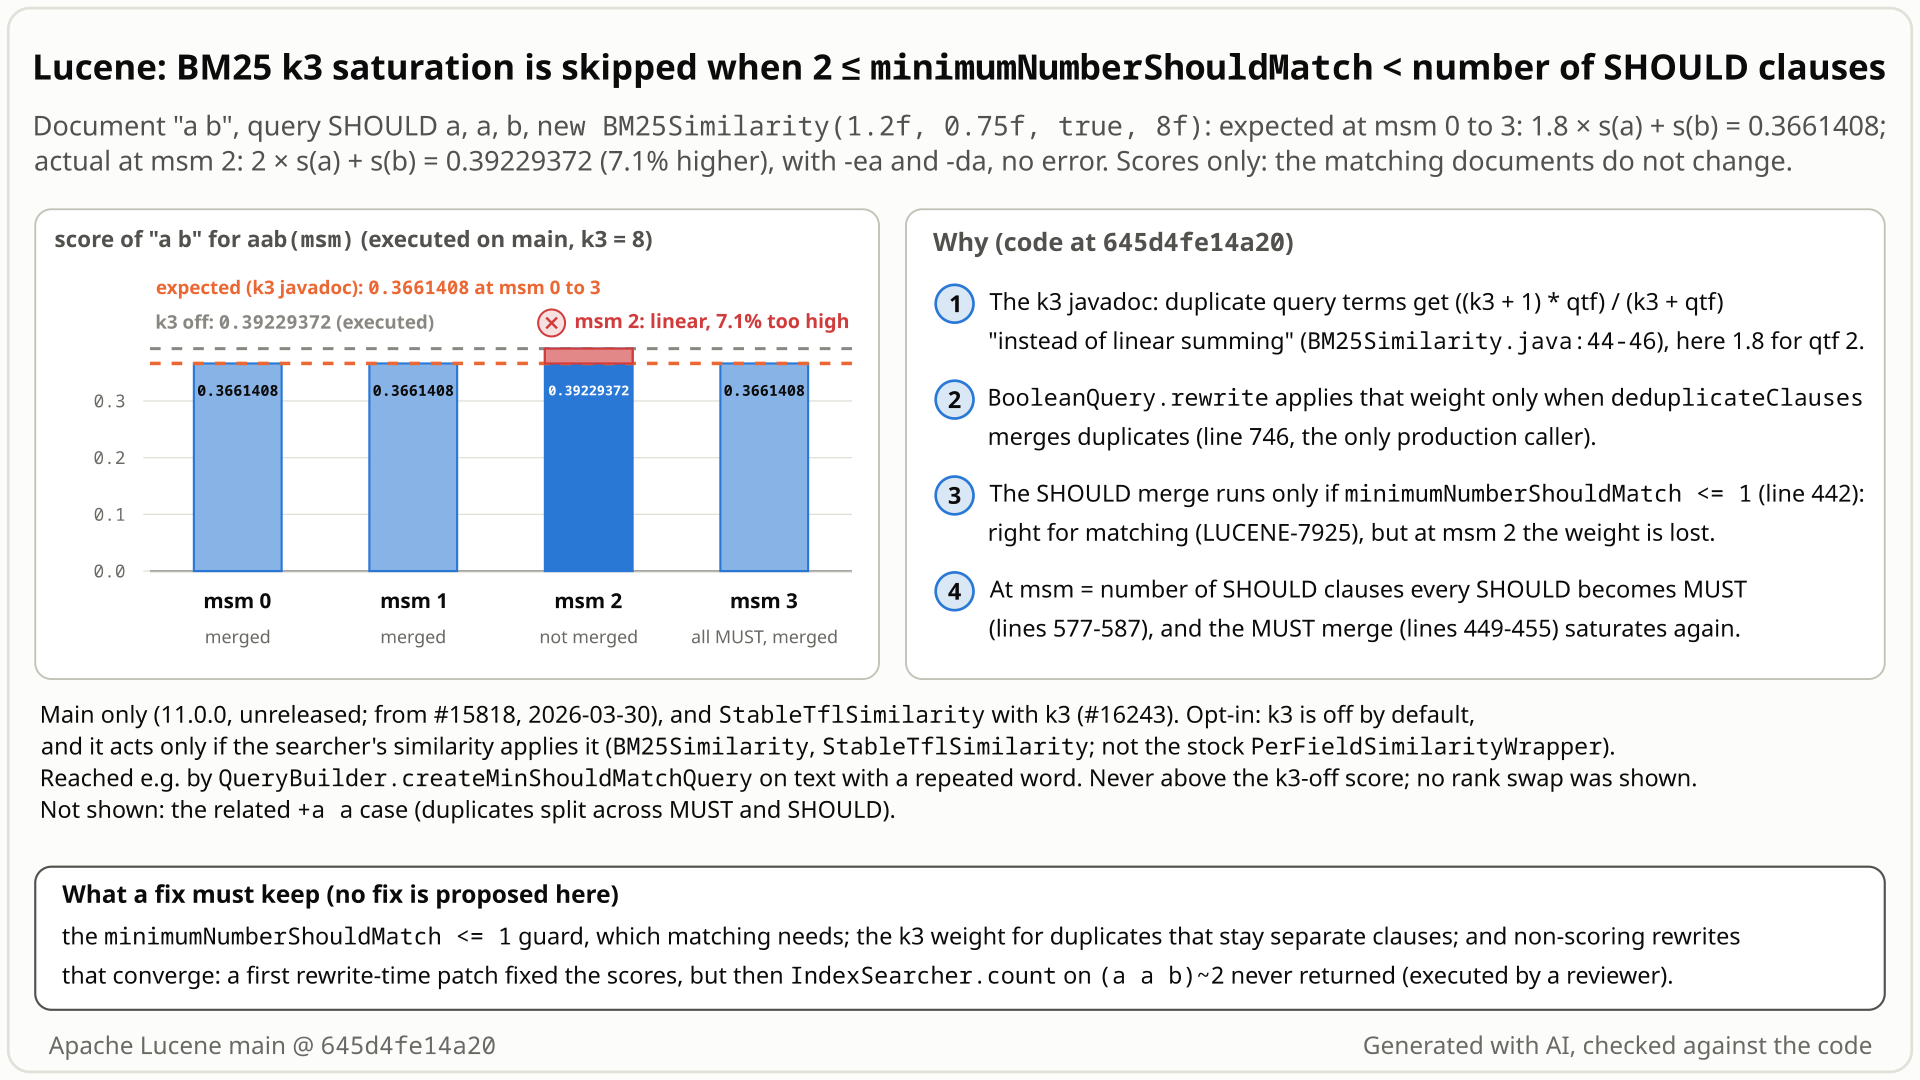
a clauses into a^1.8; at 2 it must keep them apart, and the score adds a twice. Select the still to open it at full size. Generated with AI, checked against the code.- Turn on BM25's opt-in k3:
new BM25Similarity(1.2f, 0.75f, true, 8f). Its javadoc promises that a word repeated n times in a query counts((k3 + 1) * n) / (k3 + n)times instead of n times: 1.8 instead of 2 for a word typed twice. - Index one document, "a b", and search SHOULD
a, SHOULDa, SHOULDbwith minimumNumberShouldMatch 1: score 0.3661 = 1.8 × 0.13076 + 0.13076. The rewrite merged the twoaclauses intoa^1.8. - Run the same query with minimumNumberShouldMatch 2. The document still matches all three clauses, so you expect 0.3661 again.
- Instead you get 0.3923 = 3 × 0.13076, 7% higher: the repeated
acounts twice. With all three clauses required (minimumNumberShouldMatch 3) it is 0.3661 again. - Why: the rewrite applies k3 only when it merges duplicates, and it may merge duplicate SHOULD clauses only when minimumNumberShouldMatch is at most 1, since merging changes how many clauses a document matches. In between, nothing applies the weight.
Applications on main or branch_11x (unreleased 11.0.0) that opt into k3 with BM25Similarity or StableTflSimilarity as the searcher's similarity and run minimum-should-match queries whose text repeats a word, for example through QueryBuilder.createMinShouldMatchQuery. Only scores change: about 5-10% in small examples, 4.8 times for a word repeated 50 times; which documents match never changes.
Mechanism, terms and numbers616 words
#15818 (unreleased, 11.0.0) added an opt-in k3 to BM25Similarity, and #16243 to StableTflSimilarity: a term repeated n times in a query is weighted ((k3 + 1) * n) / (k3 + n) "instead of linear summing". The weight is applied in exactly one place, when BooleanQuery.rewrite merges duplicate clauses into one boosted clause. Duplicate SHOULD clauses are merged only when minimumNumberShouldMatch <= 1, a correct guard from LUCENE-7925 (2017), because merging changes how many clauses a document matches. So for 2 <= minimumNumberShouldMatch < number of SHOULD clauses the duplicates stay separate and add up linearly, while msm 0, 1 and msm = number of SHOULD clauses are saturated. One document "a b", SHOULD a, a, b, k3 = 8: 0.3661408 at msm 1 and 3, 0.39229372 at msm 2. Only scores change; the matching documents do not, and nothing throws. Main and branch_11x only; no release has k3. A small BooleanWeight change that leaves the rewrite alone fixes it.
- The promise.
BM25Similarity.java:44-46,@param k3: "Controls query-side term frequency saturation. When duplicate terms appear in a query, their boost is computed as ((k3 + 1) * qtf) / (k3 + qtf) instead of linear summing. A negative value disables saturation (linear behavior)."StableTflSimilarity.java:103-105has the same words, and its class javadoc lists "query-side saturation for repeated query terms" (:50). The formula:BM25Similarity.java:125-136,StableTflSimilarity.java:153-164; the default constructor sets k3 = -1 (BM25Similarity.java:121-123). - The hook.
Similarity#computeQueryTermWeight(Similarity.java:164-177,@lucene.experimental) "is used during query rewriting to compute the boost for duplicate query terms"; the default is linear. - Its only caller.
deduplicateClauses(BooleanQuery.java:714-758) groups equal clauses of one occur and boosts the merged clause bysimilarity.computeQueryTermWeight(n)(:746); with explicit boosts it sums them linearly (:740-742). No other production code calls the hook. - The guard. The SHOULD dedup runs only when
minimumNumberShouldMatch <= 1(BooleanQuery.java:438-447, condition at:442). Merginga aintoa^wwould make a document with onlyastop matching(a a b)~2, so the guard is right; the hunt's Z3 model shows that a guard of msm <= 2 breaks matching (counterexample: msm = 2, two equal SHOULD clauses). - The MUST path. MUST duplicates are merged unconditionally (
BooleanQuery.java:449-455); when the number of SHOULD clauses equals msm, every SHOULD becomes MUST (:570-587). That is why msm = number of SHOULD clauses saturates again. - Result. For 2 <= msm < number of SHOULD clauses the rewrite leaves the duplicate SHOULD clauses apart (for the repro's query it returns the query unchanged; duplicate MUST clauses in the same query would still be merged),
BooleanWeightcreates one weight per clause with the same boost (BooleanWeight.java:49-62), and the duplicates add up linearly. - Before k3 the guard changed no score: merged (
a^2) and unmerged (a a) duplicates both add up linearly. k3-free controls on 9.12.3, 10.5.2, the parent of #15818 and main give one score for msm 1, 2 and 3.
One document "a b", BM25Similarity(1.2f, 0.75f, true, 8f), each term scores s = 0.13076457:
| msm | rewritten query | score |
|---|---|---|
| 0 | (body:a)^1.8 body:b | 0.3661408 (1.8 s + s) |
| 1 | ((body:a)^1.8 body:b)~1 | 0.3661408 |
| 2 | (body:a body:a body:b)~2 | 0.39229372 (2 s + s) |
| 3 | +(body:a)^1.8 +body:b | 0.3661408 |
With k3 disabled every row is 0.39229372. With five SHOULD clauses (alpha x3, bravo, charlie) msm 0, 1 and 5 are saturated (1.2603091) and msm 2, 3 and 4 linear (1.385843). StableTflSimilarity with k3 = 8 behaves the same (3.739564 at msm 1 and 3, 4.0066757 at msm 2, on the finder's six-document index).
Exposure and likelihood409 words
- Who. Users of main or
branch_11x(unreleased 11.0.0) that setBM25Similarity(k1, b, discountOverlaps, k3)orStableTflSimilarity(k1, c, k3)with k3 >= 0 as the searcher's similarity, and run aBooleanQuerywith a repeated unboosted SHOULD clause and 2 <= msm < number of SHOULD clauses. The typical producer is a "minimum should match" option over user text with a repeated word:QueryBuilder.createMinShouldMatchQuery("body", "alpha alpha bravo", f)scores one document 0.8479051 at f = 0.5 (msm 1), 0.90846974 at f = 0.7 (msm 2) and 0.8479051 at f = 1.0. Query text with a repeated word is the case k3 is for (#15768: "duplicate terms in query strings see their scores boosted by their number of occurrences"). - Reach limit. The rewrite takes the weight from
IndexSearcher#getSimilarity()(BooleanQuery.java:734,:746), so k3 has an effect only if that similarity applies it.BM25SimilarityandStableTflSimilaritydo. The stockPerFieldSimilarityWrapperdoes not overridecomputeQueryTermWeight, so behind it the rewrite gives(body:a)^2.0, not^1.8(executed); a custom wrapper could override the hook and delegate (Similarity.java:175, public and not final). That gap may be a separate issue; it was not judged. - Effect. Wrong scores, silently: the repeated term contributes
n * sinstead ofw(n) * s, about 5-10% of the total in the small examples and a factor of 4.84 for a term repeated 50 times next to two other terms (2.1188598 at msm 1, 10.250274 at msm 2). Inside the window the repeated SHOULD term contributes exactly its k3-disabled amount. When those are the query's only duplicates (the repro and every example here), the whole score equals the k3-disabled score; duplicates that the rewrite still merges (MUST ones) stay saturated. k3 only ever lowers scores (w(n) <= n), so no score goes above Lucene's default. Which documents match does not change and nothing throws. No check showed two documents swapping rank: scores change, and with them possibly the ranking. - Consistency. For one document and one query text the score is not monotone in msm: higher at msm 2 than at msm 1 or at msm 3.
- Sibling, not part of this claim. Duplicates split across occurs (
+a a) are never merged: linear at msm 0, saturated at msm 1, because a single SHOULD clause with msm 1 becomes MUST and is merged. The recommended fix does not change that case. - No release has k3, so a fix before 11.0.0 means no release ever ships the bug.
One JUnit test, one document "a b", public API: BM25Similarity with k3 = 8, the query SHOULD a, a, b, scored at minimumNumberShouldMatch 1 and 2. The document matches all three clauses both times, so the two scores must be equal.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.search.similarities.BM25Similarity;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestK3SaturationMinShouldMatch extends LuceneTestCase {

  private static Query aab(int minShouldMatch) {
    return new BooleanQuery.Builder()
        .add(new TermQuery(new Term("body", "a")), Occur.SHOULD)
        .add(new TermQuery(new Term("body", "a")), Occur.SHOULD)
        .add(new TermQuery(new Term("body", "b")), Occur.SHOULD)
        .setMinimumNumberShouldMatch(minShouldMatch)
        .build();
  }

  public void testDuplicateShouldTermSaturatedAtMinShouldMatch2() throws Exception {
    BM25Similarity sim = new BM25Similarity(1.2f, 0.75f, true, 8f);
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig().setSimilarity(sim))) {
        Document doc = new Document();
        doc.add(new TextField("body", "a b", Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        IndexSearcher s = new IndexSearcher(r);
        s.setSimilarity(sim);
        float msm1 = s.search(aab(1), 1).scoreDocs[0].score;
        float msm2 = s.search(aab(2), 1).scoreDocs[0].score;
        // expected: k3 saturates the duplicate "a" at msm=2 as at msm=1; actual: linear, higher
        assertEquals("score of 'a b' at msm=2 vs msm=1", msm1, msm2, 1e-5f);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests TestK3SaturationMinShouldMatch -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- At minimumNumberShouldMatch 2 the document scores as at 1: 0.3661408 (1.8 × s(a) + s(b)).
- Observed
- 0.39229372 (2 × s(a) + s(b)):
AssertionError: ... expected:<0.3661408> but was:<0.39229372>, with assertions on and off.
More files, environment, full output197 words
The similarity is set explicitly on the writer and the searcher, so the framework's random similarity does not apply; the framework still randomizes the codec, locale and time zone, which do not affect this one-document score (two seeds tried). ByteBuffersDirectory, a plain IndexSearcher, one thread. The query is built directly, without QueryBuilder, so no fraction arithmetic is involved.
Regression test: this same test; it passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with the fix: passes. Releases 10.5.2 and 9.12.3: the test does not compile (no k3 API) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the scoring arithmetic is pure Java) |
cp $REPRO/TestK3SaturationMinShouldMatch.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestK3SaturationMinShouldMatch -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed; -Ptests.asserts=false identical)
> Task :lucene:core:test FAILED

TestK3SaturationMinShouldMatch > testDuplicateShouldTermSaturatedAtMinShouldMatch2 FAILED
    java.lang.AssertionError: score of 'a b' at msm=2 vs msm=1 expected:<0.3661408> but was:<0.39229372>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:E5635D477A7341F3]:0)
        at org.junit.Assert.assertEquals(Assert.java:577)
        at org.apache.lucene.search.TestK3SaturationMinShouldMatch.testDuplicateShouldTermSaturatedAtMinShouldMatch2(TestK3SaturationMinShouldMatch.java:57)

# each term scores s = 0.13076457 on this index: 1.8 s + s = 0.3661408 (saturated), 2 s + s = 0.39229372 (linear)- The k3 javadoc is unconditional: duplicate query terms get
((k3 + 1) * qtf) / (k3 + qtf)"instead of linear summing" (#15818). - The only documented exception is explicit boosts; no k3 javadoc, test or review comment mentions minimumNumberShouldMatch.
- An upstream regression test expects msm to keep a matching document's score; with k3 on, 6 of 2,000 queries fail.
The full argument269 words
- The contract. The k3
@paramonBM25Similarity(:44-46) andStableTflSimilarity(:103-105) has no msm condition. The #15818 description: "Saturation is applied in BooleanQuery.rewrite() through a new Similarity.computeQueryTermWeight(int qtf) method, which BM25Similarity overrides. This works transparently regardless of which query parser or programmatic API produced the query." - The one documented exception is different. Explicit boosts are summed linearly: a code comment (
BooleanQuery.java:740-742) andTestBooleanRewrites#testDeduplicateWithExplicitBoostsFallsBackToLinearSum(:1173). The upstream k3 tests use msm 0 only (:1137,:1153), and none of the #15818 review comments mentions minimumNumberShouldMatch. - An existing upstream test expects the same.
TestBooleanMinShouldMatch#testRandomQueries(:312-360), a randomized regression test (not API documentation), checks that adding a minimumNumberShouldMatch to a random query leaves the score of a document that still matches unchanged (assertSubsetOfSameScores,:363); its comment cites "(field:v field:v field:v) gets rewritten into field:v^3" (:398-399). As configured it cannot see k3: its searcher uses the framework'sAssertingSimilarity(RandomSimilarity)(newSearcher,LuceneTestCaseParent.java:2638;SetupAndRestoreStaticEnv.java:230), and neither wrapper overridescomputeQueryTermWeight(RandomSimilarityis aPerFieldSimilarityWrapper,RandomSimilarity.java:68), so the rewrite always uses the linear default; its BM25 entry also has k3 off (:123). Adding a k3 BM25 toRandomSimilaritywould not exercise this bug. With BM25 k3 = 8 set on the searcher the same check finds 6 violations in 2,000 queries (0 with k3 off): 2 are this bug, 4 the+a asibling. - Precedent. #5368 / LUCENE-4300 ("BooleanQuery inconsistently applies coord() if it rewrites itself"): a score that depended on the rewrite shape, caught by the same invariant test, was fixed.
The devil's-advocate check205 words
The strongest case for "intended": k3 is defined by its mechanism. The hook's javadoc says it is "used during query rewriting", the PR says "Saturation is applied in BooleanQuery.rewrite()", and the SHOULD merge carries a deliberate, tested guard: TestBooleanRewrites#testDeduplicateShouldClauses (:610) asserts that (foo:bar foo:bar foo:quux)~2 rewrites to itself (:634-642). In the #15818 review rmuir called the boost handling "a bit odd and difficult to understand" and said that processing qtf separately from the boost "would create a much more invasive change", and added "This approach could use some fresh eyes and thoughts before committing to it"; the merged implementation kept the rewrite-based design. The hook is experimental, and Lucene does not promise comparable scores across different queries.
Why it fails: the guard explains why the clauses cannot be merged, not why the weight is dropped. The user-facing @param and the PR promise saturation regardless of how the query was built. For one document and one query text the score is not monotone in msm, which no review comment mentions. And a way to apply the weight without changing matching exists (the recommended fix); testDeduplicateShouldClauses stays green with it. Upstream may still reasonably prefer a javadoc caveat; that is the maintainers' call.
Recommended Apply the weight in BooleanWeight when the rewrite could not merge (validated)
In BooleanWeight, when scores are needed and minimumNumberShouldMatch > 1, create each of the n unboosted occurrences of a duplicate SHOULD clause with computeQueryTermWeight(n) / n of the boost. Matching and the rewrite stay unchanged, so count() still converges. The repro, 147 tests of the closest suites and the 2,339 tests of the search package pass.
float clauseBoost = boost;
if (c.occur() == Occur.SHOULD) {
  // computeQueryTermWeight(n) / n for an unboosted query that occurs n >= 2 times, msm > 1
  clauseBoost *= duplicateShouldWeights.getOrDefault(c.query(), 1f);
}
Weight w = searcher.createWeight(
    c.query(), c.isScoring() ? scoreMode : ScoreMode.COMPLETE_NO_SCORES, clauseBoost);
All options and trade-offs4 options · 757 words
Option A was built and run through gradle. Option B, the hunt's first fix, scores correctly but makes non-scoring rewrites loop forever, so it is rejected. C (a javadoc caveat) is the no-risk alternative; D would also cover the +a a sibling but needs its own design.
In the BooleanWeight constructor (BooleanWeight.java:49-62), when scores are needed and minimumNumberShouldMatch > 1, count the unboosted SHOULD occurrences of each query; a query that occurs n >= 2 times, and never with an explicit boost, gets each clause weight created with boost * computeQueryTermWeight(n) / n (+47/-1 lines, BooleanWeight.java only).
float clauseBoost = boost;
if (c.occur() == Occur.SHOULD) {
  // computeQueryTermWeight(n) / n for an unboosted query that occurs n >= 2 times, msm > 1
  clauseBoost *= duplicateShouldWeights.getOrDefault(c.query(), 1f);
}
Weight w = searcher.createWeight(
    c.query(), c.isScoring() ? scoreMode : ScoreMode.COMPLETE_NO_SCORES, clauseBoost);
Trade-offs
- Matching unchanged. The clauses and msm stay as they are, so exactly the same documents match. Equal clauses match the same documents, so a document matches all n occurrences or none, and the n split weights add up to the merged weight (up to float rounding).
- Rewrite unchanged. The rewrite is not touched, so
count(),ConstantScoreQueryand FILTER rewrites converge exactly as on stock main; that is where option B fails. - Same rules as the merge. Explicitly boosted duplicates stay linear, as in
BooleanQuery.java:740-742; with k3 off the factor is 1; with msm <= 1 nothing changes, since the rewrite already merged. - Scope. It does not change the
+a asibling (see option D). - Cost. A few small hash collections per scoring
BooleanWeightwith msm > 1; no benchmark was run.
What the checks validated
Applied to a scratch worktree of 645d4fe14a20 and run through gradle with OpenJDK 25.0.3, seed DEADBEEF (2026-10-31):
- stock: the minimal test fails with assertions on and off; the intended-behaviour check's re-run of the upstream msm score test finds 6 violations with k3 = 8, 0 with k3 off;
- with the fix: the minimal test passes with assertions on and off; the finder's BM25 + StableTfl repro (assertions on and off), the independent reproduction's 5 tests and the intended-behaviour check's window test pass (standalone runner, same fix);
- validation-only checks:
count(q)andcount(new ConstantScoreQuery(q))on(a a b)~2return 2 and the scoring rewrite still returns the query unchanged; deepCheckHits.checkExplanationspasses for msm 0-3; SHOULDax3,b,cscores the same for msm 0-5; explicitly boosted duplicates stay linear; k3-off scores unchanged; - the invariant re-run: 4 violations left, all msm 1 queries with the duplicate split across occurs or nesting (the
+a asibling), 0 with k3 off; TestBooleanQuery,TestBooleanRewrites,TestBooleanMinShouldMatch,TestBoolean2,TestBooleanScorer,TestBooleanOr,TestBM25Similarity,TestStableTflSimilarity,TestQueryRescorer,TestSimilarity: 147 tests, 0 failures;- the whole core
org.apache.lucene.searchtest package: 214 classes, 2,339 tests, 0 failures (49 skipped); checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainfor core pass; the worktree was removed afterwards;- scope: this validates the normal search path, where
IndexSearcherrewrites the query before it creates weights (IndexSearcher#createWeightassumes an already rewritten query,IndexSearcher.java:970-976); code that builds weights for unrewritten queries was not checked.
The hunt's first fix wraps each duplicate SHOULD clause in BoostQuery(q, computeQueryTermWeight(n) / n) during the rewrite when msm > 1. It fixes the scores and passed 99 upstream tests.
Trade-offs
BooleanQuery.rewriteNoScoring strips the boosts again (BooleanQuery.java:228-231, reached from ConstantScoreQuery.rewrite, ConstantScoreQuery.java:44-62), the scoring rewrite adds them back, and IndexSearcher.rewrite loops until it gets the same object back (IndexSearcher.java:871-878). With this patch IndexSearcher.count on an ordinary (a a b)~2 query never returns (20 s timeout; stock main returns). Any rewrite-time fix must keep non-scoring rewrites convergent.
Say in the k3 @param of both similarities and in Similarity#computeQueryTermWeight that saturation applies only where BooleanQuery merges duplicates (duplicate SHOULD clauses only when minimumNumberShouldMatch <= 1).
Trade-offs
No code risk, but the scores keep depending on msm, and the score expectation of TestBooleanMinShouldMatch stays false with k3 on the searcher. A maintainer could reasonably choose it. Not run.
Do option A's counting across SHOULD and MUST occurrences of the same query, which would also cover +a a.
Trade-offs
It has to interact with the MUST merge, which already turns +a +a into +a^1.8, and with explicit boosts, so it needs its own design and tests.
An application that relies on k3 to damp repeated words in user queries does not get that damping for minimum-should-match queries; the worst case is Lucene's default k3-off weighting, and which documents match never changes.
A Z3 model of BooleanQuery's rewrite rules proved that duplicate SHOULD clauses may be merged only when minimumNumberShouldMatch is at most 1; while writing it, the finder noticed that the new k3 weight is applied only where they are merged. A second Z3 model checked the score consequence, and a public-API JUnit confirmed it.
The method in full176 words
Method: semi-formal (the hunt's tier for a hypothesis formed during modelling and confirmed by execution). The hunt unit covered BooleanQuery rewrite and dispatch.
- Rewrite model. A Z3 model of 47 rewrite obligations; obligation R9 ("SHOULD dedup when msm <= 1" preserves matching) is proved, and its mutant R9m ("when msm <= 2") has the counterexample msm = 2 with two equal SHOULD clauses. While writing R9 the finder saw that the k3 weight is applied only inside this dedup.
- Score model. A second Z3 model: the msm 1 and msm 3 paths equal the documented k3 score (UNSAT for a difference), the msm 2 path differs (SAT), and with k3 disabled there is no difference.
- JUnit. A public-API test on the stock jar failed for BM25 and StableTfl with assertions on and off and did not compile on 10.5.2. The minimal repro above is that test cut to one document, one query shape and one assertion.
The solver's own output was not the first signal: the hypothesis came from reading the code while writing the obligation.
No prior report found: no issue, PR, review comment, list post, JIRA entry or downstream report in the searches of 2026-10-25 and 2026-10-26, re-checked 2026-10-31. Closest: #15818 itself, whose review never mentions minimumNumberShouldMatch.
Searches3 searches
- #15818 (the introducing PR): all comments, reviews and inline comments read; they cover the pluggable-similarity design, DFR qtf, NaN/inf checks and the explicit-boost fallback, not minimumNumberShouldMatch.
- #15768 (the open feature request), #15893 (the dedup refactor, kept the guard), #16243 / #16322 (StableTfl; "k3 is not supported on 10x"), #8974 / LUCENE-7925 (the guard), #11654 / LUCENE-10618 (the msm = number of SHOULD clauses rewrite), #5368 / LUCENE-4300 (the precedent).
- Open PRs: none touches the dedup or the
BooleanWeightconstructor (#16578 changes one MatchAllDocsQuery check inBooleanQuery.java; #101, a 2021 discussion-only PR, only makesBooleanWeight.WeightedBooleanClausepackage-private; #16509 changes a test file). - Limits: searches are best effort; private security reports could not be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Elasticsearch, OpenSearch, Solr; all of GitHub) | 2026-10-25, 2026-10-26 | 37 issue/PR, 5 commit and 4 downstream queries, 3 direct downstream and 4 GitHub-wide searches (computeQueryTermWeight, k3 minimumNumberShouldMatch, k3 saturation, deduplicateClauses, createMinShouldMatchQuery, LUCENE-7925, ...); the changed files of all 412 open PRs and of the 800 PRs closed or merged since 2026-03-12; full reads of #15818, #15768, #15893, #16243, #16322 and LUCENE-7925 | only the origin and related items above; none reports the bug |
| Mailing lists (dev@, java-user@, issues@, commits@), JIRA archive, web | 2026-10-25, 2026-10-26 | 36 list queries, 10 JQL queries, 8 web searches | notification mirrors of the PRs only |
| GitHub issues and PRs (apache/lucene) | 2026-10-31 | k3, computeQueryTermWeight, k3 minimumNumberShouldMatch, query-term saturation, StableTfl k3, duplicate SHOULD clauses; k3, computeQueryTermWeight and minimumNumberShouldMatch limited to items updated since 2026-10-20; open PRs mentioning BooleanQuery or BooleanWeight, with their changed files | nothing new: plain k3 returns the same 5 items as before, computeQueryTermWeight only #15818, the other and the dated queries nothing; no open PR touches the dedup or the BooleanWeight constructor |
Introduced by #15818 (05a788f0a4e, merged 2026-03-30), which applied the new k3 weight only inside the 2017 dedup and its msm <= 1 guard; StableTfl has it from #16243. On main and branch_11x; no release has k3.
Versions tested7 rows
Introduced by 05a788f0a4eb7ca44ca881689b2a10c58e22585a, #15818 "Add BM25 k3 query-term frequency saturation" (sgup432; merged to main 2026-03-30; related issue #15768). It added Similarity#computeQueryTermWeight and put its only call into the existing SHOULD and MUST dedup branches (its own BooleanQuery.java:462 and :508); #15893 (55b4574a20d2) later moved that call into deduplicateClauses (:746, which blame at 645d4fe14a20 gives to 55b4574a20d2). Blame gives the guard line (:442) to LUCENE-7925 (ab793e7ab568, 2017-08-21, first released in 7.1.0).
Not an older bug that k3 exposed: before k3, merged and unmerged duplicates both summed linearly, so the guard changed no score (k3-free controls on 9.12.3, 10.5.2, the parent 5af15dc4be5, 05a788f0a4e and main).
Later: #15893 (55b4574a20d2, 2026-04-14) moved both branches into deduplicateClauses and kept the guard; #16243 (e3a7a733c8a, 2026-07-01) added StableTflSimilarity with the same formula; #16667 changed only MUST_NOT handling.
Now (refs fetched and live heads read 2026-10-31): branch_11x (the 11.x branch, version 11.0.0; no branch_11_0 exists yet; live head d0c0decc6606, 5 commits after the fetched 603af870375, none touching these files) and main (2f424fd428da, now 12.0.0-SNAPSHOT) carry the files involved byte-identical to 645d4fe14a20; CHANGES.txt on branch_11x lists GITHUB#15818 under 11.0.0. The 10.6.0 tag has no k3.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, assertions on and off (gradle and standalone runner); passes with the fix |
main ea57360912ed, a9779ef3c193 | affected | the finder's test fails 2 of 2 (BM25 and StableTfl) |
05a788f0a4e (#15818) | introducing | core-only BM25 repro fails with assertions on and off: 0.9568421 / 1.0150898 / 0.9568421 at msm 1 / 2 / 3 |
e3a7a733c8a (#16243) | affected | BM25 and StableTfl both fail |
5af15dc4be5 (parent of #15818) | not affected | no k3 API (repro does not compile); k3-free control: one score for msm 1, 2 and 3 |
main 2f424fd428da, branch_11x 603af870375 (live head d0c0decc6606) | same code | files involved unchanged from 645d4fe14a20 (read, not run) |
| 10.6.0, 10.5.2, 9.12.3 | not affected | no k3 API: 10.5.2 and 9.12.3 cannot compile the repro (run); 10.6.0 has no k3 (read) |
Reproduced by an independent reproducer (five-clause window, QueryBuilder path), a devil's-advocate verifier (upstream msm score test fails with k3 on the searcher), three executed reviews by OpenAI GPT-5.6, an adjudication with a fresh seed and this doc's gradle run. One review showed the first fix hangs count(); the recommended fix passes every repro and test suite run.
Checks and verdicts322 words
Every check ran its own tests or re-ran an earlier one on stock jars; the cross-model reviewers executed code.
| Check | Verdict | What it found |
|---|---|---|
| Finder (Z3, then JUnit) | candidate | Z3: the msm <= 1 guard is necessary (R9m counterexample) and only the msm 2 path misses the k3 score; JUnit fails 2/2 (BM25 and StableTfl) with assertions on and off; does not compile on 10.5.2. |
| Refute lens (OpenAI GPT-5.6, executed) | real (high) | Own test fails with assertions on and off, two seeds; the msm 1 and k3-disabled controls pass. |
| Intended lens (OpenAI GPT-5.6, executed) | real (high) | Intended argument moderate but rejected; own BM25 and StableTfl repros fail; narrowed the claim to 2 <= msm < number of SHOULD clauses. |
| Independent reproducer | real | Own 5-test class fails 4 of 5 (two seeds, assertions on and off), k3-disabled control passes; five-clause window msm 2-4 linear; QueryBuilder path; 10.5.2 and 9.12.3 cannot compile it. |
| Root-cause-and-fix lens (OpenAI GPT-5.6, executed) | real (high); first fix rejected | Root cause agrees; the rewrite-time fix makes IndexSearcher.count on (a a b)~2 never return. |
| Intended-behaviour devil's advocate | real | Every intended argument rejected; upstream msm score test re-run with k3 = 8 on the searcher: 6 violations in 2,000 queries, 0 with k3 off; per-field wrapper probe. |
| Adjudication | confirmed (high) | Re-ran the finder's (2/2 fail) and the independent reproduction's (4/5 fail) repros with seed 7A11D6E1; required that the rewrite-time fix not be presented as a fix. |
| This doc | real; fix A validated | Gradle in a scratch worktree of 645d4fe14a20: the minimal test fails with assertions on and off; the recommended fix passes it, the finder's, the independent reproduction's and the intended-behaviour check's repros, the validation checks (non-scoring count() converges, explain matches score), 147 tests of the closest suites and 2,339 tests of the search package; lint passes. The +a a sibling's 4 invariant violations remain, as expected. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 472 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,348 words
- Registry title
- BM25Similarity/StableTflSimilarity k3 query-term saturation is skipped for duplicate SHOULD clauses when 2 <= minimumNumberShouldMatch < number of SHOULD clauses
- Area
- search / BooleanQuery rewrite and similarities
- Priority
- Low, rank 727: Moved down from Medium: opting into the new BM25/StableTfl k3 parameter skips query-term saturation for duplicate SHOULD clauses under minimum-should-match, changing scores with no demonstrated rank change, in unreleased main only, so a cheap fix before 11.0.
- Impact class
- silent wrong results
- Impact note
- Only applications on unreleased main (11.0.0) that opt into k3 >= 0 on BM25Similarity or StableTflSimilarity used as the searcher's own similarity (PerFieldSimilarityWrapper does not pass computeQueryTermWeight through), and that run a BooleanQuery with a repeated unboosted SHOULD term and 2 <= minimumNumberShouldMatch < number of SHOULD clauses, for example QueryBuilder.createMinShouldMatchQuery on text with a repeated token; any scale; only scores change (about 5-10% of the total in the small examples, a factor of 4.8 for a term repeated 50 times), never above the k3-disabled score; the set of matching documents does not change, and no verifier showed two documents swapping rank.
- Summary
- You turn on BM25's opt-in k3 parameter (new BM25Similarity(1.2f, 0.75f, true, 8f), or StableTflSimilarity with k3), whose javadoc promises that a term repeated in a query is weighted ((k3 + 1) * qtf) / (k3 + qtf) instead of linearly, and you search with a BooleanQuery that repeats a SHOULD term, for example QueryBuilder.createMinShouldMatchQuery('body', 'a a b', fraction). You expect a document that matches every clause to get the same saturated score whatever minimumNumberShouldMatch is. Instead, when 2 <= minimumNumberShouldMatch < the number of SHOULD clauses, the repeated term is summed linearly: with k3=8 the document 'a b' scores 1.0150898 at msm=2 but 0.9568421 at msm=1 and at msm=3 (all clauses required).
- Introduced
- 05a788f0a4eb (#15818 'Add BM25 k3 query-term frequency saturation', related issue #15768) [read: git blame, the computeQueryTermWeight call inside the SHOULD-dedup branch comes from this commit and the minimumNumberShouldMatch <= 1 guard line from LUCENE-7925; exec: a core-only repro fails at 05a788f0a4e with -ea and -da and does not compile at its parent 5af15dc4be5 (no k3 API), and a k3-free control is linear at both]; StableTflSimilarity has the same behaviour from its first commit e3a7a733c8a (#16243) [exec]; not an older bug that k3 exposed: the guard (LUCENE-7925, ab793e7ab568 on main, 7.x backport 325263a9398, 2017-08-21) changed no score before k3, because merged and unmerged duplicates both sum linearly [exec: k3-free controls on 9.12.3, 10.5.2, 5af15dc4be5, 05a788f0a4e and main] (2026-03-30 (#15818 merged; StableTflSimilarity k3 since 2026-07-01, #16243))
- First affected version
- unreleased (11.0.0, main only; no release tag contains 05a788f0a4e or e3a7a733c8a; CHANGES.txt lists #15818 under 11.0.0)
- Affected versions
- main from 05a788f0a4e (2026-03-30) through ea57360912ed for BM25Similarity with k3 >= 0, and from e3a7a733c8a (2026-07-01) for StableTflSimilarity with k3 >= 0 [exec at 05a788f0a4e and main with -ea and -da, and at e3a7a733c8a]; not affected: every release, including 10.5.2 and 9.12.3 (no k3 API, the repro does not compile; a k3-free control scores msm=1, 2 and 3 identically) [exec]; branch_10x and branch_10_6 have no computeQueryTermWeight and no k3, so 10.6.0 (released 2026-10-29) is not affected [read]; not fixed upstream as of main ea57360912ed, the upstream main HEAD on 2026-10-26 [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by Z3
- Upstream and prior reports
- none found (2026-10-25 and 2026-10-26: a scripted prior-report search with 37 GitHub issue/PR, 5 commit, 4 downstream-repo, 36 mailing-list (dev@, java-user@, issues@, commits@) and 10 JIRA-archive queries; 3 direct downstream searches (Elasticsearch, OpenSearch, Solr) and 4 GitHub-wide searches; 8 web queries; changed-file lists of all 412 open PRs and of the 800 PRs closed or merged since 2026-03-12; full reads of #15818 (all conversation comments, reviews and inline comments), #15768, #15893, #16243, #16322 and LUCENE-7925); related prior items: #15818 (introduced the feature; no review comment mentions minimumNumberShouldMatch), #15768 (open feature request), #15893 (dedup refactor, kept the guard), #16243 and #16322 (StableTfl; 'k3 is not supported on 10x'), #8974 / LUCENE-7925 (origin of the msm <= 1 guard), #11654 / #965 LUCENE-10618 (the msm == number of SHOULD clauses -> MUST rewrite), #5368 / LUCENE-4300 (precedent: scores that depended on the rewrite shape, fixed); no open PR touches the code
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner; with the recommended fix it passes, together with the finder's, the independent reproduction's and the intended-behaviour check's repros, validation checks, the closest suites and the whole coreorg.apache.lucene.searchtest package. Earlier runs: mainea57360912edanda9779ef3c193, the introducing commit05a788f0a4e,e3a7a733c8a, and 10.5.2 and 9.12.3 (no k3 API). Upstream main2f424fd428da(now 12.0.0-SNAPSHOT) andbranch_11x(603af870375; live headd0c0decc6606, whose 5 newer commits touch none of these files) carry the same files [read].
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:438-447 (SHOULD dedup comment and the minimumNumberShouldMatch <= 1 guard at :442), :449-455 (MUST dedup, unconditional), :570-587 (fewer SHOULD clauses than msm -> MatchNoDocsQuery; equal -> every SHOULD becomes MUST), :714-758 (deduplicateClauses; computeQueryTermWeight at :746, the only production caller; explicit-boost linear fallback commented at :740-742), :222-234 (rewriteNoScoring strips BoostQuery)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/BM25Similarity.java:44-46 (k3 @param: 'their boost is computed as ((k3 + 1) * qtf) / (k3 + qtf) instead of linear summing'), :121-123 (default constructor, k3 = -1), :125-136 (computeQueryTermWeight)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/StableTflSimilarity.java:50 (class javadoc 'query-side saturation for repeated query terms'), :103-105 (k3 @param, same wording), :153-164 (computeQueryTermWeight, same formula)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:164-177 (computeQueryTermWeight: 'used during query rewriting to compute the boost for duplicate query terms', @lucene.experimental)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/PerFieldSimilarityWrapper.java (no computeQueryTermWeight override)a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:146 (createMinShouldMatchQuery)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/ConstantScoreQuery.java:45-70 and IndexSearcher.java:871-878 (non-scoring rewrite and the rewrite loop that runs until the same object comes back; relevant to the fix hazard)a Lucene main checkout lucene/core/src/test/org/apache/lucene/search/TestBooleanMinShouldMatch.java:312-410 (testRandomQueries and assertSubsetOfSameScores; comment at :399 on '(field:v field:v field:v) gets rewritten into field:v^3')a Lucene main checkout lucene/test-framework/src/java/org/apache/lucene/tests/search/similarities/RandomSimilarity.java:123 (new BM25Similarity(), k3 disabled)a Lucene main checkout lucene/core/src/test/org/apache/lucene/search/TestBooleanRewrites.java:610 (testDeduplicateShouldClauses, msm=2 duplicates stay unmerged), :1137 and :1153 (k3 tests, msm=0 only), :1173 (testDeduplicateWithExplicitBoostsFallsBackToLinearSum)
- The finding in 30 seconds
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/BM25Similarity.java:44-46, :121-123, :125-136a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/StableTflSimilarity.java:50, :103-105, :153-164a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:164-177a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:438-447, :449-455, :570-587, :714-758 (call at :746; explicit boosts :740-742)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/BooleanWeight.java:49-62
- Who is affected
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/PerFieldSimilarityWrapper.java:31 (abstract, extends Similarity; no computeQueryTermWeight override); Similarity.java:175 (public, not final); BooleanQuery.java:734, :746a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:146-167 (createMinShouldMatchQuery; msm = (int) (fraction * clauses))
- Why it looks unintended
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/BM25Similarity.java:44-46a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/StableTflSimilarity.java:103-105a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:164-177a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:740-742a Lucene main checkout lucene/core/src/test/org/apache/lucene/search/TestBooleanRewrites.java:610, :634-642, :1137, :1153, :1173a Lucene main checkout lucene/core/src/test/org/apache/lucene/search/TestBooleanMinShouldMatch.java:312-360, :363, :398-399a Lucene main checkout lucene/test-framework/src/java/org/apache/lucene/tests/search/similarities/RandomSimilarity.java:68, :123a Lucene main checkout lucene/test-framework/src/java/org/apache/lucene/tests/util/SetupAndRestoreStaticEnv.java:230; LuceneTestCaseParent.java:2638 (newSearcher sets the class-environment similarity)
- Suggested fix
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/ConstantScoreQuery.java:44-62; IndexSearcher.java:871-878, :970-976; BooleanQuery.java:228-231
- History
a Lucene clone (refs fetched 2026-10-31: origin/main 2f424fd428da, origin/branch_11x 603af870375, tag releases/lucene/10.6.0; git diff 645d4fe14a20 against both for the six files involved: empty)gh api, read-only, 2026-10-31: live heads main 2f424fd428da and branch_11x d0c0decc6606; compare 603af870375...branch_11x: 5 commits, none touching the six files involved
- TestK3SaturationMinShouldMatch.java (one test, public API):
repro/LFV-103/src/org/apache/lucene/search/TestK3SaturationMinShouldMatch.java(61 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and an instrumented run of it (the rewritten query and score for msm 0 to 3, with k3 = 8 and with k3 disabled).
assets/LFV-103/bug.png(472 KB)