The examples date from Lucene 3.1 and the table was last right in 4.3; the API changes since then never updated the page. The filters themselves work as designed.
- A decompounding filter keeps each compound word and adds the parts it finds as extra tokens at the same position (posIncr=0): "Drahtschere" (wire cutters) becomes Drahtschere, Draht, schere.
HyphenationCompoundWordTokenFilterfinds candidate parts with a hyphenation grammar (an XML file you download separately);DictionaryCompoundWordTokenFilterchecks substrings against a dictionary.- Every token carries a start and an end offset, its character positions in the original text. Highlighters use them to mark what matched.
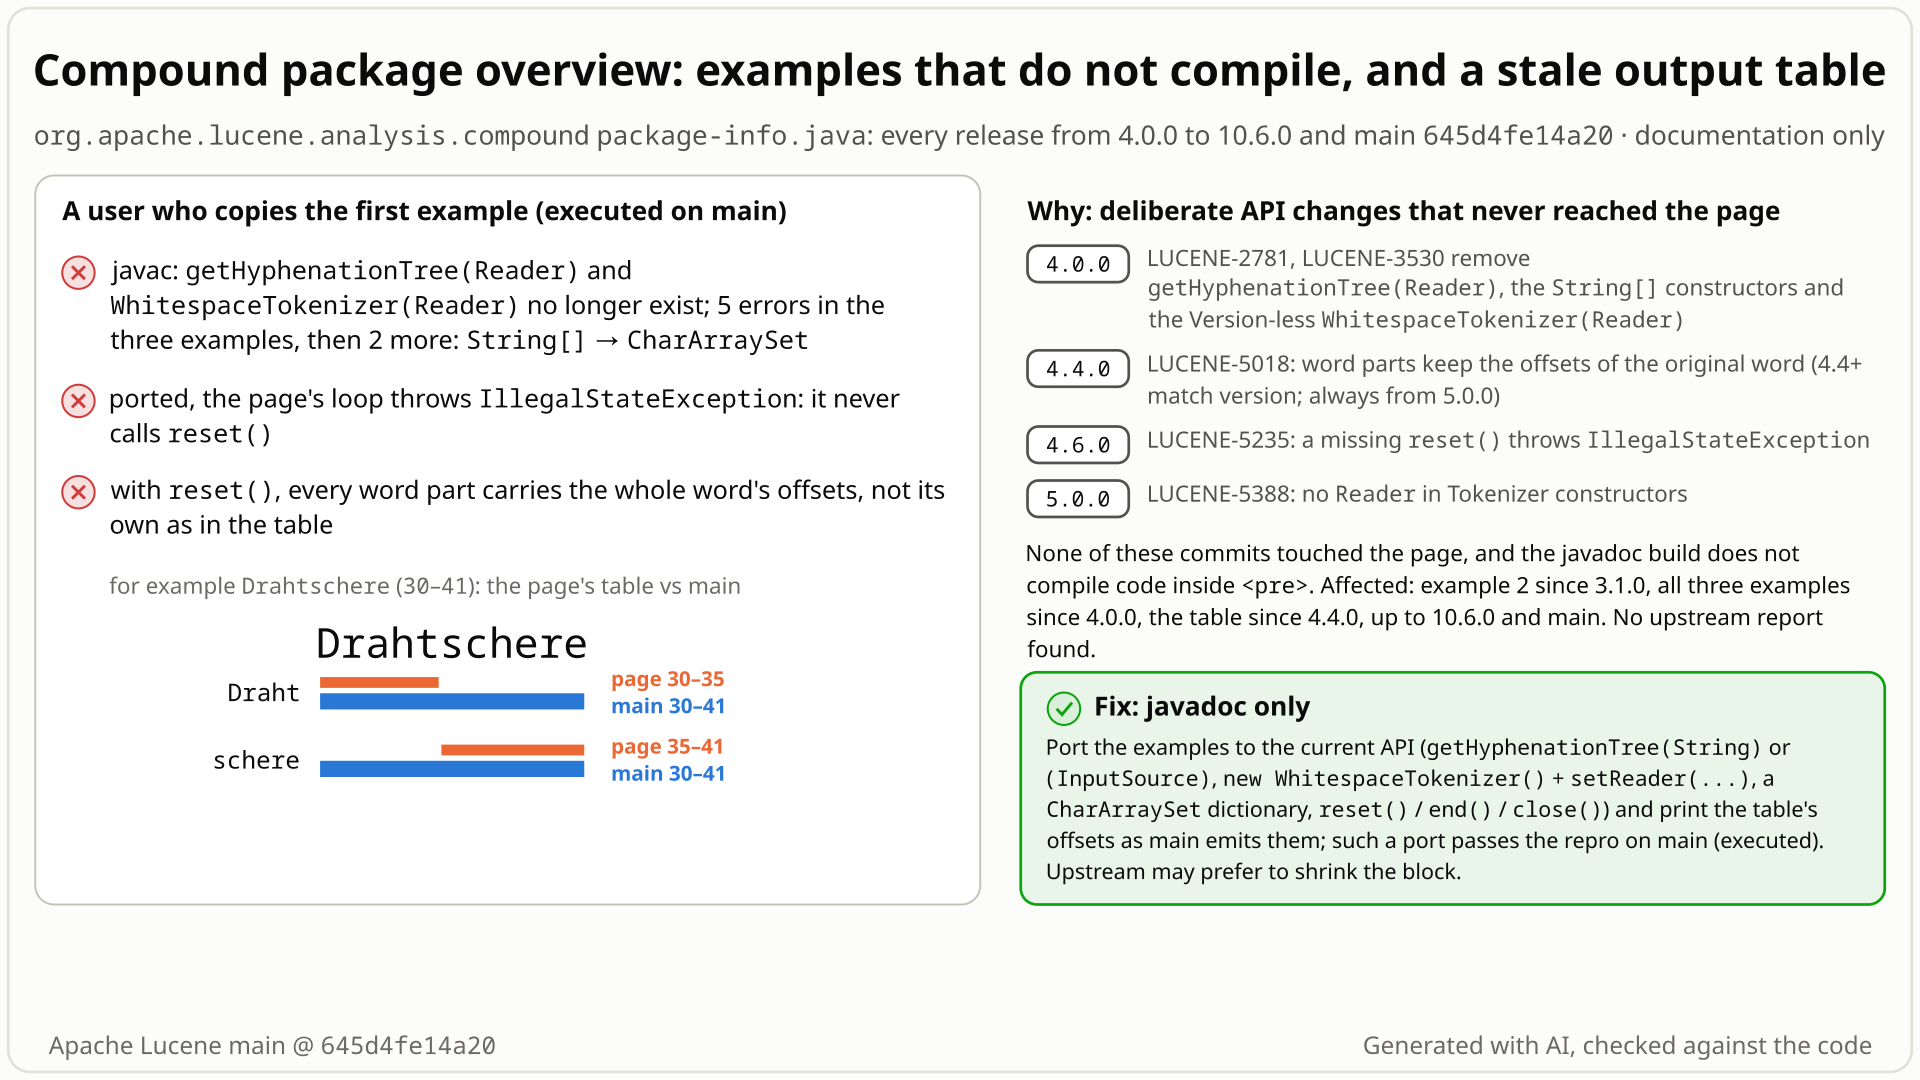
- You want to split German compound words and copy the package overview's first example: it loads a grammar with
getHyphenationTree(new FileReader("de_DR.xml")), tokenizes "Rindfleischüberwachungsgesetz Drahtschere abba" withnew WhitespaceTokenizer(new StringReader(...))and passes aString[]dictionary. - You expect it to compile and to produce the page's output table, which "shows what it does": the word itself plus Rind (offsets 0-4), fleisch (4-11), überwachung (11-22) and gesetz (23-29).
- Instead javac reports 5 errors for the three examples on main:
getHyphenationTree(Reader)andWhitespaceTokenizer(Reader)no longer exist. Fix those and 2 more appear, because both filters now take aCharArraySetdictionary. No release since 4.0.0 compiles them (4.10.x, which briefly hadWhitespaceTokenizer(Reader)again, reports 4 errors). - Port it and the loop throws
IllegalStateException("reset()/close() call missing"): it never callsreset(). Addreset()and it runs, but every part has the whole word's offsets: (Rind,0,29), (fleisch,0,29), not the table's (Rind,0,4), (fleisch,4,11). - Why: deliberate changes (methods removed in 4.0.0 and 5.0.0, the
reset()check in 4.6.0, whole-word offsets in 4.4.0, unconditional from 5.0.0) never updated the page, and nothing compiles code inside javadoc<pre>blocks.
Developers who adopt the opt-in decompounding filters from the package overview, which is also on the Lucene website. Copying the examples fails loudly, at compile time and then with an exception. The table quietly suggests word parts carry their own offsets, which matters for highlighting. No index, query or search result changes.
Mechanism, terms and numbers586 words
The org.apache.lucene.analysis.compound package overview shows how to split German and Swedish compound words with HyphenationCompoundWordTokenFilter and DictionaryCompoundWordTokenFilter, in three examples and a table of the tokens the filter produces. Copied into code, none of the three examples compiles on any release since 4.0.0: they call getHyphenationTree(Reader), new WhitespaceTokenizer(Reader) and the String[] dictionary constructors, all gone on main (the Version-less WhitespaceTokenizer(Reader) was back in 4.10.x only; today: getHyphenationTree(String) or (InputSource), new WhitespaceTokenizer() plus setReader, and a CharArraySet dictionary). Once ported, the page's loop throws IllegalStateException because it never calls reset(). With reset() it runs, but every word part carries the offsets of the whole word, for example (Rind,0,29) where the table shows (Rind,0,4): a deliberate change of 4.4.0 (LUCENE-5018, for a match version of 4.4 or later; unconditional since 5.0.0) that the table never picked up. The filters work as designed; only the page is wrong, and a javadoc-only fix solves it (validated); shrinking the block is an alternative (not run).
The overview opens with "A filter that decomposes compound words you find in many Germanic languages into the word parts. This example shows what it does:" (package-info.java:19-20 at 645d4fe14a20), the input Rindfleischüberwachungsgesetz Drahtschere abba and an output table (:40-64): (Rindfleischüberwachungsgesetz,0,29), (Rind,0,4,posIncr=0), (fleisch,4,11,posIncr=0), (überwachung,11,22,posIncr=0), (gesetz,23,29,posIncr=0), (Drahtschere,30,41), (Draht,30,35,posIncr=0), (schere,35,41,posIncr=0), (abba,42,46). The section "Examples" (:139) holds three methods in a <pre><code class="language-java"> block (:141-195).
| example | stale calls (page line) | current API |
|---|---|---|
1, hyphenation + dictionary, German (:142-162) | String[] dict (:143); getHyphenationTree(reader) on a FileReader (:146-149); new WhitespaceTokenizer(new StringReader(...)) (:152) | getHyphenationTree(String) and (InputSource) only (HyphenationCompoundWordTokenFilter.java:166, :177); every dictionary constructor takes a CharArraySet (:48, :73, :106); new WhitespaceTokenizer() plus setReader (WhitespaceTokenizer.java:34-66 has no Reader constructor) |
2, hyphenation only (:164-178) | getHyphenationTree(reader) (:165-168); WhitespaceTokenizer(StringReader) (:171) | the (TokenStream, HyphenationTree) constructor it calls exists (:150) |
3, dictionary only, Swedish (:180-194) | String[] dict (:181-183); WhitespaceTokenizer(StringReader) (:186-188) | DictionaryCompoundWordTokenFilter(TokenStream, CharArraySet) (DictionaryCompoundWordTokenFilter.java:39) |
| all three, the token loop | incrementToken() with no reset(), end() or close() | the consumer workflow: reset(), incrementToken() until false, end(), close() (TokenStream.java:49-61) |
javac reports 5 errors first (2 for getHyphenationTree(java.io.Reader), 3 for WhitespaceTokenizer(java.io.StringReader)); with those two calls fixed it reports String[] cannot be converted to CharArraySet twice.
A tokenizer reads from a placeholder reader until reset() swaps in the reader given to setReader (Tokenizer.java:100-104). Reading the placeholder throws IllegalStateException("TokenStream contract violation: reset()/close() call missing, ...") (Tokenizer.java:111-118).
Each part is a CompoundToken, which copies the current token's offsets (CompoundWordTokenFilterBase.java:163-165):
      // offsets of the original word
      this.startOffset = CompoundWordTokenFilterBase.this.offsetAtt.startOffset();
      this.endOffset = CompoundWordTokenFilterBase.this.offsetAtt.endOffset();
So "Rindfleischüberwachungsgesetz" (offsets 0-29) yields (Rind,0,29), (fleisch,0,29), ... and "Drahtschere" (30-41) yields (Draht,30,41), (schere,30,41). Lucene's own TestCompoundWordTokenFilter.testDumbCompoundWordsSE (:147), the page's example 3 with the same name, dictionary and input, asserts start offsets 0, 0, 0, 8, 8, 8, ... and end offsets 7, 7, 7, 16, 16, 16, ... (:207-215).
The term list itself depends on the grammar: the page's de_DR.xml cannot be bundled (package-info.java:88-98), and the hunt checked the terms with a hand-written 4-pattern grammar only. The offsets do not depend on the grammar.
Exposure and likelihood204 words
- Who. Developers who start with the decompounding filters from the package overview, the page the javadoc shows first for
org.apache.lucene.analysis.compound. It is published on the Lucene website too: an independent verifier fetched the 10.3.1 page, which still showsgetHyphenationTree(reader),new WhitespaceTokenizer(new StringReaderand(Rind,0,4,posIncr=0), and the fact check found the same on the published 10.3.1 and 10.6.0 pages on 2026-11-01. - Opt-in. The filters are in lucene-analysis-common and no built-in analyzer uses them (outside the
compoundpackage only the factory service registration, theTestRandomChainstest and the release notesCHANGES.txtandMIGRATE.mdname them). Users add them in code or throughDictionaryCompoundWordTokenFilterFactoryandHyphenationCompoundWordTokenFilterFactory. - What they get. First compile errors that name the missing members, then an
IllegalStateExceptiononce ported: loud, nothing wrong runs silently. The quiet part is the table: it shows per-part offsets that the filters have not produced since 4.4.0 (for a match version of 4.4 or later; at all since 5.0.0), so someone building highlighting or other offset-based features on decompounded tokens is misled about what the filter emits. How many readers rely on the table was not measured. - Scale. Every release from 4.0.0 to 10.6.0 and main; no configuration, data size or special input is involved.
One JUnit class, public API only, no randomness. testExamplesCompile compiles the page's three examples verbatim with the JDK compiler and expects no errors; testTableOffsets checks the table's offsets for "Drahtschere". Copy it into the analysis-common tests and run it with Gradle, or compile it against the built jars.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.compound;

import java.io.File;
import java.io.StringReader;
import java.net.URI;
import java.util.List;
import java.util.Locale;
import java.util.stream.Collectors;
import javax.tools.DiagnosticCollector;
import javax.tools.JavaFileObject;
import javax.tools.SimpleJavaFileObject;
import javax.tools.ToolProvider;
import org.apache.lucene.analysis.CharArraySet;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestCompoundPackageDoc extends BaseTokenStreamTestCase {

  // Expected: the package overview's three examples (verbatim) compile; actual: 5 javac errors.
  public void testExamplesCompile() throws Exception {
    String source =
        """
        import java.io.*;
        import org.apache.lucene.analysis.compound.*;
        import org.apache.lucene.analysis.compound.hyphenation.HyphenationTree;
        import org.apache.lucene.analysis.core.WhitespaceTokenizer;
        import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
        class Example {
          public void testHyphenationCompoundWordsDE() throws Exception {
            String[] dict = { "Rind", "Fleisch", "Draht", "Schere", "Gesetz",
                "Aufgabe", "Überwachung" };

            Reader reader = new FileReader("de_DR.xml");

            HyphenationTree hyphenator = HyphenationCompoundWordTokenFilter
                .getHyphenationTree(reader);

            HyphenationCompoundWordTokenFilter tf = new HyphenationCompoundWordTokenFilter(
                new WhitespaceTokenizer(new StringReader(
                    "Rindfleischüberwachungsgesetz Drahtschere abba")), hyphenator,
                dict, CompoundWordTokenFilterBase.DEFAULT_MIN_WORD_SIZE,
                CompoundWordTokenFilterBase.DEFAULT_MIN_SUBWORD_SIZE,
                CompoundWordTokenFilterBase.DEFAULT_MAX_SUBWORD_SIZE, false);

            CharTermAttribute t = tf.addAttribute(CharTermAttribute.class);
            while (tf.incrementToken()) {
               System.out.println(t);
            }
          }

          public void testHyphenationCompoundWordsWithoutDictionaryDE() throws Exception {
            Reader reader = new FileReader("de_DR.xml");

            HyphenationTree hyphenator = HyphenationCompoundWordTokenFilter
                .getHyphenationTree(reader);

            HyphenationCompoundWordTokenFilter tf = new HyphenationCompoundWordTokenFilter(
                new WhitespaceTokenizer(new StringReader(
                    "Rindfleischüberwachungsgesetz Drahtschere abba")), hyphenator);

            CharTermAttribute t = tf.addAttribute(CharTermAttribute.class);
            while (tf.incrementToken()) {
               System.out.println(t);
            }
          }

          public void testDumbCompoundWordsSE() throws Exception {
            String[] dict = { "Bil", "Dörr", "Motor", "Tak", "Borr", "Slag", "Hammar",
                "Pelar", "Glas", "Ögon", "Fodral", "Bas", "Fiol", "Makare", "Gesäll",
                "Sko", "Vind", "Rute", "Torkare", "Blad" };

            DictionaryCompoundWordTokenFilter tf = new DictionaryCompoundWordTokenFilter(
                new WhitespaceTokenizer(
                    new StringReader(
                        "Bildörr Bilmotor Biltak Slagborr Hammarborr Pelarborr Glasögonfodral Basfiolsfodral Basfiolsfodralmakaregesäll Skomakare Vindrutetorkare Vindrutetorkarblad abba")),
                dict);
            CharTermAttribute t = tf.addAttribute(CharTermAttribute.class);
            while (tf.incrementToken()) {
               System.out.println(t);
            }
          }
        }
        """;
    JavaFileObject unit =
        new SimpleJavaFileObject(URI.create("string:///Example.java"), JavaFileObject.Kind.SOURCE) {
          @Override
          public CharSequence getCharContent(boolean ignoreEncodingErrors) {
            return source;
          }
        };
    DiagnosticCollector<JavaFileObject> diagnostics = new DiagnosticCollector<>();
    // Gradle puts Lucene on the module path, plain java on the class path: compile against both.
    String classpath =
        System.getProperty("java.class.path")
            + File.pathSeparator
            + System.getProperty("jdk.module.path", "");
    List<String> options =
        List.of("-cp", classpath, "-d", createTempDir().toString(), "-proc:none");
    boolean ok =
        ToolProvider.getSystemJavaCompiler()
            .getTask(null, null, diagnostics, options, null, List.of(unit))
            .call();
    assertTrue(
        diagnostics.getDiagnostics().stream()
            .map(d -> "line " + d.getLineNumber() + ": " + d.getMessage(Locale.ROOT))
            .collect(Collectors.joining("\n")),
        ok);
  }

  // Expected (page table): Draht 0-5, schere 5-11; actual: both parts get the whole word's 0-11.
  public void testTableOffsets() throws Exception {
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader("Drahtschere"));
    CharArraySet dict = new CharArraySet(List.of("Draht", "schere"), true);
    assertTokenStreamContents(
        new DictionaryCompoundWordTokenFilter(tokenizer, dict),
        new String[] {"Drahtschere", "Draht", "schere"},
        new int[] {0, 0, 5},
        new int[] {11, 5, 11});
  }
}
# copy the file into $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/compound/, then:
./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.compound.TestCompoundPackageDoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)

# or plain javac/java against the built jars; $DEPS = junit 4.13.2, randomizedtesting-runner 2.9.2, hamcrest 3.0
CP=$LUCENE/lucene/core/build/libs/lucene-core-11.0.0-SNAPSHOT.jar:$LUCENE/lucene/codecs/build/libs/lucene-codecs-11.0.0-SNAPSHOT.jar:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-11.0.0-SNAPSHOT.jar:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-11.0.0-SNAPSHOT.jar:$DEPS
javac -encoding UTF-8 -d out -cp "$CP" $REPRO/org/apache/lucene/analysis/compound/TestCompoundPackageDoc.java
java -ea -Dtests.seed=DEADBEEF -cp "out:$CP" org.junit.runner.JUnitCore org.apache.lucene.analysis.compound.TestCompoundPackageDoc
- Expected
- The three examples compile, and Draht and schere get the table's offsets 0-5 and 5-11.
- Observed
- 5 javac errors (getHyphenationTree(Reader) twice, WhitespaceTokenizer(StringReader) three times), and Draht ends at 11: endOffset expected:<5> but was:<11>.
More files, environment, full output406 words
Two small test methods because the page has two independent stale parts. testExamplesCompile holds the page's "Examples" block verbatim (HTML entities decoded; only imports and a class wrapper added; a line-by-line check against the page confirms it) and compiles it in-process with javax.tools against the test JVM's class path and module path. testTableOffsets runs DictionaryCompoundWordTokenFilter on the page's word "Drahtschere" alone, so the table's (Draht,30,35) and (schere,35,41) become 0-5 and 5-11.
javac's line numbers refer to the text block: 14 and 33 are the getHyphenationTree(reader) calls (page lines 149 and 168), 17, 36 and 51 the new WhitespaceTokenizer( lines (152, 171, 186).
It is the hunt's minimal repro with one change: javac gets java.class.path plus jdk.module.path. Under Gradle the test JVM puts Lucene on the module path, so the class-path-only version fails its compile test there for an unrelated reason, even with the fix applied ("27 tests completed, 1 failed"); with the module path added it passes.
Regression test: none suggested. The page is documentation, TestCompoundWordTokenFilter already asserts the whole-word offsets, and this test embeds a copy of the page text, so it would need editing with every page change. If a committer wants one anyway, it is this same test with the corrected block and table.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the released 10.6.0, 10.5.2 and 9.12.3 fail the same way |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the result does not depend on the platform) |
# main 645d4fe14a20, seed DEADBEEF, assertions on (off: identical); javac's "is not applicable" lines shortened
TestCompoundPackageDoc
├─ testTableOffsets ✘ endOffset 1 term=Draht expected:<5> but was:<11>
└─ testExamplesCompile ✘ line 14: no suitable method found for getHyphenationTree(java.io.Reader)
       method ...HyphenationCompoundWordTokenFilter.getHyphenationTree(java.lang.String) is not applicable
       method ...HyphenationCompoundWordTokenFilter.getHyphenationTree(org.xml.sax.InputSource) is not applicable
   line 17: no suitable constructor found for WhitespaceTokenizer(java.io.StringReader)
       constructor ...WhitespaceTokenizer(org.apache.lucene.util.AttributeFactory) is not applicable
       constructor ...WhitespaceTokenizer(int) is not applicable
   line 33: no suitable method found for getHyphenationTree(java.io.Reader)
   line 36: no suitable constructor found for WhitespaceTokenizer(java.io.StringReader)
   line 51: no suitable constructor found for WhitespaceTokenizer(java.io.StringReader)
Tests run: 2, Failures: 2

# the same 2 failures with the released 10.6.0, 10.5.2 and 9.12.3 jars, and through Gradle: 2 tests, 2 failures with assertions on and 2 tests, 2 failures off

# the ported example 1 (current API), without and with reset(), on a 4-pattern test grammar
IllegalStateException: TokenStream contract violation: reset()/close() call missing, reset() called multiple times, or subclass does not call super.reset(). ...
[(Rindfleischüberwachungsgesetz,0,29), (Rind,0,29,posIncr=0), (fleisch,0,29,posIncr=0), (überwachung,0,29,posIncr=0), (gesetz,0,29,posIncr=0), (Drahtschere,30,41), (Draht,30,41,posIncr=0), (schere,30,41,posIncr=0), (abba,42,46)]- The page presents working code: a section headed "Examples", shown as highlighted Java, and a table that "shows what it does".
- The errors name removed members, the loop skips the documented
reset(), and Lucene's own test of example 3 asserts whole-word offsets. - The removals and the offset change were deliberate, but none of those commits touched the page.
The full argument241 words
- The page presents them as working examples. The section is headed "Examples" (
package-info.java:139) with no pseudo-code marker, and the table is introduced with "This example shows what it does" (:20). In January 2026 the block was re-tagged as highlighted Java,<pre><code class="language-java">(#15573,378ca8d1bbf, Dawid Weiss). - Not missing boilerplate. The errors name removed members:
getHyphenationTree(Reader),WhitespaceTokenizer(Reader)and theString[]dictionary constructors. The loop breaks the documented consumer workflow ("The consumer calls reset()",TokenStream.java:54). - The changes that broke it never touched the page (
git show --stat): LUCENE-2781 (a58c26978f5), LUCENE-3530 (a91efbedd1b), LUCENE-5388 (ab0e85fafedon trunk; on branch_5x inside55594bad9b0, the LUCENE-5944 backport commit), LUCENE-5235 (cdb6ea3c022) and LUCENE-5018 (3e893624367/2e92d089832, which changed onlyCHANGES.txt,CompoundWordTokenFilterBaseand its test). Main's CHANGES.txt lists LUCENE-5018 under 4.4.0 ("... don't update offsets anymore"), LUCENE-5235 under 4.6.0 and LUCENE-5388 under 5.0.0. A 2012 commit titled "code snippet improvements: fix out of date api usage" (647b5091697) changed only this block's markup. - Lucene's tests use the current API for the same examples.
TestCompoundWordTokenFilter.testDumbCompoundWordsSEis the page's example 3 with aCharArraySetdictionary, asserting whole-word offsets; the hyphenation tests load their grammar withnew InputSource(getClass().getResource("da_UTF8.xml").toExternalForm()). - Maintainers fix such pages. LUCENE-4788 ("Out of date code examples", #5853) was fixed in 4.2; #16904 (stale examples on the collation page) was approved by a committer on 2026-10-29 and is still open.
The devil's-advocate check187 words
Strongest case for "not a bug": every behaviour involved is deliberate (the removals, the reset() check, the whole-word offsets; per-part offsets were later proposed on #9496, LUCENE-8450, and opposed); the block is informal (test-method names, no imports, a grammar file that is not bundled); the TokenStream contract makes reset() the caller's job; and maintainers know examples rot. Robert Muir wrote on #15225 (2025-10-25): "Code examples need to be kept extremely minimal in the rare cases where it does make sense: the maintenance cost is very high and we don't have great validation for these" (their view).
Why it fails: the deliberate changes are the root cause and place the defect in the page, which is exactly the claim. Nothing marks the code as pseudo-code, the table is presented as what the filter does, and the examples are the page's only usage guidance, so a reader who copies them breaks no rule. The #15225 view argues for fewer, smaller examples: it changes the remedy (port, shrink or delete), not the verdict, and records no decision to keep stale ones. Every verifier and the adjudication reached the same conclusion.
Recommended Port the three examples and correct the table (validated)
Port the three examples to the current API (getHyphenationTree("de_DR.xml"), new WhitespaceTokenizer() plus setReader, a case-insensitive CharArraySet, reset()/end()/close() around the loop) and show whole-word offsets in the table. Javadoc only; validated with the repro, the compound tests, the formatter and the javadoc build. Shrinking the block instead is an alternative (not run).
- *     String[] dict = { "Rind", "Fleisch", "Draht", "Schere", "Gesetz",
- *         "Aufgabe", "Überwachung" };
- *     Reader reader = new FileReader("de_DR.xml");
+ *     CharArraySet dict = new CharArraySet(Arrays.asList("Rind", "Fleisch", "Draht", "Schere",
+ *         "Gesetz", "Aufgabe", "Überwachung"), true);
- *         .getHyphenationTree(reader);
+ *         .getHyphenationTree("de_DR.xml");
+ *     Tokenizer tokenizer = new WhitespaceTokenizer();
+ *     tokenizer.setReader(new StringReader("Rindfleischüberwachungsgesetz Drahtschere abba"));
- *         new WhitespaceTokenizer(new StringReader(
- *             "Rindfleischüberwachungsgesetz Drahtschere abba")), hyphenator,
+ *         tokenizer, hyphenator,
+ *     tf.reset();          (before the loop; tf.end(); tf.close(); after it)
All options and trade-offs4 options · 644 words
One fix (A) was validated in a scratch worktree of 645d4fe14a20. The others were not run. No option changes library code; a CHANGES entry is the committer's call.
Javadoc only, package-info.java, +36/-28. In the table every part gets the whole word's offsets ((Rind,0,29), (fleisch,0,29), (überwachung,0,29), (gesetz,0,29), (Draht,30,41), (schere,30,41)), and the sentence under it says so: "The input token is always preserved, each word part carries the start and end offsets of the whole input token, and the filters do not alter the case of word parts." In all three examples: String[] becomes new CharArraySet(Arrays.asList(...), true), the grammar is loaded with getHyphenationTree("de_DR.xml"), the tokenizer is new WhitespaceTokenizer() plus setReader(new StringReader(...)), and the loop gets tf.reset() before and tf.end(); tf.close(); after it.
- *     String[] dict = { "Rind", "Fleisch", "Draht", "Schere", "Gesetz",
- *         "Aufgabe", "Überwachung" };
- *     Reader reader = new FileReader("de_DR.xml");
+ *     CharArraySet dict = new CharArraySet(Arrays.asList("Rind", "Fleisch", "Draht", "Schere",
+ *         "Gesetz", "Aufgabe", "Überwachung"), true);
- *         .getHyphenationTree(reader);
+ *         .getHyphenationTree("de_DR.xml");
+ *     Tokenizer tokenizer = new WhitespaceTokenizer();
+ *     tokenizer.setReader(new StringReader("Rindfleischüberwachungsgesetz Drahtschere abba"));
- *         new WhitespaceTokenizer(new StringReader(
- *             "Rindfleischüberwachungsgesetz Drahtschere abba")), hyphenator,
+ *         tokenizer, hyphenator,
+ *     tf.reset();          (before the loop; tf.end(); tf.close(); after it)
Trade-offs
- Case-insensitive on purpose: the old
String[]constructors built a case-insensitive set; withfalse, example 1 finds only "Rind" and "Draht". Lucene's own compound tests build their dictionaries the same way. - Grammar by file name,
getHyphenationTree(String)("the filename of the XML grammar to load"). Wrappingnew FileReader(...)in anInputSource, as a first draft did, decodes with the platform charset: the pattern LUCENE-2732 deprecated. A relative name resolves against the working directory. getHyphenationTree(String)hands the name to the XML parser as a system id (new InputSource(hyphenationFilename)); only a relative name in the working directory was run, and with the 4-pattern test grammar, not the OFFOde_DR.xml.- The diff is against main; the 10.6.0 page still has
<pre class="prettyprint">(it lacks #15573's markup change), so a backport needs a rebased diff. - The ported block is still unchecked text and can drift again.
What the checks validated
:lucene:analysis:common:checkGoogleJavaFormat,ecjLintMainandrenderJavadocpass; the rendered page shows the new calls and offsets and none of the stale ones.- Gradle, all compound tests (
org.apache.lucene.analysis.compound.*: 5 classes, 27 tests, including the fix-check copy of the repro) with seedDEADBEEF: 0 failures with assertions on, 0 with assertions off. - The repro with the patched block and table substituted (generated from the patched file, checked line by line; it adds the imports the patched block needs,
java.util.Arrays,CharArraySetandTokenizer) passes with assertions on and off standalone: 2 tests, 0 failures. - The patched example 1 with an offset print added, run on a 4-pattern test grammar named
de_DR.xml, prints(Rindfleischüberwachungsgesetz,0,29) (Rind,0,29) (fleisch,0,29) (überwachung,0,29) (gesetz,0,29) (Drahtschere,30,41) (Draht,30,41) (schere,30,41) (abba,42,46): the corrected table's terms and offsets.
Replace the three examples with a short paragraph (the filters wrap a TokenStream, take a CharArraySet dictionary and, for the hyphenation variant, a grammar from getHyphenationTree), point to DictionaryCompoundWordTokenFilterFactory and HyphenationCompoundWordTokenFilterFactory for configuration, and keep the corrected table.
Trade-offs
Matches the view on #15225 that code examples should be minimal; readers lose a ready-to-run snippet.
Move the examples into a compiled test source and include them with the javadoc {@snippet} tag, as LUCENE-8488 (#9534, open) asks for in general.
Trade-offs
Lucene uses no {@snippet} today, so it needs build work (a snippet path) beyond this page; better as a separate, general proposal.
Correct the offsets and add the sentence about whole-word offsets; leave the examples.
Trade-offs
Smallest change for the part that can mislead quietly; leaves the compile errors.
Run-time behaviour is unchanged; only code written from the page needs a look, for example highlighting that assumes each word part has its own offsets.
Non-formal. An automated sweep compiled the Java code blocks in Lucene's javadoc against main and flagged this page; a follow-up hunt compiled the block verbatim, scanned every release jar for the called methods and ran the ported example. Independent verifiers, including reviewers from another model family (OpenAI GPT-5.6), reproduced it.
The method in full148 words
- Signal (2026-10-28). A capped compile sweep of the non-sandbox javadoc Java blocks against main reported this page's
getHyphenationTree(Reader)andWhitespaceTokenizer(StringReader)errors and listed it as a lead. A follow-up probe then compiled the block verbatim against the stock645d4fe14a20jars. - Hunt (2026-10-29). The hunt wrote the one-test repro, ran it on main (
-ea,-da), 10.5.2, 9.12.3 and the 10.6.0 RC1 jars, scanned every called signature in the cached release jars from 2.4.0 on, found the 2 hiddenString[]errors with a staged compile, and ran the ported example (thereset()throw and the whole-word offsets) on a hand-written 4-pattern grammar. - Checks. A cross-model refute review (OpenAI GPT-5.6, executing its own 4-test JUnit), independent reproducers, an intended-behaviour devil's advocate and an adjudication; then a minimal two-method repro.
- Tier. Non-formal: it compiles documentation code and scans jars for API members; no model checking or proof was involved.
No prior public report found: GitHub issues and PRs (with the migrated JIRA archive), commits, the dev@, java-user@, issues@ and commits@ lists, downstream repositories, the web and Stack Exchange were searched on 2026-10-29 and rechecked on 2026-11-01. Open PRs fix the same kind of defect on other pages (#16904, #16949), not this one.
Searches4 searches
Closest hits, none this bug: #2243 (LUCENE-1166, added the page and table, correct in 2008); #6082 (LUCENE-5018, the offset change, never mentions the page); #9496 (LUCENE-8450, open, states that parts carry the whole token's offsets); #9534 (LUCENE-8488) and #15225 (general proposals about javadoc examples, naming no page); #5853 (LUCENE-4788), #16904, #16823 and #16949 (the same kind of defect on other pages); commit 647b5091697 (2012, markup only on this page). Others are filing stale-javadoc fixes in analysis this week.
| Where | When | How | Found |
|---|---|---|---|
| Scripted searches | 2026-10-29 | 58 queries: 22 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list (dev@, java-user@, issues@, commits@), 5 JIRA-archive, 6 web; plus the finder's (51) and a verifier's (35) runs | 320 hits, none about the page |
| GitHub, manual | 2026-10-29, 2026-11-01 | about 30 searches: getHyphenationTree, compound package-info, HyphenationCompoundWordTokenFilter / DictionaryCompoundWordTokenFilter javadoc and example, the page's sample words, decompound, "package docs", stale javadoc; Solr, Elasticsearch, OpenSearch | related issues only (filter behaviour, other pages) |
| Open PRs | 2026-10-29, 2026-11-01 | changed files of all 412 open PRs (2026-10-29) and of every PR opened since (2026-11-01) | none touches the page; #16949 edits the charfilter and vectorhighlight pages |
| Page history | 2026-11-01 | commits on the file upstream (main, branch_11x, branch_10_6) | last change 378ca8d1bbf (#15573, markup only); unchanged on upstream main f815e679bf6c |
No single commit: today's example text dates from 2010 (LUCENE-1287, first release 3.1.0); LUCENE-2781 removed the methods it calls in 4.0.0, and LUCENE-5018 made word parts keep the whole word's offsets in 4.4.0 (always from 5.0.0). None of these changes updated the page, which is unchanged on upstream main.
Versions tested7 rows
- 2008
7a27cdcbc90(LUCENE-1166, #2243): page, examples and table added; that text compiled on 2.4.0 and 2.9.4 and broke on 3.0.0 whenTokenStream.next()was removed. - 2010-05-19
2c02caead74/ trunkfe5f1aabcb1(LUCENE-1287, #2364, committed by Robert Muir from Thomas Peuss's patch): today's example text; example 2 called a constructor that then existed only with a leadingVersion, so it failed from the start (3.1.0-3.6.2: example 2 fails, examples 1 and 3 compile with deprecation warnings; executed on 3.1.0 and 3.6.2, the releases in between by a bytecode scan of the called signatures). - 2010-11-30
a58c26978f5(LUCENE-2781, #3855, "drop deprecations from trunk"): removedgetHyphenationTree(Reader)(deprecated by LUCENE-2732 for charset problems), the Version-lessString[]constructors andWhitespaceTokenizer(Reader). From 4.0.0 (2012-10-11) all three examples fail. Later:a91efbedd1b(LUCENE-3530, the rest of theString[]forms, 4.0.0);cb9beac7079(LUCENE-5859, 4.10.0) added Version-less constructors,WhitespaceTokenizer(Reader)among them, so 4.10.x reports 4 errors instead of 5; LUCENE-5388 (ab0e85fafed, trunk, backported to branch_5x inside55594bad9b0) removed the Reader from tokenizer constructors in 5.0.0. - 2013-05-28
2e92d089832/ trunk3e893624367(LUCENE-5018, #6082, Adrien Grand): word parts keep the whole word's offsets for a match version of 4.4 or later (older match versions kept per-part offsets through 4.10.4; unconditional in 5.0.0); the table is stale from 4.4.0 (2013-07-22). 2013-09-22cdb6ea3c022(LUCENE-5235): a missingreset()throws, from 4.6.0. - Later page commits (2012
647b5091697, 2015 package.html to package-info.java, 2020 reformatting, 2026 #15573) changed only markup.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; upstream main f815e679bf6c | affected | repro fails with -ea and -da (standalone and Gradle); upstream read, page unchanged |
| 10.6.0, 10.5.2, 9.12.3 | affected | repro fails the same way (released jars) |
| 4.0.0, 4.10.4 | affected | history probe: all 3 examples fail to compile |
| 4.0.0 to 10.0.0 (12 releases) | affected | the fact check's compile of the verbatim block: 5 errors each, 4 on 4.10.0 and 4.10.4 |
| 4.3.1 vs 4.4.0 | table | offsets probe (match version LUCENE_CURRENT) matches the table on 4.3.1; whole-word offsets on 4.4.0 |
| 3.1.0, 3.6.2 | example 2 only | example 2 fails; examples 1 and 3 compile with deprecation warnings |
| 2.4.0, 2.9.4 | not affected | the older 2008 text compiles |
The finder, a refute review and an intended-behaviour review by another model family (OpenAI GPT-5.6), independent verifiers and an adjudication all found it real. This doc's brief re-ran the repro on main, 10.6.0, 10.5.2 and 9.12.3 and validated the fix with Gradle.
Checks and verdicts221 words
Each check ran separately; the refute review and the first verifier wrote and executed their own tests.
| Check | Verdict | What it found |
|---|---|---|
| Finder | reproduced | One-test compile repro on main, 10.5.2, 9.12.3 and the 10.6.0 RC1 jars; bytecode scan of every called signature over the release jars; staged compile; ported example. |
| Refute lens (OpenAI GPT-5.6, executing) | real, high confidence | Own 4-test JUnit: 3 of 4 fail under three seeds (compile errors, IllegalStateException, a part's end offset is the whole token's); a current-API control passes. |
| Reproducer | real | Own test: the 5 errors on main (-ea, -da), 10.5.2 and 9.12.3; the 2 hidden errors; the reset() throw and whole-word offsets. |
| Intended lens (OpenAI GPT-5.6, reading only) | real, medium confidence | Could not run commands; a separate run re-ran the repro on main -da: fail as expected. |
| Devil's advocate | real, high, Low | Argued deliberate removals, informal snippet, examples rot and offsets by design, and rejected each; found the 10.3.1 website page still stale. |
| Adjudication | confirmed, high, minor | Re-ran the independent reproduction's test with a new seed; kept as a Low documentation defect. |
| This doc's brief | real; fix validated | Repro on main (-ea, -da), 10.6.0, 10.5.2 and 9.12.3 (standalone) and through Gradle; fix A with Gradle (format, ecj lint, javadoc, compound tests) and standalone. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 428 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,555 words
- Registry title
- The org.apache.lucene.analysis.compound package overview's three code examples do not compile on any release since 4.0.0: they call HyphenationCompoundWordTokenFilter.getHyphenationTree(Reader), WhitespaceTokenizer(Reader) and the String[] dictionary constructors of both decompounding filters, all removed; their loop never calls reset(), and the page's output table shows per-part offsets that the filters stopped emitting in 4.4.0 (documentation defect)
- Area
- analysis-common / compound (package overview examples and output table, package-info.java)
- Priority
- Low, rank 1241: A compile-time-broken overview page with an outdated offsets table for the opt-in decompounding filters, with no runtime effect.
- Impact class
- minor
- Impact note
- Documentation only, with no runtime effect: a developer who adopts the opt-in decompounding filters (HyphenationCompoundWordTokenFilter, DictionaryCompoundWordTokenFilter) by copying the package overview's three examples gets compile errors on every release since 4.0.0 (5 on main, the 10.6.0 RC1, 10.5.2 and 9.12.3, then 2 more once those are fixed), a loud IllegalStateException once the code is ported, because the loop never calls reset(), and an output table whose per-part offsets the filters have not produced since 4.4.0; no configuration, scale or special input is involved.
- Summary
- The compound package overview shows how to split German and Swedish compound words with HyphenationCompoundWordTokenFilter and DictionaryCompoundWordTokenFilter, in three examples and a table of the tokens the filter produces. Copied into code, none of the three examples compiles on any release since 4.0.0, because getHyphenationTree(Reader), WhitespaceTokenizer(Reader) and the String[] dictionary constructors no longer exist (today: getHyphenationTree(String or InputSource), new WhitespaceTokenizer() plus setReader, and a CharArraySet dictionary), and once ported the loop throws IllegalStateException because it never calls reset(). With those fixes the examples run, but every word part carries the offsets of the whole word, for example (Rind,0,29) where the table shows (Rind,0,4), a deliberate 4.4.0 change (LUCENE-5018) the table never picked up; only the page is wrong.
- Introduced
- No single commit; a page that was never updated across several deliberate API changes [read: git show, log and blame in the full-history clone; exec: the follow-up's history probes on the releases on either side of each change]. Today's example text was written by 2c02caead74 (branch_3x; trunk twin fe5f1aabcb1), LUCENE-1287 'Allow usage of HyphenationCompoundWordTokenFilter without a dictionary' (migrated as #2364), committed by Robert Muir (rmuir) from Thomas Peuss's patch, 2010-05-19, first release 3.1.0: it rewrote the loop to CharTermAttribute/incrementToken() and added example 2, which calls a (TokenStream, HyphenationTree) constructor that the same commit added only with a leading Version argument, so example 2 failed from the start. The break of examples 1 and 3, behind the headline 'none compiles since 4.0.0', is a58c26978f5 (LUCENE-2781 'drop deprecations from trunk', #3855, rmuir, 2010-11-30, first release 4.0.0): it removed getHyphenationTree(Reader) (deprecated by LUCENE-2732, 843b57c4367, Uwe Schindler, 2010-10-31, for charset problems), the Version-less String[] constructors of both filters and the Version-less WhitespaceTokenizer(Reader) without updating the page. Compounded by a91efbedd1b (LUCENE-3530, #4604, Uwe Schindler, 2011-10-25, 4.0.0: the remaining String[] constructors removed, dictionaries are CharArraySet), ab0e85fafed / 55594bad9b0 (LUCENE-5388, rmuir, 2014-01-09 on trunk, branch_5x 2014-09-18, 5.0.0: Reader removed from Tokenizer constructors; LUCENE-5859, cb9beac7079, had briefly restored a Version-less WhitespaceTokenizer(Reader) in 4.10.x) and cdb6ea3c022 (LUCENE-5235, rmuir, 2013-09-22, 4.6.0: a missing reset() throws IllegalStateException). The output table (written with the page by 7a27cdcbc90, LUCENE-1166, 2008) went stale with 2e92d089832 (branch_4x; trunk 3e893624367), LUCENE-5018 'Don't update offsets in CompoundWordTokenFilterBase' (#6082, Adrien Grand (jpountz), 2013-05-28, first release 4.4.0), which changed only CHANGES.txt, CompoundWordTokenFilterBase and its test. Later commits to the page (647b5091697, 2012, 'code snippet improvements: fix out of date api usage'; 8f3a71443bd, LUCENE-6224, 2015; 378ca8d1bbf, #15573, 2026) changed only markup or format (2010-05-19 (2c02caead74 / fe5f1aabcb1, LUCENE-1287: today's example text, example 2 broken from the start); 2010-11-30 (a58c26978f5, LUCENE-2781: examples 1 and 3 break); 2013-05-28 (2e92d089832 / 3e893624367, LUCENE-5018: output table stale))
- First affected version
- 3.1.0 [exec] (the first release with today's text; only example 2 fails there); 4.0.0 [exec] is the first release where all three examples fail; the output table is stale from 4.4.0 [exec]
- Affected versions
- 3.1.0-3.6.2 (example 2 only; examples 1 and 3 compile with deprecation warnings), every release from 4.0.0 to 10.6.0 (all three examples; the output table from 4.4.0; 10.6.0 = the RC1 revision 4ae946e5a9b) and main 645d4fe14a20. [exec: the finder's JUnit fails on main (-ea and -da), 10.5.2 -da and 9.12.3 -da, and plain javac of the block against the 10.6.0 RC1 core and analysis-common jars gives the same 5 errors; the independent reproduction's own JUnit fails on main (-ea and -da), 10.5.2 (-ea and -da) and 9.12.3 -da; the follow-up's history probe (each example compiled separately with the target's jars) fails 1 of 3 on 3.1.0 and 3.6.2 and 3 of 3 on 4.0.0, 4.10.4 and main, and its offsets probe (example 1 ported, 4-pattern grammar) matches the table on 4.3.1 and gives whole-word offsets on 4.4.0; the re-run fails on main with -ea and -da] [static: the finder's bytecode presence scan of every called signature over the cached release jar sets 2.4.0-10.5.2 plus main and the RC: at least one called signature is absent in every jar set from 3.1.0 on]. Not affected: no release has today's text before 3.1.0 (the 2008 text compiled on 2.4.0 and 2.9.4 and broke on 3.0.0 when TokenStream.next() was removed, so no release since 3.0.0 has had a compiling example block on this page). Not fixed upstream: the page is unchanged on main (upstream head 2a32d42e5e85, 2026-10-29) and branch_11x (last change 378ca8d1bbf, #15573, markup only) and on branch_10_6 (last change 8ef6a0da5687, LUCENE-9570, reformatting); branch_10x was decommissioned upstream on 2026-10-29 (#16911) (GitHub commits API, 2026-10-29). Caveat: all runs used JDK 25 on Linux aarch64.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (searched 2026-10-29, with the finder's and the intended-behaviour check's searches; recheck 2026-10-29): scripted searches (22 GitHub issue/PR queries, 3 commit queries, 2 downstream-repository queries, 20 list queries over dev@, java-user@, issues@ and commits@, 5 JIRA-archive queries, 6 web queries; 320 distinct hits, none about the page), about 25 targeted GitHub searches (getHyphenationTree, compound package-info, HyphenationCompoundWordTokenFilter and DictionaryCompoundWordTokenFilter javadoc/example, the page's sample words Rindfleischüberwachungsgesetz and Drahtschere, decompound, 'package docs', stale javadoc and every item created since 2026-10-27), the downstream Solr, Elasticsearch and OpenSearch repositories, a scan of the changed files of all 412 open apache/lucene PRs (only #12478 and #12485 touch analysis/compound, neither the page), the page's commit history on main, branch_11x, branch_10_6 and branch_10x, lists.apache.org and Stack Exchange. Read but not the same bug: #2243 (LUCENE-1166, which added the page and table, correct in 2008), #6082 (LUCENE-5018, the deliberate offset change that made the table stale; it never mentions the page), #9496 (LUCENE-8450, open: states that compound parts carry the original token's offsets), #9534 (LUCENE-8488) and #15225 (generic proposals about javadoc examples, naming no page), #5853 (LUCENE-4788, a fixed stale example on another page), #16904 (collation) and #16823 (charfilter), the same defect class on other pages, #16936, #16680, #12478, #12485, #14624, #4120, #4582, SOLR-2891, a 2009 java-user thread quoting the then-correct table, and commit 647b5091697 (2012, 'fix out of date api usage', which only changed this page's markup). Recheck: the 10 items updated since a recent cutoff (8 PRs, 2 issues) do not touch analysis-common or this page, 7 searches find nothing new, and the page is unchanged on every branch. Tracking issue #16937 does not mention it.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the repro fails with assertions on and off, standalone and through Gradle; the released 10.6.0, 10.5.2 and 9.12.3 jars fail the same way. The follow-up's history probes ran on 2.4.0, 2.9.4, 3.0.0, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.3.1, 4.4.0 and 4.10.4. Fix A was validated in a scratch worktree of645d4fe14a20. Upstream mainf815e679bf6c(2026-11-01) was read: the page is unchanged.
- Finding record
a Lucene main checkout @ 645d4fe14a20: lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/package-info.java:17-66 (intro sentence 'This example shows what it does' and the output table), :139-195 (the Examples block); compound/HyphenationCompoundWordTokenFilter.java:48, :73, :106, :133, :150 (constructors), :166, :177 (getHyphenationTree(String), (InputSource)); compound/DictionaryCompoundWordTokenFilter.java:39, :58 (CharArraySet dictionaries); core/WhitespaceTokenizer.java:34, :42, :53, :66 (no Reader constructor); compound/CompoundWordTokenFilterBase.java:163-165 ('offsets of the original word')
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/package-info.java:19-66, :88-98, :139-195lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/HyphenationCompoundWordTokenFilter.java:48, :73, :106, :150, :166, :177lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/DictionaryCompoundWordTokenFilter.java:39, :58lucene/analysis/common/src/java/org/apache/lucene/analysis/core/WhitespaceTokenizer.java:34, :42, :53, :66lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:49-61; lucene/core/src/java/org/apache/lucene/analysis/Tokenizer.java:100-118lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/CompoundWordTokenFilterBase.java:163-165lucene/analysis/common/src/test/org/apache/lucene/analysis/compound/TestCompoundWordTokenFilter.java:147-220
- Who is affected
lucene/analysis/common/src/java/module-info.java:171-172 and lucene/analysis/common/src/resources/META-INF/services/org.apache.lucene.analysis.TokenFilterFactory:31-32 (factory service registration); lucene/analysis.tests/src/test/org/apache/lucene/analysis/tests/TestRandomChains.java:65, :278; lucene/CHANGES.txt, lucene/MIGRATE.md (grep for CompoundWordTokenFilter and getHyphenationTree outside compound/ at 645d4fe14a20)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/package-info.java:20, :139, :141lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:54lucene/CHANGES.txt:11370, :13043, :13594-13596lucene/analysis/common/src/test/org/apache/lucene/analysis/compound/TestCompoundWordTokenFilter.java:46-50, :147-220
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/HyphenationCompoundWordTokenFilter.java:158-167 (getHyphenationTree(String): the filename of the XML grammar to load)lucene/analysis/common/src/test/org/apache/lucene/analysis/compound/TestCompoundWordTokenFilter.java:42-50a Lucene main checkout: grep for @snippet in lucene/ (no match)
- History
a Lucene clone: CompoundWordTokenFilterBase.java at releases 4.4.0 (:160, the LUCENE_44 gate), 4.10.4 (:174) and 5.0.0 (:141-143, unconditional)a Lucene clone: release tag dates of 4.0.0 (2012-10-11) and 4.4.0 (2013-07-22)
- TestCompoundPackageDoc.java (one class, public API):
repro/LFV-1041/TestCompoundPackageDoc.java(138 lines)
Made in parallel with this doc from the mechanism in the brief; the PNG is the summary frame.
assets/LFV-1041/bug.png(428 KB)