The 4096-doc window loop that #16669 introduced runs the required clause over every window, including windows the exclusion covers completely.
- Doc IDs in a segment follow indexing order or the index sort, so documents indexed together sit next to each other: "everything older than t" is often one long run of consecutive doc IDs.
- For
+R -Xwhere the required side (its cheapest MUST or FILTER clause) is estimated to match more than 0.3% of the segment, Lucene uses a bulk scorer,ReqExclBulkScorer, that collectsR's matches and drops the documentsXmatches. - An iterator can report a run:
docIDRunEnd()says that every doc from the current one up to some end matches, so a caller can jump past all of them in one step. The default postings report runs for dense blocks.
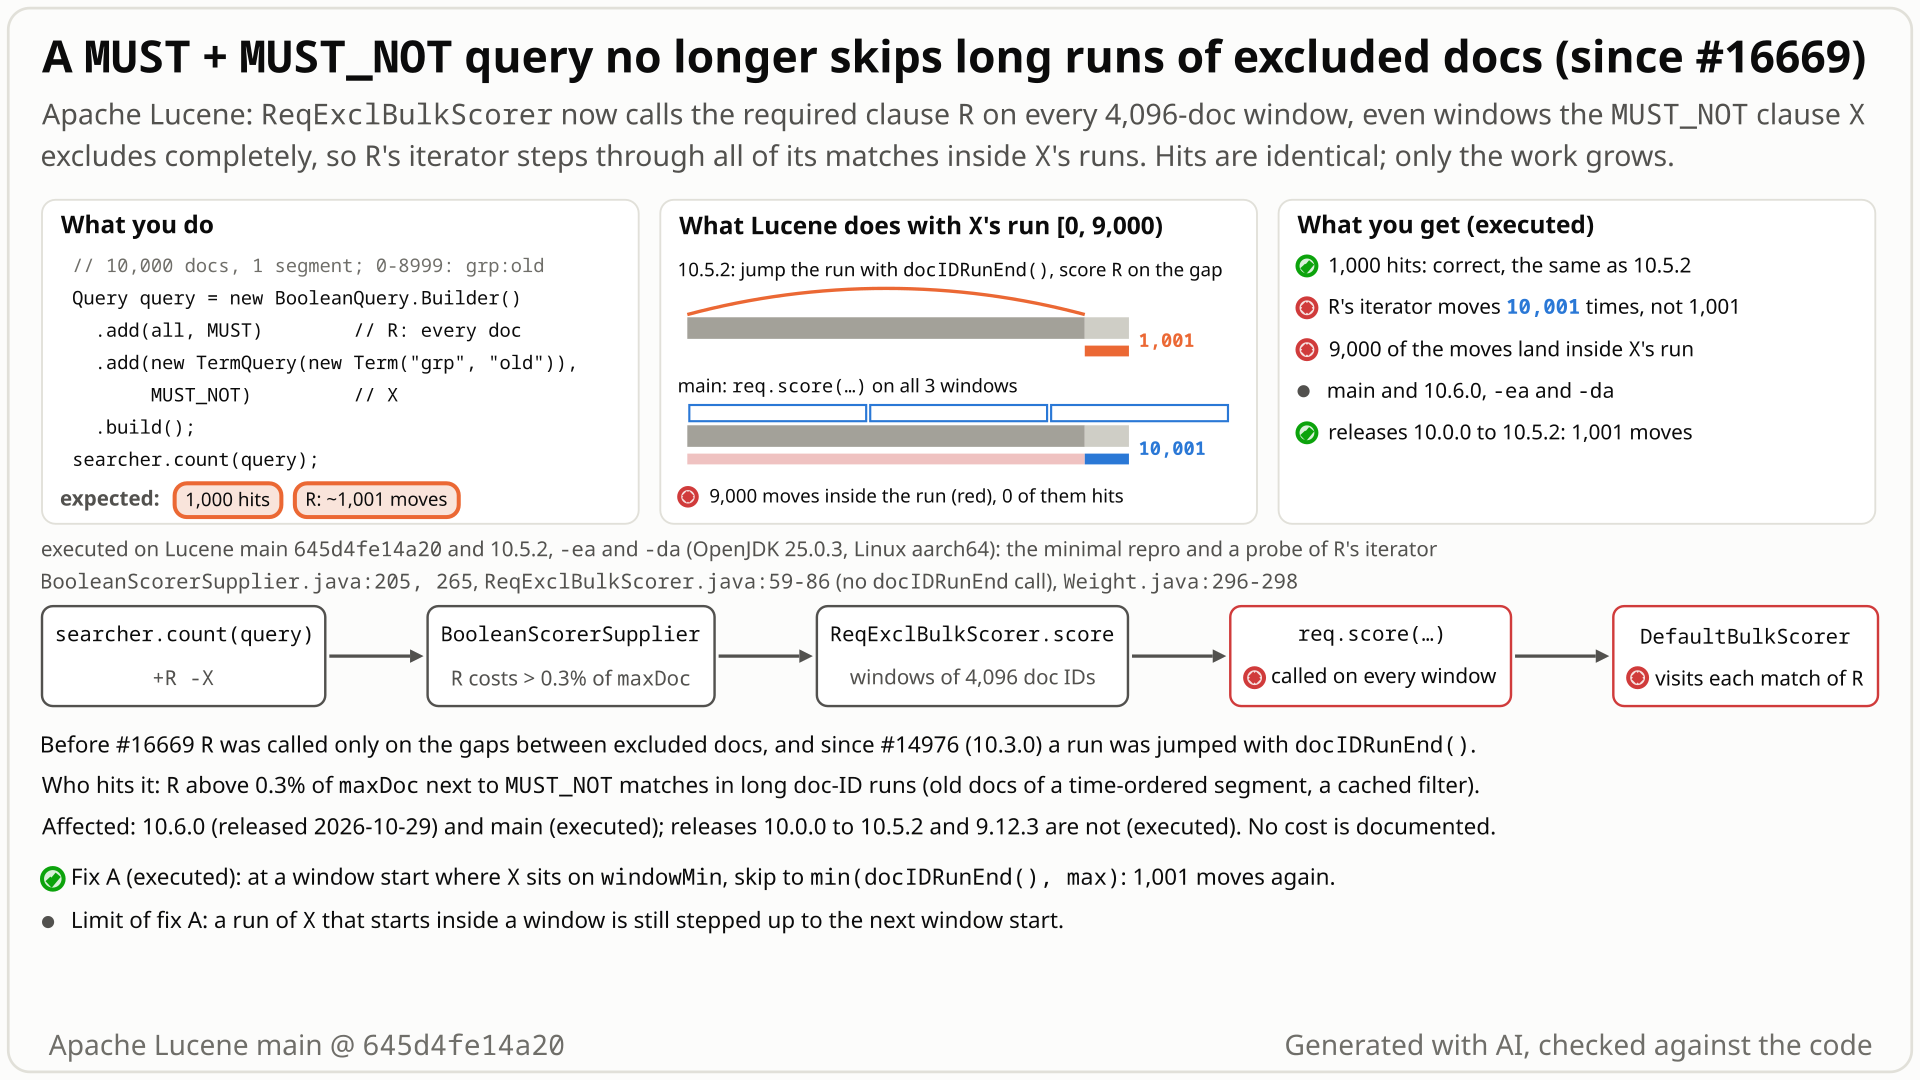
- Index 10,000 documents into one segment; the first 9,000 (doc IDs 0 to 8,999) get
grp:old, like the older documents of an append-ordered index. - Search
+R -grp:old, whereRmatches every document and counts how often its iterator moves. You expect 1,000 hits and about 1,001 moves: Lucene 10.3.0 to 10.5.2 jumps the excluded run withdocIDRunEnd, and no release before 10.6.0 stepsRthrough it. - You get the right 1,000 hits, but
Rmoved 10,001 times, once per document of the segment, on main and on 10.6.0. - Why: since #16669 the scorer works in windows of up to 4,096 docs. It loads the exclusion into a bit mask and always runs
Rover the window, even when the mask accepts nothing, andR's default bulk scorer steps through all its matches before it checks the mask. - With stock queries it is real work: at 1M documents with 99.9% in one excluded run, a phrase query as
Rreads 2,000,000 postings instead of 2,002, and indicative latency grows about 8x to 16x (term top-10: 0.30 to 2.5 ms).
Default settings. Any +R -X query whose required side matches more than 0.3% of a segment and whose MUST_NOT matches form long doc-ID runs: older documents of an append-ordered or time-sorted index, an index-sorted range, a flag on a contiguous block, a cached dense filter. Hits stay exact; the query costs about as much as R alone.
Mechanism, terms and numbers666 words
Since #16669 ("Use intoBitSet to speed up ReqExclBulkScorer with dense exclusions", merged 2026-09-24, first released in 10.6.0 on 2026-10-29), ReqExclBulkScorer scores +R -X in windows of at most 4,096 docs, each starting where the previous call to R's bulk scorer returned: it loads the exclusion of each window into a bit mask, flips it into an accept mask and always calls R's bulk scorer for the window (ReqExclBulkScorer.java:53-93, line 86 on main 645d4fe14a20), even when the mask accepts nothing. The default bulk scorer visits every match of R before it checks the mask (Weight.java:293-315). #16669 also removed the docIDRunEnd skip that 10.3.0 to 10.5.2 used to jump runs of excluded documents without moving R (#14976), and the two-phase variant added in the same cycle (#16307).
So when X excludes a long run of doc IDs (the older documents of an append-ordered or time-sorted segment, an index-sorted range, a flag on a contiguous block, a cached dense filter) and the required side costs more than 0.3% of maxDoc, +R -X costs about as much as R alone. Hits, counts and top-k were identical in every executed case; only the work changes. In the minimal repro (one 10,000-doc segment, run [0, 9000)), a counting match-all R moves 10,001 times on main and on the 10.6.0 release jars, against 1,001 on every release from 10.0.0 to 10.5.2. At 1M documents with 99.9% excluded, a PhraseQuery as R reads 2,000,000 postings instead of 2,002. The 10.6.0 release notes still say that ReqExclBulkScorer "now skips runs of excluded docs". A 12-line change that scores R only over the accepted part of each window never steps R inside an excluded run that crosses a window boundary (any run of 4,096 documents or more), as in 10.5.2, and passes the org.apache.lucene.search tests.
- Routing.
BooleanScorerSupplier.java:203-207: with a MUST_NOT clause and a supplier cost (the cheapest MUST/FILTER clause's cost,computeCost) of at most3L * maxDoc / 1000, the doc-at-a-timeReqExclScorerruns (not affected). Otherwise FILTER/MUST clauses without SHOULD getrequiredBulkScorer()(:235-236) and:259-265returnsnew ReqExclBulkScorer(positiveScorer, prohibitedScorer); several MUST_NOT clauses become one disjunction. - The window loop.
ReqExclBulkScorer.java:53-93: each window is[windowMin, min(max, windowMin + 4096))(:60-61), wherewindowMinis what the previousreq.scorecall returned; the exclusion is advanced to the window (:63-65), loaded withintoBitSet(:67-72), flipped into an accept mask and combined withacceptDocs(:73-84); thenupTo = req.score(collector, windowBits, windowMin, windowMax);(:86) runs for every window. The class has nodocIDRunEndcall left. - Why a rejected window still costs. The default bulk scorer loops
for (int doc = iterator.docID(); doc < max; doc = iterator.nextDoc())and only then checksacceptDocs.get(doc)(Weight.java:293-301; the two-phase loop:303-315also callsmatches()). So a window thatXcovers completely costs one step per match ofRin it. - What it replaced. 10.5.2
ReqExclBulkScorer.java:51-78, the leap-frog loop of LUCENE-6940 (5.5.0/6.0.0): when a non-two-phase exclusion sits onupTo,upTo = Math.min(exclApproximation.docIDRunEnd(), max);(:60-62, from #14976, 10.3.0), a two-phase one is confirmed withmatches()and passed one doc at a time (:63-65), elsereq.score(collector, acceptDocs, upTo, Math.min(exclDoc, max))(:69), soRis only scored on the gaps between excluded documents.
Minimal repro: 10,001 required-iterator moves on main and 10.6.0 against 1,001 on 10.0.0 to 10.5.2, 1,000 hits everywhere. At 1M documents with the run [0, 999000): 1,000,001 against 1,001 moves for five kinds of exclusion (postings run, index-sort range, cached bit set, two-phase doc-values range with a skip index, 2-term disjunction), count and top-10 alike; a stock PhraseQuery as R reads 2,000,000 postings against 2,002. Indicative wall clock on a shared host, 10.5.2 to main: term top-10 0.299 to 2.479 ms, 8-term OR top-10 2.330 to 18.506 ms, phrase count 0.711 to 11.368 ms. The claim rests on the counts, not the timings.
Exposure and likelihood245 words
- Configuration. Default codec,
IndexWriterConfigandIndexSearcher; assertions on or off; single thread. - Which queries. A BooleanQuery with MUST/FILTER clauses and MUST_NOT clauses that
BooleanScorerSuppliersends toReqExclBulkScorer(the required side costs more than 0.3% ofmaxDoc). By code reading the same wrapping also serves a pure SHOULD disjunction with MUST_NOT (not run). - Which data. Many of
R's matches must lie inside long runs of excluded doc IDs. Doc IDs follow indexing order and index sorting, so time-based exclusions on append-ordered or time-sorted segments, index-sorted ranges, flags on contiguous blocks and cached dense filters produce such runs; all five kinds of exclusion tested regress the same way. - How bad. About the cost of
Ralone: at most linear inmaxDocper segment, no hang, no extra memory beyond a 4096-bit mask. Largest whenRdecodes or scores postings per document (term top-k, phrase, disjunction): about 8x to 16x in the indicative timings. Probably small forMatchAllDocsQueryor another dense constant-scoreRwhose bulk scorer applies the mask word by word (code reading, not measured). - Not affected: required clauses at or below 0.3% of
maxDoc(doc-at-a-time path). Not claimed: interleaved, non-run exclusions, the case #16669 targets: there the window path moves work from the exclusion toR(on #16669's dense shape 1,000,001 required and 3 exclusion moves on main, against 40,001 and 980,003 on 10.5.2), and #16669 reports large speed-ups. - Versions. 10.6.0 (released 2026-10-29) and main. All releases from 10.0.0 to 10.5.2 are fine.
One JUnit method in org.apache.lucene.search: one 10,000-doc segment, grp:old on docs 0 to 8,999, and a match-all MUST clause that counts its iterator's moves. Deterministic, single thread, about 1.5 s; fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LeafReaderContext;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestReqExclSkipsExcludedRun extends LuceneTestCase {

  public void testRequiredClauseSkipsExcludedRun() throws IOException {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      for (int i = 0; i < 10_000; i++) {
        Document doc = new Document();
        if (i < 9_000) {
          doc.add(new StringField("grp", "old", Field.Store.NO));
        }
        w.addDocument(doc);
      }
      w.forceMerge(1);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        searcher.setQueryCache(null);
        int[] moves = new int[1];
        Query all =
            new Query() {
              @Override
              public Weight createWeight(IndexSearcher s, ScoreMode scoreMode, float boost) {
                return new ConstantScoreWeight(this, boost) {
                  @Override
                  public ScorerSupplier scorerSupplier(LeafReaderContext ctx) {
                    DocIdSetIterator it = DocIdSetIterator.all(ctx.reader().maxDoc());
                    DocIdSetIterator counting =
                        new DocIdSetIterator() {
                          @Override
                          public int docID() {
                            return it.docID();
                          }

                          @Override
                          public int nextDoc() throws IOException {
                            moves[0]++;
                            return it.nextDoc();
                          }

                          @Override
                          public int advance(int target) throws IOException {
                            moves[0]++;
                            return it.advance(target);
                          }

                          @Override
                          public long cost() {
                            return it.cost();
                          }
                        };
                    return new DefaultScorerSupplier(
                        new ConstantScoreScorer(score(), scoreMode, counting));
                  }

                  @Override
                  public boolean isCacheable(LeafReaderContext ctx) {
                    return false;
                  }
                };
              }

              @Override
              public String toString(String field) {
                return "all";
              }

              @Override
              public void visit(QueryVisitor visitor) {}

              @Override
              public boolean equals(Object o) {
                return this == o;
              }

              @Override
              public int hashCode() {
                return System.identityHashCode(this);
              }
            };
        Query query =
            new BooleanQuery.Builder()
                .add(all, BooleanClause.Occur.MUST)
                .add(new TermQuery(new Term("grp", "old")), BooleanClause.Occur.MUST_NOT)
                .build();
        assertEquals(1_000, searcher.count(query));
        // Expected: the required iterator jumps the excluded run [0, 9000) (about 1,001 moves, as in 10.5.2); actual on main: about 10,001
        assertTrue("required iterator moved " + moves[0] + " times", moves[0] <= 2_000);
      }
    }
  }
}
cp $REPRO/TestReqExclSkipsExcludedRun.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestReqExclSkipsExcludedRun -Ptests.seed=1044B21F
# the count does not depend on the seed or on assertions
- Expected
- 1,000 hits, and the required iterator moves about 1,001 times (10.0.0 to 10.5.2: 1,001).
- Observed
- 1,000 hits, but "required iterator moved 10001 times" on main and 10.6.0, with assertions on and off.
More files, environment, full output286 words
TestReqExclSkipsExcludedRun (123 lines with the license header, one test method). The counting clause is a plain Query whose ConstantScoreWeight wraps a counting DocIdSetIterator in a ConstantScoreScorer and Weight.DefaultScorerSupplier; these are public but marked @lucene.internal, fine for an in-tree test (for a stock-query demonstration, use the PhraseQuery postings count above). Its Weight keeps count() at the default -1, because with a stock MatchAllDocsQuery IndexSearcher#count would shortcut through BooleanWeight#count and never score. The query cache is off. The test first checks the hit count (1,000, passes everywhere), then that the required iterator moved at most 2,000 times.
The <= 2_000 bound is a judgement; the observable fact is maxDoc + 1 moves (10,001) against hits + 1 (1,001). It is every document of the run only because R matches all documents; in general R steps through every one of its matches inside the run. The comment line in the test is longer than 100 columns; wrap it before adding the test to the tree. As a regression test it can go into the existing TestReqExclBulkScorer as one more method.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT) and the 10.6.0 release jars (commit 4ae946e5a9b): fail; 10.0.0 to 10.5.2: pass |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific; the count is deterministic) |
cp $REPRO/TestReqExclSkipsExcludedRun.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestReqExclSkipsExcludedRun -Ptests.seed=1044B21F
# main 645d4fe14a20, gradle, -Ptests.seed=1044B21F
TestReqExclSkipsExcludedRun > testRequiredClauseSkipsExcludedRun FAILED
    java.lang.AssertionError: required iterator moved 10001 times
        at org.apache.lucene.search.TestReqExclSkipsExcludedRun.testRequiredClauseSkipsExcludedRun(TestReqExclSkipsExcludedRun.java:119)
1 test completed, 1 failed

# standalone runner
main 645d4fe14a20, -ea / -da               failures=1  required iterator moved 10001 times
10.6.0 (Maven Central jars), -ea / -da     failures=1  required iterator moved 10001 times
10.5.2, -da                                failures=0  (1,001 moves)
main + recommended fix, -ea failures=0- 10.6.0's release notes still say "ReqExclBulkScorer now skips runs of excluded docs" (#16307), next to #16669.
- #16669 deleted the old loop holding the skip (#14976) to simplify, after benchmarks with interleaved and sparse exclusions only; runs were never measured.
- A fix can keep #16669's window path (its dense shape: 988,289 vs 1,000,001 required moves with fix C).
The full argument351 words
- The same release notes say the opposite. The 10.6.0 section of
lucene/CHANGES.txtlists "GITHUB#16669: Use intoBitSet to speed up ReqExclBulkScorer with dense exclusions." (:687on main) and, earlier in the same Optimizations section, "GITHUB#16307: ReqExclBulkScorer now skips runs of excluded docs via TwoPhaseIterator#docIDRunEnd for two-phase excluded clauses (e.g. a doc-values not-equals filter), instead of advancing one doc at a time." (:632-634;:183-185and:238in the 10.6.0 release commit). The shipped class has nodocIDRunEndcall (0 references in the bytecode of main and of the RC1 core jar, 1 in 10.5.2). - The skip was built on purpose. #14976 added it (10.3.0,
CHANGES.txt:1699: "Utilize docIdRunEnd on ReqExclBulkScorer."); #16142 made it cheap for several MUST_NOT clauses (10.5.0,:1158: "Optimize disjunction #docIDRunEnd to skip runs of excluded documents."; it changedDisjunctionDISIApproximation, and its PR body says "ReqExclBulkScoreruses the prohibited scorer'sdocIDRunEnd()to skip runs of excluded documents"); #16307 extended it to two-phase clauses in the 10.6 cycle. - #16669 removed the old loop on purpose, but never measured runs. Its issue #16668 notes that "
docIDRunEnd()only helps when the iterator can expose a consecutive run of matching document IDs". Its first commit (b3094fab914) kept the old leap-frog loop, with bothdocIDRunEndbranches, as asparseScorepath used only whenexcl.cost() < req.cost() >>> 7, so any exclusion costing at least 1/128 ofR(the minimal repro's 9,000 against 10,000, for example) already took the window path. The author then wrote "I'm exploring whether we can remove thesparsepath and use thedensepath universally, which would simplify the implementation", and commite0c955a58c7("delete spare path") removed it. The benchmarks behind that (round-robin interleaved MUST_NOT terms, luceneutil ReqExclSparse/ReqExclDense, not-equals ranges) contain no run-shaped exclusion, and the PR body, its 9 comments and 4 review comments do not mention long runs or the skip. - Why no test caught it. #14976 and #16307 added no test; #16669's tests check results, not cost.
- Precedent. Upstream fixed comparable MUST_NOT slowdowns (#16049, fixed by #16142; #16702, addressed by #16715) and the same window-vs-leap-frog trade-off in
DenseConjunctionBulkScorer(#16259).
The devil's-advocate check157 words
The strongest case for "intended": Lucene documents matching semantics, not cost; #16669 chose the window path deliberately and deleted the leap-frog path on purpose, to simplify; and +R -X now costs about what R alone costs, which a maintainer may accept. The cross-model intended-lens review rated this case moderate, the intended-behaviour checker weak to moderate, and upstream may label the report an enhancement, as it did #16049.
Why it does not settle it: the release notes of the very release that ships the change advertise the skip; nothing in #16669 shows the run case was measured or the loss of the skip weighed; and, as far as measured, a fix need not undo #16669, because skipping the required clause where the mask rejects every document keeps the window path for interleaved exclusions (operation counts only, no end-to-end benchmark). Verdict: an unintended performance regression against 10.3.0 to 10.5.2, results correct; a maintainer may still label it an enhancement.
Recommended C: score R only over the accepted part of each window (validated)
Score R only from the first to the last document each window's mask accepts, and skip R when the mask accepts none (+12/-1 in ReqExclBulkScorer.score). R is then never stepped inside a run that crosses a window boundary, as in 10.5.2. The repro and the 2,340 tests of org.apache.lucene.search pass; measured by operation counts, not benchmarked end to end.
      // Score the required clause only from the first to the last doc the mask accepts, and not at
      // all when the mask accepts nothing, e.g. when a run of excluded docs covers the window.
      int first = windowMask.nextSetBit(0, windowLength);
      if (first == DocIdSetIterator.NO_MORE_DOCS) {
        upTo = windowMax;
        continue;
      }
      int last = windowMask.prevSetBit(windowLength - 1);
      upTo = req.score(collector, windowBits, windowMin + first, windowMin + last + 1);
      // No doc after the last accepted one can match: the next window starts at windowMax at the
      // earliest, where the exclusion iterator is positioned after intoBitSet.
      upTo = Math.max(upTo, windowMax);
All options and trade-offs4 options · 908 words
Three variants were written against 645d4fe14a20 and measured on the same shapes (required-iterator moves; hits identical everywhere):
| shape | 10.5.2 | main | A | C (recommended) | A+C |
|---|---|---|---|---|---|
| minimal repro, 10,000 docs, run [0, 9000) | 1,001 | 10,001 | pass | pass | pass |
| 1M docs, run [0, 999000), 5 exclusion kinds, count and top-10 | 1,001 | 1,000,001 | 1,001 | 1,001 | 1,001 |
| 1M docs, PhraseQuery R, postings reads | 2,002 | 2,000,000 | 2,002 | 2,002 | 2,002 |
| 100k docs, run [500, 99000) (starts inside a window) | 1,502 | 100,001 | 5,098 | 1,502 | 1,502 |
| 100k docs, runs of 4,000, 1 kept doc between | 51 | 100,001 | 53,141 | 4,050 | 52,013 |
| 100k docs, runs of 2,000, 1 kept doc between | 101 | 100,001 | 69,505 | 52,075 | 68,017 |
| 100k docs, alternating blocks of 100 | 50,500 | 100,001 | 99,817 | 98,713 | 98,713 |
| #16669's dense shape, 3 interleaved MUST_NOT terms, 1M docs | 40,001 | 1,000,001 | 999,272 | 988,289 | 988,337 |
On #16669's dense shape 10.5.2 pays on the exclusion side instead (980,003 exclusion moves).
ReqExclBulkScorer.java, replaces line 86; the 12 added lines of fix-optC.diff, verbatim:
      // Score the required clause only from the first to the last doc the mask accepts, and not at
      // all when the mask accepts nothing, e.g. when a run of excluded docs covers the window.
      int first = windowMask.nextSetBit(0, windowLength);
      if (first == DocIdSetIterator.NO_MORE_DOCS) {
        upTo = windowMax;
        continue;
      }
      int last = windowMask.prevSetBit(windowLength - 1);
      upTo = req.score(collector, windowBits, windowMin + first, windowMin + last + 1);
      // No doc after the last accepted one can match: the next window starts at windowMax at the
      // earliest, where the exclusion iterator is positioned after intoBitSet.
      upTo = Math.max(upTo, windowMax);
Trade-offs
- General: works for every exclusion, whether or not its iterator reports runs, and calls no
docIDRunEnd.Ris never stepped inside an excluded run that crosses a window boundary (any run of 4,096 documents or more): windows inside the run are skipped and the run's part of its first and last window is trimmed off. upTomust not fall belowwindowMax:intoBitSethas moved the exclusion iterator there, so a window starting earlier would miss excluded documents.- Leaves: a run strictly inside a window with accepted documents on both sides is still stepped (at most that window's 4,096 documents); the exclusion is still loaded into a mask for every window inside a run, as on main; if
Rruns out of matches inside a long run, masks are loaded until the next window with an accepted document (code reading, not measured); the unreleased two-phase skip of #16307 stays gone; measured by operation counts only, not benchmarked end to end.
What the checks validated
- gradle in a scratch worktree at
645d4fe14a20,-Ptests.seed=1044B21F: the minimal test fails without the fix and passes with it; with it, the nine closest suites pass (TestReqExclBulkScorer,TestBooleanQuery,TestBoolean2,TestBooleanScorer,TestBooleanMinShouldMatch,TestBooleanScorerSupplier,TestBooleanOr,TestBooleanRewritesand the new test: 138 tests), and so does the wholeorg.apache.lucene.searchpackage (215 classes, 2,340 tests, 49 skipped, 0 failures). - 1,152 count identities, 0 mismatches; a randomized partition test (run, interleaved, two-phase doc-values and disjunction exclusions, MUST and FILTER, 10% deletions, random sub-ranges against brute force), 3 seeds, pass; independent verifiers' run tests pass.
- A verifier's two-phase test still fails with C (512
matches()calls where it asserts 112; that run was launched expecting a pass, so the runner marks it unexpected): C does not restore #16307's two-phase skip.
Insert after the exclusion is advanced to windowMin (:63-65), +12:
      if (exclApproximation.docID() == windowMin) {
        int runEnd =
            exclTwoPhase == null ? exclApproximation.docIDRunEnd() : exclTwoPhase.docIDRunEnd();
        if (runEnd > windowMin) {
          upTo = (int) Math.min((long) max, (long) runEnd);
          continue;
        }
      }
Trade-offs
Brings back the released mechanism: a run that reaches a window start is jumped in docIDRunEnd steps without loading masks, and a two-phase exclusion with a proven run is skipped without matches() (#16307); when no run is proven, the existing intoBitSet path still calls matches() per candidate. Limits: a run that starts inside a window is stepped up to the next window boundary (5,098 against 1,502 moves above); only exclusions whose iterator reports runs benefit.
What the checks validated
The minimal test passes with assertions on and off; 99 upstream tests of TestReqExclBulkScorer, TestBooleanQuery, TestBoolean2, TestBooleanScorer, TestBooleanMinShouldMatch and TestBooleanScorerSupplier, 30 iterations of TestReqExclBulkScorer, 1,152 count identities and 576 partitioned checks pass.
+24/-1. C's trimming plus A's run jump and two-phase skip.
Trade-offs
Equal to C on most shapes and restores the two-phase skip, but worse than C on runs of 2,000 and 4,000 (68,017 and 52,013 against 52,075 and 4,050 moves), because A's jumps end at run ends and move the window starts onto the kept documents.
What the checks validated
The minimal test, the independent verifiers' run tests including the two-phase one, the partition test (2 seeds), a mid-window-run test and the 1,152 count identities pass. Through gradle at 645d4fe14a20 it passes the minimal test and the same nine suites (138 tests).
To restore 10.5.2's cost for runs inside a window too, a window whose mask has only a few accepted stretches could score R once per stretch, as #16259 brought leap-frog back for sparse windows in DenseConjunctionBulkScorer.
Trade-offs
More code and a heuristic threshold.
What the checks validated
Not written or measured.
Not security-sensitive: results stay exact and the extra work is bounded by the cost of the required clause alone, so a service that lets users compose +R -X queries sees at most the CPU cost of R, which those users could already run.
A review of what changed between 10.5.2 and the 10.6 release candidate flagged #16669's rewrite of the MUST_NOT bulk scorer. A timing-free count of the required iterator's moves turned it into numbers (1,001 against 1,000,001 at 1M documents), and a bounded-exhaustive cost and correctness model of the old, new and fixed loops backed it.
The method in full115 words
Method: non-formal lead, semi-formal backing. The hunt's "10.5.2 vs 10.6.0 RC1" differential lens read the #16669 diff and compared query costs on 10.5.2, RC1 and main with identical hits; MUST_NOT queries with a contiguous excluded range stood out. A skeptic re-run replaced timings with a count of the required iterator's moves (1,001 on 10.2.2 to 10.5.2 against 1,000,001 on RC1 and main at 1M documents).
The hunt then reduced it to one JUnit, measured five kinds of exclusion and stock PhraseQuery/TermQuery postings reads, and built a bounded-exhaustive model of the 10.5.2, main and fixed loops: 790,324 cases for cost and correctness plus 16.4M partitioned and chunked re-entrant correctness checks, with two mutants caught.
No prior report found (GitHub issues and PRs including the JIRA archive, the changed files of all open PRs, the 10.6.0 release threads on dev@, downstream projects, luceneutil, the web; re-checked 2026-10-30). Related: #16669 introduced it; #14976, #16142 and #16307 added the skip it removed.
Searches5 searches
Related, not reports: #16669 and its issue #16668 (the introducing change); #14806/#14976, #16142 and #16307 (they added the skip); #16049 (interleaved MUST_NOT cost, fixed by #16142); #16702/#16715 (lead cost; #16715 sets the 0.3% routing threshold); #16259 (the same window-vs-leap-frog trade-off in DenseConjunctionBulkScorer); #12194 (an old long-runs API draft). Limits: GitHub search does not index diffs; private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| Search tool (GitHub issues/PRs, commits, downstream repositories, dev@, java-user@, issues@, commits@, JIRA archive) | 2026-10-29 | three runs: identifiers, symptoms, new phrasing ("excluded docs run skip lost", "MUST_NOT 10.6 regression", "docIDRunEnd no longer used") | 349, 774 and 358 hits, none a report |
| GitHub issues and PRs (apache/lucene, Elasticsearch, OpenSearch, Solr, luceneutil) | 2026-10-29 | 82 searches, incl. everything updated in the last 48 hours | no report |
| Open and recent apache/lucene PRs | 2026-10-29 | changed files of all 409 open PRs and of the 139 closed PRs created since 2026-09-10 | only #16669 (and the stale 2023 #12194) touch ReqExclBulkScorer.java |
| #16669 and #16668; dev@ 10.6.0 RC1 vote and release threads, java-user@; luceneutil nightly annotations | 2026-10-29 | read in full | no mention of runs or of dropping the skip |
| GitHub, re-check | 2026-10-30 | ReqExclBulkScorer, docIDRunEnd, MUST_NOT PRs by update date; all issues updated since 2026-10-29 by title; the file's upstream commit history on main and branch_10_6 | no report; not fixed (last commit still #16669) |
Introduced by #16669 (c5fa32ce49f, merged 2026-09-24) and its same-day branch_10x backport (inherited by branch_10_6); first released in 10.6.0 (2026-10-29). Bisected: the parent commit passes. All twelve releases 10.0.0 to 10.5.2 and 9.12.3 are clean (1,001 moves).
Versions tested7 rows
Introduced by c5fa32ce49f, apache/lucene#16669 "Use intoBitSet to speed up ReqExclBulkScorer with dense exclusions" (by kkewwei for their issue #16668; reviewed and merged by romseygeek, 2026-09-24), backported to branch_10x as 92ce3eaf4bf the same day; branch_10_6 inherited it when it was cut from branch_10x on 2026-10-14. It replaced the leap-frog loop of LUCENE-6940 and removed both docIDRunEnd branches: the DocIdSetIterator one from #14976 (10.3.0), the released behaviour that regresses, and the two-phase one from #16307 (same 10.6 cycle, never released). Putting back only the pre-#16669 ReqExclBulkScorer.java makes main and RC1 pass. 10.0 to 10.2 kept R out of excluded runs but stepped the excluded iterator once per excluded document, so the fair cost baseline is 10.3.0 to 10.5.2.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | 10,001 moves (gradle and the standalone runner, assertions on and off) |
10.6.0 (Maven Central jars, 4ae946e5a9b) | affected | 10,001 moves (-ea and -da) |
10.6.0 RC1 (staged jars and a build of 4ae946e5a9b) | affected | 10,001 moves (-ea and -da) |
c5fa32ce49f (#16669) vs its parent c80c9f53674 | bisect | the commit fails (10,001), the parent passes (1,001) |
| 10.3.0 to 10.5.2 (7 releases) | not affected | 1,001 moves each (the docIDRunEnd skip) |
| 10.0.0 to 10.2.2 (5 releases) | not affected | 1,001 moves each (leap-frog; the excluded iterator steps per excluded doc) |
| 9.12.3 (a port of the counting clause) | not affected | 1,001 moves |
An independent reproducer, reviewers from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication each ran their own tests or the minimal one; all call it real and performance only, and agree on the root cause.
Checks and verdicts392 words
Every check counts operations rather than timing them; the timings in this doc are indicative only. The minimal test failed on main with 10,001 moves under eight seeds (the finder, the history sweep, an intended-behaviour verifier, the adjudication, the registration check, the audit, the no-noise gate and this doc), and under a ninth in the independent fact check of this doc.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | 100,000-doc test: 100,001 moves on main, 1,001 on 10.0.0, 10.2.2, 10.3.2 and 10.5.2; five exclusion kinds at 1M docs; stock PhraseQuery 2,000,000 vs 2,002 postings reads; bounded-exhaustive cost and correctness model; fix A with 99 upstream tests. |
| cross-model review, refute lens | real, high | OpenAI GPT-5.6. Its own public-API test (20,000 docs, 18,000-doc excluded prefix) moves 20,001 times for 2,000 hits on main; its alternating control passes; 10.5.2 and fix A pass. |
| cross-model review, intended lens | real, high | OpenAI GPT-5.6. Its own test (FILTER MatchAllDocsQuery, 11,700 of 12,000 docs excluded) moves 12,001 times on main; rates the by-design case moderate but finds nothing that documents giving up the skip. |
| Independent reproducer | real | Stock +f:a -x:y: 50,001 vs 5,001 postings reads. A run that starts inside a window, [2000, 29000) of 30,000 docs: 30,001 moves vs 3,002 on 9.12.3 to 10.5.2; fix A passes but restores only part (5,098). |
| Cross-model review, root-cause lens | real, high | OpenAI GPT-5.6, re-run on 645d4fe14a20: 8,193 moves for 1,192 hits; a two-phase exclusion makes 512 vs 112 matches() calls; fix A correct over 576 partitioned checks; flagged A's window-start limit. |
| Intended-behaviour devil's advocate | real, high | 0 docIDRunEnd references in the bytecode of main and RC1 (1 in 10.5.2); no cost promise in the javadocs; no run-shaped benchmark or review comment in #16669; the stale CHANGES entry. |
| adjudication | confirmed, high | Re-ran the minimal test: main fails with -ea and -da (10,001 moves), 10.5.2 passes. Impact class minor (performance only). |
| audit and no-noise gate | keep; claim-low | Re-ran the minimal test with new seeds; the claim is the one minimal test, nothing left to cut. |
| this doc | reproduced; fix validated | The minimal test through gradle on a clean 645d4fe14a20 worktree (fails) and on the 10.6.0 Maven Central jars (fails, -ea and -da); fix C written and validated; A and A+C re-measured on the same shapes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 473 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,537 words
- Registry title
- Since #16669 (10.6.0 and main), ReqExclBulkScorer no longer skips long runs of excluded doc IDs: for +R -X it scores the required clause in every 4096-doc window, even windows X fully excludes, so R's iterator steps through all of its matches inside X's runs (10,001 moves for 1,000 hits in a 10,000-doc segment, where 10.0.0-10.5.2 need 1,001; performance regression, results correct)
- Area
- search / BooleanQuery MUST_NOT bulk scoring (ReqExclBulkScorer)
- Priority
- Low, rank 362: A released 10.6.0 core default-config slowdown of 8-16x with correct results that shows only when long excluded runs hold most of the required clause's matches, so it heads the Low performance rows above LFV-1057 and LFV-791.
- Impact class
- minor
- Impact note
- Performance regression only, with the default codec, IndexWriterConfig and IndexSearcher, on main and 10.6.0 (released 2026-10-29): a BooleanQuery with a MUST/FILTER clause R that costs more than 0.3% of maxDoc and a MUST_NOT clause X whose matches form long doc-ID runs (for example excluding the older documents of an append-ordered or time-sorted segment, a flag set on a contiguous block of documents, a cached dense filter) now steps R through all of its matches inside X's runs instead of jumping each run in one step, so it costs about as much as R alone; hits, counts and top-k are identical, the extra work is at most linear in maxDoc per segment, and indicative wall-clock on a shared host at 1M docs with 99.9% of the docs in one excluded run went from 0.30 to 2.5 ms (term query, top-10), 2.3 to 18.5 ms (8-term OR, top-10) and 0.71 to 11.4 ms (phrase, count) between 10.5.2 and main.
- Summary
- You search +R -grp:old, where R matches every document and grp:old matches one run of consecutive doc IDs covering 9,000 of the 10,000 documents of a segment. You expect Lucene to jump over the excluded run, as 10.3.0 to 10.5.2 do in one docIDRunEnd step (on every release from 10.0.0 to 10.5.2 the required clause's iterator moves 1,001 times for the 1,000 hits). Instead, since #16669 ReqExclBulkScorer loads the exclusion into a bit mask per 4096-doc window and always runs the required clause over every window, even windows the exclusion covers completely, so the iterator moves 10,001 times; the 1,000 hits are still right, only the work now grows with the length of the excluded run.
- Introduced
- c5fa32ce49f6 (apache/lucene#16669 'Use intoBitSet to speed up ReqExclBulkScorer with dense exclusions', by kkewwei for their issue #16668; reviewed and merged by romseygeek on main 2026-09-24; branch_10_6 backport 92ce3eaf4bf the same day) [exec: commit-level bracket with the minimal repro, the parent c80c9f53674 passes (1,001 required-iterator moves) and c5fa32ce49f fails (10,001) with -ea and -da; putting back only the pre-#16669 ReqExclBulkScorer.java makes main 645d4fe14a20 and 10.6.0 RC1 pass (1,001); read: blame gives 27 of the 41 lines of score() to c5fa32ce49f, the rest is the LUCENE-6940 method frame, and the file is byte-identical on c5fa32ce49f, main 645d4fe14a20 and RC1]. It replaced the leap-frog loop (LUCENE-6940, 5.5.0/6.0.0) that called the required bulk scorer only on the gaps between excluded docs, and removed both docIDRunEnd branches: the DocIdSetIterator one from #14976 (10.3.0; the released behaviour that regresses) and the two-phase one from #16307 (added in the same 10.6 cycle, never released). (2026-09-24 (author date of c5fa32ce49f, 2026-09-24T08:30:33Z, equal to the PR merge time; the branch_10_6 backport 92ce3eaf4bf has the same author date and was committed at 08:33:25Z the same day))
- First affected version
- 10.6.0, released 2026-10-29 (the first affected release: 10.6.0 RC1 4ae946e5a9b reproduces it [exec, official staged jars and a build of the RC1 commit] and is the commit released as 10.6.0; on the main line 11.0.0, unreleased; the last unaffected release is 10.5.2)
- Affected versions
- [exec] main 645d4fe14a20 (minimal repro, -ea and -da; seeds DEADBEEF, 5EED4351, 7A11E5ED, A11CE5ED and 0D055E17 each give 10,001 required-iterator moves for 1,000 hits), the introducing commit c5fa32ce49f (-ea and -da) and 10.6.0 RC1 4ae946e5a9b (official staged core, codecs and test-framework jars, SHA-512 checked, and a build of the RC1 commit; -ea and -da); [read] upstream main head 70a428b5ba9, branch_11x head 203699279f5 and branch_10_6 head 6dde6c73bd1 (the last commit on ReqExclBulkScorer.java is still #16669 on all three, checked 2026-10-29). Not affected [exec, 1,001 moves each]: all 12 releases 10.0.0 to 10.5.2 (-da; 10.5.2 also -ea), 9.12.3 (with a two-hunk 9.x API port of the measuring clause only, -ea and -da) and the parent commit c80c9f53674; 9.0.0-9.12.3 have a byte-identical ReqExclBulkScorer.java [read]. 10.0-10.2 also kept R out of excluded runs but stepped the excluded iterator once per excluded doc, so the fair cost baseline is 10.3.0-10.5.2.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-29, read-only; the prior-report record verdict new: first pass, refresh, follow-up-step check): three scripted prior-report searches on identifier, symptom and new phrasing (62 GitHub issue/PR, 9 commit, 6 downstream, 60 mailing-list and 12 JIRA-archive queries; 349, 774 and 358 distinct hits, none a report); about 50 own GitHub searches in the first pass and 34 more in the refresh over apache/lucene, Elasticsearch, OpenSearch, Solr and luceneutil, including everything updated in the last 48 h; the changed files of all 409 open apache/lucene PRs (only the stale 2023 #12194 touches ReqExclBulkScorer.java) and of the 139 closed PRs created since 2026-09-10 (only #16669); the 70 issues and PRs updated since 2026-10-27, read by title; the dev@ '[VOTE] Release Lucene 10.6.0 RC1', feature-freeze and 'Lucene 10.6 as final minor 10.x release' threads and java-user@ October; luceneutil's nightly-benchmark annotations (no entry for #16669); the JIRA archive; and web searches. Context, not reports: #16669 and its issue #16668 (the introducing change; benchmarks cover interleaved and sparse exclusions only, and nobody mentions long runs or the dropped docIDRunEnd skip), #14806/#14976, #16142 and #16307 (they added the run skip), #16049 (other root, fixed by #16142), #16702/#16715 (lead cost, other root; #16715 narrows the trigger to required clauses above 0.3% of maxDoc), #16259 (the same window-vs-leap-frog trade-off fixed in DenseConjunctionBulkScorer), #16849, #16568, #12194, #11915. Not fixed upstream: the last commit on ReqExclBulkScorer.java is still #16669 on main (head 70a428b5ba9), branch_10_6 (head 6dde6c73bd1) and branch_11x, and no fix exists, so there is no fix commit whose author date could predate this report. Tracking issue #16937 does not mention it.
- Lucene commit tested
- main
645d4fe14a20(gradle in a clean worktree and a standalone runner, assertions on and off); the 10.6.0 release jars from Maven Central (commit4ae946e5a9b) and the 10.6.0 RC1 staged jars; the introducing commitc5fa32ce49fand its parentc80c9f53674; the releases 10.0.0 to 10.5.2 and 9.12.3 (a port of the counting clause). OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/core/src/java/org/apache/lucene/search/ReqExclBulkScorer.java:53-93 (at 645d4fe14a20) (score: fixed 4096-doc windows, intoBitSet of the exclusion, flip, then req.score(collector, windowBits, windowMin, windowMax) at line 86 for every window; no docIDRunEnd call in the class)lucene/core/src/java/org/apache/lucene/search/BooleanScorerSupplier.java:203-207 (at 645d4fe14a20) (MUST_NOT queries whose required cost is at most 0.3% of maxDoc go to ReqExclScorer; all others reach ReqExclBulkScorer)lucene/core/src/java/org/apache/lucene/search/Weight.java:293-315 (at 645d4fe14a20) (DefaultBulkScorer.scoreIterator/scoreTwoPhaseIterator step the iterator over every doc below max and check acceptDocs per doc)lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:245-262 (at 645d4fe14a20) (docIDRunEnd contract) and TwoPhaseIterator.java:113-132 (TwoPhaseIterator#docIDRunEnd, callable before matches())lucene/CHANGES.txt:632-634 (at 645d4fe14a20) (10.6.0: 'GITHUB#16307: ReqExclBulkScorer now skips runs of excluded docs via TwoPhaseIterator#docIDRunEnd ...'), :687 (10.6.0: GITHUB#16669) and :245 (the #16307 entry again in the 11.0.0 section)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/BooleanScorerSupplier.java:203-207, :235-236, :259-265a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/ReqExclBulkScorer.java:53-93 (line 86; no docIDRunEnd call)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/Weight.java:293-315 (DefaultBulkScorer.scoreIterator, scoreTwoPhaseIterator)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:245-263, TwoPhaseIterator.java:112-132; lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsReader.java:1100-1125a Lucene clone releases/lucene/10.5.2 lucene/core/src/java/org/apache/lucene/search/ReqExclBulkScorer.java:51-78
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/BooleanScorerSupplier.java:203-207, :210-232, :259-265Maven Central lucene-core maven-metadata.xml (release 10.6.0, lastUpdated 20261029224919) and GitHub tag releases/lucene/10.6.0 -> 4ae946e5a9b (tagged 2026-10-29), read 2026-10-30
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:245, :632-634, :687, :1158, :1699; a Lucene clone 4ae946e5a9b lucene/CHANGES.txt:183-185, :238GitHub apache/lucene PR #16669, read 2026-10-30: commit b3094fab914 (ReqExclBulkScorer.java: sparseScore with both docIDRunEnd branches; shouldUseBitSet = excl.cost() >= (req.cost() >>> 7)), commit e0c955a58c7 'delete spare path', kkewwei's comments of 2026-09-17 ('I'm exploring whether we can remove the `sparse` path ...', 'I remove the `sparse` path ...')GitHub apache/lucene PR #16142 body and changed files (DisjunctionDISIApproximation.java, MustNotBooleanQueryBenchmark.java, CHANGES.txt, a test), read 2026-10-30
- History
GitHub tag releases/lucene/10.6.0 -> 4ae946e5a9b (tagged 2026-10-29), read 2026-10-30a Lucene clone: git merge-base --is-ancestor 92ce3eaf4bf origin/branch_10x (yes); merge-base of origin/branch_10x and origin/branch_10_6 = 3e416dce059 (2026-10-14); release tags 10.0.0 to 10.5.2
- TestReqExclSkipsExcludedRun.java (lucene/core, package org.apache.lucene.search, 1 test):
repro/LFV-1044/TestReqExclSkipsExcludedRun.java(123 lines)
A small diagram, made in parallel with this doc from the executed runs. Its fix part shows fix A (restore docIDRunEnd at window starts) with its limit; this doc recommends fix C. Both are validated.
assets/LFV-1044/bug.png(473 KB)