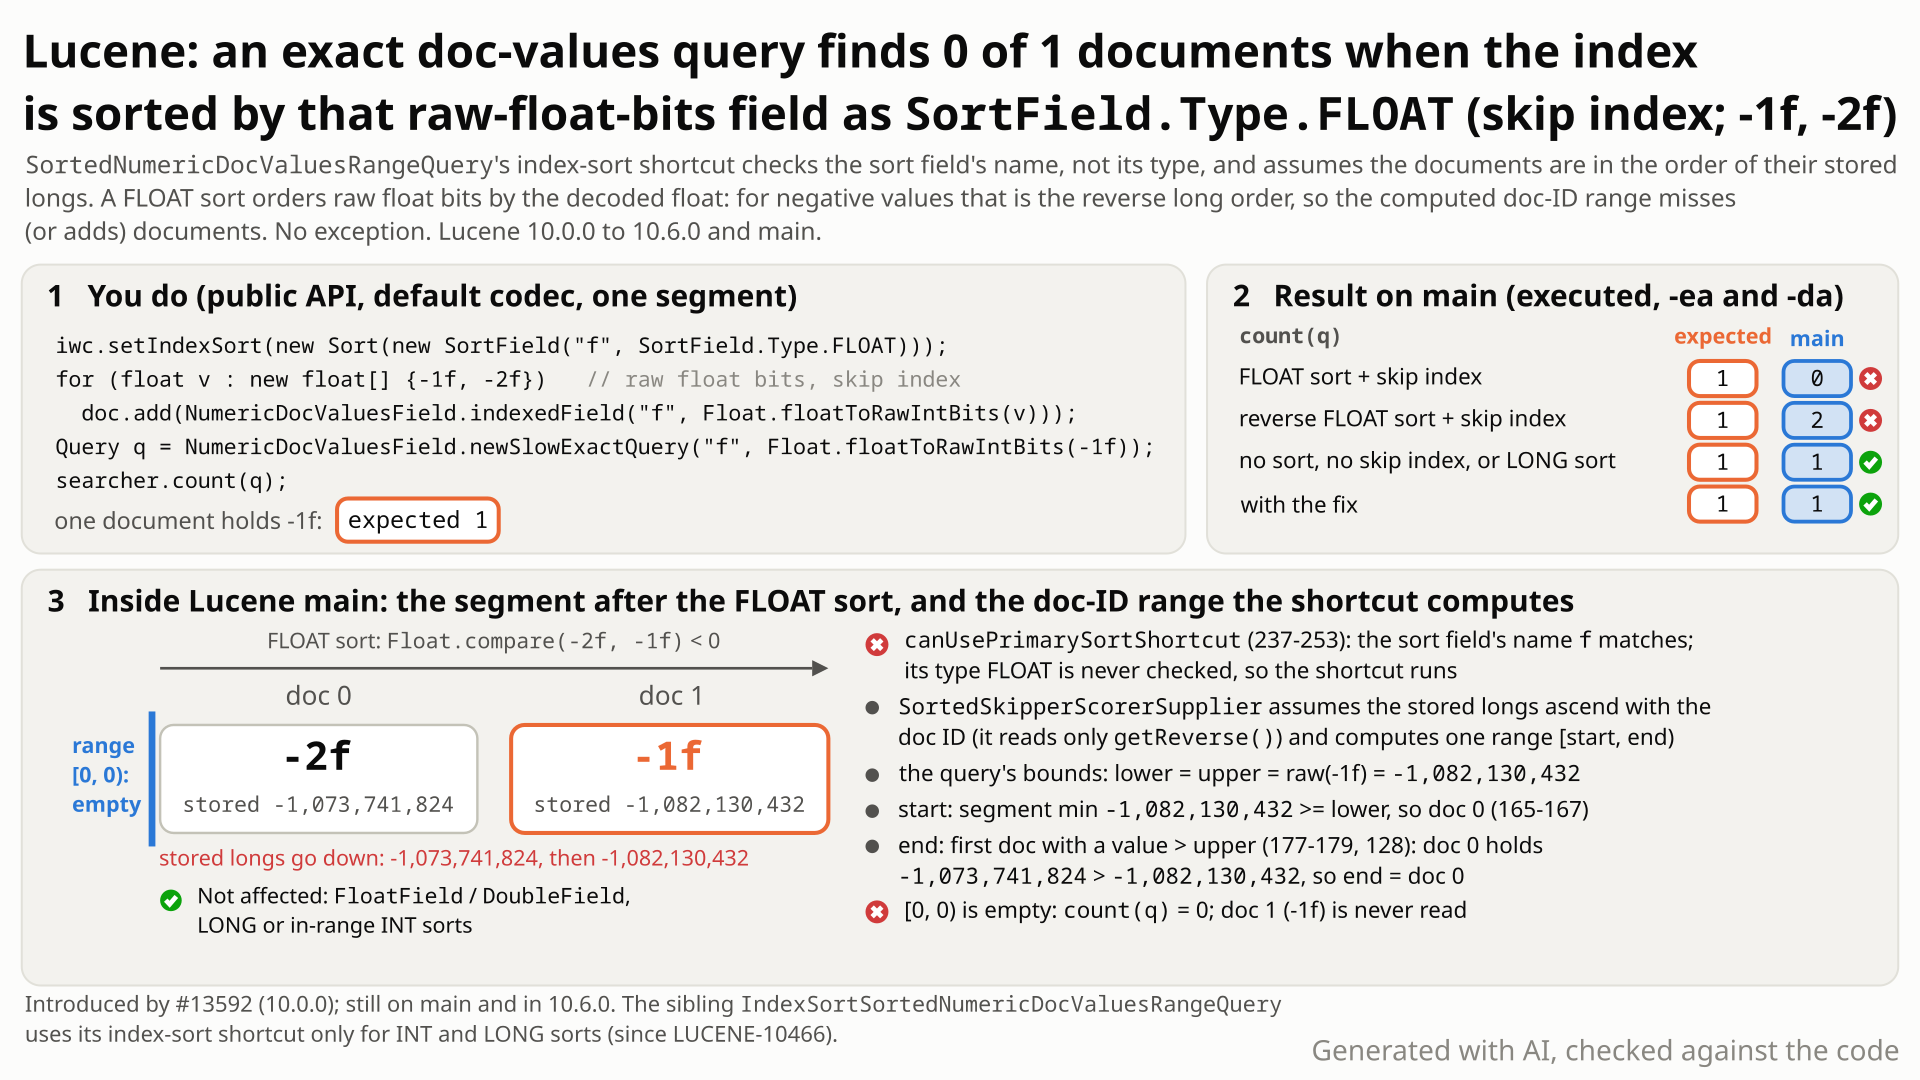
A doc-values range or exact query on the index-sort field takes a shortcut: it treats the matches as one run of consecutive doc IDs and finds its ends with the skip index. That needs documents in the order of their stored longs; a FLOAT or DOUBLE sort over raw bits breaks this once two values are negative.
FloatDocValuesFieldstores a float as its raw IEEE bits,Float.floatToRawIntBits(v), a long in a NUMERIC doc-values field. For positive floats bigger numbers have bigger bits; for negative floats the bits grow as the number gets more negative: -1f is -1,082,130,432 and -2f is -1,073,741,824.- A doc-values skip index (
NumericDocValuesField.indexedField) records, per block of documents, the minimum and maximum stored long. - An index sort (
IndexWriterConfig.setIndexSort) puts the documents of each segment in sort order. ASortField.Type.FLOATsort decodes the raw bits and orders by the float, so -2f comes before -1f.
- Index two documents whose field
fholds -1f and -2f as raw float bits with a skip index,NumericDocValuesField.indexedField("f", Float.floatToRawIntBits(v)), and sort the index bynew SortField("f", SortField.Type.FLOAT). The sort puts -2f in doc 0 and -1f in doc 1. - Count
NumericDocValuesField.newSlowExactQuery("f", Float.floatToRawIntBits(-1f)). You expect 1, which is what you get without the index sort, without the skip index, or with a LONG sort. - You get 0, with no error; the exact query for -2f counts 2. Because
fis the index sort field, the query skips checking every document: it takes one run of consecutive doc IDs, finds its ends with the skip index and a short scan, and assumes the stored numbers never go down along the doc order. - A FLOAT sort orders by the decoded float, but the raw bits of a negative float grow as the number gets more negative: doc 0 stores -1,073,741,824 and doc 1 stores -1,082,130,432. The run computed for raw(-1f) starts at doc 0 and ends before doc 0: it is empty.
- The shortcut's guard checks the sort field's name, that every document has a value and that there are no document blocks, never the sort type.
FloatField/DoubleField, LONG sorts and fields without a skip index are not affected.
Applications that store floats or doubles as raw bits in a NUMERIC doc-values field with a skip index, sort the index by it as FLOAT or DOUBLE, have two or more distinct negative values in a segment, and filter with newSlowExactQuery/newSlowRangeQuery. Opt-in and rare, but silent and deterministic, in 10.0.0 to 10.6.0 and main. FloatField/DoubleField are not affected.
Mechanism, terms and numbers713 words
SortedNumericDocValuesRangeQuery, the query behind NumericDocValuesField.newSlowExactQuery and newSlowRangeQuery, has a shortcut for a single-valued field with a skip index that is also the index's primary sort field: it treats the matching documents as one run of consecutive doc IDs and finds the run's ends from the skip index. That is right only if the documents are in the order of their stored long values. The guard, canUsePrimarySortShortcut, checks the sort field's name, density and document blocks but never the sort type. A SortField.Type.FLOAT or DOUBLE index sort orders a field of raw IEEE bits (the FloatDocValuesField / DoubleDocValuesField encoding) by the decoded number, and for negative numbers that is the reverse of the order of the raw bits. With two documents, -1f and -2f, the exact query for -1f counts 0 instead of 1 and the one for -2f counts 2; a reverse sort over-matches and a MUST_NOT clause removes documents it should keep. No error, default codec, assertions on or off, every release from 10.0.0 to 10.6.0 and main. The sibling IndexSortSortedNumericDocValuesRangeQuery has allowed its index-sort optimisation only for INT and LONG since LUCENE-10466 fixed the same kind of type assumption there as a bug (2022; there it surfaced as a ClassCastException); the shortcut was modelled on that class but did not take over the restriction.
- For a single-valued field with a skip index,
scorerSupplieraskscanUsePrimarySortShortcutwhether it may useSortedSkipperScorerSupplier(SortedNumericDocValuesRangeQuery.java:141-147). The guard's javadoc: "Returns the primary sort field if it is safe to use the SortedSkipperScorerSupplier range shortcuts" (:229-231). - The guard returns
nullonly if there is no primary sort field or it has another name, the field is not dense or the segment has document blocks (:237-253). It never readsSortField#getType. SortedSkipperScorerSupplierthen computes one doc-ID interval: it starts at the first document whose stored value is>=the lower bound and ends at the first one whose stored value is>the upper bound (mirrored for a reverse sort;SortedSkipperScorerSupplier.java:113-182). That is right only if the stored longs never decrease along the doc order.IndexSorter's FLOAT sorter orders byFloat.intBitsToFloat((int) value)and its DOUBLE sorter byDouble.longBitsToDouble(value)(IndexSorter.java:382-385,:446-449). With two distinct negative values in a segment, the stored longs go down along the doc order.
After the FLOAT sort: doc 0 = -2f (raw -1,073,741,824), doc 1 = -1f (raw -1,082,130,432); the skip index reports min -1,082,130,432 and max -1,073,741,824. For the exact query [raw(-1f), raw(-1f)]:
- start: the segment minimum is not below the lower bound, so the run starts at doc 0 (
SortedSkipperScorerSupplier.java:165-167); - end: the segment maximum is above the upper bound, so it scans from doc 0 for the first value
>raw(-1f), and doc 0's -1,073,741,824 already is (:173-180,:128); - the run [0, 0) is empty (
:83-89inget();countgoes throughbulkScorer(),:93-99, with the same check), so the count is 0. Doc 1, which holds raw(-1f), lies outside it. For raw(-2f) the same code gives [0, 2): both documents.
FloatField / DoubleField (sortable bits in SORTED_NUMERIC, sorted with SortedNumericSortField), LONG sorts, INT sorts over int-range values, fields without a skip index, sparse fields, segments with document blocks, and segments whose values are not NaN and include at most one distinct sign-bit-set value (one finite negative value, or -0.0 alone, still sorts in long order). NaN bit patterns are outside that rule: the FLOAT sort puts NaN after every other value, so a NaN with the sign bit set breaks it. With raw bits {0xFFC00000 (a NaN), raw(1f)}, the exact query for raw(1f) counts 2 and the one for 0xFFC00000 counts 0 instead of 1 each (executed on main; the repro uses finite values only). An INT sort over longs outside the int range reaches the same code, but storing such values under an INT sort is arguably out of contract. Since #16424 (10.6.0), Sort.getPrimarySortField also skips a leading sort field that has no values in the segment, or that is dense and whose skip index shows a single value, so FLOAT as the second sort field after such a field reaches the shortcut too; 10.5.2 is correct for that layout only.
Exposure and likelihood205 words
- Who is hit. A single-valued NUMERIC doc-values field that holds raw IEEE bits (
FloatDocValuesField/DoubleDocValuesField's encoding) with a skip index, built withNumericDocValuesField.indexedField(name, Float.floatToRawIntBits(v))(FloatDocValuesFieldhas no skip-index constructor of its own); an index sort on that field withSortField.Type.FLOATorDOUBLE; every document of the segment with a value; and a doc-values exact or range query on the field (NumericDocValuesField.newSlowExactQuery/newSlowRangeQuery, orSortedNumericDocValuesField.newSlowRangeQuery). All public API, accepted byIndexWriter. - The documented use.
FieldType#setDocValuesSkipIndexTypesays a skip index "is typically useful on fields that are part of the index sort". The unusual part is the raw-bit float encoding together with that sort. - What they see. Wrong
count, wrong hits and wrong filters: matching documents missed, non-matching ones added (reverse sort, or the query for the more negative value), and documents removed by aMUST_NOTclause that should stay. No exception; the same with assertions off. Two documents with distinct negative values in one segment are enough. - How likely. Rare (registry): few applications combine a hand-built raw-bit float field, a skip index, a FLOAT/DOUBLE index sort on it, negative values and a doc-values filter on the same field. For those that do, it is deterministic.
One JUnit class for lucene/core/src/test/org/apache/lucene/document/, one method, public API, default codec: two documents (-1f, -2f) as raw float bits with a skip index, a FLOAT index sort, and the count of the exact query for -1f. It fails with assertions on and off; it is also the suggested regression test.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.document;

import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Sort;
import org.apache.lucene.search.SortField;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestDocValuesRangeQueryFloatIndexSort extends LuceneTestCase {

  public void testExactQueryOnFloatIndexSort() throws Exception {
    try (Directory dir = newDirectory()) {
      IndexWriterConfig iwc = new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec());
      iwc.setIndexSort(new Sort(new SortField("f", SortField.Type.FLOAT)));
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        for (float v : new float[] {-1f, -2f}) {
          Document doc = new Document();
          doc.add(NumericDocValuesField.indexedField("f", Float.floatToRawIntBits(v)));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        // expected: the one doc holding raw(-1f) matches; actual on main: 0 matches
        assertEquals(
            1,
            new IndexSearcher(reader)
                .count(NumericDocValuesField.newSlowExactQuery("f", Float.floatToRawIntBits(-1f))));
      }
    }
  }
}
cp $REPRO/TestDocValuesRangeQueryFloatIndexSort.java $LUCENE/lucene/core/src/test/org/apache/lucene/document/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.document.TestDocValuesRangeQueryFloatIndexSort -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same failure)
- Expected
- count 1: one document stores raw(-1f), and the same documents give 1 without the index sort or the skip index.
- Observed
- count 0, no error (
expected:<1> but was:<0>); the exact query for -2f counts 2.
More files, environment, full output138 words
The test stores the floats with NumericDocValuesField.indexedField("f", Float.floatToRawIntBits(v)), which is FloatDocValuesField's encoding plus a skip index (FloatDocValuesField.indexedField is the same inherited method). It pins the default codec and has no explicit random input (newDirectory() is the test framework's randomized directory; the test failed under both seeds tried); one segment, single thread. Controls run by a verifier on the same two documents give 1 without the index sort, 1 without the skip index and 1 with a LONG sort.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); every release from 10.0.0 to 10.6.0 also fails; 9.12.3: API absent |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
TestDocValuesRangeQueryFloatIndexSort > testExactQueryOnFloatIndexSort FAILED
    java.lang.AssertionError: expected:<1> but was:<0>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:8D27622AAB57F4F9]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.junit.Assert.assertEquals(Assert.java:633)
        at org.apache.lucene.document.TestDocValuesRangeQueryFloatIndexSort.testExactQueryOnFloatIndexSort(TestDocValuesRangeQueryFloatIndexSort.java:44)

# the same with -Ptests.asserts=false; with the recommended fix the test passesnewSlowExactQuerymatches "an exact long value"; an index sort must not change the hits, and the guard promises the shortcut only "if it is safe".- The sibling
IndexSortSortedNumericDocValuesRangeQueryallows this optimisation only for INT and LONG, since the LUCENE-10466 bug fix. - Upstream tests sort raw-bit float fields as FLOAT, both with a skip index and as an index sort.
The full argument270 words
- Contract.
newSlowRangeQuery: "Create a range query that matches all documents whose value is between lowerValue and upperValue included" (NumericDocValuesField.java:91-92);newSlowExactQuery: "Create a query for matching an exact long value" (:132). Exact matching does not depend on any order. - The guard promises safety. "Returns the primary sort field if it is safe to use the SortedSkipperScorerSupplier range shortcuts for this query" (
SortedNumericDocValuesRangeQuery.java:229-231). - The sibling learned it already.
IndexSortSortedNumericDocValuesRangeQuery.java:208,:538: "The index sort optimization is only supported for Type.INT and Type.LONG". That came from LUCENE-10466 (#11502 / #749, Andriy Redko), a bug fix: "Ensure IndexSortSortedNumericDocValuesRangeQuery handles sort field types besides LONG" (lucene/CHANGES.txt:4286-4287). #13592's PR body (iverase): "Similar to what we do inIndexSortSortedNumericDocValuesRangeQueryfor primary sort, we can do the same in ...SortedNumericDocValuesRangeQuery". - Upstream tests.
TestSortOptimization#testFloatSortOptimizationSkpperIndexindexesFloatDocValuesField.indexedField(field, Float.floatToRawIntBits(value))and sorts searches bySortField.Type.FLOAT(TestSortOptimization.java:474-477,:492);TestIndexSorting#testBasicFloatand#testBasicDoublesort the index by FLOAT / DOUBLE overFloatDocValuesField/DoubleDocValuesField(TestIndexSorting.java:1465-1472,:1168-1175). These tests cover the two halves separately; none combines a skip index, a FLOAT/DOUBLE index sort and a doc-values range query, and every upstream test of the shortcut uses a LONG or STRING sort. - Maintainers know the hazard. On #16573 HoustonPutman wrote that "
NUMERICexpects floats and doubles to not be in sorted order"; on #16629 romseygeek wrote "I think we need to check that that [sic] we aren't making this assumption in other places as well", naming the sibling query. Nobody named this shortcut, and the discussions of #13592, #16085, #16424 and #16893 never mention the sort type.
The devil's-advocate check184 words
The strongest case for "not supported": SortField.Type.FLOAT's javadoc says "Fields must either be not indexed, or indexed with FloatPoint" (SortField.java:82-84), and a skip index could be read as "indexed".
Why it fails: the only index structure the javadoc names for FLOAT is FloatPoint, and the class javadoc's general "Fields must be indexed in order to sort by them" (SortField.java:39-40) is followed by a paragraph about points ("Sorting on a numeric field that is indexed with both doc values and points may use an optimization", :42-44); the repro has no points; raw bits are exactly the encoding the FLOAT index sorter decodes (IndexSorter.java:382); upstream itself sorts a skip-indexed raw-bit field as FLOAT; and the exact-match contract does not depend on the sort at all. A second objection, that raw-bit range queries over negative floats are meaningless, does not touch the exact query. The independent checks found no surviving intended-behaviour argument; the cross-model reviews rated it "weak". The INT-over-out-of-range-longs variant is arguably out of contract ("Sort values are Integer"), so it is a note, not the claim.
Recommended A: accept the shortcut only for sort types whose order is the stored-long order (validated)
Make canUsePrimarySortShortcut return null unless the index-sort order equals the stored-long order: LONG, INT on int-range values, and FLOAT/DOUBLE only through SortedNumericSortField (the FloatField/DoubleField sortable encodings). Raw-bit FLOAT/DOUBLE sorts then use the normal skip-index iterator. +25 lines; with it the repro and nearby core suites pass (671 tests, 0 failures).
private static boolean sortFollowsLongOrder(SortField sf, DocValuesSkipper skipper) {
  boolean sortable = sf instanceof SortedNumericSortField;
  SortField.Type type = sortable ? ((SortedNumericSortField) sf).getNumericType() : sf.getType();
  boolean intRange =
      skipper.minValue() >= Integer.MIN_VALUE && skipper.maxValue() <= Integer.MAX_VALUE;
  return switch (type) {
    case LONG -> true;
    case INT -> intRange;
    // SortedNumericSortField decodes the sortable encodings of FloatField and DoubleField
    case FLOAT -> sortable && intRange;
    case DOUBLE -> sortable;
    default -> false;
  };
}
All options and trade-offs3 options · 505 words
Option A was applied in a scratch worktree of 645d4fe14a20 and run with gradle (the worktree was removed after the runs). Options B and C were not built.
A: accept the shortcut only for sort types whose order is the stored-long order (validated) (recommended)
+25 lines in SortedNumericDocValuesRangeQuery.java: after the existing checks, canUsePrimarySortShortcut returns null unless sortFollowsLongOrder(sf, skipper).
private static boolean sortFollowsLongOrder(SortField sf, DocValuesSkipper skipper) {
  boolean sortable = sf instanceof SortedNumericSortField;
  SortField.Type type = sortable ? ((SortedNumericSortField) sf).getNumericType() : sf.getType();
  boolean intRange =
      skipper.minValue() >= Integer.MIN_VALUE && skipper.maxValue() <= Integer.MAX_VALUE;
  return switch (type) {
    case LONG -> true;
    case INT -> intRange;
    // SortedNumericSortField decodes the sortable encodings of FloatField and DoubleField
    case FLOAT -> sortable && intRange;
    case DOUBLE -> sortable;
    default -> false;
  };
}
Trade-offs
- Keeps the shortcut for LONG, for INT on int-range segments and for sortable float/double index sorts; drops it for every layout where it can be wrong (all plain
SortFieldFLOAT/DOUBLE sorts over raw bits, including segments where the shortcut happens to be right today, and INT segments outside the int range), where the query falls back to the skipper-driven iterator it already uses without an index sort (SortedNumericDocValuesRangeQuery.java:149-157). - More logic than option B, and it must stay in step with how the sorters decode values. No benchmark was run; the format check (
checkGoogleJavaFormat) passes on the diff.
What the checks validated
- Gradle, stock
645d4fe14a20: the repro fails with assertions on and off. - Gradle with the fix: the repro plus all of
org.apache.lucene.document.*,TestDocValuesQueries,TestGetPrimarySortField,TestIndexSortSortedNumericDocValuesRangeQuery,TestSortOptimizationandTestIndexSorting: 671 tests, 0 failures (seed DEADBEEF, assertions on). With assertions off, the repro,TestDocValuesQueriesandTestSortedSkipperScorerSupplierpass too (47 tests). - The fact check, in its own scratch worktree: the repro plus six of these suites (178 tests) pass with the fix, the repro passes with assertions off, and the format check passes.
- Earlier hunt runs: the standalone runner passes the repro with the fix; 7 same-fix tests (DOUBLE, reverse, MUST_NOT, INT over long, constant first sort field) fail 6 of 7 stock and 0 of 7 with it; a bounded-exhaustive check over a three-value alphabet per configuration (every layout of up to 7 documents over those values), 40 sort/encoding/layout configurations, 1,023,048 checks, finds 0 mismatches with it.
Return null unless the (unwrapped) sort type is LONG or INT, as IndexSortSortedNumericDocValuesRangeQuery does.
Trade-offs
Simplest and consistent with the sibling class; loses the shortcut for sortable float/double index sorts, which are correct today. Add option A's int-range check to also cover INT over out-of-range longs. A LONG-only probe made an independent test pass.
Translate the long bounds into the decoded order.
Trade-offs
A raw-bit long range can cover a positive and a negative float range, so the matches are not one doc-ID run in general; it needs two intervals and more code for a rare layout.
An application that uses such a query as an access filter, for example a MUST_NOT clause on a float field, would show or hide the wrong documents on this layout.
An AI tool writing a Z3 model of the shortcut noticed that its premise, doc order equals stored-long order, is never checked against the sort type. Among the documented sort/encoding pairings, Z3 showed the premise fails only for raw-bit FLOAT/DOUBLE sorts (and INT over out-of-range values); a differential harness, a bounded-exhaustive check and a 2-document JUnit confirmed it.
The method in full215 words
Method: code reading during Z3 modelling, confirmed by a bounded-exhaustive check (the hunt's semi-formal tier). Found first in a hunt unit (doc-values range queries, 2026-10-25); the same root was found independently by three later units, all collapsed into this bug.
- While writing a Z3 model of
SortedSkipperScorerSupplier, the AI tool noticed that the model's premise (the stored longs never decrease along the doc order) is not checked by the guard. Z3 then characterised the premise per sort type; among the documented sort/encoding pairings it holds for LONG, for INT over int-range values and forSortedNumericSortFieldFLOAT/DOUBLE over sortable bits, and fails for plain FLOAT/DOUBLE over raw bits. Its differential harness hit the mismatch at random (269 of 300 runs). - The adjudication unit re-ran a wider Z3 order model and a bounded-exhaustive check on the stock jars: every index of up to 7 documents over a 3-value alphabet, 10 sort/encoding configurations, both directions and two sort layouts, 1,023,048 checks. All 40 configurations behave as the model predicts (16 unsafe ones fail, 24 safe ones are clean), and 0 mismatches remain with the fix.
- It then reduced the finding to the 2-document public-API JUnit. So this is a code-reading find that the formal model and the exhaustive check confirmed, not a blind discovery by a tool.
No prior report found (2026-10-29): two automated passes plus 49 manual GitHub queries, 29 related items read, all 409 open PRs' file lists, four mailing lists, JIRA and the web. Closest: #16885 / #16893 (same shortcut, document blocks) and LUCENE-10466 (the same pattern in the sibling query, 2022).
Searches4 searches
No report of this bug was found, and upstream main and branch_10_6 still have the guard unchanged. The hazard is publicly known (#16573 / #16629), this instance is not. Open #16698 / #16699 plans float/double support for the sibling query, possibly built on this shortcut.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and comments (apache/lucene; Elasticsearch, OpenSearch and Solr trackers) | 2026-10-29 | two automated passes (45 issue/PR, 6 commit and 4 downstream queries: class, method, skipper and sort-type names; encodings, symptoms, IndexSorter, FloatDocValuesField, DoubleDocValuesField) and 49 manual search-API queries, including comments and items updated since 2026-10-27 | no report; closest #16885 / #16893, #16573 / #16629, #11502 / #749 |
| Related items (read in full) | 2026-10-29 | 29 apache/lucene items with comments and reviews | #16885 / #16893: same shortcut, document blocks (fixed by hasBlocks(), the repro still fails); #16573 / #16629: same hazard in rewrite(); LUCENE-10466: same pattern in the sibling query; #16698 / #16699: open adjacent work; #13592, #16085, #16424, #16857: no discussion of the sort type |
| Open PRs | 2026-10-29 | changed-file lists of all 409 open PRs | only #16847 touches SortedNumericDocValuesRangeQuery.java (a maxDoc rename); none touches the guard |
| Mailing lists, JIRA archive, web | 2026-10-29 | 40 automated and 16 manual queries on dev@, issues@, commits@, java-user@; 8 JIRA queries (the archive closed in 2022, before this code); 25 web queries | nothing about this bug |
Introduced by #13592 "Take advantage of the doc value skipper when it is primary sort" (merged 2024-08-22), first released in 10.0.0. All 13 releases from 10.0.0 to 10.6.0 and main fail the repro; on the 10.0.0 jars, removing only the #13592 shortcut call makes it pass. 9.12.3 has no skip index.
Versions tested6 rows
#13592 (Ignacio Vera / iverase, commit 579427228d4, reviewed by gsmiller and jpountz) added the shortcut with a guard that required a dense field and an index sort whose first field has the queried name (indexSort.getSort()[0].getField().equals(field)), with no type check. The sort-field check stayed name-only through #16085 (195575956df, 10.5.0: moved into SortedSkipperScorerSupplier), #16424 (693a7234bad, 10.6.0: canUsePrimarySortShortcut via Sort.getPrimarySortField) and #16893 (ffa9d816eeb: adds the hasBlocks() check).
Every release row ran the repro on the release's published jars (SHA-1 checked), seed DEADBEEF, on OpenJDK 25.0.3, Linux aarch64: first an earlier, longer variant of the test, then, in the fact check, this exact test with -da, with the same results.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 (unreleased 11.0) | affected | fails, -ea and -da, gradle and standalone: count 0 instead of 1 |
| 10.6.0 | affected | fails, -ea and -da |
| 10.5.0 to 10.5.2 | affected | fail (10.5.2 with -ea and -da) |
| 10.0.0 to 10.4.0 | affected | fail (10.0.0 with -ea and -da) |
| 10.0.0 jars with only the #13592 shortcut call removed | revert | passes |
| 9.12.3 | n/a | does not compile: no skip index API (first shipped in 10.0.0) |
The finder, verifiers, cross-model reviews (OpenAI GPT-5.6) and an adjudication each wrote or re-ran their own tests, and all fail on main (the cross-model reviews on the earlier hunt main ea57360912ed); no intended-behaviour argument survived. This page's gradle runs reproduced it and validated the fix.
Checks and verdicts373 words
Every check ran on the stock jars; all voted real, with no dissent.
| Check | Verdict | What it found |
|---|---|---|
| Earliest finder | candidate | Its 2-test JUnit (FLOAT and DOUBLE index sorts) fails on 645d4fe14a20 with -ea and -da: -1f gets 0 hits, -2f gets 2. |
| Cross-model review, refute lens (OpenAI GPT-5.6) | real, high; intended argument weak | On the earlier hunt main ea57360912ed (same name-only guard, before #16893): own test (-0.25f, -16f) returns 0 instead of 1 with 3 seeds and -da; controls pass; 10.5.2 fails; the fix passes. |
| Independent reproducer | real | Own test (-0.5f, -3f) fails on main (10 of 10 seeds), 10.0.0, 10.5.2 and the 10.6.0 commit; a LONG-only probe passes; controls give 1. |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real, high; intended argument weak | The reviewer ran its own test on ea57360912ed; the cross-model review re-ran it and the repro on 645d4fe14a20 with -ea and -da: both fail; the contract is stated over the stored long with no sort precondition. |
| Intended-behaviour devil's advocate | real, high | Controls: no sort 1, no skip index 1, LONG sort 1, FLOAT sort 0, reverse FLOAT sort 2. |
| Adjudication | confirmed, high | Re-ran the finder's test (-da) and the independent reproduction's (-ea) on main with a new seed: both fail. Not noise. |
| History, prior-report and security follow-ups | introduced by #13592 (10.0.0); new; security none | 13 releases run on published jars plus a commit-level check on 10.0.0; two prior-art passes plus manual searches; security none under SECURITY.md. |
| This page's own runs | reproduced; fix A validated | Gradle in a scratch worktree: the repro fails stock with assertions on and off; with fix A it passes, and so do the nearby core suites (671 tests in all, assertions on). |
| Fact checks of this page (an independent one, and a read-only cross-model one, OpenAI GPT-5.6) | substantively correct; wording fixed | The independent check re-ran the gradle repro (assertions on and off), fix A with six suites (178 tests) and the format check, and this exact test on 9.12.3, all 13 releases from 10.0.0 to 10.6.0 and main with a new seed; its probe found the NaN edge now stated under Not affected. Both checks' wording fixes are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 528 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,432 words
- Registry title
- Doc-values exact and range queries silently miss or add documents on a skip-indexed field that holds raw float/double bits and that the index is sorted by as FLOAT or DOUBLE: SortedNumericDocValuesRangeQuery's index-sort shortcut checks the sort field's name but not its type
- Area
- search / doc-values range queries, index-sort shortcut (SortedNumericDocValuesRangeQuery.canUsePrimarySortShortcut, SortedSkipperScorerSupplier)
- Priority
- Medium, rank 82: It has the same profile as LFV-144 (silent wrong results on a hand-built raw-bit float/double NUMERIC field with a skip index once values are negative, released since 10.0) but also needs a FLOAT/DOUBLE index sort and a doc-values exact or range query.
- Impact class
- silent wrong results
- Impact note
- Applications on 10.0.0 through 10.6.0 or main that keep floats or doubles as raw IEEE bits in a single-valued NUMERIC doc-values field with a skip index (the FloatDocValuesField/DoubleDocValuesField encoding, as in Lucene's own TestSortOptimization#testFloatSortOptimizationSkpperIndex), give every document a value and sort the index by that field with SortField.Type.FLOAT or DOUBLE get wrong counts and hits, with no error, from doc-values exact and range queries on it (NumericDocValuesField.newSlowExactQuery / newSlowRangeQuery) as soon as a segment holds two distinct negative values; default codec, -ea or -da, two documents suffice; Lucene's FloatField/DoubleField (sortable encoding with SortedNumericSortField) and LONG or in-range INT index sorts are not affected.
- Summary
- You index the floats -1f and -2f as raw bits in a skip-indexed doc-values field (FloatDocValuesField.indexedField("f", Float.floatToRawIntBits(v))), sort the index by that field with new SortField("f", SortField.Type.FLOAT), and count the documents matching NumericDocValuesField.newSlowExactQuery("f", Float.floatToRawIntBits(-1f)). You expect 1, which is what you get without the index sort or without the skip index. You get 0: the query's index-sort shortcut computes one contiguous doc-ID range as if the documents were in the order of their stored longs, but the FLOAT sort puts -2f (raw -1073741824) before -1f (raw -1082130432), the reverse of the long order, and the shortcut never checks the sort type.
- Introduced
- 579427228d4297837c8c1794ddde98af0c9815fd (apache/lucene#13592 'Take advantage of the doc value skipper when it is primary sort', iverase; reviewed by gsmiller and jpountz) [exec: commit-level check on the 10.0.0 jars: SortedNumericDocValuesRangeQuery as shipped in 10.0.0 shadowed unchanged still fails, the same file with only the #13592 index-sort shortcut call removed passes; read: git log -S on the guard expression returns only 579427228d4 (added) and 693a7234bad (replaced by an equally name-only check)]. The guard stayed name-only through #15083 (2ea7c9ed1fc), #16085 (195575956df, moved the range computation into SortedSkipperScorerSupplier), #16424 (693a7234bad, canUsePrimarySortShortcut via Sort.getPrimarySortField) and #16893 (ffa9d816eeb, adds hasBlocks() only) (2024-08-22 (#13592 merged into main as 579427228d4; PR opened 2024-07-19))
- First affected version
- 10.0.0 [exec]
- Affected versions
- [exec] main 645d4fe14a20 (-ea and -da: finder 10/10 seeds, the independent reproduction, the cross-model review check, the intended-behaviour check, judge and the re-run) and every release from 10.0.0 to 10.6.0: 10.0.0, 10.1.0, 10.2.0-10.2.2, 10.3.0-10.3.2, 10.4.0, 10.5.0-10.5.2 and 10.6.0 (SHA-1-verified Maven Central jars; 10.6.0 = commit 4ae946e5a9b; -ea and -da on 10.0.0, 10.5.2 and 10.6.0). Released in 10.6.0: the tag releases/lucene/10.6.0 exists (tag object e29d290eeb05, peels to 4ae946e5a9b; git ls-remote 2026-10-29). [read] upstream main 716d6f216f5 (same file blob as 645d4fe14a20) and branch_10_6 7e5aec4370e (same blob as the 10.6.0 tag). Not applicable: 9.12.3 and older (no doc-values skip index; the repro does not compile). Not new in 10.6, except one same-fix layout: a FLOAT sort as the second sort field after a first one that is constant in the segment reaches the shortcut only since #16424 (finder's legs test on 645d4fe: 10.5.2 passes that layout, main fails it)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by Z3, exhaustive check
- Upstream and prior reports
- none found (2026-10-29, read-only). The prior-report record (verdict new): two scripted prior-report searches (A: 25 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list, 4 JIRA and 6 web queries on class, method, skipper and sort-type names; B: 20 GitHub, 3 commit, 2 downstream, 20 mailing-list, 4 JIRA and 6 web queries on encodings, symptoms, IndexSorter, FloatDocValuesField and DoubleDocValuesField), 49 manual GitHub search-API queries (apache/lucene incl. in:comments, open and unmerged PRs, items created or updated since 2026-10-27; elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr), 29 apache/lucene items read in full with comments and reviews, the changed-file lists of all 409 open PRs (only #16847 touches SortedNumericDocValuesRangeQuery.java, for maxDoc renames), commit history with author and committer dates on main, branch_11x and branch_10_6 for the fix-site files, 16 mailing-list queries (dev@, issues@, commits@, java-user@), JIRA (LUCENE archive and SOLR) and 13 web queries; plus the candidate's 51-query pass. Related, not this bug: #16885 / #16893 (same shortcut, document-block cause, fixed by the hasBlocks() guard, which is on 645d4fe where the repro still fails); #16573 / #16629 (2026, maintainers state that NUMERIC float/double doc values are raw bits and not float-ordered, for a different site, rewrite() taking min/max from points; romseygeek asked to check other places and named the sibling IndexSortSortedNumericDocValuesRangeQuery, not this shortcut); #11502 / #749 (LUCENE-10466, 2022: the same pattern fixed in the sibling query, two years before this shortcut existed); #16698 / #16699 (open, stale since 2026-10-14: float/double support for the sibling query, with a suggestion to build it on this shortcut; adjacent planned work, a watch item); #13592, #16085, #16424, #16857 (introduced and reworked the code; their discussions never mention the sort type or encodings). Refresh (2026-10-29): no apache/lucene item updated since a recent cutoff; created since 2026-10-27 in the area only #16947 (FieldValueHitQueue and TestTopFieldCollectorEarlyTermination, blocks); canUsePrimarySortShortcut finds only #16885; no commit to SortedNumericDocValuesRangeQuery.java or SortedSkipperScorerSupplier.java on main or branch_10_6 after #16893 (author date 2026-10-26); upstream main 716d6f216f5 and branch_10_6 7e5aec4370e keep the guard unchanged. Not fixed upstream. Tracking issue #16937 does not mention it, checked
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; upstream main716d6f216f5has the same file on 2026-10-29): the repro with gradle in a scratch worktree, stock with assertions on and off, and with the recommended fix together with nearby core suites (the worktree was removed after the runs); a standalone runner on main with-eaand-da(seeds DEADBEEF and 5EEDFAC7; an earlier, longer variant of the test failed 10 of 10 seeds) and, for this exact test, on the published jars of 9.12.3 and every release from 10.0.0 to 10.6.0 (SHA-1 checked,-da); the independent tests of the finder, verifiers and an adjudication. The cross-model reviews ran their own tests on the earlier hunt mainea57360912ed(same name-only guard, before #16893); a verifier re-ran one review's test and the repro on645d4fe14a20.
- Finding record
lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesRangeQuery.java:141-147 (at 645d4fe14a20) (dense single-valued field with a skipper: canUsePrimarySortShortcut -> getScorerSupplierFromDensePrimarySort), :229-253 (canUsePrimarySortShortcut: javadoc 'if it is safe'; checks the sort field's name, skipper density and hasBlocks(), never SortField#getType)lucene/core/src/java/org/apache/lucene/document/SortedSkipperScorerSupplier.java:113-182 (at 645d4fe14a20) (range() / computeSkipperDocIds: one contiguous doc-ID range from the skipper's signed-long min/max)lucene/core/src/java/org/apache/lucene/index/IndexSorter.java:249-252, (at 645d4fe14a20) 382-385, 446-449 (INT sorts by (int) v, FLOAT by Float.intBitsToFloat((int) v), DOUBLE by Double.longBitsToDouble(v))lucene/core/src/java/org/apache/lucene/search/IndexSortSortedNumericDocValuesRangeQuery.java:205-210, (at 645d4fe14a20) 535-540 ('The index sort optimization is only supported for Type.INT and Type.LONG')lucene/core/src/java/org/apache/lucene/document/NumericDocValuesField.java:58 (at 645d4fe14a20) (indexedField(String, long), inherited by FloatDocValuesField), :91-92 (newSlowRangeQuery 'matches all documents whose value is between lowerValue and upperValue included'), :132 (newSlowExactQuery 'for matching an exact long value')lucene/core/src/java/org/apache/lucene/search/Sort.java:145 (at 645d4fe14a20) (getPrimarySortField; since #16424 it may skip a leading sort field that is constant in the segment)lucene/core/src/test/org/apache/lucene/search/TestSortOptimization.java:477, (at 645d4fe14a20) 492 (upstream test layout: FloatDocValuesField.indexedField over raw float bits with a FLOAT SortField)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesRangeQuery.java:141-147, (at 645d4fe14a20) :229-253lucene/core/src/java/org/apache/lucene/document/SortedSkipperScorerSupplier.java:83-89, (at 645d4fe14a20) :113-182lucene/core/src/java/org/apache/lucene/index/IndexSorter.java:382-385, (at 645d4fe14a20) :446-449lucene/core/src/java/org/apache/lucene/search/Sort.java:138-173 (at 645d4fe14a20) (getPrimarySortField skips a leading field absent from the segment, or dense with skipper min == max)lucene/core/src/java/org/apache/lucene/document/FloatDocValuesField.java:19-40 (at 645d4fe14a20) (raw bits); document/NumericDocValuesField.java:44-60 (indexedField, skip index)
- Who is affected
lucene/core/src/java/org/apache/lucene/document/NumericDocValuesField.java:58, (at 645d4fe14a20) :110, :144; document/SortedNumericDocValuesField.java:109lucene/core/src/java/org/apache/lucene/document/FieldType.java:525-529 (at 645d4fe14a20)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/document/NumericDocValuesField.java:91-92, (at 645d4fe14a20) :132lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesRangeQuery.java:229-231 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/IndexSortSortedNumericDocValuesRangeQuery.java:205-210, (at 645d4fe14a20) :535-540; lucene/CHANGES.txt:4286-4287 (Lucene main 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/SortField.java:39-44, (at 645d4fe14a20) :82-84lucene/core/src/test/org/apache/lucene/search/TestSortOptimization.java:474-477, (at 645d4fe14a20) :492; index/TestIndexSorting.java:1168-1175, :1465-1472
- Suggested fix
lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesRangeQuery.java:149-157; (at 645d4fe14a20) search/IndexSortSortedNumericDocValuesRangeQuery.java:208, :538
- History
a Lucene clone tags releases/lucene/10.0.0 ... 10.6.0 (git tag --contains 579427228d4)
- TestDocValuesRangeQueryFloatIndexSort.java (JUnit for Lucene's build):
repro/LFV-1047/TestDocValuesRangeQueryFloatIndexSort.java(51 lines)
Made in parallel with this page: a summary card (PNG). The alt text follows the summary card.
assets/LFV-1047/bug.png(528 KB)