Lucene inverts an indexed field either through a TokenStream or, since 9.6.0, through a fast single-term path for untokenized values (InvertableType.BINARY). The fast path updates the field length twice per value, and the norm, which BM25 uses as the document length, is computed from that length.
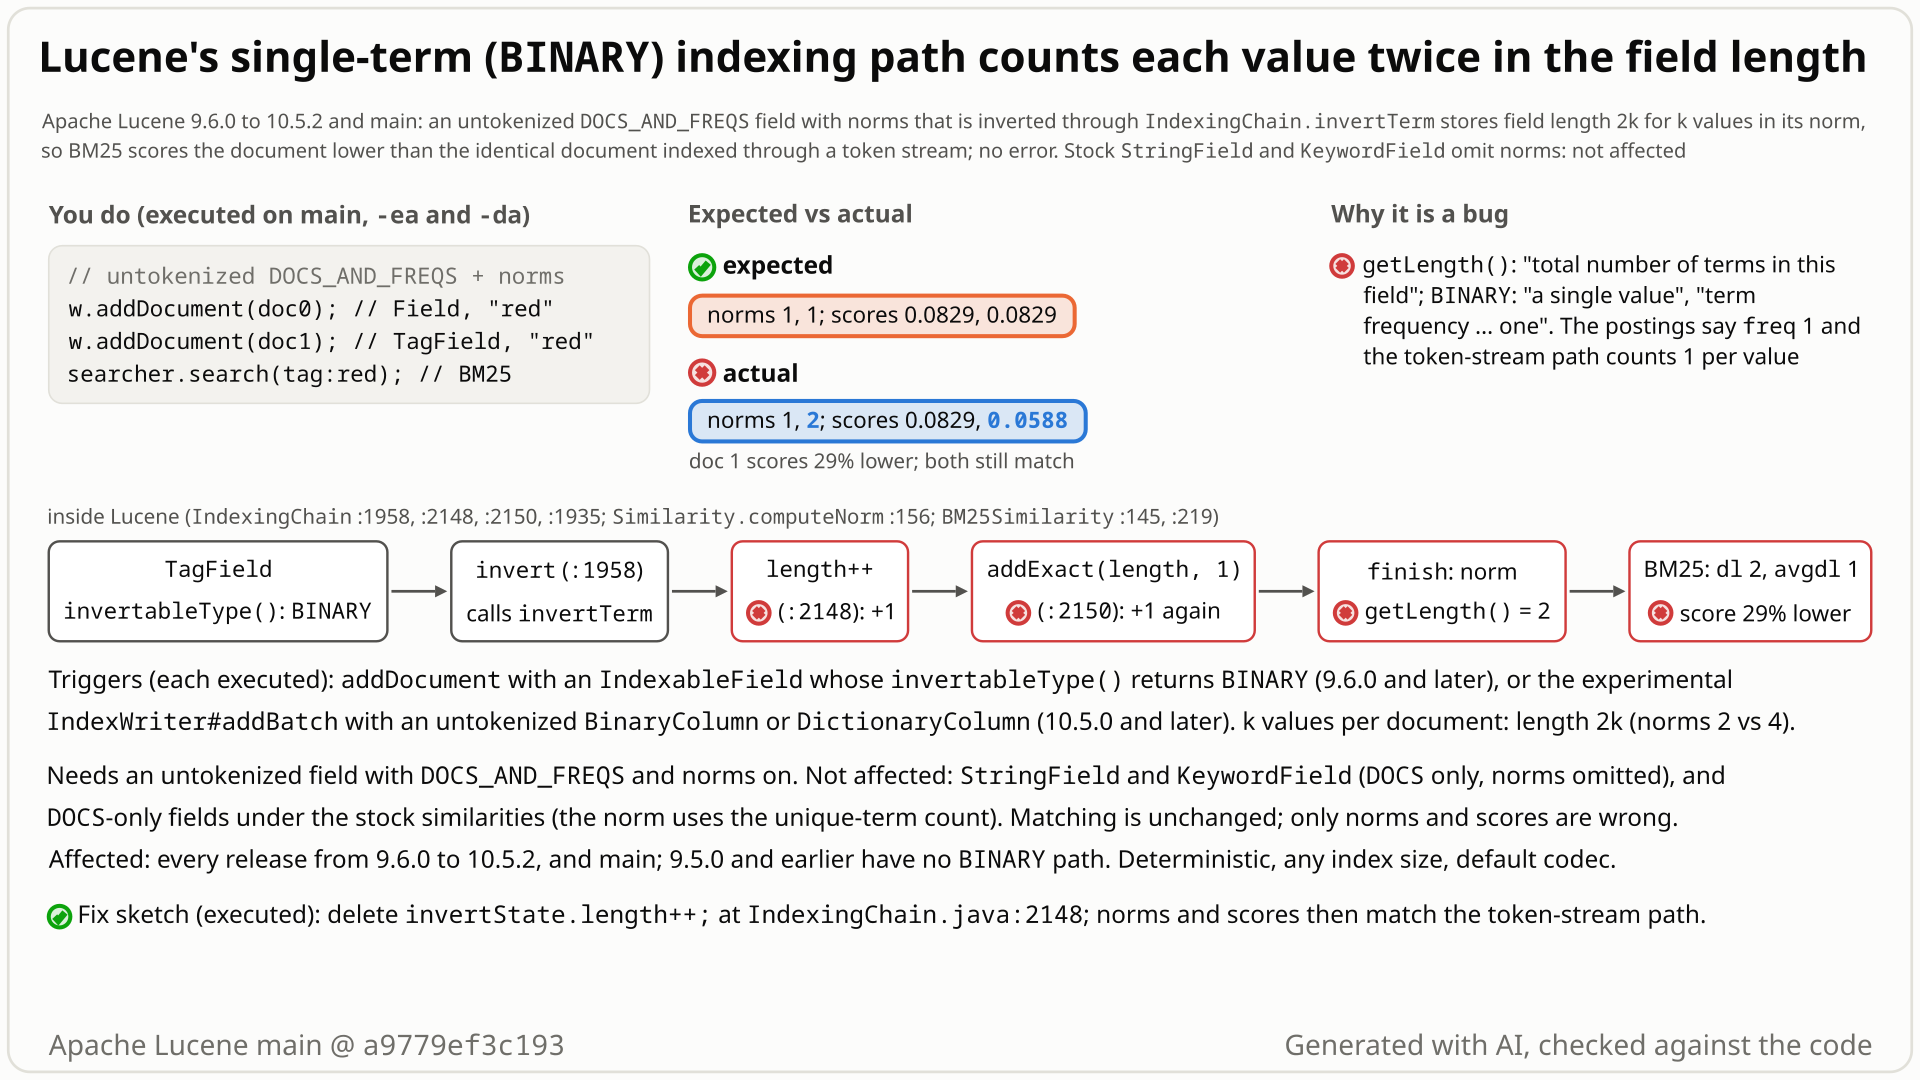
Field gets norm 1, the BINARY field goes through invertTerm, where length++ and addExact(length, 1) each add 1, so its norm is 2 and BM25 scores it 29% lower. Select the still to open it at full size. Generated with AI, checked against the code.- You give an untokenized field
tagterm frequencies and norms (DOCS_AND_FREQS, norms on by default) and index "red" twice in one index: doc 0 through a plainField, doc 1 through aFieldsubclass whoseinvertableType()returnsBINARY, the fast pathStringFielduses.addBatchcolumns take the same path. - You expect a field length of 1 for both:
FieldInvertState#getLengthis the "total number of terms in this field", and aBINARYvalue is "a single value" with term frequency one. So both documents should get norm 1 and the same BM25 score fortag:red. - Instead the fast path,
IndexingChain.invertTerm, adds 1 to the length twice per value:invertState.length++;and, two lines later,invertState.length = Math.addExact(invertState.length, 1);. Doc 1 gets norm 2; with two values, 4 instead of 2. - BM25 then treats doc 1 as twice as long:
tag:redscores 0.0829 for doc 0 and 0.0588 for doc 1, 29% lower, with no error. The postings still say freq 1, and which documents match does not change. - Through
addBatchit is the same: aBinaryColumnand aDictionaryColumnboth get norm 2 next to norm 1 for the same value added withaddDocument(BM25 0.0607 vs 0.0431).
Applications that index an untokenized field with DOCS_AND_FREQS and norms through the single-term path: a custom field returning InvertableType.BINARY (released since 9.6.0) or an untokenized BinaryColumn or DictionaryColumn in the experimental addBatch (10.5.0 and later). Every such document gets twice its length, deterministically. StringField, KeywordField and DOCS-only fields are not affected.
Mechanism, terms and numbers644 words
Since 9.6.0 an untokenized value can be indexed through a single-term path that skips the TokenStream (InvertableType.BINARY, IndexingChain.invertTerm). StringField and KeywordField use it, and so does IndexWriter#addBatch for untokenized BinaryColumn and DictionaryColumn columns. The path updates the field length twice for every value (invertState.length++; and invertState.length = Math.addExact(invertState.length, 1);), although FieldInvertState#getLength is the "total number of terms in this field" and a BINARY value is "a single value" with term frequency one. For an untokenized field with DOCS_AND_FREQS and norms, Similarity#computeNorm uses that length, so the norm encodes a length of 2k instead of k for k values and BM25 scores the document lower than the identical document indexed through a TokenStream (0.058813408 vs 0.082873434 in the repro). Postings, matching and CheckIndex are unaffected; StringField and KeywordField are DOCS-only with norms omitted. Both increments came in with the path itself in #12139; deleting the plain invertState.length++; fixes it.
- Field length and norm: while a field is inverted,
FieldInvertStatecounts its terms (getLength(), "total number of terms in this field"). At the end of the documentSimilarity#computeNormturns that count into the norm, which BM25 reads back as the document lengthdl. - Two inversion paths:
IndexableField#invertableType()chooses how a field is inverted.TOKEN_STREAM(a plainField) runs the analyzer or a one-token stream;BINARYindexesbinaryValue()as one term without aTokenStream.StringFieldandKeywordFieldreturnBINARY, andaddBatchuses it for untokenizedBinaryColumnandDictionaryColumncolumns.
PerField.invertcallsinvertTermforBINARYandinvertTokenStreamforTOKEN_STREAM(IndexingChain.java:1950-1968on maina9779ef3c193). TheaddBatchrow pass (processRowColumns,:847) wraps aBinaryColumnorDictionaryColumnin aBinaryColumnAdapter(ColumnFieldAdapter.java:51-62) whoseinvertableType()isBINARYfor indexed untokenized columns (:244-250), and reaches the sameinvertthroughinvertAndStore(IndexingChain.java:1477-1487).invertTerm(IndexingChain.java:2127-2170) rejects tokenized fields and anything with positions or term-vector positions, offsets or payloads (:2136-2144), then runsinvertState.position++;(:2147),invertState.length++;(:2148),termsHashPerField.start(field, first);(:2149) andinvertState.length = Math.addExact(invertState.length, 1);(:2150). It adds the term once (:2152), so the postings get freq 1, but the length grows by 2.invertTokenStreamadds 1 per token (or the custom term frequency) in a singleMath.addExact(IndexingChain.java:2053-2064).PerField.finishstoressimilarity.computeNorm(invertState)(IndexingChain.java:1926-1944).Similarity#computeNormusesgetLength()for every index option exceptDOCS, which uses the unique-term count (Similarity.java:151-161). The length is encoded withSmallFloat.intToByte4(Similarity.java:160), so aDOCS_AND_FREQSfield gets the norm of length 2k instead of k for k values; aDOCSfield is unaffected under the stock similarities. The norm byte equals the length up to 40 and is lossy above (SmallFloat.java:139-165): one value gives norm 2 instead of 1, 21 values the code 41 (decoded length 42) instead of 21.- BM25's average length is
sumTotalTermFreq / docCount(BM25Similarity.java:143-146), which is right; only each document's own length is doubled, so everyBINARYdocument'sdl/avgdlis twice its correct value (2 instead of 1 in the repro, where each document's true length equals the average).
One index, default IndexWriterConfig (BM25), field type untokenized DOCS_AND_FREQS with norms. One value per document, doc 0 through a plain Field and doc 1 as BINARY: norms [1, 2], TermQuery scores [0.082873434, 0.058813408], explain shows dl=1.0 and dl=2.0 with avgdl=1.0. Two values per document: norms [2, 4], the same scores. addBatch, doc 0 with addDocument and docs 1 and 2 as a BinaryColumn and a DictionaryColumn: norms [1, 2, 2], scores [0.06069608, 0.043074638, 0.043074638]. The same with IndexOptions.DOCS: norms [1, 1], equal scores. With values a, b, a in one document the BINARY path writes norm 6 while sumTotalTermFreq is 3; the TokenStream path and MemoryIndex give 3.
Exposure and likelihood495 words
- Who. Applications with an untokenized indexed field whose
FieldTypehasDOCS_AND_FREQSand norms enabled (omitNormsdefaults to false,FieldType.java:41) that goes through theBINARYpath:addDocumentwith a customIndexableFieldorFieldsubclass whoseinvertableType()returnsBINARY(public API, 9.6.0 on;IndexableField#invertableType()has no default, so every implementation that does not extendFieldpicks one), or the@lucene.experimentalIndexWriter#addBatchwith an indexed untokenizedBinaryColumnorDictionaryColumn(10.5.0 on), where no override is needed. - What goes wrong. Norms and BM25 scores only, silently: no exception,
CheckIndexclean. Matching, deletions andFieldExistsQueryare unchanged (executed throughaddDocument: 40 random documents, 2 deleted, once with a plainFieldand once with aBINARYfield, assertions on and off;addBatchreaches the sameinvertTermby code reading). - Size of the effect. BM25's term-frequency factor is
tf = freq / (freq + k1 * (1 - b + b * dl / avgdl))(BM25Similarity.java:219,:272-273,:307-328), so doublingdl/avgdllowers each score by a fraction that depends on the document's frequency and length: 29% for freq 1 atdl = avgdl, as in the repro. The scores do not drop uniformly, and ranking can flip even inside one field where every document takes theBINARYpath (executed by the fact check, public API, seed DEADBEEF, main with assertions on and off and 9.6.0): docs A = [x], B = [x,x,y] and a third with 8 distinct values (avgdl4), querytag:x. All through a plainField: A 0.3081991 < B 0.3159688; all asBINARY: A 0.26857352 > B 0.25753623 (A loses 12.9%, B 18.5%), so the order flips; with the fix theBINARYscores equal the plain-Fieldones. The doubling also shifts the field's weight against other fields and against documents of the same field indexed through aTokenStream, for exampleaddDocumentwith a plainFieldnext toaddBatchcolumns. - Default vs opt-in. Default
IndexWriterConfig, codec and similarity; the opt-in part is the field type, which no stock Lucene field uses. - Not affected.
StringFieldandKeywordField(DOCS, norms omitted);DOCS-only fields with norms under the stockcomputeNorm, which counts unique terms. ForDOCSfieldsgetLength()is doubled too (executed: the independent reproducer's recordingBM25Similarityand the diagram probe printgetLength()[1, 2] with norms [1, 1]), so a customSimilaritythat reads it there would see the doubling (read). - Scale. Deterministic for every value that takes the path, independent of the index size, up to the overflow limit below.
- Side effect (read, not executed). The
Math.addExactoverflow check fires after about 2^30 values in one field of one document instead of about 2^31: today the 2^30th value makesMath.addExact(IndexingChain.java:2150) throw a rawArithmeticException; with the fix the limit moves to the 2^31st value, still a rawArithmeticException, while theTokenStreampath wraps the same overflow inIllegalArgumentException(:2061-2064).
The test shows that one value of an untokenized DOCS_AND_FREQS field with norms, indexed through a Field whose invertableType() is BINARY, gets field length 2 in IndexingChain.invertTerm, so its BM25 norm is 2.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.InvertableType;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestBinaryInvertableTypeNorm extends LuceneTestCase {

  public void testSingleValueNorm() throws Exception {
    FieldType type = new FieldType();
    type.setIndexOptions(IndexOptions.DOCS_AND_FREQS);
    type.setTokenized(false);
    Document doc = new Document();
    doc.add(
        new Field("tag", new BytesRef("x"), type) {
          @Override
          public InvertableType invertableType() {
            return InvertableType.BINARY;
          }
        });
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      w.addDocument(doc);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        NumericDocValues norms = getOnlyLeafReader(reader).getNormValues("tag");
        assertTrue(norms.advanceExact(0));
        // one value = field length 1, so the BM25 norm should be 1; actual 2
        assertEquals(1, norms.longValue());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-105/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestBinaryInvertableTypeNorm
- Expected vs actual
- Expected norm 1 (one term, as
FieldInvertState#getLengthand theInvertableType.BINARYjavadoc say); actual 2 (expected:<1> but was:<2>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<1> but was:<2>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.junit.Assert.assertEquals(Assert.java:633)
org.apache.lucene.index.TestBinaryInvertableTypeNorm.testSingleValueNorm(TestBinaryInvertableTypeNorm.java:49)FieldInvertState#getLengthis the "total number of terms in this field"; aBINARYvalue is "a single value" with term frequency one.- The
TokenStreampath and MemoryIndex's single-term path count 1 per value; the writer's ownsumTotalTermFreqsays 1. - Lucene's own
BINARYtest accepts this field type but never checks norms; both increments came in a speed-only change.
The full argument244 words
- The contract.
FieldInvertState.java:124-131:getLength(): "Get total number of terms in this field."InvertableType.java:25-32:BINARY: "The field should be treated as a single value whose binary content is returned byIndexableField#binaryValue(). The term frequency is assumed to be one. [...] If the same value is provided multiple times, the term frequency will be equal to the number of times that this value occurred in the same document." - Every sibling counts 1 per value (executed): the same field type through the
TokenStreampath, and MemoryIndex's single-term path added in the same commit (storeTerm,info.numTokens++once per value,MemoryIndex.java:968-969). The same writer'ssumTotalTermFreq(1 per value) disagrees with its own norm (2 per value). - Lucene's own test accepts the trigger.
TestDocumentWriter#testIndexBinaryValueWithoutTokenStream(TestDocumentWriter.java:435), added in #12139, indexes aBINARYfield with six legal field types, including untokenizedDOCS_AND_FREQSwithsetOmitNorms(false)(:502-509). It checks postings and term vectors, never norms (:543-592). The upstream column tests setomitNorms(true)on their untokenized types. - History.
invertState.length++;is the form theTokenStreampath used before LUCENE-7854 (2017) replaced it with theMath.addExactform;invertTermhas both, already in the first commit of #12139, unchanged since. The PR is about attribute overhead; its 12 comments discuss API shape and naming and never mention length, norms or scores. CHANGES lists it under 9.6.0 as "GITHUB#12139: Faster indexing of string fields." No javadoc, CHANGES or MIGRATE entry restricts norms onBINARYfields.
The devil's-advocate check212 words
The strongest works-as-designed case, built by the intended-behaviour verifier, a review by a model from another family (OpenAI GPT-5.6) and the adjudication: BINARY is a performance fast path whose only stock users omit norms, so norms on a BINARY field are an unsupported combination; addBatch is @lucene.experimental and its javadoc does not promise the same index as addDocument; and the addDocument trigger needs a custom invertableType() override.
Why it fails: #12139 promised only speed and no document restricts norms on this path; the PR's own test lists the trigger field type as legal; overriding invertableType() is public API that StringField and KeywordField use themselves; two adjacent increments of the same counter serve no performance or semantic purpose; and @lucene.experimental covers API stability, not wrong index data, while the released trigger is addDocument. For DOCS fields under a custom Similarity that reads getLength() (not the stock case) the argument is narrow reach, not correctness: getLength() still promises the total number of terms and reports twice that. Every verifier and the cross-model reviews rated the intended argument weak; the cross-model fact check of this doc rated it weak for addDocument and moderate for the experimental addBatch path and the custom-Similarity DOCS case, and found no plausible purpose for the duplicate increment.
Recommended Delete invertState.length++ and keep the Math.addExact update
Delete the extra invertState.length++; in IndexingChain.invertTerm and keep the overflow-checked Math.addExact update, one line. The repro passes with assertions on and off, 18 nearby core test classes (20 with the two repro classes, 258 tests) and lucene/memory pass, and a norms check added to TestDocumentWriter's BINARY test fails on stock main and passes with the fix.
       invertState.setAttributeSource(null);
       invertState.position++;
-      invertState.length++;
       termsHashPerField.start(field, first);
       invertState.length = Math.addExact(invertState.length, 1);
All options and trade-offs3 options · 457 words
One fix was applied in a scratch worktree at a9779ef3c193 and run through gradle (seed DEADBEEF), together with a norms check added to the existing BINARY test; the alternatives were not run.
Delete invertState.length++ and keep the Math.addExact update (validated by the checks) (recommended)
One line in IndexingChain.invertTerm. Each value then adds 1 to the field length, like the TokenStream path and MemoryIndex, so norms and BM25 scores match the TokenStream path for the same field type; postings and term vectors are unchanged. A second diff adds 8 lines to TestDocumentWriter#testIndexBinaryValueWithoutTokenStream: for each legal field type with norms, norm 2 for the two DOCS_AND_FREQS values and 1 for DOCS.
       invertState.setAttributeSource(null);
       invertState.position++;
-      invertState.length++;
       termsHashPerField.start(field, first);
       invertState.length = Math.addExact(invertState.length, 1);
Trade-offs
- Existing segments keep the norms they were written with until the documents are reindexed, because merges copy the stored norms; old and new segments of such a field score differently in the meantime. Worth a CHANGES line.
- None for new documents: the result equals the
TokenStreampath.
What the checks validated
- Stock main
a9779ef3c193: the two repro files fail 3 of 4 with assertions on and off;TestDocumentWriterwith the added norms check fails 1 of 15 ("expected:<2> but was:<4>"). - With the fix: the repro files pass 4 of 4 with assertions on and with assertions off;
TestDocumentWriterwith the norms check passes 15 of 15. - With the fix, the closest suites pass: in core
TestDocumentWriter,TestIndexableField,TestFieldReuse,TestFieldInvertState,TestNorms,TestCustomNorms,TestOmitNorms,TestCustomTermFreq,TestDocInverterPerFieldErrorInfo,TestColumnBatchIndexing, the sixdocument.columnclasses,TestKeywordFieldandTestField, plus the two repro classes (20 classes, 258 tests, 0 failures); all oflucene/memory(3 classes, 51 tests). ecjLintandcheckGoogleJavaFormatpass for core with the repro tests and the norms check in place; both diffs apply cleanly to a clean tree.- Earlier, in the hunt (fix shadowed onto the stock jars): the finder's, the independent reproducer's, the GPT reviewers' and the adjudication's tests pass, as do upstream
TestDocumentWriter(15 run, 0 failed) and the column-batch tests the reviewers ran; the same deletion makes the introducing commit pass. - Not run: the full
lucene/coresuite; no benchmark (the change removes one increment).
Also gives 1 per value.
Trade-offs
Drops the overflow check that the TokenStream path has. Not recommended.
Optional hardening on top of the recommended fix: throw IllegalArgumentException("too many tokens for field ...") as invertTokenStream does (IndexingChain.java:2061-2064).
Trade-offs
Only matters at about 2^31 values in one field of one document (2^30 before the fix); today invertTerm throws a raw ArithmeticException there, and this makes both paths fail the same way.
By code reading only (not executed), Elasticsearch's keyword field also returns InvertableType.BINARY and its mapping accepts norms: true with index_options: freqs, so such keyword mappings appear to reach this path, with wrong scores only.
Translation validation of the experimental addBatch against row-by-row addDocument on the real jar: 29,408 bounded-exhaustive scenarios gave 1,242 norm mismatches, all from the one untokenized DOCS_AND_FREQS column with norms, and none with the one-line fix. Reading invertTerm then gave the root cause and the second trigger, a BINARY field in addDocument.
The method in full203 words
Method: bounded-exhaustive translation validation on the stock jar (semi-formal tier), in a hunt unit on the column-batch addBatch API.
- The harness indexes every one of 26 single-column specs (
Long,Binary,Dictionary,VectorandTokenStreamcolumns with different field types) throughaddBatchand, as the reference, the same documents row by row throughaddDocument, then compares the two indexes: dense and every sparse pattern for 0 to 3 documents, a document before and/or after the batch, and 4IndexWriterConfigs, with assertions on and off (29,408 scenarios). - It reported 1,242 norm mismatches, all from the one
DictionaryColumnspec that is untokenized withDOCS_AND_FREQSand norms: batch norm 2, row norm 1. With the one-line fix shadowed onto the jar the mismatches went to 0. - The root cause was then located by reading
invertTerm, which showed that the path is shared withaddDocument; the finder added theaddDocumenttrigger (aFieldsubclass returningBINARY), which reaches back to 9.6.0. - Found 2026-10-25 on main
ea57360912ed; then checked by an independent reproducer, an intended-behaviour devil's advocate, two executed reviews by a model from another family (OpenAI GPT-5.6), an adjudication, a history and prior-report follow-up and a credibility audit.
No prior report found (2026-10-25/26) in over 140 recorded queries from three searches over GitHub issues, PRs and commits, the mailing lists, the JIRA archive, Elasticsearch, OpenSearch, Solr and the web, plus the changed files of all 412 open PRs. Both increments are still on main and the release branches.
Searches5 searches
Verdict new: no report by anyone. Keyword search cannot prove absence; GitHub search reads the first page per query, and private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; dev@, java-user@, issues@, commits@; JIRA archive; Elasticsearch, OpenSearch, Solr; the web | 2026-10-26 | 99 recorded checks: 70 queries of the hunt's prior-report tool (30 GitHub issue/PR, 6 commit, 20 mailing-list, 4 JIRA-archive, 4 downstream-repo, 6 web), 19 more GitHub searches and 10 other records (2 list searches over all dates, 5 GitHub API reads, 1 history query, 2 web searches) | no report; related only: #12139 (introduced it), #15584, #15826, #15990, #16101, #16227 |
| every apache/lucene issue (about 1,200) and PR (about 3,700) created since 2023-01, and all 412 open PRs | 2026-10-26 | titles and bodies grepped locally; changed-file lists of the open PRs | nothing relevant; draft #16116 inverts only omitNorms columns in its new pass; #16734 (since merged as a9779ef3c193) and #16269 do not touch invertTerm |
| discussions of the PRs that created or edited the code | 2026-10-26 | read in full: #12139, #15584, #15826, #15990, #16101, #16116, #16219, #16224, #16227 and the dev@ column-API design thread | no mention of the field length or norms on the BINARY path |
| the finder's and the devil's advocate's runs | 2026-10-25 | 21 queries (16 GitHub issue/PR, 3 commit, 2 downstream); 20 mailing-list and 4 JIRA-archive queries plus direct GitHub searches | no report |
| Elastic forum | 2026-10-26 | web search | context only: a March 2023 thread on a keyword field with freqs and norms predates the downstream 9.6 upgrade and shows the correct count |
Born with the single-term path in #12139 (cce33b07e4f5, 2023-02-21; first release 9.6.0); addBatch added a second trigger in 10.5.0 (#15990). Executed: 9.6.0, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.2 and main fail, the introducing commit fails and passes with the deletion; 9.5.0 has no InvertableType. Not fixed upstream.
Versions tested8 rows
Introduced by cce33b07e4f5 on main, "Skip the TokenStream overhead when indexing simple keywords. (#12139)" (@jpountz, merged 2023-02-21), backported to the 9.x line the same day as 668246439ddf. It created InvertableType, the abstract IndexableField#invertableType(), invertTerm with both increments (already in the PR's first commit) and switched StringField and KeywordField to BINARY. Not a regression of older code: the TokenStream path, the only one before, counts 1 per value and did not change.
IndexWriter#addBatch came with #15990 (3d895681557, merged 2026-05-14; 3ec3bff01b1 in 10.5.0), and its BinaryColumnAdapter returns BINARY for untokenized indexed columns. Later edits of invertTerm, #15826 (2026-03, ArrayUtil.copyOfSubArray in the immense-term prefix copy) and #15584 (2026-04, the index-options guard), leave the increments alone. On 2026-10-26 main, branch_10x, branch_10_6, branch_10_5 and branch_9_12 still had both lines (read only; the plain increment re-read on all five on 2026-10-27 by the fact check).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the two compact JUnits fail 3 of 4 through gradle, assertions on and off; the classpath runner gives the same with -ea and -da |
main ea57360912ed | affected | the finder's, the independent reproducer's, the devil's advocate's and the reviewers' tests fail, -ea and -da |
| 10.5.0, 10.5.2 | addBatch trigger | addDocument and addBatch (BinaryColumn; DictionaryColumn on 10.5.0 in the fact check, and on 10.5.2) fail; 10.5.2 also with -da |
| 10.0.0, 10.4.0 | affected | addDocument fails; 10.4.0 has no column API |
| 9.6.0, 9.12.3 | first release | the compact JUnit fails 2 of 3 (9.6.0 also with -da), same norms and scores as main |
cce33b07e4f (#12139) vs parent dbfca9a62b8 | bisect | the commit fails the addDocument repro with -ea and -da, its norm and score variant (-ea) gives norms [1, 2] and [2, 4], and both pass with the one-line deletion; the parent has no InvertableType, and its plain Field gives the correct norms 1 and 2 |
| 9.5.0 and older | no BINARY path | compile error: InvertableType does not exist; the TokenStream baseline is correct |
fix (scratch worktree at a9779ef3c193) | not affected | the two repro files pass 4 of 4, assertions on and off; 18 nearby core classes plus the two repro classes (20 classes, 258 tests) and lucene/memory pass |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests, controls passing; two executed reviews by a model from another family (OpenAI GPT-5.6) rated it real with a weak intended argument; an adjudication re-ran it with a new seed; this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts614 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed, and every fix check passed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Translation-validation harness, then public-API JUnits for both triggers: 2 of 2 fail on main (-ea, -da) and 10.5.2; the addDocument-only test fails on 9.12.3 and 9.6.0; the fix passes. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high | Its own test fails only the custom-BINARY addDocument and BinaryColumn cases (2 of 4, -ea and -da; 6 of 12 over 3 iterations); its TOKEN_STREAM and DOCS-only controls pass; the fix passes its tests and the upstream TestDocumentWriter BINARY test. |
| independent reproducer | real | Own tests from the claim only: lengths and norms [1, 2] and [2, 4], BM25 0.082873434 vs 0.058813408; addBatch norms [1, 2, 2]; also on 10.5.2, 9.12.3 and 9.6.0; DOCS controls pass; its fix passes 3 of 3. |
| cross-model review, intended lens (OpenAI GPT-5.6) | real, high; intended argument weak | Its own test fails 3 of 6 on main, also with -da and on 10.5.2; its MemoryIndex and TOKEN_STREAM controls count 1 per value; the fix passes its test, TestDocumentWriter (15 run, 0 failed) and a column-batch parity test. Re-run locally with -ea and -da. |
| intended-behaviour devil's advocate | real, high | No intended argument survives; its consistency test (IndexWriter BINARY vs TOKEN_STREAM vs MemoryIndex) fails 2 of 2 on main (-ea, -da), 9.6.0 and 10.5.2: norms 2, 1, 1 and, for a, b, a, 6, 3, 3. |
| adjudication | confirmed, high | Re-ran the independent reproduction's two tests with seed 7A11BEEF (2 of 3 fail each, -ea and -da; 3 of 3 pass with the fix). |
| Follow-up (history, prior reports, security check) | new; not security-sensitive | 32 history runs, each as predicted (introducing commit fails and passes with the deletion, 9.6.0 to main fail, 9.5.0 lacks the API); 99 recorded prior-report checks; matching, deletions and CheckIndex identical on both paths. |
| main refresh to a9779ef3c193 | still reproduces | The finder's two repros fail with the same messages; #16734 changed IndexingChain only in the vector-column code (imports, processVectorColumn and a new processDenseVectorColumn helper); invertTerm is unchanged. |
| this doc's runs | reproduces; fix validated | The two compact JUnits fail 3 of 4 on stock main through gradle, assertions on and off; through the classpath runner the addDocument test fails on main, 10.5.2, 9.12.3 and 9.6.0 and the addBatch test on main and 10.5.2. With the fix they pass, as do 18 nearby core classes plus the two repro classes (20 classes, 258 tests), lucene/memory, lint and format; a norms check added to TestDocumentWriter fails on stock and passes with the fix. |
| Fact check of this doc (re-ran the tests) | real, reproduced; 3 wording errors fixed | Re-ran the gradle command (3 of 4 fail, assertions on and off), the classpath runs on main, 9.6.0 and 10.5.0 and the fix, and an all-BINARY ranking probe that flips the order of two documents; three wording errors (the size of the effect, dl/avgdl, the harness count) fixed. |
| Cross-model fact check (OpenAI GPT-5.6, reading only) | bug real; 4 errors, 3 overclaims, 3 missing caveats | Agreed with the mechanism, the numbers and the fix; its findings on the encoded norm, the line shift, the history wording, the query count, uniformity, scale, the security check's scope and the overflow behaviour were fixed. It rated the intended argument moderate overall (weak for addDocument). |
| Diagram check | pass; minor items fixed | Every value, API name and line number on screen matched the code and a re-run of the probe; the wording items (and the fact checks' "norm 2k" point) were fixed and the visuals re-rendered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 473 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,292 words
- Registry title
- IndexingChain.invertTerm adds 2 to the field length for each single-term (InvertableType.BINARY) value, so untokenized DOCS_AND_FREQS fields with norms get double the norm and a lower BM25 score
- Area
- index / indexing chain (single-term BINARY inversion, norms)
- Priority
- Medium, rank 238: Single-term BINARY inversion adds 2 to the field length per value, silently doubling norms and lowering BM25 for untokenized DOCS_AND_FREQS fields with norms since 9.6, deterministic once used but a combination no stock field uses.
- Impact class
- silent wrong results
- Impact note
- Applications that index an untokenized field whose FieldType has DOCS_AND_FREQS and norms enabled through the single-term BINARY inversion path, either with addDocument and a custom IndexableField whose invertableType() returns BINARY (released since 9.6.0) or with the experimental IndexWriter#addBatch and an indexed untokenized BinaryColumn or DictionaryColumn (10.5.0 and later), get norm 2k instead of k for k values and wrong BM25 scores with no error, at any scale and with the default codec, IndexWriterConfig and similarity; stock StringField and KeywordField (DOCS-only, norms omitted) are not affected, and matching is unchanged.
- Summary
- You index one value in an untokenized field whose FieldType has DOCS_AND_FREQS and norms enabled, once through a plain Field (TokenStream inversion) and once through the single-term path (a Field subclass whose invertableType() returns BINARY, or an IndexWriter#addBatch BinaryColumn or DictionaryColumn). You expect the same field length and norm, 1 per value, because FieldInvertState#getLength is the 'total number of terms in this field' and a BINARY value is documented as a single value with term frequency one. Instead IndexingChain.invertTerm adds 2 to the length for every value, so the norm is 2 (2k for k values) and the BM25 score of the identical document drops (0.082873434 to 0.058813408 in the repro), while the postings still record freq 1 per value.
- Introduced
- cce33b07e4f5 (#12139 'Skip the TokenStream overhead when indexing simple keywords', main; 9.x backport 668246439ddf the same day), which created invertTerm with both 'invertState.length++;' and 'invertState.length = Math.addExact(invertState.length, 1);' [exec: a commit-level build of cce33b07e4f fails the repro with -ea and -da and passes with the one-line deletion; at its parent dbfca9a62b8 the repro does not compile (no InvertableType) and the same field type through a plain Field gives norms 1 and 2 for one and two values; read: git blame of both lines, git log -S and git log -L on invertTerm, and the PR's first commit 9943038 already has both lines]; not a regression of older code: the doubled count came with the BINARY path itself. The addBatch trigger came later with #15990 (3d895681557, merged 2026-05-14; backport 3ec3bff01b1, first released in 10.5.0), whose BinaryColumnAdapter#invertableType returns BINARY for indexed untokenized columns [read] (2023-02-21 (#12139 merged into main and backported to branch_9x the same day); addBatch trigger from 2026-05-14 (#15990 merged))
- First affected version
- 9.6.0 [exec] (addDocument with a field whose invertableType() is BINARY); 10.5.0 for the addBatch BinaryColumn trigger [exec]
- Affected versions
- every release from 9.6.0 on: 9.6.0-9.12.3, 10.0.0-10.5.2 and 10.6.0 (by reading), and main ea57360912ed [exec: 9.6.0, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.2, main and the introducing commit cce33b07e4f fail (9.6.0, 10.5.2, main and the commit also with -da); read: both increments are present at every 9.6.0+ release tag, and invertTerm is identical in the main commit, the 9.x backport and 9.12.3]; addBatch trigger: 10.5.0-10.5.2, 10.6.0 (by reading) and main [exec: BinaryColumn on 10.5.0, 10.5.2 and main, main also with -da; DictionaryColumn on 10.5.2 and main]; not affected: 9.5.0 and earlier, where InvertableType and the BINARY path do not exist (the repro does not compile; the TokenStream baseline is correct) [exec]; not fixed upstream: main, branch_10x, branch_10_6 (10.6.0, released 2026-10-29), branch_10_5 and branch_9_12 still have both increments [read, 2026-10-26]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-25/26: the finder's scripted prior-report search with 16 GitHub issue/PR, 3 commit and 2 downstream-repo queries; the intended-behaviour check's run with 20 mailing-list and 4 JIRA-archive queries plus direct gh searches; the follow-up's 99 queries: a scripted prior-report search with 30 GitHub issue/PR, 6 commit, 20 mailing-list (dev@, java-user@, issues@, commits@), 4 JIRA-archive, 4 downstream-repo and 6 web queries, 19 more GitHub searches over apache/lucene, Elasticsearch, OpenSearch and Solr, manual list searches over all dates, a local grep of the titles and bodies of about 1,200 issues and 3,700 PRs created since 2023-01, the changed-file lists of all 412 open PRs, the full discussions of #12139, #15584, #15826, #15990, #16101, #16116, #16219, #16224 and #16227, and 2 more web searches; git log -S and git log -L on the full history); both increments are still present upstream on main, branch_10x, branch_10_6 and branch_10_5 (2026-10-26, read-only); a JIRA report cannot exist because the code dates from 2023, after the move to GitHub; related prior items, none of them this bug: #12139 (introduced it; its 12 comments discuss API shape only, never length or norms), #15584 (last functional edit of invertTerm, DOCS_AND_CUSTOM_FREQS), #15826 (edited only the immense-term message), #15990, #16101 and #16227 (added the column API and the column types that reach invertTerm), open draft #16116 (column-pass inversion only for omitNorms columns; norms-enabled columns still go through invertTerm), #16734 (merged 2026-10-26 as a9779ef3c19; on main and branch_11x, not on branch_10_6) and open draft #16269 (both touch IndexingChain but not invertTerm); no downstream report in Elasticsearch, OpenSearch or Solr)
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the two compact JUnits through gradle in a clean worktree, stock and with the fix, assertions on and off, plus 18 nearbylucene/coretest classes (20 classes and 258 tests with the two repro classes) andlucene/memorywith the fix (2026-10-27); through the hunt's classpath runner,TestBinaryInvertedFieldNormson main (-ea,-da, fix shadowed), 10.5.2, 9.12.3 and 9.6.0 (9.5.0: noInvertableType) andTestColumnBatchUntokenizedNormson main (-ea,-da, fix shadowed) and 10.5.2. Hunt runs on mainea57360912ed, releases 9.6.0 to 10.5.2, the introducing commitcce33b07e4fand its parent; the main refresh toa9779ef3c193reproduces with identical messages.
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2072-2095 (invertTerm: guard :2081-2089, 'invertState.length++;' :2093, 'invertState.length = Math.addExact(invertState.length, 1);' :2095), :1998-2008 (TOKEN_STREAM path: one addExact per token), :1872-1886 (PerField.finish norm computation)lucene/core/src/java/org/apache/lucene/index/FieldInvertState.java:124-129 (getLength javadoc 'Get total number of terms in this field.')lucene/core/src/java/org/apache/lucene/document/InvertableType.java:25-31 (BINARY javadoc: 'treated as a single value', 'The term frequency is assumed to be one')lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:151-160 (computeNorm: getLength() for every index option except DOCS, which uses getUniqueTermCount())lucene/core/src/java/org/apache/lucene/document/column/ColumnFieldAdapter.java:150 (BinaryColumnAdapter), :245-251 (invertableType returns BINARY for indexed untokenized columns)lucene/core/src/test/org/apache/lucene/index/TestDocumentWriter.java:435 (testIndexBinaryValueWithoutTokenStream), :493-508 (legal BINARY field types include untokenized DOCS_AND_FREQS with setOmitNorms(false); the test checks freqs, not norms)lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:968-969 (storeTerm, the MemoryIndex BINARY path: info.numTokens++ once per value)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:847, 872, 1477-1487, 1926-1944, 1950-1968, 2053-2064, 2127-2170 (increments :2148 and :2150)lucene/core/src/java/org/apache/lucene/document/column/ColumnFieldAdapter.java:48-68, 150, 244-250lucene/core/src/java/org/apache/lucene/index/FieldInvertState.java:124-131; lucene/core/src/java/org/apache/lucene/document/InvertableType.java:25-32lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:151-161; BM25Similarity.java:143-146lucene/core/src/java/org/apache/lucene/document/Field.java:459-462; StringField.java:89-92; KeywordField.java:111-114
- Who is affected
lucene/core/src/java/org/apache/lucene/document/FieldType.java:41; lucene/core/src/java/org/apache/lucene/index/IndexableField.java:80-84; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1528-1539lucene/core/src/java/org/apache/lucene/document/StringField.java:36-44; KeywordField.java:56-58
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/FieldInvertState.java:124-131; lucene/core/src/java/org/apache/lucene/document/InvertableType.java:25-32lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:636-645, 968-969lucene/core/src/test/org/apache/lucene/index/TestDocumentWriter.java:391-434, 435, 493-592lucene/CHANGES.txt:3628
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2053-2064, 2145-2151lucene/core/src/java/org/apache/lucene/codecs/NormsConsumer.java:104-125 (merge copies stored norms)
- TestBinaryInvertableTypeNorm.java (JUnit test):
repro/LFV-105/src/org/apache/lucene/index/TestBinaryInvertableTypeNorm.java(53 lines)
Made in parallel with this doc from a probe run on main a9779ef3c193 (stock and with the fix); the values on screen come from the probe. The diagram uses the value "red", the compact repro "x"; norms and scores are the same.
assets/LFV-105/bug.png(473 KB)