Each segment decides from the query's cost whether reading the sort field's points is worth it. Since #16857 a later segment makes that decision before the cost is known, using the placeholder -1, so it always reads.
search(query, n, sort)counts hits exactly up to a threshold, 1,000 by default. Past it, Lucene may skip documents that cannot enter the top n.- For a numeric sort field that is also indexed as points,
NumericComparatorcan ask the points index for the documents whose value still beats the current n-th hit, and then visit only those (a "competitive iterator"). - Reading points costs work, so it does that only when the result is at least 8x smaller than what the query itself matches. The query's match count (its cost) arrives with
setScorer(); until then the comparator stores -1, meaning "not known yet".
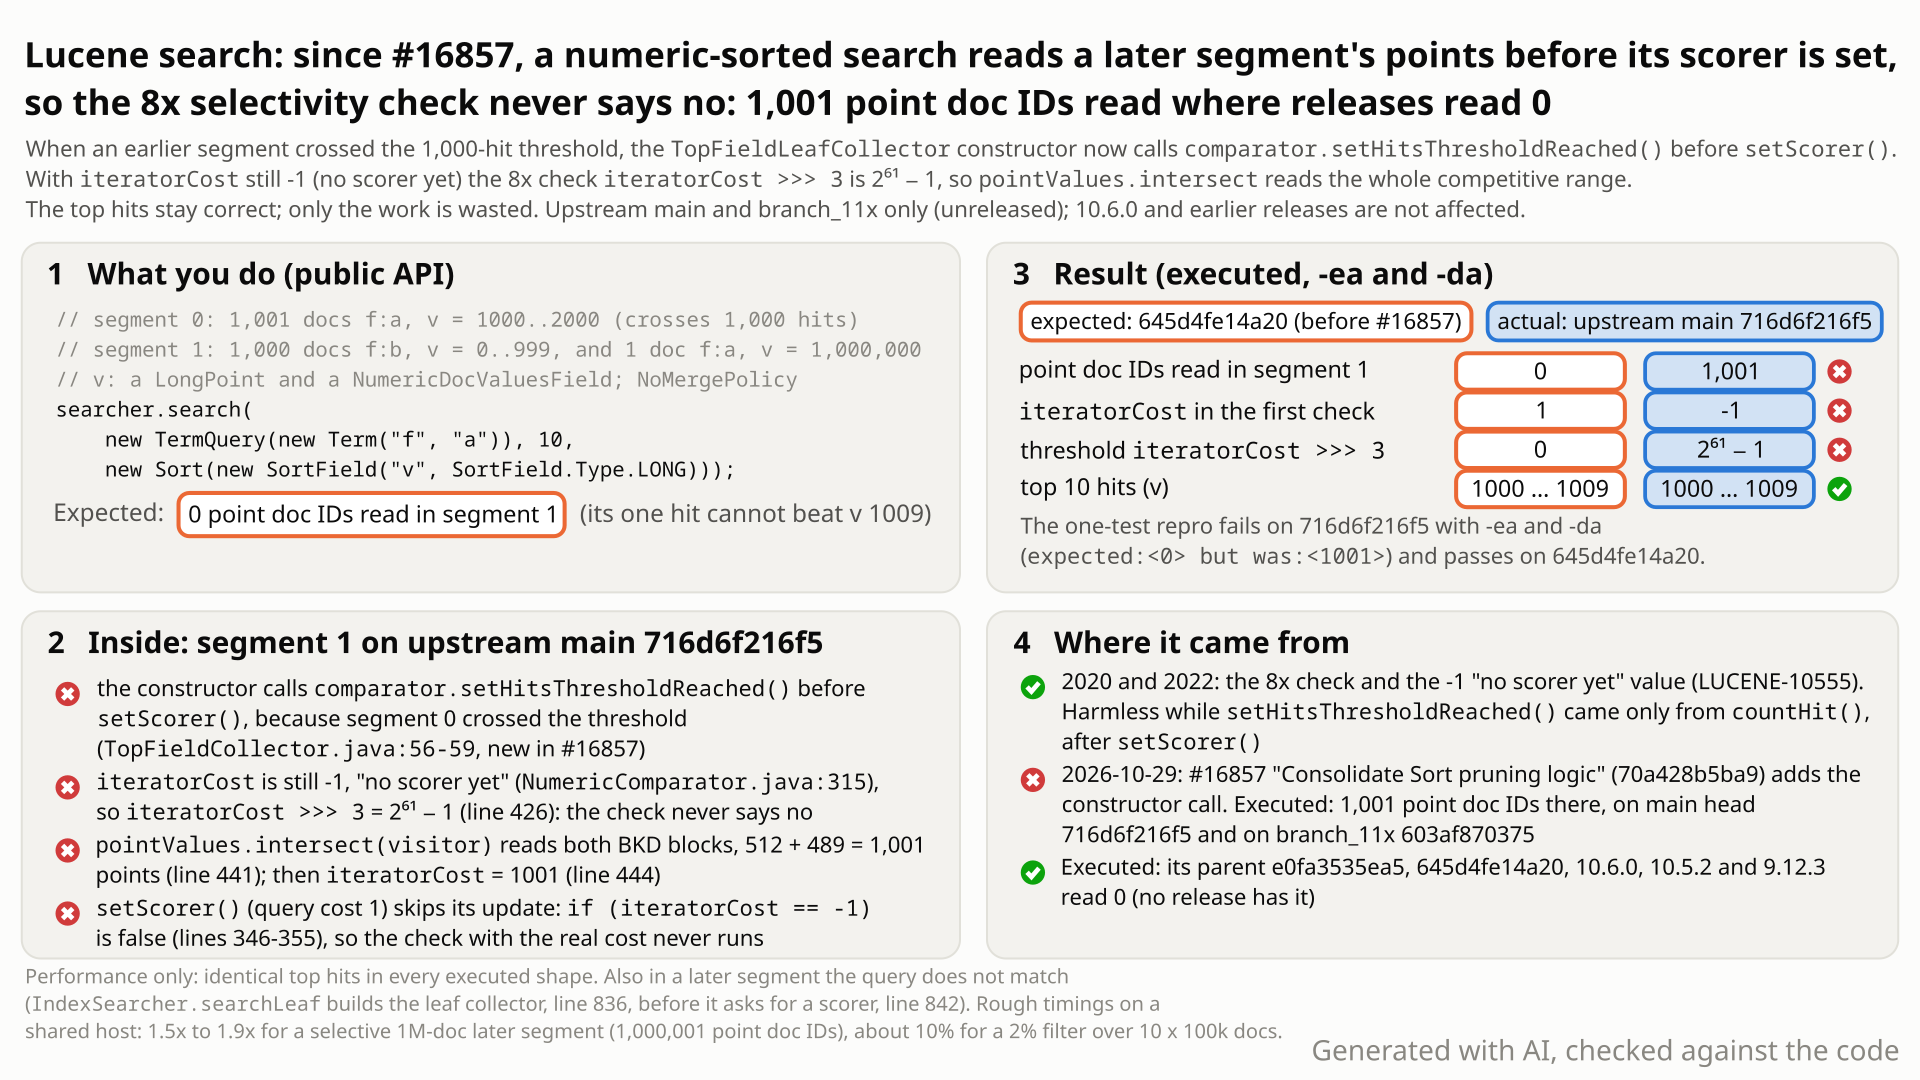
v: segment 0 crosses the 1,000-hit threshold; segment 1 then reads 1,001 point doc IDs before its scorer cost is known, where the 8x check would have read none. Select the still to open it at full size. Generated with AI, checked against the code.- Index two segments with a
LongPoint+NumericDocValuesFieldfieldv. Segment 0: 1,001 docs withf:a(v= 1,000 to 2,000). Segment 1: 1,000 docs withf:b(v= 0 to 999) and onef:adoc withv= 1,000,000. - Search
f:a, top 10, sorted byv. Segment 0 crosses the default threshold of 1,000 hits, so from now on Lucene may skip documents that cannot beat the 10th value,v= 1,009. - You expect segment 1 to read none of its points: the query matches 1 doc there, and the comparator reads points only when that cuts the documents to check at least 8x. 10.6.0, 10.5.2, 9.12.3 and main before #16857 read 0.
- Instead segment 1 reads all 1,001 of its points and builds a set of its 1,000
f:bdocs, which the query does not even match. The top 10 is still right; the work is wasted (1,000,001 doc IDs per search for a later segment of 1,000,001 docs). - Why: #16857 tells the comparator "threshold reached" when the segment's collector is created, before
setScorer(). The query's cost is still the placeholder -1, so the 8x limitcost >>> 3becomes 2^61 - 1 and never says no.
Users of main or branch_11x (the future 11.0.0) who sort by a numeric points field (a price, a timestamp) with search(query, n, sort) or searchAfter over several segments, default settings. Each later segment pays a points pass over its competitive range, wasted where the query is selective there. Results are correct; no release has it.
Mechanism, terms and numbers844 words
Since #16857 ("Consolidate Sort pruning logic", merged 2026-10-29, on main and branch_11x, in no release), TopFieldLeafCollector's constructor calls comparator.setHitsThresholdReached() when the hits threshold was already crossed in an earlier segment (TopFieldCollector.java:56-59 at 716d6f216f5). The constructor runs before setScorer(). For a numeric sort field indexed as points, that call runs the segment's first competitive-iterator update at once (NumericComparator.java:154-158), while the points builder's iteratorCost is still -1, its "no scorer yet" placeholder (:315). The 8x selectivity threshold iteratorCost >>> 3 (:426) becomes 2^61 - 1, so the "not selective enough to be worth materializing" check (:430-431) never rejects, and the segment intersects its points over the whole competitive range (:441). iteratorCost then holds the new iterator's cost estimate (1,001 here), so setScorer() skips the normal first update with the query's real cost (:346-355).
In the one-method repro, a later segment where the query matches 1 document hands all 1,001 of its points to the visitor; main before #16857, 10.6.0, 10.5.2 and 9.12.3 read 0. It also happens in a segment where the query matches nothing, because IndexSearcher.searchLeaf creates the leaf collector before it asks for a scorer. The top hits are identical in every executed shape. Rough timings on a shared host: 1.5-1.9x on a selective query with a 1M-doc later segment, about +10% for a 2% filter over 10 x 100,000 docs; a 3-line guard restores both.
- Hits threshold:
IndexSearcher#search(query, n, sort)counts hits exactly up toTOTAL_HITS_THRESHOLD= 1,000 (IndexSearcher.java:100). The 1,001st hit switches the collector'stotalHitsRelationtoGREATER_THAN_OR_EQUAL_TOand callscomparator.setHitsThresholdReached()fromcountHit()(TopFieldCollector.java:64-77). - Competitive iterator: once the threshold is reached and the queue is full,
NumericComparator'sPointsCompetitiveDISIBuilderintersects the field's points with the range of values that can still enter the top n and hands the collector a doc-ID iterator over the result (NumericComparator.java:363-446). - The 8x rule: before intersecting, it estimates the number of points in that range and gives up when the estimate is at least
iteratorCost >>> 3: "the new range is not selective enough to be worth materializing, it doesn't reduce number of docs at least 8x" (:426-439).iteratorCoststarts as the query's cost, taken insetScorer(): "starting iterator cost is the scorer's cost" (:346-355). - The placeholder:
private long iteratorCost = -1;(:315) means "not set from the scorer yet" (LUCENE-10555, #864, 2022).
It added to the TopFieldLeafCollector constructor (TopFieldCollector.java:56-59):
if (totalHitsRelation == TotalHits.Relation.GREATER_THAN_OR_EQUAL_TO) {
  // we only get told when the threshold is crossed, which may have been in a previous segment
  comparator.setHitsThresholdReached();
}
The constructor runs inside getLeafCollector, which IndexSearcher.searchLeaf calls before weight.scorerSupplier (IndexSearcher.java:836, :842), so it runs before setScorer() and even for a segment where the query has no scorer. NumericLeafComparator.setHitsThresholdReached() calls competitiveDISIBuilder.updateCompetitiveIterator() (NumericComparator.java:154-158). The flags it checks, hitsThresholdReached and queueFull, are shared by all segments of the collector (:59-60) and, in the repro, already true, so doUpdateCompetitiveIterator() runs with iteratorCost == -1: the threshold is (-1) >>> 3 = 2^61 - 1, the estimate can never reach it, pointValues.intersect reads the whole competitive range (:441), and iteratorCost becomes the new iterator's cost estimate (:444; 1,001 here). When setScorer() arrives, iteratorCost != -1, so the update with the real cost is skipped (:347).
The call itself is needed. #16857's new IndexSortedLeafFieldComparator keeps its own per-segment hitsThresholdReached flag (IndexSortedLeafFieldComparator.java:35, :91-97). And when the segment that crossed the threshold was index-sorted by the sort field and the search does not page, its comparator is that class (FieldValueHitQueue.java:190-191), which does not pass setHitsThresholdReached() on to its delegate (:91-97), while countHit() makes the call only once per collector (TopFieldCollector.java:70-72): the shared NumericComparator flag stays false, and the constructor call is what turns points skipping on in the next, unsorted segment. An independent check executed that shape: the second segment reads 512 point doc IDs on main, with either fix and on 645d4fe14a20, but 0 with the call deleted (no skipping: 5101+ hits counted instead of 1101+). So the defect is not the call but that, for the points builder, it runs the first update while the cost is still -1. When the earlier segment was not index-sorted, as in the repro, the flag is already set and that early update is the call's only effect on NumericComparator. Before #16857, setHitsThresholdReached() was called only from countHit(), during collect(), after setScorer() (645d4fe14a20 TopFieldCollector.java:87).
In the repro, segment 1's competitive range is v <= 1,008 (the 10th value is 1,009; with a single sort field ties are pruned too, FieldValueHitQueue.java:150). It holds the 1,000 f:b documents, so the intersect visits every one of segment 1's 1,001 points. With the real cost, 1 for f:a there, the threshold is 1 >>> 3 = 0 and nothing is read.
Exposure and likelihood444 words
- Who. Anyone on main or branch_11x code (so 11.0.0 unless fixed, and downstream projects that build on Lucene snapshots) who calls
IndexSearcher#search(query, n, sort)orsearchAftersorted on a numeric field indexed with points plus doc values, over an index with more than one segment. It needs the points builder: the field is the first sort field with pruning on (the default; later sort fields getPruning.NONE,FieldValueHitQueue.java:146-151) and has points (otherwise the doc-values-skipper builder is used),NumericComparator.java:98-111. - Default. Default codec,
IndexWriterConfigandIndexSearcher, the default 1,000-hit threshold, assertions on or off. It starts in the later segments (with points for the field) that a collector reaches after an earlier segment crossed the threshold. Without an executor one collector sees every segment (IndexSearcher.java:226-231); with one, each slice has its own collector and hit count (IndexSearcher.java:767-777,TopDocsCollector.java:50-53), so the threshold must have been crossed earlier in the same slice. - Cost. One points pass over the segment's competitive range plus one doc-ID set, in cases where the 8x rule would have said no. It is bounded by the segment's points in that range. Measured point doc IDs read in later segments, before #16857 vs after:
| shape | before vs after |
|---|---|
| the repro: 1,001 points, query matches 1 | 0 vs 1,001 |
| a later segment where the query matches nothing | 0 vs 10,000 |
| a later segment of 1,000,000 non-matching docs plus 1 non-competitive match, page 1 | 0 vs 1,000,001 per search, plus about 141 KB more allocated (mostly a 1M-bit doc-ID set) |
the same, page 2 via searchAfter | 0 vs 65 |
| newest-first time series, 4 x 100,000 docs, rare term | 0 vs 111,424 per later segment |
the same, common term (98% of docs) / MatchAllDocsQuery | 8,352 vs 108,352 / 10,400 vs 110,400 |
- Rough wall-clock (shared aarch64 host, JDK 25, medians of 5 rounds; indicative only): a selective query with that 1,000,001-doc later segment, 40-80 us per search before vs 73-125 us after (1.5x to 1.9x over 5 paired runs); a 2% filter over 10 x 100,000 random prices sorted by price, 435-443 us vs 483-485 us (about +10%). In these runs the 3-line fix restored both (40.6 us; 432-438 us). A newest-first time-series shape was inconclusive.
- Not claimed. Wrong results: the top hits were identical in every executed shape. The
TotalHitslower bound can change (for example2005+instead of19774+), because the early iterator prunes more; theGREATER_THAN_OR_EQUAL_TOcontract allows that. String sorts and the doc-values-skipper builder may also get an extra update per segment from the same call; its cost was not measured. - Workaround. None worth recommending:
SortField.withoutPruningavoids the read but turns off all points-based skipping.
One JUnit 4 test method on the public API: two segments in a ByteBuffersDirectory, NoMergePolicy, a sorted search(query, 10, sort), and a FilterLeafReader around segment 1 that counts the point doc IDs handed to the visitor. No randomness, single thread; it fails with assertions on and off.
package org.apache.lucene.search;

import static org.junit.Assert.assertEquals;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.LongPoint;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.FilterLeafReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LeafReader;
import org.apache.lucene.index.MultiReader;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.index.PointValues;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.junit.Test;

public class TestSortLaterSegmentPointsWork {

  @Test
  public void testSelectiveLaterSegmentReadsNoPoints() throws IOException {
    Directory dir = new ByteBuffersDirectory();
    IndexWriterConfig iwc = new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE);
    try (IndexWriter w = new IndexWriter(dir, iwc)) {
      for (int i = 0; i <= 1000; i++) {
        addDoc(w, "a", 1000 + i);
      }
      w.flush();
      for (int i = 0; i < 1000; i++) {
        addDoc(w, "b", i);
      }
      addDoc(w, "a", 1_000_000);
    }
    try (DirectoryReader reader = DirectoryReader.open(dir)) {
      long[] pointDocsRead = new long[1];
      LeafReader second = new CountingLeafReader(reader.leaves().get(1).reader(), pointDocsRead);
      IndexSearcher searcher =
          new IndexSearcher(new MultiReader(reader.leaves().get(0).reader(), second));
      searcher.search(
          new TermQuery(new Term("f", "a")), 10, new Sort(new SortField("v", SortField.Type.LONG)));
      // Expected 0 (segment 1 has 1 hit, so its points are not worth reading); main since #16857: 1001.
      assertEquals(0, pointDocsRead[0]);
    }
  }

  private static void addDoc(IndexWriter w, String f, long v) throws IOException {
    Document doc = new Document();
    doc.add(new StringField("f", f, Field.Store.NO));
    doc.add(new LongPoint("v", v));
    doc.add(new NumericDocValuesField("v", v));
    w.addDocument(doc);
  }

  private static final class CountingLeafReader extends FilterLeafReader {
    private final long[] count;

    CountingLeafReader(LeafReader in, long[] count) {
      super(in);
      this.count = count;
    }

    @Override
    public PointValues getPointValues(String field) {
      PointValues values = in.getPointValues(field);
      return values == null ? null : new CountingPointValues(values, count);
    }

    @Override
    public CacheHelper getCoreCacheHelper() {
      return null;
    }

    @Override
    public CacheHelper getReaderCacheHelper() {
      return null;
    }
  }

  private static final class CountingPointValues extends PointValues {
    private final PointValues in;
    private final long[] count;

    CountingPointValues(PointValues in, long[] count) {
      this.in = in;
      this.count = count;
    }

    @Override
    public PointTree getPointTree() throws IOException {
      return new CountingPointTree(in.getPointTree(), count);
    }

    @Override
    public byte[] getMinPackedValue() {
      return in.getMinPackedValue();
    }

    @Override
    public byte[] getMaxPackedValue() {
      return in.getMaxPackedValue();
    }

    @Override
    public int getNumDimensions() {
      return in.getNumDimensions();
    }

    @Override
    public int getNumIndexDimensions() {
      return in.getNumIndexDimensions();
    }

    @Override
    public int getBytesPerDimension() {
      return in.getBytesPerDimension();
    }

    @Override
    public long size() {
      return in.size();
    }

    @Override
    public int getDocCount() {
      return in.getDocCount();
    }
  }

  private record CountingPointTree(PointValues.PointTree in, long[] count)
      implements PointValues.PointTree {
    @Override
    public PointValues.PointTree clone() {
      return new CountingPointTree(in.clone(), count);
    }

    @Override
    public boolean moveToChild() throws IOException {
      return in.moveToChild();
    }

    @Override
    public boolean moveToSibling() throws IOException {
      return in.moveToSibling();
    }

    @Override
    public boolean moveToParent() throws IOException {
      return in.moveToParent();
    }

    @Override
    public byte[] getMinPackedValue() {
      return in.getMinPackedValue();
    }

    @Override
    public byte[] getMaxPackedValue() {
      return in.getMaxPackedValue();
    }

    @Override
    public long size() {
      return in.size();
    }

    @Override
    public void visitDocIDs(PointValues.IntersectVisitor visitor) throws IOException {
      count[0] += in.size();
      in.visitDocIDs(visitor);
    }

    @Override
    public void visitDocValues(PointValues.IntersectVisitor visitor) throws IOException {
      count[0] += in.size();
      in.visitDocValues(visitor);
    }
  }
}
cp $REPRO/TestSortLaterSegmentPointsWork.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestSortLaterSegmentPointsWork -Ptests.seed=DEADBEEF
# also with -Ptests.asserts=false (same failure); with this seed gradle's default is assertions on
- Expected
- 0 point doc IDs read in segment 1, where the query matches 1 document, as on 10.6.0, 10.5.2, 9.12.3 and main before #16857.
- Observed
AssertionError: expected:<0> but was:<1001>on main716d6f216f5, with assertions on and off; the search result itself is unchanged.
More files, environment, full output366 words
TestSortLaterSegmentPointsWork (one method). It does not extend LuceneTestCase: it fixes the IndexWriterConfig (default codec, NoMergePolicy) and uses ByteBuffersDirectory, and it runs as is under gradle. The counting wrapper adds the size of every points cell whose doc IDs are handed to the visitor (visitDocIDs / visitDocValues); estimates that only walk the tree are not counted. It is a work count: a cell handed to visitDocValues can hold values the visitor then rejects (here the v = 1,000,000 point).
The file uses the main signatures (on main LeafReader#getPointValues and the PointValues getters no longer declare IOException). For 10.6.0, 10.5.2 and 9.12.3 it needs throws IOException on six overrides; the independent fact check ran exactly that port on the releases, and this test on the commit bracket. The hunt's own release and bracket runs used an earlier test of the same shape, TestSortLeafStartPointsWork (a FilterDirectoryReader counter, other field names, a top-10 assertion), with the same outcomes.
As a regression test the same method can go into an existing sort test class (for example TestSortOptimization) or stay its own class.
| lucene | main 716d6f216f5 (12.0.0-SNAPSHOT) and branch_11x 603af870375: fail; main before #16857 (e0fa3535ea5, 645d4fe14a20), 10.6.0, 10.5.2, 9.12.3: pass |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestSortLaterSegmentPointsWork.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestSortLaterSegmentPointsWork -Ptests.seed=DEADBEEF
# gradle, worktree at main 716d6f216f5, -Ptests.seed=DEADBEEF (-Ptests.asserts=true and false)
TestSortLaterSegmentPointsWork > testSelectiveLaterSegmentReadsNoPoints FAILED
    java.lang.AssertionError: expected:<0> but was:<1001>
        at org.apache.lucene.search.TestSortLaterSegmentPointsWork.testSelectiveLaterSegmentReadsNoPoints(TestSortLaterSegmentPointsWork.java:48)
1 test completed, 1 failed

# the same worktree with fix A (assertions on)
TestSortLaterSegmentPointsWork: 1 test, 0 failures; with 11 sort and comparator suites: 12 classes, 112 tests, 0 failures (BUILD SUCCESSFUL)

# standalone JUnit runner, seed DEADBEEF, this test
main 716d6f216f5 code (13 changed search files over 645d4fe jars), -ea / -da   1 run, 1 failure   expected:<0> but was:<1001>
full lucene/core source tree at 716d6f216f5 (javac build), -ea / -da         1 run, 1 failure   expected:<0> but was:<1001>
13 changed search files + fix A, -ea / -da                                    1 run, 0 failures
13 changed search files + fix B, -ea / -da                                    1 run, 0 failures
main 645d4fe14a20 (predates #16857), -ea / -da 1 run, 0 failures- The comparator reads points only when that cuts the documents to check 8x versus the query's cost; otherwise the range is "not selective enough".
- -1 is the "no scorer cost yet" placeholder;
(-1) >>> 3= 2^61 - 1 disables the rule by accident. - The call serves #16857's index-sort comparator; that PR calls needless iterators from points "redundant work".
The full argument354 words
- The rule.
NumericComparator.java:430-431(main716d6f216f5): "the new range is not selective enough to be worth materializing, it doesn't reduce number of docs at least 8x", withthreshold = iteratorCost >>> 3(:426) and the starting cost set insetScorer(): "starting iterator cost is the scorer's cost" (:349). It is an implementation heuristic in a source comment, not a public contract; the report is the measured regression against it. - The placeholder. LUCENE-10555 (#11591 "avoid repeated NumericLeafComparator setScorer calls", PRs #864 and #878, 2022) introduced
iteratorCost == -1to mean "not set from the scorer yet". It was never meant to reach the threshold computation. - The order is new. On
645d4fe14a20the production callers ofsetHitsThresholdReached()areTopFieldCollector.countHit()(:87) and theMultiLeafFieldComparatordelegation, both aftersetScorer(). The only other caller, the unit testTestTermOrdValComparatorAdaptiveSkipping(:145,:192), calls it on a string-sort leaf comparator that never gets a scorer; it does not reach the numeric points builder. #15757 (2026-02) describes the first per-segment update as running from the builder'ssetScorer(), "by analogy with the points-based version". - Purpose of the call. Its comment, "we only get told when the threshold is crossed, which may have been in a previous segment", fits
IndexSortedLeafFieldComparator's per-segment flag (IndexSortedLeafFieldComparator.java:35,:91-97) and, after an index-sorted segment, the sharedNumericComparatorflag; neither needs the points update before the scorer cost is known. That class's comment (:31-33) says that when collection terminates anyway, "the delegate's skipping, e.g. building iterators from points, is redundant work: it measurably slows down index-sorted searches." - The PR record. #16857's body, its CHANGES entry ("Sort pruning decisions are now entirely made through the Pruning enum", 11.0.0 API Changes,
CHANGES.txt:39-47),MIGRATE.mdand all 4 reviews and 4 inline comments say nothing about reading points before the scorer is known. Its one benchmark comment ("no significant difference") ran non-selective tasks. - Precedent. #13498, "Avoid performance regression by constructing lazily the PointTree in NumericComparator", is listed under Bug Fixes in 9.11.1 and 10.0.0: avoidable points work in this very comparator was treated as a bug.
The devil's-advocate check211 words
The strongest case for "intended" (built by an intended-behaviour checker and by a reviewer from another model family): no public contract covers this cost. LeafFieldComparator#setHitsThresholdReached says only that it "is called from a collector when hits threshold is reached" (LeafFieldComparator.java:109-113) and orders nothing against setScorer; these APIs are @lucene.experimental; the constructor call is deliberate and commented; and an eagerly built iterator prunes more hits, so it could in principle be faster.
Why it fails: no public contract covers this cost, and an eager iterator can prune more (2005+ instead of 19774+ hits counted in one timed shape). But the call is deliberate for the threshold flag, and no PR record we found discusses whether it should run the points update before a scorer cost is known; fix A keeps the call and drops only that update. The value that reaches the rule is the placeholder, not an estimate. In a segment where the query matches 0 or 1 documents nothing can be gained by building an iterator over 1,000 or 1,000,000 competitive documents. The measured wall-clock is worse with the early read (1.5x to 1.9x, about +10%), and in those runs the 3-line guard restored the old numbers. Being unreleased lowers the priority, not the verdict.
Recommended A: skip the points update until the scorer cost is known
Return early from the points builder's update while its cost is still -1: if (iteratorCost == -1) return; at the top of PointsCompetitiveDISIBuilder.doUpdateCompetitiveIterator() (3 lines). setScorer() then makes the first decision with the query's real cost, as before #16857. With it the test and 11 sort and comparator suites pass (12 classes, 112 tests).
    @Override
    protected void doUpdateCompetitiveIterator() throws IOException {
      if (iteratorCost == -1) {
        return; // no scorer cost yet: setScorer() performs the first update
      }
All options and trade-offs2 options · 604 words
Two fixes were built and checked; fix A was also validated with gradle in a worktree at 716d6f216f5 (JDK 25, -Ptests.seed=DEADBEEF). Open, stale PR #16163 changes the same updateCompetitiveIterator guard family (for leafTopSet); it does not touch the placeholder, the points builder or the constructor call, but a fix should not conflict with it. Choosing between them is the maintainers' call: A is the smaller, local change; B restores the "scorer first" order for every comparator.
comparators/NumericComparator.java, top of PointsCompetitiveDISIBuilder.doUpdateCompetitiveIterator() (:363), +3 lines:
    @Override
    protected void doUpdateCompetitiveIterator() throws IOException {
      if (iteratorCost == -1) {
        return; // no scorer cost yet: setScorer() performs the first update
      }
Trade-offs
setScorer()performs the segment's first update with the real cost (:346-355), as before #16857, whileIndexSortedLeafFieldComparatorstill learns about the threshold from the constructor. A segment with no scorer does no points work.- It keeps the constructor call's purposes:
setHitsThresholdReached()sets the flag before the update returns (:155), so after an index-sorted segment the next segment still skips (512 point doc IDs read, as on main and645d4fe14a20). - Local to the points builder; the collector protocol is unchanged. The skipped call still increments
updateCounter(:235) before it returns, so in each later segment the count runs one ahead of the pre-#16857 code and the sampling that starts after 256 updates (:237-240,:456) shifts by one update. Not measured; for the maintainers to judge.
What the checks validated
- Gradle, worktree at
716d6f216f5, assertions on (the seed's default), repeated by the independent fact check: the minimal test fails without the fix (assertions on and off) and passes with it; together withTestSort(30),TestSortOptimization(31),TestTopFieldCollector(13),TestTopFieldCollectorEarlyTermination(10),TestSortedNumericSortField(9),TestNonPruningSortField(4),TestSearchAfter(1),TestSortRandom(1) and thecomparatorspackage (TestNumericComparator3,TestTermOrdValComparatorAdaptiveSkipping5,TestUpdateableDocIdSetIterator4): 12 classes, 112 tests, 0 failures. - Standalone runner: the test passes with
-eaand-daover the 13 changed search files. The one standalone full-core run with fix A used the hunt's earlier test (-da) and passed. - Every reach shape returns to the pre-#16857 counts; the hunt's two probes written to check #16857, a brute-force probe of its pruning decisions (28,512 + 874,368 checks) and an index-sorted exhaustive probe (928,320 searches), stay clean; a reviewer from another model family ran
TestSortOptimization(31 tests),TestTopFieldCollectorEarlyTermination(10) andTestNumericComparator(3) with it, 0 failures; in the TLA+ model the properties NoBlindUpdate, FirstUpdateNotLost and LeafKnowsThreshold hold.
In TopFieldLeafCollector, delete TopFieldCollector.java:56-59 and add the same if (totalHitsRelation == TotalHits.Relation.GREATER_THAN_OR_EQUAL_TO) comparator.setHitsThresholdReached(); right after comparator.setScorer(scorer) (:117).
Trade-offs
- Restores the "scorer first" order for every comparator and still tells the leaf comparator before its first
collect. setScorer()can run more than once per segment: a bulk scorer calls it on everyscore()call (Weight.java:254), for example once per interval under a query timeout (TimeLimitingBulkScorer), so the call repeats. A segment with no scorer never hears about the threshold, which is harmless because it collects nothing.
What the checks validated
The test passes with -ea and -da over the 13 changed search files; every reach shape returns to the pre-#16857 counts (the 1,000,001-doc page-1 and page-2 shapes, 0 and 0, run by the independent fact check); the hunt's two #16857 probes stay clean; the cross-model reviewer's suite runs (TestSortOptimization, TestTopFieldCollectorEarlyTermination, TestNumericComparator) pass; the TLA+ properties hold. B has no gradle run.
Downstream services that build on Lucene snapshots and sort by numeric fields pay this extra CPU on selective sorted queries until it is fixed; the hits are unaffected.
Reading the newly merged #16857 diff for changed call orders, the constructor-time setHitsThresholdReached() call stood out. A probe that counts the points a sorted search reads, run before and after #16857, showed 0 vs 80,000 doc IDs with the same top 10. It was reduced to one test, and the per-segment protocol was modelled in TLA+.
The method in full170 words
Method: non-formal (the first signal came from code reading; the formal model came later).
- Lead. A lens on newly merged upstream code read the #16857 diff and flagged the constructor call that runs before
setScorer(). - Probe. A differential count with a
PointTreewrapper on the publicFilterLeafReaderAPI, on the code before #16857 and on upstream main: 0 vs 80,000 point doc IDs read in later segments (5 x 20,000 docs, threshold 10), identical top 10. A skeptic re-run confirmed it. - Reduction. The hunt reduced it to one JUnit test (later the one-method test above) and ran it on main code, the commit bracket and three releases, with assertions on and off.
- Model. A TLA+ model of the per-segment collector and comparator protocol (TLC): the property NoBlindUpdate (no points are read before the scorer cost is known) is violated by upstream main, the shortest trace being a second segment with no scorer; it holds for the code before #16857 and for both fixes, and the vacuity probes are reachable.
No prior report found (2026-10-30: three search-tool runs, GitHub issues and PRs including the files of all 409 open PRs and every #16857 comment, the mailing lists, the JIRA archive, Elasticsearch, OpenSearch and Solr; refreshed). #16857 introduced it.
Searches5 searches
Related, not reports of this bug: #16857 (introduced it; its discussion is about hasBlocks plus one non-selective benchmark); #16947 (document blocks, FieldValueHitQueue only); #11591, #864 and #878 (origin of the -1 placeholder); #15757 (setScorer-first design of the skipper builder); #16163 (open, stale, the same guard family); OpenSearch #17404 and Elasticsearch #150714 (both discuss iteratorCost >>> 3 in other situations, before #16857). Tracking issue #16937 does not mention it. Limits: keyword search only; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| Search tool (GitHub issues/PRs, commits, Elasticsearch, OpenSearch and Solr trackers, dev@, java-user@, issues@, commits@, JIRA archive, web) | 2026-10-30 (finder's run 00:10, follow-up runs 01:18-01:26, refresh 01:30-01:36) | three runs: identifiers (iteratorCost, setHitsThresholdReached, TopFieldLeafCollector, PointsCompetitiveDISIBuilder), symptoms, and trigger phrasing ("not selective enough", "threshold is crossed"); 51, 51 and 45 queries | 97, 476 and 286 distinct hits, none a report |
| GitHub apache/lucene (manual) | 2026-10-30 | iteratorCost, setHitsThresholdReached, TopFieldLeafCollector, PointsCompetitiveDISIBuilder, IndexSortedLeafFieldComparator, "16857"; sort items updated since 2026-10-28; all items created since 2026-10-29 | no report; only unrelated items |
| Open apache/lucene PRs | 2026-10-30 | the changed files of all 409 open PRs; the diffs of #16947, #16163 and #14395 read | none changes the constructor call, the -1 placeholder or the points builder's update |
| The introducing PR #16857 | 2026-10-30 | every comment, review and inline comment, and its mailing-list mirror thread | reviews about hasBlocks; one benchmark, "no significant difference"; nothing about point reads before the scorer |
| GitHub apache/lucene, refresh | 2026-10-30 | main head and the history of TopFieldCollector.java and NumericComparator.java on main and branch_11x; items created since midnight UTC and updated since a recent cutoff | main still at 716d6f216f5, no change to either file since #16857; only #16952 is new, about bulk-scoring bounds, unrelated |
Introduced by #16857 (70a428b5ba9, merged 2026-10-29) and its branch_11x backport 203699279f5. Bracketed: the parent e0fa3535ea5 passes, 70a428b5ba9 fails. No release has it: 10.6.0, 10.5.2 and 9.12.3 pass, and a control shows the counter registers reads there.
Versions tested5 rows
Introduced by 70a428b5ba9, apache/lucene#16857 "Consolidate Sort pruning logic" (romseygeek, Alan Woodward), opened 2026-10-16 and squash-merged to main on 2026-10-29; backported to branch_11x as 203699279f5 the same day. The constructor call is already in the PR's first commit 466a0384cb8. CHANGES lists it under Lucene 11.0.0 (API Changes).
The older ingredients were harmless alone, because setHitsThresholdReached() ran only from countHit(), after setScorer(): the iteratorCost >>> 3 check with its 8x comment (b0333ab5c8d, LUCENE-9280, #1351, 2020-06-23, then in FilteringNumericLeafComparator); the hook setHitsThresholdReached -> updateCompetitiveIterator, added by 99220677fe4 (LUCENE-9449, #1725, 2020-09-08), which also moved the check into comparators/NumericComparator.java; and the -1 placeholder (f431511cb71, LUCENE-10555 / #864, 2022).
| Version or commit | Verdict | Result |
|---|---|---|
main 716d6f216f5 (head, 12.0.0-SNAPSHOT) | affected | fails: gradle in a worktree at that commit and the standalone runner, assertions on and off, expected:<0> but was:<1001> |
branch_11x 603af870375 (head) | affected | fails (-ea, -da); both files are identical to main |
70a428b5ba9 (#16857) vs its parent e0fa3535ea5 | bisect | #16857 fails (-ea, -da); the parent passes (-ea, -da) |
main 645d4fe14a20 (2026-10-28) | not affected | passes (-ea, -da; predates #16857) |
10.6.0 (4ae946e5a9b), 10.5.2, 9.12.3 | not affected | pass (-ea, -da); a control counts 512 point doc IDs on 10.6.0 and 9.12.3 when the 8x rule allows a read |
An independent reproducer, reviewers from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication each ran their own or the finder's tests on main code. All agree on the root cause and the fixes; one reviewer's formal "not real" came from a checkout older than #16857, and its own test fails on main.
Checks and verdicts447 words
The main-line evidence first came from the 13 search files #16857 changed, compiled over the 645d4fe14a20 jars, and from a javac build of the full lucene/core tree at 716d6f216f5. This doc adds gradle runs in a worktree at 716d6f216f5, which closes the remaining caveat that no real main checkout had been run.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Its test (the earlier TestSortLeafStartPointsWork) fails on main code (-ea, -da) and passes before #16857, with fix A, with fix B, on 10.6.0 and 10.5.2; the TLA+ property NoBlindUpdate is violated by main and holds for the old code and both fixes. |
| Independent reproducer | real | Own test fails on main code (1,000 vs 0) and passes on 645d4fe, 10.6.0, 10.5.2 and 9.12.3; a stack probe puts the first read in the collector's constructor, before setScorer; each of two one-line probes fixes it. |
| cross-model review, refute lens | formally not real, in substance real | OpenAI GPT-5.6. It used a checkout older than #16857, where nothing fails. On the main code its own trigger test fails with 9 point visits (a later segment with 8 non-matches and one cost-1 match), and a second test, whose later segment has no match and so no scorer, fails with 8. Agrees on the root cause and both fixes; ran the sort suites with each fix. |
| Cross-model review, intended lens | real, high | OpenAI GPT-5.6. Its own test with a later segment that has no scorer fails on main code and passes with A and with B; the intended case is moderate and rejected. |
| Intended-behaviour devil | real | Built the strongest case for intended and rejected it; measured the rough wall-clock cost and that fix A restores it. |
| adjudication | confirmed, high | Re-ran the finder's test: main code fails (-ea, -da), the old code passes, fix A passes. No-noise gate passed at Low. |
| Registration check, audit and this doc | keep | A javac build of the full core tree at 716d6f216f5 fails (-ea, -da) and, with fix A, passes (-da; the hunt's earlier test); this doc's gradle run in a worktree at 716d6f216f5 fails with assertions on and off and passes with fix A. |
| independent fact checks of this doc | real as described; wording corrected | A checker re-ran the gradle command and fix A in its own worktree, ran this test on the commit bracket and the three releases (-ea, -da), fix B on the 1,000,001-doc shapes and an index-sorted-then-unsorted shape; a reviewer from another model family (OpenAI GPT-5.6) reviewed the text read-only. Their corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 643 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,678 words
- Registry title
- Since #16857 (upstream main and branch_11x, unreleased), a numeric field-sorted search reads a later segment's whole competitive points range before the scorer is set: TopFieldLeafCollector's constructor calls setHitsThresholdReached() while NumericComparator's iteratorCost is still its -1 'no scorer yet' value, so the 8x selectivity check never rejects (1,001 point doc IDs read where releases read 0; performance regression, results correct)
- Area
- search / field sorting: TopFieldCollector + NumericComparator points-based sort pruning (competitive iterator)
- Priority
- Low, rank 363: A performance-only regression with correct results on the default numeric-sorted search path, but only in unreleased main/branch_11x code and with measured slowdowns of about 10% to 1.9x, so it is Low.
- Impact class
- minor
- Impact note
- Performance regression only, on upstream main and branch_11x since #16857 (no release has it; fixable before 11.0.0), with the default codec, IndexWriterConfig and IndexSearcher: every IndexSearcher#search(query, n, sort) (also searchAfter) sorted on a numeric field indexed with points, over a multi-segment index, runs one points intersect over the competitive range of each segment that starts after the default 1,000-hit threshold was crossed, even where the query matches few or no documents and the 8x rule would have skipped it; the waste per segment is bounded by that segment's points in the range (1,001 doc IDs in the repro, 1,000,001 plus a 1M-bit set for a 1M-doc segment), rough timings on a shared host showed about 1.9x on a selective 1M-doc later segment and about 10% on a 2%-filter 10 x 100k shape (both restored by the one-line fix), and the top hits are identical in every executed shape.
- Summary
- You run searcher.search(new TermQuery(new Term("brand", "lux")), 10, new Sort(new SortField("price", SortField.Type.LONG))) over two segments: the first has 1,001 hits, so the default 1,000-hit threshold is crossed there, and in the second the query matches one document that cannot compete. You expect the second segment not to read its points, because the comparator builds its competitive iterator from points only when that cuts the query's own cost at least 8x; 645d4fe, 10.6.0, 10.5.2 and 9.12.3 read 0 point doc IDs there. Instead, since #16857 the new leaf collector tells the comparator about the threshold before setScorer(), while its cost is still the -1 'no scorer yet' value (so the 8x limit becomes 2^61-1), and it intersects the whole competitive range, 1,001 doc IDs; the top 10 is still right, only the work is wasted.
- Introduced
- 70a428b5ba90cdbcf3c8380e21b006a68b4dcb85 (apache/lucene#16857 'Consolidate Sort pruning logic', author romseygeek (Alan Woodward), squash-merged to main 2026-10-29; branch_11x backport 203699279f5 the same day; the constructor call is already in the PR's first commit 466a0384cb8 of 2026-10-16) [exec: commit-level bracket with the shipped repro, each commit's core sources compiled over the 645d4fe jars: parent e0fa3535ea5 passes with -ea and -da, 70a428b5ba9 fails with -ea and -da, 'expected:<0> but was:<1001>'; read: git log -S finds the constructor's comment 'we only get told when the threshold is crossed' only in 70a428b5ba9]. The other ingredients were harmless before, because setHitsThresholdReached() was only called from countHit(), after setScorer(): the leaf hook setHitsThresholdReached -> updateCompetitiveIterator and the 'iteratorCost >>> 3' check (99220677fe4, LUCENE-9449 era, 2020) and the iteratorCost == -1 sentinel (f431511cb71, LUCENE-10555 / #864, 2022). (2026-10-29 (author date of 70a428b5ba9, 2026-10-29, equal to the merge time; the branch_11x backport 203699279f5 has the same author date; the code was first written on the PR branch on 2026-10-16))
- First affected version
- unreleased (11.0.0 would be the first release; #16857's CHANGES entry is under Lucene 11.0.0); 10.6.0, released 2026-10-29 from 4ae946e5a9b, and every earlier release are not affected; the last unaffected main commit is e0fa3535ea5
- Affected versions
- [exec] upstream main at the introducing commit 70a428b5ba9 (-ea and -da) and at the head 716d6f216f5 (-ea and -da, both through the 13-file shadow over the 645d4fe jars and, at the registration check on 2026-10-30, through a javac build of the full lucene/core source tree at 716d6f216f5: 'expected:<0> but was:<1001>'), branch_11x head 603af870375 (-da); every run of the finder, the independent reproduction, the intended-behaviour check, the GPT reviewers and the adjudication on the upstream-main code fails. Not affected [exec]: main parent e0fa3535ea5 (-ea, -da), main 645d4fe14a20 (-ea, -da; it predates #16857), 10.6.0 = 4ae946e5a9b (-ea, -da), 10.5.2 (-ea, -da) and 9.12.3 (-ea, -da), all with the 10.x-signature port on releases; a non-vacuity control counts 512 point doc IDs on 10.6.0 and 9.12.3, so the 0 there is a real measurement. [read] branch_10_6 has no constructor call (setHitsThresholdReached only in countHit); TopFieldCollector.java and NumericComparator.java are byte-identical on main and branch_11x, and #16857 is the last commit on both files on both branches (checked 2026-10-30). [exec 2026-11-02] upstream main e1faeba08bd, a native 12.0.0-SNAPSHOT build with no shadow, fails with -ea and -da ('expected:<0> but was:<1001>'); [read 2026-11-02] branch_11x da3ea39fa59 has both files identical to main.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by TLA+/TLC
- Upstream and prior reports
- none found (2026-10-30, read-only; the prior-report record verdict new): three scripted prior-report searches on identifiers, symptoms and trigger phrasing (51, 51 and 45 queries over GitHub issues/PRs, commits, Elasticsearch/OpenSearch/Solr trackers, dev@/java-user@/issues@/commits@ and the JIRA archive; 97, 476 and 286 distinct hits, none a report); manual gh searches for iteratorCost, setHitsThresholdReached, TopFieldLeafCollector, PointsCompetitiveDISIBuilder, IndexSortedLeafFieldComparator, NumericComparator and sort items updated since 2026-10-28, and all items created since 2026-10-29 (only #16951, unrelated); the changed files of all 409 open apache/lucene PRs and, at the registration check, of the 30 open PRs updated since 2026-10-28 (only #16947, which changes FieldValueHitQueue (hasBlocks) and a test; #16163, #14395 and others touching these files do not change the constructor call, the -1 sentinel or PointsCompetitiveDISIBuilder.doUpdateCompetitiveIterator); every comment of #16857 (1 issue comment with a non-selective benchmark, 'no significant difference'; 4 reviews and 4 inline comments, all about hasBlocks); tracking issue #16937 (no mention). Upstream main head is still 716d6f216f5 and branch_11x head 603af870375; the last commit on TopFieldCollector.java and NumericComparator.java is #16857 on both branches (author date 2026-10-29), so no fix exists by author date or by PR date.
- Lucene commit tested
- this one-method test on upstream main
716d6f216f5(gradle in a worktree at that commit with-Ptests.asserts=trueandfalse, then with fix A together with the sort suites; the standalone JUnit runner over the 13 search files #16857 changed, compiled over the645d4fe14a20jars, and over a javac build of the fulllucene/coresource tree,-eaand-da), the commit brackete0fa3535ea5(parent, passes) and70a428b5ba9(#16857, fails),branch_11x603af870375(fails), main645d4fe14a20(predates #16857, passes) and the 10.6.0, 10.5.2 and 9.12.3 release jars (pass, with a control that the counter registers reads there), all with-eaand-da. The bracket and release runs of this test come from the independent fact check; the hunt ran them with an earlier test of the same shape, with the same outcomes.
- Finding record
a Lucene clone@716d6f216f5 (git show, read-only) lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:50-62 (TopFieldLeafCollector constructor; :56-59 'if (totalHitsRelation == TotalHits.Relation.GREATER_THAN_OR_EQUAL_TO) { // we only get told when the threshold is crossed, which may have been in a previous segment comparator.setHitsThresholdReached(); }', added by #16857), :115-123 (setScorer, which runs after the constructor)a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:154-158 (NumericLeafComparator.setHitsThresholdReached -> competitiveDISIBuilder.updateCompetitiveIterator()), :315 ('private long iteratorCost = -1;'), :346-355 (setScorer: 'if (iteratorCost == -1) { ... iteratorCost = s.iterator().cost(); // starting iterator cost is the scorer's cost ... updateCompetitiveIterator(); // update an iterator when we have a new segment }'), :426-444 ('final long threshold = iteratorCost >>> 3;', 'the new range is not selective enough to be worth materializing, it doesn't reduce number of docs at least 8x', pointValues.intersect(visitor), iteratorCost = newIterator.cost())lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:836-843 (at 645d4fe14a20) (searchLeaf calls collector.getLeafCollector before weight.scorerSupplier, so the constructor runs even for a segment where the query matches nothing)https://github.com/apache/lucene/pull/16857 (introducing PR: description 'consolidates these decisions into segment-level logic', benchmark comment 'no significant difference', reviews about hasBlocks only)https://github.com/apache/lucene/pull/864 and https://github.com/apache/lucene/issues/11591 (LUCENE-10555: origin of the iteratorCost == -1 'no scorer yet' sentinel)https://github.com/apache/lucene/pull/13498 (GITHUB#13498, avoidable PointTree work in NumericComparator fixed as a bug fix: classification precedent)
- The finding in 30 seconds
a Lucene clone@716d6f216f5 (read-only) lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:50-62 (constructor, :56-59 the #16857 call), :64-77 (countHit), :114-123 (setScorer)a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:59-60 (shared flags), :154-158 (setHitsThresholdReached), :222-247 (updateCompetitiveIterator guards), :315 (iteratorCost = -1), :346-355 (setScorer), :363-446 (doUpdateCompetitiveIterator; :426 threshold, :430-431 the 8x comment, :441 intersect, :444 cost)a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/IndexSortedLeafFieldComparator.java:31-35, :91-97a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:100, :836, :842 (identical at 716d6f216f5); TopFieldCollector.java:87 (the only call before #16857)a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/FieldValueHitQueue.java:150 (single sort field: GREATER_THAN_OR_EQUAL_TO), :190-191 (IndexSortedLeafFieldComparator wrapper); TopFieldCollector.java:70-72 (countHit calls setHitsThresholdReached only while EQUAL_TO)
- Who is affected
a Lucene clone@716d6f216f5 lucene/MIGRATE.md:22-28 (SortField.withoutPruning never lets comparators skip documents using points)a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:98-111 (Pruning.NONE: no builder; points first, else DocValuesSkipper); FieldValueHitQueue.java:146-151; IndexSearcher.java:226-231, :767-777; TopFieldCollectorManager.java:111-140; TopDocsCollector.java:50-53
- Why it looks unintended
a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:315, :349, :426-431a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/IndexSortedLeafFieldComparator.java:31-35, :91-97; LeafFieldComparator.java:109-113; lucene/CHANGES.txt:39-47 and the GITHUB#13498 entries (:2410 under 10.0.0 Bug Fixes, :2765 under 9.11.1 Bug Fixes)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:87https://github.com/apache/lucene/pull/16857, https://github.com/apache/lucene/issues/11591, https://github.com/apache/lucene/pull/864, https://github.com/apache/lucene/pull/13498a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/search/comparators/TestTermOrdValComparatorAdaptiveSkipping.java:145, :192 (setHitsThresholdReached on a leaf comparator without setScorer)
- Suggested fix
a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/Weight.java:254 (DefaultBulkScorer.score calls collector.setScorer); comparators/NumericComparator.java:237a Lucene clone@716d6f216f5 lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:155 (flag set before the update), :235-240 (updateCounter and sampling), :456 (updateSkipInterval)
- Prior reports
GitHub API, read-only, 2026-10-30: repos/apache/lucene/commits?sha=main (head 716d6f216f5), commits on TopFieldCollector.java and NumericComparator.java (main, branch_11x: last is #16857), search/issues created:>=2026-10-30 (#16952 only), gh pr view 16952 (files: CHANGES.txt, IndexSearcher.java, LRUQueryCache.java, SeededKnnVectorQuery.java, TestConstantScoreBulkScorer.java, SuggestIndexSearcher.java)
- History
a Lucene clone git log: 70a428b5ba9 (author date 2026-10-29), 716d6f216f5; lucene/core/src/java/org/apache/lucene/util/Version.java:256 at 716d6f216f5 (LATEST = LUCENE_12_0_0)
- TestSortLaterSegmentPointsWork.java (lucene/core, package org.apache.lucene.search, 1 test):
repro/LFV-1057/TestSortLaterSegmentPointsWork.java(184 lines)
assets/LFV-1057/bug.png(643 KB)