Two features meet here: a leaf sorter, which reorders a reader's segments for faster sorted search, and opening a writer from that reader's commit. The writer lines its segments up with the reader's leaves by position.
- An index is a list of segments in creation order (
_0,_1, ...), recorded in the commit'sSegmentInfos. ADirectoryReaderopens one leaf reader per segment. - A leaf sorter (opt-in, for example newest segment first for time-based data) reorders the reader's leaves. The reader's
SegmentInfosstays in segment order. IndexWriterConfig#setIndexCommit(reader.getIndexCommit())(Expert) opens a writer at that reader's point in time and reuses the reader's open segment readers, so in-memory deletes of a near-real-time reader carry over.
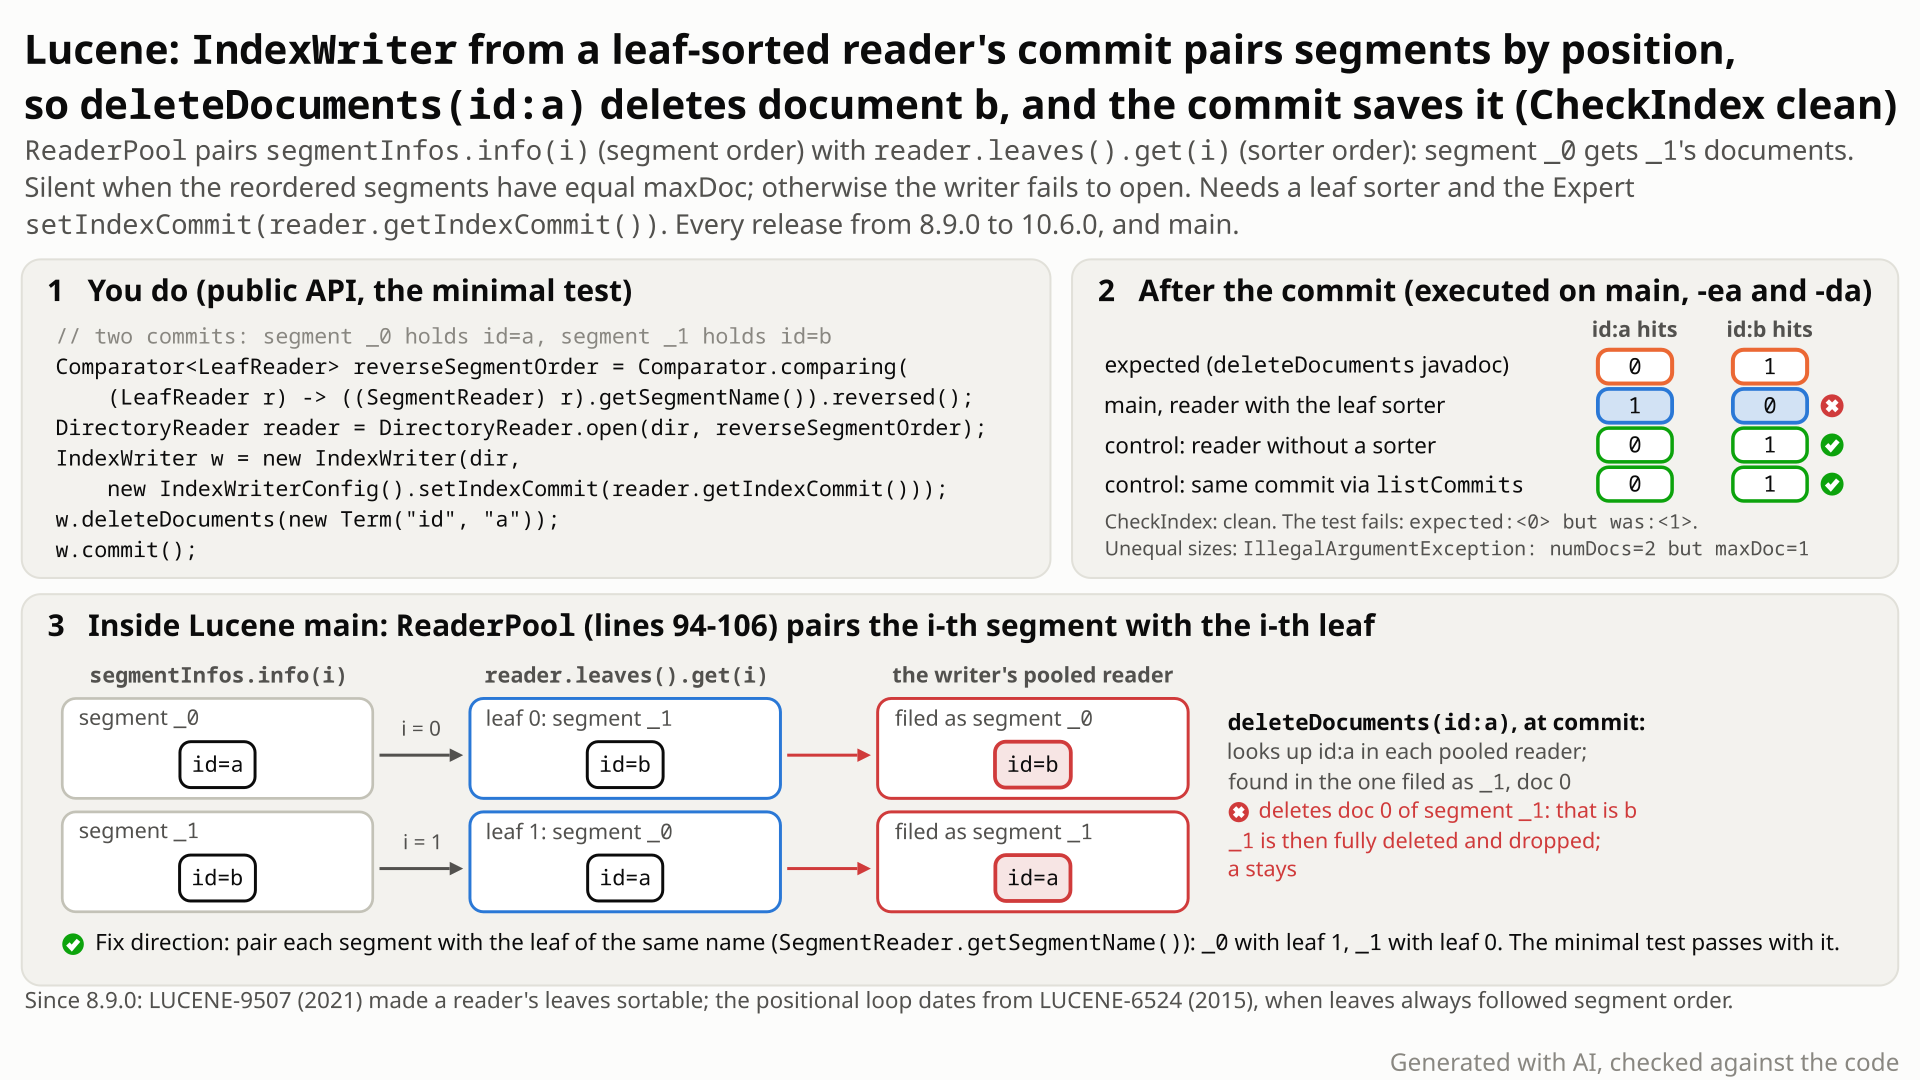
_1's slot holds a, so the delete of id:a removes b. Select the still to open it at full size. Generated with AI, checked against the code.- Commit two one-document segments:
_0holdsid:a,_1holdsid:b. OpenDirectoryReader.open(dir, sorter)with a sorter that puts the newer segment first, so its leaves are[_1, _0]. - Open an
IndexWriterwithsetIndexCommit(reader.getIndexCommit()), the documented way to start a writer from a reader, then calldeleteDocuments(new Term("id", "a"))andcommit(). - You expect
id:a0 hits andid:b1 hit, which is what you get without the sorter, or with the same commit taken fromlistCommits. - You get
id:a1 hit andid:b0. The writer's segment list is[_0, _1]and it was zipped with the leaves[_1, _0]by position, so_1's slot helda's data and the delete was saved into_1, which removedb. - No error, and
CheckIndexis clean. If the swapped segments differ in size, the writer fails to open instead:IllegalArgumentException: numDocs=2 but maxDoc=1.
Applications that combine two opt-in options: a leaf sorter (DirectoryReader.open(dir, sorter), the commit overload, or IndexWriterConfig#setLeafSorter) and a writer opened with the Expert setIndexCommit(reader.getIndexCommit()). Silent when the swapped segments have equal maxDoc (and no committed deletions), which two one-document segments already give; with unequal sizes the writer fails to open. Every release since 8.9.0.
Mechanism, terms and numbers786 words
When an IndexWriter is opened from a reader's commit (IndexWriterConfig#setIndexCommit(reader.getIndexCommit())), it pre-enrolls the reader's segment readers and pairs them with its own segment list by position. A leaf sorter reorders the reader's leaves but not the segment list, so each segment gets another segment's reader. Deletes, updates and merges then act on the wrong documents and the next commit saves that, with CheckIndex clean. In the repro, deleteDocuments(id:a) deletes b and keeps a. Every release from 8.9.0, the first with a leaf sorter, through 10.6.0 and main is affected; pairing by segment name fixes it.
IndexWriter.java:982-989: the writer takesconfig.getIndexCommit(). A commit fromDirectoryReader#getIndexCommitis aReaderCommit(StandardDirectoryReader.java:571-576) whose package-privategetReader()returns the reader itself (:644-646). A commit fromlistCommitsis aReaderCommitbuilt with anullreader (DirectoryReader.java:456,:481), so the samegetReader()returnsnull; that path never pre-enrolls anything and is not affected.IndexWriter.java:1021-1050: in the reader branch ("Init from an existing already opened NRT or non-NRT reader",:1030), the writer clonesreader.segmentInfos, which is in segment order[_0, _1](:1050), and hands the reader tonew ReaderPool(...)(:1149).BaseCompositeReader.java:75-76:Arrays.sort(subReaders, subReadersSorter). The same reader's leaves are in sorter order[_1, _0].ReaderPool.java:91-115pre-enrolls the reader's segment readers "so any in-memory NRT live docs are correctly carried over, and so NRT readers pulled from this IW share the same segment reader". It pairs them by position. The only check that the two lists match is a size assert; the per-pair checks are in step 5:
List<LeafReaderContext> leaves = reader.leaves();          // [_1, _0]
assert segmentInfos.size() == leaves.size();               // ReaderPool.java:95
for (int i = 0; i < leaves.size(); i++) {                  // :96
  SegmentReader segReader = (SegmentReader) leaves.get(i).reader();
  SegmentReader newReader = new SegmentReader(segmentInfos.info(i), segReader, ...);  // :99-106
  readerMap.put(newReader.getOriginalSegmentInfo(), new ReadersAndUpdates(...));
So _0's pool entry gets _1's reader (document b) and _1's entry gets _0's reader (document a).
SegmentReader.java:128-152: the copy constructor takes its identity fromsiand its data fromsr(this.core = sr.core,:151). It rejects onlynumDocs > maxDoc(:136-138) and a live-docs length mismatch (:139-142). An equal-size swap passes silently; an unequal one throws. Within a cycle of the permutation, unequal sizes always put a bigger reader on a smaller segment somewhere, so a swap passes these two guards exactly when the moved segments have equalmaxDoc(a Z3 model of the two guards for 2 to 8 segments agrees). Equal sizes are needed for the silent case but not always enough: with a committed deletion in a swapped segment, the next commit throws (below).deleteDocuments(id:a)is resolved against the pooled readers. Under_0it finds nothing (that reader holdsb); under_1it finds doc 0 (that reader holdsa) and marks doc 0 of_1deleted. That delete is in memory, but it makes_1, which holdsbon disk, fully deleted, so the commit drops_1(IndexWriter.java:6750-6756): the new commit lists only_0, witha, no live-docs file is written, andCheckIndexis clean.
updateDocument(id:a)deletesband leaves two copies ofa;updateNumericDocValue(id:a)setsb's value;softUpdateDocument(id:a)soft-deletesb.forceMerge(2)of three one-document segmentsa,b,ccommits[a, a, b](LogDocMergePolicy, merge factor 2,minMergeDocs1): one document lost, one duplicated,CheckIndexclean. With the defaultminMergeDocsthe merge takes all three segments and nothing is lost.- From a sorted near-real-time reader that carries one buffered delete, a bare
commit()revives the deleted document and deletes a live one, while the new writer's own NRT reader still shows the right documents. - With equal sizes and a committed deletion in one of the swapped segments, the next commit throws
NullPointerException(-da) orAssertionError(-ea) inPendingDeletes.writeLiveDocs. (Separately,PendingDeletes.java:41-44counts the other segment's deletions as pending deletes of this one.) - An NRT reader pulled from the new writer shows the right documents, but each leaf carries the other segment's name (
_0holdsb,_1holdsa). Through that reader,tryDeleteDocumentona's doc id deletesb, andtryUpdateDocValueon it setsb's value: both resolve the segment from the leaf's own segment info (tryModifyDocument,IndexWriter.java:1791-1812), which here is the wrong name. Through the original sorted reader they return -1 and change nothing. - Not affected:
forceMerge(1)and a commit fromlistCommits.
Exposure and likelihood310 words
- Who is hit. Applications that use a leaf sorter, through
DirectoryReader.open(Directory, Comparator), the commit overload (DirectoryReader.open(IndexCommit, Comparator)in 8.10.x-8.11.x,open(IndexCommit, int, Comparator)from 9.0.0) orIndexWriterConfig#setLeafSorterfor near-real-time readers (the javadoc suggests it for time-based indices: "usually a descending sort on timestamp"), and that open a writer withsetIndexCommit(reader.getIndexCommit()), for example to roll back to a reader's point in time or to hand a near-real-time reader over to a new writer. The documented NRT hand-off, combined with the documentedsetLeafSorteroption on both writers, fails the same way:id:a=1 id:b=0instead ofid:a=0 id:b=1. How often applications open a writer from the commit of the same leaf-sorted reader is unknown. - Silent and durable. No exception; the commit persists the wrong deletion;
CheckIndexreports the index clean, because it is self-consistent, just wrong. - No scale needed. Two one-document segments. The test configures no codec, directory or merge policy (the test framework randomizes codec and directory; it failed on every seed tried), and a
main()probe with the default codec gives the same result; assertions on and off. - Loud otherwise. When the moved segments differ in size, the writer constructor throws
IllegalArgumentException: numDocs=N but maxDoc=M(ormaxDoc=M but liveDocs.size()=N), so the documented path cannot open that index at all. - Upstream tests did not see it.
TestIndexWriterFromReadernever uses a leaf sorter, andTestIndexWriterReader.testIndexReaderWriterWithLeafSorternever opens a writer from a reader's commit. With a newest-first sorter injected into every config and reader open,TestIndexWriterFromReader.testRandomfails on 3 of 3 seeds (numDocs=N but maxDoc=1) and passes with the fix. - How likely. Rare: both options are opt-in, the silent case needs equal sizes, the Elasticsearch, OpenSearch and Solr call sites of
setIndexCommitread for two related bugs pass commits that carry no reader (code reading, not run), and no report was found in the five years since 8.9.0.
One JUnit test in org.apache.lucene.index, public API only, default IndexWriterConfig: two one-document commits, a reader whose sorter reverses segment order, a writer opened from that reader's commit, one delete and a commit. Its steps are deterministic (the test framework still randomizes codec and directory); it failed on every seed tried, with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.Comparator;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestIndexWriterFromLeafSortedReader extends LuceneTestCase {

  public void testDeleteThroughWriterOpenedFromLeafSortedReaderCommit() throws Exception {
    try (Directory dir = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        for (String id : new String[] {"a", "b"}) {
          Document doc = new Document();
          doc.add(new StringField("id", id, Field.Store.NO));
          w.addDocument(doc);
          w.commit();
        }
      }
      Comparator<LeafReader> reverseSegmentOrder =
          Comparator.comparing((LeafReader r) -> ((SegmentReader) r).getSegmentName()).reversed();
      try (DirectoryReader reader = DirectoryReader.open(dir, reverseSegmentOrder);
          IndexWriter w =
              new IndexWriter(
                  dir, new IndexWriterConfig().setIndexCommit(reader.getIndexCommit()))) {
        w.deleteDocuments(new Term("id", "a"));
        w.commit();
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        // expected: id:a deleted and id:b kept; actual: id:b is deleted and id:a survives
        assertEquals(0, searcher.count(new TermQuery(new Term("id", "a"))));
        assertEquals(1, searcher.count(new TermQuery(new Term("id", "b"))));
      }
    }
  }
}
./gradlew :lucene:core:test --tests "org.apache.lucene.index.TestIndexWriterFromLeafSortedReader" -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure)
- Expected
- After the commit
id:ahas 0 hits andid:bhas 1 hit. - Observed
id:ahas 1 hit andid:bhas 0:AssertionError: expected:<0> but was:<1>at the first assertion, assertions on and off.
More files, environment, full output226 words
Copy the file into lucene/core/src/test/org/apache/lucene/index/ and run the command. The test sits in org.apache.lucene.index like TestIndexWriterFromReader but uses nothing package-private. The reversed segment-name comparator is the smallest deterministic leaf sorter; on these two segments it gives the same order as a newest-first timestamp sorter (an earlier version of the test used one, with a ts doc value, and fails the same way). newDirectory() may wrap the directory in a MockDirectoryWrapper, whose close runs CheckIndex; it passes.
This is the no-noise gate's minimal repro with one line wrapped by google-java-format, so that :lucene:core:check passes with it; nothing else differs. Pass -Ptests.asserts explicitly, because by default the build picks it from the seed. The test is also the suggested regression test as it stands.
| lucene | main 645d4fe14a20 (gradle); the same failure on the 8.9.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0 jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 |
./gradlew :lucene:core:test --tests "org.apache.lucene.index.TestIndexWriterFromLeafSortedReader" -Ptests.seed=DEADBEEF -Ptests.asserts=true
# gradle, main 645d4fe14a20, seed DEADBEEF, -Ptests.asserts=true (the same with false)
TestIndexWriterFromLeafSortedReader > testDeleteThroughWriterOpenedFromLeafSortedReaderCommit FAILED
    java.lang.AssertionError: expected:<0> but was:<1>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:275702B30527020B]:0)
        ... (JUnit Assert frames)
        at org.apache.lucene.index.TestIndexWriterFromLeafSortedReader.testDeleteThroughWriterOpenedFromLeafSortedReaderCommit(TestIndexWriterFromLeafSortedReader.java:52)
:lucene:core:test (FAILURE): 1 test, 1 failure

# with the recommended fix, -Ptests.asserts=true:
:lucene:core:test (SUCCESS): 1 test
BUILD SUCCESSFUL

# with the fix, the test plus TestIndexWriterFromReader and TestReaderPool, -Ptests.asserts=true and false:
:lucene:core:test (SUCCESS): 19 tests
BUILD SUCCESSFULdeleteDocuments(Term...)"Deletes the document(s) containing any of the terms"; here it deletes the one without the term.setIndexCommitdocuments opening a writer from a reader'sgetIndexCommit()and excludes no reader; alistCommitscommit deletes correctly.- The positional loop predates the 2021 leaf sorter, which never updated it; reader reopen already pairs segments by name.
The full argument276 words
- Contract.
IndexWriter.java:1856: "Deletes the document(s) containing any of the terms." - The entry point names this flow.
IndexWriterConfig.java:235-237: "Expert: allows to open a certain commit point. The default is null which opens the latest commit point. This can also be used to open IndexWriter from a near-real-time reader, if you pass the reader's DirectoryReader#getIndexCommit." The LUCENE-6524 CHANGES entry: "IndexWriter can now be initialized from an already open near-real-time or non-NRT reader." The leaf sorter is documented only as a search-order option (DirectoryReader.java:76-90;IndexWriterConfig.java:518-520: "A DirectoryReader opened from a IndexWriter with this configuration will have its leaf readers sorted with the provided leaf sorter."). No javadoc, CHANGES or MIGRATE entry, code comment or test restricts the combination. - History. The positional loop came with LUCENE-6524 (
2d0ac9bb7f2, 2015, #7582), when a reader's leaves always followed segment order; the size assert shows the assumption. LUCENE-8260 (2018) moved it intoReaderPoolunchanged. LUCENE-9507 (48715fe898b, 2021, #10546 / #32) made leaves sortable and changed neitherReaderPool.javanorIndexWriter.java. - Sibling code pairs by identity. Reader reopen maps old readers by segment name (
StandardDirectoryReader.java:249-260), andtryDeleteDocument/tryUpdateDocValueresolve the segment from the leaf reader's own segment info (tryModifyDocument,IndexWriter.java:1791-1812). - Why tests never saw it. In the first review of LUCENE-9507 (apache/lucene-solr#2256, 2021-02-09), jimczi suggested a random leaf sorter in
LuceneTestCase#newIndexWriterConfig; the author replied that a different order "will break some of our tests that rely on specific docIds", so it was not done. - Precedent. LUCENE-8466 (2018), "IndexWriter.deleteDocs(Query... query) incorrectly applies deletes on flush if the index is sorted", treated deletes landing on the wrong documents as a bug.
The devil's-advocate check144 words
Every API involved is marked advanced: setIndexCommit is "Expert", DirectoryReader#getIndexCommit is "Expert" and @lucene.experimental, IndexCommit is @lucene.experimental, and on #214 jpountz called leafSorter one of the "super expert parameters". So a maintainer could call the combination unsupported.
Why it fails: no such precondition is documented; setIndexCommit names exactly reader.getIndexCommit(); setLeafSorter is an IndexWriterConfig option, so the documented NRT hand-off combined with that documented option yields a sorted reader without any misuse, and it fails the same way; "experimental" lets the API change, it does not let deleteDocuments delete a document that lacks the term and commit that silently. The executing reviews from another model family and the independent reproducer rated the intended-behaviour case weak; the devil's advocate found that none of its points survives; the adjudication agreed, and the audit found that deleting a document without the term "cannot be intended".
Recommended Pair each segment with the reader of the same name (validated)
Pair each segment with its own reader by segment name in the ReaderPool constructor (a map keyed by SegmentReader.getSegmentName()), not by position. Validated with gradle: the repro passes with assertions on and off, and so do TestIndexWriterFromReader, TestReaderPool, TestIndexWriterReader, TestDirectoryReader and TestDirectoryReaderReopen.
// ReaderPool constructor, reader != null: pair by segment name, not by position
Map<String, SegmentReader> readersByName = new HashMap<>();
for (LeafReaderContext leaf : leaves) {
  SegmentReader segReader = (SegmentReader) leaf.reader();
  readersByName.put(segReader.getSegmentName(), segReader);
}
for (SegmentCommitInfo info : segmentInfos) {
  SegmentReader segReader = readersByName.get(info.info.name);
  assert segReader != null : "no reader for segment " + info.info.name;
  SegmentReader newReader =
      new SegmentReader(info, segReader, segReader.getLiveDocs(),
          segReader.getHardLiveDocs(), segReader.numDocs(), true);
  // readerMap.put(...) unchanged
}
All options and trade-offs5 options · 559 words
One fix was built and validated; the other options come from the reviews and the brief and were not run.
In the ReaderPool constructor, map the reader's leaves by SegmentReader.getSegmentName() and look up each SegmentCommitInfo by info.info.name, instead of taking leaves.get(i). +10/-3 lines in ReaderPool.java; Map and HashMap are already imported.
// ReaderPool constructor, reader != null: pair by segment name, not by position
Map<String, SegmentReader> readersByName = new HashMap<>();
for (LeafReaderContext leaf : leaves) {
  SegmentReader segReader = (SegmentReader) leaf.reader();
  readersByName.put(segReader.getSegmentName(), segReader);
}
for (SegmentCommitInfo info : segmentInfos) {
  SegmentReader segReader = readersByName.get(info.info.name);
  assert segReader != null : "no reader for segment " + info.info.name;
  SegmentReader newReader =
      new SegmentReader(info, segReader, segReader.getLiveDocs(),
          segReader.getHardLiveDocs(), segReader.numDocs(), true);
  // readerMap.put(...) unchanged
}
Trade-offs
- One
HashMapper writer opened from a reader: linear, once, in the constructor. - Unchanged for unsorted readers, where position and name agree. It is the rule reader reopen already uses (
StandardDirectoryReader.java:249-260). - The pool's map is keyed by
SegmentCommitInfo, so the insertion order does not matter.
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, seedDEADBEEF: stock, the repro fails with assertions on and off whileTestIndexWriterFromReader(12) andTestReaderPool(6) pass; with the fix, all 19 tests pass with assertions on and off. - With the fix, assertions on:
TestIndexWriterReader(24, one assumption skip),TestDirectoryReader(34) andTestDirectoryReaderReopen(30) pass;:lucene:core:check -x test(format, ecj lint, forbidden APIs) passes with the fix and the test. - Earlier, in the repro harness: the independent reproducer's and both reviewers' tests pass; the 5,220-run bounded-exhaustive differential test matches the no-sorter control in every run; with a newest-first sorter injected,
TestIndexWriterFromReaderpasses 12 of 12 on 3 seeds;TestSoftDeletesDirectoryReaderWrapper(5) andTestSoftDeletesRetentionMergePolicy(14) pass. - Not run: the full Lucene test suite. The focused suites are enough for an issue and a candidate patch; run the full suite before calling the patch ready to merge.
Replace the assert segReader != null with an IllegalStateException, as one of the reviews suggested.
Trade-offs
A missing name cannot happen when the segment list and the leaves come from the same reader (the NRT path drops fully deleted segments from both), so this only changes how an internal inconsistency would surface. Not run.
Throw IllegalArgumentException in the writer's reader branch when the reader's leaves are not in segment order.
Trade-offs
Small and safe, but it rejects a documented composition of options (rollback or NRT hand-off with a leaf sorter) that today either corrupts silently or fails loudly, instead of making it work, and the javadoc would have to say so. Not run.
Have StandardDirectoryReader or its ReaderCommit keep the segment readers in segment order next to the sorted view, and pre-enroll from that.
Trade-offs
Equivalent to pairing by name, but it changes reader internals for a constructor-local problem. Not run.
Setting a random setLeafSorter in LuceneTestCase#newIndexWriterConfig, as jimczi proposed on apache/lucene-solr#2256, would have exposed this through TestIndexWriterFromReader.testRandom.
Trade-offs
Coverage, not a fix; many tests depend on doc ids, which is why it was not adopted in 2021. The regression test for this bug is the one repro test.
In a product that takes this path and lets users delete or update their own documents by term, one user's request could remove or change another document.
A planning pass proposed it and confirmed it with public-API probes on main; a skeptic pass re-ran and widened it. The hunt reduced it to one test and bounded it with a Z3 model of the writer's two size guards and a 5,220-run bounded-exhaustive differential test on the real jar.
The method in full219 words
- Lead (non-formal). A planning pass of the hunt's round 18 proposed it and witnessed it with public-API
main()probes on main: one with a directory reader opened with a newest-first sorter, one withsetLeafSorteron both writers and a near-real-time reader. A skeptic pass re-ran it, widened it (forceMerge(2)withminMergeDocs1 commits[a, a, b]) and found it on 8.9.0, 8.10.0 and 9.0.0. In the same round, injection replays (a newest-first sorter switched on in copied upstream test classes) hit the same root throughTestIndexWriterFromReader.testRandom. - Hunt. The unit reduced it to one public-API JUnit test. Then two formal legs: a Z3 model of the writer constructor's two guards (2 to 8 segments) separates the leaf orders that pass silently (equal
maxDoc) from those that fail loudly; a bounded-exhaustive differential test on the real jar (5,220 runs: 2 or 3 segments of 1 or 2 documents, with and without a deletion, every leaf order, directory and near-real-time readers, no-op, delete, update, doc-values update,forceMerge(1)andforceMerge(2); oracle: the same steps from the same commit without a sorter) matched the model's prediction in every run, and is 5,220 of 5,220 equal to the oracle with the fix. - Because the formal legs came after the lead, the hunt counts the bug as found by non-formal means.
No prior report: issues, PRs, the JIRA archive, commits, four mailing lists, downstream trackers and the web were searched on 2026-10-30, and the open pull requests touching ReaderPool were read. The closest items are the two features that combine into it (2015 and 2021).
Searches5 searches
No issue, PR, commit, JIRA entry, mailing-list thread, downstream report or web page describes this bug or any of its symptoms. The closest items are the features whose combination creates it, and open PRs in the same constructor that keep the positional pairing.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, incl. the migrated JIRA archive) | 2026-10-30 | three runs of the scripted prior-report search (119 queries over issues, PRs, commits, downstream repositories, JIRA, the lists and the web) and 67 manual searches, e.g. leafSorter, "leaf sorter", setIndexCommit, getIndexCommit, "IndexWriter from reader", ReaderPool, "numDocs=" "but maxDoc=", "wrong segment", LUCENE-9507, LUCENE-10027 | no report of this bug |
| Feature threads (read in full) | 2026-10-30 | #7582 (LUCENE-6524), #10546 / #32 / lucene-solr#2256 / #2473 (LUCENE-9507), #11066 / #214 (LUCENE-10027) | the origins of the positional loop (2015) and of the leaf sorter (2021); neither discusses opening a writer from a sorted reader's commit |
| Open PRs | 2026-10-30 | the changed files of all 410 open apache/lucene PRs; the diffs of those touching ReaderPool.java or the reader branch | #16847, #16923, #16643, #15683 and #16948 touch the area; none changes the pairing |
| Mailing lists (dev@, java-user@, issues@, commits@) | 2026-10-30 | list queries on setIndexCommit, getIndexCommit IndexWriter, leaf sorter, LUCENE-9507, LUCENE-10027 | no report; a 2017 java-user thread about rolling back with a reader's commit was answered with listCommits, which is not affected |
| Downstream (Elasticsearch, OpenSearch, Solr) and the web | 2026-10-30 | leafSorter, "leaf sorter", setIndexCommit, "numDocs=" "but maxDoc="; web queries | leaf-sorter adoption and unrelated issues; OpenSearch #7878 (a document loss after a segment-order change) is at search level, with no writer opened from a reader's commit |
Introduced in 8.9.0 by LUCENE-9507 (48715fe898b, 2021), which made a reader's leaves sortable without touching ReaderPool; the positional loop dates from LUCENE-6524 (2015). Every release from 8.9.0 through 10.6.0 and main is affected; 8.8.2 has no leaf-sorter API.
Versions tested7 rows
Introduced by LUCENE-9507 "Custom order for leaves in IndexReader and IndexWriter" (#32, issue #10546, 48715fe898b, 2021-03-26), released in 8.9.0 through its branch_8x backport 1cfd0df4e7bb (lucene-solr#2473). Latent precondition: the positional pre-enroll loop of LUCENE-6524 (2d0ac9bb7f2, 2015-06-28, #7582, released in 5.3.0), moved unchanged into ReaderPool by LUCENE-8260 (89756929537, 2018-04-23); it was correct while leaves always followed segment order. Widened by LUCENE-10027, another way to open a sorted reader: DirectoryReader.open(IndexCommit, Comparator) in 8.10.0 (branch_8x backport, lucene-solr#2540), which became open(IndexCommit, int, Comparator) in 9.0.0 (1daf7e7c742, #214). The rows below are the test shown above (ported by one import before 9.1), re-run on the release jars by the fact check; the follow-up's earlier sweep ran the finder's timestamp-sorter version of it (same steps) with the same outcomes. 8.10.0 was run with a main() probe of the same steps. The releases not listed are inferred from the code at their tags. Upstream main 716d6f216f5, branch_11x and branch_10_6 still pair by position.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | fails with assertions on and off (gradle and the repro harness) |
| 10.6.0, 10.5.2, 10.0.0, 9.12.3 | affected | fails (-da) |
| 9.0.0, 8.11.4 | affected | fails (-da; the test ported by one import) |
| 8.10.0 | affected | fails (-da; a main() probe of the same steps with a newest-first sorter) |
| 8.9.0 | first affected | fails (-ea and -da; ported by one import) |
| 8.8.2 and earlier | not affected | no leaf-sorter API: the test does not compile |
| fix (name pairing) | not affected | the test passes with assertions on and off |
An independent reproducer, executing reviews by a reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate, an adjudication and a credibility audit all call it real; each ran its own test, and the name-pairing fix made each pass.
Checks and verdicts283 words
Every check ran Java. The reviews ran on main ea57360912ed, whose ReaderPool, SegmentReader, BaseCompositeReader, StandardDirectoryReader, PendingDeletes and writer constructor are byte-identical to 645d4fe14a20. Fact checks of this doc then re-ran the test on main and on the release jars and probed the side legs.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Its own test, written from the claim, fails on main with -ea (10 of 10 iterations) and -da and on 10.6.0, 10.5.2 and 9.12.3; its unsorted control passes; its own name-pairing fix passes. It also reproduced the loud case (numDocs=2 but maxDoc=1). |
| cross-model review, refute lens | real, high | OpenAI GPT-5.6, executing: its own two-segment test fails with -ea and -da (counts 1/0 instead of 0/1), the control passes; with the fix its test, TestIndexWriterFromReader (12/12) and TestIndexWriterReader (23/23) pass. Intended-behaviour case weak. |
| cross-model review, intended lens | real, high | OpenAI GPT-5.6, executing: its own test fails on main and on 10.6.0; its test of the javadoc's sorted-NRT flow fails; a listCommits commit deletes correctly. It suggested an explicit exception instead of the assert. |
| intended-behaviour devil's advocate | real, high | Found no javadoc, CHANGES or MIGRATE entry, test or review thread that restricts the combination; ran the setIndexCommit javadoc's NRT flow with setLeafSorter: id:a=1 id:b=0. |
| adjudication | confirmed, high | Re-ran the reproducer's test on main and 10.6.0 (fail), the finder's test on main (fail), the control and the fix (pass). |
| credibility audit and no-noise gate | keep; claim | The audit re-ran the minimal test on another seed (fails with -ea and -da) and re-checked the size-guard reasoning; the gate accepted the one-test repro. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 523 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,343 words
- Registry title
- An IndexWriter opened from a leaf-sorted reader's IndexCommit pairs each segment with the segment reader at the same leaf position, so deleteDocuments(term) deletes another segment's documents and the commit persists that silently
- Area
- index / IndexWriter opened from a reader's IndexCommit (ReaderPool pre-enrollment) with a leaf-sorted reader (DirectoryReader leaf sorter, IndexWriterConfig#setLeafSorter)
- Priority
- Medium, rank 78: This is silent, durable wrong-document deletion in core IndexWriter that CheckIndex does not catch, but like its sibling LFV-593 it needs the Expert setIndexCommit-from-a-reader path plus a leaf sorter and equal-maxDoc reordered segments.
- Impact class
- data corruption
- Impact note
- Hits only applications that combine two opt-in options: a leaf sorter (DirectoryReader.open(Directory, Comparator), the IndexCommit overload with a sorter, or IndexWriterConfig#setLeafSorter for NRT readers, for example the newest-first order the javadoc suggests for time-based indices) and an IndexWriter opened with the Expert IndexWriterConfig#setIndexCommit(reader.getIndexCommit()) on such a reader; when the segments the sorter moves have equal maxDoc (two one-document segments suffice, no scale), deletes, updates, doc-values updates and merges act on another segment's documents and the next commit persists that with CheckIndex clean, and when their sizes differ the writer constructor throws IllegalArgumentException 'numDocs=N but maxDoc=M' instead; default codec, directory and merge policy, -ea and -da, every release from 8.9.0 through 10.6.0 and main.
- Summary
- You commit two one-document segments (_0 holds id=a, _1 holds id=b), open DirectoryReader.open(dir, newestFirst) so that its leaves are [_1, _0], open an IndexWriter with setIndexCommit(reader.getIndexCommit()), call deleteDocuments(new Term("id", "a")) and commit. You expect the index to keep only b, as it does when the reader has no sorter or when the same commit is taken from DirectoryReader.listCommits. Instead the writer deletes b and keeps a: ReaderPool pairs segmentInfos.info(i) (segment order) with reader.leaves().get(i) (sorted order) by position, so each segment's pooled reader carries the other segment's documents, the delete matches a's data but is recorded under _1, and the commit writes _1's live docs, with CheckIndex clean.
- Introduced
- 48715fe898bf (apache/lucene main, LUCENE-9507 'Custom order for leaves in IndexReader and IndexWriter', issue #10546, PR #32, author Mayya Sharipova, author date 2021-03-26), first released through its branch_8x backport 1cfd0df4e7bb (apache/lucene-solr#2473, author date 2021-03-30, in 8.9.0): it made a reader's leaves sortable (BaseCompositeReader Arrays.sort(subReaders, subReadersSorter)) and changed neither ReaderPool.java nor IndexWriter.java [read: git blame and git log of ReaderPool.java:90-116 and of the commit's file list; exec: 8.8.2 has no leaf-sorter API (the repro does not compile), 8.9.0 fails]. Latent precondition, not the introducing commit: the positional pre-enroll loop of 2d0ac9bb7f22 (LUCENE-6524 / #7582, author date 2015-06-28, first released in 5.3.0), moved unchanged into ReaderPool by 89756929537 (LUCENE-8260, 2018-04-23), which was correct while a reader's leaves always followed segment order (2021-03-26 (author date of 48715fe898b on main; the branch_8x backport 1cfd0df4e7bb is dated 2021-03-30))
- First affected version
- 8.9.0 [exec: the JUnit, ported to the pre-9.1 test package, fails with -ea and -da; the round-18 skeptic's main() probe also fails]; 8.8.2 and earlier are not affected [exec: DirectoryReader.open(Directory, Comparator) does not exist and the repro does not compile; the positional loop exists since 5.3.0 but cannot mispair without a sorter]
- Affected versions
- every release from 8.9.0 through 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main 645d4fe14a20; never fixed. [exec, the JUnit TestIndexWriterFromLeafSortedReader, seed DEADBEEF] 8.9.0 (-ea and -da), 8.11.4, 9.0.0 (8.x and 9.0.0 through a one-import port), 9.12.3, 10.0.0, 10.5.2 and 10.6.0 (-da) and main (-ea and -da) all fail with the same assertion; the independent reproduction's own JUnit fails on 10.6.0, 10.5.2 and 9.12.3 (-da); the round-18 skeptic's main() probes fail on 8.9.0, 8.10.0 and 9.0.0 (-da). [read] the remaining 8.10.x, 8.11.x, 9.x and 10.x releases are inferred: every 9.x and 10.x release tag contains both the positional loop and the leaf sort (git show per tag), and 8.10.1-8.11.3 lie between executed 8.x releases that fail. Upstream main 716d6f216f5, branch_11x and branch_10_6 still pair by position (the last ReaderPool.java commit is 9092bda09d6, #16570, author date 2026-09-01; re-checked 2026-10-30). Not new in 10.6.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by Z3, exhaustive check
- Upstream and prior reports
- none found (2026-10-30, read-only; the prior-report record, verdict new): three scripted prior-report searches (119 queries over apache/lucene issues and PRs incl. the migrated JIRA archive, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; 453, 724 and 45 hits); 67 manual GitHub search queries (apache/lucene, Elasticsearch, OpenSearch, Solr); full reads of the feature threads #7582 (LUCENE-6524), #10546 / #32 / lucene-solr#2256 / lucene-solr#2473 (LUCENE-9507) and #11066 / #214 (LUCENE-10027); the changed files of all 410 open apache/lucene PRs (the five that touch ReaderPool.java or the reader-commit branch, #16847, #16923, #16643, #15683 and #16948, were read: none changes the pairing); the 66 items updated since 2026-10-28. Closest, not reports: #7582 (added the positional loop in 2015, when leaves were always in segment order), #10546 / #32 (added the leaf sorter in 2021 without touching ReaderPool; in its review jimczi proposed randomizing the leaf sorter in newIndexWriterConfig, which was not adopted because tests depend on doc ids), #11066 / #214 (another way to build a sorted reader), OpenSearch #7878 (downstream document loss after a segment-order change, at search level, with no writer opened from a reader commit). Re-check (2026-10-30): no apache/lucene item matches 'leafSorter setIndexCommit', 'ReaderPool' created since 2026-10-28 or '"leaf sorter" IndexWriter' created since 2026-10-01; the only items updated after a recent cutoff are #16952 and #16949 (unrelated); upstream main is still 716d6f216f5 and the last ReaderPool.java commit is 9092bda09d6 (#16570, author date 2026-09-01). Not fixed upstream (main, branch_11x, branch_10_6)
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the one-test repro through gradle with assertions on and off, stock and with the fix, plus the closest upstream suites (2026-10-30). Earlier, in the repro harness: main with-eaand-daon several seeds, and the release jars 8.9.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0 (8.8.2 does not have the API); the fact check (2026-10-30) re-ran this test on those jars, and 8.10.0 was run with amain()probe of the same steps. Upstream main716d6f216f5,branch_11xandbranch_10_6were read, not run: they still pair by position.
- Finding record
a Lucene main checkout (645d4fe14a20): lucene/core/src/java/org/apache/lucene/index/ReaderPool.java:90-115 (pre-enroll loop: :95 'assert segmentInfos.size() == leaves.size()', :96-101 leaves.get(i) paired with segmentInfos.info(i)); BaseCompositeReader.java:74-76 (Arrays.sort(subReaders, subReadersSorter)); IndexWriter.java:1050 (segmentInfos = reader.segmentInfos.clone()), :1149 (new ReaderPool(...)), :1856 ('Deletes the document(s) containing any of the terms'); SegmentReader.java:128-142 (copy constructor rejects only numDocs > maxDoc and a liveDocs length mismatch); PendingDeletes.java:41-44 (pendingDeleteCount = reader.numDeletedDocs() - info.getDelCount()); IndexWriterConfig.java:235-241 (setIndexCommit javadoc: open IndexWriter from a near-real-time reader by passing its getIndexCommit), :517-527 (setLeafSorter); DirectoryReader.java:76-90 (open(Directory, Comparator): a search-speed option, 'for time-based indices this is usually a descending sort on timestamp')gh api read-only re-check 2026-10-30: search/issues 'repo:apache/lucene updated:>=2026-10-30', 'leafSorter setIndexCommit', 'ReaderPool created:>=2026-10-28', '"leaf sorter" IndexWriter created:>=2026-10-01'; repos/apache/lucene/commits?path=lucene/core/src/java/org/apache/lucene/index/ReaderPool.java; repos/apache/lucene/commits?sha=main
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:982-989, 1021-1050, 1149, 1791-1812 (tryModifyDocument), 6750-6756 @ 645d4fe14a20lucene/core/src/java/org/apache/lucene/index/StandardDirectoryReader.java:571-576, 644-646; DirectoryReader.java:448-481 (listCommits: ReaderCommit(null, ...) at :456, :481) @ 645d4fe14a20lucene/core/src/java/org/apache/lucene/index/BaseCompositeReader.java:75-76; ReaderPool.java:91-115; SegmentReader.java:128-152; PendingDeletes.java:41-44 @ 645d4fe14a20
- Who is affected
lucene/core/src/java/org/apache/lucene/index/DirectoryReader.java:76-90 (open(Directory, Comparator) javadoc); IndexWriterConfig.java:235-241, 518-527 @ 645d4fe14a20lucene/core/src/test/org/apache/lucene/index/TestIndexWriterReader.java:1204 (testIndexReaderWriterWithLeafSorter); TestIndexWriterFromReader.java (no leaf sorter) @ 645d4fe14a20lucene/CHANGES.txt:4769-4770 (9.0.0: open(IndexCommit, int, Comparator)), 5223-5224 (8.10.0: open(IndexCommit, Comparator)); javap on the 8.10.0 and 9.0.0 lucene-core jars
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1856, 1030, 1791-1812; IndexWriterConfig.java:235-241, 518-527; DirectoryReader.java:76-90, 644-649; IndexCommit.java:35; StandardDirectoryReader.java:249-260 @ 645d4fe14a20lucene/CHANGES.txt:10312-10314 (LUCENE-6524), 5345-5346 (LUCENE-9507), 5223-5224 (LUCENE-10027)gh api read-only 2026-10-30: apache/lucene-solr pulls/2256/comments (jimczi 2021-02-09T15:49Z; mayya-sharipova reply 2021-03-22T16:02Z); apache/lucene pulls/214/comments (jpountz 2021-07-20T12:43Z, "super expert parameters")
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/StandardDirectoryReader.java:249-260 (mapPreviousReaders by segment name) @ 645d4fe14a20gh api read-only 2026-10-30: apache/lucene-solr pulls/2256/comments (jimczi 2021-02-09; reply 2021-03-22)
- TestIndexWriterFromLeafSortedReader.java (one test):
repro/LFV-1062/TestIndexWriterFromLeafSortedReader.java(57 lines)
assets/LFV-1062/bug.png(523 KB)