Query parsers turn prefix, wildcard, fuzzy, regexp and range terms into index terms with Analyzer.normalize. A conditional block in a CustomAnalyzer never passes that call on to the filters it wraps.
- At index time the analyzer runs its whole chain on each token: whitespace splits
Apache Lucene, thenlowercaseturnsApacheinto the indexed termapache. - A query like
Apa*or[Apache TO Apache]holds partial words or bounds that must not be tokenized or stemmed. So the parser callsAnalyzer.normalize, which runs only the filters whose factory opts in throughTokenFilterFactory.normalize();lowercaseandasciifoldingdo. - A conditional block (
when()/whenTerm()...endwhen(), orProtectedTermFilterFactory) is one factory that wraps other factories and applies them only to tokens that pass its condition, for example words longer than 2 letters or words not on a protected list.
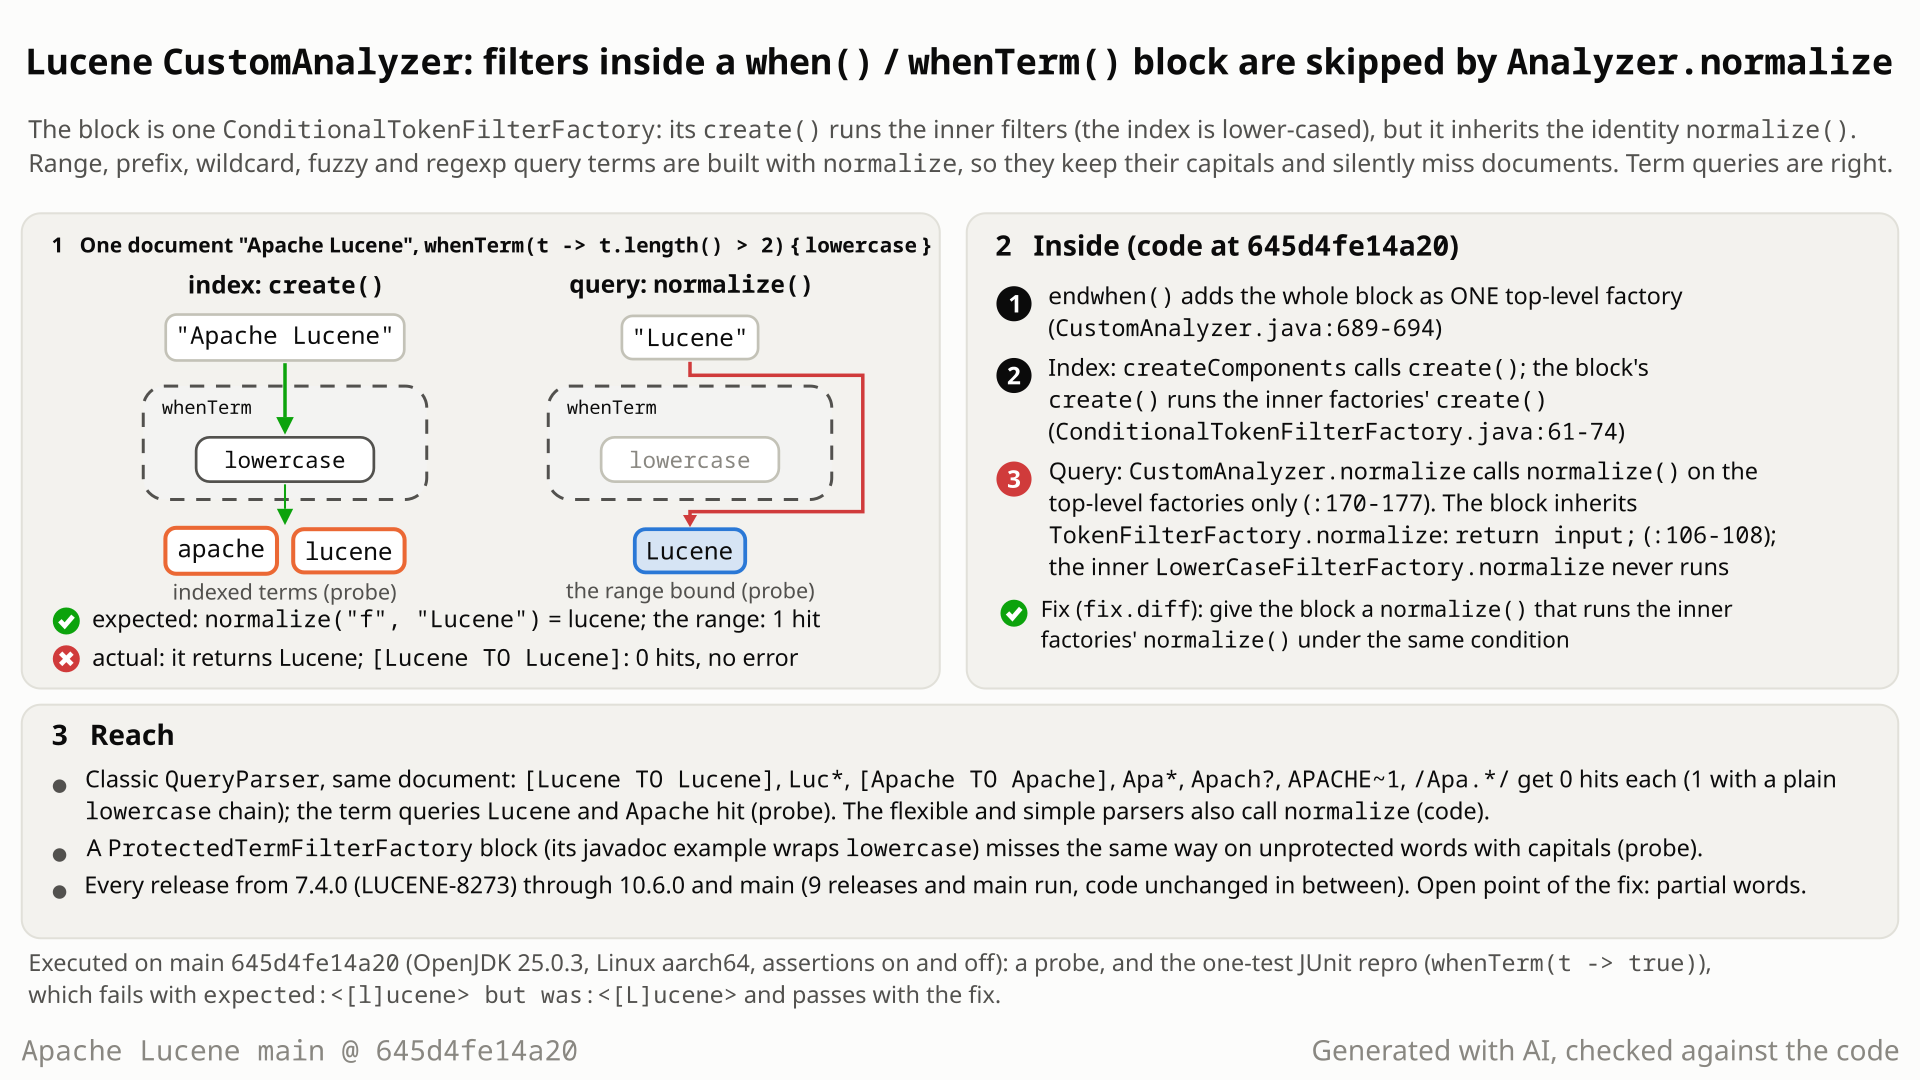
Apache Lucene and whenTerm(t -> t.length() > 2){lowercase}: indexing runs the inner lowercase through create(), but query-time normalize() goes around the block, so [Lucene TO Lucene] gets 0 hits. Select the still to open it at full size. Generated with AI, checked against the code.- Build a
CustomAnalyzer: whitespace tokenizer, thenwhenTerm(t -> t.length() > 2).addTokenFilter("lowercase").endwhen(). Index the textApache Lucene: the index holdsapacheandlucene. - Search with the classic
QueryParserforApa*,Apach?,APACHE~1,/Apa.*/or[Apache TO Apache]. For these the parser does not run the full analyzer; it callsAnalyzer.normalize("f", "Apache"), which should return the indexed form,apache. - You expect 1 hit for each query, as with the same chain without the condition.
- Instead
normalizereturnsApacheunchanged and all five queries find 0 documents, with no error; the plain term queryApachestill finds it. AProtectedTermFilterFactorywrappinglowercase(as its javadoc example does, there aftertruncate) misses the same way on the unprotectedApache. - Why: the block is one
ConditionalTokenFilterFactory. It wraps the inner filters increate()but has nonormalize(), so the do-nothing default runs and the innerlowercaseis never asked.
Applications whose CustomAnalyzer or factory chain puts a normalizing filter (lowercase, asciifolding, ...) inside when()/whenTerm() or ProtectedTermFilterFactory, and that accept prefix, wildcard, fuzzy, regexp or range syntax through Lucene's query parsers. Opt-in, but the ProtectedTermFilterFactory javadoc example has this shape (truncate, then lowercase) and a committer advised it on #14416.
Mechanism, terms and numbers552 words
Query parsers build prefix, wildcard, fuzzy, regexp and range queries from Analyzer.normalize, which applies only the filters that opt in to normalization, such as lowercase and asciifolding. In a CustomAnalyzer, a conditional block (when(...)/whenTerm(...) ... endwhen(), or ProtectedTermFilterFactory with wrapped filters) is a single ConditionalTokenFilterFactory. It runs its inner filters at index time but has no normalize() of its own, so at query time it inherits the identity default and the inner filters are skipped. A document Apache Lucene indexed as apache, lucene is then missed by Apa*, Apach?, APACHE~1, /Apa.*/ and [Apache TO Apache] (0 hits each, 1 without the condition), with no error. It has been there since conditional filters were added in 7.4.0, in every release through 10.6.0 and on main; a normalize() override that wraps the inner factories' normalize() under the same condition fixes the always-true / full-term case.
CustomAnalyzer.normalizecallsnormalize()on each of its top-level token filter factories (CustomAnalyzer.java:170-177on main645d4fe14a20).endwhen()adds the whole conditional block to the chain as one top-level factory (CustomAnalyzer.java:689-694);whenTerm(...)builds an anonymousConditionalTokenFilterFactory(:564-581), andProtectedTermFilterFactoryextends that class.ConditionalTokenFilterFactory.create()chains the inner factories'create()inside aConditionalTokenFilter(ConditionalTokenFilterFactory.java:61-74), andinform()is forwarded too (:76-85). There is nonormalize()override, soTokenFilterFactory.normalizeruns: "While the default implementation returns input unchanged, filters that should be applied at normalization time can delegate tocreatemethod." (TokenFilterFactory.java:101-108).- The inner
LowerCaseFilterFactory.normalize, which delegates tocreate()(LowerCaseFilterFactory.java:61-63), is never called. The block contributes no normalization: in this chain (whitespace tokenizer, then the block)normalizereturns the query text unchanged, while indexing applied the inner filters.
Callers that reach it: the classic QueryParserBase for range bounds (:550, :556), wildcard chunks (:646, :656), the whole regexp pattern (:683), prefix (:712) and fuzzy (:729), inherited by ComplexPhraseQueryParser through QueryParser; the flexible parser's range, fuzzy, wildcard and regexp processors; SimpleQueryParser for prefix and fuzzy, the only two of these syntaxes it has. Executed in the fact check: on stock the complex-phrase and flexible parsers miss all five multi-term queries and SimpleQueryParser misses Apa* and APACHE~1; all hit with the fix.
Document Apache Lucene, classic QueryParser, stock main, hit counts:
| analyzer | normalize("Apache") | Apache | [Apache TO Apache] | APACHE~1 | Apa* | Apach? | /Apa.*/ |
|---|---|---|---|---|---|---|---|
| whitespace, lowercase (control) | apache | 1 | 1 | 1 | 1 | 1 | 1 |
whitespace, whenTerm(len > 2){lowercase} | Apache | 1 | 0 | 0 | 0 | 0 | 0 |
whitespace, ProtectedTermFilterFactory (protects Lucene) wrapping lowercase | Apache | 1 | 0 | 0 | 0 | 0 | 0 |
whenTerm(len > 2){lowercase} with the fix | apache | 1 | 1 | 1 | 1 | 1 | 1 |
With asciifolding inside the block the same happens to accents: the index holds elan, normalize("Élan") returns Élan, and Éla*, Él?n and [Élan TO Élan] get 0 hits (1 each without the condition).
Not affected: plain term and phrase queries (they use the full analysis chain), query text already typed in the indexed form (apa*, apach? and [apache TO apache] get 1 hit on stock), and every stock analyzer (none builds a conditional block). What misses is query text the skipped filter would have changed, here a capital letter.
Exposure and likelihood288 words
- Who is hit. A
CustomAnalyzer(or a chain built from the factories by SPI name) with a normalizing filter such aslowercase,asciifoldingorgermanNormalizationinside a conditional block, used with the classic, complex-phrase, flexible or simple query parser for range, fuzzy, prefix, wildcard or regexp terms (each parser for the syntax it has;SimpleQueryParserhas only prefix and fuzzy). 28 filter factories inlucene/analysisoverridenormalize(), and any of them loses it inside a block. - Opt-in, but documented. No stock analyzer and no default builds a conditional block. But the
ProtectedTermFilterFactoryjavadoc example wrapstruncateandlowercasein one (its Solr example useswrappedFilters="truncate,lowercase"), and on #14416 a committer (rmuir) told a user to useProtectedTermFilteraround a normalizer in aCustomAnalyzer. - Silent. No exception or warning; queries just match fewer documents. With
ProtectedTermFilterFactorythe protected words keep working, while multi-term queries on other words miss whenever the query text differs from the indexed form (here, any capital letter). That is easy to overlook when tests type queries in lower case. - No scale or odd parameter. One document, one token, deterministic, with assertions on and off.
- Workaround. Put the normalizing filter outside the block, as the
CustomAnalyzerclass javadoc example does (executed in the fact check:normalize("Apache")=apache, all six queries hit). That changes what the block protects, so it is not always acceptable.CustomAnalyzerisfinal, sonormalizecannot be overridden on it, but anAnalyzerWrappercan add the missing normalization inwrapTokenStreamForNormalization(not run). - Downstream (not run). By code reading of apache/solr main
9ba1a7d42e4b(2026-10-30), Solr'sTokenizerChain.normalizealso calls each factory'snormalize()(TokenizerChain.java:140-143), so a Solr field type built this way most likely behaves the same.
One JUnit test, public API only, no index: a whitespace tokenizer and lowercase inside an always-true whenTerm(), then one normalize call. Copy it to lucene/analysis/common/src/test/org/apache/lucene/analysis/custom/ and run it with gradle; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.custom;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestConditionalFilterNormalize extends LuceneTestCase {

  public void testNormalizeAppliesFiltersInsideWhenTerm() throws Exception {
    try (Analyzer analyzer =
        CustomAnalyzer.builder()
            .withTokenizer("whitespace")
            .whenTerm(t -> true)
            .addTokenFilter("lowercase")
            .endwhen()
            .build()) {
      // expected "lucene" (the indexed term), actual "Lucene": the filter inside whenTerm() is skipped
      assertEquals("lucene", analyzer.normalize("f", "Lucene").utf8ToString());
    }
  }
}
./gradlew :lucene:analysis:common:test --tests "org.apache.lucene.analysis.custom.TestConditionalFilterNormalize" -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure)
- Expected
analyzer.normalize("f", "Lucene")returnslucene, the term the index holds forLucene.- Observed
- It returns
Luceneunchanged:ComparisonFailure: expected:<[l]ucene> but was:<[L]ucene>, with assertions on and off.
More files, environment, full output266 words
The condition is always true, so the block must behave exactly like a plain lowercase filter. The query consequence (0 hits for Apa*, [Apache TO Apache] and the others, table above) is not part of the test. What the test does not settle: it covers only an always-true condition with lowercase, not what an arbitrary or attribute-reading condition, a protected-term list, or prefix, wildcard and regexp text should give (the policy question under Suggested fix).
The module's check task rejects the file as is: ecjLintTest reports "The value of the lambda parameter t is not used" and checkGoogleJavaFormat flags the comment line (over 100 columns). The PR copy changes only those two lines (whenTerm(t -> t.length() > 0) // holds for every token and a shorter comment); it fails the same way on stock, passes with the fix, and :lucene:analysis:common:check -x test passes.
Runs of this test: gradle on main 645d4fe14a20 (-Ptests.asserts=true and false: 1 test, 1 failed); the standalone runner on main (seed 5EED0471) and on the 10.6.0 release jars, -ea and -da: fails each time; with the fix: passes. An earlier two-assertion form (it also indexes a document and runs [Lucene TO Lucene]) fails the same way on main, 10.6.0, 10.5.2, 10.0.0 and 9.12.3. Name tests.asserts explicitly: the build randomizes it per seed otherwise.
| lucene | main 645d4fe14a20 (2026-10-28) and the 10.6.0 release; every release tried since 7.4.0 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
TestConditionalFilterNormalize > testNormalizeAppliesFiltersInsideWhenTerm FAILED
    org.junit.ComparisonFailure: expected:<[l]ucene> but was:<[L]ucene>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:5C3E91A926CACBC]:0)
        at app/junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:117)
        at app/junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:146)
        at app//org.apache.lucene.analysis.custom.TestConditionalFilterNormalize.testNormalizeAppliesFiltersInsideWhenTerm(TestConditionalFilterNormalize.java:33)

1 test completed, 1 failedAnalyzer.normalizemust return "the representation that it would have in the index"; with an always-true condition it returnsLucenewhile the index holdslucene.- The inner
lowercasefactory opts in to normalization; the block forwardscreate()to it but notnormalize(). Nothing documents an exclusion. - Similar gaps were fixed as bugs: LUCENE-7606, LUCENE-8186 and LUCENE-7429.
The full argument313 words
- The contract.
Analyzer.normalize: "Normalize a string down to the representation that it would have in the index. This is typically used by query parsers in order to generate a query on a given term, without tokenizing or stemming, which are undesirable if the string to analyze is a partial word (eg. in case of a wildcard or fuzzy query)." (Analyzer.java:202-207). With an always-true condition the block must behave like the plain filter, and it does not. - The inner filters opted in.
TokenFilterFactory.normalize: "filters that should be applied at normalization time can delegate tocreate" (TokenFilterFactory.java:101-104);LowerCaseFilterFactorydoes. The conditional factory forwardscreate()andinform()to its inner factories (ConditionalTokenFilterFactory.java:61-85), notnormalize(). - The documentation invites the configuration. The
ProtectedTermFilterFactoryjavadoc putslowercaseinside the block. On #14416 rmuir wrote "Just use ProtectedTermFilter which works with any tokenfilter without requiring modification to its code?" and "If you want to change the behavior of GermanAnalyzer then just make a CustomAnalyzer with ProtectedTermsFilter.", about wrappingGermanNormalizationFilter, whose factory overridesnormalize(). - Nothing documents the exclusion. No javadoc,
CHANGES.txtorMIGRATE.mdentry, test or code comment says conditional blocks are skipped;TestCustomAnalyzer's conditional tests check only index-time output, and its normalization tests use unconditional chains. Neither the feature's review (#9320) nor thenormalize()redesign (#9543) discusses it. - How the gap arose. LUCENE-8273 added the factory in 7.4.0, when
CustomAnalyzer.normalizeapplied onlyMultiTermAwareComponentfactories, and this one was not. LUCENE-8497 (8.0.0) replaced that withTokenFilterFactory.normalize()and converted the classes that were already multi-term aware, so this one stayed out. - Precedents fixed as bugs (under "Bug Fixes" in
lucene/CHANGES.txt): LUCENE-7606 "Normalization with CustomAnalyzer would only apply the last token filter" (6.4.0), LUCENE-8186 "LowerCaseTokenizerFactory now lowercases text in multi-term queries" (7.4.0), LUCENE-7429 "AnalyzerWrapper can now modify the normalization chain too and DelegatingAnalyzerWrapper does the right thing automatically" (6.3.0).
The devil's-advocate check196 words
The strongest case for "intended" (the intended-behaviour checker and the GPT-5.6 intended-lens reviewer): normalization is opt-in and the default is identity, and TestCustomAnalyzer.testNormalization asserts that components that are not multi-term aware "should not be applied"; a condition cannot be judged faithfully on a partial word (Luc* when Lucene is protected), and a custom condition may read attributes (type, keyword) that the one-token normalize stream does not set, so never applying the block could be safer; and whenTerm(len > 2){lowercase} looks contrived.
Why it fails: the block is a container whose inner filters did opt in, and it drops that silently, like the DelegatingAnalyzerWrapper case fixed in LUCENE-7429. Nothing records a decision to exclude blocks, and the stock behaviour is no coherent policy: it skips the block for full terms too (range bounds, fuzzy terms), even under an always-true condition, where the condition would judge the whole query word just as it judges that word at index time. The fragment question is about how to fix partial words, not a defence of today's behaviour. The realistic trigger is a ProtectedTermFilterFactory wrapping lowercase, as its javadoc example does (there after truncate). Verdict: a defect.
Recommended Wrap the inner factories' normalize() under the same condition (for the full-term case)
Give ConditionalTokenFilterFactory a normalize() that wraps the inner factories' normalize() under the same condition, as create() does (+19 lines). The test passes, and so does the whole analysis-common test task (1910 tests). A tested sketch for the full-term case: protected prefixes (Luc*) change behaviour and inner filters without normalize() (truncate) stay skipped.
@Override
public TokenStream normalize(TokenStream input) {
  if (innerFilters == null || innerFilters.size() == 0) {
    return input;
  }
  Function<TokenStream, TokenStream> innerStream =
      ts -> {
        for (TokenFilterFactory factory : innerFilters) {
          ts = factory.normalize(ts);
        }
        return ts;
      };
  return create(input, innerStream);
}
All options and trade-offs3 options · 808 words
One fix was built and validated; two alternatives are described. Workaround until a fix ships: put normalizing filters outside the conditional block (.addTokenFilter("lowercase").when(...)...endwhen()), as the CustomAnalyzer class javadoc example does (executed in the fact check: all six queries hit), or wrap the analyzer in an AnalyzerWrapper that adds the missing normalization in wrapTokenStreamForNormalization (not run).
Wrap the inner factories' normalize() under the same condition (for the full-term case) (validated by the checks) (recommended)
Add normalize(TokenStream) to ConditionalTokenFilterFactory: the same body as create(TokenStream), calling each inner factory's normalize() instead of create(), wrapped by the subclass's create(input, inner), so the condition decides as at index time. +19 lines with a javadoc comment; the finder's sketch has the same logic. Offer it as a tested sketch for the case the test covers (an always-true condition, full terms), not as the settled policy for every condition and every partial word: maintainers may prefer a narrower opt-in or an explicit fragment policy to merging it unchanged.
@Override
public TokenStream normalize(TokenStream input) {
  if (innerFilters == null || innerFilters.size() == 0) {
    return input;
  }
  Function<TokenStream, TokenStream> innerStream =
      ts -> {
        for (TokenFilterFactory factory : innerFilters) {
          ts = factory.normalize(ts);
        }
        return ts;
      };
  return create(input, innerStream);
}
Trade-offs
- What the condition sees. The condition now runs on the text
normalizegets: the user's query spelling, not the document's. For a full term (a range bound, a fuzzy term) it judges the whole query word just as it would judge that word at index time, so the result is what indexing that spelling produces (thenormalizecontract). Under an always-true condition (the test), or any condition that does not depend on the spelling, that is the document's indexed term. A spelling-sensitive condition can take a different branch: underwhenTerm(t -> "Apache".contentEquals(t)), with the fixnormalize("APACHE")staysAPACHE, soAPACHE~1gets 0 hits while the indexedApachewas lower-cased, just as the term queryAPACHEgets 0 (executed). - Fragments. Prefix, wildcard and regexp text is not a whole word, and the three differ: a prefix query normalizes the stem before
*(LucofLuc*), a wildcard query each literal chunk between wildcards separately (ÉlandnofÉl?n), a regexp query the whole pattern, operators included (Apa.*of/Apa.*/). WithProtectedTermFilterFactoryprotectingLucene, stockLuc*matches the unlowercased protected term and the fixed version (which lower-cases the unprotected stemLuc) does not, while unprotected prefixes such asApa*start to match. UnderwhenTerm(len > 2){lowercase, asciifolding}the fix makesÉla*and[Élan TO Élan]hit, butÉl?nstill gets 0 hits, because the chunkÉlfails the length condition. - Only
normalize()is forwarded, notcreate(). An inner filter without anormalize()override, such astruncate, is still skipped, as it is outside a block. For the exactProtectedTermFilterFactoryjavadoc example (truncatewithprefixLength4, thenlowercase), the fix restoresApa*and/Apa.*/(0 to 1 hit), but[Apache TO Apache],APACHE~1andApach?stay at 0, as they do for the same two filters without the block. - Attributes. A custom condition that reads tokenizer-set attributes (type, keyword) sees default values in the one-token normalize stream; the two stock conditions read only the term text. Worth a javadoc sentence.
- Cost. None at index time;
normalizebuilds one more wrapper per call.
What the checks validated
- Scratch worktree at
645d4fe14a20, gradle, JDK 25: the test fails on stock with assertions on and off; with the fix it passes together withTestCustomAnalyzer,TestConditionalTokenFilter,TestProtectedTermFilterFactoryandTestProtectedTermFilter(5 suites, 45 tests), assertions on and off. - The whole
:lucene:analysis:commontest task: 340 suites, 1910 tests, 0 failures, 18 skipped, assertions on and off;:lucene:analysis:common:check -x testpasses with the PR copy of the test. - Earlier: the independent reproduction's own test and the GPT-5.6 reviewer's tests pass with the same logic; with it the hit table's conditional row is all 1s.
- The diff applies cleanly to the 10.6.0 source (
patch --dry-run); only main was built and tested.
Ignore the condition at normalization time and chain the inner factories' normalize() directly.
Trade-offs
Simpler, and fragments then behave like the plain filter. But it breaks full protected terms: with Lucene protected (indexed as Lucene), [Lucene TO Lucene] normalizes to lucene and misses, where stock finds it today. Executed in the fact check: for both protected-term forms [Lucene TO Lucene] and Luc* drop from 1 hit to 0, while every Apache query hits.
State in the when()/whenTerm() and ProtectedTermFilterFactory javadocs that filters inside a conditional block are not applied by Analyzer.normalize, and change the ProtectedTermFilterFactory example.
Trade-offs
No code change, and the silent misses stay for every existing configuration.
Downstream servers that build field analyzers from these factories, for example a Solr field type with ProtectedTermFilterFactory and wrappedFilters="...,lowercase", most likely show the same misses (by code reading of Solr's TokenizerChain.normalize on apache/solr main 9ba1a7d42e4b, 2026-10-30; not run).
A planning pass looked for siblings of earlier normalize gaps and read that ConditionalTokenFilterFactory has no normalize(). An executed probe on stock main confirmed it: inside whenTerm(len > 2){lowercase, asciifolding}, Éla* got 0 hits against 1 for the plain chain. An AI finder built a with/without-block differential and reduced it to one test.
The method in full142 words
Method: non-formal (code reading plus executed probes; the finder tagged it semi-formal, and the first signal decides).
- The hunt's round-18 planners took a family-siblings lens on
Analyzer.normalizedelegation gaps, one level above other normalize rows (analyzers whosenormalizeomits a filter), and read thatConditionalTokenFilterFactoryhas nonormalize(). - A public-API probe on stock main
645d4fe14a20(2026-10-30) witnessed it: insidewhenTerm(len > 2){lowercase, asciifolding}the index holdselan,normalize("Élan")returnsÉlan, andÉla*,Él?nand[Élan TO Élan]get 0 hits while the plain chain gets 1 each;ProtectedTermFilterFactorybehaves the same. A skeptic re-ran it. - A hunt unit built the differential (term, range, fuzzy, regexp, prefix and wildcard queries, with and without the wrapper, stock and with a fix), wrote a public-API JUnit, ran it on releases, and the no-noise gate reduced it to the one-assertion test above.
No prior report found in GitHub issues and PRs (incl. the migrated JIRA archive), JIRA, the Lucene and Solr mailing lists or the web, searched 2026-10-30 and re-checked for this page; nearest are the feature issue #9320 and earlier, different normalize gaps fixed as bugs.
Searches5 searches
No prior public report was found in the documented searches: none says that Analyzer.normalize skips the filters inside a when()/whenTerm() block or a ProtectedTermFilterFactory, or describes the symptom. Gaps: keyword search only; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, apache/solr, apache/lucene-solr, two downstream search servers, global) | 2026-10-30 | three automated runs (51, 51 and 45 queries, incl. the migrated JIRA archive and commits) and 40 manual searches on the class names and symptom phrasings | no report of this defect |
| Open apache/lucene PRs | 2026-10-30 | the changed files of all 410 open PRs; PRs created since 2026-10-29 re-checked for this page | none touches the fix site |
| JIRA (LUCENE, SOLR) | 2026-10-30 | 10 JQL searches (ProtectedTermFilter, ConditionalTokenFilter, whenTerm, TokenizerChain normalize) | no report; the class-name queries return only LUCENE-8273, the feature |
| Mailing lists | 2026-10-30 | 24 searches over dev@, java-user@ and issues@ (Lucene) and the Solr user and dev lists | no report; one Solr thread about a different conditional-filter crash |
| Related items (read) | 2026-10-30 | #9320, #9543, #8657, #9234, #8482, #14416, #12613 | the feature, the normalize() redesign, earlier different normalize gaps fixed as bugs, a committer recommending the affected configuration, and an open PR for another factory |
Introduced with the feature: LUCENE-8273 "Add ConditionalTokenFilter" (#9320, 2018-05-11, first release 7.4.0); LUCENE-8497 (8.0.0) moved normalization to TokenFilterFactory.normalize() without adding it here. Every release run from 7.4.0 to 10.6.0 and main is affected; 7.3.1 has no such API.
Versions tested5 rows
Introduced by LUCENE-8273 "Add ConditionalTokenFilter" (#9320, JIRA patch workflow, no PR), Alan Woodward, 2018-05-11: 7f13e5642924 on branch_7x (first release 7.4.0) and 1ce3ebadbd60 on master (first release 8.0.0). ProtectedTermFilterFactory came in the same release.
- 7.4.0 to 7.7.3:
CustomAnalyzer.normalizeapplied onlyMultiTermAwareComponentfactories, and the conditional factory was not one. - 8.0.0 onward: LUCENE-8497 (
65486442c4a, 2018-11-19, #9543) replaced that withTokenFilterFactory.normalize()and its identity default, and added no override here. - Between the executed releases the fix-site code changed only by formatting, SPI-name, package-split,
@sinceand instanceof-pattern commits. Upstream main716d6f216f52(2026-10-29) has no change at the fix site.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the one-test repro fails with assertions on and off (gradle and the standalone runner) and passes with the fix; the main() forms fail too, -ea and -da (fact check) |
| 10.6.0 | affected | the one-test repro and the finder's JUnit fail, -ea and -da (release jars) |
| 9.12.3, 10.0.0, 10.5.2 | affected | the finder's JUnit fails (-da) |
| 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0 | main() form | normalize("Lucene") is Lucene and the parsed range is f:[Lucene TO Lucene]; the fact check's index-and-query run shows the index holds lucene (term query Lucene 1 hit, [Lucene TO Lucene], Luc*, Apa* 0 hits, -da) |
| 7.3.1 | no API | compile error: no whenTerm / ConditionalTokenFilter |
An independent reproducer, cross-model reviews (OpenAI GPT-5.6, refute and intended lenses), an intended-behaviour devil's advocate and an adjudication all say real; the adjudication confirmed it with high confidence after re-running the reproducer's test with a new seed. A credibility audit and the no-noise gate kept it.
Checks and verdicts330 words
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit fails on main (-ea, -da), 10.6.0, 10.5.2, 10.0.0 and 9.12.3; passes with the fix; the 44 upstream tests of these classes pass with and without it; the differential covers term, range, fuzzy, regexp, prefix and wildcard. |
| Independent reproducer | real | Own test from the claim (whenTerm(t -> true){lowercase}, FooBar, FooBa*) fails on main, 10.6.0, 10.5.2 and 9.12.3; its control without the wrapper passes; the fix makes it pass. |
| cross-model review, refute lens (OpenAI GPT-5.6, executing) | real, high | Own tests (MiXeD vs indexed mixed, a prefix query 0 vs 1) fail on main and pass with the fix; intended case moderate, only the fragment trade-off of the fix. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium | Could not run code; agrees on the root cause; noted that regexp passes the whole pattern to normalize, so it is a fragment case. |
| Intended-behaviour devil's advocate | real, medium-high | Re-ran the finder's JUnit on main (fails); no javadoc, changelog, test or review thread excludes conditional blocks. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test on main with a new seed: fails for the stated reason. |
| audit and no-noise gate | keep; claim | The audit re-ran the earlier two-assertion form on main with a fresh seed (fails); the gate reduced the repro to the one assertion above and ran it with -ea and -da (fails) and with the fix (passes). |
| fact checks of this page | no factual error; wording corrected | An independent fact check re-ran the gradle commands (assertions on and off), the release jars, the fix with the whole module, a four-parser probe, option B and the old-release main() forms: no factual error. A cross-model fact check (OpenAI GPT-5.6, reading only) agreed the defect is real and flagged overstated wording (what the condition sees, "every" unprotected word, the trigger); corrected on this page. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 518 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,234 words
- Registry title
- CustomAnalyzer.normalize skips the token filters inside a when()/whenTerm() block or a ProtectedTermFilterFactory (ConditionalTokenFilterFactory has no normalize()), so query-parser range, fuzzy, prefix, wildcard and regexp terms are not lower-cased or folded like the indexed term and silently miss documents
- Area
- analysis-common / CustomAnalyzer conditional blocks (ConditionalTokenFilterFactory, ProtectedTermFilterFactory) and Analyzer.normalize, which the query parsers use for multi-term queries
- Priority
- Medium, rank 122: Multi-term queries with capital or accented letters silently miss documents in every release since 7.4.0, but only when a normalizing filter sits inside an opt-in CustomAnalyzer conditional or protected-term block.
- Impact class
- silent wrong results
- Impact note
- Applications that put a normalizing filter (lowercase, asciifolding, a language normalization filter) inside a CustomAnalyzer when()/whenTerm() block or a ProtectedTermFilterFactory (the factory's own javadoc example wraps lowercase, and a committer recommended this configuration on #14416) and accept range, fuzzy, prefix, wildcard or regexp syntax through the classic, flexible, simple or complex-phrase query parser silently get too few hits whenever the query term has a letter the block would have lower-cased or folded; plain term and phrase queries are unaffected, no scale or unusual parameter is needed, it is deterministic with -ea and -da, and every release from 7.4.0 to 10.6.0 and main has it.
- Summary
- You build a CustomAnalyzer whose lowercase filter sits inside a conditional block (withTokenizer("whitespace").whenTerm(t -> t.length() > 2).addTokenFilter("lowercase").endwhen(), or a ProtectedTermFilterFactory wrapping lowercase as in that factory's javadoc), index 'Lucene' (stored as the term 'lucene') and search with the classic QueryParser range [Lucene TO Lucene]. You expect Analyzer.normalize("f", "Lucene") to return 'lucene', 'the representation that it would have in the index', and the query to find the document, as both do for the same chain without the condition. Instead normalize returns 'Lucene' unchanged and the query finds 0 documents with no error, and Apa*, Apach?, APACHE~1 and /Apa.*/ miss 'Apache' the same way, because ConditionalTokenFilterFactory overrides create() but not normalize(), so CustomAnalyzer.normalize never reaches the normalize() of the wrapped filters.
- Introduced
- 7f13e5642924aa7f97e21b059553cfd6b5b56c21 (branch_7x, first released in 7.4.0) and its master twin 1ce3ebadbd60d4485145c71b48330d0aabde77ad (first released in 8.0.0), both 'LUCENE-8273: Add ConditionalTokenFilter', author romseygeek, author date 2018-05-11 (JIRA patch workflow, migrated as apache/lucene#9320, no PR) [read: the defect is born with the feature: create() wraps the inner factories and nothing wraps their normalization; exec: 7.3.1 lacks the API, 7.4.0 fails]. In 7.x CustomAnalyzer.normalize applied only MultiTermAwareComponent factories and ConditionalTokenFilterFactory was not one; LUCENE-8497 (65486442c4a, 2018-11-19, apache/lucene#9543, 8.0.0) replaced that with TokenFilterFactory.normalize(), whose default is the identity, and added no override here, so the outcome stayed the same. ProtectedTermFilterFactory (renamed from TermExclusionFilterFactory in 97490ac7c66 / d91273ddf0b, 2018-05-20, also LUCENE-8273) shipped in the same release (2018-05-11)
- First affected version
- 7.4.0 [exec: the release-portable main() form of the repro gives normalize('Lucene') = 'Lucene' and the parsed range f:[Lucene TO Lucene] while the index holds 'lucene']; 7.3.1 and earlier are not affected [exec: the API does not exist, compile error 'cannot find symbol: method whenTerm']
- Affected versions
- every release from 7.4.0 through 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main 645d4fe14a20; never fixed (upstream main 716d6f216f52 has no change at the fix site). [exec] the JUnit repro (seed DEADBEEF) fails 1 of 1 on main (-ea and -da), 10.6.0 (-ea and -da, SHA-1-verified release jars), 10.5.2, 10.0.0 and 9.12.3 (-da); the main() form fails on 7.4.0, 7.7.3, 8.0.0, 8.11.4 and 9.0.0 (the JUnit cannot compile on 9.0.0, which has no org.apache.lucene.tests.util); the independent reproduction's own JUnit fails on main (-ea and -da), 10.6.0, 10.5.2 and 9.12.3. [read] the fix-site code has no functional change between these releases (reformatting, SPI-name, package-split, @since and instanceof-pattern commits only). Not new in 10.6.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-30, read-only; the prior-report record, verdict new; re-checked): three scripted prior-report searches (the unit's 51 queries with 1,951 hits, then 51 and 45 queries with 307 and 337 distinct hits over apache/lucene issues and PRs incl. the migrated JIRA archive, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web); 40 manual GitHub searches (apache/lucene, apache/solr, apache/lucene-solr, elastic/elasticsearch, opensearch-project/OpenSearch, global); 10 JIRA JQL searches; 24 mailing-list searches incl. the Solr lists; 11 web searches; the changed files of all 410 open apache/lucene PRs (none touches the fix site); upstream commits on the fix-site files (last: b59848c7049, #15842, author and committer date 2026-04-02, an instanceof cleanup); PRs created since 2026-10-29 (#16938-#16952) checked, none about analysis normalization. Related, not reports: #9320 (LUCENE-8273, the feature; no normalize discussion), #9543 (LUCENE-8497, the normalize() redesign; no mention of these factories), #8657 (LUCENE-7606) and #9234 (LUCENE-8186), earlier different CustomAnalyzer.normalize gaps fixed as bugs, #8482 (LUCENE-7429, DelegatingAnalyzerWrapper did not delegate normalization, fixed), #14416 (rmuir recommends wrapping a normalizer in ProtectedTermFilter; reach, not a report), #12613 (open, adds normalize() to PatternReplaceFilterFactory, another factory)
- Lucene commit tested
- main
645d4fe14a20(2026-10-28; upstream main716d6f216f52of 2026-10-29 has the sameConditionalTokenFilterFactory.java,CustomAnalyzer.javaandTokenFilterFactory.java): the one-test repro through gradle in a scratch worktree, stock and with the fix, plus the wholelucene/analysis/commontest task and its format and lint checks, assertions on and off (the worktree was removed after the runs); the standalone JUnit runner on main and on the 10.6.0 release jars (4ae946e5a9b),-eaand-da; the finder's JUnit on 9.12.3, 10.0.0 and 10.5.2 and amain()form on 7.4.0, 7.7.3, 8.0.0, 8.11.4 and 9.0.0 (7.3.1 has no such API). An independent fact check re-ran the gradle commands, the release jars and the fix, and added a four-parser probe, option B, the workaround and an index-and-querymain()on 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0 and main. JDK OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConditionalTokenFilterFactory.java:61-74 (create() wraps the inner factories; no normalize() override)lucene/core/src/java/org/apache/lucene/analysis/TokenFilterFactory.java:101-108 (normalize() default returns the input unchanged)lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:170-177 (normalize() calls filter.normalize() on the top-level factories only)lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:203 (normalize contract)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilterFactory.java:38-47 (javadoc example wraps lowercase)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConditionalTokenFilterFactory.java:61-74, :76-85 (create() and inform() forward to the inner factories; no normalize() override)lucene/core/src/java/org/apache/lucene/analysis/TokenFilterFactory.java:101-108 (normalize() default returns the input)lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:170-177 (normalize over top-level factories), :564-581 (whenTerm), :689-694 (endwhen)lucene/analysis/common/src/java/org/apache/lucene/analysis/core/LowerCaseFilterFactory.java:61-63 (normalize delegates to create)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:550, :556, :646, :656, :683, :712, :729 (normalize call sites)lucene/queryparser/src/java/org/apache/lucene/queryparser/complexPhrase/ComplexPhraseQueryParser.java:61, classic/QueryParser.java:72, simple/SimpleQueryParser.java:573, :605
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilterFactory.java:38-60 (javadoc examples wrap lowercase)https://github.com/apache/lucene/pull/14416 (rmuir, 2025-03-27; comments read through the GitHub API)lucene/core/src/java/org/apache/lucene/analysis/AnalyzerWrapper.java:90 (wrapTokenStreamForNormalization)https://github.com/apache/solr/blob/9ba1a7d42e4b/solr/core/src/java/org/apache/solr/analysis/TokenizerChain.java (lines 140-143; read 2026-10-30, not run)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:202-213 (normalize contract)lucene/core/src/java/org/apache/lucene/analysis/TokenFilterFactory.java:101-108lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilterFactory.java:38-48lucene/analysis/common/src/test/org/apache/lucene/analysis/custom/TestCustomAnalyzer.java:523-622 (normalization and condition tests)lucene/CHANGES.txt (LUCENE-7606 under 6.4.0 Bug Fixes, LUCENE-8186 under 7.4.0 Bug Fixes, LUCENE-7429 under 6.3.0 Bug Fixes, LUCENE-8273, LUCENE-8497)
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:87-95 (class javadoc example: lowercase outside the block), :571-575 (whenTerm condition reads the term)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilter.java:51-54 (condition reads the term)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:646, :656, :683, :712, :727-730 (what text each query type normalizes)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TruncateTokenFilterFactory.java (no normalize() override)
- TestConditionalFilterNormalize.java (one JUnit test, public API):
repro/LFV-1063/TestConditionalFilterNormalize.java(36 lines)
Made separately from this page, from the repro and the differential probe on main 645d4fe14a20.
assets/LFV-1063/bug.png(518 KB)