DatasetSplitter (module lucene/classification) copies the documents of an index into a training, a test and a cross-validation index. With fieldNames left out it copies every stored field, and it rebuilds each copy with one field type: a stored, indexed, tokenized TextField. Lucene does not allow bytes in a tokenized field.
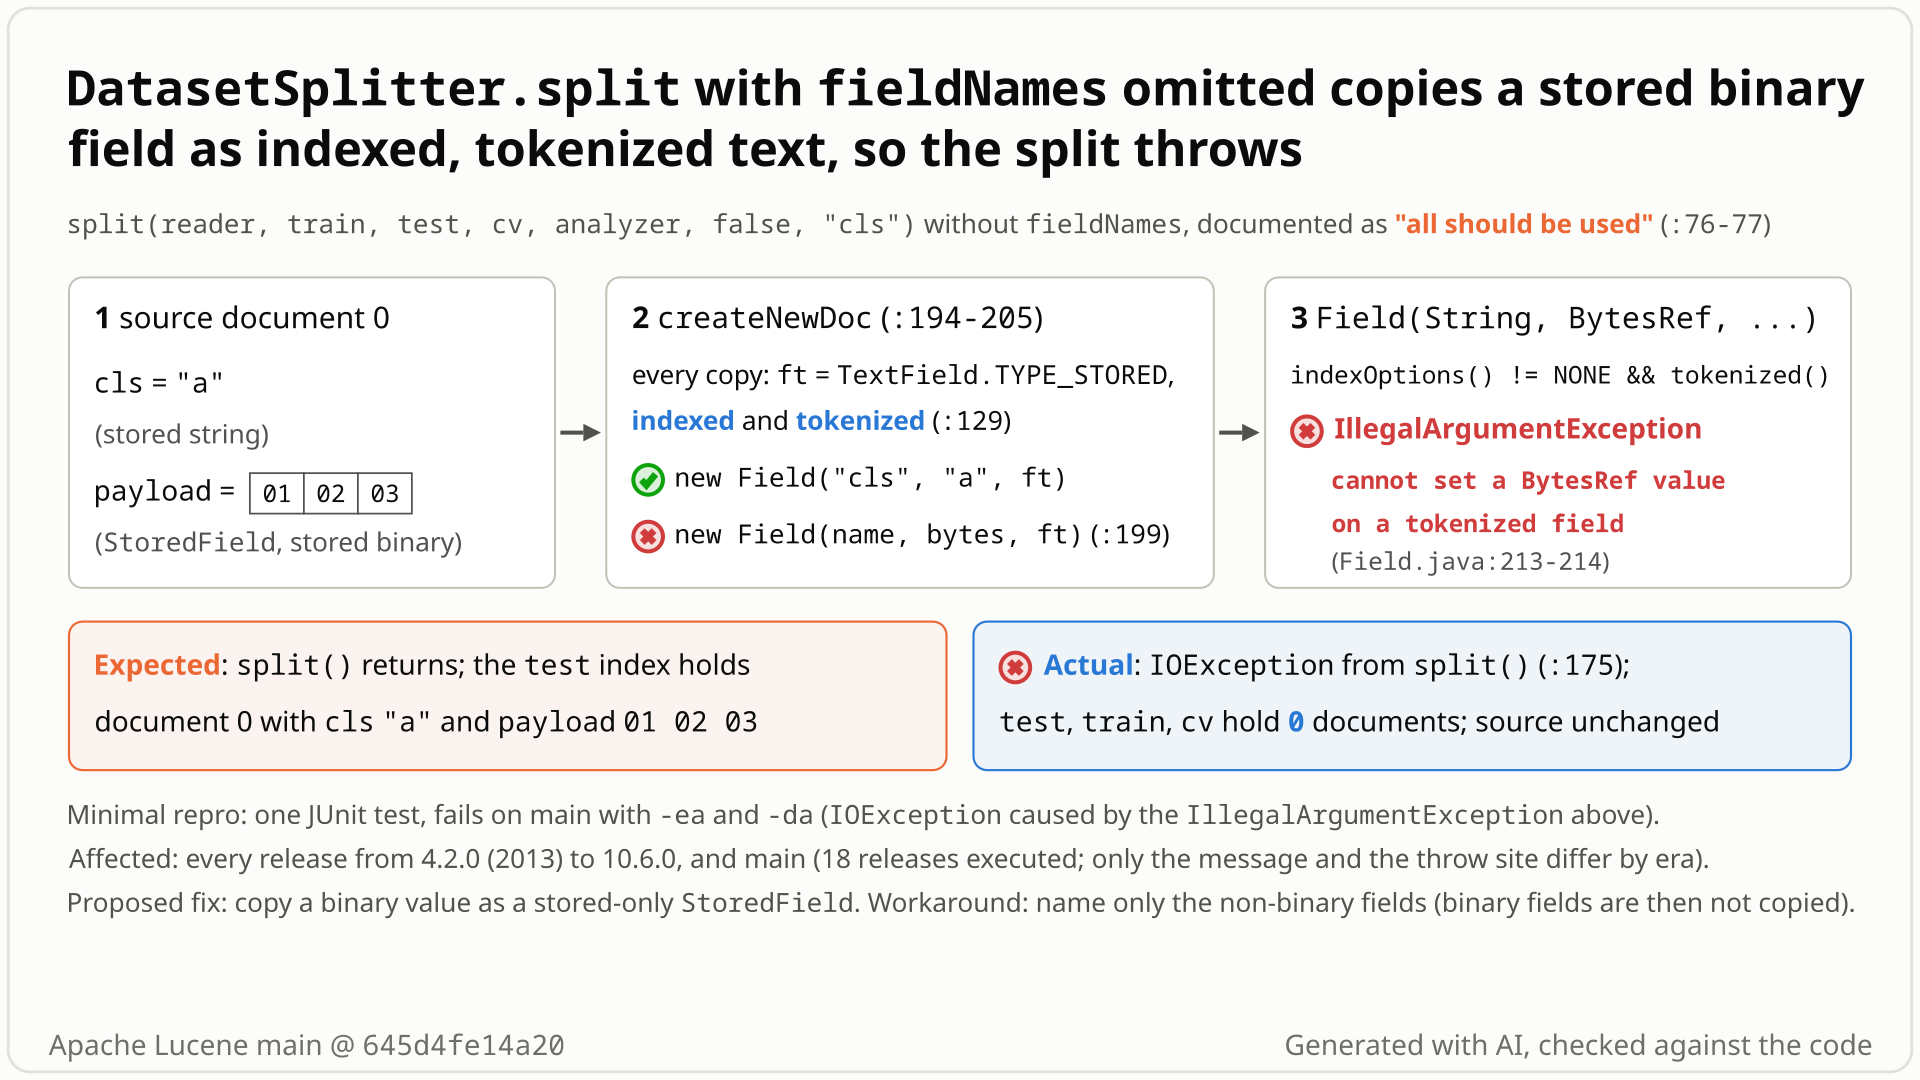
DatasetSplitter.split with fieldNames left out; the bytes meet the shared tokenized TextField type and split() throws; with the fix the bytes are copied as a stored-only field. Select the still to open it at full size. Generated with AI, checked against the code.- Index one document: a class label
cls= "a" as sorted doc values, and a stored binary fieldpayload= {1, 2, 3}. - Split it with
new DatasetSplitter(0.5, 0).split(reader, train, test, cv, analyzer, false, "cls"), leavingfieldNamesout; the javadoc says all fields "should be used" then. - You expect the split to succeed: with a test ratio of 0.5 the document goes to the test index, payload and all.
- Instead
split()throwsIOException: IllegalArgumentException: cannot set a BytesRef value on a tokenized field, with assertions on and off; in this one-document example no document reaches any output. Only binary values fail: with stored strings and numbers the split runs without error. - Why: every copy gets one field type, an indexed, tokenized
TextField.TYPE_STORED, andnew Field(name, bytes, thatType)is illegal in core. Copying the bytes as a stored-onlyStoredFieldfixes it.
Users of the opt-in lucene/classification module who split an index with fieldNames left out, when any document stores a binary value (a payload, an id kept as bytes). No setting or scale is needed: one document shows it. It fails at once and loudly, the source index is unchanged, and naming only the non-binary fields avoids it.
Mechanism, terms and numbers692 words
DatasetSplitter.split copies the documents of an index into a training, a test and a cross-validation index for classifier work. Its fieldNames parameter lists the "names of fields that need to be put in the new indexes or null if all should be used". In the all-fields mode it copies every stored value, and it rebuilds each copy with one field type, new FieldType(TextField.TYPE_STORED): indexed, tokenized and stored. For a binary stored value it calls new Field(name, bytes, ft), which core Field rejects with "cannot set a BytesRef value on a tokenized field". split() wraps that in an IOException at the first copied document that stores a binary value, such as new StoredField("payload", new byte[] {1, 2, 3}), so in that mode such an index cannot be split. The branch was written for binary values in the very first version (2012) and has never worked: every release from 4.2.0 to 10.6.0 and main fails, only the message changed. It is loud and deterministic, needs the opt-in classification module, leaves the source index alone, and naming only the non-binary fields avoids it. Copying the bytes as a stored-only StoredField fixes it.
- Split:
new DatasetSplitter(testRatio, crossValidationRatio).split(reader, training, test, cv, analyzer, termVectors, classFieldName, fieldNames...)groups the source documents by class and sends each one to the test, cross-validation or training index (DatasetSplitter.java:80-180). fieldNames: "names of fields that need to be put in the new indexes ornullif all should be used" (:76-77). Leaving it out (or passingnullor an empty array) is the all-fields mode.- Stored binary field:
new StoredField(name, byte[])ornew StoredField(name, BytesRef), "a stored-only field with the given binary value" (StoredField.java:65-77,:95-107). Reading the document back gives a field whosebinaryValue()is the bytes. - Tokenized field: a field whose value goes through the analyzer into terms.
TextField.TYPE_STOREDis indexed (DOCS_AND_FREQS_AND_POSITIONS), tokenized and stored (TextField.java:40-43). Bytes cannot be analyzed, so core forbids aBytesRefvalue on such a type.
splitbuilds one type for every copied field:FieldType ft = new FieldType(TextField.TYPE_STORED), plus term vectors with positions and offsets iftermVectorsis true (DatasetSplitter.java:128-134).- For each source document it calls
createNewDoc(:150). With no names (:187) it loops over every stored field (:195) and picks by value kind: reader (:196-197), binary (:198-199), string (:200-201), numeric as text (:202-203). - The binary branch adds
new Field(field.name(), field.binaryValue(), ft)(:199). The constructor throws "cannot set a BytesRef value on a tokenized field" for an indexed, tokenized type (Field.java:213-214). Its javadoc states a broader rule, "@throws IllegalArgumentException if ... the field's type is indexed()" (:196-197); the code accepts an indexed type that is not tokenized, as inStringField(String, BytesRef, Store).ftis tokenized, so it is rejected either way. splitcatches it and throwsnew IOException(e)(DatasetSplitter.java:174-175), at the first document with a stored binary value.- Same cause, other messages: with
termVectors = truethe offsets check fires first, "It doesn't make sense to index offsets on binary fields" (Field.java:209-211, executed); naming the binary field infieldNamesgives "value must not be null", becausestringValue()is null for bytes (DatasetSplitter.java:191,Field.java:244-245, executed).
The hunt's check over six stored-value kinds and both copy modes, on stock main and with the hunt's fix (B, executed). A cell is OK when split() returns and exactly one document arrives across the three outputs; the check does not compare the copied values (numbers are rebuilt as text). With the recommended fix A, the named binary cell still throws (executed by the fact check).
| stored value | fieldNames left out | binary field named in fieldNames | with the hunt's fix (B) |
|---|---|---|---|
| string, int, long, float, double | OK | OK | OK |
binary {1, 2, 3} | throws: cannot set a BytesRef value on a tokenized field | throws: value must not be null | OK (both modes, with the hunt's two-branch fix) |
The repro uses the first binary cell: one document, fieldNames left out.
Exposure and likelihood264 words
- Who is exposed. Callers of
DatasetSplitter.splitin its all-fields mode (fieldNamesomitted,nullor empty) on an index where any document has a stored binary field. No production code in Lucene calls the class; onlyTestDataSplitterandTest20NewsgroupsClassificationdo. - Default vs opt-in. The all-fields mode is the documented "all should be used" case and is tested upstream (
testSplitOnAllFields). No index setting or scale is needed. On main the exception is thrown while the copy is built, before it reaches a writer, so neither the codec nor the analyzer plays a part; the test uses a plainIndexWriterConfigwith the test framework'sMockAnalyzerand randomized codec. - What breaks. In that mode the call throws at the first document it copies that stores a binary value, deterministically, with assertions on and off, so the split never completes. Documents copied before that one stay in the outputs, because the writers are closed, and so committed, in
finally(DatasetSplitter.java:178): a fact-check probe found the training index holding 1 document after the failure when a stored-string document came first. In the one-document repro no document reaches any output. - Not affected. The source index (only read;
split()does close the reader it is given), stored text, string and numeric values, and named mode that leaves the binary fields out (the cross-model reviewer ran it: passes). - How likely. Certain once a stored binary field meets the all-fields mode, but the utility has few users, text-classification corpora mostly store text, the failure is loud with an obvious workaround, and no public report was found in 13 years.
One JUnit class for lucene/classification, one test, public API only. It indexes one document with a sorted doc-values label and a 3-byte stored field, splits with fieldNames left out and reads the bytes back from the test index. It fails on main, 10.6.0, 10.5.2 and 9.12.3, with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification.utils;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.document.StoredField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestDatasetSplitterStoredBinaryField extends LuceneTestCase {

  public void testSplitAllFieldsWithStoredBinaryField() throws Exception {
    Analyzer analyzer = new MockAnalyzer(random());
    try (Directory dir = newDirectory();
        Directory train = newDirectory();
        Directory test = newDirectory();
        Directory cv = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        Document doc = new Document();
        doc.add(new SortedDocValuesField("cls", new BytesRef("a")));
        doc.add(new StoredField("payload", new byte[] {1, 2, 3}));
        w.addDocument(doc);
      }
      // expected: split (fieldNames omitted = all fields) copies the bytes; actual: IOException
      // "cannot set a BytesRef value on a tokenized field"
      new DatasetSplitter(0.5, 0)
          .split(DirectoryReader.open(dir), train, test, cv, analyzer, false, "cls");
      try (DirectoryReader r = DirectoryReader.open(test)) {
        assertEquals(
            new BytesRef(new byte[] {1, 2, 3}),
            r.storedFields().document(0).getBinaryValue("payload"));
      }
    }
  }
}
cp $REPRO/TestDatasetSplitterStoredBinaryField.java $LUCENE/lucene/classification/src/test/org/apache/lucene/classification/utils/
cd $LUCENE && ./gradlew :lucene:classification:test --tests TestDatasetSplitterStoredBinaryField -Ptests.seed=5EED1071 -Ptests.asserts=true
# also with -Ptests.asserts=false; the failure does not depend on the seed (keep it for reproducibility)
- Expected
- The split succeeds, and the test index holds the document with
payload= {1, 2, 3}. - Observed
IOException: IllegalArgumentException: cannot set a BytesRef value on a tokenized fieldfromDatasetSplitter.createNewDoc(DatasetSplitter.java:199); in this one-document example no document reaches any output.
More files, environment, full output269 words
The class extends LuceneTestCase and sits in DatasetSplitter's package next to TestDataSplitter; nothing package-private is used. It uses a plain IndexWriterConfig and MockAnalyzer, passes :lucene:classification:check -x test and runs unchanged on 10.6.0, 10.5.2 and 9.12.3. The failure does not depend on the seed (the exception comes from the field type, not from the randomized test setup); keep the seed for reproducibility.
The last assertion checks that the 3 bytes arrive, which is what the suggested fix gives. If a maintainer prefers to skip binary fields instead, only that assertion changes.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also 10.6.0, 10.5.2 and 9.12.3 (release jars), test unchanged |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (plain Java; only this platform was run) |
cp $REPRO/TestDatasetSplitterStoredBinaryField.java $LUCENE/lucene/classification/src/test/org/apache/lucene/classification/utils/
cd $LUCENE && ./gradlew :lucene:classification:test --tests TestDatasetSplitterStoredBinaryField -Ptests.seed=5EED1071 -Ptests.asserts=true
# also with -Ptests.asserts=false; the failure does not depend on the seed (keep it for reproducibility)
# gradle, stock main 645d4fe14a20, -Ptests.asserts=true (the same with false); left out: the seed frame and the echoed test output before the last line
TestDatasetSplitterStoredBinaryField > testSplitAllFieldsWithStoredBinaryField FAILED
    java.io.IOException: java.lang.IllegalArgumentException: cannot set a BytesRef value on a tokenized field
        at org.apache.lucene.classification.utils.DatasetSplitter.split(DatasetSplitter.java:175)
        at org.apache.lucene.classification.utils.TestDatasetSplitterStoredBinaryField.testSplitAllFieldsWithStoredBinaryField(TestDatasetSplitterStoredBinaryField.java:48)
        Caused by:
        java.lang.IllegalArgumentException: cannot set a BytesRef value on a tokenized field
            at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.document.Field.<init>(Field.java:214)
            at org.apache.lucene.classification.utils.DatasetSplitter.createNewDoc(DatasetSplitter.java:199)
            at org.apache.lucene.classification.utils.DatasetSplitter.split(DatasetSplitter.java:150)
            ... 1 more
1 test completed, 1 failed

# the same failure through the standalone runner on main (-ea, -da), 10.6.0 (-ea, -da) and 10.5.2 (-da)
# 9.12.3 (-da): java.io.IOException: java.lang.IllegalArgumentException: Field must have either TokenStream, String, Reader or Number value; got stored,indexed,tokenized<payload:[1 2 3]>
# with the fix: 1 of 1 passes- The javadoc:
fieldNamesis "nullif all should be used"; the only precondition is sorted doc values on the class field. createNewDochas a branch for binary values (DatasetSplitter.java:198-199), which strongly suggests they were meant to be copied; it never worked.StoredField(name, byte[])is ordinary public API; the searches found no test, javadoc, CHANGES or MIGRATE entry expecting the exception.
The full argument238 words
- Contract. "@param fieldNames names of fields that need to be put in the new indexes or
nullif all should be used" (DatasetSplitter.java:76-77). The only stated precondition concerns the class field: "this must be indexed with sorted doc values" (:74-75). Nothing limits the kinds of stored fields in the source. - The code's own intent.
:198-199is a branch for binary values, which strongly suggests they were meant to be copied, not refused (the branch alone cannot prove the author's intent). - Core is right, the caller is not.
Fielddocuments the rejection (Field.java:196-197). The splitter makes that illegal call itself, for legal input. - Not a write failure.
split()declares "@throws IOException if any writing operation fails on any of the indexes" (DatasetSplitter.java:78); here nothing failed to write, the copy built an illegal field. - Tests.
TestDataSplitterindexes text fields and sorted doc values only;Test20NewsgroupsClassificationstoresStringFieldandTextFieldvalues. These are the only current tests that use the class, so no current upstream test stores a binary field for it, and none expects the exception; with the fix the whole module suite stays green. - History. The branch is in the very first
DatasetSplitter(3459b28334e, LUCENE-4345, 2012), when the constructor already refused an indexedBytesRef("Fields with BytesRef values cannot be indexed"). LUCENE-4345 never discusses binary values; the recorded searches found no CHANGES or MIGRATE entry that records a limit.
The devil's-advocate check153 words
The strongest "intended" case (the devil's-advocate verifier built it and rejected it; the cross-model reviewer rated it weak): the splitter is a text-classification helper, not a general index copier. It rebuilds every value as a stored TextField and turns numbers into text (DatasetSplitter.java:202-203), so binary values are out of scope; core documents the exception; split() declares IOException; and naming only the text fields works.
Why it fails: no documented limit was found, and the code's own binary branch points the other way. Core documenting the rejection puts the defect in the splitter, which builds the illegal field. The workaround does not make the documented "all" mode work: that mode can never succeed once a document it copies stores a binary field. The recorded searches found no test, issue, CHANGES or MIGRATE entry that treats the exception as expected. Every reviewer rated the bug real, and the adjudication confirmed it (Low).
Recommended Copy a binary value as a stored-only StoredField (fix A)
Copy a binary value as a stored-only field: in createNewDoc's all-fields branch, add new StoredField(field.name(), field.binaryValue()) instead of new Field(..., ft) (one line plus an import). The repro then passes, and TestDataSplitter, the whole lucene/classification suite (assertions on and off) and check -x test pass with it.
 import org.apache.lucene.document.FieldType;
+import org.apache.lucene.document.StoredField;
 import org.apache.lucene.document.TextField;
@@ createNewDoc, all-fields branch
         } else if (field.binaryValue() != null) {
-          doc.add(new Field(field.name(), field.binaryValue(), ft));
+          // a binary value cannot be indexed as text: copy it as a stored-only field
+          doc.add(new StoredField(field.name(), field.binaryValue()));
         } else if (field.stringValue() != null) {
All options and trade-offs4 options · 597 words
One fix was built and validated in a scratch worktree of 645d4fe14a20; the hunt validated a two-branch variant with its standalone runner. The other options are listed with their trade-offs.
In createNewDoc's all-fields branch (DatasetSplitter.java:198-199), copy the bytes with new StoredField(field.name(), field.binaryValue()) (StoredField.java:105) instead of a Field with the shared tokenized type. Text, string, numeric and reader values are unchanged.
 import org.apache.lucene.document.FieldType;
+import org.apache.lucene.document.StoredField;
 import org.apache.lucene.document.TextField;
@@ createNewDoc, all-fields branch
         } else if (field.binaryValue() != null) {
-          doc.add(new Field(field.name(), field.binaryValue(), ft));
+          // a binary value cannot be indexed as text: copy it as a stored-only field
+          doc.add(new StoredField(field.name(), field.binaryValue()));
         } else if (field.stringValue() != null) {
Trade-offs
- The copy is stored, not indexed. The
DocumentthatStoredFields.document()returns carries no indexing metadata (keeping it would need a separate lookup of the reader's field infos), and bytes cannot be tokenized anyway. Core does allow an indexed, non-tokenized binary term (StringField(String, BytesRef, Store)), so a maintainer may prefer an explicit policy for binary values. StoredFieldhas its own type, so the fix also works withtermVectors = true(executed side probe: stock throws "It doesn't make sense to index offsets on binary fields", the fix passes). The binary copy then gets no term vectors (it is stored only), while the parameter says "trueif term vectors should be kept".- Named mode is left as it is: naming a binary field still throws "value must not be null" (
DatasetSplitter.java:191), the line LFV-681's fix changes, so fix A covers the all-fields mode only (the 12-case check gives 11 of 12 with it). The two diffs touch different lines and apply cleanly withgit applyin either order (executed).
What the checks validated
- Gradle, JDK 25, scratch worktree of
645d4fe14a20: the test fails 1 of 1 on stock with assertions on and off; with the fix, the test plusTestDataSplitterpass (2 suites, 3 tests), the whole:lucene:classification:testpasses with assertions on and off (13 suites, 44 tests, 1 skipped@Monster, 0 failures each), and:lucene:classification:check -x testpasses. - Standalone runner with the fix shadowed: the test 1 of 1 (
-ea,-da); thetermVectors = trueside probe 1 of 1.
Move the per-value copy into a helper that copies a binary value as new StoredField(name, bytes), and call it from both the named and the all-fields branch. It also fixes the named-mode binary case.
Trade-offs
A larger diff, and it rewrites DatasetSplitter.java:191, the line LFV-681's fix changes; it is the better shape for one change that fixes both bugs (together with LFV-681's getFields(fieldName) loop).
What the checks validated
By the hunt, with the standalone runner: the repro passes, upstream TestDataSplitter 2 of 2, the 12-case value-kind check 12 of 12; the independent reproducer's and the cross-model reviewer's own tests pass with it. Not run through gradle or the whole module.
Drop the binary branch, so binary stored fields are not copied.
Trade-offs
The split succeeds, but the bytes the caller asked for ("all should be used") are silently left out; the repro's last assertion would become "the document arrives".
Say in the fieldNames javadoc that stored binary fields must be left out by naming the other fields.
Trade-offs
No behaviour change; the dead branch and the crash stay.
The Lucene.NET port of DatasetSplitter has the same binary-value branch, unreported.
An AI finder reading the classification module noticed that createNewDoc's branch for binary values builds a field that core always rejects, and confirmed it with a JUnit on main and four releases. A second unit reduced it to one test and checked six stored-value kinds in both copy modes: only the two binary cases throw.
The method in full132 words
Method: non-formal: code reading, then executed tests. A hunt unit (classification), 2026-10-26.
- The finder read
createNewDoc's binary branch next to the sharedTextField.TYPE_STOREDtype, wrote a JUnit, saw it fail on main, 10.5.2, 9.12.3, 9.5.0 and 9.4.2, and recorded it as a lead. - The adjudication (2026-11-01) re-ran the lead, reduced it to one JUnit with one document, and ran a bounded differential: six stored-value kinds (string, binary, int, long, float, double) x both copy modes (
fieldNamesleft out or naming the field), on stock main and with its fix (B). On main only the 2 binary cells throw; with fix B 12 of 12 pass (with the recommended fix A, 11 of 12). - Independent verifiers, a cross-model reviewer, an adjudication and an audit then re-ran it (see the checks below).
No prior report found (searched 2026-11-01/02): 254 logged queries over GitHub issues, PRs and commits, JIRA, the mailing lists, downstream projects, the web and the changed files of every open PR. The nearest items are other DatasetSplitter issues about class grouping and counting.
Searches4 searches
None of the hits is the same bug. The nearest items are listed below.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, lucene-solr, solr, lucenenet, Elasticsearch, OpenSearch, all of GitHub) | 2026-11-01/02 | three runs of the scripted prior-report search (55, 51 and 53 queries: the code site, the three version-specific messages, other phrasings) and 52 manual searches, including recent created/updated filters; every body and comment of the 68 module:classification issues and PRs | no report; #8251, #8453 and #8642 are about class grouping and counting; #12942 is a different split() failure |
| Open PRs | 2026-11-01/02 | the changed files of all 411 open apache/lucene PRs, and the PRs and issues updated since 2026-10-28 | #16847 is the only one touching DatasetSplitter.java (Math.toIntExact(maxDoc())); createNewDoc untouched |
| JIRA, mailing lists and the web | 2026-11-01/02 | 9 JIRA queries (LUCENE, including all 47 modules/classification issues, SOLR, LUCENENET); 14 lists.apache.org queries (dev@, java-user@, issues@, commits@, general@, Lucene.NET lists); 10 web queries | no report; only JIRA and commit notices and generic StoredField questions |
| Nearest items (read) | 2026-11-01/02 | #5411 / LUCENE-4345, #8251 / LUCENE-7196, #8453 / LUCENE-7400, #8642 / LUCENE-7591, #12942, #16847, #12053, #7051 / LUCENE-5989, lucenenet #27 and #1261 | the introducing issue (no binary discussion), class-counting fixes, a different test failure, core Field changes that explain the message per version, and the .NET port, which has the same branch |
Present since the class was written, 3459b28334e (LUCENE-4345, 2012), so in every release from 4.2.0 (2013) to 10.6.0 and in main. It never worked: 15 releases and main were executed and all fail; only the message changed, in 5.2.0 and 10.0.0. Not fixed upstream.
Versions tested9 rows
Introduced by 3459b28334e (trunk, 2012-11-29, svn r1415060, LUCENE-4345 / #5411, "added utility class for creating training / test / cv index from a single index"; no pull request), whose first split() already had the binary branch with the TextField.TYPE_STORED copy type. The release line got it through the branch_4x backport 21e86983ed4 (2013-02-20, LUCENE-4781 / #5846); first release 4.2.0. Later commits only reformatted, renamed or moved the binary-branch lines (c83fac62889 LUCENE-4345, 24c46305bd8 LUCENE-6971, 112078eaf90 LUCENE-7196); 7f8b7ffbcad (LUCENE-9570) and 47f8c1baa2e (#11998) changed createNewDoc but not those lines. Two core changes moved the throw site and the message, not the outcome: LUCENE-5989 dropped the constructor check, so indexing failed instead (trunk 249d0d25fec, first released in 6.0.0; branch_5x backport fd23211957a, 2015-04-11, first released in 5.2.0); #12053 (9ab324d2bed, 2023, first released in 10.0.0) added today's check.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | this doc's test fails 1 of 1 (gradle and the standalone runner, assertions on and off): cannot set a BytesRef value on a tokenized field |
| 10.6.0, 10.5.2 | affected | this doc's test fails, the same message (10.6.0 with assertions on and off) |
| 10.0.0 | history repro | cannot set a BytesRef value on a tokenized field, at the Field constructor |
| 5.2.0 to 9.12.3 | history repro | executed 5.2.0, 5.5.5, 6.0.0, 6.1.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3: Field must have either TokenStream, String, Reader or Number value, during indexing; this doc's test fails the same way on 9.12.3 |
| 4.2.0 to 5.1.0 | history repro | executed 4.2.0, 4.10.4, 5.0.0, 5.1.0: Fields with BytesRef values cannot be indexed, at the Field constructor |
| 4.2.0 with the binary branch copying a StoredField | one-line fix | passes: the test index holds the document and its 3 bytes |
| 4.1.0 | no API | no classification module and no DatasetSplitter class |
| main with fix A | not affected | this doc's test 1 of 1; the whole classification suite passes |
upstream main f815e679bf6, branch_10_6 | code reading | DatasetSplitter.java identical to 645d4fe14a20's: on main last changed in bc7deedc092 (#15499, 2025-12-11, unrelated), on branch_10_6 in its backport 3546354f82f |
An independent reproducer, a cross-model review (OpenAI GPT-5.6, executed), a devil's-advocate verifier, an adjudication and an audit agree on the root cause; each re-ran a failing test. This doc's gradle runs reproduced it on main 645d4fe14a20 and validated the fix.
Checks and verdicts293 words
Every executed check reproduced the same exception from the same line, DatasetSplitter.java:199, and every one that ran the fix saw it pass.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Reduced the first lead to one JUnit: fails on main (assertions on and off), 10.6.0, 10.5.2 and 9.12.3. The 12-case value-kind check: only the 2 binary cases throw on main; 12 of 12 pass with its fix (B). |
| independent reproducer | real | Own JUnit written from the claim only (one document; checks that exactly one copy with the bytes is found across the three outputs): fails on main (assertions on and off), 10.6.0, 10.5.2 and 9.12.3; passes with the fix. |
| cross-model review, refute lens | real (high) | OpenAI GPT-5.6, executed: its own public-API test with a LeafReader and ByteBuffersDirectory fails with assertions on and off while a stored-string control passes; naming the binary field fails, leaving it out passes; its 4 tests pass with the fix; intended argument weak. |
| devil's advocate | real (high), Low | Re-ran the repro on main (assertions on and off) and rejected every intended, documented, misuse or unreachable argument. |
| adjudication | confirmed, Low | Re-ran the repro on main with assertions on and off. |
| audit | confirmed | Re-ran the repro with a new seed (A0D17004, assertions on): fails as stated. |
| the version-history runs | 4.2.0 to main | A version-portable repro (the older split() signature before 6.1.0) on 15 releases from 4.2.0 to 10.6.0 and main: all fail, in three message eras; 4.1.0 has no module; 4.2.0 with a one-line fix passes. |
| this doc | reproduced; fix validated | The test through gradle and the standalone runner on main, 10.6.0, 10.5.2 and 9.12.3; fix A through the whole classification suite and check -x test. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 374 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,629 words
- Registry title
- DatasetSplitter.split in its all-fields mode (fieldNames omitted) throws at the first document with a stored binary field, because it copies the bytes into an indexed, tokenized TextField-type field that Field rejects
- Area
- classification / utils: DatasetSplitter (split, createNewDoc all-fields copy of a stored binary value)
- Priority
- Low, rank 669: DatasetSplitter's documented all-fields mode throws at the first stored binary field in every release since 4.2.0. It is deterministic but loud, in a little-used offline classification helper with an easy workaround, so it is Low.
- Impact class
- minor
- Impact note
- Anyone who runs DatasetSplitter.split (lucene/classification, an offline helper that builds training, test and cross-validation indexes) in its documented all-fields mode on a source index where some document has a stored binary field, such as a StoredField(name, byte[]) payload, gets an IOException at the first such document, in every release since 4.2.0, with the default IndexWriterConfig, codec and analyzer, -ea and -da alike and at any size; the failure is loud and deterministic, the source index is not changed, and naming only the non-binary fields in fieldNames avoids it.
- Summary
- You split an index into training, test and cross-validation indexes with DatasetSplitter.split and leave fieldNames out, which the javadoc documents as 'all [fields] should be used', and a document of the source index has a stored binary field such as new StoredField("payload", new byte[] {1, 2, 3}). You expect the split to succeed and keep the bytes; createNewDoc even has a branch written for binary values. Instead split() throws an IOException wrapping IllegalArgumentException 'cannot set a BytesRef value on a tokenized field', because every copied field gets the indexed, tokenized type TextField.TYPE_STORED and the core Field constructor refuses a BytesRef value on such a type, so no split of such an index is possible in that mode.
- Introduced
- 3459b28334e2f3103336c0485b3f21da6dbaeeb9 (trunk, svn r1415060, 2012-11-29, '[LUCENE-4345] - added utility class for creating training / test / cv index from a single index'; no PR, it predates GitHub PRs; the issue is LUCENE-4345 = #5411, which never discusses binary stored fields). The very first DatasetSplitter already rebuilt every copied field with new FieldType(TextField.TYPE_STORED) (indexed, tokenized) and had the branch 'else if (storableField.binaryValue() != null) doc.add(new Field(storableField.name(), storableField.binaryValue(), ft))', and Field(String, BytesRef, FieldType) already threw 'Fields with BytesRef values cannot be indexed' for an indexed type, so the branch could never succeed. Released through the branch_4x backport 21e86983ed427f19cac6c38970f19d743980c735 (svn r1448105, 2013-02-20, 'LUCENE-4781 - backporting classification module to branch_4x', = #5846), which carries the same branch [read: git log, blame and git show in the history clone; exec: 4.2.0 fails, and the same 4.2.0 with only that branch changed to copy a stored-only StoredField passes]. Not a regression. Later commits only reformatted, renamed or moved the branch: c83fac62889 (LUCENE-4345, 2012-12-10, reformat), 24c46305bd8 (LUCENE-6971, StorableField to IndexableField), 112078eaf90 (LUCENE-7196, moved into createNewDoc); 7f8b7ffbcad (LUCENE-9570) and 47f8c1baa2e (#11998, StoredFields) changed createNewDoc but not the branch lines. Two core changes moved the throw site and the message, not the outcome: LUCENE-5989 (trunk 249d0d25fec, branch_5x fd23211957a, first released in 5.2.0) dropped the constructor check, so IndexWriter.addDocument failed instead; #12053 (9ab324d2bed, 2023-01-12, main only, first released in 10.0.0) added the constructor check 'cannot set a BytesRef value on a tokenized field'. (2012-11-29 (trunk commit 3459b28334e); release line: backport 21e86983ed4 on 2013-02-20; first released in 4.2.0 (tagged 2013-03-11))
- First affected version
- 4.2.0 [exec] (2013-03-11, the first release that ships the classification module and DatasetSplitter). There is no last unaffected release: 4.1.0 has no DatasetSplitter (no lucene/classification module in releases/lucene-solr/4.1.0 [read]; lucene-classification 4.1.0 does not exist on Maven Central, HTTP 404 [exec]).
- Affected versions
- Every release that has DatasetSplitter, 4.2.0 through 10.6.0 (released 2026-10-29, 4ae946e5a9b), and main 645d4fe14a20; not fixed. [exec] fails in all three eras of the failure, only the message and throw site differ: 4.2.0-5.1.0 'Fields with BytesRef values cannot be indexed' at the Field constructor (executed 4.2.0, 4.10.4, 5.0.0, 5.1.0); 5.2.0-9.12.3 'Field must have either TokenStream, String, Reader or Number value; got stored,indexed,tokenized<payload:[1 2 3]>' from Field.tokenStream during IndexWriter.addDocument (executed 5.2.0, 5.5.5, 6.0.0, 6.1.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3; the first lead also ran 9.4.2 and 9.5.0); 10.0.0 onwards 'cannot set a BytesRef value on a tokenized field' at Field.<init> from createNewDoc:199 (executed 10.0.0, 10.5.2, 10.6.0, main 645d4fe14a20). The one-test repro fails on main with -ea and -da, on 10.6.0 (-da; the independent reproduction's own test with -ea), 10.5.2 (-da) and 9.12.3 (-da); the history probe (a main() with the same scenario) covers the other releases with -ea. [read] all 120 release tags 4.2.0-10.6.0 in the history clone contain the binary branch with the TextField.TYPE_STORED copy type (8.8.2-8.11.x are not in the clone; 8.11.4 was executed); upstream main f815e679bf6 (2026-11-01) and branch_10_6 7e5aec4370e have a DatasetSplitter.java identical to 645d4fe14a20. Not new in 10.6. All runs on Linux aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (searched 2026-11-01 and 2026-11-02): 254 logged queries: three scripted prior-report searches (55, 51 and 53 queries over GitHub issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web, covering the code site, the three version-specific error messages and other phrasings); 52 manual GitHub search/issues queries (apache/lucene, lucene-solr, solr, lucenenet, Elasticsearch, OpenSearch and all of GitHub, with created/updated filters for the last days); every body, comment and review comment of the 68 module:classification issues and PRs; 9 JIRA queries (LUCENE incl. all 47 modules/classification issues, SOLR, LUCENENET); 14 lists.apache.org queries; 10 web queries; the changed files of all 411 open apache/lucene PRs and the PRs and issues updated since 2026-10-28/30; author dates of every upstream commit to the file. The only DatasetSplitter items upstream are about other things: #5411 / LUCENE-4345 (created the class; none of its comments discusses binary values), #8251 / LUCENE-7196, #8453 / LUCENE-7400 and #8642 / LUCENE-7591 (class grouping and counting), #12942 (a different split() test failure, 'topNGroups must be >= 1'); open #16847 changes only Math.toIntExact(maxDoc()) in the file. #12053 and #7051 / LUCENE-5989 are core Field changes that explain why the message differs by version and do not mention DatasetSplitter. The Lucene.NET port has the same branch, unreported (apache/lucenenet #27 and #1261 are context). Not fixed: upstream main f815e679bf6 and branch_10_6 have no DatasetSplitter.java change since bc7deedc092 (#15499, author date 2025-12-11, unrelated). Re-check (2026-11-02): a GitHub search for 'DatasetSplitter' returns only #8453, #8642 and #12942; 'BytesRef value on a tokenized field' returns nothing; the apache/lucene issues and PRs updated since 2026-11-01 (#16961, #16960, #16896) are unrelated; the last commit to DatasetSplitter.java is still bc7deedc092. Gaps: keyword search cannot prove absence; private reports and chat are not searchable.
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; tested 2026-11-02) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.6.0, 10.5.2 and 9.12.3 release jars. The version-history runs ran a version-portable repro on 15 releases from 4.2.0 to 10.6.0 and on main. The fix was validated in the scratch worktree: the test,TestDataSplitter, the wholelucene/classificationsuite with assertions on and off, and:lucene:classification:check -x test.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:45 (at 645d4fe14a20) (class javadoc 'Utility class for creating training / test / cross validation indexes from the original index'), :74-77 ('classFieldName ... must be indexed with sorted doc values'; '@param fieldNames names of fields that need to be put in the new indexes or <code>null</code> if all should be used'), :129 (ft = new FieldType(TextField.TYPE_STORED), indexed and tokenized), :150 (createNewDoc call), :174-175 (catch Exception, throw new IOException(e)), :182-208 (createNewDoc: named branch :187-193 with new Field(fieldName, field.stringValue(), ft) at :191; all-fields branch :194-205 with the binary branch new Field(field.name(), field.binaryValue(), ft) at :198-199)lucene/core/src/java/org/apache/lucene/document/Field.java:187-214 (at 645d4fe14a20) (Field(String, BytesRef, IndexableFieldType): javadoc :196-197 '@throws IllegalArgumentException if the field name, bytes or type is null, or the field's type is indexed()'; :213-214 'cannot set a BytesRef value on a tokenized field')GitHub, read-only (2026-11-01/02): apache/lucene #5411, #5846, #8251, #8453, #8642, #12942, #12053, #7051, #16847, #15499; apache/lucenenet #27, #1261; gh search 'DatasetSplitter' and 'BytesRef value on a tokenized field'; repos/apache/lucene/issues since 2026-11-01; repos/apache/lucene/commits?path=lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:74-80 (javadoc, split signature), 128-134 (ft), 150 (createNewDoc call), 174-175 (rethrow), 182-208 (createNewDoc: 187, 191, 195-205, 198-199)lucene/core/src/java/org/apache/lucene/document/Field.java:187-214 (Field(String, BytesRef, IndexableFieldType): javadoc 196-197; offsets check 209-211; tokenized check 213-214), 230-257 (Field(String, CharSequence, ...): 244-245)lucene/core/src/java/org/apache/lucene/document/TextField.java:32-43 (TYPE_STORED: DOCS_AND_FREQS_AND_POSITIONS, tokenized, stored)lucene/core/src/java/org/apache/lucene/document/StoredField.java:65-77, 95-107 (stored-only binary constructors)
- Who is affected
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:76-77 (fieldNames javadoc), 178 (closes the source reader)lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:90-92 (testSplitOnAllFields)a Lucene main checkout: git grep -n DatasetSplitter -- 'lucene/*.java' (DatasetSplitter.java, TestDataSplitter.java, Test20NewsgroupsClassification.java only)lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java:102 (DEFAULT_COMMIT_ON_CLOSE = true)
- Why it looks unintended
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:74-78, 198-199, 202-203lucene/core/src/java/org/apache/lucene/document/Field.java:196-197, 213-214lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:59-75 (text fields and sorted doc values only)lucene/classification/src/test/org/apache/lucene/classification/Test20NewsgroupsClassification.java:392-395 (StringField, SortedDocValuesField, TextField)
- Suggested fix
lucene/core/src/java/org/apache/lucene/document/StoredField.java:105; lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:191, 198-199lucene/core/src/java/org/apache/lucene/document/StringField.java:79 (indexed, non-tokenized binary StringField); DatasetSplitter.java:73 (termVectors javadoc)
- TestDatasetSplitterStoredBinaryField.java (lucene/classification, public API):
repro/LFV-1071/TestDatasetSplitterStoredBinaryField.java(56 lines)
A summary diagram (the PNG), made from a separate probe program run on main 645d4fe14a20 with assertions on and off and with the fix as a control. The probe's document is a variant of the repro's: it also stores the label cls as a string, so the pictures show one field copied before the bytes fail; the repro's document has only the sorted doc values label and the bytes, and fails the same way.
assets/LFV-1071/bug.png(374 KB)