suggestWordCombinations suggests a joined word only if it is in the index, and SEPARATOR_TERM marks two neighbours that must not be joined. But each joined word is looked up in the field of the first array element, so a separator in front moves every lookup to the empty field "".
WordBreakSpellChecker(modulelucene/suggest) gives "did you mean" suggestions by joining neighbouring query words (sun flower->sunflower) or by splitting one word.suggestWordCombinations(Term[] terms, ...)takes the query words as terms, each a field and a text, and suggests a joined word only if it occurs in the index at leastminSuggestionFrequencytimes (default 1).SEPARATOR_TERM,new Term("", ""), is a special term you put between two words that must not be joined, for example a required and a prohibited clause.
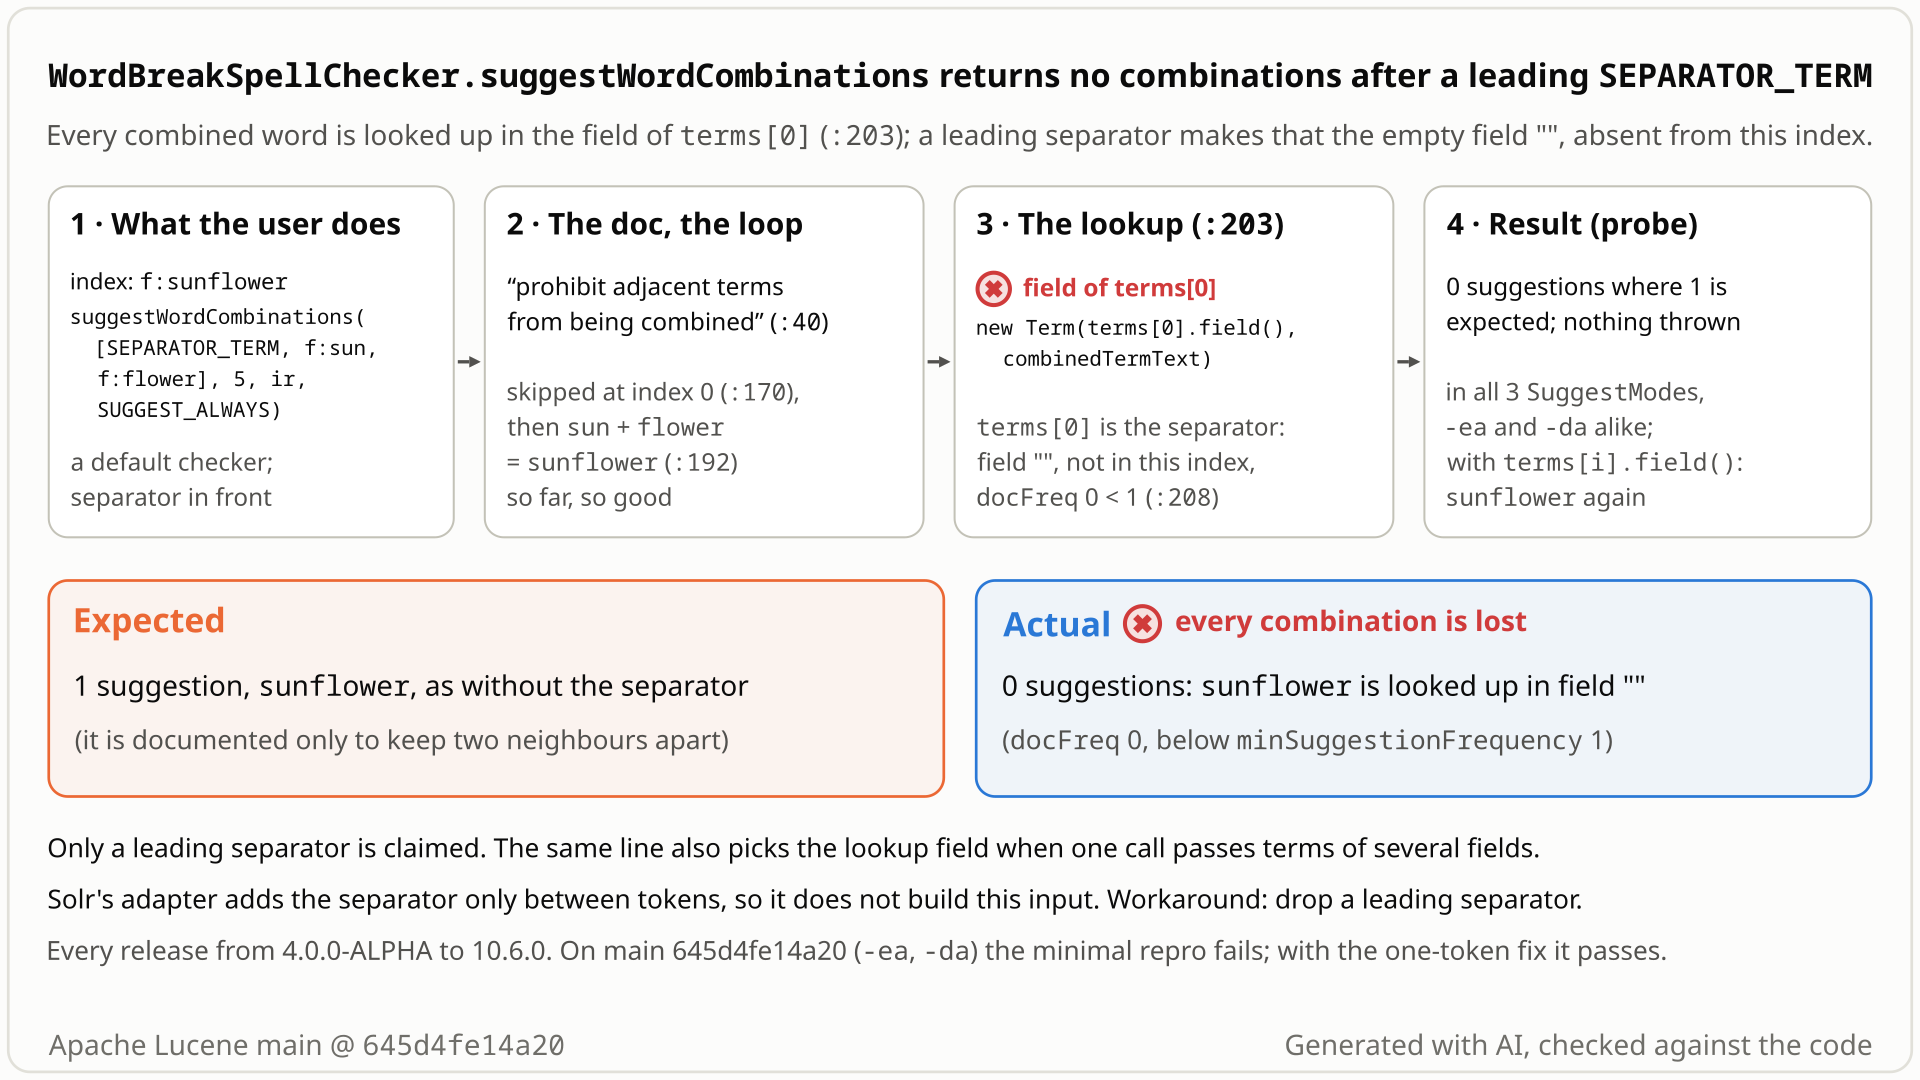
sunflower is looked up in field f (docFreq 1) and suggested; with it, in field "" (docFreq 0) and dropped. Select the still to open it at full size. Generated with AI, checked against the code.- Index one document whose field
fholds the wordsunflower. With a defaultWordBreakSpellChecker, callsuggestWordCombinations([SEPARATOR_TERM, f:sun, f:flower], 5, reader, SUGGEST_ALWAYS). - You expect one suggestion,
sunflower, the same as for[f:sun, f:flower]: the separator only stops two neighbours from being joined, and nothing stands before it. - Instead you get 0 suggestions and no error, with assertions on and off, in every release since 4.0.0-ALPHA (2012) and on main.
- Why: every joined word is looked up in the field of
terms[0]. Here that is the separator's field"", wheresunflowerhas docFreq 0 (infit has 1), so the minimum frequency of 1 drops it. Looking it up in the field of the left word being joined fixes it.
Only applications that call suggestWordCombinations directly and put SEPARATOR_TERM first, for example a loop that adds a separator whenever the clause type changes, which fires before a required first clause (+sun +flower). Solr's adapter guards with i > 0. Suggestions vanish silently; search results are unaffected. Rare; dropping the leading separator avoids it.
Mechanism, terms and numbers510 words
WordBreakSpellChecker.suggestWordCombinations suggests joining neighbouring query words, for example sun + flower -> sunflower, when the joined word is in the index. Its public SEPARATOR_TERM, new Term("", ""), is documented only as the "Term that can be used to prohibit adjacent terms from being combined", and the loop skips a separator at any position, the first included. But every joined word is looked up as new Term(terms[0].field(), combinedTermText), in the field of the first array element, whichever words are being joined. With the separator first, that field is "", which the index does not have: docFreq 0, so the minimum-frequency check (default 1) drops every combination. On an index with one document f:sunflower, [SEPARATOR_TERM, f:sun, f:flower] returns no suggestion, while [f:sun, f:flower] returns sunflower; nothing is thrown, in any SuggestMode. It has been there since the class was added (LUCENE-3523, 4.0.0-ALPHA, 2012) and is in every release up to 10.6.0 and in main. Only direct callers that emit a leading separator are hit (Solr's adapter adds one only after the first token), the effect is missing spelling suggestions only, and the fix is one token: terms[i].field().
- The separator is an ordinary
Termwith an empty field:public static final Term SEPARATOR_TERM = new Term("", "")(:41), documented as the "Term that can be used to prohibit adjacent terms from being combined" (:40). - The loop accepts it anywhere. For each left term
i, a separator is skipped (:169-172); for each right termj, a separator ends the run (:186-189). This generic check also skipsi= 0, so with a leading separator the runs start ati= 1. - The lookup ignores
i. For each runi..jthe joined text is looked up asnew Term(terms[0].field(), combinedTermText)withir.docFreq(combinedTerm)(:203-204). Withterms[0]= the separator, every run is looked up in field"". - The repro's index has no field
"", so docFreq is 0 (in fieldf,sunflowerhas docFreq 1). The checkcombinedTermFreq >= minSuggestionFrequency(:208, default 1 at:34) drops the combination. TheSUGGEST_MORE_POPULARandSUGGEST_WHEN_NOT_IN_INDEXconditions (:206-207) only add requirements, so with default settings every mode returns nothing. WithsetMinSuggestionFrequency(0)the combination comes back with freq 0 instead of 1. Empty field names are legal, so in an index that has a field""the frequency, and whether the word is offered, come from that unrelated field. - Every other lookup uses the term's own field: the original frequencies
ir.docFreq(terms[i])(:159) and thesuggestWordBreakspath (term.field()ingenerateBreakUpSuggestions,:278,:281,:312,:315).:203is the only place that takes the field from position 0.
Side note, not claimed: the same line also decides the field when one call passes terms of several fields: in [f:new, f:york, SEPARATOR_TERM, g:sun, g:flower] the g combination sunflower is counted in field f. No documented contract covers mixed-field calls.
Exposure and likelihood186 words
- Who is exposed. Callers of
WordBreakSpellChecker.suggestWordCombinations(modulelucene/suggest) whose term array starts withSEPARATOR_TERM. A natural way to get there: add a separator whenever the clause type (required, prohibited, plain) changes, with the "previous clause" flags starting at "plain"; for+sun +flowerthe change fires before the first term. - Solr's adapter does not build this input.
WordBreakSolrSpellChecker(apache/solr main, the one adapter inspected) adds the separator onlyif (i > 0 && ...)and builds every term in its one configured field. Other integrations and custom adapters were not inspected. - Default vs opt-in. Default settings, no special analyzer or codec. One document is enough; the index only needs the joined word in the terms' field. The input shape is uncommon, and no upstream test uses
SEPARATOR_TERMat all. - What breaks. That call returns no word-combination suggestions, silently. Search results are not affected; nothing is thrown, written or corrupted.
- How likely. Rare: it needs a direct-API caller that emits a leading separator, and no public report was found. Workaround: drop a leading separator before the call (or add separators only for
i > 0).
One JUnit test for lucene/suggest, public API only: one document with f:sunflower and one call on a default WordBreakSpellChecker. Deterministic and single-threaded; it fails the same way with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.spell;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestWordBreakCombineLeadingSeparator extends LuceneTestCase {

  public void testLeadingSeparatorTerm() throws Exception {
    try (Directory dir = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new StringField("f", "sunflower", Field.Store.NO));
        w.addDocument(doc);
      }
      try (IndexReader ir = DirectoryReader.open(dir)) {
        WordBreakSpellChecker wbsp = new WordBreakSpellChecker();
        Term[] terms = {
          WordBreakSpellChecker.SEPARATOR_TERM, new Term("f", "sun"), new Term("f", "flower")
        };
        CombineSuggestion[] suggestions =
            wbsp.suggestWordCombinations(terms, 5, ir, SuggestMode.SUGGEST_ALWAYS);
        // expected "sunflower", as without the separator; actual: none (looked up in field "")
        assertEquals(1, suggestions.length);
        assertEquals("sunflower", suggestions[0].suggestion().string);
      }
    }
  }
}
cp $REPRO/TestWordBreakCombineLeadingSeparator.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/spell/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests TestWordBreakCombineLeadingSeparator -Ptests.seed=5EED1073 -Ptests.asserts=true
# also with -Ptests.asserts=false; nothing depends on the seed
- Expected
- One suggestion,
sunflower, as for the same call without the separator. - Observed
- 0 suggestions and no error:
AssertionError: expected:<1> but was:<0>, with assertions on and off.
More files, environment, full output228 words
The test is the hunt's minimal repro with its comment line shortened to fit 100 columns; it passes :lucene:suggest:check -x test. It runs unchanged on 10.6.0 and 10.5.2; on 9.x write suggestions[0].suggestion.string (a field there) instead of suggestion().string.
Executed: gradle on main 645d4fe14a20 with assertions on (seed 5EED1073) and off (5EED1074), both fail; the standalone runner on the 10.6.0 release jars with assertions on and off, both fail; the hunt's runs on main, 10.5.2 and 9.12.3 fail the same way. With the one-token fix the test passes. The same call without the leading separator returns sunflower (the audit's control run); it is not part of the repro.
Use the same test as the regression test.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also 10.6.0 and 10.5.2 (release jars), test unchanged; 9.12.3 with the 9.x field access |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (plain Java; only this platform was run) |
cp $REPRO/TestWordBreakCombineLeadingSeparator.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/spell/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests TestWordBreakCombineLeadingSeparator -Ptests.seed=5EED1073 -Ptests.asserts=true
# also with -Ptests.asserts=false; nothing depends on the seed
TestWordBreakCombineLeadingSeparator > testLeadingSeparatorTerm FAILED
    java.lang.AssertionError: expected:<1> but was:<0>
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at junit@4.13.2/org.junit.Assert.failNotEquals(Assert.java:835)
        at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:647)
        at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:633)
        at org.apache.lucene.search.spell.TestWordBreakCombineLeadingSeparator.testLeadingSeparatorTerm(TestWordBreakCombineLeadingSeparator.java:47)
1 test completed, 1 failed

# the same with -Ptests.asserts=false, and on the 10.6.0 release jars with assertions on and off;
# with the fix: 1 test completed, 0 failed- The separator's only documented job is to "prohibit adjacent terms from being combined"; before the first term there is nothing to prohibit.
- The loop's generic separator check also skips index 0, and every other lookup uses the term's own field; only this line uses position 0.
- The "one field per call" argument fits mixed-field input, which is not claimed.
The full argument194 words
- Contract.
SEPARATOR_TERM: "Term that can be used to prohibit adjacent terms from being combined" (WordBreakSpellChecker.java:40). The method javadoc: "To prevent two adjacent terms from being combined (for instance, if one is mandatory and the other is prohibited), separate the two terms with SEPARATOR_TERM" (:136-137). It states the purpose, not a position rule, and says nothing about fields. Nothing in the javadoc,CombineSuggestion, the package docs or CHANGES (LUCENE-3523: "See Javadocs for usage") says all terms must share a field or thatterms[0]chooses it. - The code's own intent. The separator check at
:170runs for everyi, 0 included, so a leading separator is skipped like any other; that shows the input is handled, not that it was designed for. Every other lookup uses the term's own field (:159,:278,:281,:312,:315). - Tests.
TestWordBreakSpellCheckernever usesSEPARATOR_TERM; it passes unchanged with the fix. - History.
terms[0].field()is in the very first version of the class (642b882d5a5, LUCENE-3523, 2012) without a comment; the discussions on #4597 (9 comments) and SOLR-2993 never mention the lookup field or the separator's position.
The devil's-advocate check181 words
The strongest "intended" case (the devil's-advocate verifier built it; the cross-model lenses rated it moderate): the class quietly assumes one field per call. suggestWordCombinations has no field parameter, CombineSuggestion carries no field, every upstream test passes one field, and Solr uses one field and emits the separator only between two tokens. Read that way, terms[0].field() is "the field of this call", and "separate the two terms" means a separator belongs between terms only, so a maintainer may reasonably call a leading separator unsupported.
Why it does not settle the claimed case: it holds for mixed-field input, which is why that case is not claimed. With a leading separator all real terms share one field; terms[0] is not a real term but the class's own constant, which has no field to share. The javadoc gives no position rule, the API accepts the input, and the loop's generic check skips a separator at index 0 like any other. The behaviour is undocumented and surprising: an element documented only to keep two neighbours apart silently turns off every combination when it stands in front.
Recommended Look the joined word up in the field of the run's left term (fix A)
Look the joined word up in the field of the run's left word: new Term(terms[i].field(), combinedTermText) instead of terms[0], one token. The repro then passes, and TestWordBreakSpellChecker, the whole lucene/suggest suite (assertions on and off) and check -x test pass with it.
--- a/lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java
+++ b/lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java
@@ -200,7 +200,7 @@
           minFreq = Math.min(minFreq, origFreqs[j]);
         }

-        Term combinedTerm = new Term(terms[0].field(), combinedTermText);
+        Term combinedTerm = new Term(terms[i].field(), combinedTermText);
         int combinedTermFreq = ir.docFreq(combinedTerm);
All options and trade-offs4 options · 519 words
One fix was built and validated in a scratch worktree of 645d4fe14a20; the other options are listed with their trade-offs. Workaround until a fix ships: drop a leading SEPARATOR_TERM before the call (or add separators only for i > 0, as Solr does), and add one to each of the returned originalTermIndexes() if they are mapped to the caller's own array, because they then count positions in the shortened array ([f:sun, f:flower] gives [0, 1]; the fixed class gives [1, 2] for [SEPARATOR_TERM, f:sun, f:flower]).
Look the joined word up in the field of the run's left term (fix A) (validated by the checks) (recommended)
At WordBreakSpellChecker.java:203, use terms[i].field(). terms[i] is the left term of the run, which is never a separator (:170-172), so a leading separator no longer changes the field. For every one-field call without a leading separator the result is unchanged.
--- a/lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java
+++ b/lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java
@@ -200,7 +200,7 @@
           minFreq = Math.min(minFreq, origFreqs[j]);
         }

-        Term combinedTerm = new Term(terms[0].field(), combinedTermText);
+        Term combinedTerm = new Term(terms[i].field(), combinedTermText);
         int combinedTermFreq = ir.docFreq(combinedTerm);
Trade-offs
- It also changes mixed-field output: whenever a run starts after a
terms[0]of another field, the run is now looked up in its left term's field. A run that crosses fields is still looked up in one field; the fix does not define what such a run should mean. - Open PR #16847 edits the next line (
:204,inttolong), so one of the two needs a trivial rebase.
What the checks validated
- Gradle, JDK 25, scratch worktree of
645d4fe14a20: the test fails 1 of 1 on stock with assertions on and off; with the fix, the test plusTestWordBreakSpellCheckerpass (2 suites, 6 tests) with assertions on and off; the whole:lucene:suggest:testpasses with assertions on and off (32 suites, 237 tests, 7 skipped, 0 failures each);:lucene:suggest:check -x testpasses (checkGoogleJavaFormat,ecjLint,forbiddenApis). - The hunt: the repro and the independent reproducer's and the cross-model reviewers' own tests pass with the fix; in the bounded model the fix alone changes exactly the 416,768 calls whose result differs from the model's reference for this line, and no other.
In the inner loop, break when !terms[j].field().equals(terms[i].field()), as at a separator, so words of two fields are never joined.
Trade-offs
Changes mixed-field output, which has no documented expectation today: a separate design question, not part of the bug fix. Not validated.
Compute the field once before the loop from the first non-separator term.
Trade-offs
Same result as fix A for the claimed case and for one-field calls, and keeps "one field per call" explicit; slightly more code, and mixed-field calls still use one field. Not validated.
Say in the javadoc that the field of terms[0] is used for every combination.
Trade-offs
No behaviour change; the trap stays for callers that build separators in a loop.
Solr's word-break adapter does not build this input (it adds a separator only after the first token and uses one field), and other direct callers can drop a leading separator until a fix ships.
An AI finder building a bounded check of suggestWordCombinations against reference rules had to leave leading separators out, because the real code drops their combinations, and confirmed it with a JUnit. An adjudication unit reduced it to one test and, with a 2.28-million-call comparison, separated it from a neighbouring frequency bug.
The method in full210 words
Method: semi-formal (bounded translation validation of the real class against executable reference models, then executed JUnit tests).
- A hunt unit (spellchecker, dictionaries, word break), 2026-10-26: while building a bounded translation validation of
suggestWordCombinations(400,000 queries, 0 mismatches), it excluded leading separators because the code looks combinations up interms[0].field(), and witnessed that with a JUnit that failed on main. It recorded the lead without claiming it ("needs an unusual input"). - The adjudication (2026-11-02) re-ran the lead, reduced it to one public-API JUnit with one document, and compared the stock jar with four reference models on 2,283,840 calls (40 small random indexes, two fields, leading, inner and trailing separators, every
SuggestMode,minSuggestionFrequency0-3,maxChanges1-2). The jar matches the code-semantics model on every call; against the model's reference for this line (each run looked up in its left term's field) 416,768 calls differ, and the fix alone changes exactly those; of the differing result entries, 29,716 are one-field combinations lost or mis-counted only because of a leading separator, and the rest are in mixed-field calls, which no contract covers. So it is a separate root cause from theminSuggestionFrequencylead at:208. - Independent verifiers, cross-model reviews, an adjudication and an audit then re-ran it (see the checks below).
No public report found in the sources searched (2026-11-02): GitHub issues, PRs and commits, JIRA, the mailing lists, Solr, Elasticsearch, OpenSearch and Lucene.NET, the web and the changed files of every open PR. The nearest items are other WordBreakSpellChecker issues and the Solr integration.
Searches4 searches
None of the hits is the same bug. The nearest items are listed below.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, apache/solr, Elasticsearch, OpenSearch, Lucene.NET) | 2026-11-02 | two runs of a scripted prior-report search (51 queries each) and about 20 manual searches: WordBreakSpellChecker, SEPARATOR_TERM, suggestWordCombinations, CombineSuggestion, "word combinations", "wrong field" and others; the bodies and comments of #4597, #5652, #7299, #12077, #12100 and #4961 | no report; SEPARATOR_TERM, suggestWordCombinations and CombineSuggestion return 0 issue or PR hits |
| Open PRs | 2026-11-02 | the changed files of all 411 open apache/lucene PRs, and every PR updated since 2026-10-31 | #16847 is the only one touching the file; it edits line 204 (int to long) and keeps line 203 |
| JIRA, mailing lists and the web | 2026-11-02 | JIRA REST over LUCENE and SOLR (12 issues read in full); lists.apache.org over six Lucene and Solr lists; web queries | no report; a 2012 collation NPE, configuration questions and javadoc mirrors only |
| Nearest items (read) | 2026-11-02 | #4597 / LUCENE-3523, SOLR-2993, SOLR-8175, #12077, #12100, #7299 / LUCENE-6237, #5652 / LUCENE-4587, #16847 | the introducing issue (no remark on the lookup field), the Solr integration (its adapter adds the separator only when i > 0), other WordBreakSpellChecker fixes and requests, and a PR next to the fix line |
Present since the class was added, 642b882d5a5 (LUCENE-3523, 2012), so in every release from 4.0.0-ALPHA to 10.6.0 and in main; not a regression. Seven releases (4.0.0-ALPHA, 4.0.0, 4.10.4, 8.11.4, 9.12.3, 10.5.2, 10.6.0) and main were executed and all fail; each of the 124 release tags that contain an introducing commit has the line. Not fixed upstream.
Versions tested8 rows
Introduced by 642b882d5a5 (trunk, 2012-05-30, James Dyer, svn r1344318, LUCENE-3523 / #4597, "Add WordBreakSpellChecker to suggest based on word combinations and/or breaks") and its same-day branch_4x commit 99fa008a71e (r1344329), from which the 4.x releases come; no pull request (svn era). The class was born with SEPARATOR_TERM = new Term("", ""), the index-0 skip and new Term(terms[0].field(), ...). LUCENE-4587 (927531255d48, 2012-12-07, first in 4.1.0) rewrote the line from a BytesRef buffer to a String and kept the field, which is why git blame on main shows that commit. 3.6.x has no WordBreakSpellChecker. Upstream main e1faeba08bd (2026-11-02) and branch_10_6 still have the line at :203; the last commit to the file (54283150a81, 2026-06-14) fixed typos only.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | this doc's test fails 1 of 1 through gradle with assertions on and off |
| 10.6.0 | affected | this doc's test fails 1 of 1 with assertions on and off (release jars) |
| 10.5.2 | affected | the test fails 1 of 1 (hunt run) |
| 9.12.3 | 9.x accessor | the test with suggestion.string fails 1 of 1 (hunt run) |
| 4.0.0-ALPHA, 4.0.0, 4.10.4, 8.11.4 | history ports | a version-portable main() with the same call returns 0 suggestions; its no-separator sanity check passes on every version |
| 4.0.0-ALPHA to 10.6.0 (124 release tags) | read | 84 tags contain 642b882d5a5 and 40 contain 99fa008a71e (none both); each of the 124 has new Term(terms[0].field(), ...) exactly once |
| 3.6.0, 3.6.1, 3.6.2 | no API | no WordBreakSpellChecker class |
main with terms[i].field() | fix | the test passes, as do TestWordBreakSpellChecker and the whole lucene/suggest suite |
An independent reproducer, cross-model reviews (OpenAI GPT-5.6, executed), a devil's-advocate verifier, an adjudication and an audit agree on the root cause, and each re-ran a failing test. This doc's gradle runs reproduced it on main 645d4fe14a20 and validated the fix.
Checks and verdicts329 words
Every executed check reproduced the empty result from the same line, WordBreakSpellChecker.java:203, and every one that ran the fix saw it pass. The cross-model reviews ran on an earlier main checkout, ea57360912ed, whose WordBreakSpellChecker.java is byte-identical to 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Reduced the lead to one JUnit: fails on main (assertions on and off), 10.6.0, 10.5.2 and 9.12.3; passes with the fix. The 2,283,840-call model separates this line from the :208 lead. |
| independent reproducer | real | Own test written from the claim, [SEPARATOR_TERM, body:rain, body:bow] with body:rainbow indexed: fails on main (assertions on and off), 10.6.0, 10.5.2 and 9.12.3 while its no-separator control passes; passes with the fix. |
| cross-model review, refute lens | real (high) | OpenAI GPT-5.6, executed: its leading-separator test and an interior-separator mixed-field test fail with assertions on and off; a same-field control passes; the fix passes its tests and the 5 upstream tests. Intended argument moderate. |
| cross-model review, intended lens | real (high) | OpenAI GPT-5.6, executed: its 5-test class fails 4 on main and 10.5.2 with the one-field control passing, and passes 5 of 5 with the fix; re-run on 645d4fe14a20 with the same result. Intended argument moderate (an implicit one-field-per-call design). |
| devil's advocate | real, Low | Replay fails on main (assertions on and off). The one-field design argument holds for mixed-field input but not for a leading separator; only that case is claimed. |
| adjudication | confirmed (high), Low | Re-ran the test on main (fails) and with the fix (passes); a separate root cause from the other WordBreakSpellChecker findings. |
| audit | confirmed (Low) | The audit re-ran the test (fails) and a no-separator control (passes) on main; the repro was checked as one test, one document, deterministic, assertions on and off, and the fix. |
| this doc | reproduced | Gradle on main (assertions on and off) and the standalone runner on 10.6.0 (both) fail; fix A validated with the module's tests and static checks. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 391 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,315 words
- Registry title
- WordBreakSpellChecker.suggestWordCombinations looks every combined word up in the field of terms[0], so a leading SEPARATOR_TERM silently disables all combination suggestions
- Area
- suggest / spell (WordBreakSpellChecker word combinations)
- Priority
- Low, rank 455: With default settings in every release since 4.0, a leading SEPARATOR_TERM silently disables every word-combination suggestion of a WordBreakSpellChecker call. Solr's adapter never builds that input, so only direct API users who put the separator first are hit, and it is Low.
- Impact class
- minor
- Impact note
- Hits only applications that call WordBreakSpellChecker.suggestWordCombinations directly and put the class's own public SEPARATOR_TERM before the first term (for example a separator before every clause, including the first): every word-combination suggestion of that call is silently lost, with default settings, at any index size and with no exception (with terms of several fields in one call the same line counts a combination in the first term's field); Solr's WordBreakSolrSpellChecker never builds this input (it adds the separator only between tokens and uses one field); same behaviour in every release since 4.0.0-ALPHA and on main.
- Summary
- You call WordBreakSpellChecker.suggestWordCombinations with the class's own SEPARATOR_TERM in front of your terms, for example [SEPARATOR_TERM, f:sun, f:flower] on an index that holds f:sunflower, and expect the same 'sunflower' suggestion you get without the separator, because the separator is documented only to stop two adjacent terms from being combined. Instead you get no suggestion and no error: the code looks every combined word up in the field of terms[0], which for a leading separator is the empty field "", where nothing is indexed. The same line also picks the field when one call passes terms of several fields.
- Introduced
- 642b882d5a50721ab88ade17b06cd9e2927745b1 (trunk, svn r1344318, 'LUCENE-3523: Add WordBreakSpellChecker to suggest based on word combinations and/or breaks', by James Dyer; JIRA LUCENE-3523 = apache/lucene#4597; svn era, no pull request) and its same-day branch_4x commit 99fa008a71ef1600bf4217824f7786682432a48c (svn r1344329, the code the 4.x releases ship): the class was born with SEPARATOR_TERM = new Term("", ""), a leading separator skipped as a left term, and new Term(terms[0].field(), ...) for every combination [read: git log -S 'terms[0].field()' on the file finds only these two commits (plus a 2021 repository-note commit in no release), and git log --follow starts at 642b882d5a5]. LUCENE-4587 (927531255d48 trunk / 669fa5d4a6a branch_4x, 2012-12-07, first in 4.1.0) rewrote the line from BytesRef to String but kept terms[0].field(), which is why git blame on main :203 shows 927531255d48. Not a regression. (2012-05-30 (trunk 642b882d5a5 at 15:58Z; branch_4x 99fa008a71e at 16:10Z))
- First affected version
- 4.0.0-ALPHA [exec: 4.x main() port on the Maven Central jars fails 'expected:<1> but was:<0>' while its same-field no-separator sanity check passes]; first GA release 4.0.0 [exec]; 3.6.0, 3.6.1 and 3.6.2 are not affected because they have no WordBreakSpellChecker [read: no such class in any of their jars or tags]
- Affected versions
- every release from 4.0.0-ALPHA through 10.6.0 (released 2026-10-29, 4ae946e5a9b), and main 645d4fe14a20 (unreleased 11.0) [exec: the claimed JUnit fails 1 of 1 'expected:<1> but was:<0>' on main with -ea and -da, on 10.6.0 (Maven Central jars) and on 10.5.2; the same test with the 9.x accessor fails on 9.12.3; version-portable main() ports with a passing sanity check fail on 4.0.0-ALPHA, 4.0.0, 4.10.4 and 8.11.4; the independent reproducer's own test fails on main (-ea, -da), 10.6.0, 10.5.2 and 9.12.3]; the releases in between by a static check of all 124 releases/lucene* tags that contain the introducing commit, each with new Term(terms[0].field(), ...) exactly once [read]. Not new in 10.6 (10.5.2 fails the same test). Not fixed upstream: main e1faeba08bd (2026-11-02) and branch_10_6 still have the line at :203 [read through the GitHub API]. Executed on Linux aarch64 with JDK 25 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-11-02, on top of the finder's search and the independent reproduction's, the intended-behaviour check's and the adjudication's GitHub searches): a scripted prior-report search re-run with 51 queries (16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list, 4 JIRA, 6 web; 211 hits, 0 high); manual GitHub issue and PR searches on apache/lucene (WordBreakSpellChecker, SEPARATOR_TERM, suggestWordCombinations, CombineSuggestion, word combinations, wrong field and others) and on apache/solr, Elasticsearch, OpenSearch and Lucene.NET; the bodies and comments of #4597, #5652, #7299, #12077, #12100 and #4961; JIRA REST over LUCENE and SOLR (12 issues read in full); lists.apache.org over six Lucene and Solr lists; the changed files of all 411 open apache/lucene PRs (only #16847 touches the file, and it keeps line 203 as context); every PR updated since 2026-10-31 and every issue created since 2026-10-29; git log -S over the full history. Refresh (2026-11-02): the 15 apache/lucene PRs updated since 2026-10-31 touch no spell code; searches 'WordBreakSpellChecker' (5 hits: #7299, #12100, #12077, #4597, #5652), 'SEPARATOR_TERM' (0), 'suggestWordCombinations' (0); upstream main e1faeba08bd still has new Term(terms[0].field(), combinedTermText) at :203, and the last commit to the file is 54283150a81 (author date 2026-06-14, typo fixes only). Nearest items, none the same bug: #4597 / LUCENE-3523 (introduced the class; 9 comments, no remark on the lookup field), SOLR-2993 (Solr integration; its adapter adds the separator only when i > 0 and uses one field), #12077 and #12100 (suggestWordBreaks), #7299 / LUCENE-6237 (sort order), #5652 / LUCENE-4587 (non-latin text), SOLR-8175 (Solr token index error), open PR #16847 (changes the adjacent line 204 from int to long; a fix needs a trivial rebase).
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; tested 2026-11-02) through gradle in a scratch worktree with assertions on and off, and the 10.6.0 release jars through the standalone JUnit runner with assertions on and off. The hunt also ran the test on 10.5.2 and (with the 9.x accessor) 9.12.3, and the version-history runs ran version-portable ports on 4.0.0-ALPHA, 4.0.0, 4.10.4 and 8.11.4. The fix was validated in the scratch worktree: the test,TestWordBreakSpellChecker, the wholelucene/suggestsuite with assertions on and off, and:lucene:suggest:check -x test.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java:40-41 (at 645d4fe14a20) (SEPARATOR_TERM javadoc 'Term that can be used to prohibit adjacent terms from being combined', = new Term("", "")), :136-137 (method javadoc 'To prevent two adjacent terms from being combined ..., separate the two terms with SEPARATOR_TERM'), :159 (origFreqs via ir.docFreq(terms[i])), :169-172 (a separator is skipped as a left term at any index, including 0), :186-189 (a separator ends a run as a right term), :203 (new Term(terms[0].field(), combinedTermText): fix site), :208 (combinedTermFreq >= minSuggestionFrequency), :278, :281, :312, :315 (suggestWordBreaks uses term.field())
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java:34 (at 645d4fe14a20) (minSuggestionFrequency = 1), :40-41 (SEPARATOR_TERM javadoc and value), :136-137 (method javadoc), :159 (origFreqs), :169-172, :186-189 (separator handling), :203-204 (lookup in terms[0].field()), :206-208 (mode conditions and minSuggestionFrequency check), :278, :281, :312, :315 (suggestWordBreaks uses term.field())lucene/core/src/java/org/apache/lucene/document/Field.java:81-89 (at 645d4fe14a20) (only a null name is rejected); lucene/test-framework/src/java/org/apache/lucene/tests/index/BasePostingsFormatTestCase.java:1783-1786 (indexes new StringField("", ...))
- Who is affected
apache/solr main solr/core/src/java/org/apache/solr/spelling/WordBreakSolrSpellChecker.java:181-192 (i > 0 guard, new Term(field, ...); read through the GitHub API, 2026-11-02)Lucene main 645d4fe14a20 git grep SEPARATOR_TERM -- lucene (only WordBreakSpellChecker.java)
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java:40-41, (at 645d4fe14a20) :136-137, :159, :169-172, :203, :278, :281, :312, :315
- History
lucene/CHANGES.txt:16295-16297 (at 645d4fe14a20) (LUCENE-3523 under 4.0.0-ALPHA), :14800-14802 (LUCENE-4587 under 4.1.0)a Lucene clone releases/lucene/10.6.0 (4ae946e5a9b) WordBreakSpellChecker.java:203 (same line)
- TestWordBreakCombineLeadingSeparator.java (lucene/suggest, public API):
repro/LFV-1073/TestWordBreakCombineLeadingSeparator.java(52 lines)
A summary diagram (the PNG), made from a separate probe program run on main 645d4fe14a20 with assertions on and off and with the fix as a control.
assets/LFV-1073/bug.png(391 KB)