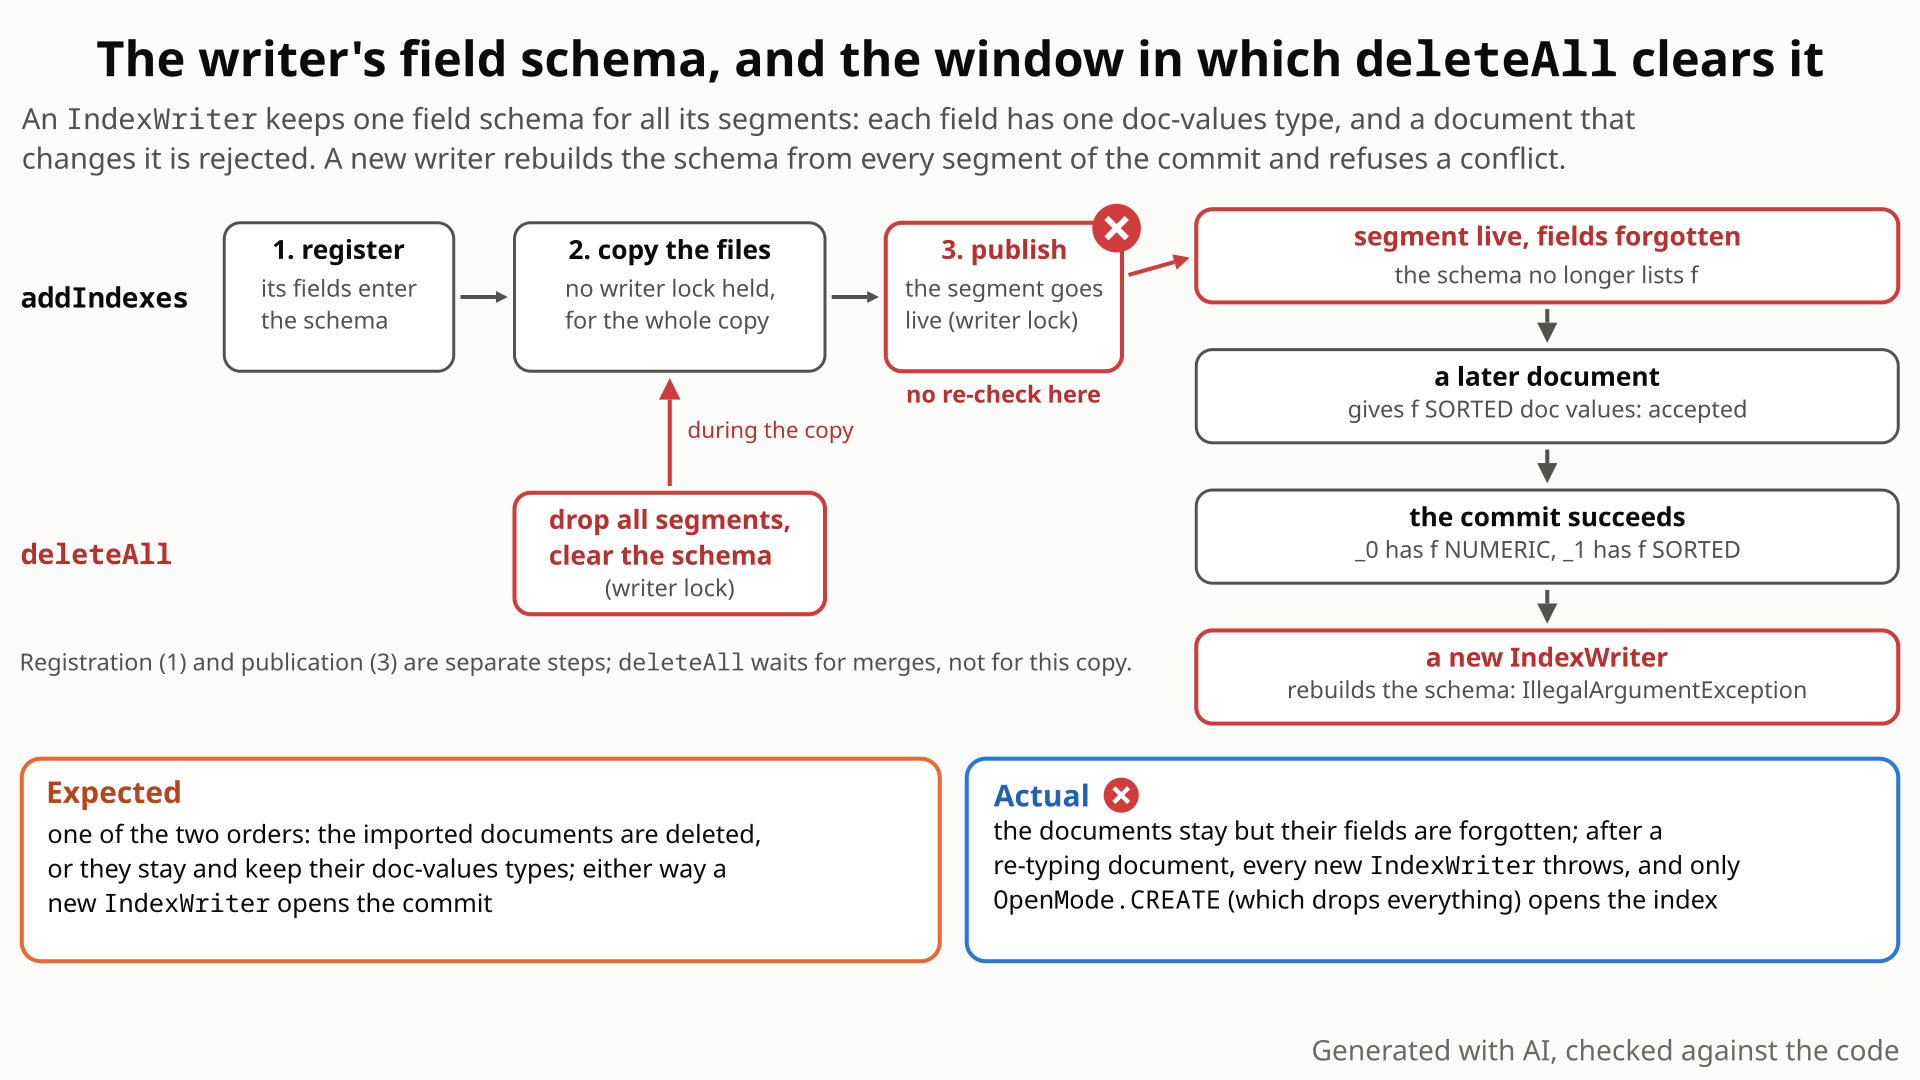
addIndexes(Directory...) registers the incoming fields in the writer-wide schema, copies the files without holding the IndexWriter lock, and only then publishes the segment. deleteAll() can run in between: it clears the schema, but the segment is published afterwards and survives, with fields the writer no longer knows.
- The writer keeps one schema per field name for the whole index (
FieldNumbers): its number and its doc-values type, for examplef= NUMERIC. A document that givesfanother type is rejected withIllegalArgumentException. addIndexes(Directory...)adds the segments of another index by copying their files. Before the copy it registers their fields in that schema, which is also its check that they fit.deleteAll()drops every segment and clears the schema, as if the index were re-created withOpenMode.CREATE; afterwardsfmay take any type.- A new
IndexWriterrebuilds the schema from all segments on disk and refuses an index in which one field has two types.
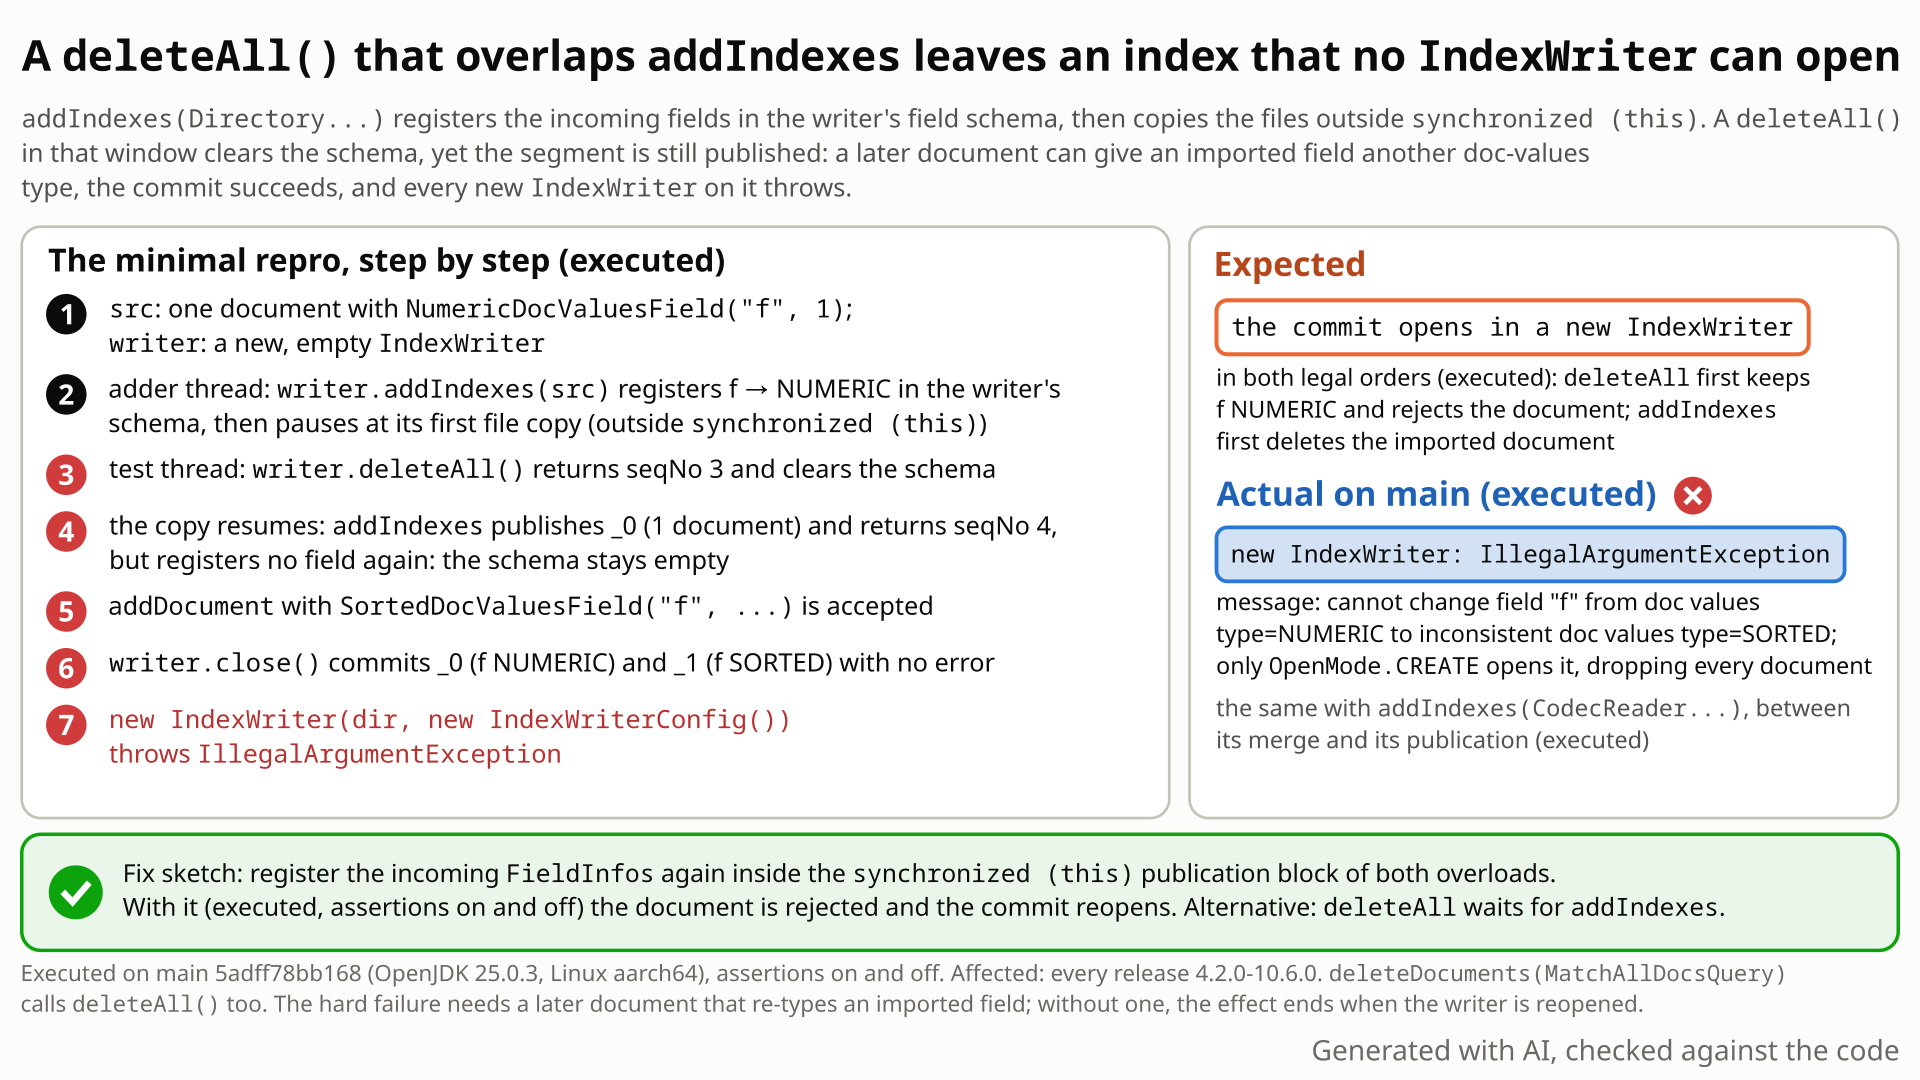
- Thread A calls
addIndexes(src);srcholds one document whose fieldfhas NUMERIC doc values. While A copies the files, the main thread callsdeleteAll(). The writer reportsdeleteAllas sequence number 3 andaddIndexesas 4. - Then add one document with
SortedDocValuesField("f", "x")andclose()the writer, which commits. - You expect one of the two orders. deleteAll first: the added document stays,
fstays NUMERIC and the SORTED document is rejected. addIndexes first: its document is deleted and the SORTED one is fine. Either way the commit holds 1 document and opens again. - Instead both happen: the added document survives and the SORTED document is accepted. The commit holds 2 segments,
fNUMERIC in one and SORTED in the other, andnew IndexWriter(dir, new IndexWriterConfig())throwsIllegalArgumentException: cannot change field "f" from doc values type=NUMERIC to inconsistent doc values type=SORTED. - Nothing failed at commit time and CheckIndex reports the index clean. Only
OpenMode.CREATEopens a writer, and it drops every document.
Applications that call deleteAll() (or delete a MatchAllDocsQuery) while another thread's addIndexes runs, then index a document that re-types an added field. Default configuration, no scale: the window is the whole file copy. Rare, but the commit succeeds silently and leaves an index no writer opens without dropping it.
Mechanism, terms and numbers563 words
IndexWriter.addIndexes(Directory...) registers every incoming field in the writer-wide schema (globalFieldNumberMap.addOrGet, IndexWriter.java:3177-3181 at 5adff78bb168) and copies the segment files (:3183) without holding the IndexWriter lock; only then does it publish the copied segments under synchronized (this) (:3194-3210), without registering or checking the fields again. deleteAll() clears that schema under the same lock (globalFieldNumberMap.clear(), :2800) and waits for running merges, not for an addIndexes(Directory...) call that is copying. A deleteAll() in that window therefore leaves a published segment whose fields the writer no longer knows. A later document can register one of them with another doc-values type; the writer accepts it and the commit succeeds, but the next new IndexWriter rebuilds the schema from every segment (:1274) and throws IllegalArgumentException: cannot change field "f" from doc values type=NUMERIC to inconsistent doc values type=SORTED. Only OpenMode.CREATE, which drops every document, opens a writer on it. addIndexes(CodecReader...) has the same gap between its merge and its publication (:3350-3368). Default configuration, public API, every release since 4.2.0 (2013). The fix registers the incoming fields again inside the publication block.
// IndexWriter.addIndexes(Directory...), main 5adff78bb168           IndexWriter.java:3103
flush(false, true);                                                  // :3119
for (SegmentCommitInfo info : sis) {               // no IndexWriter lock held in this loop
  FieldInfos fis = readFieldInfos(info);                             // :3177
  for (FieldInfo fi : fis) {
    // This will throw exceptions if any of the incoming fields
    // has an illegal schema change
    globalFieldNumberMap.addOrGet(fi);                               // :3181  (1) f = NUMERIC
  }
  infos.add(copySegmentAsIs(info, newSegName, context));             // :3183  file copy: the window
}
synchronized (this) {                                                // :3194
  ensureOpen();
  reserveDocs(totalMaxDoc);                                          // :3199
  seqNo = docWriter.getNextSequenceNumber();                         // :3201
  segmentInfos.addAll(infos);                                        // :3209  (3) publish, no re-check
  checkpoint();
}

// IndexWriter.deleteAll()                                           IndexWriter.java:2750
synchronized (fullFlushLock) {                                       // :2764
  try (Closeable _ = docWriter.lockAndAbortAll()) {                  // :2765  stops indexing threads
    synchronized (this) {
      abortMerges();                // :2771; waits for merges only (:2849), not for addIndexes(Directory...)
      segmentInfos.clear();                                          // :2785
      globalFieldNumberMap.clear();                                  // :2800  (2) f forgotten
return docWriter.getNextSequenceNumber(); // :2801addIndexesregistersfas NUMERIC. The code comment says this registration is its schema check (:3179-3180).deleteAllruns to completion while the files are copied: it drops all segments, then clears the schema. Its stop-the-world covers indexing threads (lockAndAbortAll) and merges, including the merges ofaddIndexes(CodecReader...)(runningAddIndexesMerges,:2849); anaddIndexes(Directory...)call that is copying is in neither.addIndexespublishes the copied segment. It survivesdeleteAll(it is added after the clear), but the schema has nof:getFieldNames()returns[](supplementary probe).- The SORTED document registers
fafresh (field number 0) and is accepted. The commit holdsfas NUMERIC (number 1) in the copied segment and SORTED (number 0) in the new one (probe). - A new
IndexWriterrebuilds the schema from every segment (getFieldNumberMap,:1267-1278,addOrGetat:1274);FieldNumbers.addOrGet(FieldInfos.java:415) rejects the second type (FieldInfo.verifySameDocValuesType,FieldInfo.java:297).
addIndexes(CodecReader...) has the same shape: its merge registers the incoming fields, and the merged segment is published later in a separate synchronized (this) block (:3350-3368) without registering again. deleteAll waits for that merge (LUCENE-9309, #10349) but not for the gap between its end and the publication; a two-method test (one per overload) fails for both on main 5adff78bb168 (assertions off) and earlier on 645d4fe14a20, and passes for both with the fix (supplementary probe).
Exposure and likelihood533 words
- Who is hit. An application that calls
deleteAll(), ordeleteDocuments(MatchAllDocsQuery)(whichIndexWriter.java:1886-1889routes todeleteAll()), on one thread while another thread'saddIndexes(Directory...)is copying files, or while anaddIndexes(CodecReader...)is between its merge and its publication. For the hard failure it then indexes a document that gives one of the added fields another doc-values type;deleteAll's javadoc says doc-values types "are cleared" (:2739), so an application that wipes an index to re-define its schema is the natural case. - Default vs opt-in. Default
IndexWriterConfig, codec, directory, merge policy andConcurrentMergeScheduler; public API only. - Scale and timing. No scale is needed. The
addIndexes(Directory...)window is the whole file copy, so it grows with the source index. Without any hook, a loop built to overlap the two calls (4,000-document source, assertions off, 400 rounds each) lost the schema in 39 of 400 rounds foraddIndexes(Directory...)and 4 of 400 foraddIndexes(CodecReader...)(a supplementary stress run on maina9779ef3c193, not the repro). The loop starts both threads together and varies a short spin delay per round, so it shows the window is reached without a hook, not how often an application would hit it. - Silent, then lasting. Nothing fails when the document is added or committed. Afterwards no
IndexWriteropens the index with the defaultOpenMode(CREATE_OR_APPEND), and by reading the codeAPPENDtakes the same path;OpenMode.CREATEopens it but drops every document. Readers still open the commit (2 documents), butfhas two doc-values types across segments, so no single sort type fits every segment: a sort onfas a number throwsIllegalStateException: unexpected docvalues type SORTED for field 'f' (expected=NUMERIC), and by reading a string sort would fail on the NUMERIC segment. CheckIndex at its default level reports the index clean. A merge of the two segments in the still-open writer (forceMerge(1)) is a tragic event: the writer closes itself with the sameIllegalArgumentException(supplementary probe re-run on5adff78bb168; that run reports 1 of its 5 cases failed because the test framework charged the next case with the merge thread's uncaught exception from theforceMergecase, the same tragicIllegalArgumentException; every case printed its full output). - Without the re-typing document the effect stays inside the open writer and ends when it is reopened:
getFieldNames()(@lucene.experimental) omits the added fields, andupdateNumericDocValue(term, "f", ...)is rejected with "Can't update [NUMERIC] doc values; the field [f] doesn't exist." (same probe). - Not only doc-values types. An earlier test with an indexed field whose index options change (
DOCStoNONE) failed the same way at the reopen, for both overloads ("cannot change field \"f\" from index options=DOCS to inconsistent index options=NONE", maina9779ef3c193). - Bound. Unaligned field numbers alone (new names taking the copied segment's numbers) do not corrupt data:
forceMerge(1)keeps every value with its field and a new writer opens. The damage needs a schema conflict. - How likely. Rare: wiping an index while adding another one into it, then re-typing an added field, is an unusual sequence, and no user report was found. But the window is not a few statements; it is the whole copy.
One JUnit test, one method, public API, default IndexWriterConfig. Two threads, because the overlap is the bug; a FilterDirectory.copyFrom override holds addIndexes at its first file copy until deleteAll() has returned, so it is deterministic. The test accepts either outcome for the SORTED document and only asks that the commit opens again.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import java.io.UncheckedIOException;
import java.util.concurrent.CountDownLatch;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.FilterDirectory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestDeleteAllDuringAddIndexes extends LuceneTestCase {

  public void testDeleteAllWhileAddIndexesCopiesFiles() throws Exception {
    Directory src = new ByteBuffersDirectory();
    try (IndexWriter w = new IndexWriter(src, new IndexWriterConfig())) {
      Document doc = new Document();
      doc.add(new NumericDocValuesField("f", 1));
      w.addDocument(doc);
    }

    CountDownLatch copying = new CountDownLatch(1);
    CountDownLatch resume = new CountDownLatch(1);
    Directory dir =
        new FilterDirectory(new ByteBuffersDirectory()) {
          @Override
          public void copyFrom(Directory from, String s, String d, IOContext ctx)
              throws IOException {
            if (copying.getCount() > 0) {
              copying.countDown();
              try {
                resume.await();
              } catch (InterruptedException e) {
                throw new RuntimeException(e);
              }
            }
            super.copyFrom(from, s, d, ctx);
          }
        };
    IndexWriter writer = new IndexWriter(dir, new IndexWriterConfig());
    Thread adder =
        new Thread(
            () -> {
              try {
                writer.addIndexes(src);
              } catch (IOException e) {
                throw new UncheckedIOException(e);
              }
            });
    adder.start();
    copying.await();
    writer.deleteAll();
    resume.countDown();
    adder.join();

    Document doc = new Document();
    doc.add(new SortedDocValuesField("f", new BytesRef("x")));
    try {
      writer.addDocument(doc);
    } catch (IllegalArgumentException _) {
    }
    writer.close();

    // Expected: a new IndexWriter opens the commit. Actual: IAE, f is both NUMERIC and SORTED.
    new IndexWriter(dir, new IndexWriterConfig()).close();
    dir.close();
    src.close();
  }
}
cd $LUCENE
cp $REPRO/TestDeleteAllDuringAddIndexes.java lucene/core/src/test/org/apache/lucene/index/
./gradlew :lucene:core:test --tests org.apache.lucene.index.TestDeleteAllDuringAddIndexes -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false
- Expected
- A new
IndexWriteropens the committed index, which holds 1 document in either legal order. - Observed
new IndexWriter(dir, new IndexWriterConfig())throwsIllegalArgumentException: cannot change field "f" from doc values type=NUMERIC to inconsistent doc values type=SORTED.
More files, environment, full output378 words
Put the file in lucene/core/src/test/org/apache/lucene/index/ and run the command below. It sits in org.apache.lucene.index like the upstream tests but uses nothing package-private. The latch fires after addIndexes has registered the source's fields and before any file of the new segment exists; no sleeps, no loops.
The test framework picks a random default codec; the failing check is the writer's schema check, not codec code, and the test failed with every seed tried (DEADBEEF here; 1, C0FFEE, 5EED1234, 5EED0491 and 5EED0492 on earlier mains). The file is the minimal repro test with two lint-only edits for ./gradlew check: one over-long comment line shortened, and the unused catch parameter named _.
Regression test: this same test; it passes with the recommended fix. With the "deleteAll waits" alternative (option B) deleteAll() must move to its own thread, since it would wait for the held addIndexes (and the await/join calls, which have no timeout, would then need one). The unnamed catch parameter _ needs Java 22 or later: fine on main (Java 25), but a backport of the test to a Java 21 branch such as branch_10_6 needs a named parameter.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT); the same test fails on the released 10.6.0, 10.5.2 and 9.12.3 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux, aarch64 |
TestDeleteAllDuringAddIndexes > testDeleteAllWhileAddIndexesCopiesFiles FAILED
    java.lang.IllegalArgumentException: cannot change field "f" from doc values type=NUMERIC to inconsistent doc values type=SORTED
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:85C4BDEAC9E99FE6]:0)
        at org.apache.lucene.index.FieldInfo.verifySameDocValuesType(FieldInfo.java:297)
        at org.apache.lucene.index.FieldInfos$FieldNumbers.verifySameSchema(FieldInfos.java:524)
        at org.apache.lucene.index.FieldInfos$FieldNumbers.addOrGet(FieldInfos.java:422)
        at org.apache.lucene.index.IndexWriter.getFieldNumberMap(IndexWriter.java:1274)
        at org.apache.lucene.index.IndexWriter.<init>(IndexWriter.java:1124)
        at org.apache.lucene.index.TestDeleteAllDuringAddIndexes.testDeleteAllWhileAddIndexesCopiesFiles(TestDeleteAllDuringAddIndexes.java:85)

# supplementary probe (not the repro), main 5adff78bb168, assertions off: the two orders and the overlap
PROBE before deleteAll.seqNo=2 addIndexes.seqNo=4          <- deleteAll first
PROBE before SORTED doc for f rejected: cannot change field "f" from doc values type=NUMERIC to inconsistent doc values type=SORTED
PROBE before new IndexWriter(APPEND default) ok
PROBE after deleteAll.seqNo=4 addIndexes.seqNo=2           <- addIndexes first
PROBE after NRT numDocs after both calls=0 leaves=0
PROBE after new IndexWriter(APPEND default) ok
PROBE race deleteAll.seqNo=3 addIndexes.seqNo=4            <- the overlap
PROBE race NRT numDocs after both calls=1 leaves=1
PROBE race getFieldNames()=[]
PROBE race SORTED doc for f accepted
PROBE race DirectoryReader.open(commit) ok, numDocs=2 leaves [maxDoc=1 f=NUMERIC#1][maxDoc=1 f=SORTED#0]
PROBE race CheckIndex(default level) clean=true
PROBE race new IndexWriter(APPEND default) IllegalArgumentException: cannot change field "f" from doc values type=NUMERIC to inconsistent doc values type=SORTED
PROBE race new IndexWriter(CREATE) okIndexWriteris "completely thread safe" (IndexWriter.java:167-168), anddeleteAll's javadoc expects concurrentaddIndexescallers, naming onlyMergeAbortedExceptionfor them.- Sequence numbers put
deleteAll(3) beforeaddIndexes(4), sofmust stay NUMERIC; neither legal order leaves an unopenable commit. - A field "never changes DV type, even across segments / IndexWriter sessions" (
FieldInfos.java:358-360).
The full argument289 words
- Thread safety. Class javadoc,
IndexWriter.java:167-168: "IndexWriterinstances are completely thread safe, meaning multiple threads can call any of its methods, concurrently." The only "no other threads" precondition is onclose()(:1359); the test closes after the second thread has finished. - Effective order. Each change returns a sequence number "which expresses the effective order in which each change was applied" (
:117-118). HeredeleteAll(3) precedesaddIndexes(4). - deleteAll. It clears doc-values types, is "equivalent to creating a new
IndexWriterwithOpenMode#CREATE", and for other threads runningaddIndexes(CodecReader[])names one consequence: "they may receiveMergePolicy.MergeAbortedExceptions" (:2737-2745). Its first version (64a55ede8b5, LUCENE-1705, 2009) said the same for "any of the addIndexes methods". - The schema rule.
FieldInfos.java:358-360: "to enforce that a given field never changes DV type, even across segments / IndexWriter sessions".addIndexesrelies on its registration as the check: "This will throw exceptions if any of the incoming fields has an illegal schema change" (IndexWriter.java:3179-3180). - Tests.
TestDocValuesIndexing.testMixedTypesViaAddIndexes(:592) andtestIllegalTypeChangeAcrossSegments(:648) assert that a type conflict with an added or earlier segment is rejected;testTypeChangeAfterDeleteAll(:690),testTypeChangeAfterCommitAndDeleteAll(:705) andtestTypeChangeAfterCloseAndDeleteAll(:671) assert that afterdeleteAlla field may change from NUMERIC to SORTED. The race appliesdeleteAll's permission to a segment that survivesdeleteAll.TestIndexWriterDelete.testDeleteAllNoDeadLock(:326) runsdeleteAllconcurrently with indexing on purpose. - History. LUCENE-8785 (#9829, fixed in 7.7.2 and 8.2.0) fixed "potentially broken field attributes in the IndexWriter when IndexWriter#deleteAll is called while actively indexing" as a bug (
lucene/CHANGES.txt:6400-6402). On java-user@ (2014-05-22, "IndexWriter.addIndexes() multithread correct?") Uwe Schindler answered thataddIndexesis "thread safe, like all other methods in IndexWriter".
The devil's-advocate check302 words
The argument: concurrent deleteAll has no defined semantics; it is a stop-the-world call, and users who need a clean slate should close the writer and open one with OpenMode.CREATE. In the lucene-solr#2088 review (2020) rmuir asked whether FieldNumbers.clear() is safe while another thread indexes; msfroh and s1monw answered that deleteAll stops the world (IW lock, all DWPTs locked, merges aborted), and s1monw added that they had asked to remove deleteAll and would rather have users re-create the index. mikemccand proposed a javadoc warning that concurrent operations "may or may not be deleted, i.e. the behavior of such concurrent operations are not defined / predictable". Open #6070 asks to "define the allowed concurrent behavior eg when an app calls deleteAll while other threads are indexing".
Why it fails: the warning was never added, and even as proposed it allows either outcome for the overlapping operation, not a commit that the next writer refuses to open. The stop-the-world covers indexing threads and merges; addIndexes(Directory...) registers and copies outside both, so the 2020 safety argument does not reach this path. deleteAll is public, documented and not deprecated, its javadoc expects concurrent addIndexes callers, and in the same thread mikemccand wrote "I think we should fix its bugs instead!" (2020-12-01). The re-typing document is allowed after deleteAll (the tests above); the writer's own schema check, which in the reported order should reject it, accepts it. One point stands: thread safety alone does not promise a particular outcome for a deleteAll and an addIndexes that overlap. The claim is narrower: no order, and no outcome a maintainer might call undefined but legal, should leave a commit, written by the writer itself, that the next writer refuses to open. Two executed reviews by another model family (OpenAI GPT-5.6) and an intended-behaviour verifier rated the intended-behaviour argument weak.
Recommended Register the incoming fields again under the publication lock (validated on the race tests)
Register the incoming fields again inside the synchronized (this) publication block of both addIndexes overloads (registerSchema(infos) before reserveDocs, +16 lines). deleteAll clears under the same lock, so it can no longer slip in between; the test and the gradle org.apache.lucene.index.* selection pass. LFV-124's fix edits the same block and also closes the Directory case.
// in both publication blocks, right before reserveDocs(...):
registerSchema(infos);

private void registerSchema(List<SegmentCommitInfo> infos) throws IOException {
  assert Thread.holdsLock(this);
  for (SegmentCommitInfo info : infos) {
    for (FieldInfo fi : readFieldInfos(info)) {
      globalFieldNumberMap.addOrGet(fi);
    }
  }
}
All options and trade-offs3 options · 673 words
One fix was built and validated in a scratch worktree of 5adff78bb168; the other two are design alternatives a maintainer may prefer. Coordinate with LFV-635's fix (the same clear(), another caller) and with LFV-124's fix (a failed addIndexes(Directory...) leaves its fields registered), which edits the same publication block. LFV-124's recommended fix checks every incoming field up front without registering it and then registers them all at once, all or nothing, with one synchronized FieldNumbers.addAll inside the synchronized (this) publication block. Applied on 5adff78bb168, it also makes this bug's test pass (assertions on and off), and in the two-overload test it fixes the addIndexes(Directory...) case but not the addIndexes(CodecReader...) one. So the two fixes fit together: LFV-124's register-at-publish for addIndexes(Directory...) plus this bug's re-registration (all or nothing) in the addIndexes(CodecReader...) publication block.
Register the incoming fields again under the publication lock (validated on the race tests) (recommended)
In both publication blocks, right after ensureOpen() (IndexWriter.java:3196 and :3354), call a new registerSchema(infos) before reserveDocs. It reads each incoming segment's FieldInfos and calls globalFieldNumberMap.addOrGet while holding the monitor that deleteAll clears under, so registration and publication become one step relative to it. The early loop stays as a fail-fast check before the copy. If a document registered a conflicting type after the deleteAll, the call throws IllegalArgumentException inside the block and the existing handlers delete the copied files (:3202-3208, :3358-3365): the outcome of the legal order deleteAll, addDocument, addIndexes (by reading the code; not executed).
// in both publication blocks, right before reserveDocs(...):
registerSchema(infos);

private void registerSchema(List<SegmentCommitInfo> infos) throws IOException {
  assert Thread.holdsLock(this);
  for (SegmentCommitInfo info : infos) {
    for (FieldInfo fi : readFieldInfos(info)) {
      globalFieldNumberMap.addOrGet(fi);
    }
  }
}
Trade-offs
- Re-reads each incoming segment's
FieldInfoswhile holding theIndexWritermonitor (one small file per segment). A variant that keeps theFieldInfosread in the first loop and registers those avoids the re-read; aDirectory-only form of it passedTestAddIndexes(39/39) andTestIndexWriterDelete(21/21) on maina9779ef3c193, whoseIndexWriter.javadiffers from5adff78bb168only in the #16963 InfoStream line. - Keeping the early
addOrGetloop keeps LFV-124's leak (a call that fails after it leaves its fields registered), andregisterSchemaregisters field by field, so a conflict found at publication leaves the incoming fields registered before it (by reading; not executed). An all-or-nothing registration (verify every field first, then register, as LFV-124'sFieldNumbers.addAlldoes) avoids both; with LFV-124's fix in place, only theaddIndexes(CodecReader...)publication block still needs this change (the combination was not built). - In the common case (no
deleteAll) the extraaddOrGetcalls find the same schema and change nothing.
What the checks validated
- Gradle, clean scratch worktree of
5adff78bb168, OpenJDK 25.0.3, seed DEADBEEF: the test fails on stock with assertions on and off and passes with the fix, on and off. - With the fix:
TestAddIndexes39/39,TestIndexWriterDelete23 passed + 6 skipped,TestDocValuesIndexing33/33; the gradle selection--tests org.apache.lucene.index.*(one seed, no nightly or monster runs): 215 classes, 1,398 tests, 0 failures, 56 skipped;:lucene:core:check -x testpasses with the fix and the test in place. - Both overloads: a two-method test (one per overload) fails 2 of 2 on stock and passes 2 of 2 with the same change (main
5adff78bb168, assertions off; earlier on645d4fe14a20).
Count running addIndexes(Directory...) calls, as abortMerges already counts runningAddIndexesMerges, and have deleteAll wait for them.
Trade-offs
deleteAll then blocks for up to a whole copy while it holds the full-flush lock and every DWPT lock, which needs care to avoid a new lock-order problem (compare LFV-1137). The regression test must run deleteAll() on its own thread. Not built.
FieldNumbers.clear() bumps a counter; addIndexes records it when it registers and, under the publication lock, re-registers (as the recommended option) or fails if it changed.
Trade-offs
Avoids the re-read when no deleteAll intervened, but adds state; failing instead of re-registering would give callers a new exception for a legal call order. Not built.
A service that lets the same caller trigger both a full wipe and an index addition, and then choose field types, can be left with an index no writer opens until it is rebuilt.
TLA+ model checking of the writer-wide field schema. Mapping the model to the Java code put addIndexes' field registration outside the IndexWriter lock and its publication inside it; TLC then found a 4-state trace (register, deleteAll, publish) that breaks the invariant "every published segment's fields are in the schema". It was reduced to one JUnit test.
The method in full201 words
Method: semi-formal (a hypothesis formed by code reading while writing a TLA+ model, witnessed by the model checker), 2026-10-26.
- A TLA+ model of the writer-wide field schema treats the field registration of
addIndexes(outside theIndexWritermonitor) and its publication (inside it) as separate actions, with a map from each model step to the Javafile:line. Writing that map raised the question of whatdeleteAlldoes in between. - TLC 1.8.0 reported the invariant SchemaCovers (every field of a published segment is in the schema) violated in a 4-state trace: register, deleteAll, publish. The same model is clean with the fix modelled and without
deleteAll. A re-run of the model on main645d4fe14a20(code identical to its map) gave the same trace. - Two other analyses in the hunt reached the same interleaving independently the same evening: a model-based linearizability test that held
addIndexesat 7 points against 7 concurrent operations (49 combinations; the only 2 outside the sequential model weredeleteAllat two points inside the copy loop) and a second TLA+ model ofaddIndexesand its merge source. - The three were reduced to the one public-API JUnit test of this page, with a latch so that it is deterministic.
No report of this defect found (GitHub issues and PRs incl. the JIRA archive, the dev@ and java-user@ lists, Elasticsearch, OpenSearch, Solr; re-checked 2026-11-03 in two independent passes and again for this doc). Related, different defects: lucene-solr#2088 (a field-number fix whose review asked if deleteAll's schema clear is safe with concurrent indexing) and #6070 (an open design umbrella).
Searches3 searches
In the documented searches, no Lucene issue, PR, JIRA entry or list thread, and nothing outside Lucene, describes this defect. Related prior items, each about a different defect:
- lucene-solr#2088 (LUCENE-9617, issue #10657, merged 2020): fixes a different defect,
FieldNumbers.clear()not resettinglowestUnassignedFieldNumber. In its review rmuir asked whetherclear()is safe while another thread callsaddDocumentand feared "some race condition that ultimately creates segments with unaligned field numbers"; msfroh and s1monw answered withdeleteAll's stop-the-world over indexing threads and merges.addIndexesis never mentioned, and the effect here is a schema conflict between a surviving segment and a later document, not unaligned numbers (which, checked, do not corrupt on this path). This bug is where that safety argument does not reach. - #6070 (LUCENE-5006, open since 2013, "Simplify / understand IndexWriter/DocumentsWriter synchronization"): asks to "define the allowed concurrent behavior eg when an app calls deleteAll while other threads are indexing". A design umbrella: no mechanism, no symptom.
- Also related, all fixed and on other paths: #9829 (LUCENE-8785,
deleteAllvs a concurrentaddDocument), #10349 (LUCENE-9309,abortMergeswaits foraddIndexes(CodecReader...)merges, which is whydeleteAllwaits for that merge but not for the publication after it), #7360 (LUCENE-6299,deleteAllvsaddIndexesdocument accounting), #10340 (LUCENE-9300, segments added byaddIndexesmay carry different field numbers), #1019 (2022, a lock foraddIndexesvs concurrently added new fields; nodeleteAll).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive); Elasticsearch, OpenSearch, Solr; dev@, java-user@, issues@, commits@; JIRA; web | 2026-11-02 | 173 recorded queries: two scripted prior-art runs (mechanism and symptom query sets), 52 GitHub GraphQL searches, 8 JQL queries, list and web queries; the full threads of the closest items | only the related items above |
| Open PRs | 2026-11-02, 2026-11-03 | the 20 of 410 open apache/lucene PRs whose changed files include IndexWriter.java, FieldInfos.java or SegmentMerger.java: their diffs were read (11 on 2026-11-02, the other 9 read-only from GitHub on 2026-11-03) | none changes the addIndexes registration loop, either publication block or deleteAll |
| Re-check (two independent passes; then this doc) | 2026-11-03 | this doc: 19 GitHub searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch and OpenSearch (deleteAll addIndexes, inconsistent doc values type deleteAll / addIndexes, globalFieldNumberMap, FieldNumbers clear, addIndexes getFieldNames, deleteAll thread safe, ...); every apache/lucene item updated since 2026-11-02 (52); dev@ and java-user@ for deleteAll addIndexes; the upstream history of IndexWriter.java and FieldInfos.java (GitHub commits API); two rate-limited queries were retried after 65 s | nothing new |
Introduced in 4.2.0 (2013) by LUCENE-4547 (041ff1140f3), which made doc-values types strict per field, added the schema clear to deleteAll and the registration outside the lock to addIndexes(Directory...). Every release from 4.2.0 through 10.6.0 and main is affected; 4.1.0 is not. Not fixed upstream as of 2026-11-03.
Versions tested9 rows
Introduced by 041ff1140f3 ("make DV strongly typed; fix solr", Michael McCandless, author date 2012-11-23, on the LUCENE-4547 feature branch; LUCENE-4547 = #5613, svn era, no PR), released through the trunk merge a181dc07353 (2013-02-07) and the branch_4x commit 5cbaddcbc7f (2013-02-08), both "LUCENE-4547: DocValues improvements" (CHANGES 4.2.0). That one commit made doc-values types strict per field, added globalFieldNumberMap.clear() to deleteAll() and added the registration loop to addIndexes(Directory...) outside the monitor. Not a regression: before it there was no per-field type rule to break.
Not fixed upstream: upstream main f72004515ec2 (2026-11-03); the last commit to IndexWriter.java is 5adff78bb16 itself (#16963, removes a deprecated segString overload) and to FieldInfos.java 5158a52a082 (2026-04-24); branch_10_6's last IndexWriter.java commit is the #16581 backport (2026-09-21). Not new in 10.6.
| Version or commit | Verdict | Result |
|---|---|---|
| 4.1.0 | not affected | not affected: a 4.x version of the test runs the race, but even a sequential doc-values type change is accepted, so there is no rule to break |
| 4.2.0 | first: 4.2.0 | the 4.x version fails: the new IndexWriter throws "cannot change DocValues type from NUMERIC to SORTED for field \"f\"" |
| 4.10.4 | affected | the 4.x version fails the same way |
| 5.5.5, 6.6.6, 7.7.3 | affected | a core-only main() version fails |
| 8.11.4, 9.0.0 | affected | the test, adjusted only for the older test-framework package names, fails (assertions off) |
| 9.12.3, 10.5.2, 10.6.0 | affected | this test, unchanged, fails |
main 645d4fe14a20, e1faeba08bde | affected | this test fails, assertions on and off; passes with the fix |
main 5adff78bb168 | affected | this test fails through gradle, on and off; passes with the recommended fix |
| 4.2.0 to 10.6.0 (120 release tags) | read | every tag has the clear() in deleteAll() and the registration before the synchronized publication of addIndexes(Directory...) |
An independent reproducer (its own test, another latch point and another conflicting type), two executed reviews by another model family (OpenAI GPT-5.6), an intended-behaviour verifier and a final review all rated it real; this doc's gradle runs reproduced it on main 5adff78bb168 and validated the fix.
Checks and verdicts306 words
The cross-model reviews ran on main ea57360912ed and the verifiers on 645d4fe14a20; IndexWriter.java and FieldInfos.java are identical to ea57360912ed there, and between 645d4fe14a20 and 5adff78bb168 IndexWriter.java changed only in one InfoStream line of the commit path (#16963). Neither cross-model review executed the addIndexes(CodecReader...) overload.
| Check | Verdict | What it found |
|---|---|---|
| finder (reduced test) | found | The one-test JUnit fails on main (on, off), 10 of 10 iterations and at four seeds, and on 10.6.0, 10.5.2 and 9.12.3; passes with the fix; the TLC re-run gives the same trace. |
| independent reproducer | real | Own test written from the claim: latch on the source's doc-values file instead of the destination copy, a BINARY conflicting document. Fails on main (on, off, 5 of 5), 10.6.0, 10.5.2 and 9.12.3; passes with the fix; both sequential orders pass. |
| cross-model review, intended lens (OpenAI GPT-5.6, executed) | real (high) | Own public-API test fails at the reopen; both sequential controls pass; an order-agnostic invariant test fails on stock and passes with the fix. Intended-behaviour argument: weak. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Own race tests fail (on, off); the controls pass; the invariant test passes with the fix. |
| intended-behaviour verifier | real (high) | No intended-behaviour argument survives (the javadoc, the sequence numbers, the tests, the never-adopted 2020 proposal); its re-runs on main and 10.6.0 fail. |
| final review | confirmed (high) | Re-ran the independent test with a new seed (1A2B3C4D): fails on and off, passes with the fix. Index unusable, Medium, not security-sensitive, not a duplicate (same family as LFV-635, other fix site). |
| this doc | reproduced, fix validated | Gradle on main 5adff78bb168: fails on stock (on, off), passes with the fix (on, off); 1,398 tests of the gradle org.apache.lucene.index.* selection pass with the fix; the impact probe re-run gives the same lines. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 526 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,549 words
- Registry title
- A deleteAll() that overlaps addIndexes clears the incoming fields from the writer's field schema, but addIndexes still publishes its segment, so a later document can give such a field another doc-values type and the committed index can no longer be opened by an IndexWriter
- Area
- index / IndexWriter addIndexes vs deleteAll (writer-wide field schema, FieldInfos.FieldNumbers)
- Priority
- Medium, rank 108: On the default IndexWriter of every release since 4.2.0, a deleteAll() that overlaps addIndexes drops the imported fields from the writer schema, and a later document that re-types one of them commits an index that no IndexWriter can open except with OpenMode.CREATE, which drops every document. The overlap needs no hooks but the full sequence is unusual, so it is rare, and it stays in Medium because the committed index is left unwritable.
- Impact class
- index unusable
- Impact note
- Hits applications that call deleteAll() (or deleteDocuments(MatchAllDocsQuery), which delegates to it) on one thread while another thread's addIndexes(Directory...) is copying files, or while addIndexes(CodecReader...) is between its merge and its publication, with the default IndexWriterConfig, codec, directory and merge scheduler and no scale needed: the imported segment survives but the writer forgets its fields, a later document may give one of them another doc-values type, the commit succeeds, and afterwards no IndexWriter opens the index except with OpenMode.CREATE, which drops every document [exec, -ea and -da]; per the finder's probes, a merge of the two conflicting segments closes the still-open writer as a tragic event, sorting on the field fails on readers, and CheckIndex at its default level reports the index clean; without the re-typing document the effect stays inside the open writer (getFieldNames() omits the imported fields, updateNumericDocValue on one of them is rejected) and ends when the writer is reopened; released 4.2.0 to 10.6.0.
- Summary
- One thread imports an index with IndexWriter.addIndexes while another thread calls deleteAll() on the same writer. You expect the outcome of one of the two orders: either the imported documents are deleted, or they stay and their fields keep their doc-values types, and in both cases the committed index opens again in a new IndexWriter. Instead deleteAll can clear the imported fields from the writer's schema while addIndexes still publishes the imported segment, so a later document can give an imported field another doc-values type, the commit succeeds, and the next new IndexWriter on that index throws IllegalArgumentException ('cannot change field "f" from doc values type=NUMERIC to inconsistent doc values type=SORTED').
- Introduced
- 041ff1140f3f207ab0a3571c92a738b328142e95 (author Michael McCandless, 'make DV strongly typed; fix solr', on the LUCENE-4547 feature branch, svn branches/lucene4547 r1412906; LUCENE-4547 'DocValues field broken on large indexes' = apache/lucene#5613; svn era, no pull request), released through the trunk merge a181dc07353 (2013-02-07) and the branch_4x commit 5cbaddcbc7f (2013-02-08), both 'LUCENE-4547: DocValues improvements' (CHANGES 4.2.0): that one commit made doc-values types strict per field, made deleteAll() call globalFieldNumberMap.clear(), and made addIndexes(Directory...) register incoming fields with globalFieldNumberMap.addOrGet outside the IndexWriter monitor, before the copy and before its synchronized(this) publication [read: git log -S 'globalFieldNumberMap.clear()' and -S 'globalFieldNumberMap.addOrGet(fi)' in the history clone; exec at release level only: 4.1.0 not affected, 4.2.0 affected; no commit-level bisect]. Not a regression: before it the property did not exist (no per-field doc-values type, no clear(), no registration in addIndexes(Directory...)). (2012-11-23 (author date of 041ff1140f3 on the feature branch); 2013-02-07 on trunk (a181dc07353), 2013-02-08 on branch_4x (5cbaddcbc7f))
- First affected version
- 4.2.0 (2013-03-11) [exec: a 4.x version of the claimed test fails on 4.2.0 (new IndexWriter throws 'cannot change DocValues type from NUMERIC to SORTED for field "f"') and passes on 4.1.0, where even a sequential doc-values type change is accepted]
- Affected versions
- every release from 4.2.0 through 10.6.0 and main 645d4fe14a20 [read: all 120 releases/lucene* and releases/lucene-solr* tags from 4.2.0 to 10.6.0 in the history clone have the clear() in deleteAll() and the addOrGet loop before the synchronized publication block of addIndexes(Directory...); the clone has no 8.8.2-8.11.x tags]. Executed, all fail: main 645d4fe14a20 (-ea and -da), 10.6.0 (4ae946e5a9b), 10.5.2 and 9.12.3 with the claimed JUnit; 9.0.0 and 8.11.4 (the test adjusted only for the older test-framework package names, -da); 7.7.3, 6.6.6 and 5.5.5 (a core-only main() probe, -ea); 4.2.0 and 4.10.4 (a 4.x version of the test); 4.1.0 is not affected [exec]. Not fixed upstream [read]: upstream main e1faeba08bde (2026-11-02), branch_10_6 and branch_9_12 keep both lines; the last commit to IndexWriter.java on main is 169cbffd12f (#16581, author date 2026-09-21). The addIndexes(CodecReader...) overload fails the same way on main when deleteAll runs between its merge and its publication [exec on main only, finder probe; read for older versions]. Not new in 10.6.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: TLA+/TLC, code reading
- Upstream and prior reports
- no report of this bug found (2026-11-02, 173 recorded queries, on top of the finder's scripted prior-report search of 52 queries and the independent reproduction's and the adjudication's GitHub searches; re-checked 2026-11-03): two scripted prior-report searches (mechanism and symptom query sets) over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 52 GitHub GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch and Lucene.NET; 8 JQL queries; the full threads of the closest items; the changed files of the 20 open PRs that touch IndexWriter.java, FieldInfos.java or SegmentMerger.java (none changes the addIndexes registration loop, either publication block or deleteAll). Related, class level only: lucene-solr#2088 (LUCENE-9617 review, merged 2020), where a maintainer (rmuir) asked whether deleteAll's FieldNumbers.clear() is safe while another thread calls addDocument and feared 'segments with unaligned field numbers', and was answered with deleteAll's stop-the-world (addIndexes not mentioned; addIndexes(Directory...) registers and copies outside it); open #6070 (LUCENE-5006, 2013) asks upstream to define deleteAll's behaviour while other threads index. Related, different and fixed: #9829 (LUCENE-8785, deleteAll vs concurrent addDocument, 2019), #10349 (LUCENE-9309, abortMerges waits for addIndexes(CodecReader...) merges, 2020), #7360 (LUCENE-6299, deleteAll vs addIndexes doc accounting, 2015), #10340 (LUCENE-9300), #1019 (2022). No fix commit exists, so there is no author date to compare. Tracking issue #16937 does not mention it. Refresh (2026-11-02): the 15 apache/lucene PRs updated since 2026-10-31 (#16357 to #16961) are unrelated, 'deleteAll addIndexes' returns only #9738 (unrelated), and the last commits to IndexWriter.java and FieldInfos.java on upstream main (head e1faeba08bde) are 169cbffd12f (author date 2026-09-21) and 5158a52a082 (2026-04-24).
- Lucene commit tested
- main
5adff78bb168(12.0.0-SNAPSHOT), 2026-11-03: the one-test repro through gradle in a clean scratch worktree, stock (fails, assertions on and off) and with the recommended fix (passes, on and off); with the fixTestAddIndexes(39/39),TestIndexWriterDelete(23 passed, 6 skipped),TestDocValuesIndexing(33/33) and the gradle selection--tests org.apache.lucene.index.*(one seed; 215 classes, 1,398 tests, 0 failures) pass;:lucene:core:check -x testpasses with the fix and the test in place; the supplementary impact probe (the race and both sequential orders) re-run on5adff78bb168. Earlier runs of the same test: main645d4fe14a20ande1faeba08bde, and the released 10.6.0, 10.5.2 and 9.12.3 (all fail).
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:117-118 (at 645d4fe14a20) (sequence numbers express 'the effective order in which each change was applied'), :167-168 (class javadoc: 'completely thread safe, meaning multiple threads can call any of its methods, concurrently'), :1886-1888 (deleteDocuments routes a MatchAllDocsQuery to deleteAll), :1124 and :1274 (constructor and getFieldNumberMap, where the reopen throws), :2739-2745 (deleteAll javadoc: doc value types are cleared; equivalent to OpenMode.CREATE; concurrent addIndexes(CodecReader[]) callers may receive MergeAbortedException), :2750-2812 with :2800 (deleteAll: globalFieldNumberMap.clear()), :3176-3182 (addIndexes(Directory...): readFieldInfos and globalFieldNumberMap.addOrGet for every incoming field, then copySegmentAsIs, no IndexWriter lock held), :3194-3211 (its synchronized(this) publication, no re-registration), :3350-3368 (the addIndexes(CodecReader...) publication block)lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:358-360 (at 645d4fe14a20) (the per-field record exists 'to enforce that a given field never changes DV type, even across segments / IndexWriter sessions'), :415 (FieldNumbers.addOrGet), :694 (FieldNumbers.clear)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1267-1278 (at 5adff78bb168) (getFieldNumberMap, addOrGet at :1274), :2750-2812 (deleteAll; :2764-2765 locks, :2771 abortMerges, :2785 segmentInfos.clear, :2800 globalFieldNumberMap.clear), :2821-2849 (abortMerges waits for runningMerges and runningAddIndexesMerges), :3103-3226 (addIndexes(Directory...): :3119 flush, :3177-3183 registration and copy, :3194-3210 publication), :3350-3368 (addIndexes(CodecReader...) publication), :2135 (getFieldNames)lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:358-360 (at 5adff78bb168) (per-field record comment), :415 (FieldNumbers.addOrGet), :694 (FieldNumbers.clear)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1886-1889 (at 5adff78bb168) (MatchAllDocsQuery routed to deleteAll), :2737-2745 (deleteAll javadoc), :2129-2137 (getFieldNames, @lucene.experimental)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:117-118, (at 5adff78bb168) :167-168, :1359, :2737-2745, :3179-3180lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:358-360 (at 5adff78bb168)lucene/core/src/test/org/apache/lucene/index/TestDocValuesIndexing.java:592, (at 5adff78bb168) :648, :671, :690, :705; TestIndexWriterDelete.java:326lucene/CHANGES.txt:6400-6402 (at 5adff78bb168) (LUCENE-8785, Lucene 8.2.0) and :6933-6935 (7.7.2)https://github.com/apache/lucene-solr/pull/2088 (review comments 2020-11-19 to 2020-12-01)https://github.com/apache/lucene/issues/6070java-user@lucene.apache.org, 2014-05-22, thread 'IndexWriter.addIndexes() multithread correct?' (Uwe Schindler's reply, read via the lists.apache.org archive API)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:2821-2849 (at 5adff78bb168) (abortMerges, runningAddIndexesMerges), :3194-3210, :3350-3368 (publication blocks and their failure handlers)
- Prior reports
https://github.com/apache/lucene-solr/pull/2088https://github.com/apache/lucene/issues/6070
- Diagrams
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:2800, (at 5adff78bb168) :3177-3183, :3194-3210
- TestDeleteAllDuringAddIndexes.java (one test, lucene/core):
repro/LFV-1074/TestDeleteAllDuringAddIndexes.java(89 lines)
A step-by-step picture of the repro, made in parallel with this doc from the code at 5adff78bb168 and the executed runs; the PNG is the summary still.
assets/LFV-1074/bug.png(526 KB)