The writer keeps one in-memory registry of field names and their schemas. addIndexes(CodecReader...) checks the incoming fields without touching it, then merges, and the merge's first step adds the incoming fields to it. When a later write fails, the call throws and adds nothing, but the fields stay registered.
- Every field name in an index has one schema: indexed or not (index options), doc values type, points, vectors. The first document indexed with a name fixes it; a later document that gives the name another schema is rejected with
IllegalArgumentException. IndexWriterchecks that against an in-memory registry of every name it knows, built from the segments when the writer opens.getFieldNames()returns the registry's names.addIndexes(CodecReader...)merges the given readers into a new segment of this index. Its javadoc promises that if an exception occurs ("for example disk full"), "either no indexes will have been added or they all will have been".
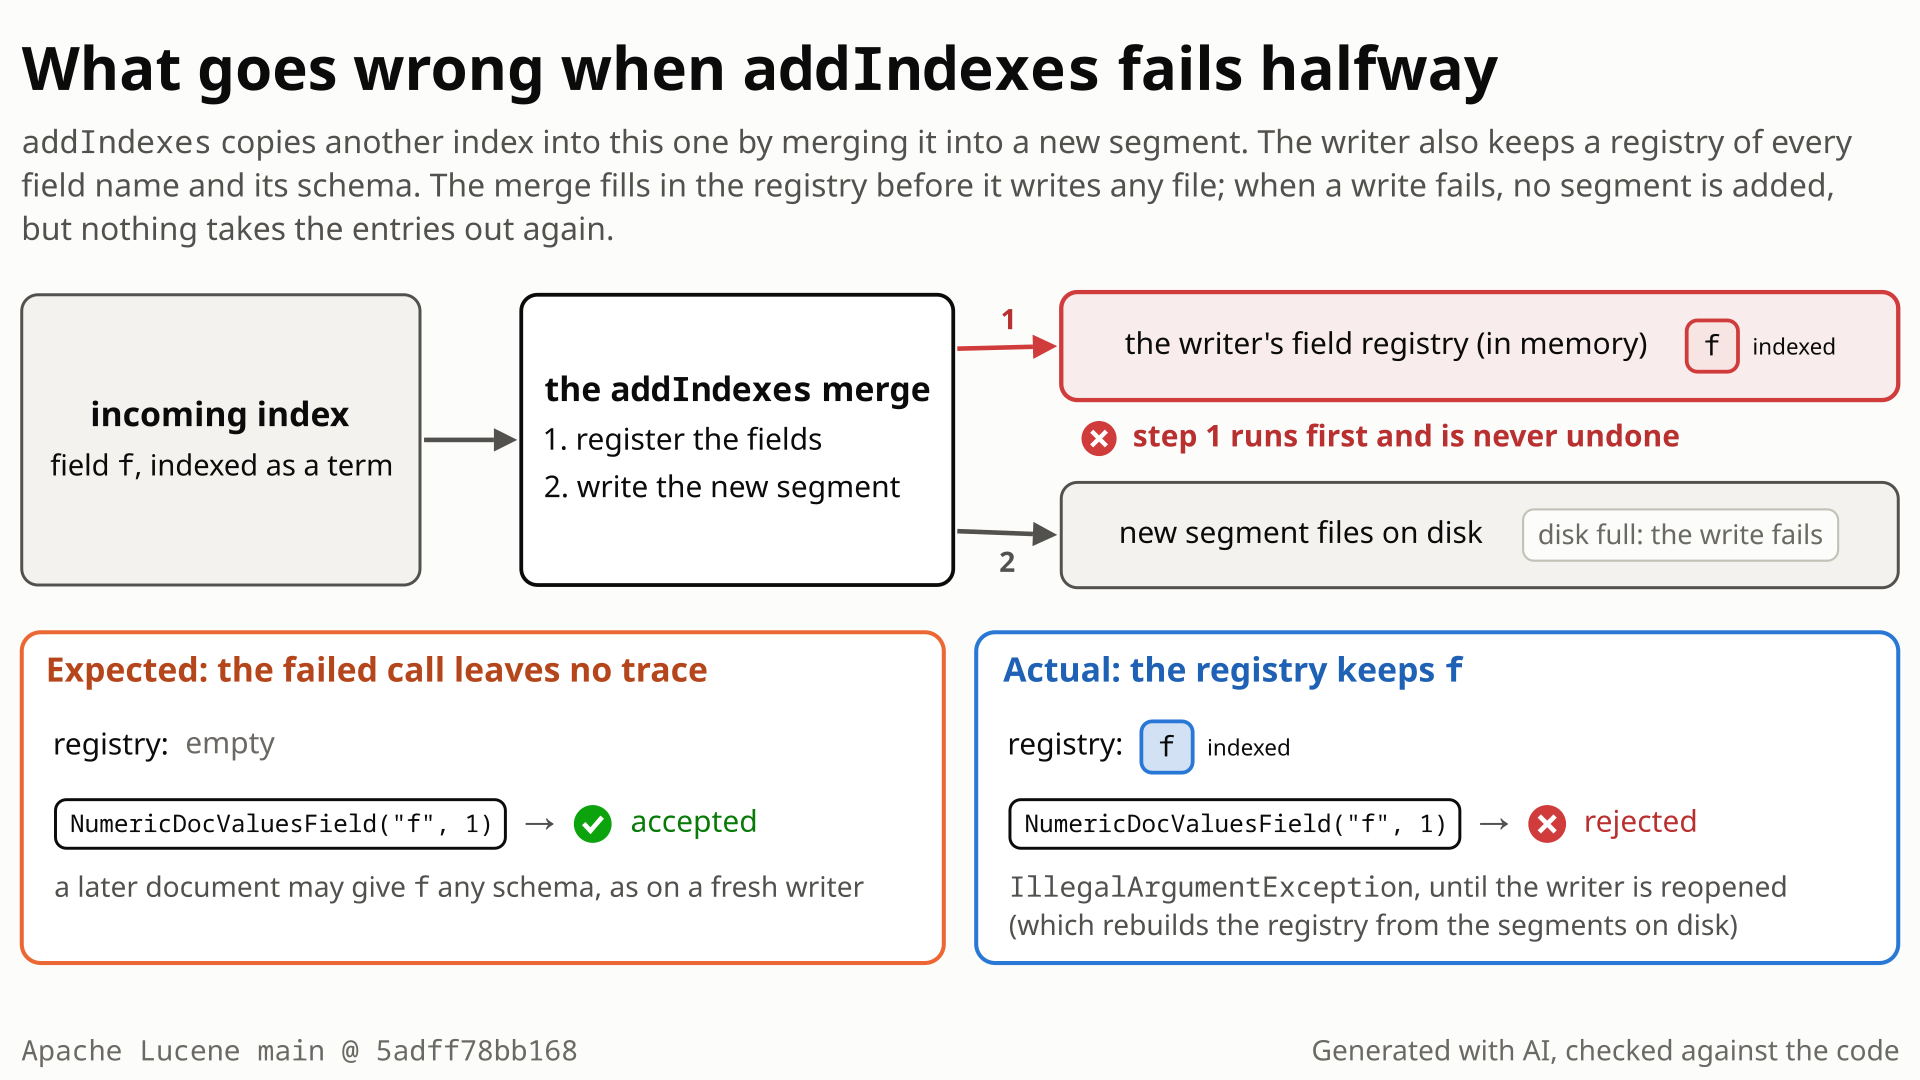
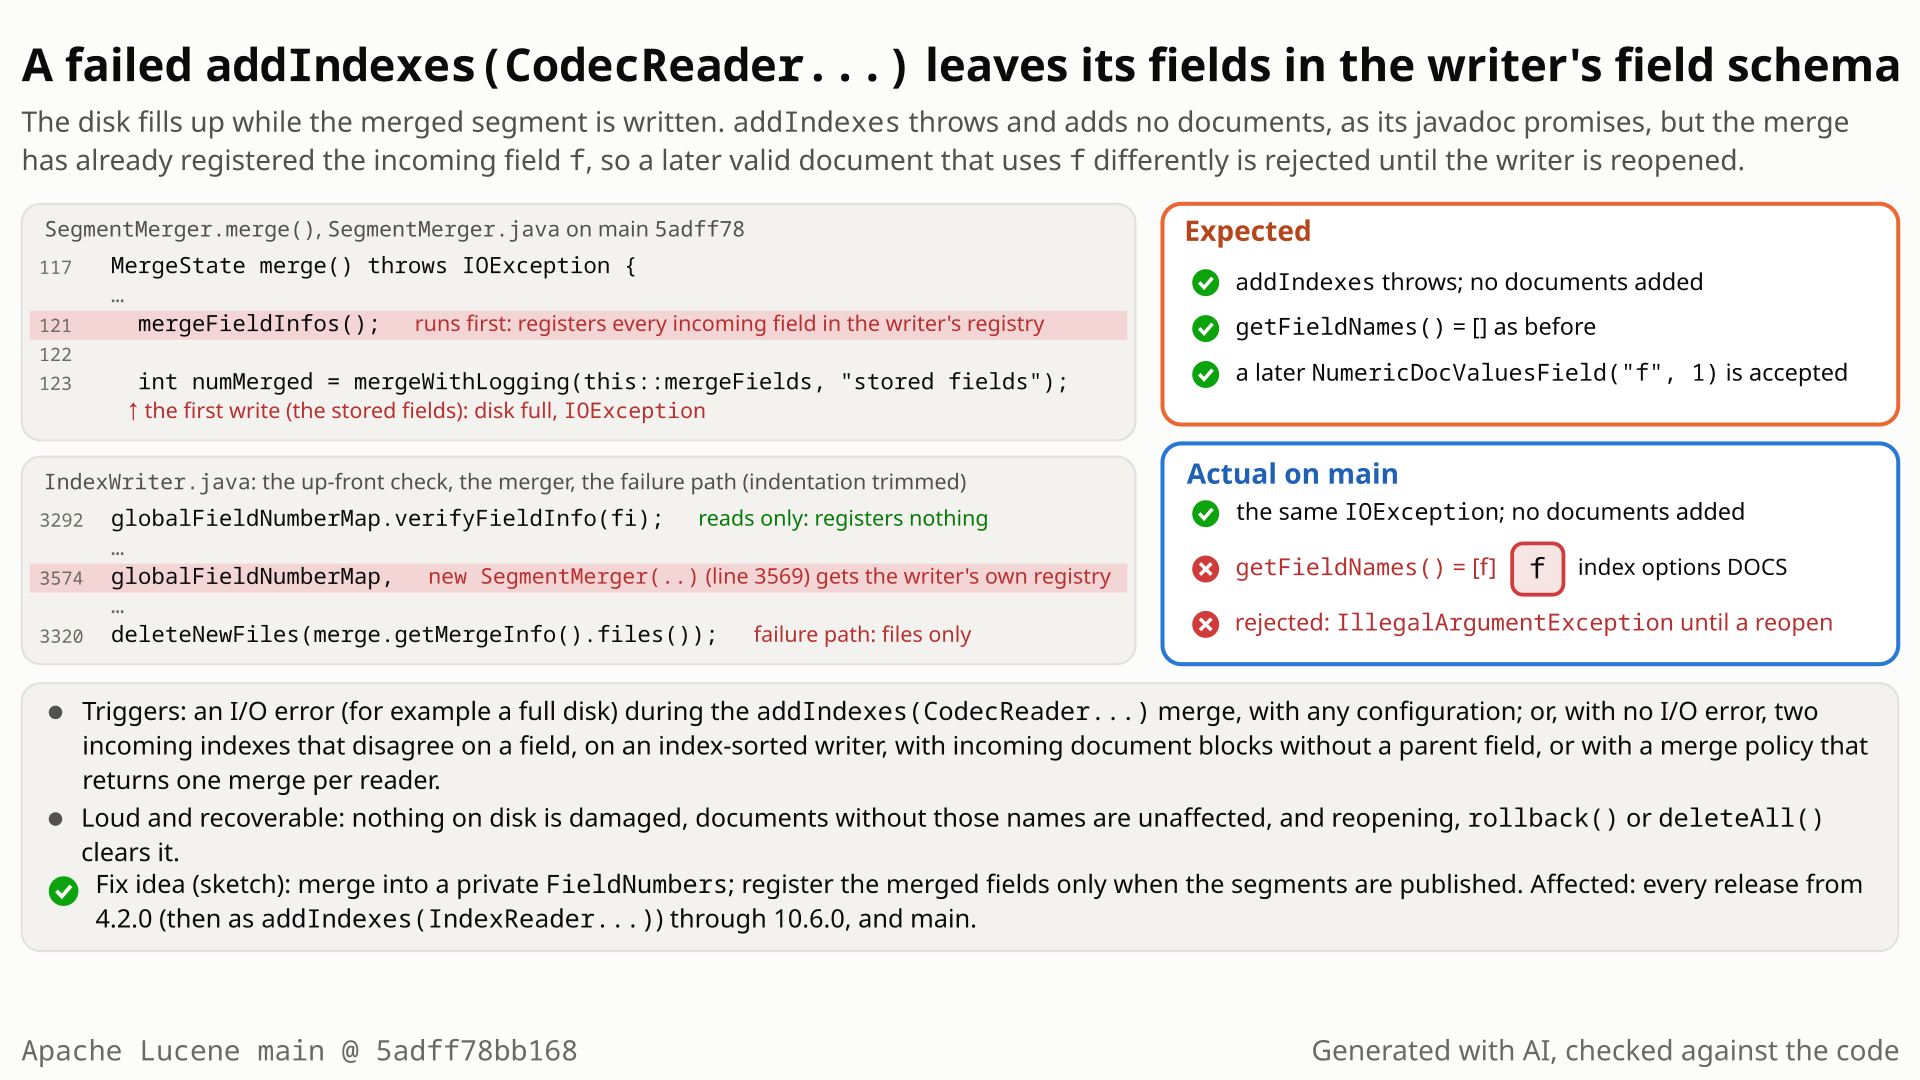
addIndexes(CodecReader...) and the later document: f is registered by the merge before the disk-full error and stays, so the doc-values f document is rejected. Select the still to open it at full size. Generated with AI, checked against the code.- The source index has 1 document with
StringField("f", "x"):fis indexed and has no doc values. The destination is a new, empty index with a defaultIndexWriterConfig. w.addIndexes(reader)hits a disk-fullIOExceptionwhile it writes the merged segment. As the javadoc promises, nothing is added: 0 documents, the writer stays open, no tragic error.- You expect the writer to be as before: no document with
fever reached it, so a document withNumericDocValuesField("f", 1)is accepted, as by a reopened writer. - Instead it is rejected:
cannot change field "f" from index options=DOCS to inconsistent index options=NONE, andgetFieldNames()listsf. The merge registeredfbefore the write failed, and nothing takes it back until a reopen,rollback()ordeleteAll(). - No I/O error is needed on an index-sorted writer, with incoming document blocks without a parent field, or with a one-merge-per-reader policy: a rejected import of two indexes that disagree on
fkeeps one index'sf(with a single merge, the first one's), and then even importing the other index alone is rejected.
Applications that keep using a writer after addIndexes(CodecReader...) failed: after an I/O error during the merge (any configuration), or after a rejected import of conflicting indexes on an index-sorted writer, with document blocks without a parent field, or with a per-reader merge policy. Later documents that use an incoming name differently are rejected until the writer is reopened.
Mechanism, terms and numbers727 words
IndexWriter keeps one in-memory registry of field names and their schemas, built from the segments when it opens, and checks every new document against it. addIndexes(CodecReader...) first checks the incoming fields without changing that registry, then merges the readers into a new segment. The merge is built over the writer's own registry, and its first step registers the incoming fields. When a later step of the merge fails (for example a full disk), the call throws and publishes nothing, but nothing removes the registrations. No document is added, as the javadoc promises, but for the rest of the writer session the incoming names keep the incoming schema: a later document that uses such a name differently is rejected with IllegalArgumentException, and getFieldNames() lists the name. With an index sort, incoming document blocks without a parent field, or a one-merge-per-reader merge policy, a rejected import of two conflicting indexes leaves the same residue without any I/O error. Reopening the writer, rollback() or deleteAll() clears it; the index on disk is not damaged. Every release from 4.2.0 through 10.6.0 and main is affected. Merging with private field numbers and registering the fields only when the merged segment is published fixes every executed trigger.
- The registry (
FieldInfos.FieldNumbers) is built when the writer opens (IndexWriter.java:1124). addIndexes(CodecReader...)(:3275) runs "Best effort up front validations":globalFieldNumberMap.verifyFieldInfo(fi)for every incoming field (:3288-3293).verifyFieldInfoonly checks (FieldInfos.java:401-408), so a conflict found here leaves nothing behind.- The merge runs in
addIndexesReaderMerge(IndexWriter.java:3491), whoseSegmentMergeris givenglobalFieldNumberMap, the writer's registry itself (:3568-3577). SegmentMerger.merge()callsmergeFieldInfos()first (SegmentMerger.java:121; the builder over the registry at:75), which adds the incomingFieldInfos one by one (:232-239; a conflict stops the loop) throughFieldInfos.Builder.add->FieldNumbers.addOrGet(FieldInfos.java:788,:415): each new name is registered with its incoming schema. Stored fields, norms, postings, doc values, points, vectors and the.fnmare written after that (SegmentMerger.java:123on), then the compound file and the.si(IndexWriter.java:3620-3641).- When one of those steps fails, the exception reaches the caller: with
SerialMergeSchedulerstraight out ofmergeScheduler.merge(IndexWriter.java:3312), withConcurrentMergeSchedulerrethrown at:3376-3384. Thefinally(:3316-3324) deletes files only of merges whose merge info is set, which happens aftermerger.merge()returns (:3600); for a failure inside the merge it deletes nothing, and files already written stay unreferenced until the writer is closed or rolled back. Only anErroris tragic (:3390-3393), so the writer stays open.FieldNumbershas no removal exceptclear()(FieldInfos.java:694-698), which onlydeleteAll()calls (IndexWriter.java:2800). - A later document reaches
FieldNumbers.addOrGet->verifySameSchema(FieldInfos.java:422) and is rejected against the leftover schema;getFieldNames()(IndexWriter.java:2135-2137) lists the name.
Unless the writer has an index sort, or at least one reader of the merge has document blocks and at least one (possibly another) has no parent field (IndexWriter.java:3549-3556), addIndexesReaderMerge first wraps the readers of one merge with SlowCompositeCodecReaderWrapper.wrap (:3560-3566), which merges their FieldInfos in a private FieldNumbers (FieldInfos.java:196-218) and throws on a conflict before anything is registered. With an index sort, in that blocks case (the wrap is skipped), or with a merge policy whose findMerges(CodecReader...) returns one merge per reader (allowed by the javadoc, IndexWriter.java:3264-3267), step 4 registers one reader's f and throws IllegalArgumentException on the other's (within one merge the first reader's; with one merge per reader under the default concurrent scheduler, whichever merge registers first). The rejected call leaves that schema behind: a later document, and even importing the other index alone, is rejected (executed with the first reader's f left behind: addIndexes(c2) is rejected), while a fresh writer accepts c2. The wrap came with #12622 (9.9.0) and the blocks skip with #13128 (9.11.0), so before 9.9.0 a conflicting two-reader import left the residue with the default configuration too.
| step | stock main | with the recommended fix |
|---|---|---|
addIndexes(reader) with the disk-full failure | throws IOException, 0 documents, writer open | the same |
getFieldNames() after the call | [f] | [] (by code reading) |
addDocument(NumericDocValuesField("f", 1)) | rejected: cannot change field "f" from index options=DOCS to inconsistent index options=NONE | accepted |
| reopened writer, the same document | accepted | accepted |
Exposure and likelihood270 words
- Who is hit. Applications that keep using an
IndexWriterafteraddIndexes(CodecReader...)failed. Two ways in: an I/O error once the merge has started (any configuration; the javadoc's own "disk full" example), or a rejected import of indexes that disagree on a field's schema on an index-sorted writer, with incoming document blocks without a parent field, or with a merge policy that returns one merge per reader (and with the default configuration on every release before 9.9.0). - What they see. Every later document that gives an incoming name another schema fails with
IllegalArgumentException;getFieldNames()lists the name. After the conflict trigger, importing only the second index is rejected too. - Loud, no data damage. Nothing of the failed import is added or committed, no commit references its files, and documents that do not use those names are accepted as usual. After an I/O error, a retry of the same import works (it has the same schema). Files a failed merge already wrote stay in the directory, unreferenced, until the writer is closed or rolled back; they are harmless and not part of this bug.
- How long. Until the writer is reopened, rolled back or
deleteAll()is called. - Default configuration. The I/O trigger needs no setting: a default-configuration check with
ConcurrentMergeSchedulershows the same residue; the repro usesSerialMergeSchedulerto keep the merge and its exception on the test thread. - Likelihood. Contrived (rare in practice): accidental harm needs an application that abandons the import, keeps the same writer without
rollback()or a reopen, and then indexes an incoming name differently. - Workaround. Reopen or roll back the writer after a failed
addIndexes(CodecReader...).
One JUnit test: a source index with StringField("f") and a destination whose directory throws a simulated disk-full IOException. addIndexes throws as expected; then a document with NumericDocValuesField("f", 1) is rejected, with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.store.MockDirectoryWrapper;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestFailedAddIndexesCodecReaderSchema extends LuceneTestCase {

  public void testFailedAddIndexesDoesNotDefineIncomingField() throws Exception {
    try (Directory src = newDirectory();
        MockDirectoryWrapper dst = newMockDirectory()) {
      try (IndexWriter w = new IndexWriter(src, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new StringField("f", "x", Field.Store.NO));
        w.addDocument(doc);
      }
      MockDirectoryWrapper.Failure diskFull =
          new MockDirectoryWrapper.Failure() {
            @Override
            public void eval(MockDirectoryWrapper dir) throws IOException {
              if (doFail) {
                throw new IOException("simulated disk full");
              }
            }
          };
      dst.failOn(diskFull);
      IndexWriterConfig iwc = new IndexWriterConfig().setMergeScheduler(new SerialMergeScheduler());
      try (DirectoryReader reader = DirectoryReader.open(src);
          IndexWriter w = new IndexWriter(dst, iwc)) {
        diskFull.setDoFail();
        expectThrows(
            IOException.class, () -> w.addIndexes((CodecReader) reader.leaves().get(0).reader()));
        diskFull.clearDoFail();
        // expected: "f" is still unknown to this writer after the failed call, so this document
        // is accepted; actual: IllegalArgumentException
        Document doc = new Document();
        doc.add(new NumericDocValuesField("f", 1));
        w.addDocument(doc);
      }
    }
  }
}
cp $REPRO/TestFailedAddIndexesCodecReaderSchema.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestFailedAddIndexesCodecReaderSchema -Ptests.seed=DEADBEEF
- Expected
- After the failed
addIndexes, the document withNumericDocValuesField("f", 1)is accepted, as by a reopened writer. - Observed
- It is rejected:
IllegalArgumentException: cannot change field "f" from index options=DOCS to inconsistent index options=NONE.
More files, environment, full output231 words
One test class, one method, single thread, deterministic. Public API plus the test framework's MockDirectoryWrapper.Failure, the upstream idiom for a full disk; SerialMergeScheduler keeps the merge and its exception on the test thread (with the default ConcurrentMergeScheduler, addIndexes throws the same exception, the merge thread reports it as well, and the residue is the same). It asserts only the user-visible harm, the rejected document; the fault-free conflict trigger and the getFieldNames() symptom are left out on purpose. The file is formatted with the project's google-java-format. The suggested regression test is this same test; it fits into TestAddIndexes.java.
The same test fails on the released 10.6.0, 10.5.2 and 9.12.3 jars, and with 30 random seeds on main.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT); also fails on the released 10.6.0, 10.5.2 and 9.12.3 jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (pure Java logic; nothing platform-specific) |
cp $REPRO/TestFailedAddIndexesCodecReaderSchema.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestFailedAddIndexesCodecReaderSchema -Ptests.seed=DEADBEEF
# the same failure with -Ptests.asserts=false
TestFailedAddIndexesCodecReaderSchema > testFailedAddIndexesDoesNotDefineIncomingField FAILED
    java.lang.IllegalArgumentException: cannot change field "f" from index options=DOCS to inconsistent index options=NONE
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:FDDE072C10F6F8B3]:0)
        at org.apache.lucene.index.FieldInfo.verifySameIndexOptions(FieldInfo.java:279)
        at org.apache.lucene.index.FieldInfos$FieldNumbers.verifySameSchema(FieldInfos.java:515)
        at org.apache.lucene.index.FieldInfos$FieldNumbers.addOrGet(FieldInfos.java:422)
        at org.apache.lucene.index.FieldInfos$Builder.add(FieldInfos.java:788)
        at org.apache.lucene.index.FieldInfos$Builder.add(FieldInfos.java:746)
        at org.apache.lucene.index.IndexingChain.initializeFieldInfo(IndexingChain.java:1393)
        ...
        at org.apache.lucene.index.IndexWriter.addDocument(IndexWriter.java:1492)
        at org.apache.lucene.index.TestFailedAddIndexesCodecReaderSchema.testFailedAddIndexesDoesNotDefineIncomingField(TestFailedAddIndexesCodecReaderSchema.java:59)

# main 5adff78bb168, gradle, seed DEADBEEF: the same with -Ptests.asserts=true and =false
# with the recommended fix: BUILD SUCCESSFUL, 1 test, 0 failures, assertions on and off- The javadoc: after an exception ("for example disk full"), "either no indexes will have been added or they all will have been" (
IndexWriter.java:3084-3086,:3259). - #633 added the non-mutating up-front check to keep this overload transactional; only merge-time failures leave fields behind.
- A field's schema comes from "the first document indexed" with it (
MIGRATE.md); none reached this writer.
The full argument307 words
- Contract.
addIndexes(CodecReader...)refers to theaddIndexesjavadoc "for details on transactional semantics" (IndexWriter.java:3259): "This method is transactional in how Exceptions are handled: it does not commit a new segments_N file until all indexes are added. This means if an Exception occurs (for example disk full), then either no indexes will have been added or they all will have been" (:3084-3086). After the disk-full failure, the incoming index still decides which documents the writer accepts. AndgetFieldNames()is documented as "all field names as visible from this IndexWriter, across all segments of the index" (:2130-2131); after the failed call it listsf, which no segment, flushed or in memory, holds. - The overload avoids it on purpose for validation failures. The commit that added the up-front check,
698f40ad51af(LUCENE-10216, #633), lists "verify field info schemas upfront from incoming readers", "Keep addIndexes API transactional" and "Maintain transactionality - register segments with iw after all merges complete". Segment registration was deferred until the merges complete; field registration was not, so failures found up front leave no residue and failures in the merge do. - Schema definition.
lucene/MIGRATE.md:1586-1593: "The per field data-structures are implicitly defined by the first document indexed that contains a certain field." No document withfreached this writer, and a reopened writer on the same files accepts the document. - Precedent.
lucene/CHANGES.txt:21400-21408(LUCENE-702) madeaddIndexes(*)transactional and fixed other paths "to clean up and keep the instance state consistent to what's actually in the index";:20905-20910(LUCENE-846) fixed a failedaddIndexesthat could "corrupt the instance of IndexWriter (but, not the index itself)". - Tests. Upstream's transactional tests check documents and files only;
TestIndexWriterOnDiskFullrolls the writer back after a failed attempt (TestIndexWriterOnDiskFull.java:383-392), and we found no upstream test that adds a document to the writer after a failedaddIndexes(CodecReader...).
The devil's-advocate check236 words
The strongest case for "accepted behaviour": the javadoc sentence is literally about segments_N and the documents added, and that part holds. The registry only grows within a session by design: field infos are "(almost) append-only" (#9597), and in #13369 (the fix of #13353, failed documents) delaying or reverting the registration was tried and not adopted. On #9738 (LUCENE-8692, 2019) a maintainer (s1monw) listed addIndexes() among the methods whose exceptions "might cause documents go missing etc. but we treated them not as fatal or tragic events since a user could always call rollback()". Upstream's disk-full test rolls back, and getFieldNames is @lucene.experimental (IndexWriter.java:2129-2134).
Why it fails: no javadoc, test or discussion says a failed addIndexes may define a field's schema. In #13353 a document with the field did reach the indexing chain; here none did. rollback() discards all uncommitted work, a heavy remedy for a call that promises all or nothing, and the fix is local to addIndexes, where #633 already defers segment registration. Our reading: a defect (the devil's advocate stayed at "uncertain", not "not real"). The usual counter, "call rollback()", is met by the javadoc, #633 and the validation-versus-merge difference. No javadoc promises to undo in-memory bookkeeping (this is an inconsistency in the writer's session state: a call that adds nothing still changes which documents the writer accepts), and the claim is not that every failed call must undo its schema changes.
Recommended Merge with private field numbers, register at publication (recommended; a tested prototype)
Let the merge number its fields privately and register them only when the merged segment is published, after checking all merges of the call against the writer and against each other. 35 added lines in IndexWriter.java; the repro, a two-block conflict check and every lucene/core test (8,923) pass with it.
// addIndexesReaderMerge: number the merged fields privately
new SegmentMerger(readers, segInfo, infoStream, trackingDir,
    new FieldNumbers(config.getSoftDeletesField(), config.getParentField()), ...);

// addIndexes(CodecReader...), in synchronized (this), before segmentInfos.addAll(infos)
synchronized (globalFieldNumberMap) {
  FieldNumbers check = new FieldNumbers(config.getSoftDeletesField(), config.getParentField());
  for (FieldInfos fis : incoming)
    for (FieldInfo fi : fis) { globalFieldNumberMap.verifyFieldInfo(fi); check.addOrGet(fi); }
  reserveDocs(totalDocs);
  for (FieldInfos fis : incoming)
    for (FieldInfo fi : fis) globalFieldNumberMap.addOrGet(fi);
}
All options and trade-offs3 options · 564 words
Three options. Only the first, recommended one covers both triggers and was validated with gradle; the second is a partial fix and the third a documentation change.
Merge with private field numbers, register at publication (recommended; a tested prototype) (validated by the checks)
In addIndexesReaderMerge, give the SegmentMerger a merge-private FieldNumbers(config.getSoftDeletesField(), config.getParentField()) instead of globalFieldNumberMap (IndexWriter.java:3574) and keep the merge's MergeState.mergeFieldInfos. In addIndexes(CodecReader...), inside the existing synchronized (this) publication block and under synchronized (globalFieldNumberMap), check every merge's fields against the writer (verifyFieldInfo) and against each other (a scratch FieldNumbers), then reserveDocs, then addOrGet them all, before segmentInfos.addAll(infos) (:3366). When a merge fails, drop the kept FieldInfos. One file, 35 insertions and 4 deletions. The core of it:
// addIndexesReaderMerge: number the merged fields privately
new SegmentMerger(readers, segInfo, infoStream, trackingDir,
    new FieldNumbers(config.getSoftDeletesField(), config.getParentField()), ...);

// addIndexes(CodecReader...), in synchronized (this), before segmentInfos.addAll(infos)
synchronized (globalFieldNumberMap) {
  FieldNumbers check = new FieldNumbers(config.getSoftDeletesField(), config.getParentField());
  for (FieldInfos fis : incoming)
    for (FieldInfo fi : fis) { globalFieldNumberMap.verifyFieldInfo(fi); check.addOrGet(fi); }
  reserveDocs(totalDocs);
  for (FieldInfos fis : incoming)
    for (FieldInfo fi : fis) globalFieldNumberMap.addOrGet(fi);
}
Trade-offs
- The new segment's field numbers can differ from the writer's, as segments copied by
addIndexes(Directory...)already can. - A concurrent document that introduces an incoming name with another schema while the merge runs is now accepted, and the
addIndexescall then fails at publication with its files deleted (all or nothing); today that document is rejected. - The cross-check is needed: registering merge by merge still leaves the first merge's fields when a per-reader merge policy splits a conflicting import (executed with an earlier variant of this fix).
- Open #16571 changes
SegmentMerger.cleanupMergeand adds a partitioned-merge guard toaddIndexes(CodecReader...)right afterfindMerges; it leavesmergeFieldInfosalone, but whichever lands second may need a small rebase inIndexWriter.java. - As a prototype, the diff drops the kept
FieldInfosafter theensureOpen()at publication; a final patch should drop them first, so a writer closed in between keeps nothing.
What the checks validated
In a scratch worktree at 5adff78bb168, through gradle, seed DEADBEEF: the repro fails without the fix and passes with it, assertions on and off; the two-block conflict check fails without it and passes with it; with the fix TestAddIndexes, TestIndexWriterOnDiskFull, TestIndexSorting, TestDocValuesIndexing, TestIndexOptions, TestIndexWriterExceptions, TestFieldInfos and TestIndexWriterDelete pass (226 tests, 0 failures, 9 skipped), every lucene/core test passes (752 classes, 8,923 tests, 0 failures, 322 skipped; the two-block check ran separately) and checkGoogleJavaFormat is clean. Earlier, on main e1faeba08bde, the index-sorted and per-reader legs were clean with this fix, and a single-fault enumeration over every file creation and write of one call had 0 violations with the same deferred registration.
Extend the up-front check (IndexWriter.java:3288-3293) to also add every reader's fields to a scratch FieldNumbers, so readers that disagree with each other are rejected before the merge.
Trade-offs
Fixes only the fault-free conflict trigger; an I/O error during the merge still leaves the residue.
State in the javadoc that after a failed addIndexes(CodecReader...) the writer's field schema may contain the incoming fields.
Trade-offs
Contradicts the transactional javadoc and the purpose of the up-front check; rollback() also discards all other uncommitted work.
Services that import indexes into a long-lived writer should reopen or roll back the writer after a failed addIndexes(CodecReader...) until this is fixed; nothing on disk needs repair.
Code reading of IndexWriter's addIndexes failure paths and fault-injection probes (a simulated disk full while the merged segment is written, and an incoming reader whose stored fields throw during the merge) showed the leftover. A semi-formal bounded-exhaustive enumeration then injected one fault at every write of one call: all 14,802 runs left it.
The method in full207 words
Method: non-formal, then semi-formal.
- Code reading of the
addIndexes(CodecReader...)merge and its failure path, and hand-written probes on the stock jar: a simulated disk full while the merged segment is written, and aFilterCodecReaderwhose stored-fields reader throws during the merge. Both left the incoming name registered and a later document rejected; a reopened writer accepted it. - A bounded-exhaustive single-fault enumeration on the stock jar: one
IOExceptionat every destinationcreateOutputand everyIndexOutputwrite of one call, withSerialMergeSchedulerand withConcurrentMergeScheduler, against the javadoc's all-or-none promise (after a failed call that added no document,getFieldNames()is unchanged and every incoming-only name accepts a document with another schema). It found violations in 14,802 of 14,802 runs, in every merge phase after the field-info step (stored fields, norms, terms, doc values, points, vectors,.fnm, compound file,.si); a no-fault control registers and rejects (the oracle is not vacuous) and a validation-time failure leaves nothing. With the deferred registration the enumeration found 0 violations in 14,786 runs. - A later code reading of
addIndexesReaderMergefound the fault-free trigger (theSlowCompositeCodecReaderWrapper.wrapskip for index sorts and blocks, and per-reader merges), executed with probes on main and on releases back to 8.11.4, and reduced to a one-test check.
No matching public report found (2026-11-02 and 2026-11-03, re-checked on GitHub on 2026-11-04). Related items are about other defects: #9738 (which IndexWriter exceptions are tragic), #13353 / #13369 (failed documents keep their field registered) and #9597 (append-only field infos).
Searches7 searches
Related prior items, each about a different defect:
- #9738 (LUCENE-8692, open): which
IndexWriterexceptions should count as tragic. A maintainer states the general stance that a non-tragic failure of methods such asaddIndexes()is followed byrollback(). It names no field schema and predates the up-front check of #633. - #13353 / #13369: a document that fails during indexing leaves its
FieldInforegistered; delaying or reverting the registration in the indexing chain was tried and not adopted. That is the per-document path, notaddIndexes. - #9597 (LUCENE-8551, won't fix): field infos stay "(almost) append-only"; no failed call is involved.
- #633 / #11253 (LUCENE-10216): added the up-front check that keeps validation failures clean; the merge path still registers as it goes.
- #16571 (open PR): changes
SegmentMerger.cleanupMergeand adds a partitioned-merge guard toaddIndexes(CodecReader...); it leaves field registration alone and does not fix this. - LFV-124 (listed here): the same kind of leftover from
addIndexes(Directory...), at another fix site; fixing either does not fix the other.
Searches are term-based and best effort.
| Where | When | How | Found |
|---|---|---|---|
| Scripted prior-report search: GitHub issues, PRs and commits (incl. the JIRA archive), downstream trackers, dev@ / java-user@ / issues@ / commits@, JIRA | 2026-11-02 | two runs (16 issue/PR, 3 commit, 2 downstream, 20 list and 4 JIRA queries; 20 list queries) | 542 and 231 hits, none on topic |
| Manual GitHub searches: apache/lucene; Elasticsearch, OpenSearch, Solr, lucene-solr, Lucene.NET, all of GitHub | 2026-11-02 | 28 and 20 searches; the last 48 hours | related items only |
| Open apache/lucene PRs | 2026-11-02 | changed files of all 410 open PRs; the diffs of the 18 that touch the fix-site files grepped | #16571 touches the fix-site files (cleanupMerge, an addIndexes guard), not a fix |
| JIRA archive and web | 2026-11-02 | 9 JQL queries; 5 web queries | nothing on topic |
| Fault-free trigger: GitHub, downstream, lists, JIRA archive | 2026-11-02 | 23 queries (addIndexes with index sort, blocks or conflicting FieldInfos; SlowCompositeCodecReaderWrapper; mergeFieldInfos) | 181 hits, none about this trigger |
| Re-check | 2026-11-03 | two independent passes | no item describes this defect |
| GitHub, apache/lucene | 2026-11-04 | issues and PRs updated since 2026-11-02 mentioning addIndexes; 3 targeted searches; commits on main touching the three fix-site files | no new item; no commit on the fix site after 5adff78bb168 |
Introduced in 4.2.0 (2013) by the LUCENE-4547 doc-values work (041ff1140f3f), first through addIndexes(IndexReader...); addIndexes(CodecReader...) has it since its first release, 5.0.0. Executed as failing from 4.2.0 through 10.6.0 and on main; 4.1.0 is not affected.
Versions tested7 rows
Introduced by 041ff1140f3f "make DV strongly typed; fix solr" (Michael McCandless, 2012-11-23, on the LUCENE-4547 branch), which gave FieldNumbers a per-field doc-values type that addOrGet enforces; it reached trunk as a181dc073539 and branch_4x as 5cbaddcbc7ff ("LUCENE-4547: DocValues improvements", 2013-02-07/08), first in 4.2.0. No PR (Subversion era).
Precondition: 54d3be3ad36 (LUCENE-2881, 2011, 4.0.0) made the addIndexes merger number its fields through the writer-wide map; until 4.2.0 that map held only names and numbers, so nothing was visible.
Later changes kept the shape: LUCENE-6158 and LUCENE-6165 (5.0.0) renamed the overload to addIndexes(CodecReader...) without changing the merge path; LUCENE-9334 (9.0.0) widened the enforced schema to every per-field attribute (so the repro's exact input conflicts only from 9.0.0); LUCENE-10216 (#633, 9.4.0) added the up-front check but kept the merge over the writer's map; #12622 (9.9.0) wrapped the readers of one merge, so the default configuration rejects a conflicting import cleanly, and #13128 (9.11.0) skips that wrap when readers have blocks but no parent field; since then the fault-free trigger needs an index sort, that blocks case or per-reader merges.
Releases between the executed ones were not run; a read of every release tag from 4.2.0 to 10.6.0 shows the addIndexes merger built over the writer's map. Not new in 10.6.
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 (12.0.0-SNAPSHOT) | affected | gradle: the repro fails with assertions on and off; passes with the fix |
main e1faeba08bde | affected | the repro fails with assertions on and off, 30 of 30 random seeds; the fault-free two-block check fails too |
| 10.6.0, 10.5.2, 9.12.3 | affected | the repro fails on the release jars; the fault-free trigger reproduces on index-sorted, blocks and per-reader legs |
| 9.0.0 | affected | an adapted copy of the test with the repro's exact input fails |
| 8.11.4, 7.7.3, 6.6.6, 6.0.0, 5.5.5, 5.0.0 | affected | fail in the doc-values-type form (SORTED then NUMERIC); the repro's exact input is not a conflict before 9.0.0 |
| 4.10.4, 4.2.0 | affected | fail through addIndexes(IndexReader...) |
| 4.1.0 | not affected | its FieldNumbers holds no schema, so the leftover registration has no visible effect |
Confirmed by an independent reproducer, executing reviews from another model family (OpenAI GPT-5.6) and an adjudication, each with own tests or controls; a devil's advocate reproduced it and stayed uncertain about intent. This doc's test was re-run with gradle on main, and the fix was validated against every lucene/core test.
Checks and verdicts250 words
Every executing check wrote or ran its own test on the stock jars, with passing controls (no fault: the rejection is then correct; a reopen clears the residue; a validation-time failure leaves nothing). Most ran on main e1faeba08bde, where the cited files have the same lines.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Own test in the mirror direction (doc values incoming, StringField later), the fault armed only while the merge runs: fails on main (assertions on and off), 10.6.0, 10.5.2 and 9.12.3; 4 controls pass; ConcurrentMergeScheduler behaves the same. |
| cross-model review, refute lens | real, high | An independent reviewer from another model family (OpenAI GPT-5.6), executing: own binary-then-sorted doc-values test fails, controls pass, passes with the fix; a later pass reproduced the index-sorted trigger while an unsorted control passed. |
| cross-model review, intended-behaviour lens | real, high | Same reviewer family, executing: rated the "segments only, append-only registry" reading moderate and rejected it. |
| devil's advocate | uncertain (not "not real") | Reproduces on main and 10.6.0; built the strongest counter-case (see the devil's-advocate check above); found no document saying a failed addIndexes may define a schema. |
| adjudication, credibility re-check | confirmed (high); Low, minor | Re-runs fail on main with new seeds; an independent default-configuration program shows the same; one minimal deterministic test. |
| this doc: gradle fix check | reproduced; fix validated | Scratch worktrees at 5adff78bb168: the repro fails without the fix and passes with it; 8,923 lucene/core tests pass with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 477 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,992 words
- Registry title
- A failed addIndexes(CodecReader...) leaves the incoming fields registered in the writer's field schema, so later valid documents that use those names differently are rejected until the writer is reopened
- Area
- index / IndexWriter addIndexes(CodecReader...) merge (SegmentMerger) and the writer-wide field registry (FieldInfos.FieldNumbers)
- Priority
- Low, rank 841: After an I/O failure during addIndexes(CodecReader...), the writer keeps the incoming field registrations and rejects later documents that use those names differently until it is reopened. The failure is loud and nothing is corrupted, and it needs an application that keeps using the writer after the failure, so it is Low.
- Impact class
- minor
- Impact note
- Hits applications that keep using an IndexWriter after an addIndexes(CodecReader...) call failed, in two ways: (1) the call is rejected because two incoming indexes disagree on a field's schema (a user error Lucene rightly rejects) on a writer with an index sort, or when the incoming indexes contain document blocks and have no parent field, or with a merge policy whose findMerges(CodecReader...) returns one merge per reader, and on every release before 9.9.0 with the default configuration; (2) an I/O error (for example a full disk) interrupts the merge, with any configuration. From then on every document that gives one of the incoming field names another schema is rejected with IllegalArgumentException, getFieldNames() lists those names, and retrying the import with only the second index (the one whose schema differs from the registered residue) is rejected too, until the writer is reopened, rolled back or deleteAll() is called; nothing on disk is corrupted, nothing of the failed import becomes visible, after an I/O error (2) a retry of the same import works, and documents without those names are unaffected; ordinary scale; every release from 4.2.0 through 10.6.0 (through addIndexes(IndexReader...) before 5.0.0).
- Summary
- You import an index with IndexWriter.addIndexes(CodecReader...) and the call fails with an IOException (for example a full disk) while the merged segment is written; as its javadoc promises, no documents are added, and the writer stays open. You expect the writer to behave as if the call had never happened, so that a later document may use an imported field name with any schema, as it may on a fresh or reopened writer and after a validation-time failure of the same call. Instead the merge has already registered every incoming field in the writer-wide field schema before it failed, and nothing undoes that: a later document with NumericDocValuesField("f") is rejected ('cannot change field "f" from index options=DOCS to inconsistent index options=NONE') although no document with "f" was ever indexed into this writer, until the writer is reopened. No I/O error is needed: on a writer with an index sort, when the incoming indexes contain document blocks without a parent field, or with a merge policy that returns one merge per incoming reader, two incoming indexes that use a field differently make the call fail with IllegalArgumentException and leave the first index's schema registered in the same way, so a later document, or an import of only the second index, is rejected; before 9.9.0 every conflicting two-reader import did so.
- Introduced
- 041ff1140f3f207ab0a3571c92a738b328142e95 (author Michael McCandless, 'make DV strongly typed; fix solr', on the LUCENE-4547 development branch; LUCENE-4547 = apache/lucene#5613; svn era, no pull request), which gave FieldInfos.FieldNumbers a per-field doc-values type that addOrGet enforces; it reached trunk as a181dc07353 (2013-02-07) and branch_4x as 5cbaddcbc7f (2013-02-08), both 'LUCENE-4547: DocValues improvements'. Precondition: 54d3be3ad36 (LUCENE-2881 = apache/lucene#3955, Simon Willnauer, 2011-03-22, first in 4.0.0) made the addIndexes merger number its fields through the writer-wide globalFieldNumberMap instead of a private clone, so a failed merge already left the incoming names registered, with no visible effect while the map held only name-to-number. The CodecReader overload inherited the path when addIndexes(IndexReader...) was renamed by LUCENE-6158 (e2b348cef08) and LUCENE-6165 (1a394ff3950), both before 5.0.0; LUCENE-9334 (d03662c48bf, apache/lucene#10374, 9.0.0) widened the enforced schema to every per-field attribute; LUCENE-10216 (698f40ad51a, PR #633, 9.4.0) added the non-mutating up-front verifyFieldInfo but kept the merge over globalFieldNumberMap [read: diffs and blame in the full-history clone; exec: 4.1.0 passes, 4.2.0 fails] (2012-11-23 (author date of 041ff1140f3 on the LUCENE-4547 branch); landed on trunk 2013-02-07 (a181dc07353) and branch_4x 2013-02-08 (5cbaddcbc7f); 4.2.0 released 2013-03)
- First affected version
- 4.2.0 [exec: a version of the test through addIndexes(IndexReader...), the overload's predecessor, fails with 'cannot change DocValues type from SORTED to NUMERIC for field "f"' and its reopen control passes; 4.1.0 passes]; addIndexes(CodecReader...) itself from 5.0.0, its first release [exec]; fault-free conflicting-import trigger: with the default configuration on every executed release up to 9.8.0 (8.11.4 in its doc-values-type form, 9.0.0 and 9.8.0 [exec: version-adapted tests; the 9.9.0 control passes]); from 9.9.0 (#12622 added the wrap) only on index-sorted writers or with a per-reader merge policy, and from 9.11.0 (#13128) also with incoming blocks without a parent field [exec: the 9.10.0 blocks leg is clean, 9.12.3 fails]
- Affected versions
- every release from 4.2.0 (as addIndexes(IndexReader...)) and from 5.0.0 (addIndexes(CodecReader...)) through 10.6.0 (4ae946e5a9b), and main e1faeba08bde (unreleased) [exec: the one-test JUnit fails on main e1faeba with -ea and -da (finder, the independent reproduction, the intended-behaviour check, judge and a separate re-run; 30 of 30 with --iters 30), and on 10.6.0, 10.5.2 and 9.12.3; the version-adapted tests fail on 9.0.0 (the JUnit's exact index-options scenario), on 8.11.4, 7.7.3, 6.6.6, 6.0.0, 5.5.5 and 5.0.0 (doc-values-type form) and on 4.10.4 and 4.2.0 (through addIndexes(IndexReader...)), each with its reopen control passing; 4.1.0 passes (its FieldNumbers held no schema); read: a scan of every x.y.z release tag from 4.2.0 to 10.6.0 finds the addIndexes SegmentMerger built over globalFieldNumberMap; releases in between were not executed]; the JUnit's exact trigger (an indexed StringField against a doc-values-only field) is a conflict only from 9.0.0 (LUCENE-9334) on, and on 8.11.4 that input passes while the doc-values-type form fails [exec]; not fixed upstream: upstream main head is still e1faeba08bde (checked 2026-11-02) and no open PR changes the registration or the addIndexes failure path [read]; fault-free trigger (2026-11-02, -da unless stated): the one-test JUnit TestRejectedAddIndexesConflictingReadersSchema (blocks without a parent field) fails on main e1faeba08bd with -ea and -da and on 10.6.0 and 10.5.2; a four-leg probe (plain, index-sorted, blocks, per-reader merges) leaves residue on the sorted, blocks and per-reader legs with a clean plain leg on main (-ea and -da), 10.6.0, 10.5.2 and 9.12.3, sorted and per-reader residue with clean plain and blocks legs on 9.10.0, and residue on all four legs on 9.8.0; the plain default-config adapted test fails on 8.11.4, 9.0.0 and 9.8.0 and passes on 9.9.0 and main
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by code reading, exhaustive check
- Upstream and prior reports
- no report of this bug found (2026-11-02, read-only, on top of the finder's two scripted prior-report searches of 51 and 53 queries and the independent reproduction's and the intended-behaviour check's GitHub searches): two more scripted prior-report searches (one with 16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list and 4 JIRA queries, 542 distinct hits, none on topic; one with 20 mailing-list queries over dev@, java-user@, issues@ and commits@, 231 hits, none on topic); 28 manual GitHub queries on apache/lucene and 20 across Elasticsearch, OpenSearch, Solr, lucene-solr, Lucene.NET and all of GitHub; all 410 open apache/lucene PRs with their changed files, the diffs of 18 that touch the fix-site files grepped; 9 JIRA-archive JQL queries; 5 web queries; items updated or created in the last 48 hours; a later refresh (addIndexes, FieldInfos and SegmentMerger items updated since 2026-11-01: only the unrelated sandbox PR #16357; upstream main head still e1faeba08bde). Partial, class-level overlap: open #9738 (LUCENE-8692, 2019), where a maintainer (s1monw) lists addIndexes() among the IndexWriter methods whose exceptions may leave data loss or inconsistencies and are not tragic 'since a user could always call rollback()'; it names no field schema and predates the up-front verify of #633. Related, not this bug: #13353 / #13369 (a failed document leaves a FieldInfo registered; reverting was rejected for the indexing chain), #9597 (LUCENE-8551, won't fix: field infos '(almost) append-only'), #2835 (LUCENE-1761, open), #633 / #11253 (LUCENE-10216: up-front verify to keep the CodecReader overload transactional), #3955 (LUCENE-2881), #1777 (LUCENE-702), #1921 (LUCENE-846), #13116, #11684, SOLR-15356; open #16571 changes SegmentMerger.cleanupMerge and adds a partitioned-merge guard to addIndexes(CodecReader...); it leaves mergeFieldInfos and the registration alone and does not fix this. Not fixed upstream. Refresh for the fault-free trigger (2026-11-02, read-only): 23 queries over apache/lucene issues, PRs and commits, downstream trackers, the mailing lists and the JIRA archive on addIndexes with an index sort, blocks or conflicting FieldInfos, SlowCompositeCodecReaderWrapper, addIndexesReaderMerge and mergeFieldInfos: 181 hits, none about this trigger; #13353/#13369 (failed documents keep FieldInfo registrations; reverting was judged too sharp) were re-read and concern documents, not addIndexes.
- Lucene commit tested
- main
5adff78bb168(12.0.0-SNAPSHOT) through gradle in fresh scratch worktrees: the one-test repro fails with assertions on and off and passes with the recommended fix; with the fix, a two-block conflict check passes, 8 closest suites pass (226 tests), everylucene/coretest passes (752 classes, 8,923 tests, 0 failures) andcheckGoogleJavaFormatis clean. The repro file as shown was also run with the plain JUnit runner on the main jars, stock and with the fixedIndexWriter. The hunt's runs were on maine1faeba08bde(the cited files have the same lines: the only later change toIndexWriter.javais #16963, an infoStream message at lines 3888-3889, off this path) and on the 10.6.0, 10.5.2, 9.12.3 and older release jars. Upstream mainc1eb27be5ef6(2026-11-04) has no later change toIndexWriter.java,SegmentMerger.javaorFieldInfos.java.
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3084-3086 (at e1faeba08bde) (transactional addIndexes javadoc: 'if an Exception occurs (for example disk full), then either no indexes will have been added or they all will have been'), :3259 (the CodecReader overload refers to it), :3288-3293 ('Best effort up front validations': non-mutating globalFieldNumberMap.verifyFieldInfo), :3316-3324 (failure path deletes only the merge files), :3561 (SlowCompositeCodecReaderWrapper.wrap), :3568-3576 (addIndexesReaderMerge builds the SegmentMerger over globalFieldNumberMap: fix site), :2129-2137 (getFieldNames, @lucene.experimental), :3176-3182 (LFV-124's addOrGet loop in addIndexes(Directory...), not on this path)lucene/core/src/java/org/apache/lucene/index/SegmentMerger.java:75 (at e1faeba08bde) (fieldInfosBuilder = new FieldInfos.Builder(fieldNumbers)), :121 (merge() calls mergeFieldInfos() first), :123 (stored fields next), :233-239 (mergeFieldInfos adds every incoming FieldInfo)lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:415 (at e1faeba08bde) (FieldNumbers.addOrGet validates and registers), :694 (clear(), the only removal), :788 (Builder.add -> globalFieldNumbers.addOrGet)lucene/MIGRATE.md:1571-1578 (at e1faeba08bde) ('Require consistency between data-structures on a per-field basis': the per-field structures are implicitly defined by the first document indexed with the field)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3549-3566 (at e1faeba08bde) (addIndexesReaderMerge: hasIndexSort / hasBlocksButNoParentField skip SlowCompositeCodecReaderWrapper.wrap, the only place where two incoming readers' FieldInfos are checked against each other before registration), :3264-3267 (javadoc: findMerges(CodecReader...) may be overridden to split the readers into several merges), :3292 (up-front verifyFieldInfo compares each reader with the writer only)full-history clone: f7cab164501 / 6b1538b3313 (#12622, 2023-11-23, first in 9.9.0) added the wrap with the index-sort skip; 4a3f4cfe974 / 2e503b65754 (#13128, 2024-03-29, first in 9.11.0) added the blocks-without-parent skip
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1124, 2135-2137, 2800, 3264-3267, 3275, 3288-3293, 3312, 3316-3324, 3376-3384, 3390-3393, 3491, 3549-3566, 3568-3577, 3600, 3620-3641lucene/core/src/java/org/apache/lucene/index/SegmentMerger.java:75, 121, 123, 232-239lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:196-218, 401-408, 415, 422, 694-698, 788
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3084-3086 ("for example disk full"), 3259, 3264-3267
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:2129-2134 (2130-2131 quoted), 3084-3086, 3259lucene/MIGRATE.md:1586-1593lucene/CHANGES.txt:20905-20910 (LUCENE-846), 21400-21408 (LUCENE-702)lucene/core/src/test/org/apache/lucene/index/TestIndexWriterOnDiskFull.java:383-392https://github.com/apache/lucene/issues/9738 (s1monw, 2019-03-06 comment)
- Suggested fix
https://github.com/apache/lucene/pull/16571 (open; changes SegmentMerger.cleanupMerge and adds a partitioned-merge guard to addIndexes(CodecReader...); leaves mergeFieldInfos alone)
- TestFailedAddIndexesCodecReaderSchema.java (lucene/core, one test):
repro/LFV-1081/TestFailedAddIndexesCodecReaderSchema.java(63 lines)
A picture of the writer's field registry through the failed call and the later document; its values come from executed runs of the repro and a probe on main.
assets/LFV-1081/bug.png(477 KB)