Where a segment's index sort matches the search sort, Lucene stops early and should skip all points work there. Since #16857 the only off-switch is a call the wrapper does not forward, but the comparator reads a threshold flag that all segments share, so an earlier segment switches the work back on.
search(query, n, sort)counts hits exactly up to a threshold, 1,000 by default. Past it, Lucene may skip documents that cannot enter the top n.- Points-based skipping: for a numeric sort field indexed with points, the comparator asks the points (BKD) index which documents can still beat the current n-th value and visits only those. It does so only when that cuts the documents to visit at least 8x.
- Index-sort early termination: in a segment already stored in the search's sort order, Lucene simply stops at the first document that cannot compete. Points-based skipping is then wasted work, and since 10.6.0 Lucene has switched it off per segment.
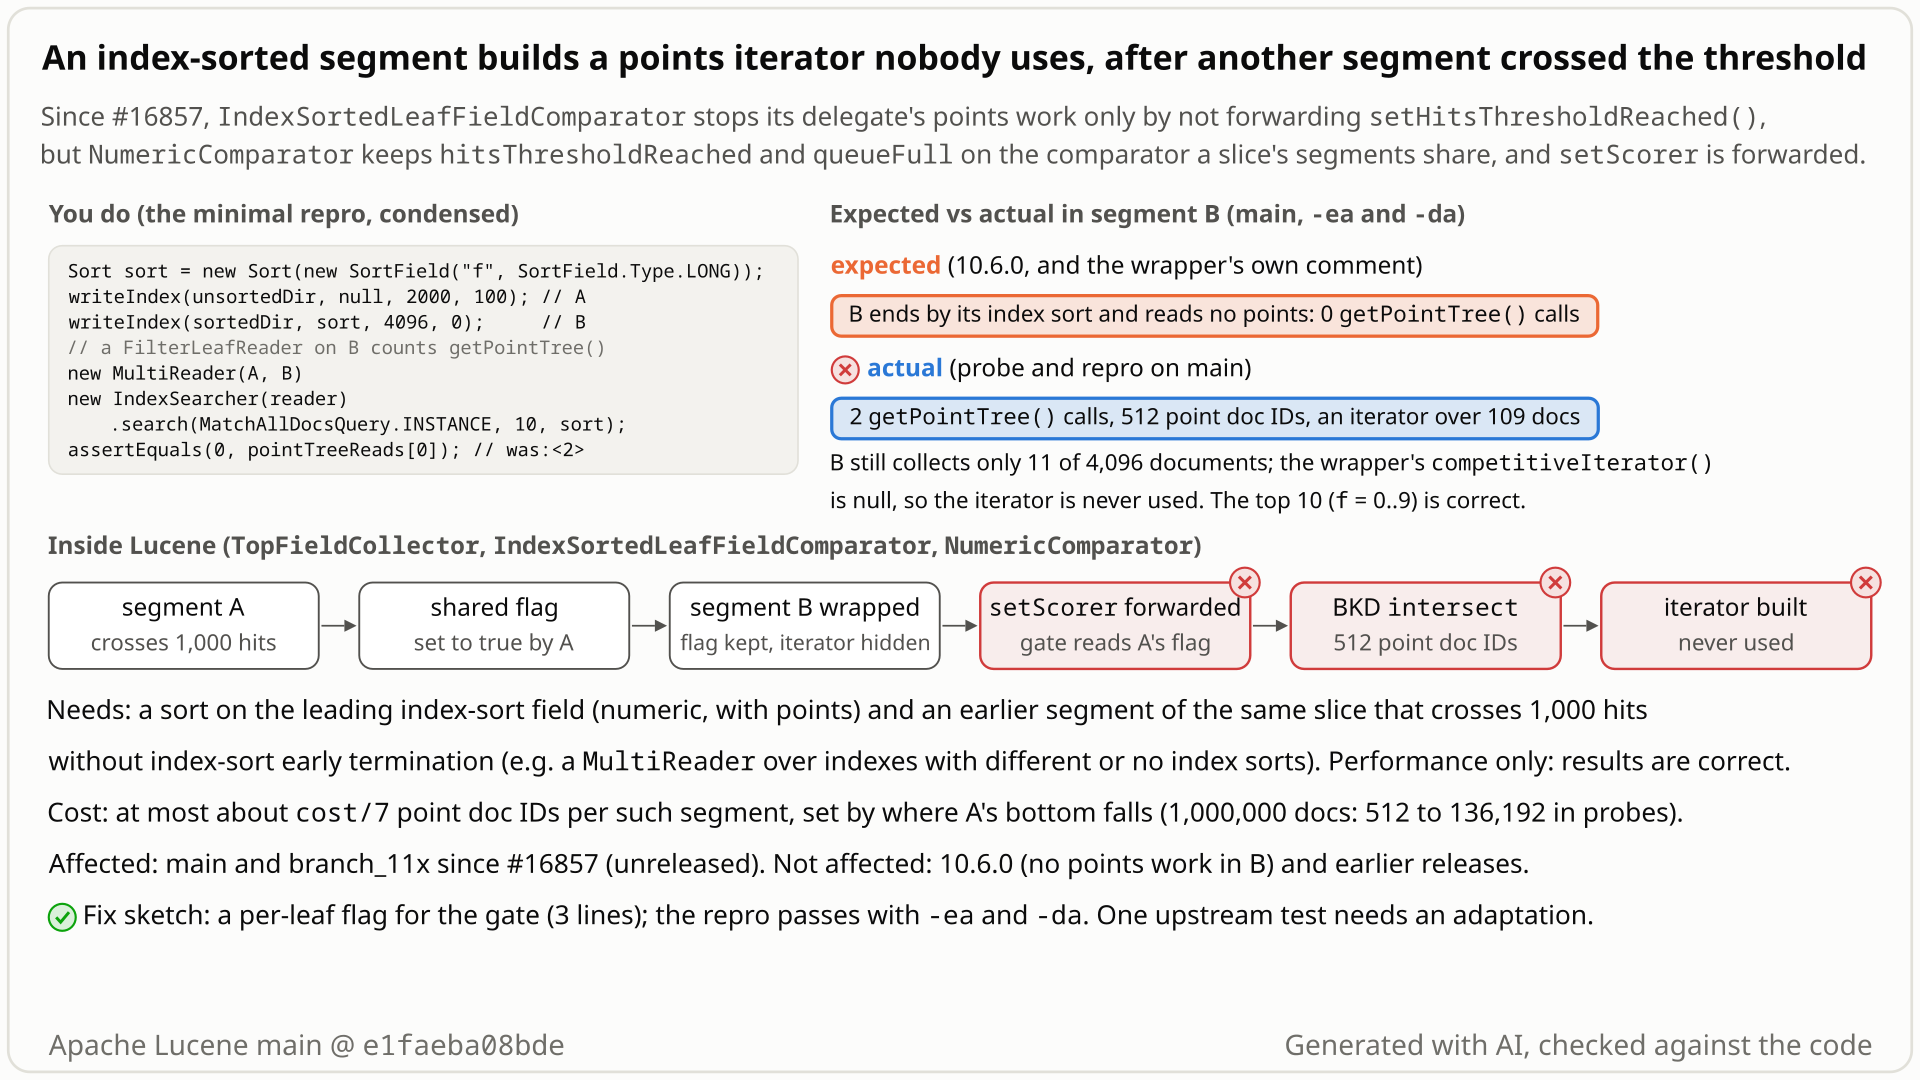
- Search a
MultiReaderover two indexes for the top 10 by a long fieldf. Index A has no index sort: 2,000 docs,f= 100 to 2,099. Index B is index-sorted byf: 4,096 docs,f= 0 to 4,095. - A is searched first. Its 2,000 hits cross the default threshold of 1,000, and the top 10 so far is
f= 100 to 109. - You expect B to do no points work: it is stored in
forder, so Lucene stops after 11 docs, and #16857's ownIndexSortedLeafFieldComparatorcalls building iterators from points there "redundant work". 10.6.0 opens B's point tree 0 times. - Instead, B's comparator sees the threshold flag that A set on the comparator all segments share. It estimates
f <= 108as selective (under 4,096 / 8 = 512 docs) and intersects B's BKD tree: 2 point-tree opens, 512 point doc IDs, and the iterator is never used. The top 10 (f= 0 to 9) is still right. - How much is wasted depends on where A's bottom falls in B; only the ceiling grows with the segment, at most about 1/7 of its matching docs. A 1,000,000-doc B reads 512 point doc IDs after this A, 125,440 when A's top 10 starts at
f= 124,700 and 136,192 after a spread top 10; indicatively 1.3x to 3x slower searches on that shape.
Users of main or branch_11x (11.0.0 unless fixed) who sort by the leading field of an index sort, a numeric points field, when an earlier segment of the same search is not terminated early and has over 1,000 hits: a MultiReader over differently sorted indexes, block and non-block segments, or a constant leading index-sort field. Results are correct.
Mechanism, terms and numbers687 words
Since #16857 ("Consolidate Sort pruning logic", merged 2026-10-29 to main and branch_11x, in no release), a segment whose index sort starts with the search sort gets its comparator wrapped in the new IndexSortedLeafFieldComparator (FieldValueHitQueue.java:190-191 at e1faeba08bde). When not paging, the wrapper avoids the delegate's skipping work, which its own comment calls "redundant work: it measurably slows down index-sorted searches" (IndexSortedLeafFieldComparator.java:31-33), only by hiding competitiveIterator() and not forwarding setHitsThresholdReached() (:86-97). But NumericComparator keeps hitsThresholdReached and queueFull on the comparator that every leaf shares (comparators/NumericComparator.java:59-60). Once an earlier segment of the same slice that is not terminated early has crossed the threshold, the wrapped segment's points builder passes its gate (:222-228) on the forwarded setScorer and setBottom calls, estimates the competitive range and, when it is selective, intersects the BKD tree (:426-445). The iterator is never used. 10.6.0 called disableSkipping() on such segments, which dropped the builder. Performance only: the hits are correct.
- Hits threshold:
IndexSearcher#search(query, n, sort)counts hits exactly up toTOTAL_HITS_THRESHOLD= 1,000 (IndexSearcher.java:100). The 1,001st hit makescountHit()callcomparator.setHitsThresholdReached()(TopFieldCollector.java:64-77); a leaf collector created after that is told in its constructor (:56-59). - Competitive iterator: once the threshold is reached and the queue is full,
NumericComparator'sPointsCompetitiveDISIBuilderestimates how many points fall in the range that can still enter the top n and, when that is underiteratorCost >>> 3(8x fewer than the query matches), intersects the BKD tree and hands the collector an iterator over the result (comparators/NumericComparator.java:363-446). - Index-sort early termination:
FieldValueHitQueue.getLeafComparatorwraps the comparator of each segment whose index sort starts with the search sort inIndexSortedLeafFieldComparator(FieldValueHitQueue.java:177-194, decided per segment,:202-214). It throwsCollectionTerminatedExceptionat the first non-competitive document once the threshold is reached (IndexSortedLeafFieldComparator.java:59-69).
- When not paging, the wrapper returns
nullfromcompetitiveIterator()(IndexSortedLeafFieldComparator.java:86-89) and does not forwardsetHitsThresholdReached()(:91-97). Its comment explains why (:31-33): "Otherwise collection terminates anyway and the delegate's skipping, e.g. building iterators from points, is redundant work: it measurably slows down index-sorted searches." It still forwardssetBottom(:53-56) andsetScorer(:81-84); it has to, becausecompareBottomneeds the bottom and other comparators of a multi-field sort need the scorer. - The points builder's gate reads fields of the top-level comparator,
protected boolean hitsThresholdReached; protected boolean queueFull;(NumericComparator.java:59-60), shared by every leaf comparator:if (hitsThresholdReached == false) return;andif (leafTopSet == false && queueFull == false) return;(:222-228). - An earlier segment that is not terminated early sets both:
countHit()->NumericLeafComparator.setHitsThresholdReached()(:153-159) andsetBottom()(:131-137). - In the index-sorted segment, the forwarded
setScorer()reachesPointsCompetitiveDISIBuilder.setScorer(), which takes the query's cost and runs the segment's first update, "update an iterator when we have a new segment" (:345-355); each forwardedsetBottom()runs another. The gate passes, the estimate walks the tree (:426-429) and, when the range is selective,pointValues.intersect(visitor)builds an iterator (:441-445) that the wrapper never exposes.
Before #16857, 10.6.0's TopFieldCollector said "Early termination handles this segment; skipping work in the comparator is redundant." and called comparator.disableSkipping() on each such segment (TopFieldCollector.java:69-74 at 10.6.0), which set competitiveDISIBuilder = null (comparators/NumericComparator.java:110-114 at 10.6.0). #16857 removed disableSkipping (CHANGES 11.0.0, MIGRATE.md:31-32). queueFull being search-wide is legitimate; the comparator-wide hitsThresholdReached is what defeats the wrapper's only off-switch.
Repro data (2,000 unsorted docs with f = 100 to 2,099, then 4,096 docs index-sorted by f, top 10 by f): when the sorted segment starts, the bottom is f = 109, so the competitive range is f <= 108. Its estimate is under 4,096 / 8 = 512, so it intersects one 512-point BKD leaf. The segment stops after 11 of its 4,096 docs. On main the test counts 2 point-tree opens (the estimate's tree and the one inside intersect), and the earlier counting version of the test counts 512 point doc IDs; 10.6.0 and main before #16857: 0.
Exposure and likelihood688 words
- Who. Anyone on main or branch_11x code (so 11.0.0 unless fixed, and downstream projects on Lucene snapshots) who calls
IndexSearcher#search(query, n, sort)sorted by the leading field of the index sort, a numeric field indexed with points plus doc values (a timestamp, a price), and whose search reaches such a segment after an earlier segment that the index sort does not terminate early has crossed the threshold. Executed trigger shapes (100,000-doc sorted segment after an earlier top 10 fromf= 10,000: 10,752 point doc IDs on main, 0 with the fix, top 10 correct in each):- a
MultiReaderover indexes with different or no index sorts (the GITHUB#14399 use that 10.6.0 added per-segment support for; the repro); - one index with a parent field that mixes segments with and without document blocks (block segments are not terminated early since #16947);
- one index sorted by
(k, f)wherekis constant in some segments, searched byf(#16857's no-op leading field path,FieldValueHitQueue.java:210-213); - a two-field search sort
[f, g]over an[f, g]index sort (512 point doc IDs with the repro's data).
- a
- Conditions in the segment. The points builder exists only for the first sort field when that field has points (
NumericComparator.java:98-106); the gate also returns when docs without the field make the missing value competitive (:230-233); and an intersection runs only when the competitive range is under 1/8 of the current cost (:426-441), otherwise an update stops after the estimate walk. - Default vs opt-in. Default codec,
IndexSearcherand threshold, assertions on or off; but index sorting is opt-in and the mixed layout is uncommon. Without an executor one collector sees every segment (IndexSearcher.java:226-231); with one, only an earlier segment of the same slice counts (a segment over 250,000 docs gets its own slice,:106); that is a property of the current implementation (each slice's collector creates its own comparators,TopFieldCollectorManager.java:112-114), not an API guarantee. Order matters: a sorted segment before the unsorted one wastes nothing. - Cost. Each intersection reads about as many point doc IDs as fall in the competitive range (whole BKD leaf blocks of 512) and runs only when the estimate is under 1/8 of the current iterator cost (
NumericComparator.java:426-441); each latersetBottom-time intersection must cut the cost 8x again. So the total per affected segment is at most aboutcost / 7(cost/8 + cost/64 + ..., plus up to a leaf block of slack per intersection), plus one estimate walk per update. How much of that ceiling is used depends on where the earlier segment's bottom falls in the sorted segment (the sorted segment counts 11 docs and the top 10 is correct in every run):
| index-sorted segment | earlier segment's top 10 | point doc IDs read on main | 10.6.0 / with the fix |
|---|---|---|---|
| 4,096 docs (the repro data) | f from 100 | 512 (one BKD leaf) | 0 / 0 |
| 100,000 docs | f from 10,000 | 10,752 | 0 / 0 |
| 1,000,000 docs | f from 100 | 512 | not run |
| 1,000,000 docs | f from 124,700 (range just under cost/8) | 125,440 (245 BKD leaves, 2 intersections) | 0 / 0 |
| 1,000,000 docs | spread: 150, 1,200, 14,000, 120,000, then 2,000,000 and up | 136,192 (266 BKD leaves, 3 intersections, all at setBottom time; above cost/8 = 125,000; an independent fact check's probe) | 0 / 0 |
- Rough wall-clock (indicative only: shared aarch64 host, 2 CPUs, JDK 25, medians of 9 x 400 searches, 2 runs): 2,000 unsorted + 1,000,000 sorted docs, top 10. Typical bottom (
ffrom 100): 103.1 / 97.5 us per search on main vs 76.3 / 73.7 us with the fix (about 1.3x). A bottom just under cost/8 (ffrom 124,700): 203.8 / 185.4 vs 68.4 / 68.0 us (about 2.7-3x). - Not part of this finding. Wrong results: none seen (top hits and totals identical in every shape; an exhaustive multi-leaf harness found 0 wrong results). The STRING sort (
TermOrdValComparatorhas the same comparator-wide flag; a probe saw 9postings()opens vs 0 in a 100,000-doc terminated segment, not verified independently) and the doc-values-skipper builder (iterator object only, no skipper reads).
One JUnit test method: a MultiReader over 2,000 unsorted docs and 4,096 docs index-sorted by f, MatchAllDocsQuery, top 10 by f; a FilterLeafReader counts how often the sorted segment opens its point tree. Deterministic, single thread; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.LongPoint;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.FilterLeafReader;
import org.apache.lucene.index.IndexReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LeafReader;
import org.apache.lucene.index.MultiReader;
import org.apache.lucene.index.PointValues;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.index.AssertingLeafReader.AssertingPointValues;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestIndexSortedSegmentPointsWork extends LuceneTestCase {

  public void testEarlyTerminatedSegmentReadsNoPoints() throws IOException {
    Sort sort = new Sort(new SortField("f", SortField.Type.LONG));
    try (Directory unsortedDir = newDirectory();
        Directory sortedDir = newDirectory()) {
      writeIndex(unsortedDir, null, 2000, 100);
      writeIndex(sortedDir, sort, 4096, 0);
      try (DirectoryReader unsorted = DirectoryReader.open(unsortedDir);
          DirectoryReader sorted = DirectoryReader.open(sortedDir)) {
        int[] pointTreeReads = new int[1];
        LeafReader sortedLeaf =
            new FilterLeafReader(getOnlyLeafReader(sorted)) {
              @Override
              public PointValues getPointValues(String field) {
                return new AssertingPointValues(super.getPointValues(field), maxDoc()) {
                  @Override
                  public PointTree getPointTree() throws IOException {
                    pointTreeReads[0]++;
                    return super.getPointTree();
                  }
                };
              }

              @Override
              public CacheHelper getCoreCacheHelper() {
                return null;
              }

              @Override
              public CacheHelper getReaderCacheHelper() {
                return null;
              }
            };
        try (IndexReader reader =
            new MultiReader(new IndexReader[] {getOnlyLeafReader(unsorted), sortedLeaf}, false)) {
          new IndexSearcher(reader).search(MatchAllDocsQuery.INSTANCE, 10, sort);
          // expected 0: the index-sorted segment terminates early; actual on main: 2 BKD tree reads
          assertEquals(0, pointTreeReads[0]);
        }
      }
    }
  }

  private static void writeIndex(Directory dir, Sort indexSort, int numDocs, long firstValue)
      throws IOException {
    IndexWriterConfig iwc = new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec());
    if (indexSort != null) {
      iwc.setIndexSort(indexSort);
    }
    try (IndexWriter w = new IndexWriter(dir, iwc)) {
      for (int i = 0; i < numDocs; i++) {
        Document doc = new Document();
        doc.add(new LongPoint("f", firstValue + i));
        doc.add(new NumericDocValuesField("f", firstValue + i));
        w.addDocument(doc);
      }
    }
  }
}
cp $REPRO/TestIndexSortedSegmentPointsWork.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestIndexSortedSegmentPointsWork -Ptests.seed=DEADBEEF
# also with -Ptests.asserts=false: same failure
- Expected
- 0 point-tree opens in the index-sorted segment, as on 10.6.0 and on main before #16857.
- Observed
AssertionError: expected:<0> but was:<2>on maine1faeba08bde, assertions on and off; the top 10 is unchanged.
More files, environment, full output328 words
TestIndexSortedSegmentPointsWork (one method, extends LuceneTestCase). Each index is written with the default codec (TestUtil.getDefaultCodec()) in one IndexWriter session, so each is one segment; the searcher is a plain new IndexSearcher(reader) (one slice, no executor). The sorted segment's PointValues are wrapped in the test framework's AssertingPointValues, overriding getPointTree() to count. Same outcome with seed DEADBEEF (-ea and -da) and with seeds C0FFEE and 7A11CE (-ea, in the fact check's runs). The test asserts only the tree opens; the correct top 10 and the 11 docs collected come from the earlier counting test and a separate probe.
It uses the main signatures; for 10.x add throws IOException to the getPointValues override, nothing else (the 10.6.0 runs of this test used such a port; the hunt's separate 10.x port is of the earlier test). The commit bracket and the 10.5.2 and 9.12.3 runs used an earlier, longer version of the test (a counting PointTree wrapper that also checks the top 10), which counts 512 point doc IDs where this one counts 2 tree opens.
As a regression test the same method can go into TestTopFieldCollectorEarlyTermination or stay its own class; fix A also needs the TestNumericComparator adaptation (see the fixes).
| lucene | main e1faeba08bde (12.0.0-SNAPSHOT): fails; main 645d4fe14a20 (before #16857) and 10.6.0: pass |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestIndexSortedSegmentPointsWork.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestIndexSortedSegmentPointsWork -Ptests.seed=DEADBEEF
# gradle, scratch worktree at main e1faeba08bde, -Ptests.seed=DEADBEEF (asserts on; again with -Ptests.asserts=false)
TestIndexSortedSegmentPointsWork > testEarlyTerminatedSegmentReadsNoPoints FAILED
    java.lang.AssertionError: expected:<0> but was:<2>
        at org.apache.lucene.search.TestIndexSortedSegmentPointsWork.testEarlyTerminatedSegmentReadsNoPoints(TestIndexSortedSegmentPointsWork.java:74)
1 test completed, 1 failed

# same worktree + the per-leaf flag fix and the TestNumericComparator adaptation
TestIndexSortedSegmentPointsWork: 1 test, 0 failures (asserts on and off)

# standalone JUnit runner, seed DEADBEEF, -ea and -da
main e1faeba08bde        1 run, 1 failure    expected:<0> but was:<2>
main 645d4fe14a20        1 run, 0 failures   (predates #16857)
10.6.0 (4ae946e5a9b) 1 run, 0 failures (10.x signature port)- #16857's new wrapper says points work in such a segment "is redundant work: it measurably slows down index-sorted searches".
- 10.6.0 switched it off per segment on purpose (
disableSkipping, GITHUB#14399); #16857 removed that switch as a consolidation. - Not forwarding one call cannot stop work gated by a flag that every segment shares.
The full argument250 words
- The PR's own words.
IndexSortedLeafFieldComparator.java:31-33(#16857,e1faeba08bde): "When paging, docs before the top value never fill the queue, so only the delegate can skip them. Otherwise collection terminates anyway and the delegate's skipping, e.g. building iterators from points, is redundant work: it measurably slows down index-sorted searches." - The released design. 10.6.0's
LeafFieldComparator#disableSkippingjavadoc (LeafFieldComparator.java:115-122at 10.6.0): "Called by TopFieldCollector when the search sort is a prefix of this segment's index sort, so the collector can already terminate early and any extra skipping work in the comparator is redundant. This is a per-segment decision: a MultiReader may combine segments with different index sorts." CHANGES 10.6.0 (GITHUB#14399): "...so document skipping can be disabled per segment." - Older precedent. LUCENE-9599 (#10639, 2020): "As the early termination in this case is already handled in TopFieldCollector, we need to disable sort optimization in comparators."
- A consolidation, not a policy change. The 11.0.0 CHANGES entry #16857 added (
CHANGES.txt:39-47, labelled GITHUB#14399, the same issue number as 10.6.0'sdisableSkippingentry) says the pruning decisions are "consolidated into FieldValueHitQueue, and early termination through examining index sorts is handled by a new IndexSortedLeafFieldComparator class";MIGRATE.md:31-32listsdisableSkippingas removed. The PR's review is about document blocks; mixed segments and the shared flag never come up. - No test covers it.
TestTopFieldCollectorEarlyTermination.testMultiReaderWithDifferentIndexSorts(:283) andtestQueueFilledInEarlierSegment(:548) check hits only. - Precedent for the class of bug. #13498, "Avoid performance regression by constructing lazily the PointTree in NumericComparator", is listed under Bug Fixes in 9.11.1 and 10.0.0.
The devil's-advocate check129 words
The strongest case for "intended" (built by an intended-behaviour checker): the flags are comparator-wide on purpose (since LUCENE-9449, 2020), and upstream TestNumericComparator sets comparator1.hitsThresholdReached = true before creating a leaf comparator to emulate a later leaf; the wrapper is package-private and its @param paging javadoc only says what is "passed through" when paging; no public javadoc promises "no points work"; the cost is bounded.
Why it fails: the shared flag was harmless while an early-terminated segment had no points builder (10.6.0 dropped it per segment). #16857 replaced that switch with a mechanism, not forwarding one call, that works only if the delegate's state is per segment, and its own comment states the goal it then misses. Bounded cost and the missing javadoc promise lower the priority, not the verdict.
Recommended A per-leaf threshold flag in NumericLeafComparator (validated)
Give NumericLeafComparator its own threshold flag, set in its setHitsThresholdReached(), and gate the points update on it (3 lines). Since #16857 every normal leaf is told at construction; a wrapped leaf never is. Validated with gradle: the repro passes and 217 search test classes pass; one unit test that writes the shared field needs a small adaptation.
     private final CompetitiveDISIBuilder competitiveDISIBuilder;
+    // Whether this leaf was told that the hits threshold is reached. A leaf that terminates early
+    // by its index sort is not told (IndexSortedLeafFieldComparator), so it does no points work.
+    private boolean leafHitsThresholdReached;
@@ NumericLeafComparator.setHitsThresholdReached()
       hitsThresholdReached = true;
+      leafHitsThresholdReached = true;
@@ CompetitiveDISIBuilder.updateCompetitiveIterator()
-      if (hitsThresholdReached == false) {
+      if (leafComparator.leafHitsThresholdReached == false) {
         return;
       }
All options and trade-offs3 options · 708 words
Two designs; the first was built and validated, the second is the released 10.6.0 behaviour. The choice is the maintainers'.
In comparators/NumericComparator.java: NumericLeafComparator records whether it was told itself, and CompetitiveDISIBuilder.updateCompetitiveIterator() tests that instead of the comparator-wide field. Since #16857, TopFieldLeafCollector tells every leaf at construction once the threshold was crossed earlier (TopFieldCollector.java:56-59) and countHit() tells it when it crosses it (:70-75), and MultiLeafFieldComparator forwards the call to the first comparator of a multi-field sort (MultiLeafFieldComparator.java:95-99), so in Lucene's own TopFieldCollector paths every normal leaf keeps its pruning; only a wrapped, non-paging leaf, which the wrapper never tells, stops doing points work. Code that writes the protected field directly is the first trade-off. The same gate also guards the doc-values-skipper builder.
     private final CompetitiveDISIBuilder competitiveDISIBuilder;
+    // Whether this leaf was told that the hits threshold is reached. A leaf that terminates early
+    // by its index sort is not told (IndexSortedLeafFieldComparator), so it does no points work.
+    private boolean leafHitsThresholdReached;
@@ NumericLeafComparator.setHitsThresholdReached()
       hitsThresholdReached = true;
+      leafHitsThresholdReached = true;
@@ CompetitiveDISIBuilder.updateCompetitiveIterator()
-      if (hitsThresholdReached == false) {
+      if (leafComparator.leafHitsThresholdReached == false) {
         return;
       }
Trade-offs
- It changes what the protected comparator-wide field means for the gate. Upstream
TestNumericComparator.testEmptyCompetitiveIteratorOptimizationsetscomparator1.hitsThresholdReached = truedirectly (TestNumericComparator.java:215and three siblings) and fails with the fix,expected:<2147483647> but was:<0>; the adaptation makes those four helpers callleafComparator.setHitsThresholdReached()instead, "as TopFieldCollector does for a leaf that starts after the threshold was reached". Subclasses outside Lucene that set the field directly would need the same change. - It relies on #16857's constructor-time call to tell later normal leaves. LFV-1057's fixes keep that (a cost guard) or move it into
setScorer(); both combine with this fix (both repros pass). - Scope: it covers
NumericComparatoronly.TermOrdValComparator(STRING sort) has its own comparator-widehitsThresholdReached(comparators/TermOrdValComparator.java:110, set at:318, read at:418), so the STRING analogue (not part of this finding) would remain; it could get the same per-leaf flag. - Open PR #16163 (
search_afterwith the doc-values skipper) rewrites the same gate line intoif (hitsThresholdReached == false && leafTopSet == false) {, so the two conflict as text; they appear to compose asif (leafComparator.leafHitsThresholdReached == false && leafTopSet == false) {(not built or tested: rebase onto its current head and run both changes' tests).
What the checks validated
- Gradle in a scratch worktree at
e1faeba08bde, JDK 25,-Ptests.seed=DEADBEEF(2026-11-02): the repro fails without the fix (asserts on and off) and passes with it (asserts on and off). With the fix and the test adaptation,org.apache.lucene.search.*(all subpackages) plusorg.apache.lucene.index.TestIndexSorting: 217 classes, 2,413 tests, 0 failures, 49 skipped, among themTestSortOptimization(31),TestTopFieldCollectorEarlyTermination(12),TestTopFieldCollector(13),TestSort(30) andTestNumericComparator(3). The fix alone with the unmodifiedTestNumericComparatorfails 1 of 3 (the trade-off above). - Hunt (standalone runner): the trigger shapes drop to 0 while the plain control without an index sort keeps its 10,752; the 1,000,000-doc case with a bottom just under cost/8 drops to 0 while its control keeps 125,440; an exhaustive multi-leaf harness (42,520,140 + 113,540,400 searches) finds 0 wrong results, wasted points work in 90,192 / 337,440 wrapped leaf-searches on main vs 0 with the fix, and identical pruning in every non-wrapped leaf of its bounded configurations; in a TLA+ model of the leaf protocol (TLC) the invariant NoETWork is violated on main and holds with the fix.
Give LeafFieldComparator back a hook like 10.6.0's disableSkipping() (default no-op; NumericLeafComparator drops its builder; MultiLeafFieldComparator forwards it) and have IndexSortedLeafFieldComparator call it on its delegate when not paging.
Trade-offs
Keeps the protected field's meaning and needs no test change; it is the 10.6.0 behaviour. But it re-adds a method #16857 removed on purpose (CHANGES 11.0.0, MIGRATE.md:31-32), and since the wrapper and the comparators live in different packages the hook has to be public (perhaps @lucene.internal).
The wrapper could hide the calls that drive the builder.
Trade-offs
compareBottom needs the bottom set by setBottom, and other comparators of a multi-field sort need the scorer, so this breaks sorting.
Downstream engines on Lucene 11 or 12 snapshots (branch_11x, main) that combine differently sorted indexes or segments in one sorted search can pay this extra CPU, under the conditions above, until it is fixed; the hits are unaffected.
While reviewing newly merged upstream code, reading the #16857 diff raised the question whether the new wrapper really stops the comparator's points work after a mixed segment. A probe counting point reads showed 10,752 vs 0 point doc IDs with the same top 10. It was reduced to one test, modelled in TLA+ and checked with an exhaustive multi-leaf harness.
The method in full243 words
Method: non-formal (the first signal came from code reading and an executed probe; the formal model came later).
- Lead. A review of newly merged upstream code read the #16857 diff.
- Probe. A differential count through the public
FilterLeafReaderAPI with a countingPointValues/PointTreewrapper, on upstream main, on main before #16857 and on 10.6.0, identical top 10 in every run: in theMultiReaderand block/non-block shapes 10,752 point doc IDs on main vs 0 before #16857 and on 10.6.0; in the no-op leading-field shape 10,752 on main vs 0 with the fix (before #16857 that segment is not terminated early, so its 10,752 there is real pruning; not run on 10.6.0). - Reduction. One JUnit test, run on main and the commit bracket with assertions on and off, and on three releases (10.6.0 with assertions on and off, 10.5.2 and 9.12.3 with assertions off); a later review replaced it with the one-method test above.
- Model. A TLA+ model of the per-leaf collector/comparator protocol with leaf kinds and the wrapper (TLC): the invariant NoETWork (no points work in a leaf the index sort terminates, when not paging) is violated by upstream main and holds for the code before #16857 and for every per-leaf-flag variant; the properties that no first update is lost and that paging keeps its updates hold everywhere.
- Exhaustive harness. A bounded-exhaustive multi-leaf harness with a per-leaf points-work counter: 0 wrong results; points work in wrapped, non-paging leaves on main only.
No prior report found (2026-11-02: two scripted prior-report searches over GitHub issues and PRs including the JIRA archive, the mailing lists and downstream trackers; the changed files of all 410 open PRs; every #16857 comment; rechecked the same day).
Searches5 searches
Related, not reports of this bug: #16857 (introduces it; its review is about document blocks); #16947 / #16887 (document blocks; adds one trigger shape); #16434 / #14399 (the 10.6.0 per-segment switch this regresses from); #10639 (LUCENE-9599, design precedent); #16163 (open; loosens the same gate line for search_after, would not fix this); #16847 (open, long global doc IDs; one unrelated line of NumericComparator). Tracking issue #16937 does not mention it. Limits: keyword search; GitHub search does not index inline review comments (read directly for #16857, #16947, #16954 and #16434); private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| Scripted prior-report search (GitHub issues/PRs incl. the migrated JIRA archive, commits, Elasticsearch, OpenSearch and Solr, dev@, java-user@, issues@, commits@) | 2026-11-02 | two runs, 90 queries: IndexSortedLeafFieldComparator, NumericLeafComparator, PointsCompetitiveDISIBuilder, setHitsThresholdReached, updateCompetitiveIterator, disableSkipping, primarySortFieldIndex, "sort pruning", "index sort" + early termination / competitive iterator / MultiReader / regression | 181 and 433 distinct hits, none a report |
| GitHub apache/lucene (manual) | 2026-11-02 | 27 queries, including every issue/PR created since 2026-10-29 and every sort item since 2026-10-16; phrase variants of the wrapper's design comment | no report |
| Introducing and related threads | 2026-11-02 | body, reviews and inline comments of #16857, #16947, #16953, #16954, #16434 and #14399 | #16857's review is about document blocks; nothing about mixed segments or the shared flag |
| Open apache/lucene PRs | 2026-11-02 | the changed files of all 410 open PRs | none touches IndexSortedLeafFieldComparator; the scan listed only #16163 for NumericComparator (it rewrites the gate line, see the fixes); the recheck found that #16847 (long global doc IDs, 441 files), missed by the scan for this file, changes one unrelated NumericComparator line (maxDoc in the CompetitiveDISIBuilder constructor) |
| Recheck | 2026-11-02 | issues/PRs updated or created since; commits on the fix-site files on main and branch_11x; #16937 | nothing new; no commit on the files after #16857 and #16947 |
Introduced by #16857 (70a428b5ba9, merged 2026-10-29) and its branch_11x backport 203699279f5; its parent e0fa3535ea5 passes. No release has it: 10.6.0 passes. 10.5.2 and 9.12.3 read the same points, but there the segment is not terminated early and uses the iterator.
Versions tested6 rows
Introduced by 70a428b5ba9, apache/lucene#16857 "Consolidate Sort pruning logic" (romseygeek, Alan Woodward), opened 2026-10-16, merged to main on 2026-10-29; backported to branch_11x as 203699279f5 the same day (same patch-id). CHANGES lists it under Lucene 11.0.0. As of 2026-11-02 no later commit on main or branch_11x touches the four files involved, except #16947 on FieldValueHitQueue (document blocks, which adds one trigger shape).
Older ingredients, harmless alone: the comparator-wide hitsThresholdReached (99220677fe4, LUCENE-9449, 2020); disableSkipping (LUCENE-9599, 2020); per-segment early termination with per-segment disableSkipping (7a6a3766f72 main / 466f27afa9a 10.x, #16434 / GITHUB#14399, shipped in 10.6.0), which made the mixed-segment case reachable without waste.
Older releases: before 10.6 the first segment's index sort decided early termination for the whole search, so in the repro data the sorted segment is not terminated early (it counts 109 of 4,096 docs) and the 512 point doc IDs build the iterator it really uses. 10.6.0 is the regression baseline.
| Version or commit | Verdict | Result |
|---|---|---|
main e1faeba08bde (12.0.0-SNAPSHOT) | affected | fails: gradle in a scratch worktree and the standalone runner, assertions on and off, expected:<0> but was:<2> |
branch_11x da3ea39fa59 (head) | affected | the four involved files are identical to main (read) |
70a428b5ba9 (#16857) vs its parent e0fa3535ea5 | bisect | #16857 fails (512 point doc IDs), the parent passes (0), -ea and -da, earlier counting version of the test |
main 645d4fe14a20 (2026-10-28) | not affected | passes (-ea, -da; predates #16857) |
10.6.0 (4ae946e5a9b) | not affected | passes (-ea, -da); calls disableSkipping() on such segments |
| 10.5.2, 9.12.3 | not this bug | the earlier test counts 512, but the sorted segment is not terminated early there (109 of 4,096 docs) and uses the iterator: real pruning |
An independent reproducer, reviews from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication confirmed it on main code; a third cross-model review's formal "not real" ran on a checkout older than #16857, where the test passes as expected.
Checks and verdicts412 words
This doc adds gradle runs of the one-method test in a scratch worktree at e1faeba08bde, with and without the fix, and runs of it on 10.6.0 and 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Its test fails on main (-ea, -da, four seeds) and passes on 645d4fe and 10.6.0; TLA+ (TLC): NoETWork violated on main, holds with the per-leaf flag; exhaustive multi-leaf harness: 0 wrong results, wasted work only in wrapped leaves. |
| Independent reproducer | real | Own test with different data fails on main (512) and passes on 10.6.0; a stack probe puts the read in IndexSortedLeafFieldComparator.setScorer -> PointsCompetitiveDISIBuilder -> PointValues.intersect; a below-threshold control reads 0; a 1,000,000-doc probe reads 120,832. |
| cross-model review, refute lens | formally not real, vacuous | OpenAI GPT-5.6. It used a checkout older than #16857, where the test passes as on 645d4fe; it called the root cause plausible on the newer code. |
| cross-model code review | real, high | OpenAI GPT-5.6, from the e1faeba and 645d4fe sources and the executed results, without running code: mechanism confirmed line by line, distinct from LFV-1057, Low; its wording objections were adopted. |
| Cross-model review, intended lens | real, high | OpenAI GPT-5.6, executed on e1faeba: its own test reads 1,751 point doc IDs in the later wrapped leaf with correct results; it flagged the TestNumericComparator trade-off of the fix. |
| Intended-behaviour devil's advocate | real, Low | Built the strongest case for intended and rejected it; measured the indicative wall-clock cost. |
| adjudication | confirmed, high, Low | Re-ran with seed 1234ABCD: main fails (-ea, -da), 10.6.0 passes. |
| credibility audit | confirmed (Low) | The one-method test replaced a 212-line repro; the audit re-ran the earlier repro on main with seed BADC0DE5 (fails, -ea and -da). |
| this doc | real as described | Gradle at e1faeba08bde: fails without the fix (asserts on and off), passes with it; 217 test classes pass with the fix; the test passes on 10.6.0 and 645d4fe14a20. |
| fact checks of this doc | real as described; wording corrected | An independent fact check re-ran the one-method test (main fails with seeds DEADBEEF, C0FFEE and 7A11CE; 645d4fe14a20 and 10.6.0 pass) and the gradle command with and without the fix; its own 1,000,000-doc probe read 136,192 point doc IDs, above cost/8, which corrected the cost bound to about cost/7. A second fact check by another model family (OpenAI GPT-5.6) found wording issues only. Both sets of corrections are in this version. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 496 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,658 words
- Registry title
- Since #16857 (upstream main and branch_11x, unreleased), a segment that its index sort terminates early can still build an unused points-based competitive iterator when an earlier segment of the same field-sorted search crossed the hits threshold without early termination: NumericComparator keeps hitsThresholdReached on the comparator that all leaves share, so IndexSortedLeafFieldComparator's not forwarding setHitsThresholdReached() no longer stops the delegate's BKD work (512 point doc IDs read in the repro, up to about cost/7 per segment, where 10.6.0 reads 0; performance regression, results correct)
- Area
- search / field sorting: index-sort early termination (IndexSortedLeafFieldComparator) + NumericComparator points-based sort pruning (competitive iterator)
- Priority
- Low, rank 1032: Performance only, with correct results, in unreleased main and branch_11x. With an index sort, a field-sorted search wastes up to about cost/7 point reads in each segment the sort terminates early, but only after an earlier segment without early termination crossed the hits threshold. That mixed-leaf layout is uncommon, and the bug can be fixed before 11.0.0.
- Impact class
- minor
- Impact note
- Performance regression only, on upstream main and branch_11x since #16857 (no release has it; fixable before 11.0.0): a field-sorted IndexSearcher#search(query, n, sort) with the default codec and searcher, sorted by the leading index-sort field (a numeric field indexed with points), reads points in each segment that its index sort terminates early once an earlier segment of the same slice, not terminated early, has crossed the default 1,000-hit threshold (a MultiReader over indexes with different or no index sorts, a parent-field index mixing block and non-block segments, or an (k, f) index sort with a constant k in some segments); the iterator it builds is never used, the waste is bounded by about cost/7 point doc IDs per such segment (each intersection must cut the current cost 8x) and depends on where the earlier segment's bottom falls (512 in the repro; 512, 125,440 or 136,192 for different earlier top 10s in a 1,000,000-doc segment that collects 11 documents), indicative timings on a shared host were about 1.3x on a typical shape and 2.7-3x with a bottom just under cost/8, and the top hits are identical in every executed shape.
- Summary
- You search a MultiReader over two indexes for the top 10 by a long field f: the first index has no index sort and 2,000 hits, so the default 1,000-hit threshold is crossed there, and the second (4,096 documents) is sorted by f, so the search stops in it after a few documents. You expect that sorted segment to read no points: the new IndexSortedLeafFieldComparator says the comparator's skipping work, 'e.g. building iterators from points, is redundant work' there, and 10.6.0 reads 0. Instead, since #16857 the comparator still sees the threshold flag that the first segment set on the comparator shared by all segments, so it walks the sorted segment's BKD tree and builds a points iterator that nobody uses (512 point doc IDs here, up to about cost/7 per segment); the top 10 is still right, only the work is wasted.
- Introduced
- 70a428b5ba90cdbcf3c8380e21b006a68b4dcb85 (apache/lucene#16857 'Consolidate Sort pruning logic', author romseygeek (Alan Woodward), merged to main 2026-10-29; branch_11x backport 203699279f5 the same day, same patch-id) [exec: commit bracket with the earlier counting version of the repro (not the one-method minimal test), the stock 645d4fe14a2 jars plus each commit's own changed core/codecs/test-framework sources compiled by repro.sh --shadow-src: 70a428b5ba9 fails with -ea and -da ('expected:<0> but was:<512>'; the sorted segment collects 11 of 4,096 documents and reads 512 point doc IDs), its parent e0fa3535ea5 passes with -ea and -da (0)]. #16857 removed FieldComparator#disableSkipping and LeafFieldComparator#disableSkipping, which 10.6.0's TopFieldCollector called on each segment that its index sort terminates early ('Early termination handles this segment; skipping work in the comparator is redundant.'), and replaced them with IndexSortedLeafFieldComparator, which suppresses the delegate's skipping only by hiding competitiveIterator() and not forwarding setHitsThresholdReached() when not paging [read]. Older ingredients, harmless before: the comparator-wide 'protected boolean hitsThresholdReached' (99220677fe4, LUCENE-9449, 2020) [read]; per-segment index-sort early termination (#16434 / GITHUB#14399, 10.6.0) made the mixed-leaf precondition reachable but dropped the points builder per segment [read; 10.6.0 executed]. (2026-10-29 (author date = commit date of 70a428b5ba9, 2026-10-29; the branch_11x backport 203699279f5 has the same author date, committed 2026-10-29))
- First affected version
- unreleased (11.0.0 would be the first release: #16857's CHANGES entry is under Lucene 11.0.0); 10.6.0, released 2026-10-29 from 4ae946e5a9b, and every earlier release are not affected; the last unaffected main commit is e0fa3535ea5
- Affected versions
- [exec] upstream main e1faeba08bd (native 12.0.0-SNAPSHOT build, stock jars): the one-method minimal test fails ('expected:<0> but was:<2>') with seed DEADBEEF (-ea and -da) and seeds C0FFEE and 7A11CE (-ea); the earlier counting version of the test fails with -ea and -da ('expected:<0> but was:<512>') with seeds DEADBEEF, 1, C0FFEE and 12345678 (finder), 7A11CE (the intended-behaviour check), 1234ABCD (the adjudication) and C0FFEE (registration check, 2026-11-02); main 70a428b5ba9 = #16857 (shadow over the 645d4fe jars, -ea and -da). [read] branch_11x since 203699279f5: at head da3ea39fa59 IndexSortedLeafFieldComparator, NumericComparator, TopFieldCollector and FieldValueHitQueue are identical to main; upstream main 254ce48660d (2026-11-02) and branch_11x have no commit on these files after #16857 and #16947 (check 2026-11-02). Not affected [exec]: main parent e0fa3535ea5 (-ea, -da), main 645d4fe14a2 (-ea, -da), 10.6.0 = 4ae946e5a9b (-ea, -da; the same test with the 10.x 'throws IOException' signatures). [read] branch_10_6 (the 10.6.x bugfix line) has no #16857 and still calls comparator.disableSkipping(); branch_10x was retired by #16911 before #16857. 10.5.2 and 9.12.3 also fail the test's assertion (512), but that is NOT this bug: before 10.6 the first segment decides index-sort early termination for the whole search, so the sorted segment is not terminated early (109 of 4,096 documents counted) and the 512 doc IDs build the competitive iterator it really uses; they are not affected.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by TLA+/TLC, exhaustive check
- Upstream and prior reports
- none found (searched 2026-11-02: two scripted prior-report searches, 90 queries over GitHub issues and PRs including the migrated JIRA archive, commits, Elasticsearch/OpenSearch/Solr, dev@/java-user@/issues@/commits@ and JIRA; 27 manual GitHub searches including every apache/lucene issue/PR created since 2026-10-29; the full threads of #16857, #16947, #16953/#16954, #16434 and #14399; the changed files of all 410 open PRs; the branch heads; web search. A recheck the same day: no new issue or PR; no commit on the fix-site files after #16857 and #16947 on main or branch_11x (author dates 2026-10-29 and 2026-10-30); of the open PRs updated in the last 48 h only #16847 (long global doc ids) touches NumericComparator, TopFieldCollector and FieldValueHitQueue, for doc-id widths only, not the threshold gate; tracking issue #16937 does not mention it). Related, not this bug: #16857 (introducing PR; its review is only about document blocks), #16947/#16887 (document blocks, wrong results; adds a single-index trigger shape), #16434/#14399 (10.6.0 per-segment disableSkipping, the behaviour this regresses from), #10639 / LUCENE-9599 (design precedent), open #16163 (loosens the same updateCompetitiveIterator gate for search_after; would not fix this).
- Lucene commit tested
- this one-method test on upstream main
e1faeba08bde(gradle in a scratch worktree at that commit with-Ptests.asserts=trueandfalse, then with the per-leaf flag fix and theTestNumericComparatoradaptation together with 217 test classes oforg.apache.lucene.searchandTestIndexSorting; the standalone JUnit runner,-eaand-da), main645d4fe14a20(before #16857) and the 10.6.0 jars (pass,-eaand-da). The commit bracket (70a428b5ba9fails, its parente0fa3535ea5passes) and the 10.5.2 and 9.12.3 runs used the earlier counting version of the test (512 point doc IDs).
- Finding record
lucene/core/src/java/org/apache/lucene/search/IndexSortedLeafFieldComparator.java:31-33 (at e1faeba08bde) (design comment: when not paging 'collection terminates anyway and the delegate's skipping, e.g. building iterators from points, is redundant work: it measurably slows down index-sorted searches'), :53-56 setBottom and :81-84 setScorer always forwarded, :86-89 competitiveIterator() null when not paging, :91-97 setHitsThresholdReached() forwarded only when paginglucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:59-60 (at e1faeba08bde) ('protected boolean hitsThresholdReached; protected boolean queueFull;' on the comparator shared by every leaf), :132-133 setBottom sets queueFull, :147 setScorer, :155 setHitsThresholdReached, :222-226 updateCompetitiveIterator gates 'hitsThresholdReached == false' and 'leafTopSet == false && queueFull == false', :353 'update an iterator when we have a new segment', :426 'iteratorCost >>> 3', :441 pointValues.intersectlucene/core/src/java/org/apache/lucene/search/FieldValueHitQueue.java:177-191 (at e1faeba08bde) (getLeafComparator wraps the leaf comparator in IndexSortedLeafFieldComparator when canEarlyTerminate holds for the segment), :202-220 canEarlyTerminatelucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:55 (at e1faeba08bde) (leaf collector takes queue.getLeafComparator(context, paging))lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:69-74 (at 645d4fe14a20) ('Early termination handles this segment; skipping work in the comparator is redundant.' + comparator.disableSkipping()) and comparators/NumericComparator.java:109-114 (disableSkipping drops the competitive DISI builder): the pre-#16857 = 10.6.0 behaviourhttps://github.com/apache/lucene/pull/16857 (introducing PR: consolidation; review only about document blocks)https://github.com/apache/lucene/pull/16434 and https://github.com/apache/lucene/issues/14399 (10.6.0 per-segment early termination with disableSkipping)https://github.com/apache/lucene/issues/10639 (LUCENE-9599: disable comparator sort optimization when index-sort early termination applies)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/IndexSortedLeafFieldComparator.java:31-33, (at e1faeba08bde) :53-56, :59-69, :81-84, :86-89, :91-97lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:59-60, (at e1faeba08bde) :98-106, :131-137, :153-159, :222-228, :345-355, :426-445lucene/core/src/java/org/apache/lucene/search/FieldValueHitQueue.java:146-151, (at e1faeba08bde) :177-194, :202-214lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:55-59, (at e1faeba08bde) :64-77; IndexSearcher.java:100a Lucene clone releases/lucene/10.6.0 (4ae946e5a9b): lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:69-74, comparators/NumericComparator.java:110-114lucene/CHANGES.txt:39-47, (at e1faeba08bde) lucene/MIGRATE.md:31-34
- Who is affected
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:106, (at e1faeba08bde) :226-231, :312-325; FieldValueHitQueue.java:203-213lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:98-106, (at e1faeba08bde) :222-246, :426-445; TopFieldCollectorManager.java:112-114
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/IndexSortedLeafFieldComparator.java:31-33, (at e1faeba08bde) :41-46a Lucene clone releases/lucene/10.6.0: lucene/core/src/java/org/apache/lucene/search/LeafFieldComparator.java:115-122, lucene/CHANGES.txt:16-17 (GITHUB#14399)https://github.com/apache/lucene/issues/10639 (LUCENE-9599)lucene/CHANGES.txt:39-47, (at e1faeba08bde) :2412-2423 and :2773-2778 (#13498 under Bug Fixes), lucene/MIGRATE.md:31-34lucene/core/src/test/org/apache/lucene/search/TestTopFieldCollectorEarlyTermination.java:283, (at e1faeba08bde) :548; lucene/core/src/test/org/apache/lucene/search/comparators/TestNumericComparator.java:207-220
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:56-59, (at e1faeba08bde) :70-75; comparators/NumericComparator.java:90, :155, :223lucene/core/src/test/org/apache/lucene/search/comparators/TestNumericComparator.java:207-265 (at e1faeba08bde)a Lucene clone releases/lucene/10.6.0: lucene/core/src/java/org/apache/lucene/search/LeafFieldComparator.java:115-122, comparators/NumericComparator.java:110-114lucene/core/src/java/org/apache/lucene/search/MultiLeafFieldComparator.java:95-99, (at e1faeba08bde) comparators/TermOrdValComparator.java:110, :318, :418
- TestIndexSortedSegmentPointsWork.java (lucene/core, package org.apache.lucene.search, 1 test):
repro/LFV-1088/TestIndexSortedSegmentPointsWork.java(95 lines)
A small diagram made from the executed repro numbers.
assets/LFV-1088/bug.png(496 KB)