For a string field, the query turns both bounds into exact int ordinals, then compares each document's ordinal with them as a float. A float is exact only up to 2^24, so above that a value next to a bound rounds onto the bound's float and is matched.
- A string doc-values field (
SortedDocValuesField, orSortedSetDocValuesField) keeps, per segment, a sorted dictionary of its distinct values. Each value has a number, its ordinal: 0 for the smallest, 1 for the next, and so on. FunctionRangeQuery(new BytesRefFieldSource("f"), lower, upper, includeLower, includeUpper)(modulelucene/queries) matches the documents whose value lies in the range. For a string field it looks both bounds up in the dictionary once, and then compares each document's ordinal with the two bound ordinals.- A Java
floathas 24 bits of precision. It holds every whole number up to 2^24 = 16,777,216 exactly; above that only every second one (16,777,218, 16,777,220, ...), then every fourth, up to every 128th near 2^31. Other numbers round to the nearest.
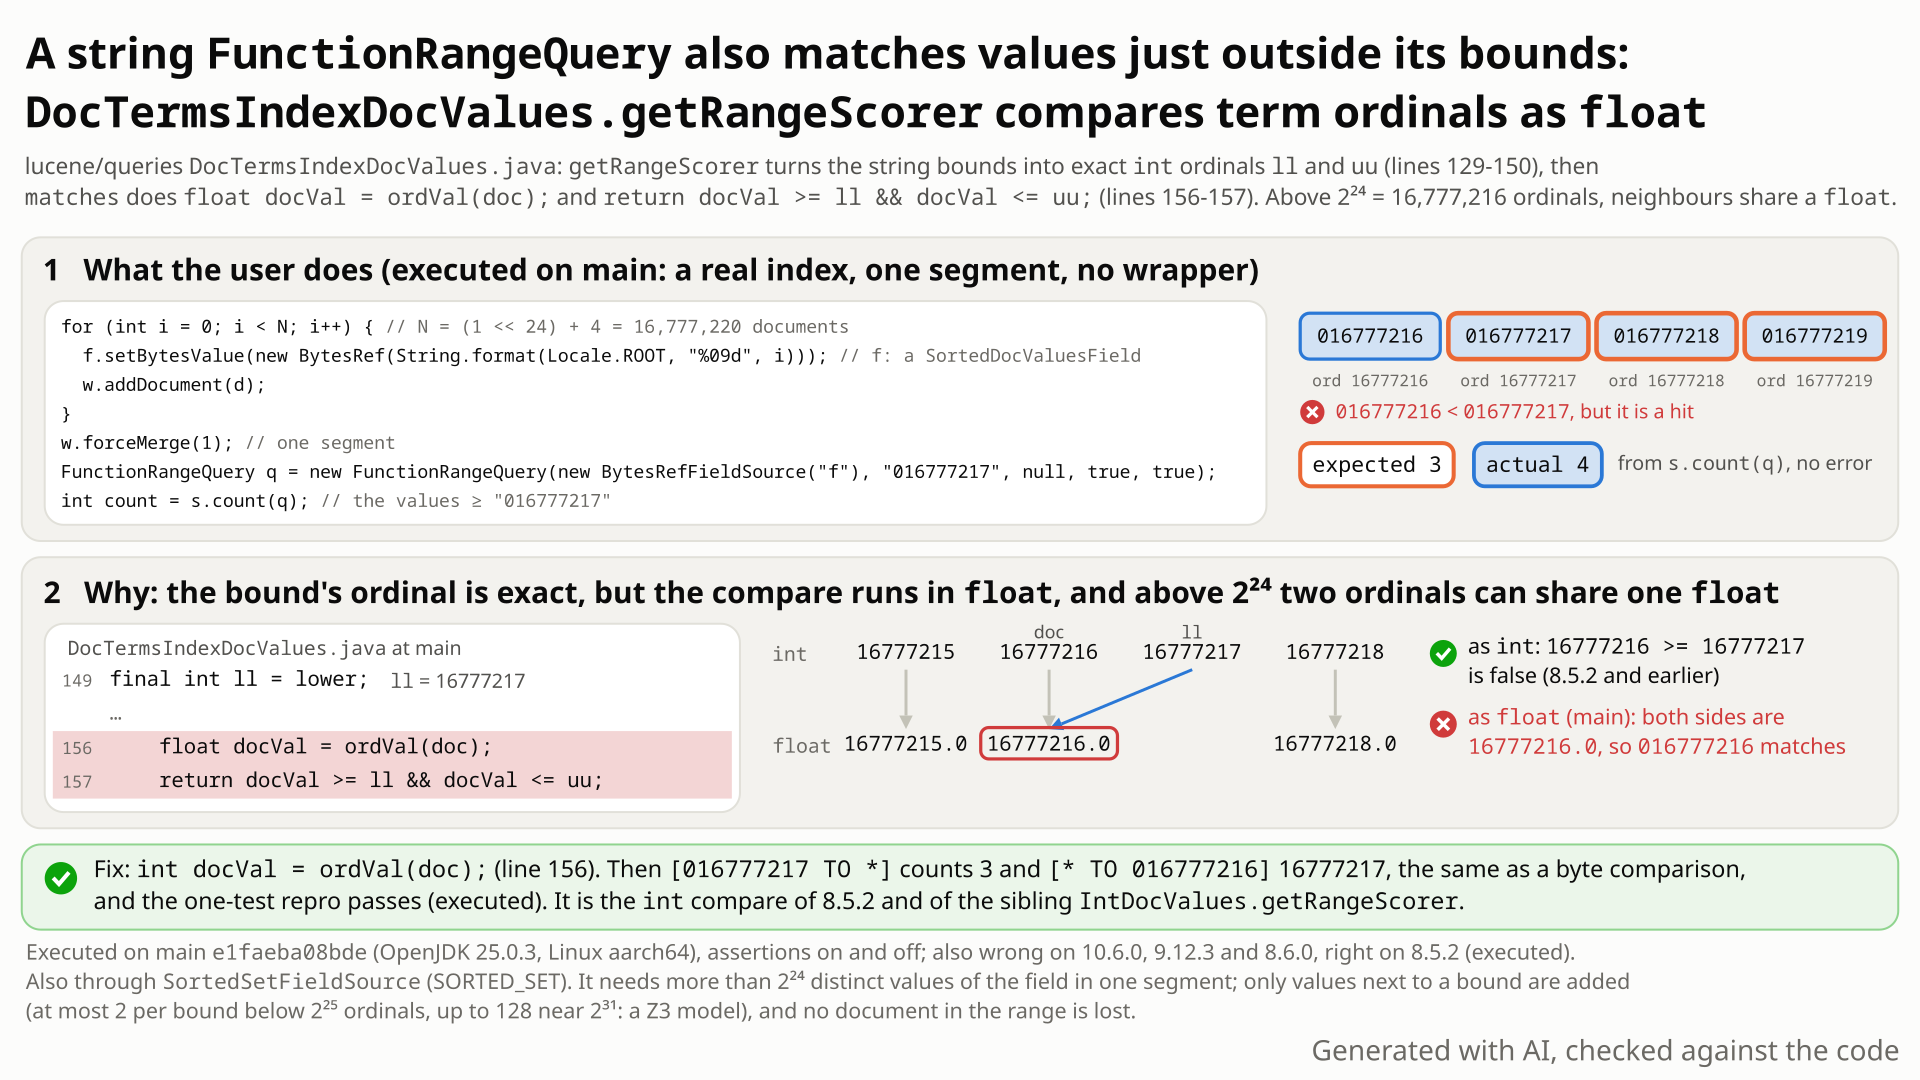
- Index 16,777,220 documents, each with its own value
000000000...016777219in aSortedDocValuesFieldf, and merge to one segment. Each value's ordinal, its position in the segment's sorted dictionary, equals its number. - Count
FunctionRangeQuery(new BytesRefFieldSource("f"), "016777217", "016777217", true, true). The range holds exactly one value, so you expect 1 hit. - You get 2 hits,
016777216and016777217, with no error;[016777217 TO *]gives 4 hits instead of 3. Lucene 8.5.2, running the same program, returns 1 and 3. - Why: the bounds become exact ordinals (lower = upper = 16,777,217), but each document's ordinal is compared with them as a
float. Above 2^24 a float holds only every second whole number, so 16,777,216 and 16,777,217 both become 16,777,216.0 and the neighbour passes the bound. - Only values right next to a bound slip in (at most 2 per bound below 2^25 ordinals, up to 128 near 2^31), and no in-range hit is lost.
SortedSetFieldSourcebehaves the same.
Code that filters with FunctionRangeQuery over BytesRefFieldSource (SORTED) or SortedSetFieldSource (SORTED_SET) on segments where the field has more than 16,777,216 distinct values, such as a unique id in a large merged segment. Default codec and config, every release since 8.6.0. Only values at the range edges are added, silently; rare in practice.
Mechanism, terms and numbers509 words
FunctionRangeQuery over BytesRefFieldSource on a SORTED field, or over SortedSetFieldSource on a SORTED_SET field, does a string range through DocTermsIndexDocValues.getRangeScorer. That method looks the two string bounds up in the segment's sorted dictionary and gets exact int ordinals, then compares each document's ordinal with them as a float (float docVal = ordVal(doc); return docVal >= ll && docVal <= uu;). A float is exact for whole numbers only up to 2^24 = 16,777,216, so in a segment where the field has more than 2^24 distinct values, a value whose ordinal sits next to a bound rounds onto the bound's float and is matched. On a real single segment of 16,777,220 unique values, the range [016777217 TO 016777217] returns 2 hits, 016777216 and 016777217, with no error. Only extra hits occur, at most 2 per bound below 2^25 ordinals and up to 128 near 2^31; no in-range hit is lost. The compare was int up to 8.5.2; LUCENE-9258 changed it to float while adding multi-valued support, so every release from 8.6.0 to 10.6.0 and main are affected. Changing float back to int fixes it.
- Entry points.
BytesRefFieldSource("for string based fields") returns aDocTermsIndexDocValuesfor any non-BINARY field (valuesource/BytesRefFieldSource.java:118-119).SortedSetFieldSource("multi-valued string based fields") returns one over aSortedSetSelectorview (valuesource/SortedSetFieldSource.java:59-61).FunctionRangeQuery's scorer isfunctionValues.getRangeScorer(...)(FunctionRangeQuery.java:172). - Exact bounds.
DocTermsIndexDocValues.getRangeScorerconverts each bound withtermsIndex.lookupTerm(...). A lower bound missing from the dictionary becomes its insertion point, a missing upper bound the ordinal just below it, an exclusive bound moves by one, an absent bound isInteger.MIN_VALUE/Integer.MAX_VALUE; the results arefinal int ll,uu(docvalues/DocTermsIndexDocValues.java:129-150). - The narrowing.
matches(int doc):if (!exists(doc)) return false; float docVal = ordVal(doc); return docVal >= ll && docVal <= uu;(:155-157).ordValis the exactintordinal (:79-81); assigning it tofloatrounds it to the nearest float (ties to even), and binary numeric promotion turnsllanduuinto floats for the comparisons too. - The arithmetic. In the one-document repro the document has ordinal 16,777,216 and the lower bound
016777217, absent from the dictionary, has insertion point 16,777,217. Both become 16,777,216.0f, sodocVal >= llis true and the document matches although its value sorts before the bound.
- Int-to-float rounding is monotone, so an in-range ordinal is never rejected: only extra hits.
- No wrong match while every ordinal and bound is at most 2^24, so it needs more than 2^24 distinct values of the field in the segment.
- For a bound in [2^24, 2^25) at most 2 values outside it are admitted; the overall maximum is 128 values per bound, near 2^31. The model covers the lower bound; the upper bound is the mirror case, shown next.
- An upper bound admits extras too: on 16,777,224 hex ids,
{1000000 TO 1000003](3 values) returns 6 hits,1000000below the range and1000004,1000005above it.
Exposure and likelihood222 words
- Who is hit. Callers of
FunctionRangeQuery(the only caller ofgetRangeScorerin Lucene's main sources; a test also calls it directly) overBytesRefFieldSourceon a SORTED field orSortedSetFieldSourceon a SORTED_SET field (the only in-tree users ofDocTermsIndexDocValues). A string source has nofloatVal, so these queries are used where scores are not needed: a filter clause,ConstantScoreQuery,IndexSearcher.count. - Default vs opt-in. Default codec and configuration; the API itself is opt-in (
lucene/queries;FunctionRangeQueryis@lucene.experimental). - Scale. Only segments in which the field has more than 2^24 distinct values. For SORTED that means more than 16.8 million documents in one segment; for SORTED_SET the distinct values can outnumber the documents. Such segments are legal:
IndexWriter.MAX_DOCSisInteger.MAX_VALUE - 128, andSortedSetSelectorrejects only fields withInteger.MAX_VALUEor more unique values. - Size of the error. Only extra hits, only values next to a range edge: at most 2 per bound below 2^25 ordinals, up to 128 near 2^31. No in-range hit is lost.
- Silent. No exception and no assertion: the counts are wrong with assertions on and off.
- Likelihood: rare. It needs this experimental API on a string field and a very large segment, and it only moves the range edges; no public report of it was found, although it has shipped since 8.6.0 (2020).
One JUnit test for lucene/queries, public API only. One document holds 016777216; a FilterLeafReader serves it as ordinal 2^24 of a 16,777,217-term sorted dictionary, so the test runs in about a second instead of indexing 16.8 million documents. It counts [016777217 TO *]. Deterministic, single thread; fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queries.function;

import java.io.IOException;
import java.util.Locale;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.FilterLeafReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.SortedDocValues;
import org.apache.lucene.queries.function.valuesource.BytesRefFieldSource;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestFunctionRangeQueryLargeOrdinals extends LuceneTestCase {

  private static final int BASE = 1 << 24;

  private static BytesRef term(int ord) {
    return new BytesRef(String.format(Locale.ROOT, "%09d", ord));
  }

  public void testOrdinalAbove2Pow24() throws IOException {
    try (Directory dir = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new SortedDocValuesField("f", term(BASE)));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        FilterLeafReader leaf =
            new FilterLeafReader(getOnlyLeafReader(reader)) {
              @Override
              public SortedDocValues getSortedDocValues(String field) throws IOException {
                SortedDocValues in = super.getSortedDocValues(field);
                return new SortedDocValues() {
                  @Override
                  public int ordValue() throws IOException {
                    return BASE + in.ordValue();
                  }

                  @Override
                  public BytesRef lookupOrd(int ord) {
                    return term(ord);
                  }

                  @Override
                  public int getValueCount() {
                    return BASE + 1;
                  }

                  @Override
                  public boolean advanceExact(int target) throws IOException {
                    return in.advanceExact(target);
                  }

                  @Override
                  public int docID() {
                    return in.docID();
                  }

                  @Override
                  public int nextDoc() throws IOException {
                    return in.nextDoc();
                  }

                  @Override
                  public int advance(int target) throws IOException {
                    return in.advance(target);
                  }

                  @Override
                  public long cost() {
                    return in.cost();
                  }
                };
              }

              @Override
              public CacheHelper getCoreCacheHelper() {
                return null;
              }

              @Override
              public CacheHelper getReaderCacheHelper() {
                return null;
              }
            };
        FunctionRangeQuery q =
            new FunctionRangeQuery(new BytesRefFieldSource("f"), "016777217", null, true, true);
        // doc "016777216" (ord 2^24 of 2^24+1 terms) < "016777217": expected 0 hits, actual 1
        assertEquals(q.toString(), 0, new IndexSearcher(leaf).count(q));
      }
    }
  }
}
cp $REPRO/TestFunctionRangeQueryLargeOrdinals.java $LUCENE/lucene/queries/src/test/org/apache/lucene/queries/function/
cd $LUCENE && ./gradlew :lucene:queries:test --tests TestFunctionRangeQueryLargeOrdinals -Ptests.seed=5EED1108 -Ptests.asserts=true
# also with -Ptests.asserts=false; the result does not depend on the seed
- Expected
- 0 hits: the only value,
016777216, sorts before the lower bound016777217. - Observed
- 1 hit, no error:
AssertionError: frange(f):[016777217 TO *] expected:<0> but was:<1>, with assertions on and off.
More files, environment, full output293 words
The test is the hunt's minimal repro with one statement re-wrapped so that it passes :lucene:queries:check -x test (google-java-format); the code is otherwise identical. The wrapper keeps the dictionary consistent: lookupOrd(ord) is the 9-digit number ord, lookupTerm is the inherited binary search over it, and getValueCount() is 2^24 + 1. The query is counted, which needs no scores (a scored search over a string source throws UnsupportedOperationException from floatVal, as the documented float score implies; not part of this finding).
Executed: gradle on main e1faeba08bde with assertions on (seeds DEADBEEF, 5EED1108) and off (5EED1108): fails 1 of 1; with the fix it passes. The hunt's runs fail the same way (5 of 5 random seeds with assertions off).
About the stand-in dictionary: "Ordinals are dense" describes the numbering, which the wrapper keeps, and a wrapper-free program over a real single segment of 16,777,218 unique values (stock IndexWriter, forceMerge(1), about 24 s at a 2 GB heap) returns [0016777217 TO *] count 2 instead of 1 and [* TO 0016777216] count 16,777,218 instead of 16,777,217 on main and 10.6.0, and the right counts with the fix. That run is evidence, not part of the repro.
Use the same test as the regression test.
| lucene | main e1faeba08bde (12.0.0-SNAPSHOT) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (only this platform was run) |
cp $REPRO/TestFunctionRangeQueryLargeOrdinals.java $LUCENE/lucene/queries/src/test/org/apache/lucene/queries/function/
cd $LUCENE && ./gradlew :lucene:queries:test --tests TestFunctionRangeQueryLargeOrdinals -Ptests.seed=5EED1108 -Ptests.asserts=true
# also with -Ptests.asserts=false; the result does not depend on the seed
TestFunctionRangeQueryLargeOrdinals > testOrdinalAbove2Pow24 FAILED
    java.lang.AssertionError: frange(f):[016777217 TO *] expected:<0> but was:<1>
        at __randomizedtesting.SeedInfo.seed([5EED1108:711E936FD763D735]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at junit@4.13.2/org.junit.Assert.failNotEquals(Assert.java:835)
        at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.queries.function.TestFunctionRangeQueryLargeOrdinals.testOrdinalAbove2Pow24(TestFunctionRangeQueryLargeOrdinals.java:111)
1 test completed, 1 failed

# with the fix (int docVal): :lucene:queries:test (SUCCESS): 1 test- The method computes exact
intordinal bounds for a string range, then compares them infloat; nothing documents approximate string ranges. - Up to 8.5.2 the same method compared
intordinals; LUCENE-9258 (8.6.0) switched tofloatwhile adding multi-valued support, never mentioning precision. - The sibling
IntDocValues.getRangeScorerstill compares inint; 8.5.2 counts the same data correctly.
The full argument228 words
- Contract.
FunctionRangeQuery"matches docs in which the values in the value source match a configured range" (FunctionRangeQuery.java:32-33);FunctionValues.getRangeScorer"matches documents with values between the specified range" (FunctionValues.java:224-226), and the comment above it names the string case, "doing a binary search on the StringIndex" (:228-230). For a string source the range is lexicographic, and the override computes it exactly (DocTermsIndexDocValues.java:129-150). No javadoc, package doc, CHANGES or MIGRATE entry says string ranges are approximate. - Sibling.
IntDocValues.getRangeScorercompares in its native type:int val = intVal(doc); return val >= ll && val <= uu;(IntDocValues.java:113-114). - Tests. No test exercises more than 2^24 ordinals or asserts float rounding;
TestSortedSetFieldSourcechecks an"a".."z"range over two documents, andTestFunctionRangeQuerycovers numeric sources only. - History. Up to 8.5.2 the scorer compared
intordinals:int ord = values.ordValue(); return ord >= ll && ord <= uu;at the 7.0.0, 8.0.0 and 8.5.2 tags, andint ord = termsIndex.getOrd(doc);with the samereturnat 4.0.0, 5.0.0 and 6.0.0. LUCENE-9258 (b1ec1cd9e0c, 2020-03-11, #10298) replaced its private doc-values lookup withexists(doc)/ordVal(doc)so that it works onSortedSetSelectorviews, and wrotefloat docVal = ordVal(doc);, the shape of the float default scorer (float docVal = floatVal(doc);). The commit, its CHANGES entry and the #10298 discussion never mention float or precision.
The devil's-advocate check157 words
The strongest "intended" case (built by the intended-behaviour verifier; a cross-model reviewer rated it moderate): function ranges are float-based by default (Float.parseFloat bounds), the score is documented as a float, DocTermsIndexDocValues is @lucene.internal and FunctionRangeQuery @lucene.experimental, ValueSource is named in the open deprecation proposal #16820, the scale is extreme, and the test's stand-in dictionary has more terms than documents although "Ordinals are dense".
Why it fails: this override exists to do a string range by ordinal and computes exact int bounds, and a string source has no float value at all ("Float scoring does not require float matching", the cross-model reviewer). The trigger goes through public, non-deprecated classes; "experimental" allows API changes, not wrong hits. A plain 16.8M-document single segment reproduces it in under a minute, silently. "Dense" describes the numbering, which the wrapper keeps, and the real-index runs need no wrapper. The deprecation proposal bears on priority, not validity. Verdict: not intended, a regression.
Recommended Compare the ordinal as an int (fix A)
Compare the ordinal as an int: in DocTermsIndexDocValues.getRangeScorer's matches(), change float docVal = ordVal(doc); to int docVal = ordVal(doc);, restoring the pre-8.6 compare. The repro then passes, and so do the whole lucene/queries test suite (513 tests, 0 failures) and :lucene:queries:check -x test.
--- a/lucene/queries/src/java/org/apache/lucene/queries/function/docvalues/DocTermsIndexDocValues.java
+++ b/lucene/queries/src/java/org/apache/lucene/queries/function/docvalues/DocTermsIndexDocValues.java
@@ -153,7 +153,7 @@ public abstract class DocTermsIndexDocValues extends FunctionValues {
       @Override
       public boolean matches(int doc) throws IOException {
         if (!exists(doc)) return false;
-        float docVal = ordVal(doc);
+        int docVal = ordVal(doc);
         return docVal >= ll && docVal <= uu;
       }
     };
All options and trade-offs3 options · 333 words
One fix was built and validated in a scratch worktree of e1faeba08bde; the alternatives are listed with their trade-offs.
One word in DocTermsIndexDocValues.getRangeScorer: the document's ordinal stays an int, so it is compared exactly with the exact int bounds ll and uu. LUCENE-9258's multi-valued support (exists / ordVal) stays as it is.
--- a/lucene/queries/src/java/org/apache/lucene/queries/function/docvalues/DocTermsIndexDocValues.java
+++ b/lucene/queries/src/java/org/apache/lucene/queries/function/docvalues/DocTermsIndexDocValues.java
@@ -153,7 +153,7 @@ public abstract class DocTermsIndexDocValues extends FunctionValues {
       @Override
       public boolean matches(int doc) throws IOException {
         if (!exists(doc)) return false;
-        float docVal = ordVal(doc);
+        int docVal = ordVal(doc);
         return docVal >= ll && docVal <= uu;
       }
     };
Trade-offs
None known. Results change only where they were wrong: values just outside a bound, in segments with more than 2^24 distinct values, stop matching. It also drops the int-to-float conversions per document.
What the checks validated
- Gradle, JDK 25, scratch worktree of
e1faeba08bde(removed afterwards): the test fails on stock with assertions on (seedsDEADBEEF,5EED1108) and off (5EED1108), and passes with the fix, assertions on and off. - With the fix: the test plus
TestFunctionRangeQuery,TestSortedSetFieldSourceandTestDocValuesFieldSources, 12 tests, 0 failures; the whole:lucene:queries:test, 513 tests including the new one, 0 failures, 5 skipped;:lucene:queries:check -x testpasses. - The hunt: the repro passes with the fix shadowed; the wrapper-free 16,777,218-value index gives the right counts; a cross-model reviewer's real-index test and the existing function-query suites pass with it.
Both hold every int ordinal exactly, so they would also fix it.
Trade-offs
No advantage over int, and a wider type would suggest that one is needed. Not validated.
State that string function ranges are approximate above 2^24 distinct values.
Trade-offs
Not recommended: it would legitimise wrong hits that a one-word change removes, and it contradicts the exact bounds the method computes. Not validated.
Downstream, Solr's {!frange} on a string field appears to use the same class (read in Solr's code, not run), and an application that used a string FunctionRangeQuery as an access filter could admit a few documents whose value sits just outside the range edge.
An AI code-reading pass over under-tested classes flagged the float compare of exact int ordinals. A probe on a real 16,777,220-document single segment then showed wrong counts on main, 10.6.0 and 8.6.0 against a byte-comparison reference, with 8.5.2 correct. A second lens found it independently; a Z3 model bounded the error window.
The method in full166 words
Method: non-formal (code reading, then an executed differential probe; the Z3 floating-point model only bounded the window afterwards).
- Round 21 of the hunt built a ranked map of under-tested classes over core and 13 modules. The coverage-gap lens read
DocTermsIndexDocValues.getRangeScorerwith the property "a string range scorer must compare ordinals exactly" and saw thefloatcompare. Its probe (2026-11-02) indexed 16,777,220 unique values into one segment and compared five ranges with a byte-comparison reference: 3 wrong on main, also on 10.6.0 and 8.6.0 (SORTED; SORTED_SET on main too); 8.5.2 clean. - The coverage-critic lens found the same root independently (its probe: 16,777,224 documents, wrong also on 9.12.3). The two leads were then judged together as one finding.
- Its finder reduced it to a public-API JUnit, bounded the window with a Z3 floating-point / bit-vector model (10 obligations) and bisected it to LUCENE-9258. Independent verifiers, a cross-model reviewer (OpenAI GPT-5.6), an adjudication and an audit then re-ran it, and a last check reduced the test to one document.
No public report found (2026-11-02): GitHub issues and PRs incl. the migrated JIRA archive, JIRA (LUCENE, SOLR), the Lucene and Solr mailing lists, Solr, Elasticsearch, OpenSearch, the web and all 409 open PRs. Nearest: the introducing change #10298 (no precision discussion) and #9720 (a different exception from the float default range scorer).
Searches4 searches
None of the hits is the same bug. Not fixed upstream: the newest commit on DocTermsIndexDocValues.java on upstream main, branch_11x and branch_10_6 is d0d2aa274fb (#13440, 2024), which left the compare unchanged. Search limits: keyword search only; GitHub search returns at most 100 results per query; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; apache/solr, apache/lucene-solr, Elasticsearch, OpenSearch) | 2026-11-02 | two scripted prior-report searches (102 queries: class, method, symptom and phrase variants such as DocTermsIndexDocValues ordVal, FunctionRangeQuery 16777216, frange string ordinal float); 17 manual apache/lucene queries plus every issue and PR created or updated since 2026-10-31; 9 downstream queries; 2 code searches | no report; 0 high hits |
| Open PRs and upstream commits | 2026-11-02 | the changed files of all 409 open apache/lucene PRs; the commits API on the file for main, branch_11x, branch_10_6 and branch_10x | no open PR touches DocTermsIndexDocValues.java or changes a range compare; newest commit on the file d0d2aa274fb (#13440, 2024) |
| JIRA, mailing lists and the web | 2026-11-02 | 13 JQL queries over LUCENE and SOLR; dev@, java-user@, issues@, commits@ and the Solr lists; 8 web queries | no report |
| Nearest items (read) | 2026-11-02 | #10298 (LUCENE-9258) body and comments, #9720 (LUCENE-8674), #2723 (LUCENE-1649), SOLR-6562, #16820 | the introducing change (multi-valued support and an NPE, no precision discussion); a different exception in the float default range scorer; int-to-float precision in since-removed score code; float function arithmetic; the open ValueSource deprecation proposal |
Introduced by LUCENE-9258 (#10298, b1ec1cd9e0c, 2020-03-11), first released in 8.6.0; 8.5.2 is the last good release. Main, 10.6.0, 10.5.2, 10.0.0, 9.12.3, 9.0.0, 8.11.4 and 8.6.0 fail; 8.5.2 passes; swapping only the commit's two main source files flips the result both ways. Not fixed upstream.
Versions tested8 rows
Introduced by LUCENE-9258, "DocTermsIndexDocValues' range scorer didn't support multi-valued fields": b1ec1cd9e0c on master and its branch_8x backport e783f3729d6 (author date 2020-03-11; a JIRA patch migrated as #10298, no GitHub PR). The backport shipped first, in 8.6.0. Up to 8.5.2 the method compared int ordinals (the same shape at the 4.0.0, 5.0.0, 6.0.0, 7.0.0 and 8.0.0 tags), so this is a regression. Three later commits touched the file and left the compare: 8ef6a0da568 (reformat) and d0d2aa274fb (#13440) changed the method itself, f3a284ad830 (LUCENE-9796) only bytesVal and strVal. A bytecode check finds the float compare (i2f/fcmp) in all 50 release jars from 8.6.0 to 10.6.0 and an int compare in 8.5.2.
| Version or commit | Verdict | Result |
|---|---|---|
main e1faeba08bde | affected | this doc's test fails through gradle with assertions on and off; passes with the fix |
| 10.6.0, 10.0.0, 9.12.3, 9.0.0, 8.11.4 | affected | the hunt's earlier 2-document test fails, expected:<1> but was:<2> (release jars) |
| 10.5.2 | own test | the independent reproducer's test fails |
| 8.6.0 | first release | the 2-document test fails; the real 16,777,220-value index gives 3 of 5 ranges wrong |
| 8.5.2 | last good | the 2-document test passes; the real index gives 5 of 5 ranges right |
8.5.2 + only the two main source files of e783f3729d6 | bisect | fails: the commit alone breaks the last good release |
8.6.0 + only the same two files from e783f3729d6^ | bisect | passes: reverting only the commit fixes the first bad release |
| 8.6.0 to 10.6.0 (50 releases) | bytecode | matches(int) uses i2f/fcmp and no if_icmp in every release jar |
An independent reproducer (own test plus a wrapper-free 16,777,218-value index), a cross-model review (OpenAI GPT-5.6, executed, real-index test), a devil's-advocate verifier, an adjudication, an audit and a last minimal-repro check reproduced it and agree on the root cause. This doc's gradle runs reproduced it on main and validated the fix.
Checks and verdicts341 words
Every executed check saw the extra hit from the same lines, DocTermsIndexDocValues.java:156-157, and every one that ran the fix saw it pass. The cross-model refute review ran on an earlier main checkout, ea57360912ed, whose four affected source files are identical to e1faeba08bde's.
| Check | Verdict | What it found |
|---|---|---|
| first sighting and an independent second find (round 21) | wrong counts | Lenses, independently: real single-segment indexes of 16,777,220 and 16,777,224 unique values, wrong counts on main, 10.6.0, 9.12.3 and 8.6.0 (SORTED; SORTED_SET on main too), clean on 8.5.2. |
| finder | reproduced | Public-API JUnit fails with assertions on and off and on 10.6.0, passes with the fix; Z3 model bounded the window. Its cross-model review (OpenAI GPT-5.6) confirmed it as Low and corrected the window bound to one float step. |
| independent reproducer | real | Own test fails on main (on, off), 10.6.0, 10.5.2, 9.12.3 and 8.6.0, passes on 8.5.2 and with the fix; a wrapper-free 16,777,218-value index gives wrong counts on main and 10.6.0 and right ones with the fix. |
| cross-model review, refute lens | real (high) | OpenAI GPT-5.6, executed: its own real codec-written 16,777,218-document test returns 2 hits instead of 1 (on, off) and passes with the fix; the fix passes 11 existing tests. Float-semantics argument moderate, rejected. |
| devil's advocate | real, Low | Seven defences tested (float convention, deliberate change, internal/experimental API, scale, dense ordinals, deprecation proposal, upstream acceptance); none survives. Replay fails on main (on, off) and 10.6.0. |
| adjudication | confirmed (high), Low | Re-ran on main (off): fails; with the fix: passes. Silent wrong results, security none. |
| audit and last minimal-repro check | confirmed | The audit re-ran it on main (off) and confirmed it. The last check reduced the test to one document (expected 0, actual 1), 5 of 5 random seeds fail, passes with the fix. |
| this doc | reproduced; fix validated | Gradle on main e1faeba08bde: the test fails with assertions on and off; with the fix it passes, the whole lucene/queries suite passes (513 tests) and :lucene:queries:check -x test passes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 498 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,301 words
- Registry title
- FunctionRangeQuery on a string field (BytesRefFieldSource / SortedSetFieldSource) compares term ordinals as float, so in a segment with more than 2^24 distinct values of the field it also matches values just outside the range bounds
- Area
- queries / function queries (DocTermsIndexDocValues.getRangeScorer: string ValueSource range matching behind FunctionRangeQuery)
- Priority
- Low, rank 580: Released since 8.6.0 with default settings, FunctionRangeQuery over a string ValueSource silently adds a few values just outside a range bound and never loses a hit. It only happens in a segment with more than 2^24 distinct values of the field and only through a rarely used module API, so it is Low.
- Impact class
- silent wrong results
- Impact note
- Applications that filter with lucene/queries FunctionRangeQuery (or another FunctionValues.getRangeScorer caller) over BytesRefFieldSource on a SORTED field or SortedSetFieldSource on a SORTED_SET field get extra hits with no error, but only in segments where that field has more than 2^24 (16,777,216) distinct values, and only for values whose term ordinal rounds to the same float as a bound's ordinal (at most 2 values per bound below 2^25 ordinals, up to 128 near 2^31); no hit is ever lost; default codec and config; every release from 8.6.0 through 10.6.0 and main.
- Summary
- You run FunctionRangeQuery(new BytesRefFieldSource("f"), "016777217", null, true, true) as a filter on a segment whose SORTED field f has more than 2^24 distinct values, and expect only documents whose value is at least "016777217". The document holding "016777216" matches too, with no error: getRangeScorer turns the string bounds into exact int ordinals but then compares each document's ordinal as a float, and above 2^24 neighbouring ordinals round to the same float. Only values within one float step of a bound are wrongly added; no in-range document is lost.
- Introduced
- b1ec1cd9e0ce3498945adaac67d497c226072ba7 (master) and its branch_8x backport e783f3729d63dff23fc82cd151c4348561b7966d (the copy that shipped first, in 8.6.0), LUCENE-9258 'DocTermsIndexDocValues should not assume it's operating on a SortedDocValues field' (apache/lucene#10298, migrated JIRA issue; JIRA patch, no GitHub PR; author micpalmia, committed by dsmiley). To support SortedSetSelector views it replaced the matches() body 'int ord = values.ordValue(); return ord >= ll && ord <= uu;' with 'float docVal = ordVal(doc); return docVal >= ll && docVal <= uu;' [read: git blame of DocTermsIndexDocValues.java:156-157 on main, git log --all -S 'float docVal = ordVal' (only these two commits); exec: 8.5.2 with only the two files from e783f3729d6 shadowed fails, 8.6.0 with the two files from e783f3729d6^ passes]. Later commits 8ef6a0da568 (reformat) and d0d2aa274fb (#13440) touched the method without changing the compare, and f3a284ad830 (LUCENE-9796) changed only bytesVal and strVal in the same file [read]. (2020-03-11 (author date 16:56:10 -0400; committed 16:57:47 -0400 on master and 16:58:42 -0400 on branch_8x))
- First affected version
- 8.6.0 [exec: the repro (8.x port: LuceneTestCase package and totalHits.value spelling only) fails on 8.6.0 and passes on 8.5.2, the last good release]; the string range scorer compared int ordinals from at least 4.0.0 through 8.5.2 [read], so this is a regression
- Affected versions
- every release from 8.6.0 through 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main e1faeba08bde (12.0.0-SNAPSHOT). Executed, all failing 'expected:<1> but was:<2>': the repro JUnit on main (-ea and -da), 10.6.0, 10.0.0, 9.12.3, 9.0.0, 8.11.4 and 8.6.0 (ports differ only in API spelling), an independent reproducer's own JUnit on 10.5.2 as well; 8.5.2 passes [exec]. Bytecode: matches(int) of DocTermsIndexDocValues$1 uses i2f/fcmp and no if_icmp in all 50 release jars 8.6.0-10.6.0, the reverse in 8.5.2 [read]. Real single-segment indexes without any wrapper: 16,777,218 unique SORTED values give wrong counts on main -da and 10.6.0 -da (by the independent reproducer) and on main ea57360912ed -ea/-da (by the cross-model reviewer; the source files involved are identical to e1faeba08bde's); the lead probes (16,777,220 and 16,777,224 documents) fail on main, 10.6.0, 9.12.3 and 8.6.0 and are clean on 8.5.2 [exec]. Not new in 10.6 (10.5.2 fails). Not fixed upstream: the newest upstream commit on DocTermsIndexDocValues.java on main (HEAD 3078a1ce833, checked 2026-11-02), branch_11x and branch_10_6 is d0d2aa274fb (#13440, 2024-06-06), which left the compare unchanged; no open PR touches the file [read through the GitHub API]. Executed on Linux aarch64 with JDK 25.0.3 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by Z3
- Upstream and prior reports
- none found (2026-11-02, on top of the finder's scripted prior-report search of 51 queries and the independent reproduction's, the intended-behaviour check's and the adjudication's GitHub searches; rechecked the same day): two scripted prior-report searches with different phrasings (102 queries over apache/lucene issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; 0 high hits), 17 manual GitHub issue/PR keyword queries on apache/lucene plus listings of every issue or PR created or updated since 2026-10-31, 9 queries on apache/solr, apache/lucene-solr, Elasticsearch and OpenSearch, 2 GitHub code searches, 13 JIRA queries over LUCENE and SOLR, 6 mailing-list searches (Lucene and Solr lists), 8 web queries, and the changed files of all 409 open apache/lucene PRs (none touches DocTermsIndexDocValues.java or SortedSetFieldSource.java or changes a range compare); the items created since 2026-10-31 (#16956-#16962) are unrelated. Not fixed upstream (newest commit on the file d0d2aa274fb, #13440, 2024-06-06). Closest items are context only: #10298 (the introducing change, no precision discussion) and #9720 (open, UnsupportedOperationException from the float default getRangeScorer: different path and symptom).
- Lucene commit tested
- main
e1faeba08bde(2026-11-02) through gradle in a scratch worktree, with assertions on and off, without and with the fix (the repro, the closest suites, the wholelucene/queriestest suite and:lucene:queries:check -x test). The hunt ran the same mechanism on the 10.6.0, 10.5.2, 10.0.0, 9.12.3, 9.0.0, 8.11.4, 8.6.0 and 8.5.2 release jars, bisected the introducing commit by swapping only its two main source files, and ran real single-segment indexes of 16,777,218 to 16,777,224 unique values on main, 10.6.0, 9.12.3, 8.6.0 and 8.5.2. Only Linux aarch64 with OpenJDK 25.0.3 was run.
- Finding record
lucene/queries/src/java/org/apache/lucene/queries/function/docvalues/DocTermsIndexDocValues.java:35 (at e1faeba08bde) (@lucene.internal), :79 (int ordVal(int doc)), :129-150 (getRangeScorer maps the string bounds to exact int ordinals ll/uu with termsIndex.lookupTerm), :152-158 (matches(): 'float docVal = ordVal(doc); return docVal >= ll && docVal <= uu;' at :156-157: fix site)lucene/queries/src/java/org/apache/lucene/queries/function/FunctionRangeQuery.java:31-42 (at e1faeba08bde) (class javadoc 'matches docs in which the values in the value source match a configured range. The score is the float value.'; @lucene.experimental at :42)lucene/queries/src/java/org/apache/lucene/queries/function/valuesource/BytesRefFieldSource.java:33 (at e1faeba08bde) ('for string based fields'), :119 (returns a DocTermsIndexDocValues for SORTED fields); lucene/queries/src/java/org/apache/lucene/queries/function/valuesource/SortedSetFieldSource.java:32 ('multi-valued string based fields'), :60-61 (DocTermsIndexDocValues over SortedSetSelector.wrap)lucene/queries/src/java/org/apache/lucene/queries/function/docvalues/IntDocValues.java:82-114 (at e1faeba08bde) (sibling getRangeScorer compares 'int val = intVal(doc); return val >= ll && val <= uu;' at :113-114); lucene/queries/src/java/org/apache/lucene/queries/function/FunctionValues.java:230-279 (the float default range scorer for numeric sources parses bounds with Float.parseFloat; comment at :230 names the string case)lucene/core/src/java/org/apache/lucene/search/SortedSetSelector.java:35, (at e1faeba08bde) :63-66 (only limit: Integer.MAX_VALUE or more unique values); lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:208 (MAX_DOCS = Integer.MAX_VALUE - 128)
- The finding in 30 seconds
lucene/queries/src/java/org/apache/lucene/queries/function/docvalues/DocTermsIndexDocValues.java:79-81, (at e1faeba08bde) :117-160 (getRangeScorer; exact int bounds :129-150; float compare :155-157)lucene/queries/src/java/org/apache/lucene/queries/function/valuesource/BytesRefFieldSource.java:33, (at e1faeba08bde) :118-119; valuesource/SortedSetFieldSource.java:32, :59-61; FunctionRangeQuery.java:172
- Who is affected
lucene/queries/src/java/org/apache/lucene/queries/function/FunctionRangeQuery.java:42 (at e1faeba08bde) (@lucene.experimental), :172 (only in-tree getRangeScorer caller); FunctionValues.java:48-50 (floatVal throws UnsupportedOperationException); ValueSourceScorer.java:85-87 (score is floatVal)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:208 (at e1faeba08bde) (MAX_DOCS); lucene/core/src/java/org/apache/lucene/search/SortedSetSelector.java:35, :63-68lucene/queries/src/test/org/apache/lucene/queries/function/TestSortedSetFieldSource.java:78 (a test calling getRangeScorer directly)
- Why it looks unintended
lucene/queries/src/java/org/apache/lucene/queries/function/FunctionRangeQuery.java:32-33; (at e1faeba08bde) FunctionValues.java:224-230, :261; docvalues/IntDocValues.java:113-114; docvalues/DocTermsIndexDocValues.java:35, :129-157; lucene/core/src/java/org/apache/lucene/index/SortedDocValues.java:30, :41
- TestFunctionRangeQueryLargeOrdinals.java (lucene/queries, public API):
repro/LFV-1108/TestFunctionRangeQueryLargeOrdinals.java(115 lines)
A summary still (PNG), made from probe runs on main e1faeba08bde.
assets/LFV-1108/bug.png(498 KB)