A shortcut added in 10.3.0 assumes that a field is stored the same way everywhere in the reader. That holds inside one healthy index created by Lucene 9 or later, but not across a MultiReader of separately built indexes.
- A numeric field can be stored as points (a BKD tree, which range queries use) and as doc values (per-document values for sorting and faceting).
LongFieldwrites both. - Inside one index created by Lucene 9 or later, Lucene requires every document to use the same structures for a field (LUCENE-9334). So in one index, "has a doc value for p" means "has a point for p".
- A
MultiReadersearches several separately built indexes as one. Nothing makes their schemas agree.
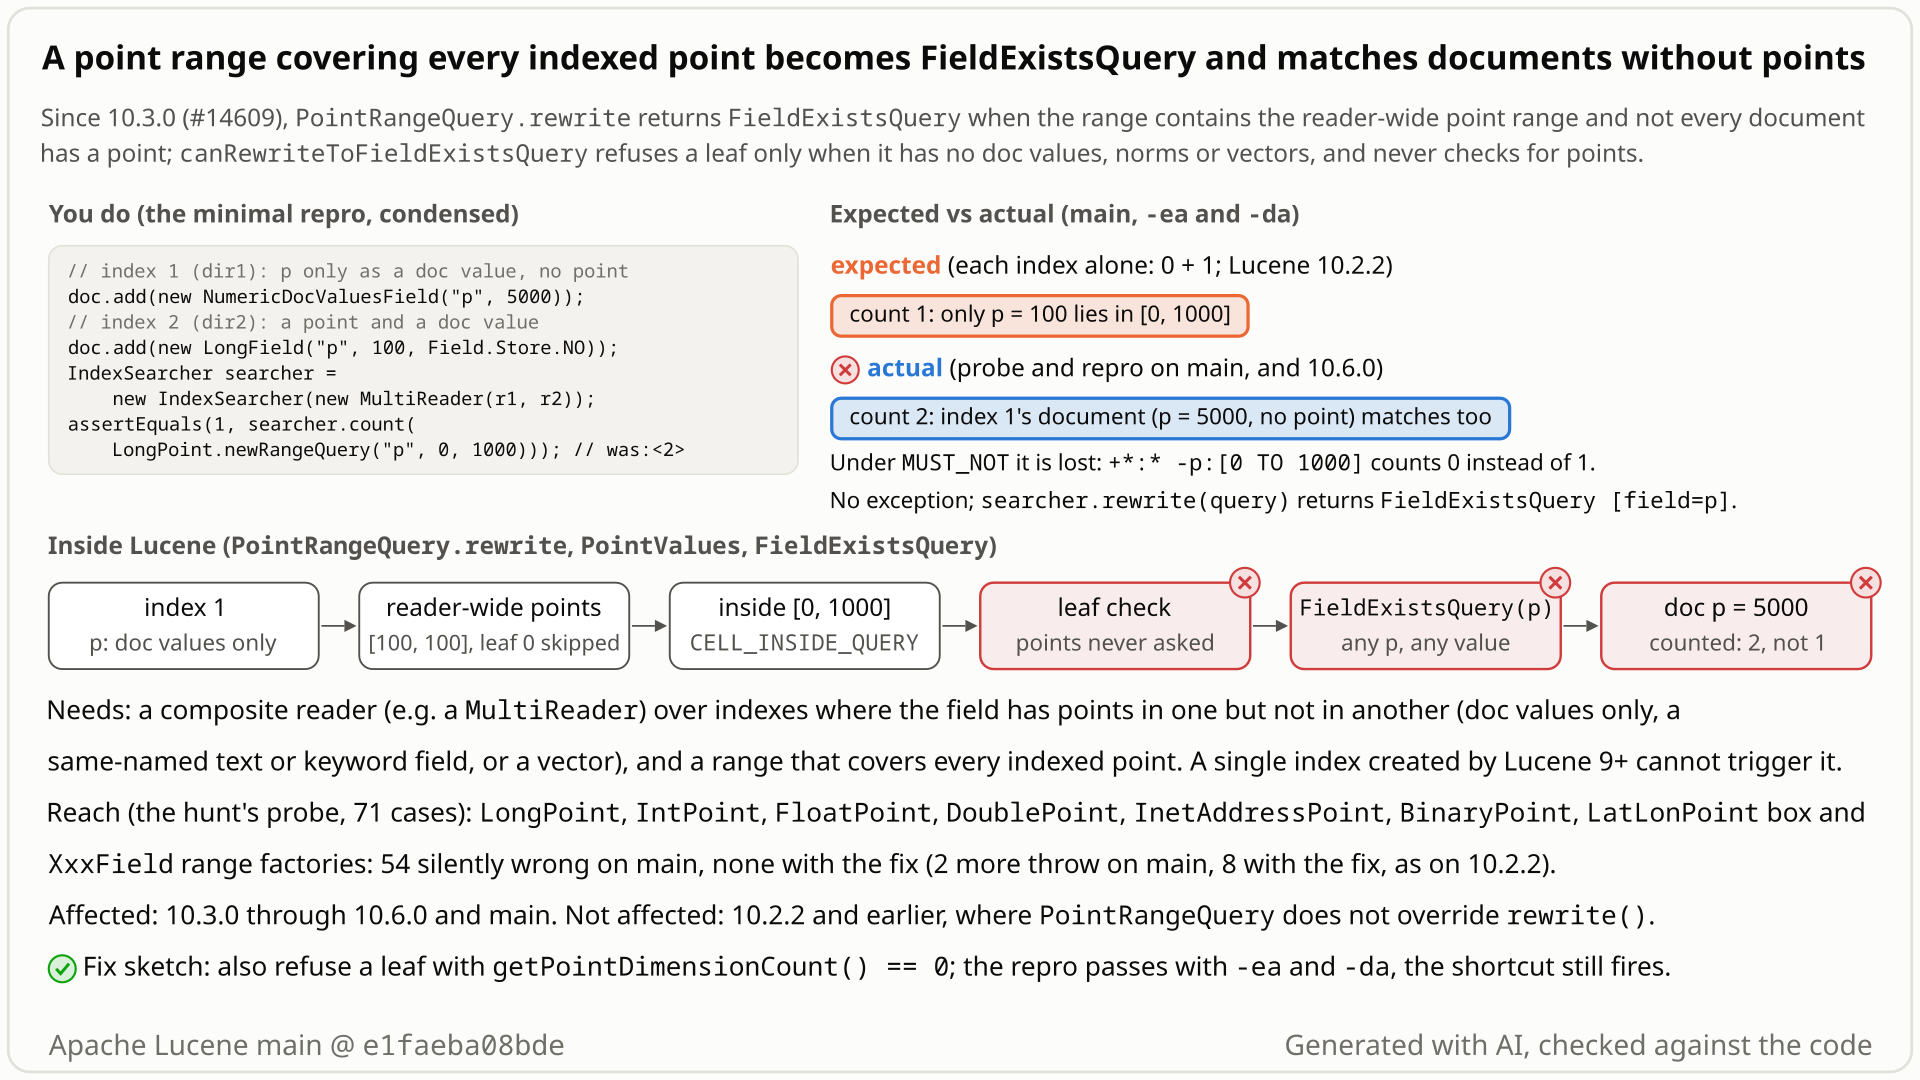
MultiReader: the reader-wide point range [100, 100] skips index 1, lies inside [0, 1000], and the query becomes "has field p", which also matches index 1's document with value 5000. Select the still to open it at full size. Generated with AI, checked against the code.- Build two indexes with default settings. Index 1: one document with only a doc value
p = 5000, no point. Index 2: one document withLongField p = 100(a point plus a doc value). - Open both in one
MultiReaderand countLongPoint.newRangeQuery("p", 0, 1000). You expect 1: only index 2's document has a point, and 100 is in range. Each index alone gives 0 + 1, and 10.2.2 gives 1. - Since 10.3.0 the query first looks at the reader-wide point range. That range skips index 1 (no points), so it is [100, 100], inside [0, 1000]. The query is rewritten to
FieldExistsQuery("p"): any document with norms, a vector or doc values forp. - The safety check asks each index only whether
phas doc values, norms or vectors, never whether it has points. Index 1 has a doc value, so its document matches: the count is 2, although 5000 is outside the range. - Under a NOT clause it flips:
+*:* -p:[0 TO 1000]returns 0 instead of 1. No error; every point range factory tried is affected.
Applications on 10.3.0-10.6.0 or main that search one MultiReader over separately built indexes where a field has points plus doc values, norms or a vector in one index (as LongField writes) and only doc values, text, a keyword or a vector in another, with a range covering every indexed point. Default settings; every point range factory tried. A single index created by Lucene 9 or later reaches it only through another defect that lets in documents with and without the field's points (such as a deleteAll() that overlaps addIndexes); an index first created by Lucene 8 can, when Lucene 9 wrote its documents with and without points for the field into separate segments (run on main).
Mechanism, terms and numbers579 words
Since 10.3.0 (#14609), PointRangeQuery.rewrite checks whether the query range contains every indexed point of the whole reader and, if not every document has a point, replaces the query with FieldExistsQuery(field) (PointRangeQuery.java:544-572 at e1faeba08bde). The reader-wide bounds skip leaves without points (PointValues.java:150-151), and the check that should keep the rewrite safe, canRewriteToFieldExistsQuery (:578-592), refuses a leaf only when the field has no doc values, no norms and no vectors there; it never asks whether the leaf has points. On a MultiReader over separately built indexes, where one index stores the field without points (doc values only, text, a keyword or a vector), the rewritten query therefore matches every document of that index that has norms, a vector or doc values for the field, whatever its value, and under MUST_NOT it drops them. The repro counts 2 instead of 1; 10.2.2 returns 1. A single index created by Lucene 9 or later reaches it only through another defect that lets in documents with and without the field's points, such as a deleteAll() that overlaps addIndexes.
- Points and doc values: two ways to store a numeric field. Range queries such as
LongPoint.newRangeQueryread points;FieldExistsQueryreads norms, vectors or doc values.LongFieldwrites a point and a SORTED_NUMERIC doc value. - LUCENE-9334: "A field across all documents within an index must be indexed with the same index options and data-structures" (
lucene/CHANGES.txt:4771-4775).IndexWriterenforces it per index. MultiReader: "A CompositeReader which reads multiple indexes, appending their content" (MultiReader.java:22-25). Each sub-index becomes one or more leaves; there is no schema check across them.
PointRangeQuery.rewritetakes the reader-wide bounds,PointValues.getMinPackedValue(reader, getField())andgetMaxPackedValue(search/PointRangeQuery.java:552-553). Their javadoc: "Leaves that do not have points for the given field are ignored." (index/PointValues.java:150-151,:185-186). In the repro: [100, 100].relategivesCELL_INSIDE_QUERY(:560).canRewriteToMatchAllQuerycomparesreader.maxDoc()with the point doc count (:574-576): 2 vs 1, no.canRewriteToFieldExistsQuery(:578-592) returns false for a leaf only wheninfo.getDocValuesType() == DocValuesType.NONE && !info.hasNorms() && info.getVectorDimension() == 0(:582-588). Index 1's leaf has NUMERIC doc values, so it passes;getPointDimensionCount()is never read. The query becomesnew FieldExistsQuery(field)(:563-564).FieldExistsQuerymatches documents with a vector field "or a field that indexes norms or doc values" (search/FieldExistsQuery.java:38-41), per leaf through norms, else vectors, else doc values (:170-219). Index 1's document has a doc value, so it matches.- The premise, in
FieldExistsQuery's own rewrite: "This optimization is possible due to LUCENE-9334 enforcing a field to always use the same data structures (all or nothing)." (search/FieldExistsQuery.java:143-144). True per index, not across separately built indexes.
- When every document of every leaf has the field (
FieldExistsQuery.java:116-163; for example the probe's one-document index 1 with a same-namedKeywordField),FieldExistsQueryrewrites further toMatchAllDocsQuery; underMUST_NOTthe clause becomesMatchNoDocsQuery. - A range that only partly overlaps the indexed points is not rewritten (
CELL_CROSSES_QUERY), and one that excludes them all becomesMatchNoDocsQuery(CELL_OUTSIDE_QUERY,PointRangeQuery.java:569-570); both stay correct. - If the point-bearing index has points only (
LongPointwithout doc values, norms or vectors), the check refuses that leaf and the result is correct. - Before #14609,
PointRangeQuerydid not overriderewrite(); every leaf was matched through its own points, so a leaf without points matched nothing.
Exposure and likelihood531 words
- Who. Anyone who searches a
MultiReader(or another composite reader) over separately built indexes in which one field has points plus doc values, norms or vectors in one index (for exampleLongField), and the same field name has doc values, norms or a vector but no points in another. Realistic shapes: a field that was doc-values-only in older indexes and became aLongFieldlater; a name reused for text, a keyword or a vector. - Which queries. Executed reach probe, 71 one-document cases: 54 silently wrong on main (plus 2 that throw), none silently wrong with the fix (the same 8 cases throw there as on 10.2.2).
LongPoint,IntPoint,FloatPoint,DoublePoint,InetAddressPointandBinaryPoint.newRangeQuery,LatLonPoint.newBoxQuery(a box that does not cross the dateline, which is onePointRangeQuery), and theLongField/IntField/FloatField/DoubleField.newRangeQueryfactories (throughIndexOrDocValuesQuery). Also insideBooleanQueryandFunctionScoreQuery.boostByValue(composite decomposition harnesses: 600 of 17,366 and 69 of 2,534 query/composite checks mismatch, 0 with the fix). - Scope for the
XxxField.newRangeQueryfactories. The finding covers only point-less leaves withNUMERICorSORTED_NUMERICdoc values outside the range, and forDoubleFieldandFloatFieldalso leaves that hold only norms or vectors.IndexOrDocValuesQueryrequires that "Both provided queries must match the same documents" (IndexOrDocValuesQuery.java:61), which an in-range doc-values-only leaf already breaks; andLongFieldandIntField.newRangeQuerywrap it inIndexSortSortedNumericDocValuesRangeQuery(LongField.java:138-146), which reads numeric doc values on every leaf (IndexSortSortedNumericDocValuesRangeQuery.java:190,:528), so over a keyword, text, string or vector leaf those two throw on 10.2.2 and with the fix (on main 6 of these 8 cases give a wrong count instead). The headline repro uses plainLongPoint.newRangeQuery. - When. Only ranges that contain every indexed point of the reader: open-ended or wide ranges, the case #14609 targets ("particularly when using time based partitioning, range queries may overlap several indexes").
- Effect. Every document of the point-less index that has norms, a vector or doc values for the field is added, or under
MUST_NOTremoved, whatever its value. Silent: no exception, nothing in the index changes. - Default vs opt-in. Default
IndexWriterConfigandIndexSearcher, assertions on or off. The test picks no codec (for seedDEADBEEFthe test framework choseAsserting(Lucene104); 20 of 20 random seeds fail), and the reach probe, plain Java withnew IndexWriterConfig(), runs on the default codec. The rare part is the reader layout, so likelihood rare (no public report was found either); priority Medium. - Not part of this finding. The 8 loud
IllegalStateExceptioncases ("unexpected docvalues type ... Re-index with correct docvalues type") ofLongFieldandIntField.newRangeQueryover a point-less leaf without numeric doc values, thrown byIndexSortSortedNumericDocValuesRangeQuery(DocValues.getSortedNumericincount,:190); 10.2.2 and the fix throw on the same 8.FieldInfos.getMergedFieldInfosthrowing on such readers (a separate bug). A single segment of an index first created by Lucene 8 whose documents are not all-or-nothing for the field: another root, which this fix does not change. With those documents in separate segments of such an index it is this bug, as Who is affected says (count 2 and 2 hits on main, 1 and 1 with the fix).
One JUnit test method on the public API: two one-document indexes with default settings, a MultiReader, one count. No random inputs, single-threaded; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.LongField;
import org.apache.lucene.document.LongPoint;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.MultiReader;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestPointRangeRewriteLeafWithoutPoints extends LuceneTestCase {

  public void testLeafWithDocValuesButNoPoints() throws Exception {
    try (Directory dir1 = new ByteBuffersDirectory();
        Directory dir2 = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir1, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new NumericDocValuesField("p", 5000));
        w.addDocument(doc);
      }
      try (IndexWriter w = new IndexWriter(dir2, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new LongField("p", 100, Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader r1 = DirectoryReader.open(dir1);
          DirectoryReader r2 = DirectoryReader.open(dir2)) {
        IndexSearcher searcher = new IndexSearcher(new MultiReader(r1, r2));
        // expected 1 (only the p=100 point is in range), actual 2 (the point-less p=5000 doc also matches)
        assertEquals(1, searcher.count(LongPoint.newRangeQuery("p", 0, 1000)));
      }
    }
  }
}
cp $REPRO/TestPointRangeRewriteLeafWithoutPoints.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestPointRangeRewriteLeafWithoutPoints -Ptests.seed=DEADBEEF
# also with -Ptests.asserts=false: same failure
- Expected
- 1 hit: only index 2's document has a point, and 100 is in [0, 1000] (10.2.2 returns 1).
- Observed
java.lang.AssertionError: expected:<1> but was:<2>: the point-less document with value 5000 also matches.
More files, environment, full output225 words
TestPointRangeRewriteLeafWithoutPoints (one method, extends LuceneTestCase, package org.apache.lucene.search of lucene/core tests). Index 1 gets NumericDocValuesField("p", 5000), index 2 LongField("p", 100, Field.Store.NO); both use new IndexWriterConfig() and ByteBuffersDirectory; the searcher is a plain new IndexSearcher(new MultiReader(r1, r2)). About 1.3 s in the standalone runner (a gradle run with build startup took 12-55 s).
Index 1's value can also be written as new SortedNumericDocValuesField("p", 5000), so index 1 uses the same doc-values type as LongField and the only difference is the missing points. In that form it fails on main (-ea) and 10.6.0 (-da) and passes on 10.2.2 (-da).
As a regression test the same method fits in TestPointQueries, next to testRangeQueryOptimizesRewrites.
| lucene | main e1faeba08bde (12.0.0-SNAPSHOT) and 10.3.0-10.6.0: fail; 10.2.2 and earlier: pass |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestPointRangeRewriteLeafWithoutPoints.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestPointRangeRewriteLeafWithoutPoints -Ptests.seed=DEADBEEF
# gradle, worktree at e1faeba08bde, -Ptests.seed=DEADBEEF (same with -Ptests.asserts=false)
TestPointRangeRewriteLeafWithoutPoints > testLeafWithDocValuesButNoPoints FAILED
    java.lang.AssertionError: expected:<1> but was:<2>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1FD6C01022C186CF]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.junit.Assert.assertEquals(Assert.java:633)
        at org.apache.lucene.search.TestPointRangeRewriteLeafWithoutPoints.testLeafWithDocValuesButNoPoints(TestPointRangeRewriteLeafWithoutPoints.java:51)
:lucene:core:test (FAILURE): 1 test, 1  failure

# same test, standalone runner
10.2.2 -da: PASS        10.6.0 -da: FAIL expected:<1> but was:<2>
main -ea / -da: FAIL expected:<1> but was:<2> main + fix -ea / -da: PASSLongPoint.newRangeQueryreturns "a query matching documents within this range";MultiReaderreads multiple indexes with no schema precondition; 10.2.2 is correct.- The shortcut's premise, LUCENE-9334, is a per-index rule ("within an index"), and #14609 scoped the rewrite to "all docs in index".
- Maintainers fixed the same kind of per-index assumption leaking across
MultiReaderleaves as incorrect results (#14399, fixed in 10.6.0).
The full argument292 words
- Contracts.
LongPoint.newRangeQuery: "@return a query matching documents within this range." (LongPoint.java:212).PointRangeQuery: "Abstract class for range queries against single or multidimensional points" (PointRangeQuery.java:41).MultiReader: "A CompositeReader which reads multiple indexes, appending their content. It can be used to create a view on several sub-readers (like DirectoryReader) and execute searches on it." (MultiReader.java:22-25), no schema precondition. - A rewrite must not change results. The un-rewritten query is correct on every leaf; 10.2.2 and 9.12.3 return the right count on the same
MultiReader. - Scoped to one index by its authors. PR #14609: "handle cases where the query either fully contains or fully excludes all documents within the shard". CHANGES 10.3.0: "rewriting to MatchAllDocsQuery/FieldExistsQuery/MatchNoDocsQuery if all docs in index are contained or excluded" (
CHANGES.txt:1681-1682). The review's code comments were about reusingrelate(), an early return when a dimension is neither inside nor outside, and null min/max, plus the javadoc tag order and a request for a CHANGES entry; none of them mentions composite readers. - Tests.
TestPointQueries.testRangeQueryOptimizesRewrites(TestPointQueries.java:2473) uses one consistent index; no upstream test builds aMultiReaderwith a point-less leaf. - Precedent. #14399 (jpountz): "While IndexWriter enforces that the whole index has the same index sort, it is possible to create a
MultiReaderacross several indexes which have different index sorts, so this cache is incorrect." Fixed by #16434: "This fixes incorrect results when searching a MultiReader that combines indexes with different index sorts" (CHANGES.txt:763-765). In the #15083 review jpountz wrote "MultiReaderallows mixing segments that have a skip index on the field and segments that don't", andDocValuesSkipper.globalMinValuereturnsLong.MIN_VALUEwhen a leaf has the field but no skipper (DocValuesSkipper.java:145-160): the guard this check lacks.
The devil's-advocate check177 words
The strongest case for "intended" (built by an intended-behaviour checker): the rewrite builds on LUCENE-9334, which Lucene relies on for several optimizations; the two indexes conflict on field p, and FieldInfos.getMergedFieldInfos throws on this exact reader ("cannot change field \"p\" from doc values type=NUMERIC to inconsistent doc values type=SORTED_NUMERIC"); PointRangeQuery is @lucene.experimental (PointRangeQuery.java:52); so a mixed-schema MultiReader could be called unsupported.
Why it fails: LUCENE-9334 is documented per index. #14609 combines a reader-wide statistic (point bounds that skip point-less leaves) with a per-leaf FieldExistsQuery that also matches point-less leaves, which stretches the per-index rule across index boundaries. MultiReader documents no schema precondition and getMergedFieldInfos documents no exception (its throw is a separate bug). @lucene.experimental marks an unstable API, not wrong results, and the factories that return the query are not experimental. The extra document's value, 5000, matches [0, 1000] under no reading; with index 1 written as SortedNumericDocValuesField the indexes differ only in the missing points and it still fails. Maintainers fixed the same kind of cross-leaf assumption as incorrect results (#14399 / #16434).
Recommended Also refuse a leaf that has the field without points (validated)
In canRewriteToFieldExistsQuery, also refuse a leaf whose field has no points (info.getPointDimensionCount() == 0). A mixed reader then runs the normal point query; consistent indexes keep the shortcut. Validated with gradle: the repro passes, and so do 275 search and document test classes.
       if (info != null
-          && info.getDocValuesType() == DocValuesType.NONE
-          && !info.hasNorms()
-          && info.getVectorDimension() == 0) {
+          && (info.getPointDimensionCount() == 0
+              || (info.getDocValuesType() == DocValuesType.NONE
+                  && !info.hasNorms()
+                  && info.getVectorDimension() == 0))) {
         // Can't use a FieldExistsQuery on this segment, so return false
         return false;
       }
All options and trade-offs2 options · 467 words
Two options; the first was built and validated, the second is simpler but gives up more of the optimization. The choice is the maintainers'.
One condition in canRewriteToFieldExistsQuery (PointRangeQuery.java:582-585). A leaf with the field but no points makes rewrite fall back to super.rewrite(searcher), the normal per-leaf point query; a leaf without the field (info == null) still allows the rewrite.
       if (info != null
-          && info.getDocValuesType() == DocValuesType.NONE
-          && !info.hasNorms()
-          && info.getVectorDimension() == 0) {
+          && (info.getPointDimensionCount() == 0
+              || (info.getDocValuesType() == DocValuesType.NONE
+                  && !info.hasNorms()
+                  && info.getVectorDimension() == 0))) {
         // Can't use a FieldExistsQuery on this segment, so return false
         return false;
       }
Trade-offs
- Keeps the optimization on every consistent layout tested: a rewrite differential over consistent layouts (points only, points plus doc values or norms, sparse, multi-valued, 2-D, absent-field segments, deletions) ran 1,250,932 checks with 0 failures and the same rewrite-kind histogram as stock (FieldExistsQuery 4,696, MatchAllDocsQuery 2,370).
- On a mixed composite the shortcut is lost for that query, which then runs as before #14609.
- It does not cover a single 8.x-created segment whose documents are not all-or-nothing; that is a different root and needs its own fix. With such documents in separate segments the fix does apply (count 2 -> 1).
What the checks validated
- Gradle in a scratch worktree at
e1faeba08bde, JDK 25,-Ptests.seed=DEADBEEF(2026-11-02): the repro fails without the fix (asserts on and off) and passes with it (asserts on and off). - With the fix:
TestPointQueries(56 tests, 2 skipped),TestFieldExistsQuery(30) andTestIndexOrDocValuesQuery(5, 1 skipped) pass; all oforg.apache.lucene.search.*andorg.apache.lucene.document.*with the repro: 275 classes, 2,849 tests, 0 failures, 75 skipped. - Earlier checks: the composite decomposition harnesses go from 600 of 17,366 and 69 of 2,534 mismatching query/composite checks to 0, the factory reach probe from 54 silently wrong cases to 0 (with the fix its summary reads
ok=63 bad=8: all 8 are loudIllegalStateExceptions that 10.2.2 throws too), and a Z3 model of the rewrite decision (3 leaves x 2 documents, 11 queries) finds a counterexample with the shipped condition onMultiReaders and none with the fix or on a single strict index.
Keep the MatchAllDocsQuery and MatchNoDocsQuery rewrites, which use reader-wide counts and are sound on composites, and fall back to super.rewrite(searcher) where the FieldExistsQuery branch is. The weight's per-leaf shortcuts stay (for example count returns a leaf's point doc count when its own bounds are inside the range, PointRangeQuery.java:353-357).
Trade-offs
Simplest to reason about, but it also gives up the FieldExistsQuery rewrite on consistent indexes, which TestPointQueries.testRangeQueryOptimizesRewrites asserts and #14609 wanted ("rewriting at the shard level enables other optimizations downstream").
Downstream engines that combine indexes with different schemas for one field and filter visibility with a full-coverage point range would show (or, under an exclusion, hide) every document of the point-less index that has norms, a vector or doc values for the field, whatever its value.
While reviewing 10.x features, reading the 10.3.0 rewrite (#14609) raised the question whether a point range on a composite reader still matches exactly the documents with an in-range point. An executed probe showed 2 hits instead of 1 on main, 10.6.0 and 10.3.0, with 10.2.2 correct. It was reduced to one test and checked with a Z3 model.
The method in full172 words
Method: non-formal (the first signal came from code reading and an executed probe; the Z3 model came later).
- Lead. A review of features new in 10.x read the #14609 rewrite with the property "on every composite reader a point range query matches exactly the documents that have a point in range, leaf by leaf".
- Probe. Public-API probes on the stock main jar: 6 hits instead of 3 in a larger probe and a count of 2 instead of 1 in the minimal one, on main, 10.6.0 and 10.3.0; 10.2.2 correct.
- Generalisation. A composite-reader count-decomposition oracle (a
MultiReadercount must equal the sum of the per-index counts) found that every mixed-schema mismatch among the layouts it tried has this root. - Reduction and model. One JUnit test; a Z3 model of the rewrite decision (3 leaves x 2 documents, 11 queries) finds a counterexample with the shipped condition on
MultiReaders, none with the fix or on a single strict index, and shows that positive ranges can only over-match (lost hits needMUST_NOT).
No prior report found (2026-11-02): 102 scripted queries over GitHub issues and PRs (including the JIRA archive), downstream trackers, the mailing lists and the web; a GitHub-wide search for canRewriteToFieldExistsQuery (0 hits); the changed files of all 410 open PRs.
Searches5 searches
Related, not reports of this bug: #14609 (introduces it; no review comment mentions composite readers); #16582 (sibling doc-values rewrite, leaves this check alone); #14399 / #16434 (the same class of bug in TopFieldCollector, fixed in 10.6.0); #16573 (closed: a doc-values range query trusting point statistics within one index); #10374 / LUCENE-9334 (the per-index rule); #11554 / LUCENE-10518 (consistency shortcuts on Lucene-8-created indexes); #15290 (open refactor that keeps the condition). Limits: keyword search; a report worded without these class names could be missed; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| Scripted search (GitHub issues and PRs including the migrated JIRA archive, commits, Elasticsearch, OpenSearch and Solr, dev@, java-user@, issues@, commits@, the web) | 2026-11-02 | two runs, 102 queries, for example canRewriteToFieldExistsQuery, "PointRangeQuery rewrite FieldExistsQuery", "FieldExistsQuery MultiReader", "PointRangeQuery mixed schema", "PointRangeQuery doc values only", symptom phrasings ("wrong results", "missing documents") | the only high-overlap hit is the introducing PR #14609 |
| GitHub (manual) | 2026-11-02 | 12 issue/PR searches on apache/lucene; downstream repositories; all of GitHub for canRewriteToFieldExistsQuery; "PointRangeQuery MultiReader", "FieldExistsQuery rewrite points", "MultiReader schema consistency" | no report (0 hits for the method name; these are exact-phrase searches; the fact checker's plain term searches returned #14609, #15083, #16578 and #16582, none a report) |
| Open apache/lucene PRs | 2026-11-02 | the changed files of all 410 open PRs; the patches of the 9 that touch PointRangeQuery.java or FieldExistsQuery.java | none changes the condition (#15290 keeps it) |
| Threads read in full | 2026-11-02 | #14609, #16582, #14399, #16573, #15083, #11554, #10374 and others | no mention of composite readers or leaves without points |
| New items | 2026-11-02 | every issue and PR created since 2026-10-31 (through #16963); commits on PointRangeQuery.java | nothing related; newest commit on the file is #16089, already in e1faeba08bde |
Introduced by #14609 (416dd2fe7c37 on main, b6851e1b37c on branch_10x, merged 2025-05-10), first released in 10.3.0. Fails on 10.3.0 through 10.6.0 and main; passes on 9.12.3 and 10.0.0-10.2.2, where PointRangeQuery has no rewrite() override. Bisected both ways.
Versions tested8 rows
Introduced by apache/lucene#14609 "Overrides rewrite in PointRangeQuery to optimize AllDocs/NoDocs cases" (ebradshaw; reviewed and approved by jpountz and jainankitk; milestone 10.3.0; no linked issue): main merge commit 416dd2fe7c37 and branch_10x backport b6851e1b37c (the copy that shipped), same author date 2025-05-09 and the same PointRangeQuery.java diff.
Since then the condition is unchanged at every affected tag and on upstream main head 3078a1ce833 (2026-11-02), branch_11x and branch_10_6. Later commits to the file (#14626, #14991, #15499, #16582, #16089) left it alone; #16582 rewrote canRewriteToMatchAllQuery only.
10.3.1, 10.5.0 and 10.5.1 are affected by code identity of the rewrite()..relate() block (not executed).
| Version or commit | Verdict | Result |
|---|---|---|
main e1faeba08bde (12.0.0-SNAPSHOT) | affected | fails: gradle and the standalone runner, assertions on and off, expected:<1> but was:<2> |
10.6.0 (4ae946e5a9b) | affected | fails, -ea and -da |
| 10.5.2, 10.4.0, 10.3.2 | affected | fails, -da |
| 10.3.0 | affected | fails, -ea and -da (first affected release) |
10.2.2 + only b6851e1b37c's PointRangeQuery.java | bisect | fails: the commit alone introduces it |
10.3.0 with only the rewrite() override removed | bisect | passes |
| 10.2.2, 10.2.0, 10.0.0, 9.12.3 | not affected | passes (no rewrite() override; checked at all 26 9.x and 10.0-10.2 tags) |
| main + fix | not affected | passes; 275 search and document test classes pass |
An independent reproducer, reviews from another model family (OpenAI GPT-5.6, executing), an intended-behaviour devil's advocate, an adjudication and a credibility audit all confirmed it; this doc adds gradle runs with and without the fix.
Checks and verdicts337 words
This doc adds gradle runs of the one-method test in a scratch worktree at e1faeba08bde, without and with the fix (plus 275 search and document test classes with the fix), and runs of it on 10.6.0 and 10.2.2.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Fails on main, 10.6.0 and 10.3.0 (-ea, -da) and 20 of 20 random seeds; passes on 10.2.2 and with the fix; Z3 model of the rewrite decision. |
| cross-model reviews, refute and intended lenses | real, high | OpenAI GPT-5.6, executing, on main ea57360912ed (the code involved is byte-identical to e1faeba08bde): own tests give 3 hits instead of 2 and 2 instead of 1 on main, pass on 10.2.2, fail on 10.3.0, pass with the fix; the intended case was judged weak. |
| Independent reproducer | real | Own test (LongPoint plus NumericDocValuesField): count 2 vs 1 and MUST_NOT 0 vs 1 on main (4 seeds), 10.6.0, 10.5.2 and 10.3.0; passes on 10.2.2, 9.12.3 and with the fix. |
| Cross-model review, root-cause lens | real, high | OpenAI GPT-5.6: count 2 vs per-index sum 1, MUST_NOT loses a document; a trace shows the point-less leaf has 0 point dimensions yet the rewrite returns FieldExistsQuery. |
| intended-behaviour devil's advocate | real, high | Four defences tested, none survives; SortedNumericDocValuesField-only and TextField probes fail on main and 10.6.0 and pass on 10.2.2. |
| adjudication | confirmed, high, Medium | Re-ran on main (-ea, -da: fails) and with the fix (passes); the SortedNumericDocValuesField form fails on main and 10.6.0 and passes on 10.2.2. |
| credibility audit and final repro check | confirmed | One minimal test, fails on main -ea/-da, passes with the fix; the audit's own probe confirms the FieldExistsQuery [field=p] rewrite and the lost MUST_NOT document. |
| this doc | real as described | Gradle at e1faeba08bde: fails without the fix (asserts on and off), passes with it; 275 test classes pass with the fix; the test passes on 10.2.2 and fails on 10.6.0. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 508 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,605 words
- Registry title
- PointRangeQuery rewrites a range that covers every indexed point to FieldExistsQuery without checking that each leaf has points, so on a MultiReader whose other index stores the field without points it also matches (or, under MUST_NOT, drops) documents that have no point
- Area
- core / search: PointRangeQuery.rewrite (GITHUB#14609 full-coverage rewrite to FieldExistsQuery, new in 10.3.0) on composite readers
- Priority
- Medium, rank 88: In 10.3.0 through 10.6.0 with default settings, the core point range queries silently match (or under MUST_NOT drop) documents that have no point when the range covers every indexed point and a composite reader spans separately built indexes, one of which stores the field without points. That mixed-schema layout is rare, so it is mid-Medium.
- Impact class
- silent wrong results
- Impact note
- Applications on 10.3.0 through 10.6.0 or main that search one MultiReader (or another composite reader) over separately built indexes in which a field has points plus doc values, norms or a vector in one index (as LongField writes) but no points in another (only doc values, a same-named KeywordField or TextField, or a vector field), with the default IndexWriterConfig, codec and IndexSearcher and at ordinary scale: every point range query on that field whose range covers all indexed points (LongPoint, IntPoint, FloatPoint, DoublePoint, InetAddressPoint and BinaryPoint.newRangeQuery, LatLonPoint.newBoxQuery (tested with a box that does not cross the dateline), and the Long/Int/Float/DoubleField.newRangeQuery factories through IndexOrDocValuesQuery) silently also matches every document of the point-less index that has norms, a vector or doc values for the field, whatever its value, and silently drops those documents under MUST_NOT; the same range used as the filter of a KnnFloatVectorQuery lets those documents into the kNN hits, used as the child query of a ToParentBlockJoinQuery it returns their parents (with every ScoreMode), and a QueryBitSetProducer over it caches the wrong bitset for the point-less index's segment and returns it again when that segment is later reached through the index's own reader; a single index created by Lucene 9 or later reaches it only when IndexWriter has let in documents that have the field without its points, which its per-field consistency check should prevent, for example since 10.5.0 through LFV-118's skipped schema check, which can accept such a document into the same in-memory segment (executed: LongPoint and LongField.newRangeQuery("f", 0, 100) count 3 instead of 2 on main, 10.5.0 and 10.6.0, while 10.4.0 rejects that document), or through a deleteAll() that overlaps addIndexes (LFV-1074), which lets a later document give a field that addIndexes brought in a schema without points (executed with -da, on main also with -ea: LongPoint.newRangeQuery("f", 0, 100) counts 2 instead of 1 on main, 10.6.0, 10.5.0, 10.4.0 and 10.3.0); an index first created by Lucene 8 can reach it when Lucene 9 wrote its documents with and without points for the field into separate segments (executed on main); nothing throws and no index is changed.
- Summary
- You open a MultiReader over two separately built indexes, one whose document has field p only as a doc value (5000, no point) and one whose document has LongField p=100, and count LongPoint.newRangeQuery("p", 0, 1000); you expect 1, which is what each index gives on its own (0 + 1) and what 10.2.2 returns. You get 2 with no error: since 10.3.0 (#14609) PointRangeQuery.rewrite sees that the reader-wide point range [100, 100] lies inside the query and, because every leaf has doc values, norms or vectors for p, replaces the query with FieldExistsQuery(p), which also matches the document that has no point. Under a MUST_NOT clause the same rewrite drops that document instead.
- Introduced
- b6851e1b37cbed68da83247110efa2da41d3b570 (branch_10x backport, the copy that shipped first, in 10.3.0) and its main-line merge commit 416dd2fe7c37ef76b2085ea25b0f54e5a6f32367 (same author date, identical PointRangeQuery.java diff), apache/lucene#14609 'Overrides rewrite in PointRangeQuery to optimize AllDocs/NoDocs cases' (author ebradshaw, reviewed and approved by jpountz and jainankitk, milestone 10.3.0, no linked issue). Before it, PointRangeQuery inherited Query.rewrite() and matched every leaf through its own points. [exec: 10.2.2 with only the commit's PointRangeQuery.java fails; 10.3.0 with only the rewrite() override removed passes; git log -S canRewriteToFieldExistsQuery finds only these two commits] (2025-05-09 (author date 2025-05-09 23:48:53 -0400 = 2025-05-10T03:48:53Z; merged on main 2025-05-10T03:48:54Z; branch_10x backport committed 2025-05-10T03:55:58Z))
- First affected version
- 10.3.0 [exec: the repro fails with -ea and -da; 10.2.2, the last unaffected release, passes with -ea and -da]; a regression, not a day-one bug
- Affected versions
- 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 and 10.6.0 (released 2026-10-29, 4ae946e5a9b), and main e1faeba08bde (12.0.0-SNAPSHOT). Executed, all failing 'expected:<1> but was:<2>': main -ea and -da, 10.6.0 -ea and -da, 10.5.2 -da (and -ea in the independent reproduction), 10.4.0 -da, 10.3.2 -da, 10.3.0 -ea and -da [exec]; 10.3.1, 10.5.0 and 10.5.1 by code identity of the rewrite()..relate() block [read]; upstream main head 3078a1ce833 (2026-11-02), branch_11x and branch_10_6 heads have the same condition [read]. Not affected: every 9.x release and 10.0.0-10.2.2, where PointRangeQuery does not override rewrite() (checked at all 26 tags); the repro passes unchanged on 9.12.3, 10.0.0, 10.2.0 and 10.2.2 [exec]. Not new in 10.6.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by code reading
- Upstream and prior reports
- none found (2026-11-02, on top of the finder's scripted prior-report search of 51 queries and the independent reproduction's, the intended-behaviour check's and the adjudication's GitHub searches; rechecked the same day): two scripted prior-report searches (102 queries over apache/lucene issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; the only high-overlap hit is the introducing PR #14609), 12 manual GitHub issue/PR searches on apache/lucene, searches of elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr, an all-GitHub search for canRewriteToFieldExistsQuery (0 hits), the file lists of all 410 open apache/lucene PRs plus the patches of the 9 that touch PointRangeQuery.java or FieldExistsQuery.java (none changes the condition; #15290 keeps it), every issue or PR created or updated since 2026-10-31 (through #16963, created 2026-11-02; none touches PointRangeQuery, FieldExistsQuery or MultiReader), and lists.apache.org dev@ and java-user@ over 2 years. A same-day recheck found no apache/lucene issue or PR for canRewriteToFieldExistsQuery, "PointRangeQuery MultiReader" or "FieldExistsQuery rewrite points"; the newest upstream commit on PointRangeQuery.java is still 1169cd2007d (#16089, 2026-10-14, already in e1faeba). Related, not reports: #14609 (introducing PR), #16582 (sibling doc-values rewrite, merged 2026-09-15), #14399 / #16434 (same bug class in TopFieldCollector, fixed in 10.6.0), #16573 (closed: a doc-values range query trusting point statistics in one index), #10374 (LUCENE-9334, the per-index consistency rule) and #11554 (LUCENE-10518, consistency shortcuts on Lucene-8-created indexes, the background of LFV-490).
- Lucene commit tested
- this one-method test on main
e1faeba08bde(gradle in a scratch worktree at that commit with-Ptests.asserts=trueandfalse, without and with the fix; with the fix also 275 test classes oforg.apache.lucene.search.*andorg.apache.lucene.document.*; the standalone JUnit runner with-eaand-da), on 10.6.0 (fails) and 10.2.2 (passes),-da. The same test body (an earlier copy that differs only in the method name and comments) was run on 10.3.0, 10.3.2, 10.4.0 and 10.5.2 (fail) and on 9.12.3, 10.0.0 and 10.2.0 (pass), plus the two bisect shadows.
- Finding record
lucene/core/src/java/org/apache/lucene/search/PointRangeQuery.java:41 (at e1faeba08bde) (class javadoc 'Abstract class for range queries against single or multidimensional points'), :52 (@lucene.experimental), :544-572 (rewrite: reader-wide min/max at :552-553, CELL_INSIDE_QUERY -> MatchAllDocsQuery at :561 or FieldExistsQuery at :563-564), :574-576 (canRewriteToMatchAllQuery: maxDoc == point doc count), :578-592 (canRewriteToFieldExistsQuery: rejects a leaf only when its FieldInfo has no doc values, no norms and no vectors; no point-dimension check: fix site)lucene/core/src/java/org/apache/lucene/index/PointValues.java:155-165 (at e1faeba08bde) and :190-196 (getMinPackedValue and getMaxPackedValue skip leaves without point values)lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:39-40 (at e1faeba08bde) (matches documents with a vector field or a field that indexes norms or doc values), :143-144 ('This optimization is possible due to LUCENE-9334 enforcing a field to always use the same data structures (all or nothing)')lucene/core/src/java/org/apache/lucene/document/LongPoint.java:212 (at e1faeba08bde) ('@return a query matching documents within this range.')lucene/core/src/java/org/apache/lucene/index/MultiReader.java:22-25 (at e1faeba08bde) ('A CompositeReader which reads multiple indexes, appending their content'; no schema precondition)lucene/CHANGES.txt:1681-1682 (at e1faeba08bde) (10.3.0 Optimizations: GITHUB#14609 rewrites 'if all docs in index are contained or excluded'), :763-765 (10.6.0: GITHUB#14399 'fixes incorrect results when searching a MultiReader that combines indexes with different index sorts'), :4772 (LUCENE-9334 'A field across all documents within an index must be indexed with the same index options and data-structures')
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/PointRangeQuery.java:544-572 (at e1faeba08bde) (rewrite), :552-553 (reader-wide bounds), :560-564 (CELL_INSIDE_QUERY branch), :574-576, :578-592 (canRewriteToFieldExistsQuery, no point check), :569-570 (CELL_OUTSIDE_QUERY, CELL_CROSSES_QUERY)lucene/core/src/java/org/apache/lucene/index/PointValues.java:150-182, (at e1faeba08bde) :185-196 (min/max skip leaves without points)lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:38-41, (at e1faeba08bde) :116-163 (its own rewrite to MatchAllDocsQuery when every document of every leaf has the field), :143-144, :170-219lucene/core/src/java/org/apache/lucene/index/MultiReader.java:22-25 (at e1faeba08bde)lucene/CHANGES.txt:4771-4775 (at e1faeba08bde) (LUCENE-9334)
- Who is affected
lucene/core/src/java/org/apache/lucene/search/IndexOrDocValuesQuery.java:61 (at e1faeba08bde)lucene/core/src/java/org/apache/lucene/document/LongField.java:138-146, (at e1faeba08bde) search/IndexSortSortedNumericDocValuesRangeQuery.java:190, :528 (the wrapper that reads numeric doc values on every leaf), index/DocValues.java:226 (the exception)lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:116-163 (at e1faeba08bde) (its rewrite to MatchAllDocsQuery needs every document of every leaf)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/document/LongPoint.java:212 (at e1faeba08bde)lucene/core/src/java/org/apache/lucene/search/PointRangeQuery.java:41, (at e1faeba08bde) :52lucene/core/src/java/org/apache/lucene/index/MultiReader.java:22-25 (at e1faeba08bde)lucene/CHANGES.txt:763-765 (at e1faeba08bde) (GITHUB#14399), :1681-1682 (GITHUB#14609), :4771-4775 (LUCENE-9334)lucene/core/src/test/org/apache/lucene/search/TestPointQueries.java:2473 (at e1faeba08bde)lucene/core/src/java/org/apache/lucene/index/DocValuesSkipper.java:145-160 (at e1faeba08bde)
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/PointRangeQuery.java:353-357, (at e1faeba08bde) :578-592
- TestPointRangeRewriteLeafWithoutPoints.java (lucene/core, package org.apache.lucene.search, 1 test):
repro/LFV-1109/TestPointRangeRewriteLeafWithoutPoints.java(55 lines)
A small diagram made from the executed repro numbers.
assets/LFV-1109/bug.png(508 KB)