The owner rule is right inside one segment, but the composite reader applies it separately in each segment. A segment of the first index that lacks the field (no document written to it had the field) falls through to the next index.
- A
ParallelCompositeReaderputs indexes side by side: document 7 of the result is document 7 of every index, with the union of their fields. The indexes must hold the same documents in the same order, in the same segments. - When two indexes have the same field, the class javadoc says matches come from the first index added that has the field.
- Each segment keeps its own field list (
FieldInfos): the fields of the documents written to it. A field that no document of the segment ever had is not on the list.
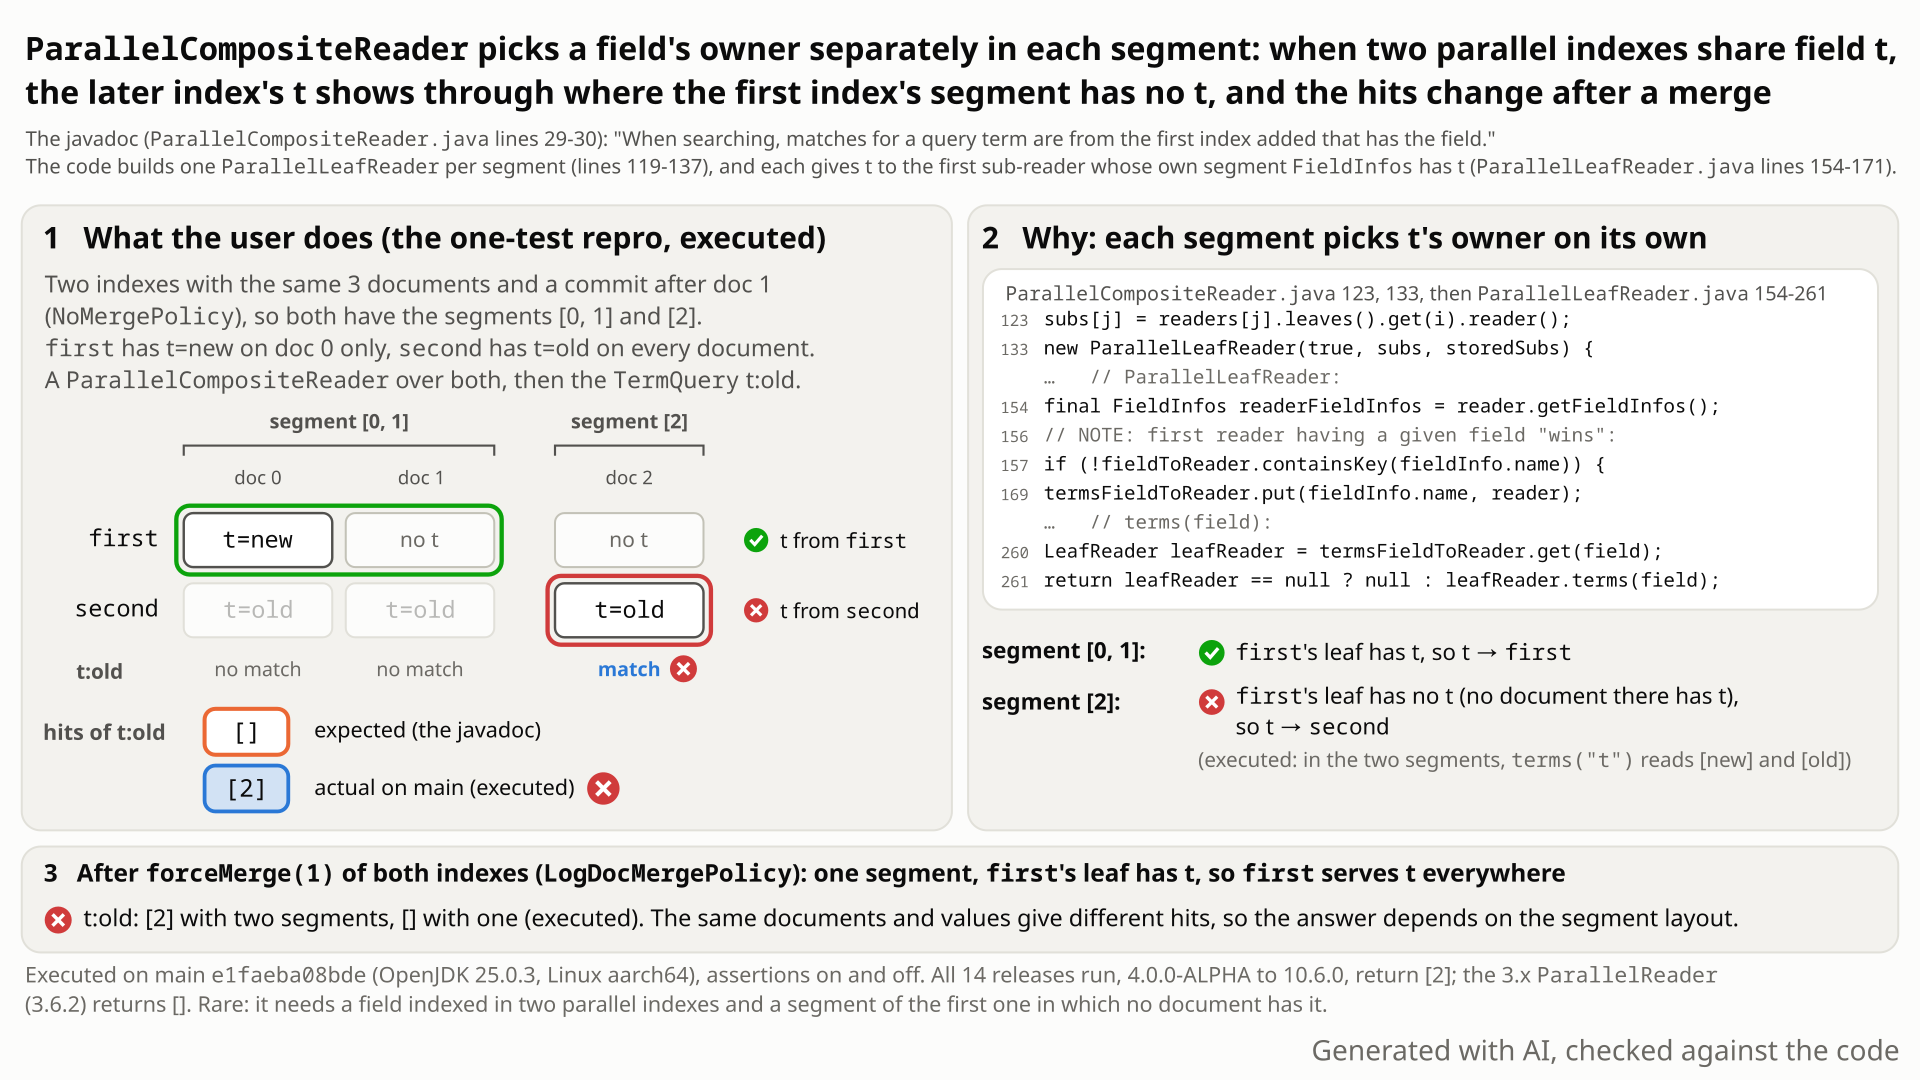
t, so the second index's t=old answers there; after a merge to one segment the first index owns t again. Select the still to open it at full size. Generated with AI, checked against the code.- Build two indexes with the same 3 documents and the same two segments, [0, 1] and [2]. First index:
t=newon doc 0 only. Second index:t=oldon all 3 documents. - Open
new ParallelCompositeReader(first, second)and searcht:old. You expect no hits: the javadoc says matches come from "the first index added that has the field", and the first index hastbut not=old. - You get doc 2, but not doc 1, although docs 1 and 2 are identical in both indexes. No error, with assertions on or off.
- Why: the reader builds one
ParallelLeafReaderper segment, and each picks the first index whose segment has the field. Segment [2] of the first index has no document witht, so there the second index ownst. - Merge both indexes to one segment (
forceMerge(1)) and the same search returns no hits. Doc values follow the same rule:FieldExistsQueryon a shared doc-values field gives [0, 2] instead of [0].
Applications that use the expert ParallelCompositeReader with a field that two of the parallel indexes share, such as a field re-indexed in a second index, when a segment of the earlier index lacks that field. Codec-independent by code reading; three documents suffice. Hits and counts are silently wrong and change as segments merge.
Mechanism, terms and numbers581 words
ParallelCompositeReader documents that "matches for a query term are from the first index added that has the field" (ParallelCompositeReader.java:29-30 at e1faeba08bde). But prepareLeafReaders builds one ParallelLeafReader per segment position from that position's leaves only (:119-137), and ParallelLeafReader gives each field to the first sub-reader whose own leaf FieldInfos contain it (ParallelLeafReader.java:154-171). In a segment of the first index with no FieldInfo for the field (in the example, no document of that segment has it), the second index serves the field. With two 3-document indexes whose segments are [0, 1] and [2], the first having t=new on doc 0 only and the second t=old everywhere, t:old returns [2] instead of []; identical docs 1 and 2 answer differently, and after forceMerge(1) of both indexes the answer is []. Doc values behave the same (executed); norms, points and vectors use the same owner map. Wrong since 4.0 (LUCENE-3736, 2012); the 3.x ParallelReader chose owners per index and gives [].
ParallelCompositeReader: "An CompositeReader which reads multiple, parallel indexes. Each index added must have the same number of documents, and exactly the same number of leaves (with equal maxDoc), but typically each contains different fields. Deletions are taken from the first reader. Each document contains the union of the fields of all documents with the same document number. When searching, matches for a query term are from the first index added that has the field." (ParallelCompositeReader.java:26-30). Its use case: "The smaller fields may be re-indexed in a new index and both indexes may be searched together." (:32-34).ParallelLeafReader: the same reader for single segments, with the same precedence sentence (ParallelLeafReader.java:38-40).FieldInfos: per segment: the fields of the documents written to that segment (documents deleted later and doc-values updates included). A field that no document written to a segment had is not in that segment'sFieldInfos.
prepareLeafReaderschecks that all readers have the same leaf count and leafmaxDoc(ParallelCompositeReader.java:105-115,validateat:142-162), then, for each leaf positioni, buildsnew ParallelLeafReader(true, subs, storedSubs)fromreaders[j].leaves().get(i).reader()only (:119-137).ParallelLeafReader's constructor walks its sub-readers in order and, for eachFieldInfoof that sub-reader's owngetFieldInfos(), records it infieldToReaderandtermsFieldToReaderunless an earlier sub-reader already has it:// NOTE: first reader having a given field "wins":(ParallelLeafReader.java:154-171).- Segment [2] of the first index (doc 2, no
t) has noFieldInfofort, so at position 2 the second index winst. At position 0 the first index (doc 0 hast=new) wins. terms("t")readstermsFieldToReader(ParallelLeafReader.java:258-262):t:oldfinds doc 2 in segment [2] and nothing in segment [0, 1]. Doc values, norms, points and vectors readfieldToReader(:396-503), the same per-segment choice.- After
forceMerge(1)of both indexes there is one segment, the first index's segment hast, andt:oldmatches nothing.
3 documents per index, segments [0, 1] and [2], first index t=new on doc 0, second index t=old on docs 0-2: t:old returns [2] (expected []); t:new returns [0]. After forceMerge(1) of both: t:old returns [], t:new [0] (main, 10.6.0, 9.12.3 and 9.0.0). Doc-values probe, same layout with NumericDocValuesField("n") (n=1 on doc 0 of the first index, n=9 on every document of the second): FieldExistsQuery("n") returns [0, 2] instead of [0], n == 9 returns [2] instead of [].
Exposure and likelihood441 words
- Who. Users of
ParallelCompositeReader(an expert, rarely used class) whose parallel indexes share a field: the overlap the javadoc's precedence rule is written for. The class javadoc's own use case is re-indexing frequently changing fields in a second index (ParallelCompositeReader.java:32-34); a field kept in both, or re-indexed only for some documents, has this shape. Overlap probably occurs in practice: a 2016 java-user post ("Faceted Search with Parallel Indexes", unanswered) used aParallelCompositeReaderover two indexes with taxonomy facets and got facet results only from whichever index came first. That both indexes carried the same facet field (taxonomy facets share a default$facetsfield) is an inference; the post shows no schema. What they describe matches the documented first-index rule, not this bug. - When. Some segment of an earlier index has no
FieldInfofor the shared field (no document written to it had the field) while a later index has the field in the same segment. Small segments and sparsely set fields make this more likely (no frequency data), and it changes as segments flush and merge. - Effect. Silent extra hits and wrong counts on the shared field; in a
MUST_NOTclause the same extra matches remove documents instead (code reading, not run). Two documents with identical data in every index answer differently depending on their segment, and an ordinary merge changes the answer ([2] before, [] afterforceMerge(1)of both indexes). Executed forTermQuery,FieldExistsQueryand aBooleanQueryon a text field and, for this doc, forFieldExistsQueryand an exact doc-values query on a numeric doc-values field ([0, 2] instead of [0], [2] instead of []). Norms, points and vectors use the same owner map (code reading, not run). - Default vs opt-in. Opt-in: Lucene never builds a
ParallelCompositeReaderover two different indexes by itself (the test framework'swrapReaderbuilds aParallelCompositeReaderover one reader only, or aParallelLeafReaderover two field-disjoint halves of the same leaf; in neither does a field occur twice). Codec-independent by code reading: the gradle runs usedAsserting(Lucene104), and the fact-check runs failed the same way with 4 more seeds, underCheapBastardand a compressing stored-fields codec as well. The repro uses the defaultIndexWriterConfigplusNoMergePolicyonly to pin the segment boundaries; the merge probe (the sametvalues plus a storedidfield) usedLogDocMergePolicy, the policy the class javadoc recommends (:39-41), with the same result. - Scale and likelihood. Three documents. The first signal was 6 of 3,720 checks of a randomized sweep, all with a later index re-using a field. No public report of it was found since 4.0 (2012), so likelihood rare and priority Low.
One JUnit test method on the public API: two 3-document indexes with the same two segments, one ParallelCompositeReader, one TermQuery. Deterministic, single-threaded; it fails with assertions on and off.
package org.apache.lucene.index;

import java.util.Arrays;
import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestParallelCompositeReaderFieldOwner extends LuceneTestCase {

  private static Directory index(String... tValues) throws Exception {
    Directory dir = newDirectory();
    try (IndexWriter w =
        new IndexWriter(dir, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
      for (int i = 0; i < tValues.length; i++) {
        Document doc = new Document();
        if (tValues[i] != null) {
          doc.add(new StringField("t", tValues[i], Field.Store.NO));
        }
        w.addDocument(doc);
        if (i == 1) {
          w.commit();
        }
      }
    }
    return dir;
  }

  public void testFirstIndexOwnsSharedField() throws Exception {
    try (Directory first = index("new", null, null);
        Directory second = index("old", "old", "old");
        ParallelCompositeReader reader =
            new ParallelCompositeReader(DirectoryReader.open(first), DirectoryReader.open(second))) {
      List<Integer> hits =
          Arrays.stream(new IndexSearcher(reader).search(new TermQuery(new Term("t", "old")), 10).scoreDocs)
              .map(sd -> sd.doc)
              .toList();
      // expected: no hits (the first index owns "t"); actual: [2], the second index's "t" leaks into segment [2]
      assertEquals(List.of(), hits);
    }
  }
}
cp $REPRO/TestParallelCompositeReaderFieldOwner.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestParallelCompositeReaderFieldOwner -Ptests.seed=DEADBEEF
# also with -Ptests.asserts=false: same failure
- Expected
- No hits: the first index owns
tand has not=old. - Observed
java.lang.AssertionError: expected:<[]> but was:<[2]>: doc 2 matches, the identical doc 1 does not.
More files, environment, full output285 words
TestParallelCompositeReaderFieldOwner (one method, extends LuceneTestCase, package org.apache.lucene.index of the lucene/core tests). Each index is written with new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE) and a commit() after doc 1, which pins the segments to [0, 1] and [2] in both. The first index has StringField("t", "new") on doc 0 only; the second has StringField("t", "old") on every document. The reader is new ParallelCompositeReader(DirectoryReader.open(first), DirectoryReader.open(second)).
./gradlew tidy re-wraps three long lines of the file (the ParallelCompositeReader construction, the Arrays.stream chain and the comment; formatting only). The file has no Apache license header. Deterministic for its input; the recorded runs used seed DEADBEEF (codec Asserting(Lucene104)), and 4 more seeds failed the same way. As a regression test the same method fits in TestParallelCompositeReader. The merge dependence ([2] before, [] after forceMerge(1) of both indexes) is shown by the merge probe, not by this test.
| lucene | main e1faeba08bde (12.0.0-SNAPSHOT), 10.6.0, 10.5.2, 9.12.3: fail; 3.6.2 (ParallelReader port): passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestParallelCompositeReaderFieldOwner.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestParallelCompositeReaderFieldOwner -Ptests.seed=DEADBEEF
# gradle, scratch worktree at e1faeba08bde, -Ptests.seed=DEADBEEF (same with -Ptests.asserts=false)
TestParallelCompositeReaderFieldOwner > testFirstIndexOwnsSharedField FAILED
    java.lang.AssertionError: expected:<[]> but was:<[2]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:FDB92538CC60A78]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:120)
        at org.junit.Assert.assertEquals(Assert.java:146)
        at org.apache.lucene.index.TestParallelCompositeReaderFieldOwner.testFirstIndexOwnsSharedField(TestParallelCompositeReaderFieldOwner.java:43)
:lucene:core:test (FAILURE): 1 test, 1  failure

# same test, standalone JUnit runner on the main jars: -ea and -da FAIL, expected:<[]> but was:<[2]>
# with the recommended fix: PASS, asserts on and off

# evidence probe (plain main; same t values plus a stored id field; LogDocMergePolicy), main / 10.6.0 / 9.12.3 / 9.0.0, -da:
segments=2 t:old -> [2] t:new -> [0]
segments=1 t:old -> [] t:new -> [0] # after forceMerge(1) of both indexes- The javadoc rule is per index: matches come from "the first index added that has the field".
- Per index the answer is []; per document [1, 2] (plain union: [0, 1, 2]). Only a per-segment reading gives [2], splitting identical docs 1 and 2.
- The 3.x
ParallelReader, whose sentence the class kept, gives []; a merge turns [2] into [].
The full argument400 words
- Contract. "Each index added must have the same number of documents, and exactly the same number of leaves ... When searching, matches for a query term are from the first index added that has the field." (
ParallelCompositeReader.java:26-30). In the same paragraph "index added" is the composite argument, not a leaf. - The warning does not apply. "Undefined behavior" is promised only when the indexes are not "created and modified the same way" (
:36-44). Here both have the same documents in the same order and the same segment boundaries (the constructor checks the leaf count and each leaf'smaxDoc,:142-162). - No per-index or per-document reading gives the observed answer. Per index (the javadoc): []. Per document ("the union of the fields of all documents with the same document number"): [1, 2] if the first index wins in each document, or [0, 1, 2] if both indexes' values were unioned. Only a per-segment reading gives [2], the code's answer, and it treats identical documents 1 and 2 differently.
- Overlap is supported input. Both Parallel* javadocs define the overlap case (
ParallelLeafReader.java:38-40), and an upstream test relies on it: "important that parallelReader is first, so if there are field name overlaps, because changes to the schema overwrote existing field names, it wins" (TestDemoParallelLeafReader.java:178-180). LUCENE-606 (#1684) describes the 3.x overlap behaviour: a term search "only yields results if that term was contained in the first matching IndexReader which contained the field". - History. Before 4.0,
ParallelReadertook owners from the mergedFieldInfosof the whole index; 3.6.2 gives [] for this scenario (an API-adapted port). LUCENE-3736 (6188bc66d7d, 2012) made the new composite variant work per leaf for performance ("as it works on the atomic subreaders") and kept the 3.x sentence; its CHANGES entry offersSlowCompositeReaderWrapper+ParallelAtomicReaderas the alternative (CHANGES.txt:15675-15681), which still chose owners per index (a 4.0.0 control gives []). Comments of 2012-02-21 on LUCENE-3736 by Uwe Schindler and Robert Muir discuss how the field maps are built ("The fieldInfos and fieldToReaderMap is now only used for retrieving stored fields and other global information."), but none of its 45 comments and nothing in LUCENE-6501 ("a flat structure of ParallelLeafReaders",CHANGES.txt:10577-10584) discusses a field present in more than one index, or a segment of the earlier index without the field. - Tests.
TestParallelCompositeReaderuses disjoint fields; no upstream test asserts per-segment ownership.
The devil's-advocate check188 words
The strongest case for "intended": field presence is a per-segment property; ParallelLeafReader's rule is defined over leaf FieldInfos; the per-leaf construction is as old as the class, and LUCENE-6501 calls the result "a flat structure of ParallelLeafReaders"; and in 2011 Shai Erera closed LUCENE-606 with "the general concept behind ParallelReader is that fields do not exist in more than 1 sub-reader". So overlapping fields could be called unsupported, with per-leaf precedence as a consequence.
Why it fails: that remark was about 3.x stored fields, in a reader that chose owners per index. The current javadocs of both classes define the overlap case and an upstream test depends on it. The class javadoc states the rule per "index added". A per-leaf reading does give [2], and it is how the code is built; but under it the answer for identical documents depends on a segment boundary and changes after a merge that keeps every document and value, which no javadoc states. The case for "intended" is not empty (an independent reviewer rated it moderate), so a maintainer may choose to document per-segment precedence instead (fix option C).
Recommended Decide the owner once per index and pass it to every per-segment reader (built; validated by the recorded tests)
Decide each field's owner once per index (the first index that has the field in any segment) and let every per-segment reader skip the field in the other indexes. +37/-2 lines in two files; tested with gradle: the repro passes, and so do 1,398 index and 2,350 search tests.
// ParallelCompositeReader.prepareLeafReaders: owner = first index with the field in any leaf
final Map<String, Integer> fieldOwners = new HashMap<>();
for (int j = 0; j < readers.length; j++) {
  for (LeafReaderContext ctx : readers[j].leaves()) {
    for (FieldInfo fieldInfo : ctx.reader().getFieldInfos()) {
      fieldOwners.putIfAbsent(fieldInfo.name, j);
    }
  }
}
// ... new ParallelLeafReader(true, subs, storedSubs, fieldOwners) { ... }

// ParallelLeafReader, FieldInfos loop over sub-reader i (fieldOwners is null for public use):
Integer owner = fieldOwners == null ? null : fieldOwners.get(fieldInfo.name);
if (owner != null && owner != i) continue;
All options and trade-offs3 options · 626 words
Three options; the first was built and tested, the other two were not. The choice is the maintainers'.
Decide the owner once per index and pass it to every per-segment reader (built; validated by the recorded tests) (recommended)
In prepareLeafReaders, map each field name to the first top-level reader that has it in any leaf, and pass the map to every per-leaf ParallelLeafReader through a new package-private constructor (the public constructors delegate with null). In its FieldInfos loop, a sub-reader skips a field whose owner is another index. Where the owning index has no FieldInfo for the field in a segment, the field is simply absent there, as with the 3.x reader. The full diff has 91 lines; its core is shown below.
// ParallelCompositeReader.prepareLeafReaders: owner = first index with the field in any leaf
final Map<String, Integer> fieldOwners = new HashMap<>();
for (int j = 0; j < readers.length; j++) {
  for (LeafReaderContext ctx : readers[j].leaves()) {
    for (FieldInfo fieldInfo : ctx.reader().getFieldInfos()) {
      fieldOwners.putIfAbsent(fieldInfo.name, j);
    }
  }
}
// ... new ParallelLeafReader(true, subs, storedSubs, fieldOwners) { ... }

// ParallelLeafReader, FieldInfos loop over sub-reader i (fieldOwners is null for public use):
Integer owner = fieldOwners == null ? null : fieldOwners.get(fieldInfo.name);
if (owner != null && owner != i) continue;
Trade-offs
- One extra pass over the
FieldInfosof every leaf of every reader when the reader is built, O(leaves x fields); no per-query cost. - Behaviour change for users who got the later index's values in sparse segments: they now get the per-index rule the javadoc states. It changes per-leaf metadata too, not only query routing: in such a leaf,
getFieldInfos()no longer lists the later index'sFieldInfofor the field (index options, doc-values type, points, vectors), so the field is absent there. Soft-deletes and parent field names still come from all sub-readers (ParallelLeafReader.java:110-124). Fields whose schema differs between the indexes were not tested; this part needs maintainer review. - Stored fields (taken from all
storedFieldsReaders), the by-document term-vector lookup (termVectors()loops over the sub-readers directly and never readstvFieldToReader,ParallelLeafReader.java:326-375) and the index-sort metadata are untouched;ParallelLeafReader's public behaviour is unchanged.
What the checks validated
- Gradle in a scratch worktree at
e1faeba08bde, JDK 25,-Ptests.seed=DEADBEEF(2026-11-02): the repro fails without the fix and passes with it, assertions on and off. - With the fix:
TestParallelCompositeReader,TestParallelLeafReader,TestParallelReaderEmptyIndex,TestParallelTermEnum,TestDemoParallelLeafReaderand the repro pass (30 tests); all oforg.apache.lucene.index.*(1,398 tests, 56 skipped) andorg.apache.lucene.search.*(2,350 tests, 49 skipped) pass with 0 failures (these two package runs used the same diff before one comment line was shortened for formatting);checkGoogleJavaFormatis clean for the two changed files. - The doc-values evidence probe gives [0] and [] with the fix (stock main: [0, 2] and [2]).
Decide owners as above, then wrap each later sub-leaf in a FilterLeafReader that drops the fields owned by an earlier index. This was the hunt's first fix idea.
Trade-offs
No change to ParallelLeafReader, but core has no field-filtering leaf reader (the test framework's FieldFilterLeafReader is not in core), and the wrapper must hide the field from getFieldInfos and every per-field accessor, so it is more code and easier to break when accessors are added.
Say in the javadoc that for a field in several indexes the owner is chosen per segment, so results can depend on segment boundaries and merges.
Trade-offs
Cheapest and no behaviour change, but it documents an inconsistency (identical documents answering differently, answers that change after a merge) instead of removing it, and it departs from the 3.x behaviour the javadoc sentence came from.
Downstream, a filter on a field that the first index is meant to override would also match the later index's values in segments where the first index lacks that field.
A randomized comparison of parallel readers with one freshly built index holding the same visible fields: 6 of 3,720 checks failed, all where a later index re-uses a field, all on the same field. Reading the reader's construction gave the mechanism, and the case was reduced to three documents.
The method in full163 words
Method: non-formal (a seeded metamorphic differential; no model checker or proof).
- Sweep. A harness built field-split sub-indexes from random documents (60 seeds, 120 legs), opened them as a
ParallelLeafReaderor aParallelCompositeReader, and compared every query result with one index built from the union of the visible fields: 3,720 checks per assertion mode on the stock main jars. - Signal. 6 checks failed with
-eaand with-da, allParallelCompositeReaderlegs whose last sub-index re-uses fields, all on the text fieldt(TermQuery,FieldExistsQueryand aBooleanQuery, one extra hit each).ParallelLeafReaderlegs and composite legs without a shadowing index were clean. - Mechanism and reduction. Reading
prepareLeafReadersshowed the per-segment owner choice; the case was reduced to two 3-document indexes and one JUnit test, and a merge probe showed the answer change afterforceMerge(1). - An earlier model of parallel field ownership in the hunt looked at a single segment only, so it never compared per-segment with per-index ownership.
No prior report found (2026-11-02): about 60 GitHub issue and PR queries including the JIRA archive, the mailing lists, downstream trackers and the web. Nearest items are background only: LUCENE-3736, LUCENE-6501 and LUCENE-606.
Searches5 searches
Background, not reports: #4810 (LUCENE-3736, 2012, introduced the per-leaf construction; its 45 comments never discuss a field present in two indexes); #3840 (LUCENE-2766, the per-segment proposal); #7560 (LUCENE-6501, 2015, flattened the structure); #1684 (LUCENE-606, 2011, stored fields of overlapping fields, closed as not a bug with the "fields do not exist in more than 1 sub-reader" remark); #1639 (LUCENE-561, 2006, fixed in 2.0.0: a ParallelReader NPE on a field no document had yet). Open PR #16847 touches both files but only adapts the doc-count API (maxLeafDoc/numLeafDocs, a long maxDoc); nothing in it is about field ownership. Limits: keyword search; a report worded without these class names could be missed; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, including the migrated JIRA archive) | 2026-11-02 | about 60 queries: ParallelCompositeReader, ParallelLeafReader, ParallelAtomicReader, ParallelReader, prepareLeafReaders, fieldToReader, termsFieldToReader, and symptom phrasings (overlap, same field, first reader, segment, merge results differ, wrong hits); comments read on 23 items | no report; background items only |
| Open and recent PRs; commits | 2026-11-02 | the changed files of every PR updated since 2026-10-31 (28); the commits API for both files; upstream main head | #16847 only adapts the doc-count API (maxLeafDoc/numLeafDocs, a long maxDoc), nothing about field ownership; no later change to either file |
| JIRA archive and mailing lists | 2026-11-02 | 4 JIRA text queries; dev@, java-user@, issues@ and commits@ (20 queries, 5 threads read in full) | no report; a 2016 java-user post shows a facet field shared by two parallel indexes (the documented rule, not this bug) |
| Downstream trackers and the web | 2026-11-02 | Elasticsearch, OpenSearch, Solr, Lucene.NET; one GitHub-wide search; 7 web queries | test-framework wrapping issues and unrelated questions only |
| Re-check | 2026-11-02, three times | both class names updated since 2026-11-01; "parallel reader" field segment; "ParallelCompositeReader" "first index"; the PRs created on 2026-11-02; in the last one, issues and PRs mentioning ParallelCompositeReader or ParallelLeafReader sorted by last update, the commits of both files and upstream main head aa2de9a025b3 | nothing new |
Introduced in 4.0 by LUCENE-3736 (6188bc66d7d, 2012), which split the 3.x ParallelReader and built the new composite reader segment by segment. Fails on every release tried from 4.0.0-ALPHA to 10.6.0 and on main; 3.6.2 gives the expected answer. Not fixed upstream.
Versions tested8 rows
Introduced by 6188bc66d7d (2012-02-10, Uwe Schindler), LUCENE-3736 "ParallelReader was split into ParallelAtomicReader and ParallelCompositeReader" (migrated as #4810; from Subversion r1242924, no PR). The per-leaf loop (ParallelCompositeReader.java:119-137) and the owner rule (ParallelLeafReader.java:154-159) originate in it: that commit already built one reader per aligned sub-reader and had the first-reader-wins rule. Later commits reshaped those lines and kept the per-leaf construction: for the owner rule 208e9626d4b (:155) and fc75babcacc (:157, the containsKey check), both February 2012 LUCENE-3736 follow-ups, and 77ea2110965 (LUCENE-8045, 2017, :158); for the loop LUCENE-4953 (60151ce379a), LUCENE-5569 (85bf3181737) and LUCENE-6501 (4c6300f105a, backport 376c8fc7d9c, 5.3.0); the 2020 reformat (2d6ad2fee6d) re-wrapped both. Not a regression.
Not fixed upstream: the last commit to ParallelCompositeReader.java is 48715fe898b (2021); the last to ParallelLeafReader.java is bfe5c847d3c (2026-07-27), already in e1faeba08bde; upstream main head aa2de9a025b3 (2026-11-02, checked) has no later change to either file. Releases between the ones run were not run; that they are affected is inferred from the unchanged code.
| Version or commit | Verdict | Result |
|---|---|---|
main e1faeba08bde (12.0.0-SNAPSHOT) | affected | fails: gradle and the standalone runner, assertions on and off, [2] instead of [] |
| 10.6.0, 10.5.2, 9.12.3 | affected | the JUnit test (or an equivalent) fails the same way |
| 9.0.0, 8.11.4, 7.7.3, 6.6.6, 5.5.5 | affected | API-adapted port of the scenario fails, [2] |
| 5.0.0, 5.1.0, 5.2.0 | before LUCENE-6501 | port fails, [2] |
| 4.0.0-ALPHA, 4.0.0, 4.10.4 | affected | port fails, [2] (4.0.0-ALPHA is the first affected release) |
| 4.0.0, ParallelAtomicReader over SlowCompositeReaderWrapper | control | passes, [] (the alternative named in the LUCENE-3736 CHANGES entry) |
| 3.6.2 ParallelReader | not affected | passes, [] (an API-adapted port; owners chosen per index) |
| main + recommended fix | not affected | passes; index and search test packages pass |
An independent reproducer, executing reviews from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate, an adjudication and a credibility audit all confirmed it; this doc adds gradle runs with and without the fix and a doc-values probe.
Checks and verdicts474 words
This doc adds gradle runs of the one-method test in a scratch worktree at e1faeba08bde, without and with the recommended fix (plus the org.apache.lucene.index.* and org.apache.lucene.search.* tests with the fix), and a doc-values evidence probe on main without and with the fix.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | 6 of 3,720 sweep checks fail (-ea and -da), all on a field re-used by a later index; the JUnit fails on main, 10.6.0 and 9.12.3; merge probe [2] -> []. |
| cross-model review | real, 0.98 | OpenAI GPT-5.6, executing: ran the JUnit and the merge probe; judged the per-leaf reading of "first index" untenable and unable to justify merge-dependent answers. |
| Independent reproducer | real | Own test fails on main (-ea, -da), 10.6.0, 10.5.2 and 9.12.3; probe: leaf 0 of the first index has t, leaf 2 not; [2] becomes [] after the merge. |
| Cross-model adversary, refute lens | real, high | OpenAI GPT-5.6, executing: own 4-document test gives [2, 3] instead of []; its nearest control (the first index has the field in both segments) passes; merge leg [2, 3] -> []; re-run on e1faeba08bde and 10.6.0 fails. |
| Intended-behaviour devil's advocate | real | Per-leaf design, per-segment FieldInfos, the LUCENE-606 remark and the disjoint-field tests examined and rejected; re-ran the repro on main (-ea, -da: fails). |
| adjudication | confirmed, high, Low | Re-ran the independent reproduction's test (-ea, -da) and the finder's test on main: fail. Related findings LFV-981, LFV-018, LFV-652 and LFV-743 have other fix sites. |
| credibility audit and final repro check | confirmed | The one-test repro fails on main -ea and -da; the audit re-ran the finder's test with -da and confirmed it, priority Low. |
| this doc | real as described | Gradle: fails without the fix (asserts on and off), passes with it; with the fix 1,398 index and 2,350 search tests pass; doc-values probe [0, 2] -> [0] and [2] -> []. |
| Fact checks and diagram check of this doc | bug holds; wording corrected | An independent fact check re-ran the doc's gradle command on a clean copy of e1faeba08bde (fails with assertions on and off, passes with the fix), the repro at 5 seeds and on 10.6.0, 10.5.2 and 9.12.3, the fix with the 5 Parallel* test classes, the doc-values probe and the merge probe, and found six wording errors. A cross-model fact check (OpenAI GPT-5.6) re-read the citations and the recorded logs, found the bug real and the repro and merge dependence well supported, and listed overstatements (the union reading, "no reading gives [2]", the field-presence condition, "any codec"). A diagram check found one false caption, a stale fix status and one loose wording; the visuals were re-rendered. The errors are fixed in this doc; two findings were rejected with reasons. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 522 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,433 words
- Registry title
- ParallelCompositeReader picks a field's owner separately in each segment, so when two parallel indexes share a field, the later index's values show through in segments where the earlier index has no document with that field, and hits change after a merge
- Area
- core / index (ParallelCompositeReader.prepareLeafReaders: per-leaf field ownership through ParallelLeafReader's 'first reader having a given field wins' rule)
- Priority
- Low, rank 289: Since 4.0, the expert ParallelCompositeReader silently uses a later index's values of a shared field in every segment where the earlier index has no document with that field, so queries get extra hits that change after a merge. It needs the same field in two parallel indexes plus a segment without it, a rare layout, so it is Low.
- Impact class
- silent wrong results
- Impact note
- Applications that open the expert ParallelCompositeReader over parallel indexes that share a field (the overlap that the javadoc's rule 'matches for a query term are from the first index added that has the field' is there for, for example a sidecar index that re-indexes a field for some documents) get the later index's values of that field in every segment where the earlier index has no document with the field, so queries on it return extra hits and wrong counts with no error, and the answers change after an ordinary merge of both indexes; codec-independent by code reading (the three codecs run all fail), three documents suffice, the same with -ea and -da, every release from 4.0.0 through 10.6.0 and main.
- Summary
- You open a ParallelCompositeReader over two indexes that hold the same 3 documents in the same two segments ([0, 1] and [2]); the first index has field t only on doc 0 (t=new), the second has t=old on every document, and you search t:old. You expect no hits, because the javadoc says matches come from the first index added that has the field (and docs 1 and 2 are identical in both indexes, so they must at least be treated alike). You get doc 2 but not doc 1, with no error: the reader chooses each field's owner separately in every segment, and segment [2] of the first index has no document with t, so the second index's t shows through there; after forceMerge(1) of both indexes the same search returns nothing.
- Introduced
- 6188bc66d7d00511cb5fc9a0ee76c25d76aec73a ('LUCENE-3736: ParallelReader was split into ParallelAtomicReader and ParallelCompositeReader', issue LUCENE-3736, migrated as apache/lucene#4810; Subversion r1242924, no PR): the new composite reader builds one ParallelAtomicReader (today ParallelLeafReader) per aligned leaf from that leaf's own FieldInfos, so the first-reader-wins owner rule became per segment while the class javadoc kept the 3.x per-index sentence [read: git blame of the per-leaf loop ParallelCompositeReader.java:119-137 and of the owner rule ParallelLeafReader.java:154-159 on main; exec: 3.6.2 ParallelReader passes, 4.0.0-ALPHA fails]. Later changes kept the per-leaf construction (LUCENE-4953 60151ce379a, LUCENE-5569 85bf3181737, LUCENE-6501 4c6300f105a / 376c8fc7d9c, reformat 2d6ad2fee6d). Not a regression: wrong since the class was added (2012-02-10 (author date = commit date of 6188bc66d7d))
- First affected version
- 4.0.0-ALPHA (first GA release 4.0.0) [exec: an API-adapted port of the repro fails on 4.0.0-ALPHA and 4.0.0; the 3.x ParallelReader passes on 3.6.2, and on 4.0.0 the LUCENE-3736 CHANGES alternative, ParallelAtomicReader over SlowCompositeReaderWrapper, passes]
- Affected versions
- every release from 4.0.0-ALPHA through 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main e1faeba08bde (12.0.0-SNAPSHOT). Executed, all failing the same way (t:old -> [2] instead of []): the JUnit repro on main (-ea and -da), 10.6.0, 10.5.2 and 9.12.3; API-adapted ports on 4.0.0-ALPHA, 4.0.0, 4.10.4, 5.0.0, 5.1.0, 5.2.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 10.6.0 and main [exec]; the releases in between by code identity (the per-leaf construction never changed) [read]. Not affected: the 3.x line (no ParallelCompositeReader; 3.6.2 ParallelReader gives []) [exec]. Not new in 10.6 (10.5.2 fails). Not fixed upstream: no commit touches ParallelCompositeReader.java after 48715fe898b (author date 2021-03-26), the last ParallelLeafReader.java commit is bfe5c847d3c (author date 2026-07-27, already in e1faeba08bde), and upstream main head 5adff78bb168 (2026-11-02) has no later change to either file [read through the GitHub API, 2026-11-02]. Executed on Linux aarch64 with JDK 25.0.3 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by exhaustive check, code reading
- Upstream and prior reports
- none found (2026-11-02, on top of the finder's search (a scripted prior-report search of 51 queries, 16 manual GitHub queries and 3 web queries), the intended-behaviour check's 22 queries and the adjudication's check; rechecked the same day): about 60 apache/lucene issue and PR queries (ParallelCompositeReader, ParallelLeafReader, ParallelAtomicReader, ParallelReader, prepareLeafReaders, fieldToReader, termsFieldToReader and symptom phrasings), comments read on 23 items, the changed files of every apache/lucene PR updated since 2026-10-31 (28), the commits API for both files, 4 LUCENE JIRA queries, the dev@, java-user@, issues@ and commits@ lists (5 threads read in full), Elasticsearch, OpenSearch, Solr and lucenenet, one GitHub-wide search and 7 web queries: no report of per-segment field ownership in ParallelCompositeReader, of a later index showing through in a segment where the earlier index lacks the field, or of hits that change after a merge. The only open PR that touches both files, #16847 (long global doc ids), only renames maxDoc()/numDocs() there and leaves field ownership unchanged. A same-day recheck of GitHub searches found nothing new: ParallelCompositeReader and ParallelLeafReader updated since 2026-11-01 (0 hits each), "parallel reader" field segment (13 hits, none relevant; #11685 / LUCENE-10649 and its PR #1025 are a test merge-policy fix in TestDemoParallelLeafReader) and "ParallelCompositeReader" "first index" (only #4810); the 4 PRs created on 2026-11-02 (#16962-#16965) touch no Parallel* file. Background, not reports: #4810 (LUCENE-3736, introduced the per-leaf construction), #3840 (LUCENE-2766, the per-segment proposal), #7560 (LUCENE-6501, flattened it), #1684 (LUCENE-606, 2011, stored fields of overlapping fields, closed with the remark that fields do not exist in more than one sub-reader), #1639 (LUCENE-561, 2006, a 3.x NPE on a field no document had yet).
- Lucene commit tested
- the one-method test on main
e1faeba08bde: gradle in a scratch worktree at that commit with-Ptests.asserts=trueandfalse, without the fix (fails) and with it (passes; with the fix also allorg.apache.lucene.index.*andorg.apache.lucene.search.*tests oflucene/core), and the standalone JUnit runner with-eaand-da; the same test or an equivalent on 10.6.0, 10.5.2 and 9.12.3 (fail); API-adapted ports of the scenario on 4.0.0-ALPHA through 9.0.0 (fail) and 3.6.2 (passes); a doc-values evidence probe on main without and with the fix.
- Finding record
lucene/core/src/java/org/apache/lucene/index/ParallelCompositeReader.java:25-30 (at e1faeba08bde) (class javadoc: same number of documents and leaves, 'typically each contains different fields', 'Each document contains the union of the fields of all documents with the same document number. When searching, matches for a query term are from the first index added that has the field.'), :36-44 (Warning: undefined behaviour only if the indexes are not created and modified the same way), :115-140 (prepareLeafReaders: one ParallelLeafReader per aligned leaf from that leaf's sub-readers only; fix site)lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:38-40 (at e1faeba08bde) (same precedence sentence), :154-171 ('first reader having a given field "wins"': fieldToReader and termsFieldToReader filled from each sub-leaf's own FieldInfos)lucene/core/src/test/org/apache/lucene/index/TestDemoParallelLeafReader.java:178-180 (at e1faeba08bde) ('important that parallelReader is first, so if there are field name overlaps ... it wins': upstream relies on overlapping fields)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/ParallelCompositeReader.java:26-30, (at e1faeba08bde) :32-34 (class javadoc), :105-115, :119-137 (prepareLeafReaders per-leaf loop), :142-162 (validate)lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:38-40 (at e1faeba08bde) (precedence sentence), :154-171 (first reader wins from each leaf's FieldInfos), :258-262 (terms), :396-503 (per-field accessors through fieldToReader)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/ParallelCompositeReader.java:32-34 (at e1faeba08bde) (use case), :39-41 (LogDocMergePolicy advice)lucene/test-framework/src/java/org/apache/lucene/tests/util/LuceneTestCaseParent.java:2368-2405 (at e1faeba08bde) (wrapReader: a ParallelCompositeReader over one reader, or a ParallelLeafReader over two field-disjoint FieldFilterLeafReader halves of one leaf)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/ParallelCompositeReader.java:26-30, (at e1faeba08bde) :36-44, :142-162lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:38-40 (at e1faeba08bde)lucene/core/src/test/org/apache/lucene/index/TestDemoParallelLeafReader.java:178-180 (at e1faeba08bde)lucene/core/src/test/org/apache/lucene/index/TestParallelCompositeReader.java:76-87 (at e1faeba08bde) (disjoint fields f1-f4)lucene/CHANGES.txt:15675-15681 (at e1faeba08bde) (LUCENE-3736), :10577-10584 (LUCENE-6501)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:326-374 (at e1faeba08bde) (termVectors() does not use the owner maps), :276-298 (stored fields from storedFieldsReaders)lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:110-124 (at e1faeba08bde) (soft-deletes and parent field from all sub-readers), :154-171 (the loop the fix changes)
- TestParallelCompositeReaderFieldOwner.java (lucene/core, package org.apache.lucene.index, 1 test):
repro/LFV-1114/TestParallelCompositeReaderFieldOwner.java(46 lines)
The diagram shows the repro's scenario; an independent diagram check compared every frame with the code at e1faeba08bde and the executed runs.
assets/LFV-1114/bug.png(522 KB)