- With
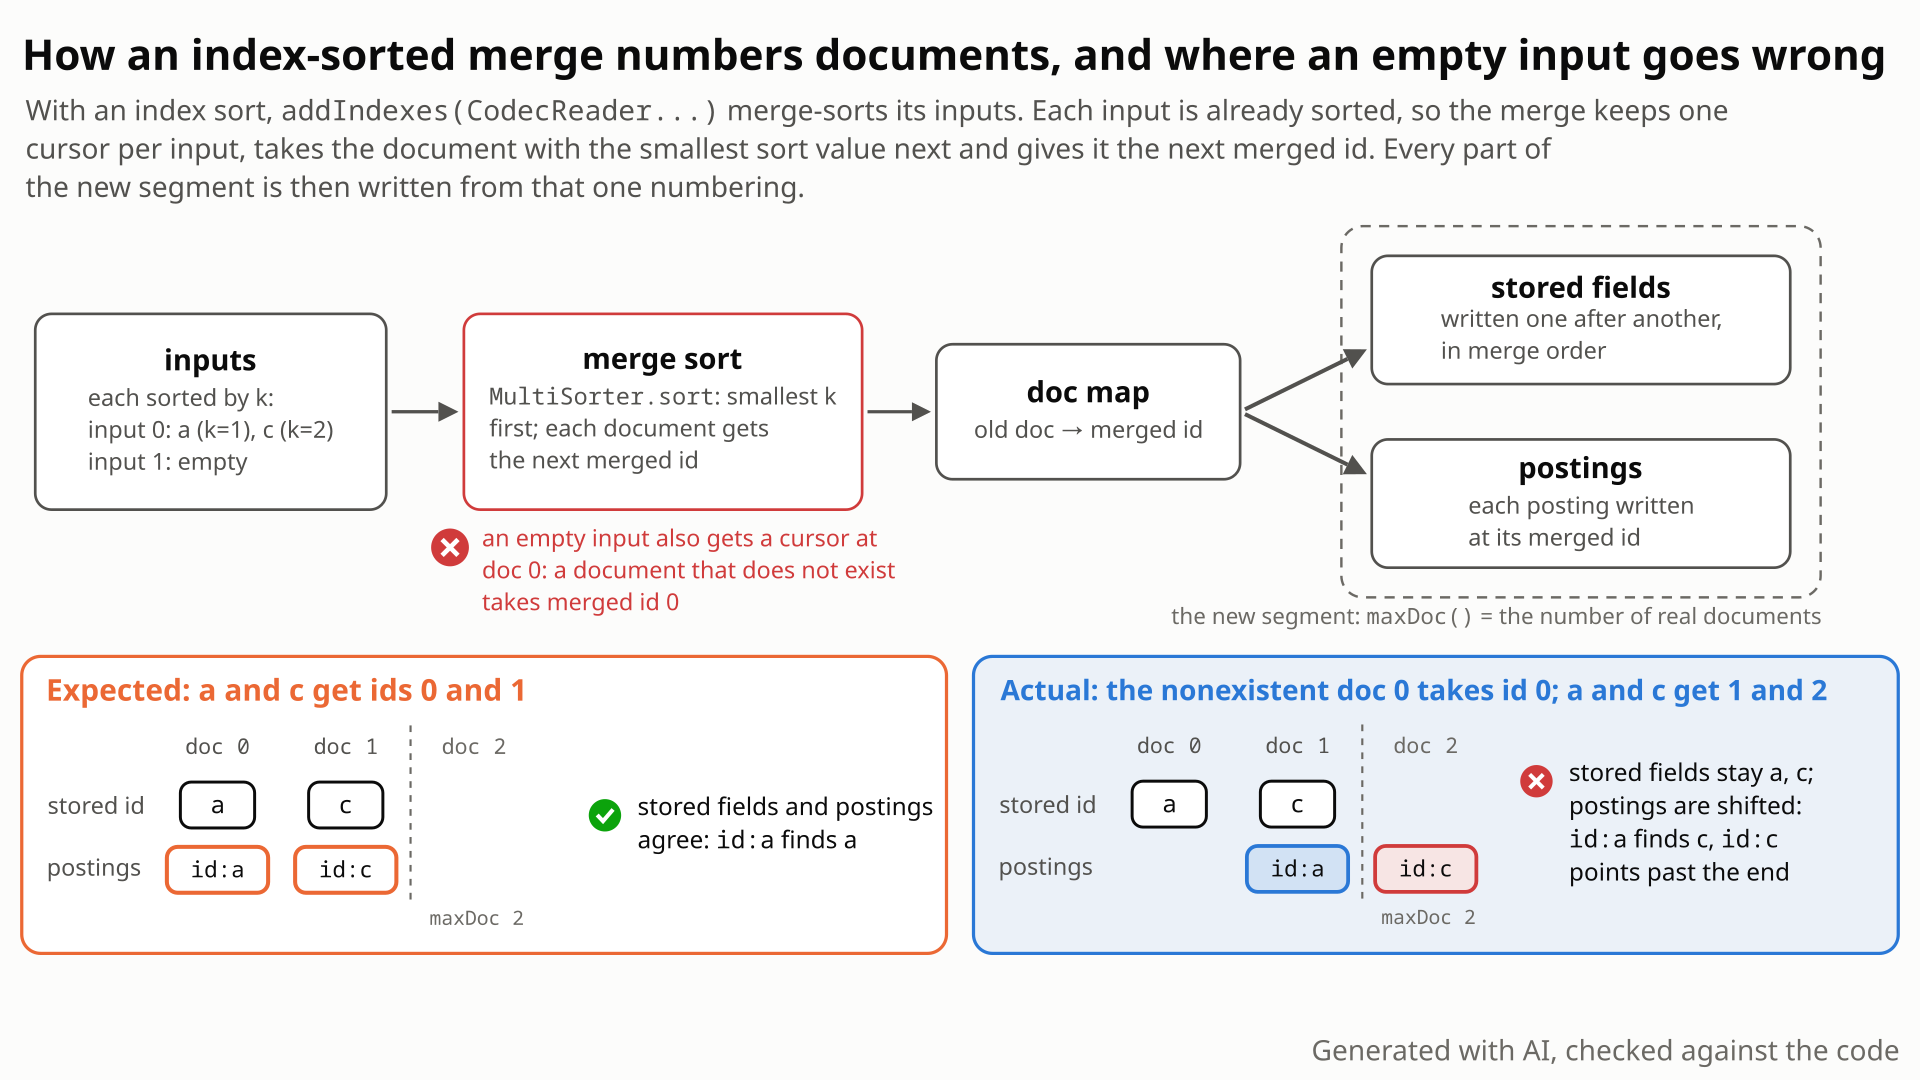
IndexWriterConfig.setIndexSort, every segment keeps its documents in sort order. When inputs are merged, for example byaddIndexes(CodecReader...),MultiSortermerge-sorts them: a priority queue holds one cursor per input, and each pop gives the next document the next merged doc id. - The result is one doc map per input (old id to merged id). Postings are rewritten through these maps; stored fields are copied in merge order, one after the other, so the two agree only if the maps are dense: 0, 1, 2, ...
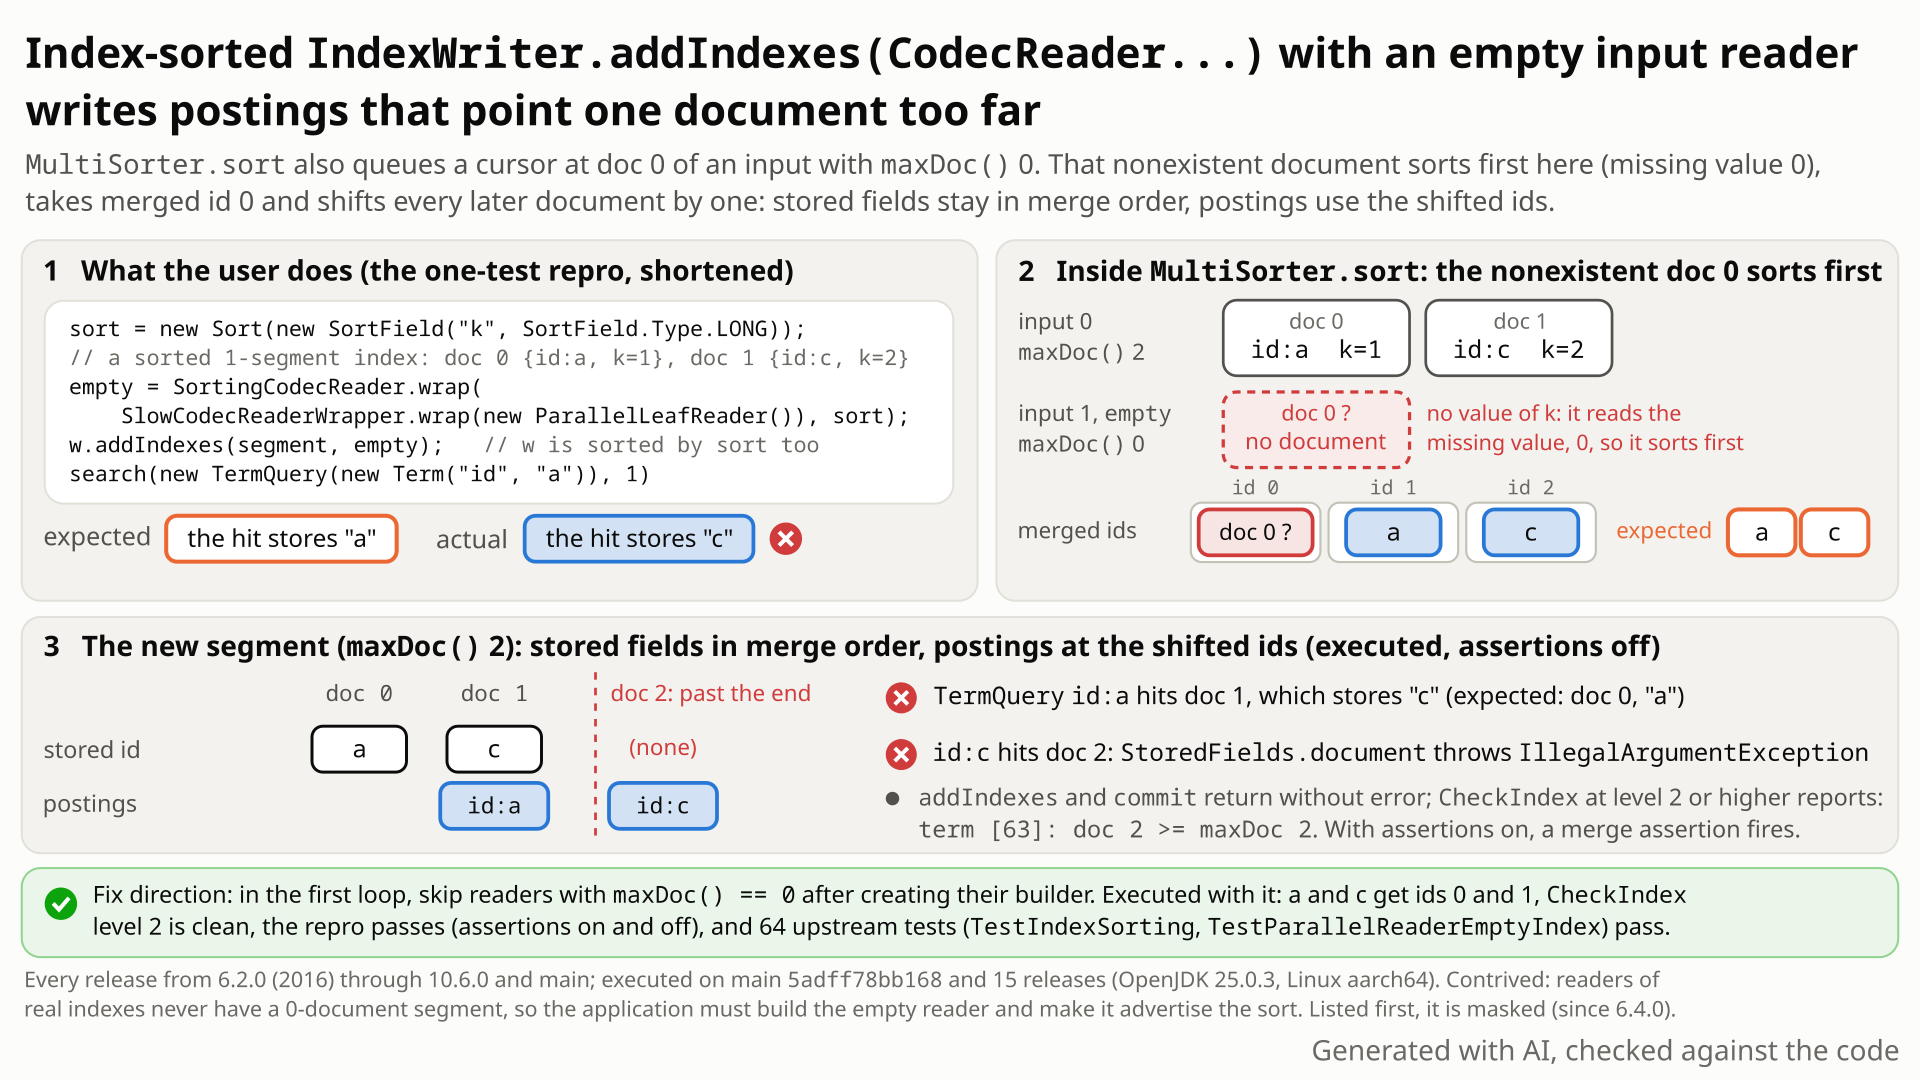
a and c land on ids 1 and 2 while their stored fields stay at 0 and 1. Select the still to open it at full size. Generated with AI, checked against the code.- Index two documents,
a(k = 1) andc(k = 2), into a writer sorted by the long fieldk. On a second writer with the same sort, calladdIndexes(segment, empty), whereemptyhasmaxDoc() == 0and advertises the sort:SortingCodecReader.wrap(SlowCodecReaderWrapper.wrap(new ParallelLeafReader()), sort). - You expect a 2-document segment in which
id:afinds the document that storesa, as you get without an index sort or with the empty reader listed first. - The sorting merge also puts a cursor at doc 0 of the empty reader. That document does not exist and has no
k, so it sorts as the missing value 0, beforea, and takes merged id 0.agets 1 andcgets 2, but the new segment hasmaxDoc2. - Stored fields are written in order (doc 0 =
a, doc 1 =c), postings at the shifted ids.id:areturns doc 1, which storesc;id:cpoints at doc 2, past the end. - With assertions off,
addIndexesandcommitsucceed; of the integrity checks onlyCheckIndexat level 2 or higher reportsdoc 2 >= maxDoc 2, and loading theid:chit throwsIllegalArgumentException. With assertions on, a stored-fields merge assertion fails insideaddIndexes.
Applications that call addIndexes(CodecReader...) on an index-sorted writer and pass a reader with no documents that advertises the sort, such as an empty ParallelLeafReader wrapped with SortingCodecReader. Readers of real indexes never have empty leaves, so ordinary indexing and merging are safe. Two documents are enough, and every release since 6.2.0 has it.
Mechanism, terms and numbers527 words
With an index sort, IndexWriter.addIndexes(CodecReader...) merge-sorts its inputs with MultiSorter.sort. Its init loop puts a cursor at doc 0 of every input, including one with maxDoc() == 0, and the merge loop gives that nonexistent document a merged doc id before it notices the reader is exhausted (MultiSorter.java:106-135 at 5adff78bb168). Every real document the merge places after it is mapped one id too far, while the merged segment's maxDoc counts only real documents. Stored fields are written in merge order and postings at the shifted ids: with a sorted segment {a k=1, c k=2} and an empty reader that advertises the sort, id:a returns the document that stores c, and id:c points at doc 2 of a 2-document segment. With assertions off the commit succeeds and id:a silently returns the wrong document; loading the id:c hit throws, and of the integrity checks only CheckIndex at level 2 or higher reports it; with assertions on a stored-fields merge assertion fails inside addIndexes. Every release since 6.2.0 (LUCENE-6766, 2016) has it. The empty input must be built by the application, so the priority is Low.
- Accepted input.
addIndexes(CodecReader...)validates each reader's created version,minVersionand index sort, not its size (IndexWriter.java:3228-3252). With an index sort,addIndexesReaderMergeskips the reorder path (:3548-3560) andMergeStatecallsMultiSorter.sort(MergeState.java:223). - A cursor for an empty input. The init loop creates a cursor at doc 0 for every reader and reads its sort value, with no
maxDoc() > 0check (MultiSorter.java:106-112, the fix site). For the empty readeradvanceExact(0)finds no value (IndexSorter.java:297), so the LONG sorter uses its missing value0L(:285-290). That call is outside theadvanceExactcontract: the target "must be a valid doc ID, ie. >= 0 and < maxDoc" (DocValuesIterator.java:25-27). - The phantom takes an id. The queue pops the smallest value: the phantom doc 0 (value 0) before
a(1). The loop recordsbuilders[1].add(0)and incrementsmappedDocID(MultiSorter.java:125-128; no deletions), and only then seesdocID 1 >= maxDoc 0and pops the reader (:129-135).agets 1 andcgets 2. - The shifted maps are used. Reader 0 popped after reader 1, so
isSortedis false (:120-123) and the maps are returned (:137-155) instead ofnull. - Two views disagree. The merged
maxDocis the sum of the inputs'numDocs(), 2 (MergeState.java:170-173). Stored fields are written with a running count (codecs/StoredFieldsWriter.java:146-158; with assertions on,assert sub.mappedDocID == docCountat:152fails), so doc 0 storesaand doc 1 storesc, while the postings use the mapped ids 1 and 2.
Only documents the merge places after the phantom are shifted: with three inputs, a document with k = -3 sorts before the phantom and keeps id 0, while documents with k = 5 and 7 get ids 2 and 3 in a segment of maxDoc 3 (executed). A reader whose documents are all deleted is not the trigger: deleted documents take no merged id (MultiSorter.java:126-128).
Exposure and likelihood200 words
- Who. Callers of
addIndexes(CodecReader...)on an index-sorted writer whose inputs include a reader withmaxDoc() == 0that advertises the same sort (since 8.0 a sorted writer rejects inputs that do not, LUCENE-8505).SortingCodecReader's javadoc names this use: re-sorting by wrapping readers and adding them to a fresh writer "via IndexWriter#addIndexes(CodecReader...)" (SortingCodecReader.java:47-50). - Not hit. Lucene has not written 0-document segments since LUCENE-5173 (
lucene/CHANGES.txt:13474), soDirectoryReaderleaves are never empty and ordinary indexing, merges andaddIndexes(Directory...)never see this input. The same inputs into an unsorted writer pass, and so does the empty reader listed first, where the pop order equals the reader order andsortreturnsnull(both executed). - Default vs opt-in. Opt-in: index sorting, the expert
addIndexes(CodecReader...)and, in practice, the@lucene.experimentalSortingCodecReader. - Effect. Silent, durable corruption: the commit succeeds and a term query returns the neighbouring document; a hit at
doc == maxDocmakesStoredFields.documentthrowIllegalArgumentException("docID must be >= 0 and < maxDoc=2 (got docID=2)" in the history runs, and in a cross-model reviewer's run). The defaultCheckIndexlevel 1 checks checksums only (CheckIndex.java:4742-4754); postings are checked from level 2 (:1114-1125). - Scale. Two documents; no concurrency.
One JUnit test method on the public API: a sorted 2-document segment and an empty reader that advertises the sort go into addIndexes, then one TermQuery. Deterministic, single thread; it fails with assertions on and off.
package org.apache.lucene.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Sort;
import org.apache.lucene.search.SortField;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestIndexSortAddIndexesEmptyReader extends LuceneTestCase {

  public void testEmptyReaderDoesNotShiftDocIds() throws Exception {
    Sort sort = new Sort(new SortField("k", SortField.Type.LONG));
    try (Directory src = newDirectory();
        Directory dst = newDirectory()) {
      try (IndexWriter w = new IndexWriter(src, new IndexWriterConfig().setIndexSort(sort))) {
        for (String id : new String[] {"a", "c"}) {
          Document doc = new Document();
          doc.add(new StringField("id", id, Field.Store.YES));
          doc.add(new NumericDocValuesField("k", id.equals("a") ? 1 : 2));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader full = DirectoryReader.open(src);
          IndexWriter w = new IndexWriter(dst, new IndexWriterConfig().setIndexSort(sort))) {
        CodecReader empty =
            SortingCodecReader.wrap(SlowCodecReaderWrapper.wrap(new ParallelLeafReader()), sort);
        w.addIndexes((CodecReader) full.leaves().get(0).reader(), empty);
      }
      try (DirectoryReader r = DirectoryReader.open(dst)) {
        IndexSearcher s = new IndexSearcher(r);
        TopDocs hits = s.search(new TermQuery(new Term("id", "a")), 1);
        // expected: id:a hits the doc storing "a"; actual: it hits the doc storing "c" (doc ids shifted by the empty reader)
        assertEquals("a", s.storedFields().document(hits.scoreDocs[0].doc).get("id"));
      }
    }
  }
}
cp $REPRO/TestIndexSortAddIndexesEmptyReader.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestIndexSortAddIndexesEmptyReader -Ptests.seed=DEADBEEF
# and with -Ptests.asserts=false: the silent form, expected:<[a]> but was:<[c]>
- Expected
id:areturns the document that storesa.- Observed
expected:<[a]> but was:<[c]>with assertions off (the test framework's close-timeCheckIndex, level 2 or higher:doc 2 >= maxDoc 2); with assertions on, anAssertionErrorin the stored-fields merge insideaddIndexes.
More files, environment, full output309 words
TestIndexSortAddIndexesEmptyReader (one method, extends LuceneTestCase, package org.apache.lucene.index of the lucene/core tests). The source writer and the target writer both use new IndexWriterConfig().setIndexSort(new Sort(new SortField("k", SortField.Type.LONG))); the empty input is SortingCodecReader.wrap(SlowCodecReaderWrapper.wrap(new ParallelLeafReader()), sort), the same empty reader an upstream test passes to addIndexes, wrapped so that it advertises the sort.
The comment line is 125 columns, so checkGoogleJavaFormat flags it and ./gradlew tidy re-wraps it (formatting only). The file has no license header. As the regression test, the same method fits in TestIndexSorting. The test asserts only id:a; the id:c evidence (doc 2 >= maxDoc 2) is the close-time CheckIndex that the test framework's directory wrappers run on close (an application runs no such check unless it calls CheckIndex), plus the longer tests. The recorded runs used seed DEADBEEF; the independent reproducer's slightly longer version (it also checks id:c and maxDoc) failed the same way with three more seeds and on 10.6.0, 10.5.2 and 9.12.3.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): fails; 6.2.0 to 10.6.0 (16 releases run): fail; 6.1.0: no IndexWriterConfig.setIndexSort or MultiSorter (does not compile) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestIndexSortAddIndexesEmptyReader.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestIndexSortAddIndexesEmptyReader -Ptests.seed=DEADBEEF
# gradle, scratch worktree at 5adff78bb168, -Ptests.seed=DEADBEEF -Ptests.asserts=false
TestIndexSortAddIndexesEmptyReader > testEmptyReaderDoesNotShiftDocIds FAILED
    org.junit.ComparisonFailure: expected:<[a]> but was:<[c]>
        at org.apache.lucene.index.TestIndexSortAddIndexesEmptyReader.testEmptyReaderDoesNotShiftDocIds(TestIndexSortAddIndexesEmptyReader.java:39)
:lucene:core:test (FAILURE): 1 test, 1  failure

# gradle, same, assertions on
TestIndexSortAddIndexesEmptyReader > testEmptyReaderDoesNotShiftDocIds FAILED
    java.lang.AssertionError: <no message>
    UncaughtExceptionError: Captured an uncaught exception in thread: Thread[id=21, name=Lucene Merge Thread #0, ...]
        Caused by: java.lang.AssertionError
            at org.apache.lucene.codecs.StoredFieldsWriter.merge(StoredFieldsWriter.java:152)
            at org.apache.lucene.index.SegmentMerger.mergeFields(SegmentMerger.java:252)
            at org.apache.lucene.index.SegmentMerger.mergeWithLogging(SegmentMerger.java:293)
            at org.apache.lucene.index.SegmentMerger.merge(SegmentMerger.java:123)
            at org.apache.lucene.index.IndexWriter.addIndexesReaderMerge(IndexWriter.java:3589)

# standalone JUnit runner on the main jars, -da, seed DEADBEEF
    => org.junit.ComparisonFailure: expected:<[a]> but was:<[c]>
       Suppressed: org.apache.lucene.index.CheckIndex$CheckIndexException: term [63]: doc 2 >= maxDoc 2

# with the fix: PASS with assertions on and offMultiSorter.sortpromises doc maps that "map each leaf's documents into the merged segment"; an empty leaf has nothing to map, yet takes an id.addIndexes(CodecReader...)says "empty segments are dropped", and upstreamTestParallelReaderEmptyIndexpasses the same empty reader, unwrapped, toaddIndexes.- MultiSorter calls
advanceExact(0)on a reader withmaxDoc0, whichDocValuesIteratorforbids (the target must be belowmaxDoc).
The full argument173 words
- Contract.
MultiSorter.sortreturns doc maps "to map each leaf's documents into the merged segment" (MultiSorter.java:35-40).addIndexes(CodecReader...): "empty segments are dropped by this method and not added to this index" (IndexWriter.java:3262). Since LUCENE-5173 that is enforced on the merged output (SegmentMerger.shouldMerge,SegmentMerger.java:101-103), so it is the API promise that an empty input is harmless, not a filter that was bypassed. - Tests.
TestParallelReaderEmptyIndex.testEmptyIndexcallsaddIndexes(SlowCodecReaderWrapper.wrap(new ParallelLeafReader()))("should not throw any exception",TestParallelReaderEmptyIndex.java:34-50);TestAddIndexes.testAddEmptyandtestFakeAllDeletedassert "empty segments should be dropped by addIndexes" (TestAddIndexes.java:1568-1604). No upstream test combines an empty input with an index sort. - History. LUCENE-5173 (
fe938c64edd, 2013) replaced LUCENE-5116's per-input empty filter with the check on the merged output, so empty inputs reach the merge code; in that thread Uwe Schindler expected that something outsideSegmentMerger"could maybe insert empty readers into the merge queue" (#6237). The 2016 MultiSorter (LUCENE-6766) queued every reader, and its issue (#7824, 40 comments) never discusses empty inputs. - Effect. Silent corruption, not a clean rejection.
The devil's-advocate check104 words
The strongest case for "not a bug": Lucene never writes 0-document segments, so the input exists only if the application builds it and wraps it in the experimental SortingCodecReader; the "dropped" promise is about the output; and the effect needs a reader order that forces a reorder.
Why it fails: that bears on likelihood, not intent. The API accepts the input, an upstream test uses the same empty reader, MultiSorter breaks the advanceExact contract on it, and the result is silent corruption. A credibility audit's committer-style view agreed it is real and the fix small, while pushing back on severity; hence priority Low.
Recommended Skip readers with maxDoc() == 0 in MultiSorter's init loop (fix A)
Skip readers with maxDoc() == 0 in MultiSorter's init loop, after creating their (unused) doc-map builder: +4/-1 in MultiSorter.java. The repro passes with assertions on and off, and 107 tests of TestIndexSorting, TestAddIndexes, TestSortingCodecReader and TestParallelReaderEmptyIndex pass.
    for (int i = 0; i < leafCount; i++) {
      CodecReader reader = readers.get(i);
      builders[i] = PackedLongValues.monotonicBuilder(PackedInts.COMPACT);
      if (reader.maxDoc() == 0) {
        continue; // nothing to map; a cursor at doc 0 would take a merged doc id
      }
      LeafAndDocID leaf = new LeafAndDocID(i, reader.getLiveDocs(), reader.maxDoc());
      setComparableValues(comparables, parents[i], i, leaf.docID);
      queue.add(leaf);
    }
All options and trade-offs3 options · 424 words
Option A was built and checked through gradle on 5adff78bb168; B and C are alternatives that were not run. Open PR #16851 rewrites the same loop (PriorityQueue#addAll) and keeps the bug; a fix would conflict with it textually.
Skip readers with maxDoc() == 0 in MultiSorter's init loop (fix A) (validated by the checks) (recommended)
Create every builder first (an empty reader's doc map is never called), then skip the empty reader, so it never enters the queue and takes no merged id.
    for (int i = 0; i < leafCount; i++) {
      CodecReader reader = readers.get(i);
      builders[i] = PackedLongValues.monotonicBuilder(PackedInts.COMPACT);
      if (reader.maxDoc() == 0) {
        continue; // nothing to map; a cursor at doc 0 would take a merged doc id
      }
      LeafAndDocID leaf = new LeafAndDocID(i, reader.getLiveDocs(), reader.maxDoc());
      setComparableValues(comparables, parents[i], i, leaf.docID);
      queue.add(leaf);
    }
Trade-offs
One maxDoc() call per input; by reading the diff, non-empty inputs go through the loop as before; it also removes the out-of-contract advanceExact(0) call. Without the empty reader in the queue, the remaining pop order decides isSorted as if it were absent.
What the checks validated
- Gradle in a scratch worktree at
5adff78bb168, seedDEADBEEF: the repro fails without the fix (assertions on and off) and passes with it (on and off). - With the fix:
TestIndexSorting(62),TestAddIndexes(39),TestSortingCodecReader(3),TestParallelReaderEmptyIndex(2) and the repro: 107 tests, 0 failures.checkGoogleJavaFormatflags only the repro's comment line, notMultiSorter.java. - Earlier runs: equivalent changes (same logic; headers and comment differ) pass the finder's and reviewers' tests and 64, 103 and 67 upstream tests; the equivalent change at 6.2.0 makes the scenario pass there.
Filter empty readers at the entry point, as the javadoc's "empty segments are dropped" suggests.
Trade-offs
Would also cover LFV-318, a different failure from the same kind of empty input on the unsorted reorder path: the first document after the empty reader loses its stored fields and term vectors (fix site SlowCompositeCodecReaderWrapper.docIdToReaderId). It changes what the merge policy's findMerges(CodecReader...) sees and leaves MultiSorter itself unguarded; it can complement A.
In Jim Ferenczi's PR "Let a merge write more than one segment", a MultiSorter commit by Michael Marshall queues a reader only when docID < maxDoc after skipping deleted documents; by reading its head e869d510b30, that also removes this bug.
Trade-offs
The PR is about range-restricted readers, never mentions empty ones and is not merged; the regression test is worth adding either way.
Downstream, a term query or filter over a segment built this way returns the neighbouring document's stored fields, so an application that filters by a term (for example a tenant or access term) can show a document the filter did not select.
A proof-obligation audit of MultiSorter.sort's contract: its doc maps must map every input's documents into the merged segment, for every input that addIndexes(CodecReader...) accepts. A reader with maxDoc 0 is accepted, and the init loop still queues a cursor for it; a public-API JUnit test then witnessed the shifted ids.
The method in full147 words
Method: semi-formal (a proof-obligation audit of a class's contract, witnessed by an executable repro).
- The finder read
MultiSorter.sortagainst its javadoc obligation (doc maps that "map each leaf's documents into the merged segment") and against whataddIndexes(CodecReader...)accepts (validateMergeReaderchecks version and sort, not size). For an input withmaxDoc0 the obligation is that it maps nothing; the init loop and merge loop give it one id. - The finder then wrote a public-API JUnit test (three inputs: two documents, the empty reader, one document) that fails on main with assertions on and off and on 10.6.0 and 10.0.0, and a skip-empty fix that passes it and 64 upstream tests.
- An independent reproducer wrote the smaller 2-document test that this doc's repro is trimmed from; two executed cross-model reviews, a devil's-advocate verifier and an adjudication reproduced it with their own tests ("Prior reports, history and checks").
No prior report in apache/lucene issues, PRs and commits (including the JIRA archive), the dev@, java-user@, issues@ and commits@ lists, downstream trackers or the web (searched 2026-11-02, re-checked 2026-11-03). Open PR #16571 rewrites the same loop and would fix it as a side effect.
Searches3 searches
No matching public report was found in the documented searches. The nearest items are related changes, not reports: open PR #16571 (would remove the bug as a side effect), open PRs #16851 and #16847 (edit the loop, keep the bug), #8619 (LUCENE-7568, the fast path that hides the empty-first order), #6180 (LUCENE-5116, origin of "empty segments are dropped"), #11253 (LUCENE-10216, testAddIndexesWithEmptyReaders, whose inputs have no leaves) and #7824 (LUCENE-6766). Limits: keyword search; GitHub search does not index all review comments (read directly for #16571, #16851 and #16847); private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive) | 2026-11-02, re-checked 2026-11-03 | a scripted prior-report search (16 issue/PR and 3 commit queries) and 25 manual searches (MultiSorter, empty reader / empty CodecReader, maxDoc == 0, index sort with addIndexes, LeafAndDocID); every issue and PR created since 2026-10-31 | no report; only #16571 among recent PRs touches MultiSorter |
| Open PRs | 2026-11-02 | the changed files of all 408 open apache/lucene PRs; the MultiSorter patches of #16571, #16851 and #16847 read | #16571 would fix it as a side effect; #16851 and #16847 keep it |
| Mailing lists, JIRA, downstream, web | 2026-11-02 | 20 list queries (dev@, java-user@, issues@, commits@) plus lists.apache.org, 4 JIRA-archive queries and JQL, Elasticsearch, OpenSearch and Solr trackers, 6 web queries; three scripted search runs with 1,956, 1,183 and 439 hits | nothing about this bug |
Introduced in 6.2.0 by LUCENE-6766 ("LUCENE-6766: initial patch", Mike McCandless, 2016), which made index sorting a core IndexWriterConfig feature and added MultiSorter; the loop is unchanged since. It fails on every release that was run, 6.2.0 to 10.6.0, and on main; not fixed upstream.
Versions tested7 rows
Introduced by LUCENE-6766 "Make index sorting a first-class citizen" (#7824), commit "LUCENE-6766: initial patch" by Mike McCandless, author date 2016-05-04: fdc220eeb42 on branch_6x (shipped in 6.2.0) and 54fa7dfd271 on master (merged with d715210467a). No PR. All 81 release tags from 6.2.0 to 10.6.0 in the history clone have the loop without a maxDoc check; the clone has no tags for 8.8.2 to 8.11.2, which are inferred from 8.8.1 (read) and 8.11.3 (run). 6.1.0 has no IndexWriterConfig.setIndexSort and no MultiSorter: its index sorting was lucene/misc's SortingMergePolicy (LUCENE-4752, 97ec69bb69c, 2013).
The trigger form changed, the bug did not: 6.2.0-7.7.3 accept any maxDoc-0 reader into a sorted writer; from 8.0.0 the input must advertise the sort (LUCENE-8505); 8.7.0 added SortingCodecReader (LUCENE-9484). Before 6.4.0 even the empty-first order corrupts; LUCENE-7568's isSorted fast path (6.4.0) masks that order. Not fixed upstream: the last commit to MultiSorter.java is e6f12f31d08 (#16202, 2026-06-05).
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | gradle: fails with assertions on and off; passes with fix A |
| 10.0.0, 10.5.2, 10.6.0, 9.12.3, 8.11.3 (API-adapted) | affected | the JUnit test: expected:<[a]> but was:<[c]> |
| 6.2.0, 6.4.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.6.3, 8.7.0, 8.11.4, 9.0.0, 9.12.3 | affected | the era-adapted main() form: id:a hits doc 1, which stores c; id:c hits doc 2 (docID must be >= 0 and < maxDoc=2 (got docID=2)); CheckIndex term [63]: doc 2 >= maxDoc 2 |
| 6.2.0, 6.3.0, empty reader first | before the fast path | also fails |
| 6.4.0, empty reader first | fast path | passes: the pop order equals the reader order, so sort returns null |
| 6.2.0 with the skip-empty change | fix at the introducing release | passes with assertions on and off |
| 6.1.0 | API absent | no IndexWriterConfig.setIndexSort and no MultiSorter (index sorting was lucene/misc's SortingMergePolicy); the repro does not compile |
A finder, an independent reproducer, two executed cross-model reviews (OpenAI GPT-5.6, refute and intended lenses), a devil's-advocate verifier, an adjudication, an audit and a final repro check reproduced it and agree on the root cause. This doc's gradle runs reproduced it on main and validated the fix.
Checks and verdicts284 words
The cross-model reviews ran on main ea57360912ed, where MultiSorter, MergeState, SortingCodecReader, ParallelLeafReader and SegmentMerger are byte-identical to 5adff78bb168; IndexWriter, SlowCodecReaderWrapper and SortField differ only by an infoStream message, a vector-reader overload and query-time sort pruning (#16963, #16905, #16857), none on this path. Every other check ran on 5adff78bb168.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Own 3-input test fails on main (assertions on and off), 10.6.0 and 10.0.0; the skip-empty fix passes it and 64 upstream tests. |
| independent reproducer | real | Own 2-document test (the basis of this repro) fails on main, 10.6.0, 10.5.2 and 9.12.3 (on and off) and 8.11.3; controls (no sort; empty reader first) pass; its fix passes. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Own test fails; a hit at doc == maxDoc makes StoredFields.document throw; 103 upstream tests pass with the fix. |
| cross-model review, intended lens (OpenAI GPT-5.6, executed) | real (high) | Direct test of the doc maps: the empty reader takes merged id 1 (b0 = 0, a0 = 2, a1 = 3); intended argument weak; 67 upstream tests pass with the fix. |
| devil's-advocate verifier | real (high) | The strongest "intended" case is rejected; fails on the released 10.6.0 jars. |
| adjudication | confirmed (high), Low | Re-ran both tests on main (fail) and the finder's with the fix (pass). |
| separate re-run, audit and final repro check | confirmed; likelihood lowered to contrived, impact class lowered to minor | The one-test repro fails on main with assertions on and off and passes with the fix. |
| this doc | reproduced; fix validated | Gradle without the fix fails (on and off); with it 107 tests pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 534 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,709 words
- Registry title
- Index-sorted IndexWriter.addIndexes(CodecReader...) with an empty (maxDoc 0) input reader silently writes a corrupt segment: MultiSorter gives the empty reader's nonexistent doc 0 a merged doc id, so the postings of later documents point one document too far
- Area
- index / index sorting at merge: MultiSorter doc maps, reached through IndexWriter.addIndexes(CodecReader...)
- Priority
- Low, rank 471: An index-sorted addIndexes(CodecReader...) with an empty input reader silently commits a segment whose postings point one document too far, in every release since 6.2.0. The empty reader must be built by the application and wrapped to advertise the index sort, which readers of real indexes never do, so it is contrived despite the durable damage.
- Impact class
- minor
- Impact note
- Applications on 6.2.0 through 10.6.0 or main that call addIndexes(CodecReader...) on an index-sorted IndexWriter and pass, among their inputs, a CodecReader with maxDoc() == 0 that advertises the index sort (for example SortingCodecReader.wrap(SlowCodecReaderWrapper.wrap(new ParallelLeafReader()), sort)), in an order that makes the merge reorder documents, silently commit a segment whose postings are shifted by one document against its stored fields (a TermQuery returns the neighbouring document and the last posting points at doc == maxDoc): nothing throws with -da, an internal stored-fields merge assertion fires inside addIndexes with -ea, only CheckIndex at level 2 or higher reports it, no scale is needed, but readers opened on real indexes never have a maxDoc-0 leaf, so the empty input must be built by the application.
- Summary
- You sort an IndexWriter by a long field k and call addIndexes(CodecReader...) with the single segment of a sorted 2-document index {a k=1, c k=2} followed by an empty reader that advertises the same sort (SortingCodecReader.wrap(SlowCodecReaderWrapper.wrap(new ParallelLeafReader()), sort)), and you expect a 2-document segment in which a TermQuery on id:a returns the document that stores a, as it does without an index sort or with the empty reader listed first. Instead MultiSorter.sort also queues a cursor at doc 0 for the empty reader, whose nonexistent doc 0 (missing sort value 0) is popped first and takes merged doc id 0, so a and c are mapped to 1 and 2 while the new segment has maxDoc 2. With assertions disabled addIndexes and commit succeed, but id:a returns the document that stores c and the posting of id:c points at doc 2 (>= maxDoc 2), which only CheckIndex at level 2 or higher reports.
- Introduced
- fdc220eeb42 on branch_6x (committed 2016-06-11; the copy that shipped in 6.2.0) and 54fa7dfd271 on master (reached master through the index_sort branch merge d715210467a, 2016-05-13), both 'LUCENE-6766: initial patch' by Mike McCandless for LUCENE-6766 'Make index sorting a first-class citizen' (migrated issue #7824; no PR, the work was done on a git branch against the JIRA issue): it created MultiSorter.java with the init loop that queues a doc-0 cursor for every reader without a maxDoc() > 0 check [read: history clone, tag sweep of all 81 release tags 6.2.0-10.6.0, git log -S'maxDoc() == 0' and -S'maxDoc() > 0' on the file return nothing; exec: 6.2.0 fails with -ea and -da, the skip-empty shadow of 6.2.0's MultiSorter makes it pass, and 6.1.0 has no index-sorting API] (2016-05-04 (author date of both fdc220eeb42 and 54fa7dfd271; branch_6x commit date 2016-06-11))
- First affected version
- 6.2.0 [exec] (tagged 2016-08-20; fails with -ea and -da, passes with the skip-empty MultiSorter shadow); on the master line first released in 7.0.0 [read]; 6.1.0 and earlier are not affected (no IndexWriterConfig.setIndexSort, no MultiSorter class) [exec: the repro does not compile there]
- Affected versions
- Every release from 6.2.0 through 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main 5adff78bb168 (12.0.0-SNAPSHOT) [read: all 81 release tags from 6.2.0 to 10.6.0 in the history clone have the loop with no skip for maxDoc() == 0; the clone lacks the 8.8.2-8.11.x tags]. Executed (fail): history runs of the independent reproduction's test body (adapted to each era) on 6.2.0 (-ea, -da), 6.4.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.6.3, 8.7.0, 8.11.4, 9.0.0 and 9.12.3 (-da); the independent reproduction's one test unchanged on 9.12.3, 10.5.2, 10.6.0 and main (-ea and -da each) and an API-adapted copy on 8.11.3 (-da); the finder's test on 10.0.0, 10.6.0 (-da) and main (-ea, -da); the intended-behaviour check on 10.6.0 (-da); a separate re-run on main (-ea, -da). The trigger form changed, the root cause did not: 6.2.0-7.7.3 accept any maxDoc-0 reader into a sorted writer, 8.0.0-8.6.3 need one that advertises the sort (LUCENE-8505, e.g. a FilterCodecReader), and from 8.7.0 on the SortingCodecReader form works (LUCENE-9484); in 6.2.0-6.3.0, before the LUCENE-7568 isSorted fast path, listing the empty reader first also corrupts (executed), while from 6.4.0 on that order is masked. Not new in 10.6. Not fixed upstream: MultiSorter.java is unchanged on upstream main 1c2072f0284 (author date 2026-11-02), branch_10_6 and branch_10x since e6f12f31d08 (#16202, author date 2026-06-05) [read, re-checked through the GitHub API on 2026-11-02]. Executed on Linux aarch64 with JDK 25.0.3 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (2026-11-02, on top of the finder's, the intended-behaviour check's and the adjudication's searches; rechecked the same day): a scripted prior-report search over 16 GitHub issue and PR queries on apache/lucene, 3 commit queries, 5 downstream-repository queries (Elasticsearch, OpenSearch, Solr), 20 mailing-list queries (dev@, java-user@, issues@, commits@), 4 JIRA-archive queries and 6 web queries (1956 distinct hits, none highly relevant and 28 of medium relevance, each of those checked), the finder's run (43 queries, 1183 hits) and the intended-behaviour check's run (22 queries, 439 hits), plus 25 manual GitHub searches on apache/lucene (including PRs and issues created or updated since 2026-10-31), 10 downstream GitHub searches, a scan of the file lists of all 408 open apache/lucene PRs, direct JIRA JQL queries and issue reads, and lists.apache.org searches: no report of an empty (maxDoc 0) input taking a merged doc id in MultiSorter.sort, or of postings and stored fields disagreeing after an index-sorted addIndexes(CodecReader...). Same-day recheck: GitHub search on apache/lucene for 'MultiSorter' (6 hits: open PR #16571 and the closed #10370, #9943, #9638, #8625), 'MultiSorter empty' (only #16571), 'addIndexes empty reader sort', 'SortingCodecReader empty' and '"maxDoc 0" addIndexes' (no relevant hit); the 9 PRs and 1 issue created since 2026-10-31 (#16956-#16965) do not touch MultiSorter or the addIndexes path; the last upstream commit on MultiSorter.java is still e6f12f31d08 (#16202, author date 2026-06-05), with main at 1c2072f0284. Related, not reports: open PR #16571 (jimczi, 'Let a merge write more than one segment', updated 2026-11-02, not merged; its MultiSorter commit, authored by Michael Marshall on 2026-09-30, queues a reader's cursor only when docID < maxDoc after skipping deleted docs, read at head e869d510b30 on 2026-11-02), which would remove this bug as a side effect but is motivated by range-restricted readers and never mentions empty readers; open PRs #16851 (vsop-479) and #16847 (jimczi) also edit the init loop but keep the bug; #8619 (LUCENE-7568, the isSorted fast path that masks the bug when the pop order equals the reader order); #6180 (LUCENE-5116, the source of the 'empty segments are dropped' javadoc note).
- Lucene commit tested
- main
5adff78bb168(2026-11-02) through gradle in a scratch worktree with assertions on and off, without and with the fix (the repro,TestIndexSorting,TestAddIndexes,TestSortingCodecReader,TestParallelReaderEmptyIndex,checkGoogleJavaFormat), and through a standalone JUnit runner on the main jars. The hunt ran the test or its era-adaptedmain()form on 6.1.0 (noIndexWriterConfig.setIndexSortorMultiSorter: does not compile), 6.2.0 through 10.6.0 (16 releases, all fail) and main. Only Linux aarch64 with OpenJDK 25.0.3 was run.
- Finding record
lucene/core/src/java/org/apache/lucene/index/MultiSorter.java:35-40 (at 5adff78bb168) (sort javadoc: returns DocMap 'to map each leaf's documents into the merged segment'), :106-112 (init loop: a LeafAndDocID cursor at doc 0 and setComparableValues(.., leaf.docID) for every reader, no maxDoc() > 0 check; fix site), :115-135 (merge loop: builders[top.readerIndex].add(mappedDocID) and mappedDocID++ at :125-128 run for the empty reader's nonexistent doc 0 before 'top.docID < top.maxDoc' pops it at :130-134), :137-139 (isSorted fast path returns null), :141-153 (the shifted doc maps); IndexSorter.java:284-289 (LONG sorter: missing value 0L when none is set)lucene/core/src/java/org/apache/lucene/index/MergeState.java:127-173 (at 5adff78bb168) (merged maxDoc = sum of the inputs' numDocs, :170-173) and :223 (MultiSorter.sort called for an index-sorted merge); lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3228-3252 (validateMergeReader checks version, minVersion and index sort, not maxDoc), :3262 (addIndexes(CodecReader...) javadoc: 'empty segments are dropped by this method and not added to this index'), :3549-3560 (with an index sort the reorder/merged-view path is skipped)lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1114-1124 (at 5adff78bb168) (postings are tested only at level >= MIN_LEVEL_FOR_INTEGRITY_CHECKS), :4740-4757 (Level.MIN_VALUE = 1 = DEFAULT_VALUE, MIN_LEVEL_FOR_INTEGRITY_CHECKS = 2) [read at the registration check]https://github.com/apache/lucene/pull/16571 (MultiSorter.java patch read at head e869d510b30 through the GitHub API on 2026-11-02), https://github.com/apache/lucene/pull/16851, https://github.com/apache/lucene/pull/16847, https://github.com/apache/lucene/issues/7824, https://github.com/apache/lucene/issues/8619, https://github.com/apache/lucene/issues/6180, read 2026-11-02; GitHub API search and commit list on MultiSorter.java, read about 2026-11-02
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/MultiSorter.java:35-40 (at 5adff78bb168) (sort javadoc), :106-112 (init loop, fix site), :115-135 (merge loop; :125-128 id given before :129-135 pops), :137-155 (isSorted fast path and the returned maps)lucene/core/src/java/org/apache/lucene/index/IndexSorter.java:285-290 (at 5adff78bb168) (LONG missing value 0L), :297 (advanceExact); DocValuesIterator.java:25-27 (advanceExact contract)lucene/core/src/java/org/apache/lucene/index/MergeState.java:170-173 (at 5adff78bb168) (merged maxDoc), :223 (MultiSorter.sort); IndexWriter.java:3228-3252 (validateMergeReader), :3548-3560 (reorder path skipped with an index sort)lucene/core/src/java/org/apache/lucene/codecs/StoredFieldsWriter.java:146-158 (at 5adff78bb168) (stored fields in merge order; assert at :152)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:47-54 (at 5adff78bb168) (re-sorting via addIndexes; @lucene.experimental); CheckIndex.java:1114-1125, :4742-4754 (levels)lucene/CHANGES.txt:13474 (at 5adff78bb168) (LUCENE-5173: no 0-document segments)lucene/test-framework/src/java/org/apache/lucene/tests/store/BaseDirectoryWrapper.java:33, (at 5adff78bb168) 45, 64-71 and MockDirectoryWrapper.java:917 (the test directories run CheckIndex at level 2 or higher on close)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/MultiSorter.java:35-40; (at 5adff78bb168) IndexWriter.java:3262; SegmentMerger.java:101-103; DocValuesIterator.java:25-27lucene/core/src/test/org/apache/lucene/index/TestParallelReaderEmptyIndex.java:34-50; (at 5adff78bb168) TestAddIndexes.java:1568-1604
- Prior reports
github.com/apache/lucene search 'MultiSorter' and four phrase searches, and the commit list of MultiSorter.java (read 2026-11-03)
- History
github.com/apache/lucene commit list of MultiSorter.java (e6f12f31d08 latest; main 1c2072f0284; read 2026-11-03)
- Diagrams
lucene/core/src/java/org/apache/lucene/index/MultiSorter.java:106-135 (at 5adff78bb168)
- TestIndexSortAddIndexesEmptyReader.java (lucene/core, package org.apache.lucene.index, 1 test):
repro/LFV-1133/TestIndexSortAddIndexesEmptyReader.java(43 lines)
The diagram illustrates the repro's scenario (main 5adff78bb168, MultiSorter.java:106-135).
assets/LFV-1133/bug.png(534 KB)