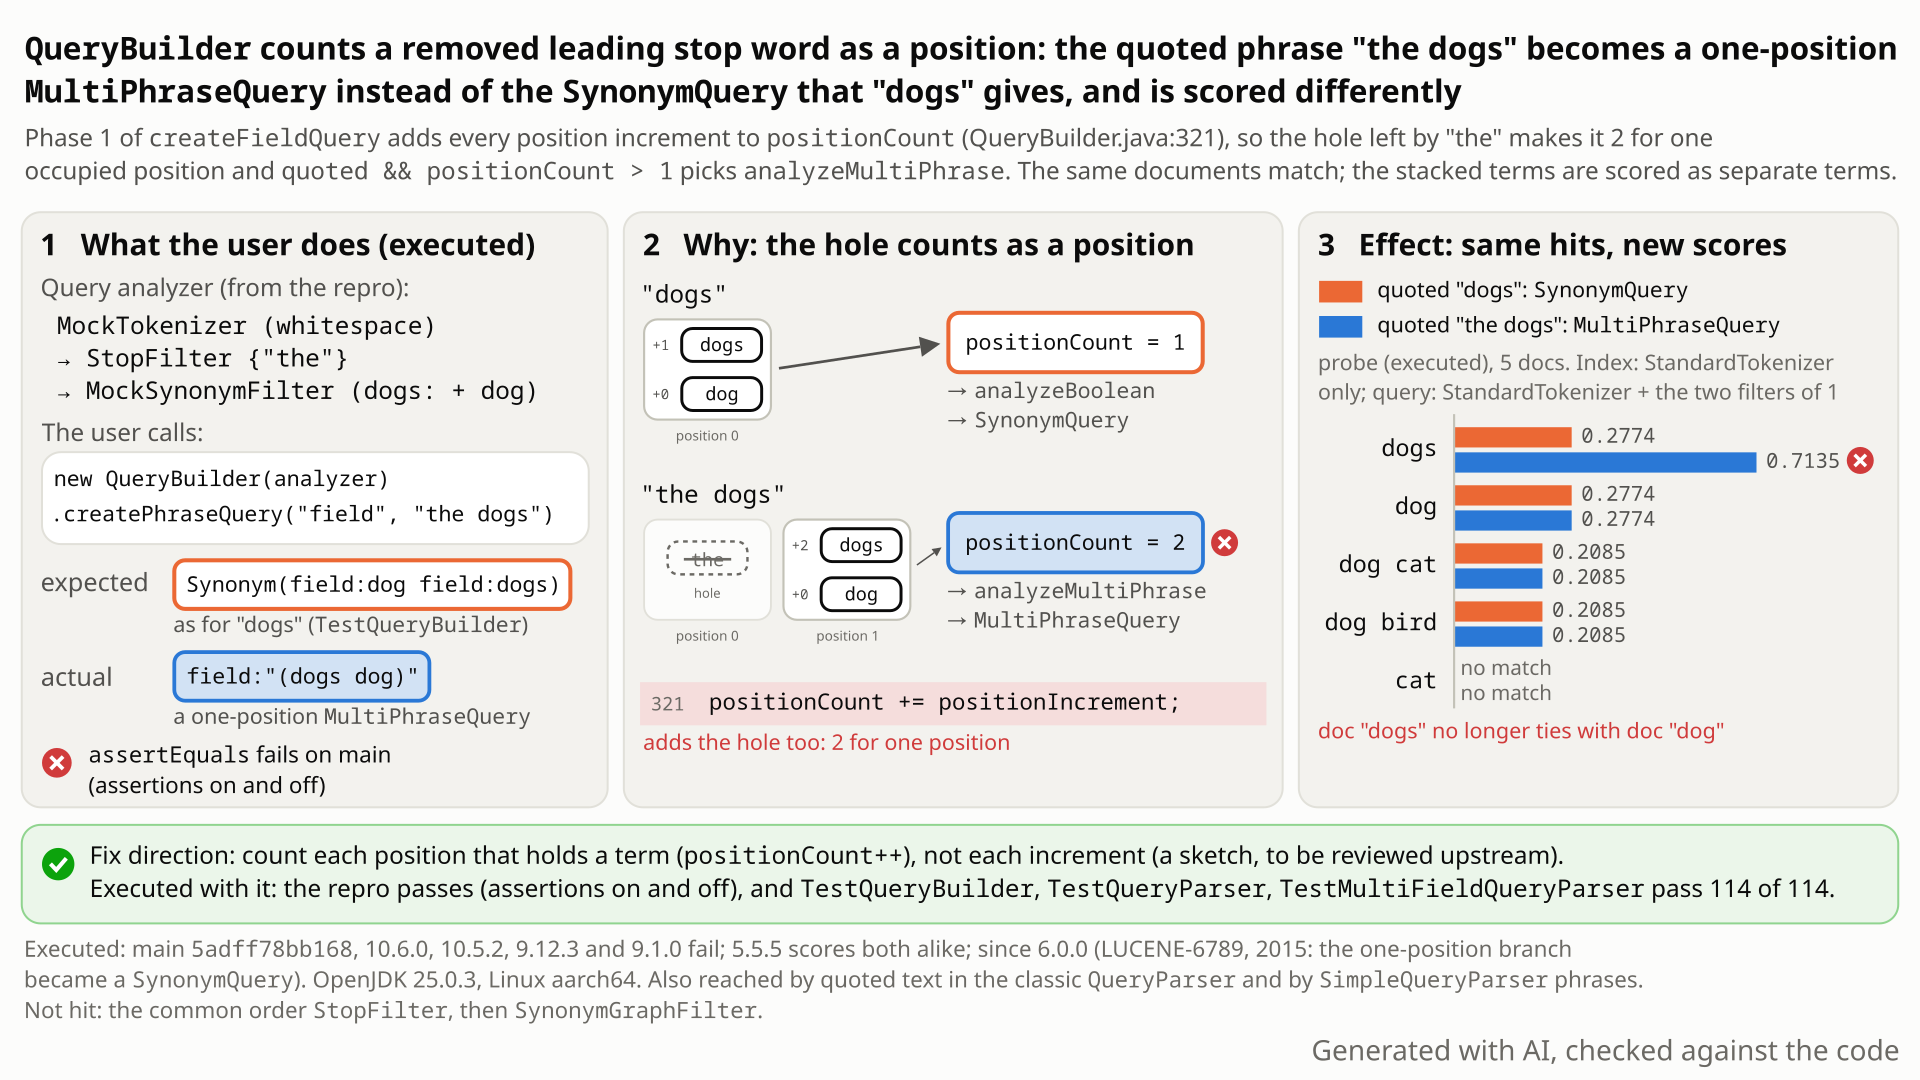
"dogs" and "the dogs" through QueryBuilder: the removed the leaves a hole, the increment sum counts two positions for one, and the text becomes a one-position MultiPhraseQuery. On the five example documents only doc dogs changes, from 0.2774 to 0.7135. Counting positions fixes it. Select the still to open it at full size. Generated with AI, checked against the code.- Your query analyzer removes the stop word
theand stacksdogondogsat the same position (here a synonym filter; KeywordRepeatFilter plus a stemmer is another trigger, with its own numbers below). The index holds five documents, analyzed with StandardTokenizer alone:dogs,dog,dog cat,dog bird,cat. - Search the quoted phrase
"dogs"withcreatePhraseQueryor the classicQueryParser: you getSynonymQuery(dogs, dog), 4 hits, and docsdogsanddogtie at 0.2774 in this setup, as synonyms should. - You expect
"the dogs"to give the same: oncetheis removed only one position is left, and QueryBuilder makes a phrase only "when terms occur at more than one position". - You get
MultiPhraseQuery field:"(dogs dog)". It matches the same 4 documents, but docdogsnow scores 0.7135 while docdogstays at 0.2774."dogs the"still gives the SynonymQuery. - Why: QueryBuilder adds up position increments instead of counting positions. The removed
theleaves a hole, sodogsarrives with increment 2 and one position counts as two. A one-position MultiPhraseQuery rewrites to a plain OR of term queries, each scored with its own IDF.
Applications whose query analyzer leaves a stop-word hole in front of stacked tokens: SynonymGraphFilter before StopFilter, or StopFilter followed by KeywordRepeatFilter plus a stemmer, or by ASCIIFoldingFilter with preserveOriginal. Reached through createPhraseQuery and quoted text in the classic and simple query parsers. StopFilter then SynonymGraphFilter is not affected. Ranking changes; matches do not.
Mechanism, terms and numbers617 words
QueryBuilder.createFieldQuery, which createPhraseQuery, the classic and simple query parsers use, decides between a phrase and a synonym query by the number of positions in the analyzed text: its quoted parameter means "phrases should be generated when terms occur at more than one position". It gets that number by adding up position increments (QueryBuilder.java:321), so the hole a StopFilter leaves for a removed leading word counts as a position. Quoted "the dogs", where dog is stacked on dogs, then becomes the one-position MultiPhraseQuery field:"(dogs dog)" instead of SynonymQuery(dogs, dog), the query "dogs" and "dogs the" get. The MultiPhraseQuery rewrites to a plain disjunction of term queries, so the same documents match but the stacked terms are scored separately: with default BM25, doc dogs scores 0.2774 under "dogs" and 0.7135 under "the dogs", while doc dog stays at 0.2774. It needs a query analyzer that leaves a stop-word hole in front of stacked tokens (for example SynonymGraphFilter before StopFilter, or StopFilter then KeywordRepeatFilter and a stemmer); the common StopFilter then SynonymGraphFilter order is not affected. Affected: 6.0.0 to 10.6.0 and main; a one-line fix (count positions, not increments) was validated.
- Position increment: each token carries the distance to the previous token's position. A normal next word has 1; a synonym or variant stacked on the same position has 0; a word after a removed stop word has 2 (the StopFilter leaves a hole).
- SynonymQuery: scores several terms "as if you had indexed them as one term" (
SynonymQuery.java:47-49): one pseudo-term with the larger document frequency of the terms and their summed total term frequency (SynonymQuery.java:210-226). So in the example below docsdogsanddogscore alike. - One-position MultiPhraseQuery: a multi-phrase with a single term array. Its rewrite ("optimize one-term case") is a BooleanQuery of SHOULD TermQuerys and drops the position (
MultiPhraseQuery.java:182-191): each term keeps its own IDF.
- Phase 1 of
createFieldQueryis "counting the number of tokens/positions" (QueryBuilder.java:308-309): for every token with a non-zero increment,positionCount += positionIncrement(:320-321); an increment of 0 setshasSynonyms(:322-323). - For
"the dogs"the tokens aredogs(increment 2) anddog(increment 0):numTokens2,positionCount2,hasSynonymstrue. For"dogs the"the hole is only inend(), sopositionCountis 1. - Phase 2:
quoted && positionCount > 1with synonyms goes toanalyzeMultiPhrase(:347-351);positionCount == 1would have gone toanalyzeBoolean(:358-360), which returnsnewSynonymQuery(:395). A single token (numTokens == 1) goes toanalyzeTermfirst (:337-339), so plain stop-word phrases are not affected. - The resulting
MultiPhraseQueryholds one term array at position 1 and rewrites todogs OR dog. The hole adds no constraint; it only changes the scoring model. The rare termdogs(document frequency 1 in the example) now gets its own, higher IDF.
Five documents dogs, dog, dog cat, dog bird, cat, default similarity; the index is analyzed with StandardTokenizer alone, the query with StandardTokenizer, StopFilter for the and MockSynonymFilter (the repro's two filters): quoted "dogs" scores dogs 0.27742466, dog 0.27742466, dog cat and dog bird 0.20845169; quoted "the dogs" matches the same 4 documents and scores dogs 0.7135338, the others unchanged. With production filters only, the same analyzer at index and query time (StandardTokenizer, LowerCaseFilter, English StopFilter, KeywordRepeatFilter, PorterStemFilter, RemoveDuplicatesTokenFilter, the classic QueryParser): doc dogs 0.20100057 and doc dog 0.15446018 under "dogs" and "dogs the", doc dogs 0.8987793 under "the dogs". How far and in which direction a score moves depends on the corpus statistics and the similarity.
Exposure and likelihood211 words
- Trigger chains (executed): SynonymGraphFilter placed before StopFilter (
"the tv"); StopFilter followed by KeywordRepeatFilter + PorterStemFilter + RemoveDuplicatesTokenFilter (KeywordRepeatFilter's documented use: "to index the stemmed and the un-stemmed version of a term into the same field"); StopFilter followed by ASCIIFoldingFilter withpreserveOriginal("the café"). Same on main and 10.6.0. - Not affected: StopFilter followed by SynonymGraphFilter, the common order: the graph filter re-emits the match with increment 1, so the hole is gone. The flexible
StandardQueryParserhas the same sum (AnalyzerQueryNodeProcessor.java:137); it builds a plain BooleanQuery for"dogs"and a one-position MultiPhraseQuery for"the dogs", which rewrites to the same disjunction, so its scores do not differ (docdogs0.8987793 under all three texts, production filters). Unquoted text returns a one-clause BooleanQuery around the SynonymQuery, which scores the same. - Entry points:
createPhraseQuery(executed); the classicQueryParserfor quoted text (executed) and withautoGeneratePhraseQueries, throughnewFieldQuery(QueryParserBase.java:405-410), henceMultiFieldQueryParsertoo (read);SimpleQueryParserphrases (SimpleQueryParser.java:588, executed). - Defaults: default QueryBuilder flags, parser settings and BM25 similarity. The trigger is the analyzer chain.
- Size and likelihood: any index; one stop word and one content word suffice. A silent ranking change on the same hits; no matching public report was located in the recorded searches: rare.
One JUnit test, public API: a whitespace tokenizer, StopFilter for the and the test framework's MockSynonymFilter (dogs -> dog), asserting that createPhraseQuery("field", "the dogs") equals SynonymQuery(dogs, dog). It fails with assertions on and off on main, 10.6.0 and 9.12.3, and passes with the fix.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.util;

import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.CharArraySet;
import org.apache.lucene.analysis.StopFilter;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.SynonymQuery;
import org.apache.lucene.tests.analysis.MockSynonymFilter;
import org.apache.lucene.tests.analysis.MockTokenizer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestQueryBuilderLeadingStopWordSynonym extends LuceneTestCase {

  // Expected: SynonymQuery(dogs, dog), as for "dogs"; actual: MultiPhraseQuery "(dogs dog)".
  public void testLeadingStopWordBeforeSynonym() {
    Analyzer analyzer =
        new Analyzer() {
          @Override
          protected TokenStreamComponents createComponents(String fieldName) {
            Tokenizer tokenizer = new MockTokenizer(MockTokenizer.WHITESPACE, true);
            CharArraySet stopWords = new CharArraySet(List.of("the"), false);
            return new TokenStreamComponents(
                tokenizer, new MockSynonymFilter(new StopFilter(tokenizer, stopWords)));
          }
        };
    SynonymQuery expected =
        new SynonymQuery.Builder("field")
            .addTerm(new Term("field", "dogs"))
            .addTerm(new Term("field", "dog"))
            .build();
    assertEquals(expected, new QueryBuilder(analyzer).createPhraseQuery("field", "the dogs"));
  }
}
cp $REPRO/TestQueryBuilderLeadingStopWordSynonym.java $LUCENE/lucene/core/src/test/org/apache/lucene/util/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestQueryBuilderLeadingStopWordSynonym -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false; nothing depends on the seed
- Expected
Synonym(field:dog field:dogs), the SynonymQuery that quoted"dogs"gives.- Observed
AssertionError: expected:<Synonym(field:dog field:dogs)> but was:<field:"(dogs dog)">: a one-position MultiPhraseQuery.
More files, environment, full output144 words
The test uses the same analyzer pieces as TestQueryBuilder (MockTokenizer, core StopFilter, MockSynonymFilter, which stacks dog on dogs with increment 0). Single thread, deterministic, about 1.5 s. It needs the org.apache.lucene.tests.* test-framework packages, so it runs as written on 9.1.0 and later. Use the same test as the regression test; it passes :lucene:core:check -x test together with the fix.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT); the same test also fails unchanged on the 10.6.0 and 9.12.3 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (only this platform was run) |
cp $REPRO/TestQueryBuilderLeadingStopWordSynonym.java $LUCENE/lucene/core/src/test/org/apache/lucene/util/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestQueryBuilderLeadingStopWordSynonym -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false; nothing depends on the seed
TestQueryBuilderLeadingStopWordSynonym > testLeadingStopWordBeforeSynonym FAILED
    java.lang.AssertionError: expected:<Synonym(field:dog field:dogs)> but was:<field:"(dogs dog)">
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:365F54E92B900FB8]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:120)
        at org.junit.Assert.assertEquals(Assert.java:146)
        at org.apache.lucene.util.TestQueryBuilderLeadingStopWordSynonym.testLeadingStopWordBeforeSynonym(TestQueryBuilderLeadingStopWordSynonym.java:49)
:lucene:core:test (FAILURE): 1 test, 1 failure- Contract: phrases are generated "when terms occur at more than one position" (
QueryBuilder.java:241); here the terms occupy one. TestQueryBuilderpins quoted"dogs"toSynonymQuery,"dogs the"gets it too, and PhraseQuery documents leading holes as meaningless.- The one-position MultiPhraseQuery drops its position on rewrite: the hole adds no constraint, only another scoring model.
The full argument241 words
- Contract.
@param quoted"true if phrases should be generated when terms occur at more than one position" (QueryBuilder.java:241,:286); phase 1 says it counts "tokens/positions" (:309). - Test.
TestQueryBuilder.testSynonymsassertscreatePhraseQuery("field", "dogs")equalsSynonymQuery(dogs, dog)(TestQueryBuilder.java:144-156). No test anywhere asserts the leading-hole outcome. - Leading holes carry no meaning. PhraseQuery: "Leading holes don't have any particular meaning for this query and will be ignored" (
PhraseQuery.java:52), from LUCENE-6255 (#7317, 5.1.0). There Robert Muir objected to an exception for leading holes: "I don't think its their fault if they type \"the query\", and the search engine has a stopword filter in the chain. It will confuse them, they dont get an error with \"query the\"." Here too,"dogs the"and"the dogs"behave differently. - History. The sum comes from the classic QueryParser (
2ce046a7a6d, 2005: "Make QueryParser work with analyzers that return tokens with a position increment > 1"); the goal was to stop treating an increment > 1 as a synonym, and its test covers only multi-position text. LUCENE-5261 (2013, 4.6.0) moved it into QueryBuilder. Up to 5.5.5 both branches built the same BooleanQuery, so the wrong branch was invisible.a944ab17a71(LUCENE-6789, 2015) switched the single-position boolean branch (and stacked positions in boolean queries) to SynonymQuery but left MultiPhraseQuery's one-position rewrite a BooleanQuery; the issue never mentions phrases, stop words or holes, and the commit's own tests expect a SynonymQuery for single-position quoted text.
The devil's-advocate check153 words
The strongest case for "intended": createPhraseQuery's @return lists MultiPhraseQuery (QueryBuilder.java:118-119); setEnablePositionIncrements says "result phrase and multi-phrase queries will be aware of position increments. Useful when e.g. a StopFilter increases the position increment of the token that follows an omitted token" (:201-203); the user asked for a phrase; the sum is 20 years old; and Lucene does not promise equal scores for different query texts. A cross-model reviewer rated it moderate.
Why it fails: a one-position MultiPhraseQuery drops its position on rewrite, so the hole gives no positional meaning at all; PhraseQuery documents leading holes as meaningless; the trailing-hole text gets the SynonymQuery; and even with setEnablePositionIncrements(false), whose purpose is to ignore increments, the hole still selects the MultiPhraseQuery (executed). Verdict: not intended. A maintainer may still prefer another fix site (MultiPhraseQuery's rewrite) or call a score-only defect low priority; that is about where and when, not whether.
Recommended Count positions, not increments (recommended, validated)
Count positions instead of adding increments: positionCount++ instead of positionCount += positionIncrement (QueryBuilder.java:321). Only text with a single occupied position after a leading hole changes; it then gets the SynonymQuery, as without the stop word. Validated: the repro passes, and so do TestQueryBuilder, the queryparser and highlighter test tasks and :lucene:core:check -x test.
--- a/lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java
+++ b/lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java
@@ -318,7 +318,8 @@
         numTokens++;
         int positionIncrement = posIncAtt.getPositionIncrement();
         if (positionIncrement != 0) {
-          positionCount += positionIncrement;
+          // count positions that hold a term; holes (e.g. removed stop words) are not positions
+          positionCount++;
         } else {
           hasSynonyms = true;
         }
All options and trade-offs3 options · 485 words
From reading the code of QueryBuilder as shipped: positionCount is read only in the two branch tests (QueryBuilder.java:347, :358). The count and the sum differ only when an increment is greater than 1, and the branch changes only when exactly one position holds terms after a leading hole. Then quoted text gets the SynonymQuery, and unquoted text the bare SynonymQuery instead of a one-clause BooleanQuery around it (same scores). Token boosts on that path are kept as a side effect, because analyzeBoolean carries them and analyzeMultiPhrase does not (a separate finding, LFV-584). Subclasses that override newSynonymQuery, newMultiPhraseQueryBuilder or the protected analyze* methods may see other query types change. LFV-829 (the classic Highlighter counts a MultiPhraseQuery's leading positions as gaps) is related but independent: it needs two or more positions (quoted "the dogs bark"), which this fix leaves a MultiPhraseQuery with the same highlight, and for the one-position query of this bug the Highlighter already marks the same words as for the SynonymQuery (executed). Neither fix affects the other.
Phase 1 increments positionCount once per token with a non-zero increment.
--- a/lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java
+++ b/lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java
@@ -318,7 +318,8 @@
         numTokens++;
         int positionIncrement = posIncAtt.getPositionIncrement();
         if (positionIncrement != 0) {
-          positionCount += positionIncrement;
+          // count positions that hold a term; holes (e.g. removed stop words) are not positions
+          positionCount++;
         } else {
           hasSynonyms = true;
         }
Trade-offs
Scores of affected phrase queries change on purpose, back to what the same text without the stop word gives: a CHANGES entry with a note on the score change. Unquoted text with a leading hole gets a bare SynonymQuery instead of a one-clause BooleanQuery, a compatibility point for code that inspects query classes. The flexible parser's identical sum (AnalyzerQueryNodeProcessor.java:137) shows no score difference today and can be left or changed for consistency. Downstream copies of this logic are not reached.
What the checks validated
In a scratch worktree of 5adff78bb168 with gradle and JDK 25, removed afterwards: stock, the repro fails with assertions on and off; with the fix it passes on and off, the repro plus TestQueryBuilder (27 tests) pass, the whole :lucene:queryparser:test (533 tests, 1 skipped) and :lucene:highlighter:test (722 tests) tasks pass, and :lucene:core:check -x test passes (google-java-format, ecj lint, forbidden APIs). The full core test suite was not run.
Make MultiPhraseQuery.rewrite's one-position case return a SynonymQuery instead of a SHOULD BooleanQuery.
Trade-offs
Fixes the scores for every caller, but also changes them for applications that build one-position MultiPhraseQuerys themselves; QueryBuilder still returns a MultiPhraseQuery, so the repro would have to assert scores.
What the checks validated
Not built.
Return newSynonymQuery from analyzeMultiPhrase when it collected only one position.
Trade-offs
Local, but duplicates the branch decision phase 1 already makes; A is smaller.
What the checks validated
Not built.
Elasticsearch's MatchQueryParser and OpenSearch's MatchQuery carry their own copy of the same increment sum and branch (read on their default branches, not run), so a Lucene fix would not reach their phrase queries.
A proof-obligation audit of QueryBuilder.createFieldQuery's contract: the obligation that quoted text becomes a phrase only when its terms occupy more than one position was checked against phase 1, which adds increments instead of counting positions. A one-test JUnit on the stock main jars witnessed the gap, and a BM25 probe measured its effect.
The method in full86 words
Method (semi-formal): state the documented obligation of the quoted parameter ("phrases should be generated when terms occur at more than one position"), find the code that decides it (positionCount in phase 1, the tests at :347 and :358), and look for an input that satisfies the precondition's wording but not the code's: one occupied position whose increment sum is 2. The witness is the leading stop word in front of a stacked token, run on the stock main jars with assertions on and off.
No matching public report was located in the recorded keyword searches (2026-11-02): GitHub issues, PRs and commits incl. the migrated JIRA archive, mailing lists, downstream projects and the web. Nearest: #8029 (the same single/multi-position split, a different symptom) and #7317 (PhraseQuery ignores leading holes).
Searches3 searches
Nearest items, none this bug: #8029 (LUCENE-6972, open since 2016: QueryBuilder's single- vs multi-position split, a minimum_should_match symptom on unquoted 5.x queries, no holes); #7317 (LUCENE-6255: PhraseQuery ignores leading holes; supports this report); #6427 (LUCENE-5363, leading stop words in phrase matching); #3603 (LUCENE-2529, quotes the sum, index-time topic); #9986 (LUCENE-8943, MultiPhraseQuery IDF); #8470 (LUCENE-7417, highlighter crash on a one-clause MultiPhraseQuery). Limits: keyword search only; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Elasticsearch, OpenSearch, Solr) | 2026-11-02 | a scripted prior-report search (56 queries, 478 hits, every relevant one read) plus a 39-query run and manual queries such as "leading stop word", positionCount, stopword synonym MultiPhraseQuery | no report; related items listed above |
| Mailing lists and JIRA | 2026-11-02 | dev@, java-user@, issues@ and commits@; LUCENE and SOLR JIRA queries | nothing on this; SOLR-11022 is different |
| Open PRs and upstream main | 2026-11-02 | file lists of all open apache/lucene PRs updated since 2026-10-30; newest commits on QueryBuilder.java; upstream main 1c2072f0284 | no PR touches the sum; the newest QueryBuilder commit is a 2026-04-01 refactor; the sum is still at line 321 |
Introduced in 6.0.0 by a944ab17a71 (LUCENE-6789, 2015), which made the single-position branch return a SynonymQuery; the increment sum is older but was invisible before. 5.5.5 scores both texts alike; 6.0.0 through 10.6.0 and main differ. Not fixed upstream.
Versions tested7 rows
Introduced by a944ab17a71 "LUCENE-6789: change IndexSearcher default similarity to BM25" (Robert Muir, 2015-09-14; JIRA LUCENE-6789, migrated as #7847; no PR): it added SynonymQuery and changed analyzeBoolean from a coord-disabled BooleanQuery to a SynonymQuery, while MultiPhraseQuery's one-position rewrite stayed a BooleanQuery. The sum itself came from the classic QueryParser (2ce046a7a6d, 2005) and moved into QueryBuilder with LUCENE-5261 (57f38e67d65, 2013, 4.6.0). All 84 release tags from 6.0.0 to 10.6.0 carry the three pieces (8.8.2 to 8.11.3 are not tagged in the history clone and are covered by 8.8.1 and the executed 8.11.4). The 6.x and 7.x scores are 2.2 times the later ones because 8.0 dropped BM25's k1+1 factor; the divergence is the same. Upstream main 1c2072f0284 (2026-11-02) still has the sum.
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | the repro fails through gradle with assertions on and off |
| 10.6.0, 9.12.3 | affected | the repro fails on the release jars |
| 10.5.2, 9.1.0 | affected | the same test body fails |
| 6.0.0, 7.7.3, 8.11.4 | history probe | doc dogs: 0.6103343 vs 1.5697745 (6.0.0, 7.7.3), 0.27742466 vs 0.7135338 (8.11.4) |
| 6.0.0 | first release | first release with a944ab17a71 |
| 5.5.5 | last clean | both texts score 1.6152921 (both branches built the same BooleanQuery) |
| main + fix A | fix | the repro passes with assertions on and off |
An independent reproducer, a cross-model review (OpenAI GPT-5.6, executed), a devil's-advocate verifier, an adjudication, an audit and a final repro check agree on the root cause, and each re-ran a failing test. This doc's gradle runs reproduced it on main and validated the fix.
Checks and verdicts283 words
Every check saw the same branch choice from the same line, QueryBuilder.java:321. The cross-model review ran on an earlier main checkout, ea57360912ed, whose QueryBuilder, MultiPhraseQuery, SynonymQuery, StopFilter and MockSynonymFilter are byte-identical to 5adff78bb168's; its leading-hole test was re-run on 5adff78bb168 and fails the same way.
| Check | Verdict | What it found |
|---|---|---|
| finder (proof-obligation audit) | reproduced | Own JUnit fails on main (on, off), 10.6.0 and 9.12.3; passes with the fix; TestQueryBuilder, TestQueryParser, TestMultiFieldQueryParser 114 of 114 with the fix; BM25 probe 0.2774 vs 0.7135. |
| independent reproducer | real | Own test (the same body as the repro) fails on main (on, off), 10.6.0, 10.5.2 and 9.12.3; passes with the fix; production-filter probes find the trigger chains and the immune order. |
| cross-model review, refute lens | real (high); intended case moderate | OpenAI GPT-5.6, executed: its own test with a custom stacking filter fails (assertions on, two seeds; off); controls pass; score test on another corpus 0.7135 vs 0.2774; the fix passes, TestQueryBuilder 26 of 26. |
| devil's advocate | real | No intended reading survives; reproduced with production filters on main and 10.6.0; SimpleQueryParser affected, StandardQueryParser not. |
| adjudication | confirmed (high), priority Low | Re-ran the tests on clean main (on, off): fail; with the fix: pass. |
| audit and final repro check | confirmed | Re-ran on main: fail; production-filter probe 0.2010 vs 0.8988; the one-test repro fails on main and passes with the fix. |
| this doc | reproduced; fix validated | Gradle on main (on, off): fail; with fix A the repro passes (on, off), and TestQueryBuilder, the queryparser (533 tests) and highlighter (722 tests) test tasks and :lucene:core:check -x test pass. Release jars 10.6.0 and 9.12.3: fail. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 530 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,740 words
- Registry title
- QueryBuilder counts a removed leading stop word as a position, so a quoted phrase such as "the dogs", whose one remaining word carries a same-position synonym or variant, becomes a one-position MultiPhraseQuery instead of the SynonymQuery that "dogs" gives, and is scored differently (since 6.0.0)
- Area
- core / util QueryBuilder (createFieldQuery position count choosing the phrase branch over the single-position synonym branch; reached through the classic, multi-field and simple query parsers)
- Priority
- Low, rank 375: When a removed leading stop word sits in front of stacked tokens, a quoted phrase with a single content word scores its stacked terms separately in every release since 6.0.0, which changes ranking but not which documents match. It needs a query analyzer that leaves that stop-word hole in front of stacked tokens, so it is a rare, ranking-only defect.
- Impact class
- minor
- Impact note
- Minor rather than silent wrong results: the same documents match and only the BM25 scores of the stacked terms change. Applications whose query analyzer removes stop words and leaves the hole in front of a position with stacked tokens (SynonymGraphFilter before StopFilter, or StopFilter followed by KeywordRepeatFilter + PorterStemFilter + RemoveDuplicatesTokenFilter, or by ASCIIFoldingFilter with preserveOriginal [exec]) and that build phrases through QueryBuilder (createPhraseQuery [exec], quoted text in the classic QueryParser [exec] and MultiFieldQueryParser or autoGeneratePhraseQueries [read], SimpleQueryParser phrases [exec]) get, for a phrase whose only content word follows a removed stop word, a one-position MultiPhraseQuery that rewrites to a plain SHOULD disjunction of TermQuerys instead of the SynonymQuery the same word gets without the stop word: the same documents match, but the stacked terms are scored as separate terms with their own IDF, so ranking changes (BM25 probe: doc 'dogs' 0.2774 under "dogs", 0.7135 under "the dogs", while doc 'dog' stays at 0.2774) [exec]. Default QueryBuilder flags and similarity, no scale needed. Not affected: the common order StopFilter then SynonymGraphFilter (the graph filter re-emits the match with increment 1, so the hole is gone) [exec], and the flexible StandardQueryParser, which has the same sum but builds the same disjunction on both branches [exec].
- Summary
- You analyze query text with stop-word removal and a same-position synonym (dogs -> dog) and call createPhraseQuery(field, "the dogs"), or type the quoted phrase "the dogs" into the classic QueryParser. You expect the SynonymQuery(dogs, dog) that "dogs" and "dogs the" give, because the remaining terms sit at one position and QueryBuilder generates phrases only 'when terms occur at more than one position'; you get the one-position MultiPhraseQuery field:"(dogs dog)", which rewrites to a plain disjunction of the two terms. The same documents match, but BM25 scores them differently (doc 'dogs' rises from 0.2774 to 0.7135 and no longer ties with doc 'dog'), because createFieldQuery adds up position increments, so the hole left by 'the' counts as a second position.
- Introduced
- a944ab17a712f58e8417639763a0c7267fa11e61 (trunk r1703070), LUCENE-6789 'change IndexSearcher default similarity to BM25' (migrated as apache/lucene#7847; a JIRA patch from before GitHub PRs; author Robert Muir, GitHub rmuir): it added SynonymQuery and made QueryBuilder.analyzeBoolean, the positionCount == 1 branch, return a SynonymQuery instead of a coord-disabled BooleanQuery of SHOULD TermQuerys, while MultiPhraseQuery's one-position rewrite ('optimize one-term case') stayed a plain BooleanQuery of SHOULD TermQuerys, so from then on the leading hole changes the scoring model [read: the a944ab17a71 diff; exec bracket: the history probe passes on 5.5.5 and fails on 6.0.0]. The increment sum itself is older and had no visible effect alone: 'positionCount += positionIncrement' came from the classic QueryParser (2ce046a7a6d, 2005-11-08, first released in 1.9), moved into QueryBuilder with LUCENE-5261 (57f38e67d65 on trunk and 3bd5beca408 on branch_4x, 2013-10-09, issue #6325, first released in 4.6.0) and was kept by LUCENE-6401 (3b8ea7b2e78, 2015-04-08) [read: git blame and git log on the history clone]. (2015-09-14 (author and commit date 2015-09-14 22:03:35 +0000; LUCENE-6789 / #7847 opened 2015-09-09, closed 2015-09-14))
- First affected version
- 6.0.0 [exec: the core-only history probe fails on 6.0.0 ("dogs" gives SynonymQuery, doc 'dogs' 0.6103343; "the dogs" gives MultiPhraseQuery, 1.5697745; default BM25) and passes on 5.5.5 (1.6152921 for both); from 4.6.0 through 5.5.5 the leading hole already picked MultiPhraseQuery, but both branches built the same coord-disabled BooleanQuery, so the scores were equal (executed on 5.5.5, read for 4.6.0); no 5.x tag contains a944ab17a71]
- Affected versions
- every release from 6.0.0 through 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main 5adff78bb168 (12.0.0-SNAPSHOT). Executed: the independent reproduction's one-test JUnit TestQuotedLeadingStopWordSynonym (shipped as TestQueryBuilderLeadingStopWordSynonym, the same test renamed) fails on main (-ea and -da; the independent reproduction, the adjudication and a separate re-run) and on 10.6.0, 10.5.2, 9.12.3 and 9.1.0 (-da); it cannot compile on 9.0.0 and earlier (test-framework package org.apache.lucene.tests.* from 9.1.0); the finder's test fails on main (-ea and -da), 10.6.0 and 9.12.3 (-da); the core-only history probe fails on 6.0.0, 7.7.3, 8.11.4, 9.12.3, 10.6.0 and main and passes on 5.5.5 (-ea) [exec]. By code identity, all 84 release tags from 6.0.0 to 10.6.0 in the history clone carry the increment sum, the SynonymQuery single-position branch and MultiPhraseQuery's one-position BooleanQuery rewrite; 8.8.2, 8.9.0, 8.10.x and 8.11.0-8.11.3 are not tagged there and are covered by inference between 8.8.1 and the executed 8.11.4 [read]. Not new in 10.6 (10.5.2 fails). Not fixed upstream: the newest commit on QueryBuilder.java is 1518164afa3 (author date 2026-04-01, a refactor), already in 5adff78; upstream main 1c2072f0284 (author date 2026-11-02, 3 commits past 5adff78, none in core) still has the sum at QueryBuilder.java:321, and none of the 21 open PRs updated since 2026-10-31 touches QueryBuilder, MultiPhraseQuery, SynonymQuery, StopFilter, QueryParserBase or SimpleQueryParser [read through the GitHub API, 2026-11-02]. Executed on Linux aarch64 with JDK 25.0.3 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (2026-11-02, on top of the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches; rechecked the same day): a scripted prior-report search over 56 queries (16 GitHub issue and PR, 3 commit, 4 downstream on Elasticsearch, OpenSearch and Solr, 20 mailing-list over dev@, java-user@, issues@ and commits@, 5 JIRA-archive and 8 web; 478 distinct hits, 4 rated highly and 56 moderately relevant, every relevant one read with its comments) plus the finder's 39-query run (105 hits), the independent reproduction's, the intended-behaviour check's and the adjudication's manual GitHub searches, the file lists of the 26 open PRs updated since 2026-10-30 (only #14262 touches QueryBuilder.java, elsewhere) and upstream commits on QueryBuilder.java by author date: no report that a removed leading stop word makes createFieldQuery count an extra position and turn quoted single-position text with stacked tokens into a MultiPhraseQuery. Same-day recheck: GitHub search on apache/lucene for QueryBuilder issues and PRs updated since 2026-10-31 (0), PRs created since 2026-10-31 naming QueryBuilder (0), PRs naming positionCount (0), 'leading stop word synonym' (0), 'MultiPhraseQuery SynonymQuery stop' (0), 'createPhraseQuery stopword' (0), 'phrase synonym stopword hole' with PRs (0); the 21 open PRs updated since 2026-10-31 touch none of the involved files; the newest commit on QueryBuilder.java is still 1518164afa3 (author date 2026-04-01). Related, not reports: #8029 / LUCENE-6972 (open since 2016; the same single- vs multi-position split, but a minimum_should_match symptom on unquoted 5.x queries with no holes; body and comments re-read), #7317 / LUCENE-6255 (PhraseQuery ignores leading holes; supports this claim), #6427 / LUCENE-5363, #3603 / LUCENE-2529 (quotes the increment sum, index-time topic), #9986 / LUCENE-8943 (MultiPhraseQuery IDF), #8899 / LUCENE-7848, #10028 / LUCENE-8985, elastic/elasticsearch#86021.
- Lucene commit tested
- main
5adff78bb168(12.0.0-SNAPSHOT) through gradle in a scratch worktree, stock and with the fix, assertions on and off; the 10.6.0 and 9.12.3 release jars with a standalone runner. Earlier checks: the same test body on 10.5.2 and 9.1.0, and a core-only score probe on 5.5.5 (clean), 6.0.0, 7.7.3 and 8.11.4 (affected). OpenJDK 25.0.3 on Linux aarch64 only.
- Finding record
lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:241, (at 5adff78bb168) :286 (javadoc of createFieldQuery's quoted parameter: 'true if phrases should be generated when terms occur at more than one position')lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:308-325 (at 5adff78bb168) (phase 1, comment 'counting the number of tokens/positions'; :321 positionCount += positionIncrement adds the size of a hole: fix site)lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:335-366 (at 5adff78bb168) (numTokens == 1 -> analyzeTerm; quoted && positionCount > 1 -> analyzeMultiPhrase when hasSynonyms, :347-351; positionCount == 1 -> analyzeBoolean, :358-360)lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:385-396 (at 5adff78bb168) (analyzeBoolean: one position -> newSynonymQuery, :395), :464 (analyzeMultiPhrase)lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:181-195 (at 5adff78bb168) (rewrite, 'optimize one-term case': one position -> BooleanQuery of SHOULD TermQuerys; the position is dropped)lucene/core/src/java/org/apache/lucene/search/SynonymQuery.java:44-49 (at 5adff78bb168) (class javadoc: score the terms 'as if you had indexed them as one term')lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:48-53 (at 5adff78bb168) (class javadoc: 'Leading holes don't have any particular meaning for this query and will be ignored')lucene/core/src/test/org/apache/lucene/util/TestQueryBuilder.java:144-156 (at 5adff78bb168) (testSynonyms pins createPhraseQuery("field", "dogs") to SynonymQuery(dogs, dog))lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:398-410 (at 5adff78bb168) (newFieldQuery -> createFieldQuery with the quoted flag)lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:588 (at 5adff78bb168) (phrases through createPhraseQuery)lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/processors/AnalyzerQueryNodeProcessor.java:119-137, (at 5adff78bb168) :184-187 (the same increment sum in the flexible parser; no score divergence there in a probe by the intended-behaviour check)github.com/apache/lucene/issues/8029, /issues/7317, /issues/6427, /issues/3603, /issues/9986, /issues/7847
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:308-325, (at 5adff78bb168) :337-360, :395, :464 (phase 1 sum, branches, analyzeBoolean, analyzeMultiPhrase)lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:182-191 (at 5adff78bb168) (one-position rewrite, 'optimize one-term case')lucene/core/src/java/org/apache/lucene/search/SynonymQuery.java:44-49, (at 5adff78bb168) :210-226 (class javadoc; pseudo-term statistics)
- Who is affected
lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/processors/AnalyzerQueryNodeProcessor.java:119-137, (at 5adff78bb168) :184-187 (the same sum in the flexible parser)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:405-410 (at 5adff78bb168) (newFieldQuery -> createFieldQuery with quoted || autoGeneratePhraseQueries)lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:588 (at 5adff78bb168) (phrases through createPhraseQuery)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/KeywordRepeatFilter.java:26-29 (at 5adff78bb168) (documented use)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:118-119, (at 5adff78bb168) :201-203, :241, :286, :309 (javadoc and comments)lucene/core/src/test/org/apache/lucene/util/TestQueryBuilder.java:144-156 (at 5adff78bb168) (testSynonyms)lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:52 (at 5adff78bb168) (leading holes ignored)lucene/CHANGES.txt:11202 (at 5adff78bb168) (LUCENE-6255)github.com/apache/lucene/issues/7317 (LUCENE-6255; Robert Muir's comment of 2015-02-19)
- Suggested fix
lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:312, (at 5adff78bb168) :321, :347, :358 (every use of positionCount)lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:385-396, (at 5adff78bb168) :464-497 (analyzeBoolean keeps boosts; analyzeMultiPhrase builds terms without boosts)lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:182-195 (at 5adff78bb168) (rewrite, option B site)
- How it was found
lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:241, (at 5adff78bb168) :286, :308-325, :347, :358
- Prior reports
github.com/apache/lucene/issues/8029, /issues/7317, /issues/6427, /issues/3603, /issues/9986, /issues/8470
- TestQueryBuilderLeadingStopWordSynonym.java (lucene/core, public API):
repro/LFV-1148/TestQueryBuilderLeadingStopWordSynonym.java(51 lines)
A light summary card (the PNG), drawn from the code at 5adff78bb168, the repro test and the hunt's score probe.
assets/LFV-1148/bug.png(530 KB)