Compressor.compress takes a ByteBuffersDataInput: a read view over a list of buffers, whose length() is a long. Each built-in compressor narrows that length to an int with a plain (int) cast and reads that many bytes (the three CompressionMode compressors into one byte[] of that size, the two preset-dictionary ones in sub-blocks into a reused buffer), so above 4 GiB the length wraps around.
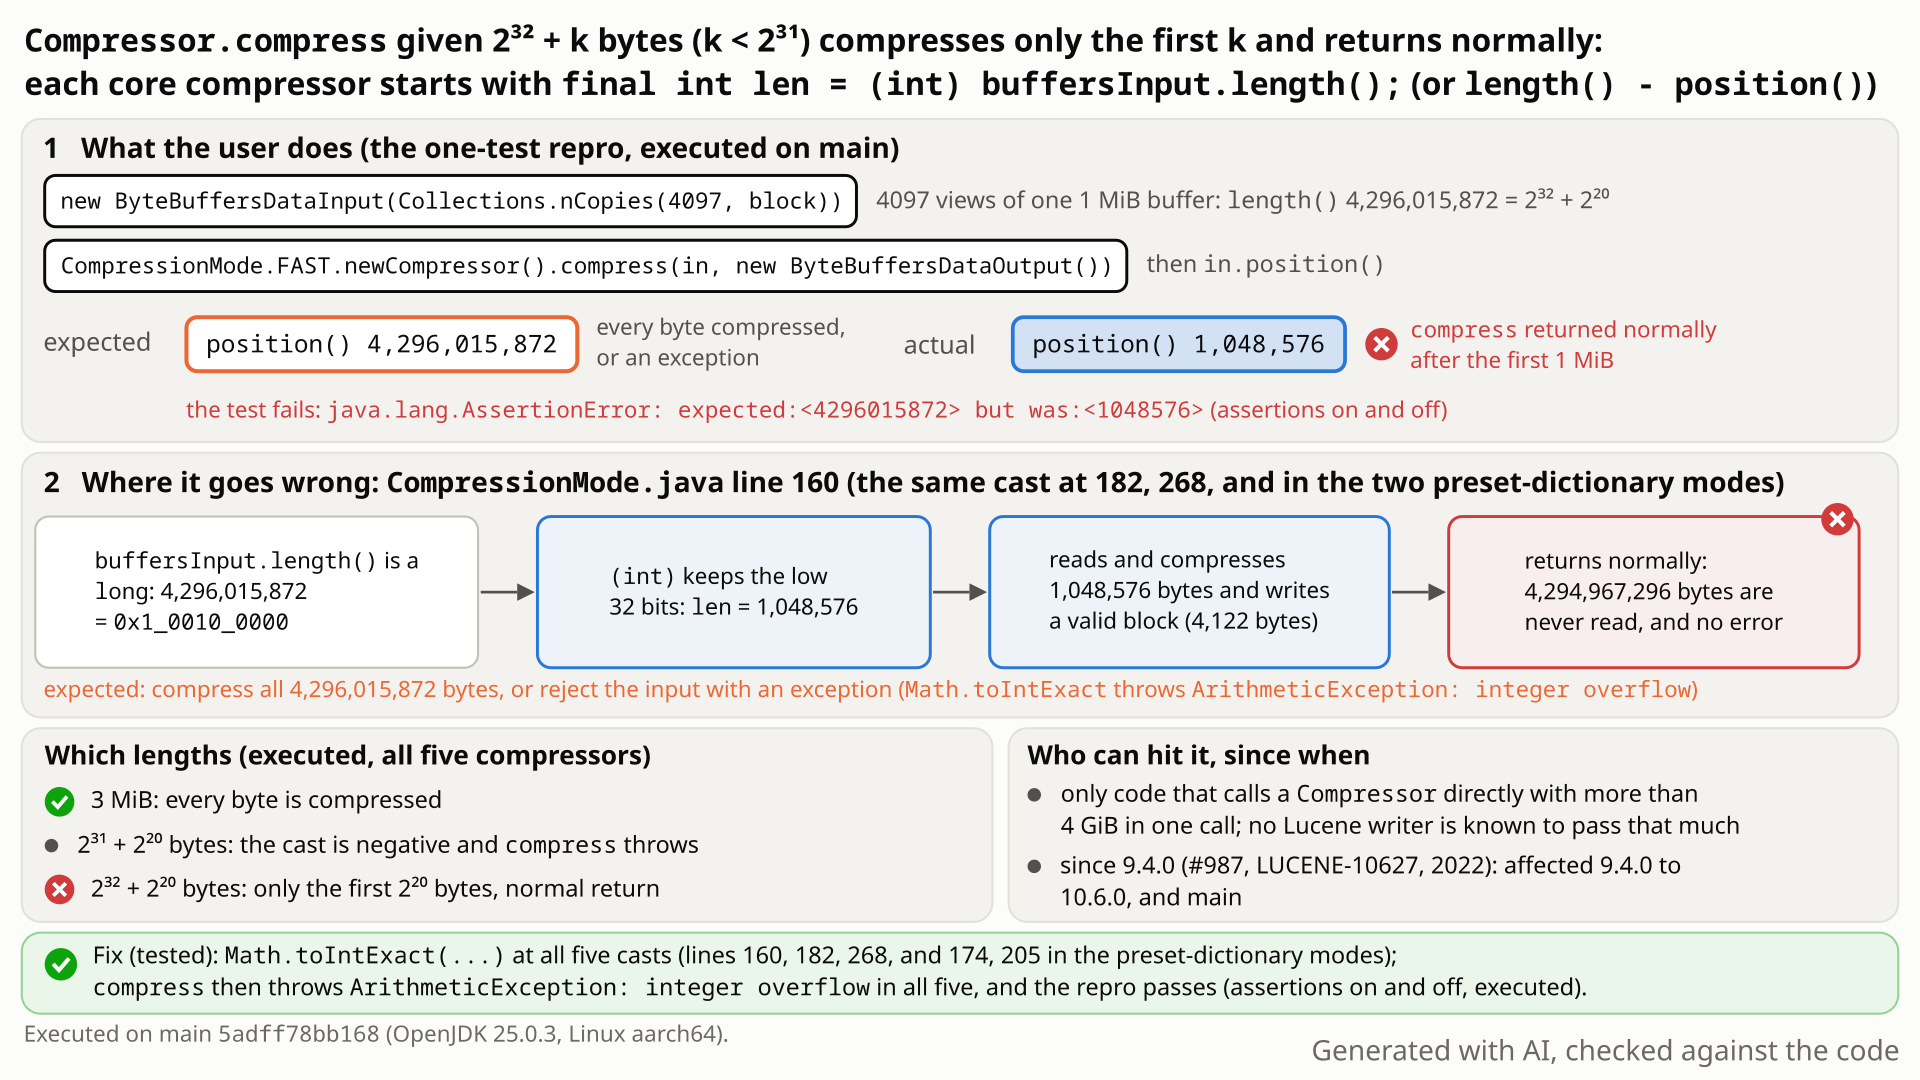
compress call on the 4,296,015,872-byte input: the (int) cast keeps only the low 32 bits, 1,048,576, so one MiB is compressed and the call returns normally; with Math.toIntExact the call throws instead. Select the still to open it at full size. Generated with AI, checked against the code.- Build a 4 GiB + 1 MiB input without using 4 GiB of memory:
new ByteBuffersDataInput(Collections.nCopies(4097, ByteBuffer.allocate(1 << 20))), 4097 views of one 1 MiB buffer, solength()is 4,296,015,872. - Compress it with
CompressionMode.FAST.newCompressor().compress(in, out). You expect all 4,296,015,872 bytes compressed, or an exception if that is too big. - Instead
compressreturns normally andin.position()is 1,048,576: one MiB was read and compressed, and the block it wrote decodes to just that MiB. All five built-in compressors do the same. - Why: each one starts with
final int len = (int) buffersInput.length();(CompressionMode.java:160). The cast keeps the low 32 bits, so 2^32 + 2^20 becomes 2^20. - One band lower fails loudly: at 2 GiB + 1 MiB the cast is negative and all five compressors throw. The pattern repeats every 2^32 bytes: when the length mod 2^32 is below 2^31 (4 GiB + 1 MiB, 8 GiB + 1 MiB) only that remainder is compressed, silently; otherwise
compressthrows, except in the last few bytes below each multiple of 2^32, where the two preset-dictionary compressors return normally having read nothing.
Only code that calls a compressor itself with one input of 2^32 + k bytes: a custom codec, plugin or application using CompressionMode.FAST, FAST_DECOMPRESSION or HIGH_COMPRESSION (experimental API) or the internal preset-dictionary modes. Lucene's stored-fields and term-vectors writers pass chunk-sized blocks and are not known to reach it. The caller gets no error and stores only a prefix.
Mechanism, terms and numbers610 words
Since 9.4.0, Compressor.compress takes a ByteBuffersDataInput, whose length() is a long and can exceed 4 GiB when the input spans many buffers. All five core compressors (CompressionMode.FAST, FAST_DECOMPRESSION, HIGH_COMPRESSION and the two preset-dictionary modes behind the stored-fields BEST_SPEED and BEST_COMPRESSION) first narrow that length with a plain (int) cast (CompressionMode.java:160, :182, :268; LZ4WithPresetDictCompressionMode.java:174; DeflateWithPresetDictCompressionMode.java:205 at 5adff78bb168). For an input of 2^32 + k bytes with k < 2^31 the cast gives k, so the compressor compresses only the first k bytes, writes a valid block for them and returns normally; this repeats every 2^32 bytes. When the length mod 2^32 is 2^31 or more the cast is negative and the call fails loudly, except in the last few bytes below a multiple of 2^32, where the two preset-dictionary compressors return normally having read nothing. No Lucene writer is known to pass more than 4 GiB to one call, so only code that calls a compressor directly is hit. Math.toIntExact at the five casts fixes it.
- Input.
ByteBuffersDataInput.length()returns along(ByteBuffersDataInput.java:206at5adff78bb168), and the constructor (:55) only requires a non-empty list, a power-of-two first page and equal-sized intermediate pages at position 0 (ensureAssumptions,:448-478), so views of one 1 MiB buffer make an input longer than 2^32 bytes without copying anything. - The cast.
LZ4FastCompressor.compress(CompressionMode.java:159-164) doesfinal int len = (int) buffersInput.length(); byte[] bytes = new byte[len]; buffersInput.readBytes(bytes, 0, len); LZ4.compress(bytes, 0, len, out, ht);.LZ4HighCompressor(:182) andDeflateCompressor(:268) start the same way; the preset-dictionary compressors computelenfromlength() - position()with the same cast (LZ4WithPresetDictCompressionMode.java:174,DeflateWithPresetDictCompressionMode.java:205) and then readlenbytes in sub-blocks. - The wrap. A
longtointcast keeps the low 32 bits. 4,296,015,872 = 2^32 + 1,048,576, solenis 1,048,576: the compressor reads one MiB, compresses it, writes a well-formed block and returns. Nothing checks that the input was consumed.
| input length | (int) gives | result |
|---|---|---|
| below 2^31 | the length | correct |
| 2^31 to 2^32 - 60 (e.g. 2,148,532,224) | negative | loud. The three CompressionMode compressors: NegativeArraySizeException. Preset-dict, assertions on: AssertionError ("size must be positive ... likely integer overflow?", ArrayUtil.growNoCopy, ArrayUtil.java:457), LZ4 before writing anything, Deflate after its 10-byte header. Preset-dict, assertions off: an out-of-bounds exception after the 10-byte header |
| 2^32 - 59 to 2^32 - 1 | -59 to -1 | the CompressionMode compressors still throw. Preset-dict from 2^32 - 18 up: silent, assertions on and off: a normal return having read nothing (dictLength and blockLength round to 0, so the sub-block loop never runs). Below that: AssertionError with assertions on; with assertions off also silent at 2^32 - 19 (both) and from 2^32 - 59 to 2^32 - 20 (Deflate; LZ4 throws) |
| 2^32 + k, 0 <= k < 2^31 (e.g. 4,296,015,872) | k | silent: only the first k bytes are compressed, normal return |
| and so on, every 2^32 bytes | the same bands repeat: 6 GiB + 1 MiB throws in all five, 8 GiB + 1 MiB is cut to its first 1 MiB in all five |
"Preset-dict" means the LZ4 and Deflate preset-dictionary compressors behind the stored-fields BEST_SPEED and BEST_COMPRESSION modes. Executed for all five compressors, assertions on and off: 3 MiB, 2,148,532,224 and 4,296,015,872 bytes (the block written in the silent case decodes to exactly the first MiB), 2^32 - 1, 2^32 - 18, 2^32 - 19, 2^32 - 20, 2^32 - 59, 2^32 - 60, 6 GiB + 1 MiB and 8 GiB + 1 MiB; the lengths in between are by reading.
Exposure and likelihood219 words
- Opt-in only.
Compressoris public with no experimental tag (Compressor.java:24-36);CompressionMode, which hands out the three standard compressors, is public and@lucene.experimental(CompressionMode.java:35); the two preset-dictionary modes are@lucene.internal(LZ4WithPresetDictCompressionMode.java:36,DeflateWithPresetDictCompressionMode.java:38). - In-tree callers (read, not proven unreachable): the only callers of
Compressor.compressin Lucene's main sources are the stored-fields writer, which bounds its buffer withMath.toIntExact(bufferedDocs.size())per document (Lucene90CompressingStoredFieldsWriter.java:191) and compresses chunk-sized slices (:255-262); the term-vectors writer flushes once a chunk reaches its chunk size (4 KiB by default,Lucene90TermVectorsFormat.java:170;Lucene90CompressingTermVectorsWriter.java:328,:379-380) and compresses at:426. Only one document with more than 4 GiB of term-vector data could come near it. The per-thread RAM hard limit (below 2048 MB,IndexWriterConfig.java:383-385) does not stop that in advance: it is checked after each document (DocumentsWriterFlushControl.java:215-251) and only marks the thread for flushing. NoIndexWriterpath is claimed. The other in-treeCompressorimplementations (SortingStoredFieldsConsumer.NO_COMPRESSION, the test framework'sDummyCompressingCodec) pass thelonglength toout.copyBytesand have no cast. - Effect. No error; the stored block holds only the first k bytes of the caller's data, and the input is left at position k.
- Scale. More than 4 GiB in one
compresscall. The recorded searches found no report since 9.4.0 (2022).
One JUnit test method on the public API: 4097 views of one 1 MiB buffer compressed with CompressionMode.FAST; it never allocates 4 GiB. Deterministic and single-threaded; the method takes about 0.02 s; it fails with assertions on and off and accepts the recommended fix's ArithmeticException.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.compressing;

import java.io.IOException;
import java.nio.ByteBuffer;
import java.util.Collections;
import org.apache.lucene.store.ByteBuffersDataInput;
import org.apache.lucene.store.ByteBuffersDataOutput;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCompressorInputOver4GiB extends LuceneTestCase {

  public void testCompressInputOver4GiB() throws IOException {
    ByteBuffer block = ByteBuffer.allocate(1 << 20);
    ByteBuffersDataInput in = new ByteBuffersDataInput(Collections.nCopies(4097, block));
    try (Compressor compressor = CompressionMode.FAST.newCompressor()) {
      compressor.compress(in, new ByteBuffersDataOutput());
    } catch (ArithmeticException ignored) {
      return;
    }
    // expected: all 2^32 + 2^20 bytes consumed (or an exception); actual: only 2^20
    assertEquals(in.length(), in.position());
  }
}
cp $REPRO/TestCompressorInputOver4GiB.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/compressing/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.compressing.TestCompressorInputOver4GiB -Ptests.seed=5EED1150 -Ptests.asserts=true
# and with -Ptests.asserts=false (assertions off)
- Expected
- All 4,296,015,872 bytes are consumed, or
compressthrows (with the fix:ArithmeticException). - Observed
compressreturns normally after 1,048,576 bytes:AssertionError: expected:<4296015872> but was:<1048576>, with assertions on and off.
More files, environment, full output149 words
The test lives in package org.apache.lucene.codecs.compressing next to the existing compression-mode tests but uses only public API. It passes when compress throws ArithmeticException (option A); with option B the catch becomes IllegalArgumentException.
Pass -Ptests.asserts explicitly: without it, Lucene's build picks assertions on or off from the seed. The result depends on neither. As a regression test, the same method can go into the existing TestFastCompressionMode, or into AbstractTestCompressionMode to cover every mode.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): this test fails; an earlier test with the same trigger also fails on 9.4.0, 9.12.3, 10.0.0 and 10.6.0 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 (nothing platform-specific) |
TestCompressorInputOver4GiB > testCompressInputOver4GiB FAILED
    java.lang.AssertionError: expected:<4296015872> but was:<1048576>
        at org.apache.lucene.codecs.compressing.TestCompressorInputOver4GiB.testCompressInputOver4GiB(TestCompressorInputOver4GiB.java:37)

# main 5adff78bb168, gradle, seed 5EED1150: the same failure with -Ptests.asserts=true and =false
# with the fix (Math.toIntExact at the five casts): BUILD SUCCESSFUL, 1 test, 0 failures, assertions on and offCompressor.compresspromises to "compress bytes intoout", states no size limit and takes an input with alonglength.- Nothing checks the range and no test comes near it; 2 GiB + 1 MiB already fails loudly.
- Even if over 2 GiB is misuse, the answer is an exception, not a normal return after compressing 1 MiB.
The full argument200 words
- Contract. "Compress bytes into
out. It is the responsibility of the compressor to add all necessary information so that aDecompressorwill know when to stop decompressing bytes from the stream." (Compressor.java:30-34). No size limit, no check at any of the five sites, no CHANGES or MIGRATE entry about one. - Tests.
AbstractTestCompressionMode.randomArrayuses at most 33 KiB (192 KiB nightly) (AbstractTestCompressionMode.java:36-39), and the largest compression test,testExtremelyLargeInput, uses 16 MiB (:158-164). Lucene's ownTestByteBuffersDataInput.testSlicingLargeBuffersbuilds aByteBuffersDataInputlonger than 4 GB by duplicating pages (:231-241), the repro's technique, so such inputs are normal objects. - History. The casts arrived in
34154736c6e(LUCENE-10627, #987), which changedcompress(byte[] bytes, int off, int len, DataOutput out)tocompress(ByteBuffersDataInput, DataOutput). The review comment on the cast line asked only "Should position() always be 0?". One week later, on #1047 (LUCENE-10661, same author and reviewer), the reviewer flagged a similarint len = (int) numBytes("We could makelena long and avoid the unchecked cast, couldn't we?") then commented "the cast is safe now because the number we're casting is guaranteed to fit in a 32-bits integer" (2022-07-27) and merged the PR right after.
The devil's-advocate check157 words
The strongest case for "intended": compressor blocks are implicitly int-sized. Decompressor.decompress takes int originalLength (Decompressor.java:42-43), the API took an int length before 9.4, and the stored-fields format "does not support documents larger than (2^31 - chunkSize) bytes" (Lucene90CompressingStoredFieldsFormat.java:36-37). So more than 2 GiB is misuse, on an experimental API with no in-tree caller that does it.
Why it fails: that limit is documented for the stored-fields format, not for Compressor, and nothing enforces it there. Read as an unstated precondition it argues for rejecting the input, as the same code already does, loudly, for most of 2^31 to 2^32 - 1 bytes (all of it in the three CompressionMode compressors); it does not justify a normal return after compressing 1 MiB of 4 GiB + 1 MiB. The experimental tag and the missing in-tree caller limit the impact, hence Low, not the intent. Verdict: an unchecked narrowing, a real Low bug.
Recommended A. Math.toIntExact at all five casts (validated)
Replace the five (int) casts with Math.toIntExact(...), so an input above 2^31 - 1 bytes throws instead of being cut. The repro passes with assertions on and off, and 145 compression-mode, stored-fields and term-vectors tests pass. Alternative: an explicit check that throws IllegalArgumentException naming the length.
-      final int len = (int) buffersInput.length();
+      final int len = Math.toIntExact(buffersInput.length());

-      final int len = (int) (buffersInput.length() - buffersInput.position());
+      final int len = Math.toIntExact(buffersInput.length() - buffersInput.position());
All options and trade-offs2 options · 376 words
Option A was applied in a scratch worktree at 5adff78bb168 and checked with gradle; option B was not built.
CompressionMode.java:160, :182, :268, LZ4WithPresetDictCompressionMode.java:174 and DeflateWithPresetDictCompressionMode.java:205: 3 files, 5 lines.
-      final int len = (int) buffersInput.length();
+      final int len = Math.toIntExact(buffersInput.length());

-      final int len = (int) (buffersInput.length() - buffersInput.position());
+      final int len = Math.toIntExact(buffersInput.length() - buffersInput.position());
Trade-offs
One comparison per compress call (per chunk), nothing per byte. Inputs above 2^31 - 1 bytes fail with ArithmeticException: integer overflow, which names no argument. For 2^31 to 2^32 - 1 bytes it replaces NegativeArraySizeException, the preset-dictionary modes' AssertionError (assertions on) or out-of-bounds exception (off), and their silent normal return just below 2^32. For inputs whose length fits in an int, the changed expressions give the same value as before. It is range hardening, not support for every int length: an input of exactly Integer.MAX_VALUE bytes still passes, and the three CompressionMode compressors then allocate an array of that size, which can fail on VM array-size or heap limits (not executed).
What the checks validated
- The repro passes with assertions on and off (gradle, seed
5EED1150). - With the fix, the five compression-mode tests,
TestCompressingStoredFieldsFormat,TestCompressingTermVectorsFormat,TestStoredFieldsIntand the threeTestLucene90StoredFieldsFormat*classes pass with assertions on (12 classes with the repro, 145 tests, 0 failures, 8 skipped: the@NightlytestLineFileDocsandtestBigDocumentsof the four stored-fields classes). :lucene:core:checkGoogleJavaFormatpasses with the fix and the test file.- A five-compressor check against the fixed classes: all five throw
ArithmeticExceptionfor 2,148,532,224- and 4,296,015,872-byte inputs, and a 3 MiB control still round-trips, so the two preset-dict sites, which the one test does not reach, are covered too. The diagram's probe adds 2^32 - 1 bytes: with the fix all five throwArithmeticExceptionthere too.
At the same five places, or once in a small helper: if (length > Integer.MAX_VALUE) throw new IllegalArgumentException("Compressor input too large: " + length + " bytes");. Either option can also add "at most Integer.MAX_VALUE bytes" to the Compressor.compress javadoc.
Trade-offs
A clearer error for a little more code; the repro's catch becomes IllegalArgumentException. Not built or tested.
A product with its own codec that hands one input of 2^32 + k bytes (k < 2^31) to these compressors would store a prefix with no error; keeping each call below 2 GiB, or checking the length first, avoids it.
A proof-obligation audit of Compressor's contract: compress must consume its whole input or fail, for every legal ByteBuffersDataInput, including ones longer than Integer.MAX_VALUE bytes. Each compressor's first line narrows the long length to int, which breaks that obligation above 4 GiB. A one-method JUnit test on the public API witnessed it.
The method in full69 words
The obligation came from Compressor.compress's javadoc and its long-length parameter type, checked against the first statement of each of the five core compressors. The witness test (an earlier one-test repro with the same trigger) fails on main with assertions on and off and on the 10.6.0 and 10.0.0 jars; a five-compressor probe showed the same silent prefix in every mode and the loud failure one band lower.
The recorded searches found no prior report in apache/lucene issues, PRs and commits (incl. the JIRA archive), the mailing lists, downstream trackers or the web (searched 2026-11-02). Nearest: #987, the change that added the casts, and #1047, where the same reviewer asked for a similar unchecked cast to be made safe.
Searches3 searches
Nearest items, none of them this bug: #987 (LUCENE-10627, origin; its review discussed position(), never the int range), #6907 (LUCENE-5845, open: an unclear exception for one stored document above the stored-fields writer's documented limit; different site, loud), #1047 (the reviewer's safe-cast request), #11726 (a dictionary-size clamp on the same path), #9671 (LUCENE-8625, an earlier int narrowing inside ByteBuffersDataInput, fixed as a bug), #13286 (renamed size() to length() on the cast lines) and the open, stale #12948, which edits the cast lines but keeps the casts.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive) | 2026-11-02; re-checked the same day | two scripted prior-report searches (102 queries over GitHub, commits, lists, JIRA and the web) and about 30 manual searches: CompressionMode, the five compressor class names, buffersInput, toIntExact, ByteBuffersDataInput overflow / 4GB, compress truncated; git log -S'(int) buffersInput' | no report; #987, #6907, #1047, #11726, #9671, #13286 are context |
| Open PRs | 2026-11-02 | the changed files of all 409 open apache/lucene PRs | #12948 touches the cast lines and keeps the casts; others touch the preset-dict files on the decompress side only |
| Mailing lists, downstream, web | 2026-11-02 | dev@, java-user@, issues@, commits@; Solr, Elasticsearch, OpenSearch; web searches | nothing about this narrowing |
Introduced by LUCENE-10627 (#987, 34154736c6e, 2022), which changed the compressor input to ByteBuffersDataInput; first released in 9.4.0. 9.4.0, 9.12.3, 10.0.0, 10.6.0 and main fail; 9.3.0 lacks the API. Not fixed upstream.
Versions tested4 rows
34154736c6e "LUCENE-10627: Using ByteBuffersDataInput reduce memory copy on compressing data (#987)" (luyuncheng, 2022-08-01 UTC, merged by jpountz; branch_9x 2b75fe6d200) replaced compress(byte[], int, int, DataOutput) with compress(ByteBuffersDataInput, DataOutput) and added the cast at all five compressors; before it the int length was in the signature, so no longer input could reach a compressor. #13286 (66b121f9b0f, 2024-04-11) renamed size() to length() on the cast lines and kept the casts. The release runs used an earlier one-test repro with the same trigger (on 9.4.0 with size() for length(), the only accessor before 9.9.0). Upstream main 1c2072f0284 (2026-11-02) still has the casts.
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | gradle: fails with assertions on and off (1,048,576 of 4,296,015,872 bytes); passes with the fix |
| 10.6.0, 10.0.0, 9.12.3 | affected | fails, same numbers |
| 9.4.0 | affected | fails with assertions on and off (first release with the casts) |
| 9.3.0 | no API | compress takes (byte[], int, int, DataOutput); the test does not compile |
An independent reproducer, two executed cross-model reviews (OpenAI GPT-5.6, real, high), a devil's-advocate verifier (real, medium) and an adjudication (confirmed, Low) agree, and separate re-runs reproduced it. This doc's gradle run reproduced it on main and validated the fix at all five sites.
Checks and verdicts240 words
The cross-model reviews ran their Java on main ea57360912ed, whose fix-site files are byte-identical to 5adff78bb168's; their tests were re-run on 5adff78bb168 and 10.6.0.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Own test fails on main (assertions on and off), 10.6.0, 10.5.2 and 9.12.3; 2^31 + 2^20 bytes gives NegativeArraySizeException; a 3 MiB control is fully consumed. |
| cross-model reviews, refute and intended lenses (OpenAI GPT-5.6, executed) | real (high) | Own test: 65,536 of 4,295,032,832 bytes consumed, normal return; the same wrapped prefix in all five compressors; Math.toIntExact rejects the input while a normal-size control still compresses fully. |
| devil's-advocate verifier | real, medium | Steelmanned the implicit int-sized block, the experimental tag and unreachability; only the impact limit survives. |
| adjudication and separate re-runs | confirmed, Low | Re-runs fail on main with assertions on and off and pass with the fix; it is not a loud failure, because 2^32 + k returns normally. |
| this doc's fix check | reproduced; option A validated | Gradle in a scratch worktree at 5adff78bb168: the repro fails without and passes with option A; 145 tests in 12 related classes pass; all five compressors now throw for oversized inputs. |
| fact checks of this doc (one by a reviewer from another model family) | real; option A works | Re-ran the repro and the fix; corrected how the length bands, the title and a few references were described. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 477 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,370 words
- Registry title
- Compressor.compress casts ByteBuffersDataInput.length() to int, so an input of 2^32 + k bytes is compressed as only its first k bytes and the call returns normally
- Area
- codecs / compressing (Compressor.compress in CompressionMode FAST, FAST_DECOMPRESSION, HIGH_COMPRESSION and the Lucene90 preset-dict compressors)
- Priority
- Low, rank 976: A Compressor given more than 4 GiB in one call silently compresses only the first (length mod 2^32) bytes and returns normally, in every release since 9.4.0. It needs extreme input size on an expert compression API that no in-tree caller is known to reach, so it is contrived.
- Impact class
- minor
- Impact note
- Only code that calls a Compressor directly (CompressionMode.FAST / FAST_DECOMPRESSION / HIGH_COMPRESSION, @lucene.experimental, or the @lucene.internal preset-dict modes) with more than 4 GiB of input in one call is hit, and then silently: compress returns normally after compressing only the length mod 2^32 prefix, while inputs of 2^31 to 2^32 - 1 bytes fail loudly (NegativeArraySizeException or an out-of-bounds exception); no in-tree caller is known to reach it (the stored-fields writer guards its buffer with Math.toIntExact and compresses chunk slices; term vectors would need one document with more than 4 GiB of buffered term-vector data, not proven impossible, read only); every release from 9.4.0 to 10.6.0 and main.
- Summary
- You build a valid ByteBuffersDataInput of 2^32 + k bytes (here 4097 views of one 1 MiB buffer, so nothing is copied) and call CompressionMode.FAST.newCompressor().compress(in, out); you expect the whole input to be compressed, or an exception if it is too large. Instead compress returns normally after reading and compressing only the first k bytes (1 MiB of 4,296,015,872), leaving the input positioned at k, and the block it wrote decodes to just that prefix. All five core compressors start with 'final int len = (int) buffersInput.length()' (or length() - position() in the preset-dict modes), and for a length of 2^32 + k that cast yields k.
- Introduced
- 34154736c6ed241d7d9d0c6f4a0e6419936490b7 (LUCENE-10627, apache/lucene#987 'Using ByteBuffersDataInput reduce memory copy on compressing data', author luyuncheng, merged by jpountz; branch_9x copy 2b75fe6d2005785e5214364a0563fdcba5d66c50) [read: its diff changes Compressor.compress(byte[], int, int, DataOutput) to compress(ByteBuffersDataInput, DataOutput) and adds the (int) cast at all five compressors; git log -S'(int) buffersInput' finds only this commit; #13286 (66b121f9b0f, 2024-04-11) later renamed size() to length() on the cast lines and kept the casts. exec: 9.3.0 lacks the API, so the repro does not compile there; 9.4.0 fails with -ea and -da] (2022-08-01 (author date 2022-08-02 00:34:41 +0800, that is 2022-08-01 16:34 UTC; merged 2022-08-01; branch_9x commit 2022-08-01))
- First affected version
- 9.4.0 [exec: fails with -ea and -da; 9.3.0 has no compress(ByteBuffersDataInput, DataOutput), so the repro does not compile there and no longer-than-int input can reach a compressor]
- Affected versions
- 9.4.0 to 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main 5adff78bb168 (12.0.0-SNAPSHOT). Executed, fail [exec]: main with -ea and -da (finder, the independent reproduction, the intended-behaviour check, judge and the registration check), 10.6.0 (-ea: finder, the independent reproduction, history step and the GPT reviewer's test re-run; -da: the intended-behaviour check), 10.5.2, 10.0.0 (finder, history step), 9.12.3 (the independent reproduction, history step) and 9.4.0 (-ea and -da, with the test's two length() calls written as size(), the only length accessor before 9.9.0). Not affected: 9.3.0 and older (the API is absent). The other releases by reading: no commit between 9.4.0 and 10.6.0 changes the casts beyond the size() to length() rename. Not new in 10.6 (since 9.4.0). Not fixed upstream: upstream main 1c2072f0284 (2026-11-02) still has the three casts in CompressionMode.java (lines 160, 182, 268). All runs on Linux aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (2026-11-02, on top of the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches; rechecked the same day): two scripted prior-report searches (102 queries over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web) plus the intended-behaviour check's own scripted search (24 mailing-list queries), 19 manual GitHub issue and PR searches, 2 commit searches, 7 manual JIRA-archive queries, 4 manual list queries, downstream searches (Elasticsearch, OpenSearch, Solr), web searches, and a scan of the changed files of all 409 open apache/lucene PRs: #12948 (open, stale) edits the five cast lines but only renames size() to length() and keeps the casts; #16791, #16836, #16660, #14397 and #1003 touch the preset-dict modes on the decompress side only. Hits are context only: #987 (LUCENE-10627, the introducing PR; its review discussed position(), never the int range), #6907 (LUCENE-5845, open since 2014: an unclear exception for one stored document above the stored-fields writer's documented limit; different site, loud failure), #11726 (dictionary-size clamp on the same term-vector compress path), #1047 (the #987 reviewer asking for a safe cast of the same kind elsewhere), #9671 (LUCENE-8625, an earlier int narrowing inside ByteBuffersDataInput, fixed), #13286 (the rename). Re-check the same day: GitHub searches 'CompressionMode toIntExact', 'Compressor compress truncated', 'compress 4GB int cast' and 'CompressionMode' or 'compressing' updated since 2026-10-31 return nothing new; the newest PRs (#16956-#16966) touch no compressing file; the newest upstream commits on the fix-site files are 66b121f9b0f (author date 2024-04-11) and, for Compressor.java, 34154736c6e; upstream main 1c2072f0284 still has the casts. Not fixed anywhere.
- Lucene commit tested
- main
5adff78bb168(12.0.0-SNAPSHOT): gradle in a scratch worktree for this doc (the repro fails with assertions on and off and passes withMath.toIntExactat the five casts; with the fix 12 compression-mode, stored-fields and term-vectors test classes, 145 tests, pass, the formatter check passes, and all five compressors reject 2,148,532,224- and 4,296,015,872-byte inputs while a 3 MiB control round-trips). Earlier runs of an earlier one-test repro with the same trigger fail on 9.4.0, 9.12.3, 10.0.0, 10.6.0 and main; 9.3.0 lacks the API.
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/compressing/CompressionMode.java:160, (at 5adff78bb168) :182, :268 ('final int len = (int) buffersInput.length();' then new byte[len] and readBytes(bytes, 0, len)), lucene/core/src/java/org/apache/lucene/codecs/lucene90/LZ4WithPresetDictCompressionMode.java:174 and lucene/core/src/java/org/apache/lucene/codecs/lucene90/DeflateWithPresetDictCompressionMode.java:205 ('final int len = (int) (buffersInput.length() - buffersInput.position());'), lucene/core/src/java/org/apache/lucene/codecs/compressing/Compressor.java:30-36 ('Compress bytes into out'; no size bound)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsWriter.java:191 (at 5adff78bb168) (Math.toIntExact(bufferedDocs.size())), :259, :262 (chunk-slice compress); lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:328, :379-380 (flush once a chunk reaches chunkSize); lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java:383-385 (per-thread RAM hard limit below 2048 MB) [read]
- The finding in 30 seconds
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/compressing/CompressionMode.java:159-164, :181-186, :267-271 ('final int len = (int) buffersInput.length();' then new byte[len] and readBytes(bytes, 0, len))Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/LZ4WithPresetDictCompressionMode.java:174 and DeflateWithPresetDictCompressionMode.java:205 ('final int len = (int) (buffersInput.length() - buffersInput.position());')Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/store/ByteBuffersDataInput.java:55 (constructor over a List<ByteBuffer>), :206 ('public long length()'), :448-478 (ensureAssumptions)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/LZ4WithPresetDictCompressionMode.java:174-190 and DeflateWithPresetDictCompressionMode.java:205-224 (dictLength, blockLength, ArrayUtil.growNoCopy, the 'start < len' loop); lucene/core/src/java/org/apache/lucene/util/ArrayUtil.java:457 (the 'size must be positive' assert)
- Who is affected
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/compressing/Compressor.java:24-36 (public, no @lucene.experimental tag)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/compressing/CompressionMode.java:35 ('@lucene.experimental')Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/LZ4WithPresetDictCompressionMode.java:36, DeflateWithPresetDictCompressionMode.java:38 ('@lucene.internal')Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsWriter.java:191, :255-262Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:328, :379-380, :426; codecs/lucene90/Lucene90TermVectorsFormat.java:170 (CompressionMode.FAST, chunk size 1 << 12)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java:383-385 (per-thread hard limit below 2048 MB)Lucene main 5adff78bb168: grep of '.compress(' in lucene/core, lucene/codecs and lucene/backward-codecs src/java (the two writers above are the only Compressor callers)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/DocumentsWriterFlushControl.java:215-251 (doAfterDocument; the hard-limit check at :247), DocumentsWriter.java:434Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/SortingStoredFieldsConsumer.java:42-55; lucene/test-framework/src/java/org/apache/lucene/tests/codecs/compressing/dummy/DummyCompressingCodec.java:76-85 (out.copyBytes(buffersInput, buffersInput.length()))
- Why it looks unintended
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/compressing/Compressor.java:30-36Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/compressing/Decompressor.java:28-43 ('int originalLength')Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsFormat.java:36-37Lucene main 5adff78bb168: lucene/core/src/test/org/apache/lucene/codecs/compressing/AbstractTestCompressionMode.java:36-39, :158-164; lucene/core/src/test/org/apache/lucene/store/TestByteBuffersDataInput.java:231-241GitHub apache/lucene#987 review comments (jpountz 2022-07-19 on DeflateWithPresetDictCompressionMode.java: 'Should position() always be 0?'; luyuncheng 2022-07-20 reply)GitHub apache/lucene#1047 reviews on BytesStore.java (jpountz 2022-07-26 and 2022-07-27; all the reviews in COMMENTED state, merged by jpountz on 2022-07-27 right after the last comment)
- Diagrams
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/compressing/CompressionMode.java:160
- TestCompressorInputOver4GiB.java (one test, public API):
repro/LFV-1150/TestCompressorInputOver4GiB.java(39 lines)
One diagram of the repro's path, made separately; its notes are in the diagram directory.
assets/LFV-1150/bug.png(477 KB)