- An analyzer turns a field's text into a TokenStream. Each token carries attributes: the term, its position increment (1 = the next position; 2 = one position skipped, for example by a removed stop word) and its offsets. When the stream ends, it reports a final increment and offset for what it skipped at the end.
- Attribute objects come from an AttributeFactory. You can give a tokenizer your own, for example
new StandardTokenizer(factory). IndexWriter then asks the stream to add the attributes it needs that the tokenizer did not create, such asTermFrequencyAttribute, and the stream asks the factory. - An analyzer hands back the same reused TokenStream object (per thread) each time. To save work, IndexWriter keeps, for each field, the stream it last read and handles to that stream's attributes, and skips the lookup when the same stream object comes back.
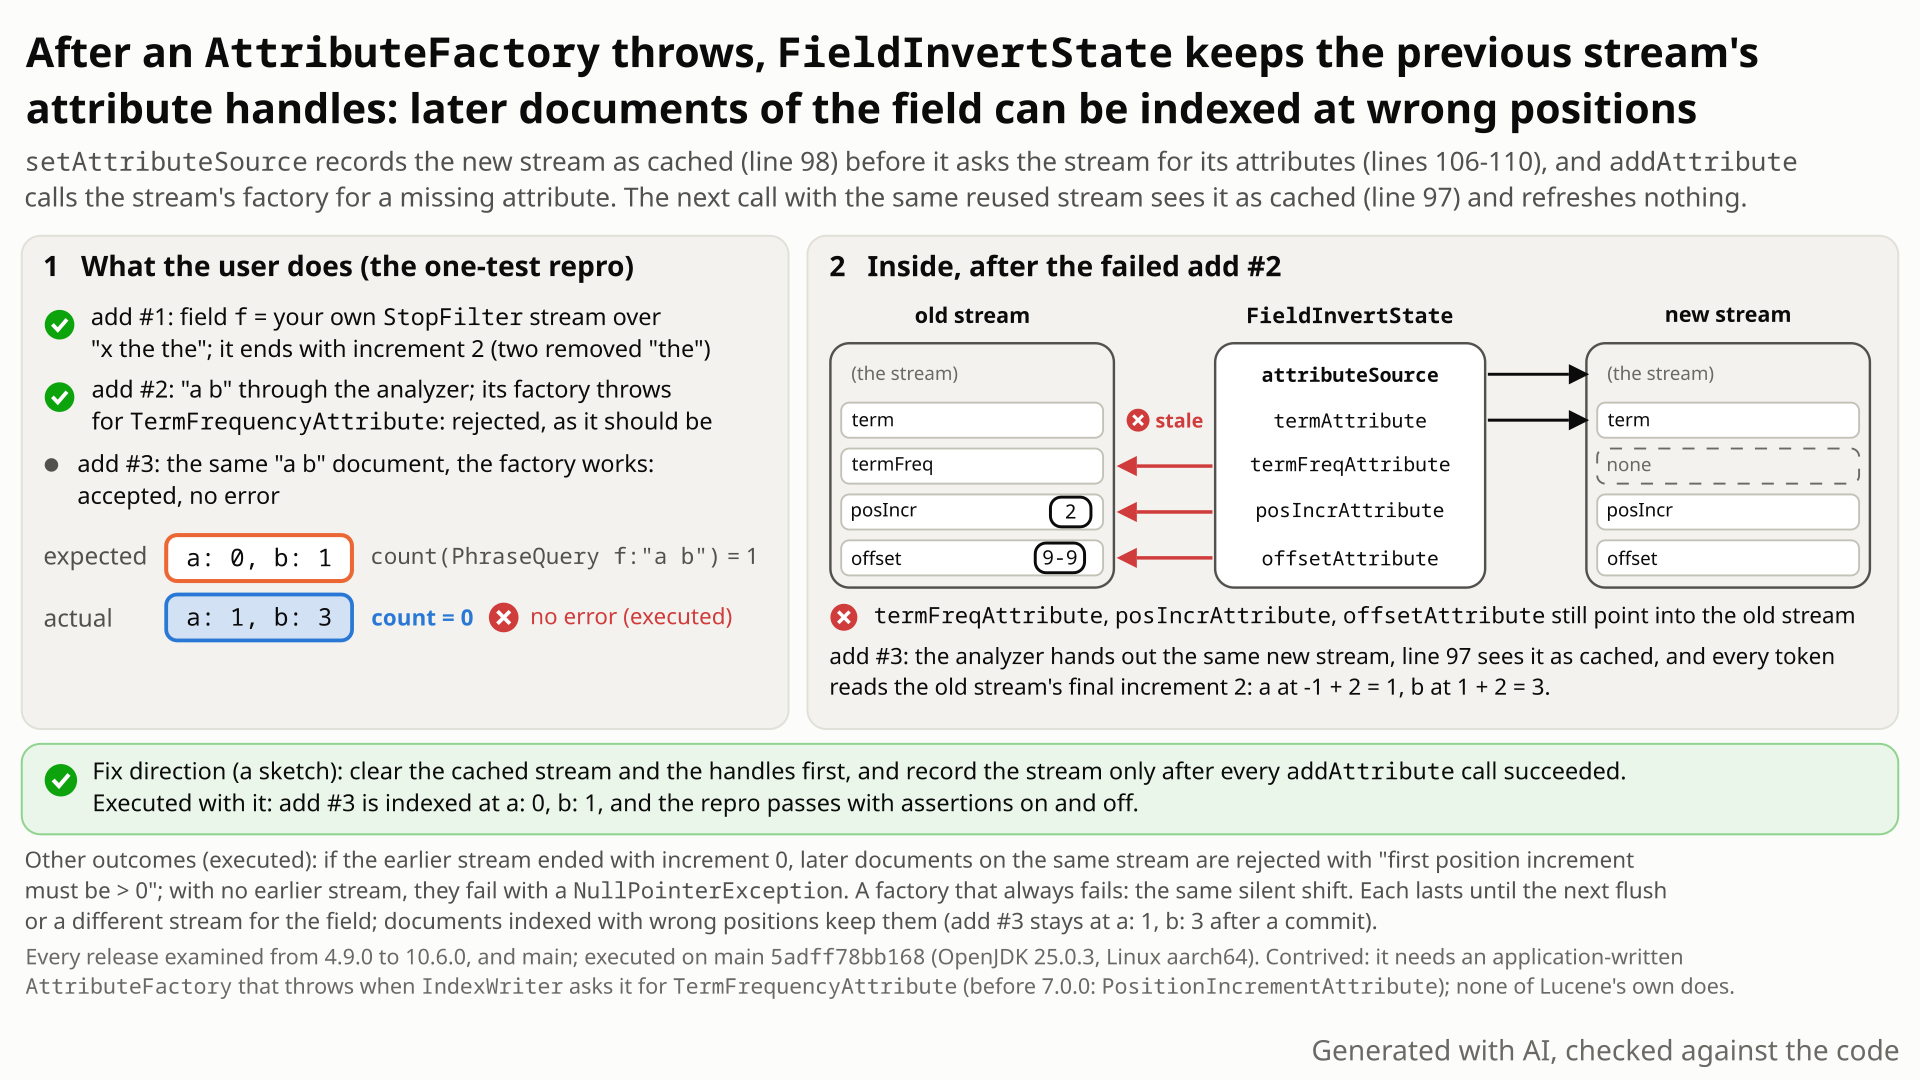
"a b" lands at positions 1 and 3. Select the still to open it at full size. Generated with AI, checked against the code.- Add a document whose field
fis your own TokenStream,StopFilter(StandardTokenizer("x the the")). The two removed stop words leave a final position increment of 2 at the end of the stream. - Add
"a b"through an analyzer whoseStandardTokenizer(factory)uses your AttributeFactory, which throws once when IndexWriter asks it forTermFrequencyAttribute.addDocumentthrows and the document is dropped, as expected. - Add the same
"a b"again; the factory works now. You expectaat position 0 andbat 1, soPhraseQuery f:"a b"finds 1 document, as it does without the failure. - Instead it is accepted at positions 1 and 3 and the phrase finds 0 documents, with no error (with offsets indexed: 9-9 for both tokens, not 0-1 and 2-3). IndexWriter had cached the analyzer's stream before fetching its attributes, so it keeps reading the first stream's frozen values for every document that gets that stream back, until the next flush; the documents mis-indexed meanwhile keep their wrong positions.
Applications whose tokenizer uses their own AttributeFactory that throws when IndexWriter asks it for TermFrequencyAttribute (one built on the default packed token factory is never asked). No non-test factory in Lucene throws there. The silent case needs the cache to hold another stream's handles, in the repro an earlier document's own TokenStream. Every release examined since 4.9.0.
Mechanism, terms and numbers687 words
For each field, FieldInvertState caches the TokenStream it last inverted together with handles to that stream's attributes, and skips the lookup when the same stream object comes back, which is the normal case because an analyzer hands back the same reused TokenStream object (per thread) each time. setAttributeSource stores the new stream as the cached identity first (FieldInvertState.java:98 at 5adff78bb168) and only then calls addAttribute for TermFrequencyAttribute, PositionIncrementAttribute and OffsetAttribute (:107-109), which asks the stream's AttributeFactory for any attribute the stream lacks. If that factory throws, IndexWriter rejects the document as a non-aborting exception, as documented, but the cache now names the analyzer's stream while the frequency, position, offset and payload handles still belong to the previous stream of that field. Every later document of the field in the same in-memory segment that gets the same stream back reuses those handles, until the next flush or until the field inverts a different TokenStream object, and the documents mis-indexed in that window keep their wrong positions: after a pre-analyzed value that ended in two removed stop words, "a b" is indexed at positions 1 and 3 instead of 0 and 1 and PhraseQuery f:"a b" finds nothing, with no error. With no earlier stream, later documents fail with a NullPointerException instead. Every release examined since 4.9.0 (2014) has it. The trigger is an application-written factory that throws, which no non-test factory in Lucene's source does, so the priority is Low.
- Getting the stream.
IndexingChain.java:1981callsfield.tokenStream(analyzer, tokenStream): for a string value that is the analyzer's reused stream (analysis/Analyzer.java:183-195,document/Field.java:493-498), for a TokenStream value the field's own stream.:1984callsinvertState.setAttributeSource(stream). - The identity is stored first (the fix site).
FieldInvertState.java:97compares the stream with the cached one;:98stores the new stream;:106refreshestermAttribute;:107callsaddAttribute(TermFrequencyAttribute.class).StandardTokenizercreates its term, offset, position-increment and type attributes itself (analysis/standard/StandardTokenizer.java:140-144) but not the frequency attribute, soAttributeSource.addAttributeasks the factory (util/AttributeSource.java:218), which throws.:108-110never run. - The document is rejected, the cache is not. The exception is non-aborting: only this document is marked deleted (
DocumentsWriterPerThread.java:392-398; the runs show the rejection with the writer still open). Left behind: identity = the analyzer's stream B,termAttribute= B's, buttermFreqAttribute,posIncrAttribute,offsetAttributeandpayloadAttribute= the first document's stream A, whoseend()left increment 2 and offsets 9-9 (analysis/FilteringTokenFilter.java:72-74,analysis/standard/StandardTokenizer.java:178-184). A probe that reads this state by reflection on main prints exactly that. - Later documents read the old values. The next document gets the same stream B;
:97sees the cached identity and returns early. Every token reads A's frozen values:IndexingChain.java:1996(increment 2) and:2035-2036(offsets 9-9). Fromposition = -1(FieldInvertState.java:84),alands at 1 andbat 3. - Until the next flush, or a different stream. There is one
FieldInvertStateper field per in-memory segment, that is perDocumentsWriterPerThread(IndexingChain.java:1416,:1905-1909). A different TokenStream object for the field fails the identity check at:97and refreshes the handles (executed: a document with its own stream"c d"between the failure and the next"a b"givesPhraseQuery f:"a b"count 1). After a commit the next document is indexed correctly, but the document mis-indexed before it keeps positions 1 and 3 (executed).
| earlier stream of the field in this segment | factory fails once | factory always fails |
|---|---|---|
| own TokenStream ending with increment 2 or more (stop words) | later documents accepted with wrong positions (silent) | the same (silent) |
own TokenStream ending with increment 0 ("x y") | later documents rejected: "first position increment must be > 0 (got 0)" | not run |
| none | later documents rejected: NullPointerException (this.invertState.posIncrAttribute is null, IndexingChain.java:1996) | the same |
"Later documents" means later documents of the field that get the same stream back. Not run: an earlier stream whose end() leaves increment exactly 1 (one trailing removed stop word); by reading (FilteringTokenFilter.java:72-74), positions then come out right and only the offsets are stale.
Exposure and likelihood260 words
- Who. An analyzer whose tokenizer was built with an application-written AttributeFactory that throws when IndexWriter requests
TermFrequencyAttribute(before 7.0.0:PositionIncrementAttribute), once or always. - Reach limits (by reading). The factory is asked only for an attribute the stream does not have yet (
AttributeSource.java:209-221). A factory built on the packed token factory, the default, is never asked here, becausePackedTokenAttributeImplalready implements all three attributes (PackedTokenAttributeImpl.java:29-40); one that creates a separate implementation per attribute, as one built onAttributeFactory.DEFAULT_ATTRIBUTE_FACTORYdoes (the repro's), is asked forTermFrequencyAttribute. No non-test AttributeFactory in the Lucene source at5adff78bb168throws for these attributes (the default ones inAttributeFactory.javaand the two collation factories). The silent variant also needs the field's cache to hold another stream's handles when the factory fails: in the repro, an earlier document in the same in-memory segment that passed its own TokenStream for that field (by reading, another thread's analyzer stream used earlier in the same pooled in-memory segment would do the same; not run). - Effect. Silent wrong positions (phrase, span and interval queries miss the documents) and wrong offsets (highlighting), or later documents of the field rejected with a misleading error. New documents are affected until the next flush or until the field inverts a different TokenStream object; the documents already indexed with wrong positions keep them after the flush (executed). The failing document itself is handled correctly.
- Scale. Three small documents, one thread. Likelihood contrived: no matching public report was found in the documented searches, although every release examined since 4.9.0 (2014) has it.
One JUnit test method on the public API: three documents on one writer, no flush, then one PhraseQuery count. Deterministic and single-threaded; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.StringReader;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.StopFilter;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.standard.StandardTokenizer;
import org.apache.lucene.analysis.tokenattributes.TermFrequencyAttribute;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.PhraseQuery;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.Attribute;
import org.apache.lucene.util.AttributeFactory;
import org.apache.lucene.util.AttributeImpl;

public class TestFieldInvertStateAttributeFactoryFailure extends LuceneTestCase {

  public void testFactoryFailureDoesNotShiftLaterPositions() throws Exception {
    AttributeFactory factory =
        new AttributeFactory() {
          boolean failed;

          @Override
          public AttributeImpl createAttributeInstance(Class<? extends Attribute> attClass) {
            if (attClass == TermFrequencyAttribute.class && failed == false) {
              failed = true;
              throw new IllegalStateException("transient factory failure");
            }
            return AttributeFactory.DEFAULT_ATTRIBUTE_FACTORY.createAttributeInstance(attClass);
          }
        };
    Analyzer analyzer =
        new Analyzer() {
          @Override
          protected TokenStreamComponents createComponents(String fieldName) {
            return new TokenStreamComponents(new StandardTokenizer(factory));
          }
        };
    try (Directory dir = newDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
      Tokenizer tokenizer = new StandardTokenizer();
      tokenizer.setReader(new StringReader("x the the"));
      Document doc0 = new Document();
      doc0.add(new TextField("f", new StopFilter(tokenizer, StopFilter.makeStopSet("the"))));
      w.addDocument(doc0);
      Document doc = new Document();
      doc.add(new TextField("f", "a b", Field.Store.NO));
      expectThrows(IllegalStateException.class, () -> w.addDocument(doc));
      w.addDocument(doc);
      try (DirectoryReader r = DirectoryReader.open(w)) {
        // expected: the re-added "a b" is at positions 0,1 and matches; actual: positions 1,3, 0 hits
        assertEquals(1, new IndexSearcher(r).count(new PhraseQuery("f", "a", "b")));
      }
    }
    analyzer.close();
  }
}
cp $REPRO/TestFieldInvertStateAttributeFactoryFailure.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestFieldInvertStateAttributeFactoryFailure -Ptests.seed=DEADBEEF
# and with -Ptests.asserts=false: the same failure
- Expected
PhraseQuery f:"a b"counts 1: the re-added document is at positions 0 and 1.- Observed
expected:<1> but was:<0>: the document is accepted at positions 1 and 3, with no error and the writer still open.
More files, environment, full output282 words
TestFieldInvertStateAttributeFactoryFailure (one method, extends LuceneTestCase, package org.apache.lucene.index of the lucene/core tests, public API only). Document 1 is a TextField whose value is StopFilter(StandardTokenizer("x the the")); document 2 is "a b" through an analyzer whose StandardTokenizer(factory) throws IllegalStateException the first time TermFrequencyAttribute is requested (expectThrows); document 3 is the same "a b" document. The test asserts that PhraseQuery f:"a b" counts 1.
The result does not depend on the seed: this file fails with expected:<1> but was:<0> on main with DEADBEEF (assertions on and off), 5EEDF151 and A0D17001 (on) and 5EEDF152 (off), and on the 9.1.0, 9.12.3, 10.5.2 and 10.6.0 release jars. The comment line is 102 columns, so checkGoogleJavaFormat flags it and wraps its last word (formatting only). As the regression test, the same method fits in TestFieldInvertState or TestIndexWriterExceptions.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): fails; 9.1.0, 9.12.3, 10.5.2, 10.6.0: the same test fails; 4.9.0, 4.10.4, 5.5.5, 6.6.6, 7.0.0, 7.7.3, 8.11.4: an era-adapted probe fails; 4.8.1: clean |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestFieldInvertStateAttributeFactoryFailure.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestFieldInvertStateAttributeFactoryFailure -Ptests.seed=DEADBEEF
# gradle, scratch worktree at 5adff78bb168, -Ptests.seed=DEADBEEF -Ptests.asserts=false (assertions on: the same assertion at the same line)
TestFieldInvertStateAttributeFactoryFailure > testFactoryFailureDoesNotShiftLaterPositions FAILED
    java.lang.AssertionError: expected:<1> but was:<0>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:B9F9175C71685E69]:0)
        ...
        at org.apache.lucene.index.TestFieldInvertStateAttributeFactoryFailure.testFactoryFailureDoesNotShiftLaterPositions(TestFieldInvertStateAttributeFactoryFailure.java:72)
BUILD FAILED

# with fix A: BUILD SUCCESSFUL with assertions on and off

# postings of the accepted "a b" document, offsets indexed (state probe, assertions off)
main:            PhraseQuery f:"a b" count=0 | a pos 1 off 9-9 | b pos 3 off 9-9
main with fix A: PhraseQuery f:"a b" count=1 | a pos 0 off 0-1 | b pos 1 off 2-3- IndexWriter's code says a document hit by a non-aborting exception is added "all or none" and an analysis failure "won't cause the DWPT to be stale".
- LUCENE-1072's test throws from a TokenStream, then: "Make sure we can add another normal document".
- A 2014 refactor moved the cache's stream store from last to first; no review comment discusses that order.
The full argument203 words
- Contract.
DocumentsWriter.java:76-79: after a non-aborting exception "we immediately mark the document as deleted so that the document is always atomically ("all or none") added to the index."DocumentsWriterPerThread.java:392-398: an exception during analysis "causes the doc to be rejected but won't cause the DWPT to be stale".IndexingChain.java:1988-1994says the same for an exception in the token loop ("in stream.next below"); this throw comes just before that loop, fromsetAttributeSourceat:1984, and the runs show it is handled the same way.IndexWriter.java:1465: "if an Exception is hit ... the index will be consistent". - Tests.
TestIndexWriterExceptions.testExceptionFromTokenStream(LUCENE-1072,:493-494) throws from a TokenStream, then: "Make sure we can add another normal document" (:541). - History. The cache came with LUCENE-5611 (#6673). Its first, inline form in
DefaultIndexingChain.invertstored the identity as its last statement (67ebc26fa97, kept byf0414ff3af7). After the review request "Can we factor this into FieldInvertState?" (Robert Muir on #6673),e7b59c5a211moved the block into the setter with the identity first; no comment in the thread discusses the setter's order or a throw from its lookups (its commit notices about non-aborting exceptions concern other code). The parent commit does not reproduce;e7b59c5a211does (executed).
The devil's-advocate check187 words
The strongest case for "not a bug": a throwing AttributeFactory is a broken component. The factory javadoc names only UndeclaredThrowableException and says "attributes should not throw or declare checked exceptions" (AttributeFactory.java:28-35), and #9656 (LUCENE-8610), an NPE from the same cache, was closed Not A Bug as the tokenizer's fault.
Why it fails: that javadoc sentence is about attribute constructors, and createAttributeInstance is a public extension point that IndexWriter itself calls. In #9656 the stream broke the TokenStream contract by adding attributes lazily; here every stream follows the contract, and the failure is reported to the caller, who then continues as LUCENE-1072's test does. IndexWriter documents that such a failure drops one document, not that it changes how later ones are indexed. No javadoc explicitly promises isolation after a throwing AttributeFactory, so the case is that the behaviour is inconsistent with the non-aborting design above, not that it breaks an explicit contract. That bears on likelihood, which is why the priority is Low, not on intent. A credibility audit anticipated the "broken component" objection and still kept the finding, with its small fix and single test.
Recommended Clear the cache first, publish the stream last (fix A)
In FieldInvertState.setAttributeSource, clear the cached stream and handles first and store the stream only after every addAttribute call has succeeded (+9/-8 lines). The repro passes with assertions on and off, and 78 tests of the closest suites pass; the same-stream fast path is unchanged.
      // clear the identity first, so that a failing addAttribute below leaves no stale handles
      this.attributeSource = null;
      termAttribute = null;
      termFreqAttribute = null;
      posIncrAttribute = null;
      offsetAttribute = null;
      payloadAttribute = null;
      if (attributeSource != null) {
        termAttribute = attributeSource.getAttribute(TermToBytesRefAttribute.class);
        termFreqAttribute = attributeSource.addAttribute(TermFrequencyAttribute.class);
        posIncrAttribute = attributeSource.addAttribute(PositionIncrementAttribute.class);
        offsetAttribute = attributeSource.addAttribute(OffsetAttribute.class);
        payloadAttribute = attributeSource.getAttribute(PayloadAttribute.class);
        this.attributeSource = attributeSource;
All options and trade-offs3 options · 448 words
Fix A was built and checked through gradle on 5adff78bb168; B passed the independent reproducer's own test; C was not built.
After a failure the next call with the same stream fetches the handles again: a factory that failed once now works, and one that always fails rejects every document loudly instead of mis-indexing them.
      // clear the identity first, so that a failing addAttribute below leaves no stale handles
      this.attributeSource = null;
      termAttribute = null;
      termFreqAttribute = null;
      posIncrAttribute = null;
      offsetAttribute = null;
      payloadAttribute = null;
      if (attributeSource != null) {
        termAttribute = attributeSource.getAttribute(TermToBytesRefAttribute.class);
        termFreqAttribute = attributeSource.addAttribute(TermFrequencyAttribute.class);
        posIncrAttribute = attributeSource.addAttribute(PositionIncrementAttribute.class);
        offsetAttribute = attributeSource.addAttribute(OffsetAttribute.class);
        payloadAttribute = attributeSource.getAttribute(PayloadAttribute.class);
        this.attributeSource = attributeSource;
Trade-offs
The fast path (same stream, :97) is unchanged; a new stream costs six extra null stores (the identity and the five handles). No handle of the previous stream survives a failed call.
What the checks validated
- Gradle in a scratch worktree at
5adff78bb168, seedDEADBEEF: the repro fails without the fix (assertions on and off) and passes with it (on and off). - With the fix:
TestFieldInvertState(2),TestIndexWriterExceptions(40, 3 skipped),TestIndexWriterExceptions2(1),TestDocumentWriter(15),TestPostingsOffsets(12),TestPayloads(7) and the repro: 78 tests, 0 failures.checkGoogleJavaFormatflags only the repro's comment line. The full core suite was not run. - Earlier, a separate re-run with the same change passed; the cross-model reviewers' equivalent change passed
TestFieldInvertStateandTestIndexWriterExceptions2(refute lens) andTestFieldInvertStateandTestIndexWriterExceptions.testAddDocsNonAbortingException(intended lens).
Only set the identity to null first and to the stream last (fix B; validated only on a reproducer's test, not recommended as is)
Two lines: this.attributeSource = null; before the lookups, this.attributeSource = attributeSource; after them.
Trade-offs
It leaves the previous stream's handles in place after a failure while the cached identity is null, and by reading one path still reads them: a later non-tokenized (TERM) value of the same field calls setAttributeSource(null) (IndexingChain.java:2146), which then returns early, and FreqProxTermsWriterPerField.start copies termFreqAttribute (:78-80). The field schema compares index options, not tokenization (IndexingChain.java:2278-2288), so for a field without positions that sequence is accepted. Not run. A clears the handles and has no such gap.
What the checks validated
Passed the independent reproducer's own test (expected:<0> but was:<1> without it); not run through gradle.
As the cache's original inline form did.
Trade-offs
After a failure the identity keeps the previous stream while termAttribute already points at the new one, so if that previous stream object is passed again, its term attribute is wrong. Not built.
Downstream, a search product that loads outside analysis plugins could index a field's later documents with wrong positions and offsets after one plugin's attribute factory fails; those documents stay wrong in the index, and new ones are indexed correctly again after the next flush. The factory is passed only the attribute class, never the document text.
A proof-obligation audit of FieldInvertState.setAttributeSource's failure atomicity: a failed call must not leave a cache that a later call with the same stream relies on. The stream is stored before the lookups that can throw; a public-API JUnit test then witnessed the wrong positions.
The method in full118 words
Method: semi-formal (a proof-obligation audit of a class's contract, witnessed by an executable repro).
- The finder checked
setAttributeSourceagainst the obligation that a call which throws leaves no cache a later call with the same source relies on. The identity is assigned at:98, before theaddAttributecalls at:107-109, which reach the user's AttributeFactory. - The finder then wrote the public-API JUnit test (positions 1 and 3 instead of 0 and 1), two probes (the positions, and the
NullPointerExceptionvariant with no earlier stream) and the fix that makes the test pass. - An independent reproducer, two executed cross-model reviews, a devil's-advocate verifier and an adjudication reproduced it with their own tests ("Prior reports, history and checks").
No matching prior report found in apache/lucene issues, PRs and commits (incl. the JIRA archive), the mailing lists, downstream trackers or the web (searched 2026-11-02). Nearest: #9656 (LUCENE-8610, closed Not A Bug), the same cache with a different trigger; its patch would not fix this.
Searches3 searches
No matching public report was found in the documented searches. Nearest items, none a report of this bug: #9656 (LUCENE-8610, 2018: a stream that added attributes lazily, against the TokenStream contract, got a null termAttribute cached; closed Not A Bug), #6673 (LUCENE-5611, origin), #8905 (LUCENE-7854) and #12139 (later edits of the setter), #10080 (LUCENE-9037) and #16553 (same class, other code). Limits: keyword search; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive) | 2026-11-02 | a scripted prior-report search of 51 queries (459 hits, one high-overlap: #9656) and 33 manual searches: method and field names, error messages, "stale attribute(s)", activity since 2026-10-31 | no report; #9656 is the nearest |
| Open PRs | 2026-11-02 | the changed files of all 409 open apache/lucene PRs | none touches FieldInvertState.java; five touch IndexingChain.java without changing the attribute handling |
| Mailing lists, JIRA, downstream, web | 2026-11-02 | dev@, java-user@, issues@ and commits@ over their full history and the last 30 days, extra JIRA queries, Elasticsearch, OpenSearch, Solr and Lucene.NET trackers, 14 web queries | nothing about this bug |
Introduced by LUCENE-5611 (e7b59c5a211, 2014-04-28) and first released in 4.9.0; 4.8.1 and the parent commit are clean. Every release run since then fails, through 10.6.0 and main. Not fixed upstream.
Versions tested5 rows
Introduced by e7b59c5a2115 "LUCENE-5611: move attribute juggling to a fieldinvertstate setter" (Robert Muir, 2014-04-28, on an svn feature branch before GitHub PRs; the issue is migrated as #6673), merged to trunk (f5de5d01e81) and branch_4x (eb045b5a853) on 2014-04-29 by Michael McCandless. Before it, 4.8.1 fetched the attributes for every field instance with no cross-document cache.
TermFrequencyAttribute arrived in 7.0.0 (LUCENE-7854, d276acfbbcb); on 4.9.0 to 6.6.6 the same root cause is reached when the factory fails PositionIncrementAttribute (executed). cce33b07e4f (#12139, 2023) added the null branch and kept the order. By reading, all 106 release tags from 4.9.0 to 10.6.0 in the history clone have the identity-first setter; the clone has no 8.x tags after 8.8.1 (8.11.4 was run from its release jar), and releases in neither set are inferred. Upstream main 1c2072f0284 (2026-11-02) and branch_10_6 still store the identity first.
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | gradle: fails with assertions on and off; passes with fix A |
| 9.1.0, 9.12.3, 10.5.2, 10.6.0 | affected | this JUnit fails (expected:<1> but was:<0>) |
| 4.9.0 (also -da), 4.10.4, 5.5.5, 6.6.6, 7.0.0, 7.7.3, 8.11.4 | era-adapted probe | a@1, b@3 instead of a@0, b@1 |
| 4.8.1 | not affected | no attribute cache: a@0, b@1 |
e7b59c5a211 vs its parent f0414ff3af7 | bisect | the introducing commit reproduces; its parent does not |
A finder, an independent reproducer, two executed cross-model reviews (OpenAI GPT-5.6, both real, high), a devil's-advocate verifier, an adjudication, an audit and a final repro check reproduced it. This doc's gradle runs reproduced it on main and validated fix A.
Checks and verdicts226 words
The cross-model reviews ran on the older main ea57360912ed; FieldInvertState.java, AttributeSource.java and AttributeFactory.java are identical there, and IndexingChain.java differs only outside inversion (#16734). Every other check ran on 5adff78bb168 or release jars.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Repro fails on main (assertions on and off), 10.6.0 and 9.12.3; probes show a@1, b@3 and the NullPointerException variant; the fix passes. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Own test: first position 3 instead of 0 (on, off, a second seed); control passes; the fix passes it, TestFieldInvertState and TestIndexWriterExceptions2. "Genuine but highly contrived." |
| independent reproducer | real | Own test fails on main (on, off), 10.6.0, 10.5.2 and 9.12.3; control and own fix pass; an always-failing factory also mis-indexes. |
| cross-model review, intended lens (OpenAI GPT-5.6, executed) | real (high) | NullPointerException variant on main and 10.6.0, recovery after a commit; the fix passes its test, TestFieldInvertState and TestIndexWriterExceptions.testAddDocsNonAbortingException. |
| devil's-advocate verifier | real | The "broken component" case is rejected; every variant was run. |
| adjudication, separate re-runs, audit and final repro check | confirmed, Low | Re-runs on main fail with assertions on and off and pass with the fix; one minimal deterministic test. |
| this doc | reproduced; fix A validated | Gradle without the fix fails (on, off); with it, 78 tests of 7 suites pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 530 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,632 words
- Registry title
- When an AttributeFactory throws while IndexWriter adds TermFrequencyAttribute, FieldInvertState keeps the previous stream's attribute handles, so later accepted documents of that field are indexed with the wrong positions and offsets until the next flush
- Area
- index / IndexingChain inversion (FieldInvertState.setAttributeSource attribute cache)
- Priority
- Low, rank 676: After an application-written AttributeFactory throws while IndexWriter adds its attributes, later documents of that field in the same in-memory segment can be indexed silently with wrong positions and offsets, in every release since 4.9.0. No stock factory throws there, and the silent case also needs an earlier stream that ended with skipped positions, so the trigger is contrived.
- Impact class
- minor
- Impact note
- Hits only applications whose analyzer's tokenizer uses their own AttributeFactory built on the one-implementation-per-attribute default (AttributeFactory.DEFAULT_ATTRIBUTE_FACTORY, not the packed token factory) that throws when IndexWriter requests TermFrequencyAttribute, once or always; otherwise default IndexWriterConfig, codec and ordinary scale: the failing document is rejected as it should be, but later documents of the same field in the same in-memory segment are then accepted with the previous TokenStream's final position increment and offsets (silent: phrase, span and interval queries miss them) when an earlier document supplied its own TokenStream for that field ending with an increment of 2 or more (for example trailing stop words), or are all rejected with the misleading 'first position increment must be > 0' (earlier stream ending with increment 0) or a NullPointerException (no earlier stream), until the next flush; every release from 4.9.0 to 10.6.0 and main.
- Summary
- You add a document whose field value is your own TokenStream ending in two removed stop words ('x the the' through StopFilter), then a document whose analysis fails because your analyzer's AttributeFactory throws when IndexWriter asks for TermFrequencyAttribute, then the plain-text document 'a b' through the same analyzer with the factory working again. You expect the failed document to be dropped and 'a b' to be indexed at positions 0 and 1, as it is without the failure. Instead 'a b' is accepted at positions 1 and 3 and PhraseQuery f:"a b" finds nothing, with no error, because FieldInvertState.setAttributeSource recorded the analyzer's reused stream as cached before it fetched that stream's attributes, so every later document of the field keeps reading the first stream's position increment (frozen at 2) until the next flush.
- Introduced
- e7b59c5a2115678ccf258d36f22d909144398834 'LUCENE-5611: move attribute juggling to a fieldinvertstate setter' (Robert Muir, GitHub rmuir; svn r1590747 on the lucene5611 feature branch; JIRA-patch era, no GitHub PR; the issue is migrated as apache/lucene#6673), merged to trunk in f5de5d01e810 and to branch_4x in eb045b5a8537 ('LUCENE-5611: simplify the default indexing chain', Michael McCandless). It moved the inline attribute cache of DefaultIndexingChain.invert, which stored the stream identity as its last statement (67ebc26fa97, kept by f0414ff3af7), into FieldInvertState.setAttributeSource and made the identity assignment the first statement, done as a review cleanup ('Can we factor this into FieldInvertState?', rmuir on #6673) with no discussion of exceptions [exec: commit-level A/B on source builds: the parent f0414ff3af7 does not reproduce, e7b59c5a211 reproduces; release pair 4.8.1 not reproduced, 4.9.0 reproduced]. Later edits kept the order: d276acfbbcb (LUCENE-7854, #8905, 7.0.0) added the TermFrequencyAttribute lookup that the one-test repro fails, and cce33b07e4f (#12139, 2023) added the null branch. (2014-04-28 (author and commit date of e7b59c5a211, 18:55:37Z); merged to trunk 2014-04-29T17:18:41Z and branch_4x 2014-04-29T21:46:51Z; first release 4.9.0 (tag commit dated 2014-06-24))
- First affected version
- 4.9.0 [exec: the history probe reproduces on 4.9.0 with -ea and -da; 4.8.1, the last release before LUCENE-5611, has no attribute cache and does not reproduce]
- Affected versions
- Every release from 4.9.0 through 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main 5adff78bb168 (12.0.0-SNAPSHOT); never fixed. [exec, JDK 25] The one-test JUnit, unchanged, fails on 9.1.0, 9.12.3 and 10.6.0 and on main with -ea and -da (it needs the test framework of 9.1.0 and later); the independent reproduction's own test fails on main (-ea, -da), 10.6.0, 10.5.2 and 9.12.3; the follow-up's main() probe (same scenario in one API spelling per era) reproduces on 4.9.0 (-ea and -da), 4.10.4, 5.5.5, 6.6.6, 7.0.0, 7.7.3, 8.11.4, 9.12.3, 10.6.0 and main (-ea and -da) and does not on 4.8.1 or on the parent commit f0414ff3af7. The exact trigger of the repro (the factory fails the TermFrequencyAttribute request) exists from 7.0.0 (LUCENE-7854); on 4.9.0 to 6.6.6 the same root cause is reached through the PositionIncrementAttribute request with a tokenizer that does not add that attribute itself [exec, probes]. Releases between executed ones: by reading, all 106 release tags from 4.9.0 to 10.6.0 in the history clone have the identity-first setter (the clone has no 8.x tags after 8.8.1; the executed 8.11.4 jar reproduces). Not new in 10.6 (10.5.2 and older fail). Not fixed upstream: upstream main 1c2072f02843 (2026-11-02) and branch_10_6 still assign the identity at FieldInvertState.java:98 before the addAttribute calls, and the file's last upstream commit is cce33b07e4f (#12139, author date 2023-02-21) [read through the GitHub API, 2026-11-02].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (2026-11-02, on top of the finder's 25-query scripted prior-report search and the independent reproduction's, the intended-behaviour check's and the adjudication's GitHub searches; rechecked the same day): a scripted prior-report search over 51 queries (16 GitHub issue and PR, 3 commit, 2 downstream, 20 mailing-list over the full dev@, java-user@, issues@ and commits@ history, 4 JIRA-archive, 6 web; 459 distinct hits, 1 high: #9656), 33 manual GitHub searches (method and field names, error messages, 'stale attribute(s)', open-PR filters, activity since 2026-10-31, Elasticsearch, OpenSearch, Solr, lucene-solr and Lucene.NET), five extra JIRA queries, 16 list queries over the last 30 days, 8 web queries, and the changed-file lists of all 409 open apache/lucene PRs (none touches FieldInvertState.java; #16116, #16269, #15330, #13525 and #13342 touch IndexingChain.java without changing the attribute handling): no report that a throw inside FieldInvertState.setAttributeSource (an AttributeFactory failure) leaves stale or null attribute handles that later documents of the field reuse. Nearest, not the same bug: #9656 (LUCENE-8610, 2018, closed Not A Bug: the same identity cache caches a null termAttribute when a TokenStream adds attributes lazily against the TokenStream contract; its patch moved the setter call and would not fix this), #6673 (LUCENE-5611, origin), #8905 (LUCENE-7854) and #12139 (later edits of the setter), #10080 (LUCENE-9037) and #16553 (same class, other code). Same-day recheck: GitHub search on apache/lucene for setAttributeSource (3 old hits: #9656, #5707, #3385), FieldInvertState and AttributeFactory updated since 2026-11-01 (0), posIncrAttribute updated since 2026-10-31 (0), and the 5 PRs created on 2026-11-02 (#16962-#16966, unrelated); upstream FieldInvertState.java unchanged since cce33b07e4f (2023-02-21). Not fixed upstream.
- Lucene commit tested
- main
5adff78bb168(2026-11-02) through gradle in a scratch worktree with assertions on and off, without and with fix A (the repro, 7 closest suites,checkGoogleJavaFormat), and standalone on the main jars with seedsDEADBEEF,5EEDF151,5EEDF152andA0D17001(all fail). The same test fails on the 9.1.0, 9.12.3, 10.5.2 and 10.6.0 release jars. The hunt ran an era-adaptedmain()probe on 4.8.1 (clean), on 9 releases from 4.9.0 to 10.6.0 (all fail), on the introducing commit (fails) and on its parent (clean). Only Linux aarch64 with OpenJDK 25.0.3 was run.
- Finding record
lucene/core/src/java/org/apache/lucene/index/FieldInvertState.java:96-113 (at 5adff78bb168) (setAttributeSource: identity check :97, new identity stored :98, then getAttribute(TermToBytesRefAttribute) :106 and addAttribute for TermFrequencyAttribute/PositionIncrementAttribute/OffsetAttribute :107-109, which reach the AttributeFactory; a throw leaves the identity new and those handles old or null: fix site)lucene/core/src/java/org/apache/lucene/util/AttributeSource.java:209-221 (at 5adff78bb168) (addAttribute calls factory.createAttributeInstance for a missing attribute, :218); lucene/core/src/java/org/apache/lucene/util/AttributeFactory.java:28-35 (public abstract createAttributeInstance; only UndeclaredThrowableException documented)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1981-1984 (at 5adff78bb168) (field.tokenStream(analyzer, tokenStream) returns the analyzer's reused stream; invertState.setAttributeSource(stream)), :1988-1994 (comment: an analysis exception is non-aborting and only this document is marked deleted), :1996-1997 and :2035-2036 (posIncrAttribute and offsetAttribute read for every token: the stale handles), :1903-1909 (one FieldInvertState per field per DWPT, so the stale cache lives until the next flush)lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:76-79 (at 5adff78bb168) (non-aborting exceptions: 'the document is always atomically ("all or none") added'); DocumentsWriterPerThread.java:392-398 (an analysis exception rejects the document but 'won't cause the DWPT to be stale'); IndexWriter.java:1465 (addDocument: 'the index will be consistent'); lucene/core/src/test/org/apache/lucene/index/TestIndexWriterExceptions.java:494, :541 (testExceptionFromTokenStream, 'Make sure we can add another normal document')
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/FieldInvertState.java:84 (at 5adff78bb168) (reset: position = -1), :96-113 (setAttributeSource: identity check :97, identity stored :98, lookups :106-110; fix site)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1416, (at 5adff78bb168) :1905-1909 (one FieldInvertState per field per in-memory segment), :1981-1984 (stream, setAttributeSource), :1988-1994 (non-aborting comment, for an exception in the token loop), :1996, :2035-2036 (handles read per token)lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:183-195 (at 5adff78bb168) (reused components); document/Field.java:493-498 (TokenStream value or analyzer stream); analysis/standard/StandardTokenizer.java:140-144, :178-184 (own attributes; end()); analysis/FilteringTokenFilter.java:72-74 (end(): skipped positions); util/AttributeSource.java:209-221 (addAttribute asks the factory, :218)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:392-398 (at 5adff78bb168) (analysis exception rejects the document only)
- Who is affected
lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/PackedTokenAttributeImpl.java:29-40 (at 5adff78bb168) (implements PositionIncrement, Offset and TermFrequency attributes); util/AttributeFactory.java:28-35; util/AttributeSource.java:209-221lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThreadPool.java:31-41, (at 5adff78bb168) :115-126 (pooled DWPTs, assignments may differ from document to document); analysis/Analyzer.java:93-99, :468-480 (per-thread reuse)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:76-79; (at 5adff78bb168) index/DocumentsWriterPerThread.java:392-398; index/IndexingChain.java:1988-1994; index/IndexWriter.java:1465; util/AttributeFactory.java:28-35lucene/core/src/test/org/apache/lucene/index/TestIndexWriterExceptions.java:493-494, (at 5adff78bb168) :541 (LUCENE-1072)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/FieldInvertState.java:96-113; (at 5adff78bb168) index/IndexingChain.java:1984-1985; index/FreqProxTermsWriterPerField.java:78-80 (handles copied after setAttributeSource); index/IndexingChain.java:2127-2149 (TERM path: setAttributeSource(null) at :2146), :2278-2288 (FieldSchema.setIndexOptions: index options compared, not tokenization)
- Diagrams
lucene/core/src/java/org/apache/lucene/index/FieldInvertState.java:96-113; (at 5adff78bb168) index/IndexingChain.java:1996
- TestFieldInvertStateAttributeFactoryFailure.java (lucene/core, package org.apache.lucene.index, 1 test):
repro/LFV-1154/TestFieldInvertStateAttributeFactoryFailure.java(77 lines)
The diagram illustrates the repro's three documents and the state that a probe dumps on main after the failed call (FieldInvertState.java:97-110, IndexingChain.java:1996).
assets/LFV-1154/bug.png(530 KB)