The constructor checks the value as a chunk count (at least 1), but the writer uses it as a block shift (2 to 22). The two meanings disagree for 1 and for every value from 23 up, and nothing notices until the first flush.
- The compressing term vectors format compresses the term vectors of several documents together into chunks. A small index records where each chunk starts (its first document and its file position).
- That index is written in blocks of chunks. The format's last constructor argument sets the block size. Since 8.5.0 it is given as the exponent of a power of two (the log in base 2 of the chunk count): the stock format passes 10, meaning 2^10 = 1024 chunks per block.
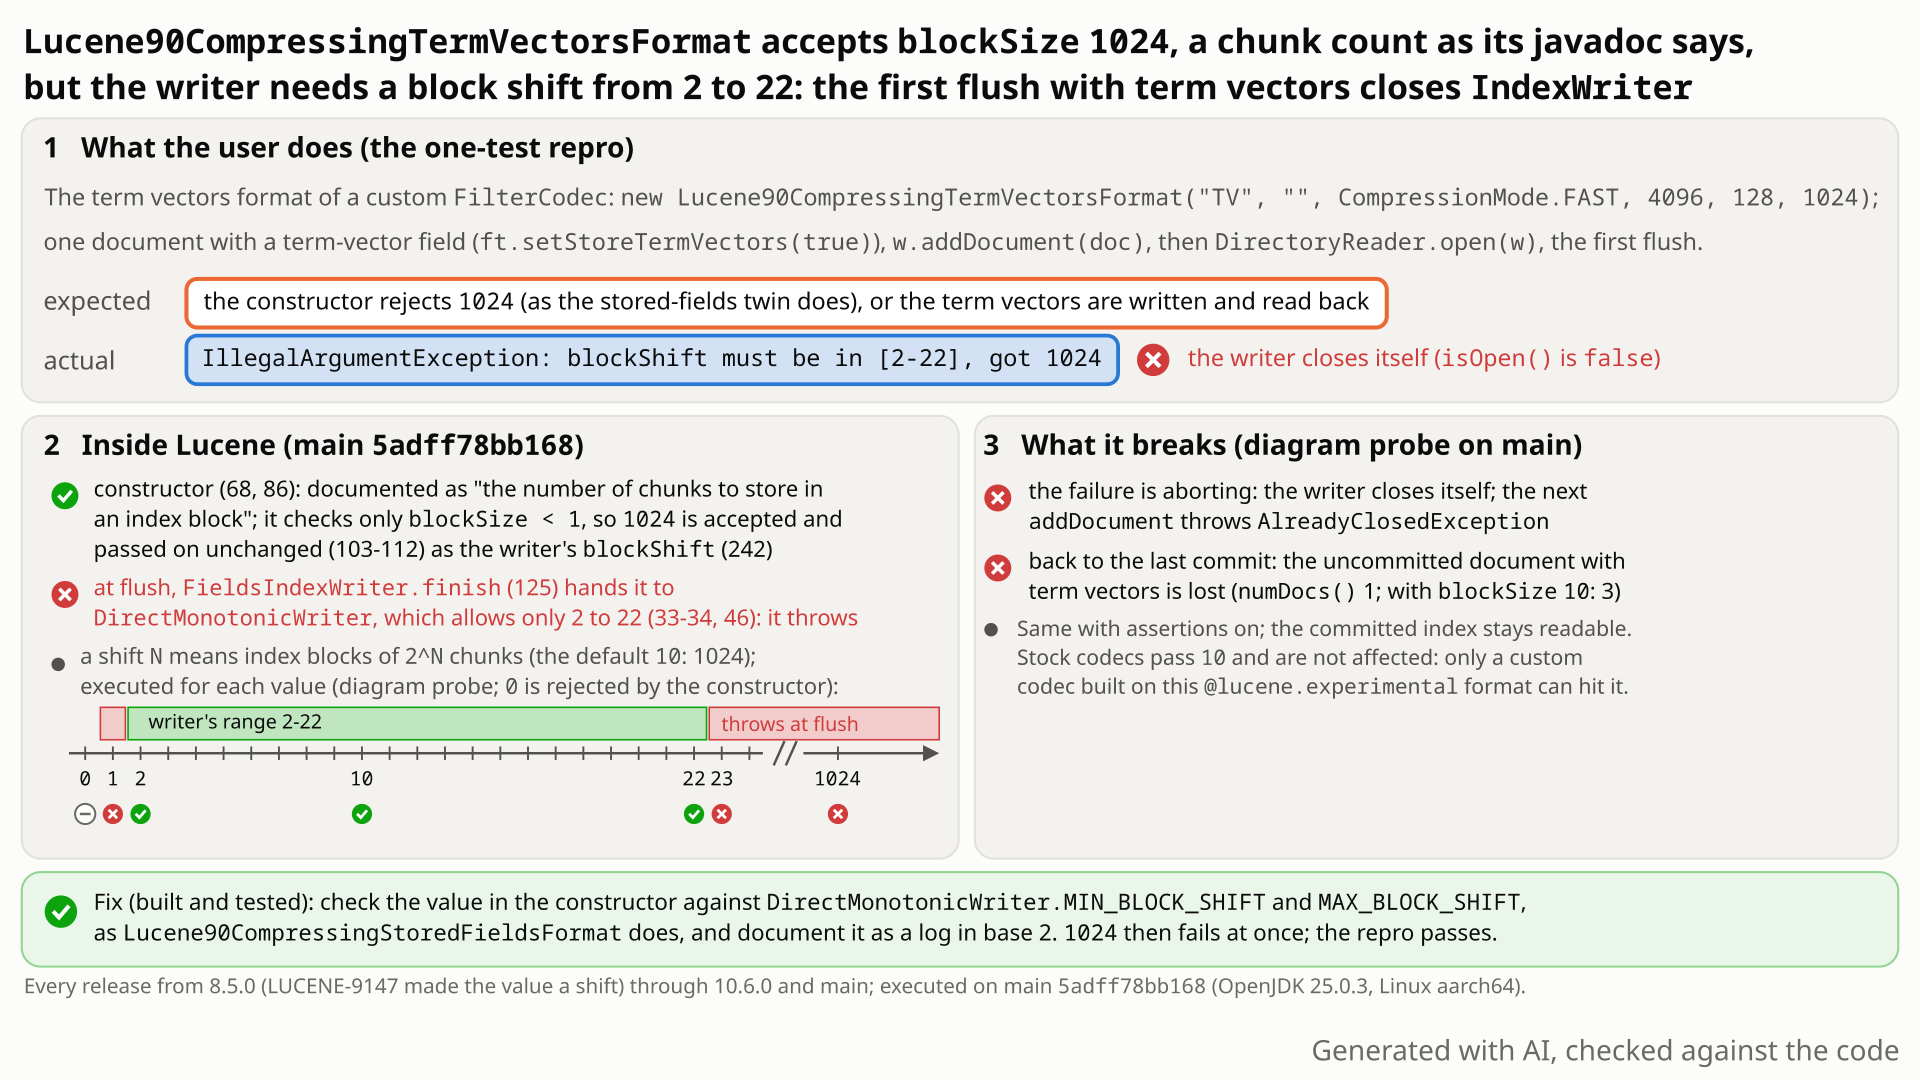
- You build a custom codec with
new Lucene90CompressingTermVectorsFormat("TV", "", CompressionMode.FAST, 4096, 128, 1024): 1024 chunks per index block, as the javadoc describes the last argument ("the number of chunks to store in an index block"). - You expect the constructor to reject 1024, as the stored-fields twin
Lucene90CompressingStoredFieldsFormatdoes, or the format to work. It only checksblockSize >= 1, so it accepts 1024, andaddDocumentsucceeds. - But since 8.5.0 the writer reads the value as a shift: the stock format passes 10, meaning 2^10 = 1024 chunks. Your 1024 means 2^1024, and the chunk-index encoder (
DirectMonotonicWriter) allows only shifts 2 to 22 (4 to 4,194,304 chunks). - The first flush of a segment with term vectors (here
DirectoryReader.open(writer)) throwsIllegalArgumentException: blockShift must be in [2-22], got 1024. The IndexWriter closes and documents added since the last commit are lost; the last commit stays intact. blockSize 1, the constructor's own minimum, fails the same way.
Only applications whose custom codec builds this experimental format with 1 or a value from 23 up, such as a chunk count or 1024 (the stock value up to 8.4.1). Stock codecs pass 10 and are fine. The failure is loud but late: at the first flush, closing the writer and dropping uncommitted documents.
Mechanism, terms and numbers599 words
Lucene90CompressingTermVectorsFormat's last constructor argument, blockSize, is documented as "the number of chunks to store in an index block", and the constructor rejects only values below 1. Since 8.5.0 the writer uses the value as a DirectMonotonicWriter block shift, the log in base 2 of the chunk count, and DirectMonotonicWriter accepts only 2 to 22. So a custom codec that passes a chunk count such as 1024 (the value the stock format passed up to 8.4.1), or 1 (the constructor's own minimum), builds fine and, in the repro, addDocument returns, but the first flush of a segment with term vectors throws IllegalArgumentException: blockShift must be in [2-22], got 1024 and the IndexWriter closes itself, losing the documents added since the last commit.
The stored-fields twin, Lucene90CompressingStoredFieldsFormat, got exactly the missing range check and a "log in base 2" javadoc in the same change that made the value a shift (LUCENE-9147, 2020); the term vectors format file was not part of that change. Stock codecs pass 10 and are not affected; the committed index stays intact, and nothing returns wrong results.
- The constructor documents and checks a count.
codecs/lucene90/compressing/Lucene90CompressingTermVectorsFormat.java:68:@param blockSize the number of chunks to store in an index block.;:86-88: the only check,if (blockSize < 1) throw new IllegalArgumentException("blockSize must be >= 1"). This is the fix site. The class is@lucene.experimental(:35). - The value goes on unchanged, as a shift.
vectorsWriter(:100-113) passes it as the last argument ofLucene90CompressingTermVectorsWriter, whose parameter is namedblockShift(Lucene90CompressingTermVectorsWriter.java:242), and that hands it tonew FieldsIndexWriter(..., blockShift, context)(:281-289). - Nothing checks it until the segment is finished. At flush,
TermVectorsConsumer.flushcallswriter.finish(index/TermVectorsConsumer.java:85), which callsFieldsIndexWriter.finish(Lucene90CompressingTermVectorsWriter.java:725). That writes the shift into the meta file (FieldsIndexWriter.java:116) and callsDirectMonotonicWriter.getInstance(metaOut, dataOut, totalChunks + 1, blockShift)(:125). DirectMonotonicWriteraccepts only 2 to 22.util/packed/DirectMonotonicWriter.java:33-34(MIN_BLOCK_SHIFT = 2,MAX_BLOCK_SHIFT = 22);:46-54throwsIllegalArgumentException("blockShift must be in [2-22], got " + blockShift).- Outcome. The exception escapes a segment flush, which
IndexWritertreats as aborting: the writer closes (isOpen() == false) and documents added since the last commit are lost; the last commit stays readable, and a new writer with the same codec fails the same way at its next flush with term vectors (all executed). Any flush of such a segment fails, soaddDocumentitself throws when it triggers an automatic flush (index/DocumentsWriter.java:450,:400-404), and a merge that writes term vectors with this codec reaches the samefinish(index/SegmentMerger.java:170-171,:261-267;Lucene90CompressingTermVectorsWriter.java:934). A segment without any term-vector field never creates the term vectors writer:finishDocumentreturns beforeinitTermVectorsWriterwhen no field has vectors (index/TermVectorsConsumer.java:119-126,:103-110), and flush skips the finish (:78), so it flushes fine. - The twin does it right.
Lucene90CompressingStoredFieldsFormat.java:96:@param blockShift the log in base 2 of number of chunks to store in an index block;:117-126reject anything outsideMIN_BLOCK_SHIFT..MAX_BLOCK_SHIFTin the constructor.
Not claimed. Values 2 to 22 are silently read as a shift (asking for "16 chunks" gives 2^16 = 65,536 chunks per block); that is only the documentation mismatch and fails nothing. The exception carries a suppressed CorruptIndexException: checksum passed (...). possibly transient resource issue, or a Lucene or JVM bug for a temp file; it is CodecUtil.checkFooter's generic handling of the earlier exception (FieldsIndexWriter.java:139), not a second defect, though it can mislead.
Exposure and likelihood146 words
- Who. Code that constructs
Lucene90CompressingTermVectorsFormatitself (it is@lucene.experimental) and passes 1 or 23 and above: for example a chunk count, as the javadoc describes the argument, or 1024, the value the stock format used up to 8.4.1. A custom codec that passed 1024 under 8.4.1 compiles unchanged against 8.5.0 and fails at its first flush there. A GitHub code search found no downstream product that constructs the format, and no public report of it was found since 2020, so the likelihood is rare. - Default vs opt-in. Opt-in only. Stock code passes 10 (
Lucene90TermVectorsFormat.java:170,SortingTermVectorsConsumer.java:40-41). - Effect. Loud and deterministic, but late and aborting: the error comes at the first flush instead of at construction, the IndexWriter closes, and the documents added since the last commit are lost. No wrong results, no damage to committed data.
- Scale. One document; nothing large is needed.
One JUnit test method on the public API: a FilterCodec with this format and blockSize 1024, one document with a term-vector field, then DirectoryReader.open(writer). If the constructor rejects 1024 the test returns, so it doubles as the regression test. Single thread, no random draws in the test method.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene90.compressing;

import org.apache.lucene.codecs.FilterCodec;
import org.apache.lucene.codecs.TermVectorsFormat;
import org.apache.lucene.codecs.compressing.CompressionMode;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestTermVectorsBlockSize extends LuceneTestCase {

  public void testAcceptedBlockSizeCanWriteTermVectors() throws Exception {
    // Expected: 1024 (a chunk count, per the javadoc) is rejected or works; actual: IAE at flush.
    TermVectorsFormat format;
    try {
      format =
          new Lucene90CompressingTermVectorsFormat("TV", "", CompressionMode.FAST, 4096, 128, 1024);
    } catch (IllegalArgumentException e) {
      return;
    }
    FilterCodec codec =
        new FilterCodec("TestCodec", TestUtil.getDefaultCodec()) {
          @Override
          public TermVectorsFormat termVectorsFormat() {
            return format;
          }
        };
    FieldType ft = new FieldType(TextField.TYPE_NOT_STORED);
    ft.setStoreTermVectors(true);
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig().setCodec(codec))) {
      Document doc = new Document();
      doc.add(new Field("f", "a b", ft));
      w.addDocument(doc);
      try (DirectoryReader r = DirectoryReader.open(w)) {
        assertEquals(2, r.termVectors().get(0, "f").size());
      }
    }
  }
}
cp $REPRO/TestTermVectorsBlockSize.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/compressing/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.compressing.TestTermVectorsBlockSize -Ptests.seed=DEADBEEF
- Expected
- The constructor throws
IllegalArgumentException, or the reader opens and shows the document's 2 terms. - Observed
DirectoryReader.open(writer)throwsIllegalArgumentException: blockShift must be in [2-22], got 1024fromFieldsIndexWriter.finish(FieldsIndexWriter.java:125), assertions on and off.
More files, environment, full output240 words
TestTermVectorsBlockSize (one method, extends LuceneTestCase, package org.apache.lucene.codecs.lucene90.compressing of the lucene/core tests, Apache license header). It is the hunt's minimal repro with one comment shortened to pass the 100-column format check. The test method draws no random values (it uses ByteBuffersDirectory, new IndexWriterConfig() and a FilterCodec over the fixed default codec); LuceneTestCase still randomizes class-level settings such as locale, time zone, similarity and InfoStream from the seed, none of which is on the failing path.
Without a fix it fails through gradle with assertions on and off; with fix A the constructor rejects 1024 and the test returns. The same failure shows through a standalone JUnit runner on the main jars and on the 10.6.0, 10.5.2 and 9.12.3 jars (assertions on and off), which also prints the suppressed CorruptIndexException from FieldsIndexWriter.java:139.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): fails; 8.5.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2, 10.6.0: fail; 8.4.1: passes (8.x and 9.0.0: core-only copies of the same logic) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (only this platform was run) |
cp $REPRO/TestTermVectorsBlockSize.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/compressing/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.compressing.TestTermVectorsBlockSize -Ptests.seed=DEADBEEF   # add -Ptests.asserts=false: same failure
# gradle, scratch worktree at 5adff78bb168, -Ptests.seed=DEADBEEF (assertions on; -Ptests.asserts=false gives the same)
TestTermVectorsBlockSize > testAcceptedBlockSizeCanWriteTermVectors FAILED
    java.lang.IllegalArgumentException: blockShift must be in [2-22], got 1024
        at org.apache.lucene.util.packed.DirectMonotonicWriter.<init>(DirectMonotonicWriter.java:47)
        at org.apache.lucene.util.packed.DirectMonotonicWriter.getInstance(DirectMonotonicWriter.java:158)
        at org.apache.lucene.codecs.lucene90.compressing.FieldsIndexWriter.finish(FieldsIndexWriter.java:125)
        at org.apache.lucene.codecs.lucene90.compressing.Lucene90CompressingTermVectorsWriter.finish(Lucene90CompressingTermVectorsWriter.java:725)
        at org.apache.lucene.index.TermVectorsConsumer.flush(TermVectorsConsumer.java:85)
        ...
        at org.apache.lucene.index.IndexWriter.getReader(IndexWriter.java:586)
        at org.apache.lucene.index.DirectoryReader.open(DirectoryReader.java:144)
        at org.apache.lucene.index.DirectoryReader.open(DirectoryReader.java:123)
        at org.apache.lucene.codecs.lucene90.compressing.TestTermVectorsBlockSize.testAcceptedBlockSizeCanWriteTermVectors(TestTermVectorsBlockSize.java:59)
1 test completed, 1 failed- The javadoc calls it "the number of chunks" per index block, and the check admits any value from 1 up; the writer takes only 2 to 22.
- The 8.5.0 change that made it a shift gave the stored-fields twin this exact check, but skipped this file.
- Nothing documents a shift or range for it; no upstream test reaches the gap.
The full argument269 words
- The constructor's own contract. The javadoc (
Lucene90CompressingTermVectorsFormat.java:68) says the value is a chunk count, and the check (:86-88) says every value from 1 up is legal. The writer can use neither 1 nor any value from 23 up. - The same change fixed the twin, not this file. LUCENE-9147 (
136dcbdbbce, Adrien Grand, 2020-02-05; issue #10187, PR apache/lucene-solr#1179) turned the value into a shift: it renamed the writer's parameterblockSizetoblockShift, changed the stock argument from 1024 to 10 (Lucene50TermVectorsFormat), and gaveCompressingStoredFieldsFormattheMIN_BLOCK_SHIFT..MAX_BLOCK_SHIFTcheck and the "log in base 2" javadoc.CompressingTermVectorsFormat.javais not in that commit's file list. The class dates from LUCENE-4599 (5837fe83bd8, 2013); its count javadoc and>= 1check were added by LUCENE-6153 (55eb8b3da39, 2015), when the value really was a count. LUCENE-9705 (f8be421ae1f, 2021) copied them intoLucene90CompressingTermVectorsFormat. - A second leftover of the old meaning. The same commit switched the test codec's main random range for the value from
1..1024toMIN_BLOCK_SHIFT..MAX_BLOCK_SHIFT, butCompressingCodec.randomInstance(Random, boolean)still draws it from1..1024(lucene/test-framework/.../CompressingCodec.java:97-105; no in-tree caller). It points to an oversight rather than a design; it is not claimed as a bug. - Tests never reach the gap. The test codec passes one value to both formats (
CompressingCodec.java:111-125), so the stored-fields constructor rejects a bad value before the term vectors one sees it. No upstream test passes a term vectors value outside 2 to 22, and no PR review comment, issue comment, MIGRATE or CHANGES entry documents a shift or a range for this argument.
The devil's-advocate check134 words
The strongest counter-argument (a summary of the verifiers' intended-behaviour arguments): since 8.5 the value is meant to be a shift; the writer calls it blockShift and every in-tree caller passes a valid shift, so only the javadoc is stale. The class is experimental and the failure is loud.
Why it does not settle it. The code's validation is wrong too, not just the text, and the authors' intent is visible in the twin, which got the range check in the same commit. @lucene.experimental marks API instability, not permission for the check and the writer to disagree. Loud is not harmless here: the failure comes late, closes the writer and drops uncommitted documents, for a value the javadoc describes (1024) or the constructor's own minimum (1). The argument does hold for impact, hence priority Low.
Recommended Range-check in the constructor, like the stored-fields twin (fix A)
In the constructor, check the value against DirectMonotonicWriter.MIN_BLOCK_SHIFT..MAX_BLOCK_SHIFT and document it as "the log in base 2 of the number of chunks", exactly as the stored-fields twin does. The repro then passes, and with it the two term vectors format suites run 44 tests with 0 failures.
if (blockSize < DirectMonotonicWriter.MIN_BLOCK_SHIFT
    || blockSize > DirectMonotonicWriter.MAX_BLOCK_SHIFT) {
  throw new IllegalArgumentException(
      "blockSize must be in "
          + DirectMonotonicWriter.MIN_BLOCK_SHIFT
          + "-"
          + DirectMonotonicWriter.MAX_BLOCK_SHIFT
          + ", got "
          + blockSize);
}
All options and trade-offs3 options · 400 words
Fix A was built and checked through gradle on 5adff78bb168 in a scratch worktree: the repro with assertions off, then the repro with TestCompressingTermVectorsFormat and TestLucene90TermVectorsFormat, seed DEADBEEF, then :lucene:core:checkGoogleJavaFormat. Option B was not run separately. The hunt's own fix check (the same change) also passed its test and the same two suites, and the verifiers re-ran the fix with their own tests.
Range-check in the constructor, like the stored-fields twin (fix A) (validated by the checks) (recommended)
In Lucene90CompressingTermVectorsFormat (:68, :86-88) replace the >= 1 check with the twin's MIN_BLOCK_SHIFT..MAX_BLOCK_SHIFT check and message (Lucene90CompressingStoredFieldsFormat.java:117-126), document the value as "the log in base 2 of the number of chunks to store in an index block", and import org.apache.lucene.util.packed.DirectMonotonicWriter. +11/-3 lines.
if (blockSize < DirectMonotonicWriter.MIN_BLOCK_SHIFT
    || blockSize > DirectMonotonicWriter.MAX_BLOCK_SHIFT) {
  throw new IllegalArgumentException(
      "blockSize must be in "
          + DirectMonotonicWriter.MIN_BLOCK_SHIFT
          + "-"
          + DirectMonotonicWriter.MAX_BLOCK_SHIFT
          + ", got "
          + blockSize);
}
Trade-offs
The mistake surfaces at construction, with the twin's message. No behaviour change for any value the writer can use (2 to 22) and no file format change. Code that passes 1 or 23 and above now fails at construction instead of at the first flush.
What the checks validated
Gradle, scratch worktree at 5adff78bb168, seed DEADBEEF: the repro passes with assertions off (the constructor now rejects 1024 and the test returns); the repro plus TestCompressingTermVectorsFormat (22) and TestLucene90TermVectorsFormat (21): 44 tests, 0 failures; :lucene:core:checkGoogleJavaFormat passes with the fix and the test in place.
Also rename blockSize to blockShift in the constructor, the field and the toString label, matching the writer and the twin.
Trade-offs
Clearer, and source compatible (parameter names are not part of the API); the toString output changes.
What the checks validated
Not run separately; the check itself is fix A.
Convert the value to a shift (for example with Integer.numberOfTrailingZeros) so that 1024 works as the javadoc says.
Trade-offs
It would change the meaning of the value 10 that the stock formats pass (Lucene90TermVectorsFormat.java:170, SortingTermVectorsConsumer.java:40-41) and of the valid shifts the test codec draws (CompressingCodec.java:76-83), and a count that is not a power of two has no exact shift.
What the checks validated
Not run.
A product that exposed this format's blockSize as a user setting would see a bad value only at the first flush with term vectors, as a closed IndexWriter, not when the setting is applied.
A proof-obligation audit of the term vectors format's constructor contract: every value its javadoc and check accept must be usable by the writer. Following the value showed it reaches a check that allows only 2 to 22; a one-test public-API JUnit then witnessed the failure on main.
The method in full135 words
Method: semi-formal (a proof-obligation audit of a class's contract, witnessed by an executable repro).
- The finder took the constructor's stated contract, its javadoc (
Lucene90CompressingTermVectorsFormat.java:68) and its argument check (:86-88), and the obligation it implies: every accepted value must be one the writer can use. - It followed
blockSizethroughvectorsWriter(:100-113) intoLucene90CompressingTermVectorsWriter(:242,:281-289) andFieldsIndexWriter.finish(:125) toDirectMonotonicWriter's range check (:46-54), which admits only 2 to 22, so the obligation fails for 1 and for every value from 23 up. - A one-test public-API JUnit (blockSize 1024, one document, a reader or a commit) witnessed it on main with assertions on and off and on the 10.6.0 and 9.12.3 jars; the verifiers, the adjudication and a separate re-run all reproduced it.
No prior report found (searched 2026-11-03): apache/lucene issues, PRs and commits with the JIRA archive, the Lucene mailing lists, Elasticsearch, OpenSearch, Solr and the web. Nearest item: #10187 / lucene-solr#1179, the change that made the value a shift.
Searches3 searches
No matching public report was found in the documented searches. Related, not reports: #10187 and apache/lucene-solr#1179 (LUCENE-9147, the introducing change; its review comments do not mention the term vectors argument), #7215 (LUCENE-6153, 2015: added the >= 1 check when the value was a count), #10201 (LUCENE-9161, a different DirectMonotonicWriter check). Only one open PR (#1003) edits the format file, for an unrelated parameter type change. Upstream main 1c2072f0284 (2026-11-02) still has the count javadoc and the >= 1 check.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive, apache/lucene-solr) | 2026-11-03, re-checked the same day | three scripted prior-report searches (51 queries each: identifiers and the exception message; symptom and trigger; history such as LUCENE-9147 and LUCENE-9705), 20 manual issue and PR searches (exact messages such as "blockShift must be in" returned 0 hits), 4 commit searches | no report; #10187, lucene-solr#1179, #7215, #10201 are history |
| open apache/lucene PRs | 2026-11-03 | changed-file lists of all 409 open PRs and of the 27 updated since 2026-11-01 | only #1003 edits the format file (an unrelated type change); none touches the check, FieldsIndexWriter or DirectMonotonicWriter's range |
| dev@, java-user@, issues@ and commits@ lists; Elasticsearch, OpenSearch and Solr trackers; GitHub code search; the web | 2026-11-03 | the scripted searches' list, downstream and web legs; 4 code searches; 5 web searches | no report; no downstream product constructs the format |
Since LUCENE-9147 (136dcbdbbce, branch_8x 597141df6b6, 2020-02-05), first release 8.5.0. 8.4.1 passes; 8.5.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2, 10.6.0 and main fail. Not fixed upstream.
Versions tested5 rows
Introduced by 136dcbdbbce "LUCENE-9147: Move the stored fields index off-heap. (#1179)" (Adrien Grand, author date 2020-02-05; issue #10187, PR apache/lucene-solr#1179), first released on the main line in 9.0.0, and its branch_8x cherry-pick 597141df6b6, first release 8.5.0. It made the writer's argument a shift and fixed the stored-fields twin, but did not touch CompressingTermVectorsFormat.java. LUCENE-9705 (f8be421ae1f, 2021-02-24) copied the stale javadoc and check into Lucene90CompressingTermVectorsFormat; the newest commit on the file is be94a667f20 (LUCENE-9827, 2021-04-06), which did not touch them.
Release runs use the repro's logic (8.x and 9.0.0 as core-only main() copies, because org.apache.lucene.tests starts in 9.1.0). 8.5.1 to 8.8.1 and 10.0.0 have the same check with a shift-taking writer by reading. Not new in 10.6.
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | gradle and the standalone runner: fails with assertions on and off; passes with fix A |
| 10.6.0, 10.5.2, 9.12.3 | affected | the JUnit repro fails with the same exception |
| 9.0.0, 8.11.4 | affected | core-only copy of the repro fails with the same exception |
| 8.5.0 | affected | first release with the bug: same exception, writer closed |
| 8.4.1 | not affected | passes: the commit succeeds and the term vectors read back (the value was still a chunk count) |
A finder, an independent reproducer, an executed cross-model review (OpenAI GPT-5.6, refute lens), a devil's-advocate verifier, an adjudication and a separate re-run reproduced it and agree on the root cause; a final repro check confirmed it at Low.
Checks and verdicts257 words
The cross-model review ran on main ea57360912ed, whose files here are identical, and its own test was re-run on 5adff78bb168 with the same result. All other main runs used 5adff78bb168; the release runs used each release's own jars.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Own test (blockSize 1024, commit()) fails on main (assertions on and off), 10.6.0 and 9.12.3; the writer is closed afterwards; the fix passes it and 43 existing term vectors tests. |
| independent reproducer | real | Own test written from the description fails on main (assertions on and off), 10.6.0, 10.5.2 and 9.12.3. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real, high | Own 1024 test fails (assertions on and off), a shift-10 control passes; with the fix its test and 43 existing term vectors tests pass. Intended-behaviour case judged moderate. |
| devil's-advocate verifier | real, high | Own test with blockSize 1, the documented minimum, fails on main and 10.6.0; every intended-behaviour argument fails. |
| adjudication | confirmed, high, Low | Re-ran the reproducer's test on main (assertions on and off): fails; passes with the fix. |
| separate re-run, final repro check | fails on main, passes with the fix; confirmed, Low | Re-runs fail on main and pass with the fix; the final check confirmed the minimal repro at Low and set the impact class to minor, not crash. |
| this doc | reproduced; fix A validated | Gradle runs on 5adff78bb168: the repro fails with assertions on and off and passes with fix A; 44 tests, 0 failures. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 494 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,419 words
- Registry title
- Lucene90CompressingTermVectorsFormat documents and validates its last argument, blockSize, as a chunk count (>= 1), but the writer uses it as a DirectMonotonic block shift limited to [2, 22], so values such as 1024 or 1 are accepted and the first flush with term vectors throws and closes the IndexWriter (since 8.5.0)
- Area
- core / codecs: compressing term vectors format (Lucene90CompressingTermVectorsFormat blockSize validation; FieldsIndexWriter, DirectMonotonicWriter)
- Priority
- Low, rank 691: A custom codec that gives the experimental Lucene90CompressingTermVectorsFormat a blockSize of 1, or a chunk count such as 1024 as its javadoc describes the argument, closes the IndexWriter at the first flush with term vectors and loses the uncommitted documents, in every release since 8.5.0. Stock codecs are unaffected, the failure is loud and comes at the first flush, and the committed index stays intact.
- Impact class
- minor
- Impact note
- Only applications with a custom codec that constructs this @lucene.experimental format with blockSize 1 or 23 and above (for example 1024, a chunk count as the javadoc describes and the in-tree value before 8.5.0) are hit, at the first flush of a segment with term vectors, which throws IllegalArgumentException and closes the IndexWriter, so documents added since the last commit are lost [exec, -ea and -da]; stock codecs pass 10 and are not affected, no scale is needed, and every release from 8.5.0 through 10.6.0 is affected. The impact class is minor, not crash: a loud, deterministic first-flush failure of a hand-built codec on an experimental format, with no wrong results and the committed data intact.
- Summary
- You build a custom codec whose term vectors format is new Lucene90CompressingTermVectorsFormat(..., blockSize) and, as its javadoc says ('the number of chunks to store in an index block'), pass a chunk count such as 1024; the constructor accepts it, since it rejects only values below 1. You expect a format that writes and reads term vectors, or an IllegalArgumentException from the constructor, as the stored-fields twin Lucene90CompressingStoredFieldsFormat gives for the same argument. Instead the value goes unchanged to the writer, which uses it as a DirectMonotonicWriter block shift, so addDocument succeeds and the first flush with term vectors (here DirectoryReader.open(writer) or commit) throws 'blockShift must be in [2-22], got 1024' and closes the IndexWriter; blockSize 1, the constructor's own minimum, fails the same way.
- Introduced
- 136dcbdbbced7c2d32b4d244ca99ace2c59baee8 on the main line (first release 9.0.0) and its branch_8x cherry-pick 597141df6b6a017fced16ec27b8fd180e9a6fcc2 (first release 8.5.0), the same change: LUCENE-9147 'Move the stored fields index off-heap' by Adrien Grand (apache/lucene-solr PR #1179, migrated issue #10187). It turned the term vectors writer's index-block argument from a chunk count into a DirectMonotonic block shift (CompressingTermVectorsWriter: blockSize -> blockShift; Lucene50TermVectorsFormat: 1024 -> 10) and gave the stored-fields twin the [2, 22] check and the 'log in base 2' javadoc, but did not touch CompressingTermVectorsFormat.java, which kept '@param blockSize the number of chunks' and 'blockSize < 1' [read: git show --stat 136dcbdbbce in the history clone; exec: 8.4.1 passes, 8.5.0 fails]. LUCENE-9705 (f8be421ae1f, 2021) copied the stale javadoc and check into Lucene90CompressingTermVectorsFormat; the API itself dates from LUCENE-4599 (4.2.0). (2020-02-05 (author date 2020-02-05T18:35:08+01:00; PR merged 2020-02-05T17:35:09Z); first release 8.5.0)
- First affected version
- 8.5.0 [exec: a core-only main() with the repro's logic fails on the 8.5.0 jars]; 8.4.1 is not affected [exec: passes, commit succeeds and the term vectors read back, because the value was still a chunk count]
- Affected versions
- Every release from 8.5.0 (2020) through 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main 5adff78bb168 (12.0.0-SNAPSHOT); never fixed. [exec, JDK 25.0.3, Linux aarch64] the independent reproduction's one-test repro (blockSize 1024) fails on main with -ea and -da (the independent reproduction, the adjudication and a separate re-run of 2026-11-03) and on the 10.6.0, 10.5.2 and 9.12.3 jars (-ea, the independent reproduction); the finder's equivalent test fails on main (-ea, -da), 10.6.0 and 9.12.3; the intended-behaviour check's blockSize-1 test fails on main (-ea, -da) and 10.6.0; core-only main() equivalents fail on 8.5.0, 8.11.4 and 9.0.0, and 8.4.1 passes. [read] the 8.5.1 to 8.8.1, 9.0.0, 9.12.3, 10.0.0 and 10.6.0 sources all have 'blockSize < 1' with a shift-taking writer; 8.8.2 to 8.11.3 fall between executed failing releases. Not new in 10.6 (10.5.2 fails too). Not fixed upstream: main 1c2072f0284 (2026-11-02) still has the count javadoc and the >= 1 check (contents API, 2026-11-03), and the newest upstream commit on the file is be94a667f20 (2021-04-06).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (2026-11-03, on top of the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches; rechecked the same day): three follow-up scripted prior-report searches (identifiers and error messages, symptom and trigger, history; 51 queries each over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web, none same-bug) plus the finder's and the intended-behaviour check's runs, 20 manual GitHub issue and PR searches (3 of them in downstream repositories), 4 commit searches, 4 code searches (no downstream product constructs the format), the changed files of all 409 open apache/lucene PRs (only #1003 edits the file, for an unrelated type change) and of the 27 PRs updated since 2026-11-01 (none touches the format, FieldsIndexWriter or DirectMonotonicWriter), the constructor on upstream main and the commit history of the file (author dates); the same-day recheck found no issue or PR on the term vectors blockSize, the 'blockShift must be in' message or the 'number of chunks to store in an index block' javadoc, and no term-vectors issue or PR updated since 2026-11-01 that touches this code. Related history, not reports: #10187 (LUCENE-9147, the introducing change; no term-vectors follow-up), apache/lucene-solr#1179 (its PR; review comments do not mention the term vectors argument), #7215 (LUCENE-6153, 2015: added the >= 1 check when the value really was a count) and #10201 (LUCENE-9161: a different DirectMonotonicWriter check).
- Lucene commit tested
- main
5adff78bb168(2026-11-02) through gradle on 2026-11-03 in a scratch worktree: the repro with assertions on and off without a fix (fails), and with fix A (passes, assertions off), plusTestCompressingTermVectorsFormatandTestLucene90TermVectorsFormatwith the repro (44 tests, 0 failures) and the google-java-format check; OpenJDK 25.0.3, Linux aarch64. Release runs from the hunt: 8.4.1 passes; 8.5.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2 and 10.6.0 fail.
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsFormat.java:68 (at 5adff78bb168) ('@param blockSize the number of chunks to store in an index block.'), :86-89 (the only check: 'if (blockSize < 1) throw new IllegalArgumentException("blockSize must be >= 1")'), :100-113 (vectorsWriter passes blockSize unchanged to Lucene90CompressingTermVectorsWriter)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:242 (at 5adff78bb168) (the parameter is named blockShift), :281-289 (new FieldsIndexWriter(..., blockShift, ...))lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/FieldsIndexWriter.java:116 (at 5adff78bb168) (metaOut.writeInt(blockShift)), :125 (DirectMonotonicWriter.getInstance(metaOut, dataOut, totalChunks + 1, blockShift): the first range check, at segment finish), :139 (CodecUtil.checkFooter on the temp file, the source of the suppressed CorruptIndexException)lucene/core/src/java/org/apache/lucene/util/packed/DirectMonotonicWriter.java:33-34 (at 5adff78bb168) (MIN_BLOCK_SHIFT = 2, MAX_BLOCK_SHIFT = 22), :46-54 (IllegalArgumentException 'blockShift must be in [2-22], got N')lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsFormat.java:96 (at 5adff78bb168) ('@param blockShift the log in base 2 of number of chunks to store in an index block'), :117-126 (the twin range-checks MIN_BLOCK_SHIFT..MAX_BLOCK_SHIFT at construction)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java:170 (at 5adff78bb168) (the default format passes 10, a shift); lucene/test-framework/src/java/org/apache/lucene/tests/codecs/compressing/CompressingCodec.java:111-125 (at 5adff78bb168) (the test codec passes one blockShift to both formats, so the stored-fields check runs first and upstream tests only pass valid shifts)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsFormat.java:35, (at 5adff78bb168) :68, :86-89, :100-113lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:242, (at 5adff78bb168) :281-289, :725lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/FieldsIndexWriter.java:116, (at 5adff78bb168) :125, :139lucene/core/src/java/org/apache/lucene/util/packed/DirectMonotonicWriter.java:33-34, (at 5adff78bb168) :46-54lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumer.java:78-89, (at 5adff78bb168) :103-110, :119-126lucene/core/src/java/org/apache/lucene/index/DocumentsWriter.java:400-404, (at 5adff78bb168) :412, :434, :450; SegmentMerger.java:170-171, :261-267; lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:896, :934lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsFormat.java:96, (at 5adff78bb168) :117-126lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java:170 (at 5adff78bb168)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java:170; (at 5adff78bb168) lucene/core/src/java/org/apache/lucene/index/SortingTermVectorsConsumer.java:40-41
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsFormat.java:68, (at 5adff78bb168) :86-88lucene/test-framework/src/java/org/apache/lucene/tests/codecs/compressing/CompressingCodec.java:66-84, (at 5adff78bb168) :97-105, :111-125
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsFormat.java:117-126 (at 5adff78bb168)lucene/test-framework/src/java/org/apache/lucene/tests/codecs/compressing/CompressingCodec.java:76-83 (at 5adff78bb168) (randomInstance(Random) draws valid shifts); lucene/core/src/java/org/apache/lucene/index/SortingTermVectorsConsumer.java:40-41
- Diagrams
lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsFormat.java:68, (at 5adff78bb168) :86-88; FieldsIndexWriter.java:125; Lucene90CompressingStoredFieldsFormat.java:117-126; lucene/core/src/java/org/apache/lucene/util/packed/DirectMonotonicWriter.java:33-34, :46-54; lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java:170
- TestTermVectorsBlockSize.java (lucene/core, package org.apache.lucene.codecs.lucene90.compressing, 1 test):
repro/LFV-1175/TestTermVectorsBlockSize.java(64 lines)
The diagram follows the repro on main 5adff78bb168 (Lucene90CompressingTermVectorsFormat.java:68, :86-88; FieldsIndexWriter.java:125; DirectMonotonicWriter.java:33-34, :46-54; Lucene90CompressingStoredFieldsFormat.java:117-126) and the repro's executed output.
assets/LFV-1175/bug.png(494 KB)