Lucene requires every document that contains a field to give it the same data structures (postings, doc values, points, vectors), and checks each document against the field's established structures.
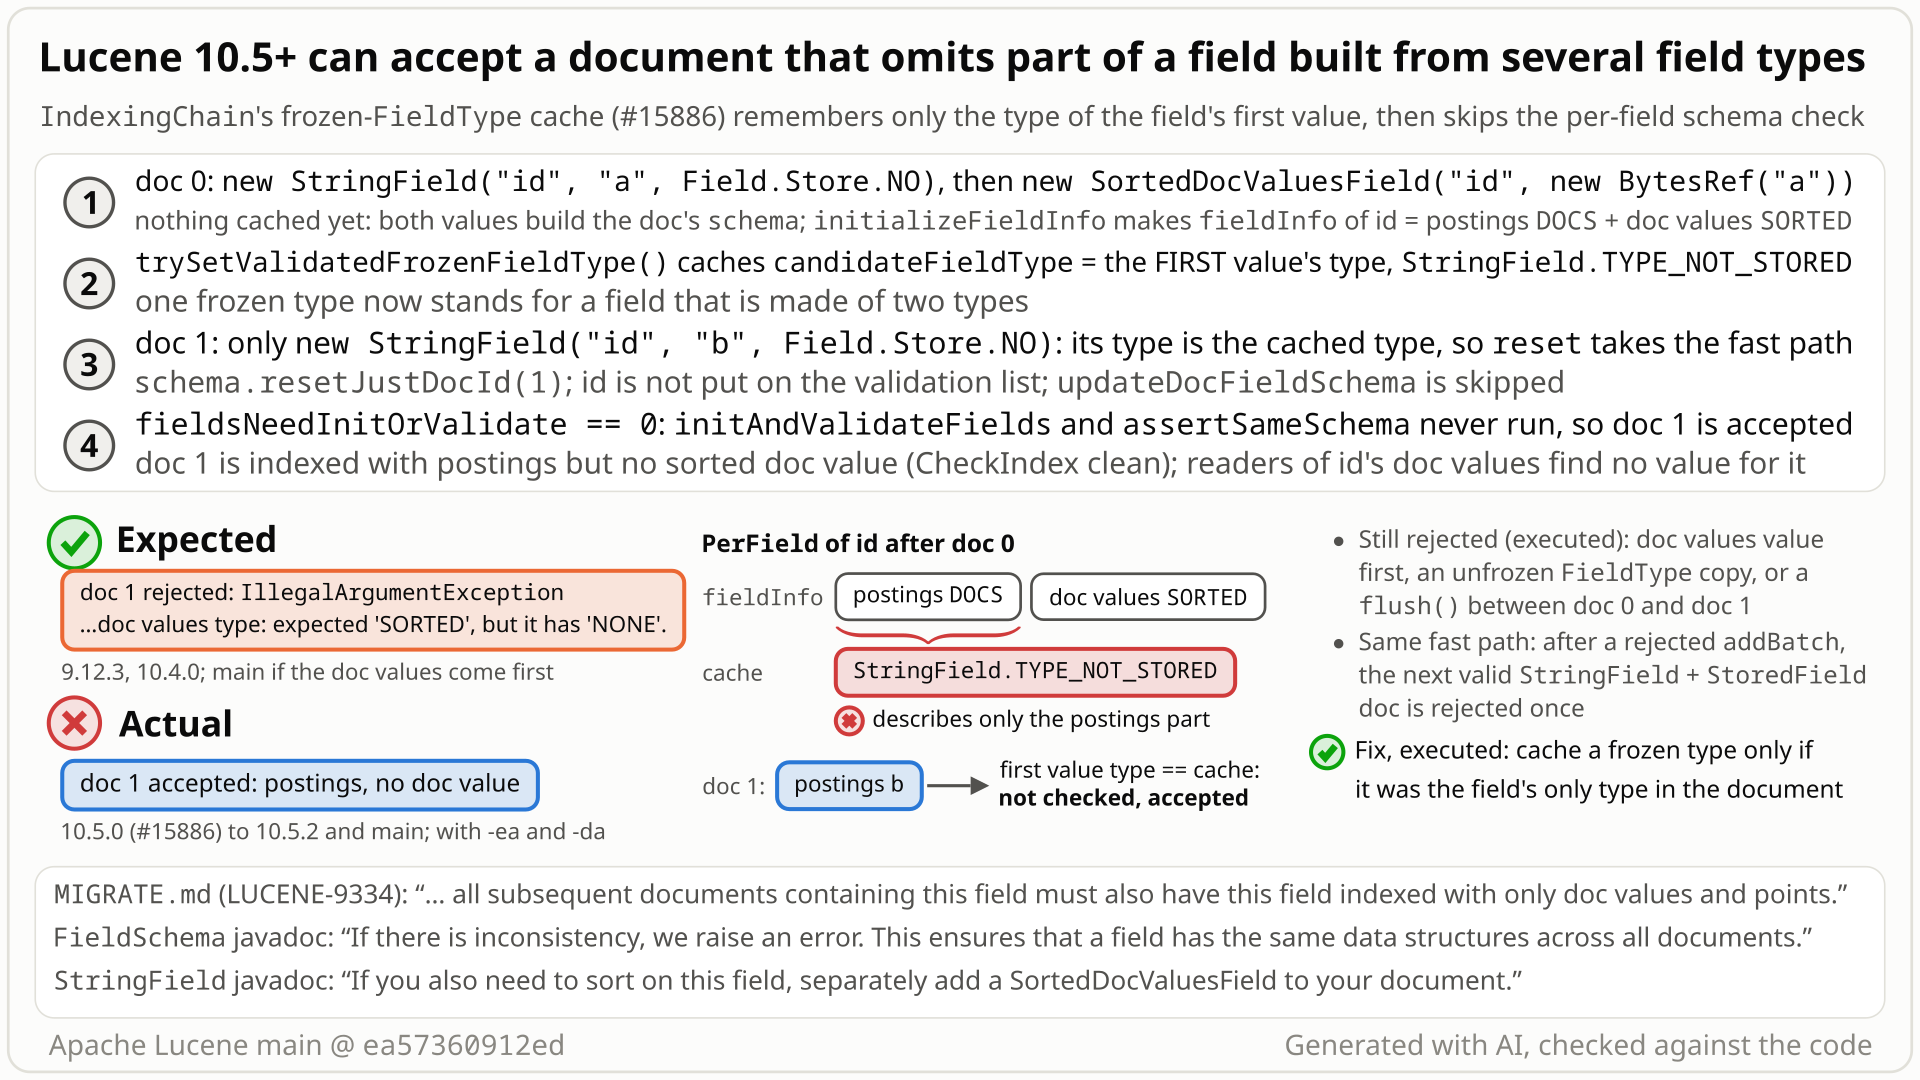
id built from a StringField and a SortedDocValuesField: doc 0 gives the field both structures, the cache keeps only the first value's type, and doc 1, with only the StringField, skips the check and is accepted without a doc value; every other path rejects it. Select the still to open it at full size. Generated with AI, checked against the code.- Add doc 0 with
StringField("id", "a")and thenSortedDocValuesField("id", "a"). Fieldidnow has two structures: postings and sorted doc values. - Add doc 1 with only
StringField("id", "b"). You expectIllegalArgumentException("doc values type: expected 'SORTED', but it has 'NONE'"), as on 10.4.0; main also rejects it when doc 0 lists the doc-values value first, or after a flush. - On 10.5.0, 10.5.1, 10.5.2 and main, doc 1 is accepted with no error, with assertions on or off. So is doc 1 =
StringField+StoredField: it is checked, but against doc 0's leftover state. - Why: after doc 0, Lucene caches the type of the field's first value,
StringField's shared frozen type, as "validated", and skips the check for every later document whose first value has that type. But the field's schema came from two types. - Effect: an accepted document lacks a structure, so a search that reads it can miss that document. In one segment of 20,000 documents with
NumericDocValuesField+LongPoint, a doc-values-only document holding the top value 1,000,000 is accepted, and a default top-1 descending sort of a term query returns 999,999 (seen with that document at positions 10,000 to 19,999, not at 1,500 or 5,000). No error is raised; CheckIndex reports the index clean.
Applications on 10.5.0-10.6.0 (10.6.0 by reading) and main that build one field from several field classes (StringField + SortedDocValuesField, NumericDocValuesField + LongPoint) and sometimes leave one part out. Lucene used to reject that mistake; now it can accept it if the field's last validated document in the in-memory segment started with the same frozen type. Sorts and queries can then miss it.
Mechanism, terms and numbers748 words
Lucene requires every document that has a field to give that field the same data structures (LUCENE-9334, 9.0). A documented, ordinary way to build a field is from several Field instances under one name, for example a StringField plus a SortedDocValuesField, as StringField's javadoc suggests. Since 10.5.0, a later document that carries only one part is accepted when that part's type was the first value of the field in the most recently validated document of that field in the same in-memory segment; 9.1.0-10.4.0 reject it. The frozen-FieldType cache added by #15886 caches the first value's type after the document was validated and then skips validation for later documents whose first value has that type. Whether Lucene enforces its rule now depends on value order, frozen vs unfrozen types and flushes. The same fast path keeps leftover per-document schema state, so after a rejected addBatch the next valid multi-type document is rejected once. The index stays valid; queries and sorts that use the missing structure can silently miss the document.
- Field schema /
FieldInfo: the data structures a field has in a segment, fixed by the first document that contains it (MIGRATE.md, "Require consistency between data-structures on a per-field basis"). - Multi-type field: one field name filled by several
Fieldinstances of different types in a document, for exampleStringField(postings) +SortedDocValuesField(doc values). The field's schema is the union of the types. - Frozen type: a
FieldTypeafterfreeze(). Stock classes share static frozen types, for exampleStringField.TYPE_NOT_STORED,TextField.TYPE_*,StoredField.TYPE, the*DocValuesField.TYPEconstants andKeywordField's types; an application can also reuse its own frozenFieldType(for example one fromKnnFloatVectorField.createFieldType).LongPoint,IntPointand the default vector-field constructors build a new type per instance.
- For each document,
processDocumentbuilds a per-document schema for every field from all its values andinitAndValidateFieldscompares it with theFieldInfo(:611-640,:683-697,assertSameSchema:2290-2304). TheFieldSchemajavadoc (:2154-2161): "If there is inconsistency, we raise an error." - Since 10.5.0 (#15886),
PerField.resetruns for the field's first value and records its type. If it is the cachedvalidatedFrozenFieldType, it only updates the doc id (resetJustDocId,:1821-1831,:2272-2274), the field is not validated (:622-624) and the value is not added to the schema (:633-635). - A later value forces validation only if its type differs from the cached one (
multiValueForcesDeoptimize,:625-630,:1833-1835), and it is merged into whatever schema state the previous operation left. - After validation,
trySetValidatedFrozenFieldTypecaches the first value's type if it is frozen (:695,:1837-1843), although theFieldInfowas checked against the union of all values.
- doc 0 =
[StringField, SortedDocValuesField]: no cache yet, so both values enter the schema;FieldInfo= postingsDOCS+ doc valuesSORTED;StringField.TYPE_NOT_STOREDis cached. - doc 1 =
[StringField]: first value has the cached type, so no schema update and no validation. Indexed with postings and no doc value. - doc 1 =
[StringField, StoredField]: theStoredFielddeoptimises, but the schema still holds doc 0'sDOCS+SORTED, and a stored value adds nothing to it, so the check passes. - With doc 0 =
[SortedDocValuesField, StringField]the cached type isSortedDocValuesField.TYPE: aStringField-only document is rejected, aSortedDocValuesField-only one is accepted.
| doc 0 | doc 1 | main, 10.5.2 | 10.4.0, fix | |
|---|---|---|---|---|
| A | StringField, SortedDocValuesField | StringField | accepted | rejected |
| B | SortedDocValuesField, StringField | StringField | rejected | rejected |
| C | SortedDocValuesField, StringField | SortedDocValuesField | accepted | rejected |
| D | as A, then flush() | StringField | rejected | rejected |
| E | unfrozen copy of the StringField type, SortedDocValuesField | the unfrozen type | rejected | rejected |
| F | StringField, SortedDocValuesField | StringField, StoredField | accepted | rejected |
processBatch resets the field's schema and fills it from the batch columns (:756-783) but never clears the cache; a rejected batch throws before the cache is updated (:693, :695). After addDocument([StringField("id")]), an addBatch with a NumericDocValuesField.TYPE column for id is correctly rejected, which leaves the batch's state (index options NONE, doc values NUMERIC) in the schema. The next document [StringField, StoredField] takes the fast path for its StringField, deoptimises on the StoredField, and is compared using the batch's leftovers: index options: expected 'DOCS', but it has 'NONE'. One false rejection per rejected batch; the next document is validated from scratch.
Exposure and likelihood513 words
- Who is hit. Default
IndexWriterConfigand codec, assertions on or off. The cached first value must be a shared frozen type (for exampleStringField,TextField,StoredField, the*DocValuesFieldconstants,KeywordField, or a frozenFieldTypethe application reuses), so "point first" does not trigger it. Examples:StringField+SortedDocValuesField(StringField's javadoc: "If you also need to sort on this field, separately add a SortedDocValuesField"),NumericDocValuesField+LongPoint(the numeric sort optimisation),SortedNumericDocValuesField+LongPoint(theIndexOrDocValuesQuerypattern),StoredField+ doc values. - What it takes. A later document in the same in-memory segment that omits one of the field's structures. That document is the application's own mistake; Lucene documents that it rejects it, and every tested release from 9.1.0 to 10.4.0 does.
- Sort consequence (executed). One segment of 20,000 documents, each with
StringField("k", "x"): 19,999 withNumericDocValuesField+LongPointonts(doc-values value first; document 1 holds 999,999) and, as document 15,000, one with onlyNumericDocValuesField("ts", 1000000), the highest value. It is accepted; a default top-1 descending sort of the term queryk:x(search(query, 1, sort)) returns 999,999, while the same search without skipping returns 1,000,000. Default codec, plainmain(), main-ea/-daand 10.5.2. MIGRATE.md: the sort optimisation "relies on the assumption that the same data is stored in these points and doc values." - Conditions of the sort consequence. Whether the document is missed depends on where it falls: at positions 10,000 to 19,999 (five tried) the default search returns 999,999, at 1,500 and 5,000 it finds it, and
MatchAllDocsQuerywith the same sort found it at every position tried. The verifier's JUnit shows the miss with seed5EEDF00D; with 15 other seeds its default search did not skip at all and returned 1,000,000. - Query consequence (executed). 5,000 documents with
SortedNumericDocValuesField+LongPointonn, then a doc-values-only document with value 7:IndexOrDocValuesQuery(n in [7, 1500])alone does not match it (points path), butid:dv-only ANDthe same query does (doc-values path); the same with 6 test seeds and codecs, while 10.4.0 rejects the document.IndexOrDocValuesQueryrequires its two queries to match the same documents, so this is the bypass letting the application's violation through, not a defect of that query. - Not corruption. CheckIndex is clean before and after
forceMerge(1); each structure holds exactly the documents that carried it (a probe of 350 documents:idpostings 350, sorted doc values 300). On this bug's path an accepted document can lack a checked structure, but a value with a conflicting checked schema dimension (index options, norms, term vectors, doc values, points, vectors) is still rejected; stored status and attributes are not part of the check, and the sibling LFV-127 is a separate path. - The batch face. With the experimental
IndexWriter#addBatch, a schema-rejected batch makes the next valid multi-type document of that field fail once (measured: 1 of 50 per rejected batch, in each of 3 rounds), then it heals. - Scale. Two documents are enough.
- Status. Regression in 10.5.0; still on main and
branch_10x, and in 10.6.0 (released 2026-10-29).
The test shows that after a document whose field id is a StringField followed by a SortedDocValuesField, the frozen-FieldType cache lets a second document with only the StringField id skip the per-field schema check (TestFrozenTypeCacheMultiTypeField#testDocumentWithoutDocValuesRejected).
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestFrozenTypeCacheMultiTypeField extends LuceneTestCase {

  public void testDocumentWithoutDocValuesRejected() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      w.addDocument(
          List.of(
              new StringField("id", "a", Field.Store.NO),
              new SortedDocValuesField("id", new BytesRef("a"))));
      // expected IllegalArgumentException (doc lacks the doc values "id" has), actual: accepted
      expectThrows(
          IllegalArgumentException.class,
          () -> w.addDocument(List.of(new StringField("id", "b", Field.Store.NO))));
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-118/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestFrozenTypeCacheMultiTypeField
- Expected vs actual
- Expected
IllegalArgumentException(the LUCENE-9334 per-field consistency rule; 10.4 and main with the other value order reject it); actual: the document is accepted (Expected exception IllegalArgumentException but no exception was thrown), with -ea and -da.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => junit.framework.AssertionFailedError: Expected exception IllegalArgumentException but no exception was thrown
       org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1432)
       org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1418)
org.apache.lucene.index.TestFrozenTypeCacheMultiTypeField.testDocumentWithoutDocValuesRejected(TestFrozenTypeCacheMultiTypeField.java:22)- MIGRATE.md (LUCENE-9334): every later document with the field "must also have" the same structures; the
FieldSchemajavadoc: "If there is inconsistency, we raise an error." - 10.4.0 rejects the document; so does main with the other value order or after a flush, and upstream's
TestPerFieldConsistencyfails if only its loop order is reversed. - #15886 was an optimisation: "this work is redundant".
The full argument404 words
The contract, in its own words (at ea57360912ed):
- MIGRATE.md:1557-1564: "The per field data-structures are implicitly defined by the first document indexed that contains a certain field. ... if you first index a document where a certain field is indexed with doc values and points, all subsequent documents containing this field must also have this field indexed with only doc values and points." CHANGES (9.0.0): "LUCENE-9334: Require consistency between data-structures on a per-field basis."
IndexingChain.FieldSchemajavadoc (:2154-2161): "If there is inconsistency, we raise an error. This ensures that a field has the same data structures across all documents."TestPerFieldConsistency#testDocWithMissingSchemaOptionsThrowsError: "the same segment: indexing a doc with a missing field throws error", for each of four structures.
Why upstream's test misses it. It drops the fields first to last. Its first rejected document drops field 0, the frozen postings type, so that document's first value has another type, which clears the cache, and the later documents are fully checked. Reversed, the first rejected document still starts with the cached type and is accepted: the reversed copy fails on main, 10.5.0, 10.5.2 and #15886's own commit, and passes on 10.4.0, 9.12.3, #15886's parent and with the fix.
Intent of #15886 (commit message): "For the common case where a field consistently uses the same frozen FieldType instance, this work is redundant — a frozen type is immutable, so its schema contribution is identical every time." "If a different type is encountered, the cache is invalidated and the full validation path runs." "A deoptimize path handles multi-valued fields where a later value uses a different type than earlier values within the same document." CHANGES lists it under 10.5.0 Optimizations. The PR had one approval and no discussion of fields made of complementary types; its tests and those of #16171 cover multi-valued fields whose types share one schema or conflict inside one document. The author's first PR comment names the motivation: light-indexing workloads where schema validation dominates processDocument; no difference in the luceneutil benchmarks, and a 10% documents-per-second gain in doc-values-oriented macro runs of Elasticsearch, together with another change.
Old behaviour. 9.1.0, 9.12.3, 10.0.0, 10.3.2, 10.4.0 and #15886's parent reject every subset document; #15886 and every later release accept them.
Context. In LUCENE-10125 (2021) a committer wrote that "the schema definition of a field to be splitted across multiple Field instances makes it challenging to improve" the LUCENE-9334 check: the case the cache gets wrong.
The devil's-advocate check245 words
The cache is a deliberate hot-path optimisation keyed by object identity (the PerField comment says it lets IndexingChain "skip schema validation if fields keep using the same frozen field type"); the subset document breaks the documented rule anyway (garbage in); the LUCENE-9334 issue called the check "best-effort"; addBatch is @lucene.experimental.
Why it fails: Lucene documents that it rejects such input, upstream tests assert it, and 9.1.0-10.4.0 did so deterministically. The "best-effort" list in the LUCENE-9334 issue (#10374) names this very case: "it is illegal for a document to only enable points and another document to only enable doc values". "Best-effort" does not cover an outcome that flips with value order, frozen vs unfrozen types and flush timing. #15886 presented the change as removing redundant work, not as relaxing the rule. The comment's premise (the field keeps using one frozen type) is false for a field built from several types. And an experimental API does not license a rejected call making a later valid addDocument fail.
What a maintainer could still raise (the cross-model fact check rated the intended case moderate for the subset document and weak for the other two faces): detection may have been meant as a defence rather than a guarantee, and the triggering document is the application's own mistake; a document that omits the field entirely is always legal, while this one has the field with only part of its structures; and the two faces have separate causes and fix parts.
Recommended Cache a type only if it was the field's only type in the document; rebuild before deoptimising
Don't cache a frozen type when the field used several types in the document (a candidateMixed flag), and rebuild the schema from the cached type before deoptimising: +19/-6 lines in IndexingChain. Valid multi-type documents already run the full validation on main, so they cost almost nothing more. The repro, the regression tests and all 8,870 :lucene:core tests pass.
} else {  // a later value of a field already seen in this document
  if (fieldType != pf.candidateFieldType) {
    pf.candidateMixed = true;  // several types: the first one alone does not describe the field
  }
  if (pf.multiValueForcesDeoptimize(fieldType)) {
    pf.schema.reset(docID);   // rebuild from the earlier values, all of the cached type
    updateDocFieldSchema(fieldName, pf.schema, pf.validatedFrozenFieldType);
    pf.validatedFrozenFieldType = null;
    fields[fieldsNeedInitOrValidate++] = pf;
  }
}
// PerField.reset: candidateMixed = false;
// trySetValidatedFrozenFieldType: cache only if candidateMixed == false
All options and trade-offs4 options · 908 words
The fix has two independent parts, one per face, confirmed by running each part alone: the "mixed" flag alone fixes the row cases but not the batch face; clearing the cache in processBatch alone fixes the batch face but not the row cases. Option A was validated with gradle in a scratch worktree at ea57360912ed (removed after the runs), including the whole :lucene:core suite; option B with gradle on the closest suites; C with a one-line probe; D was not written.
Cache a type only if it was the field's only type in the document; rebuild before deoptimising (validated by the checks) (recommended)
In processDocument, a later value whose type differs from the first value's sets candidateMixed; trySetValidatedFrozenFieldType caches only when candidateMixed == false; on deoptimisation the schema is reset and rebuilt from the cached type (all earlier values in the document had it) before the new value is added.
} else {  // a later value of a field already seen in this document
  if (fieldType != pf.candidateFieldType) {
    pf.candidateMixed = true;  // several types: the first one alone does not describe the field
  }
  if (pf.multiValueForcesDeoptimize(fieldType)) {
    pf.schema.reset(docID);   // rebuild from the earlier values, all of the cached type
    updateDocFieldSchema(fieldName, pf.schema, pf.validatedFrozenFieldType);
    pf.validatedFrozenFieldType = null;
    fields[fieldsNeedInitOrValidate++] = pf;
  }
}
// PerField.reset: candidateMixed = false;
// trySetValidatedFrozenFieldType: cache only if candidateMixed == false
Trade-offs
- Almost no cost for valid documents of a field that always carries the same several types: on main every such document already deoptimises and is fully validated, because its second value's type differs from the cached one (
IndexingChain.java:625-630,:1833-1835). On main its first value still takes the fast path; with the fix each such document does oneschema.resetand one moreupdateDocFieldSchemacall (a few assignments and comparisons). Not benchmarked. - The documents that lose the fast path are single-type documents right after a multi-type document of the same field. When the other type adds a structure, these are the subset documents the bug lets through. When it adds none (
StringField+StoredField, or two types with the same schema), the first valid single-type document after a multi-type one is validated instead of skipped, as on 10.4.0; the next one is cached again. Not benchmarked. - The rebuild does not depend on every other path (such as
processBatch) clearing the cache when it leaves a foreign schema state behind. It usesFieldSchema.reset, which does not clear the skip-index type; that is the separate bug LFV-116, with its own fix.
What the checks validated
- Gradle, scratch worktree at
ea57360912ed: the repro and the reverse-orderTestPerFieldConsistencytest fail on stock (7 tests, 4 failed, seedsDEADBEEFand1234ABCD) and pass with the fix (both seeds, and with-Ptests.asserts=false);checkGoogleJavaFormatclean. - TestIndexOptions (the #15886 and #16171 cache tests), TestFieldInfos, TestColumnBatchIndexing, TestIndexWriterExceptions, TestDocValuesIndexing, TestPerFieldConsistency and the new class: 135 tests, 0 failures, 3 skipped. The whole
:lucene:core:test(seedDEADBEEF): 748 classes, 8,870 tests, 0 failures, 322 skipped. - Earlier in the hunt: the 6-test repro and the reversed upstream test pass; in the bounded-exhaustive harness this fix alone drops the 352 accepted-invalid sequences (of 246,848: 928 first documents x 133 single-field second documents, with and without a flush) and the 292 valid-rejected ones (of 123,424 document/batch/document triples) to 0; mismatch classes of the sibling bugs LFV-116 and LFV-127 remain until their fixes are added (all three together: 0). An Alloy check of the fixed cache found no counterexample in a small universe without
addBatch; the larger checks timed out.
Instead of the rebuild, add pf.validatedFrozenFieldType = null; next to pf.schema.reset(baseDocID) in processBatch (IndexingChain.java:761); +13/-6 lines.
// processBatch, first column for this field name in the batch
pf.columnFeatures = (byte) columnFeatures;
pf.validatedFrozenFieldType = null;   // the batch replaces the field's per-document schema
pf.schema.reset(baseDocID);
Trade-offs
Simpler, and it sits on the line where the sibling bug LFV-127 (a rejected document's type promoted by addBatch) also needs pf.candidateFieldType = null;, so both batch issues can be fixed in one place. It relies on every path that leaves a foreign schema state also clearing the cache.
What the checks validated
The repro 4/4 and the hunt's repro 6/6 pass; all six probe cases are rejected (fact check A); checkGoogleJavaFormat clean; the seven closest classes: 135 tests, 0 failures, 3 skipped. The full core suite was not run with this variant.
Never cache a frozen type; every document is fully validated, as in 10.4.0.
Trade-offs
Fixes both faces by construction but gives up the validation skip #15886 added for documents that repeat one frozen type. Its author reported no difference in the luceneutil benchmarks and about 10% more documents per second in doc-values-oriented macro runs of a downstream engine, measured together with another change; nothing was benchmarked here.
What the checks validated
A one-line probe that never caches a frozen type makes an independent verifier's row, batch and sort-impact tests and the hunt's repro pass.
For example, remember the set of types of the last validated document and take the fast path only for the same set.
Trade-offs
More general and keeps a fast path for multi-type fields, but more code and per-document bookkeeping. Not written or tested.
An AI tool writing an Alloy 6.2 model of IndexingChain's per-field schema checks and their frozen-type cache noticed the problem while reading the code; Alloy then produced 3-document counterexamples against a stateless reference of the per-document rule. A JUnit test on the stock jar and a bounded-exhaustive harness on the real code confirmed it.
The method in full202 words
Method: Alloy 6.2 model plus bounded-exhaustive differential testing (semi-formal: the first signal came from code reading while modelling).
- The hunting unit modelled the per-segment
FieldSchema/PerFieldstate machine ofIndexingChain, including the frozen-type cache,addBatchand flushes, with a file:line mapping to the Java code. - While writing the cache part, the AI tool saw that the cached type is the first value's type while validation runs on the union. The check
RowOnlyStockCacheSoundagainst a stateless reference of the per-document contract was satisfiable with 3-document counterexamples; with the fix,CacheFixLocalCacheSoundhad no counterexample in a small bounded universe withoutaddBatch(row-only traces; the larger fixed-model checks timed out). - A differential harness on the real jar ran every pair of a first document (928 kinds) and a second document that has only field
f(133 kinds), with and without a flush in between (246,848 sequences: 352 accepted although invalid), and every document /addBatch/ single-field document triple (928 x 133 = 123,424: 292 valid documents rejected); this fix removes both classes, and neither of the two sibling fixes does. - The counterexample was minimised to a public-API JUnit test on the stock main jar (4 of 6 fail,
-eaand-da).
No report found (2026-10-26): every apache/lucene issue, PR and comment since #15886 was opened, all 412 open PRs, the mailing lists, the JIRA archive and downstream repos. #15886 introduced it; #16171 fixed a different cache problem. Not fixed upstream.
Searches4 searches
No report of this defect was found, and no open PR changes the cache. Related, none of them this bug: #15886 (introduced it), #16171 (a follow-up that fixed re-promotion of the cache between same-schema types and widened when caching happens), #15943 / #15946 and #16309 / #16315 (flaky cache tests fixed by forceMerge), #15990 (addBatch, cites #15886 as performance work), LUCENE-10125 / #11162 (a 2021 comment naming the split-schema case as hard to optimise), #10374 (LUCENE-9334, the contract's origin). A sibling finding of this hunt, LFV-127, touches the same cache with a different defect and fix site; both are #15886 follow-ups.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene), via a scripted prior-report search | 2026-10-26 | 30 issue/PR queries (45 planned; capped by GitHub's search rate limit), 3 commit queries, comments of the top hits read | only #15886 and #16171 rank high; neither reports this |
| apache/lucene, complete enumeration | 2026-10-26 | every issue/PR (1,198), conversation comment (2,554) and review comment (2,301) updated since 2026-03-27, the day #15886 was opened, scanned for the cache identifiers and related terms | no other text names the cache |
| Open PRs | 2026-10-26 | all 412 open PRs with their changed files; the 7 touching IndexingChain, FieldType, FieldInfos or TestPerFieldConsistency read (#16847, #16734, #16269, #16116, #15330, #13525, #13342) | none touches the cache |
| Mailing lists, JIRA archive, downstream, web | 2026-10-26 | 32 queries over dev@, java-user@, issues@, commits@; 6 JIRA queries (LUCENE-10125 read in full); downstream searches in Elasticsearch, OpenSearch and Solr; 9 web queries | no report; issues@/commits@ hold only notification mirrors of #15886, #16171, #15943, #16315 |
Introduced in 10.5.0 by #15886 (9e1c6a37c6e, merged 2026-04-07): its parent rejects the documents, the commit accepts them. Affects 10.5.0, 10.5.1, 10.5.2, 10.6.0 (by reading) and main; 9.1.0 to 10.4.0 are clean. Not fixed upstream as of 2026-10-26.
Versions tested6 rows
Introduced by #15886 "Cache frozen FieldType to skip schema validation" (by @Tim-Brooks, merged by @ChrisHegarty on 2026-04-07): main 9e1c6a37c6e, branch_10x backport 9a6f19f34b2 (same patch-id). git log -S and git blame put the fast path, the skipped validation and the deoptimise-into-leftover-schema lines there.
- Widened by #16171 (
3ca085e1c77, merged 2026-06-13): it re-caches the first value's type after every validated document; not needed for the row repro. - The batch face needs
IndexWriter#addBatch, added by #15990 (3d895681557, 2026-05-14). - 10.5.0 is the first release with all three. branch_10x and branch_10_6 (10.6.0, released 2026-10-29) have the same code (read, not run). The last
IndexingChain.javachange upstream is #16708 on main and its backport #16732 on branch_10x and branch_10_6 (both 2026-09-28); neither touches the cache. - The commit-level jars are plain
javacbuilds of core, codecs and test-framework, not gradle builds; the release rows use Maven Central jars, SHA-1 checked.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed (unreleased 11.0) | affected | the repro fails 3 of 4 (-ea, -da); the hunt's repro 4 of 6 |
| 10.5.0, 10.5.1, 10.5.2 | affected | the hunt's repro fails 4 of 6 (10.5.2 also -da; 10.5.1 -ea only); the repro fails 3 of 4 on 10.5.0 (-ea, -da), 10.5.1 and 10.5.2 |
| 10.4.0, 10.3.2, 10.0.0, 9.12.3, 9.1.0 | not affected | the row tests pass: the subset documents are rejected (no cache) |
9e1c6a37c6e (#15886) vs its parent 86ba05a5982 | bisect | the row tests fail 3 of 5 on #15886 (-ea, -da) and pass on the parent |
3d895681557 (#15990, first addBatch) | affected | the hunt's repro fails 4 of 6, the batch test included |
| 9.0.0 and 8.x | not run | the per-field rule starts in 9.0.0; earlier versions allowed differing structures |
The finder, an independent reproducer, an intended-behaviour devil's advocate, reviews by an independent reviewer from another model family (OpenAI GPT-5.6) and an adjudication all found it real, each with its own executed tests; the adjudication re-ran the repros. This brief re-ran the repro and validated the fix with gradle.
Checks and verdicts453 words
Every check wrote or re-ran tests on the stock main jar; none found a convincing case for intended behaviour.
| Check | Verdict | What it found |
|---|---|---|
| Finder (Alloy model, then JUnit) | candidate | 4 of 6 fail on main (-ea, -da) and 10.5.2; the row tests pass on 10.4.0; 6/6 pass with the fix. |
| Cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6) wrote its own StringField + IntPoint test: fails on main (-ea, -da, 2 seeds) and 10.5.2, passes on 10.4.0 and with the fix. |
| Independent reproducer | real | Own row test fails 3 of 6 on main, 10.5.0 and 10.5.2, passes on 10.4.0 and 9.12.3; own batch test fails; a probe that disables the cache makes every test pass; found the top-1 sort consequence (999,999 instead of 1,000,000). |
| Works-as-designed review | real (high) | The same reviewer family, arguing "intended": own contract test fails 2 of 2 on main and passes with the fix; rated the intended argument moderate and rebutted it. |
| Devil's advocate | real (high) | No intended or misuse argument survived; its IndexOrDocValuesQuery probe fails on main and 10.5.2 and passes on 10.4.0. Its own sort probe was inconclusive and supports no claim. |
| Adjudication | confirmed (high) | Re-ran the finder's repro (-ea, -da), the independent reproduction's row test (main fails, 10.4.0 passes) and the independent reproduction's impact probe (fails). |
| This brief | re-run and fix validated | New minimal repro (3 of 4 fail on main -ea/-da, 10.5.0, 10.5.2; row tests pass on 10.4.0 and 9.12.3); the fix through gradle, closest suites and the whole core suite; each fix part tested alone. |
| Fact check A (independent AI tool, executed) | real; 7 text errors, fixed | Reproduced the bug on main, 10.5.0, 10.5.1 and 10.5.2 and the fix on main; re-ran the probe, the regression test and both impact tests; its own default-codec sort probe set the conditions of the sort consequence. Its errors (an imprecise speed-up claim, the sort conditions, diff sizes, harness counts, a backport number, a date, the fix's cost) are corrected. |
| Fact check B (OpenAI GPT-5.6, reading only) | sound; 5 errors, 5 overclaims, 8 caveats | Checked the brief against code and recorded runs without running anything. Its errors and overclaims are corrected and its caveats added (incomplete list of frozen types, the batch path's cache update, the Alloy scope, the harness classes of sibling bugs, the impact tests' codecs). |
| Diagram check (independent AI tool) | pass, no errors | Every code line, citation, state and message in the diagram matches the code; two extra probes re-ran the on-screen documents. Its six non-blocking notes are answered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 588 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,554 words
- Registry title
- The frozen-FieldType validation cache (#15886) keys a field on its first value's type, so for a field built from several field types a later document skips the per-field schema check (or is checked against stale state after a rejected addBatch), depending on value order, flushes and earlier operations
- Area
- index / IndexingChain per-field schema validation (frozen-FieldType cache)
- Priority
- Medium, rank 14: A 10.5.0 default-indexing-chain regression that skips the per-field schema check so sorts and IndexOrDocValuesQuery can later silently miss documents, but it needs the application's own invalid subset document.
- Impact class
- wrong error
- Impact note
- Applications on 10.5.0 and later (default IndexWriterConfig and codec, -ea or -da, ordinary scale) that give one field name several stock field types in a document with a shared frozen type first (StringField then SortedDocValuesField, the pairing StringField's javadoc recommends; NumericDocValuesField then LongPoint; StoredField plus doc values; KeywordField): a later document in the same in-memory segment that omits one of the field's structures is accepted, where 9.0-10.4 reject it and main still rejects it with the other value order, an unfrozen type or a flush in between, and queries or sort optimisations that use the omitted structure can then miss that document with no error (executed: a wrong top-1 of a default descending numeric sort, and an IndexOrDocValuesQuery that misses a document its own conjunction matches); separately, after an experimental addBatch on such a field is rejected, the next valid multi-type document for that field is rejected once; the triggering subset document is itself the application's mistake, and the index stays valid (CheckIndex clean).
- Summary
- You index documents whose field id is a StringField plus a SortedDocValuesField, adding the StringField first, and then a document that has only the StringField. You expect IllegalArgumentException, as Lucene's per-field consistency rule (LUCENE-9334, MIGRATE.md) requires, as 9.0-10.4 do, and as main still does when the doc-values value comes first, the type is an unfrozen copy, or a flush comes in between. Instead the document is accepted, because the frozen-FieldType cache added in 10.5.0 (#15886) caches the first value's type after the union of all the document's values was validated and then skips the check for every later document whose first value has that type; on the same fast path the schema state is not rebuilt, so after a rejected addBatch a valid StringField + StoredField document fails with 'index options: expected DOCS, but it has NONE'.
- Introduced
- 9e1c6a37c6e3 (#15886 'Cache frozen FieldType to skip schema validation', by Tim-Brooks, merged by ChrisHegarty; 10.x backport 9a6f19f34b29 with an identical patch-id; CHANGES lists it under 10.5.0 Optimizations) [read: git log -S/-G and git blame put the fast path, the skipped validation and the deoptimise-into-previous-schema lines in this commit; exec: the 5 row tests pass on its parent 86ba05a5982 and fail 3 of 5 at 9e1c6a37c6e with -ea and -da, and the reversed-order copy of the upstream TestPerFieldConsistency test behaves the same]; widened by #16171 (3ca085e1c77, 10.x eccb3394382), which re-caches the first value's type after every validated document (not needed for the row repro); symptom 2 also needs IndexWriter#addBatch, added by #15990 (3d895681557, backport #16066 / 3ec3bff01b1), where the full repro fails 4 of 6 [exec]; the skipped check itself, FieldSchema.assertSameSchema, dates from LUCENE-9334 (d03662c48bf, 9.0.0) (2026-04-07 (#15886 merged into main as 9e1c6a37c6e); 2026-05-14 (#15990, addBatch); 2026-06-14 (#16171); 10.5.0 is the first release containing all three)
- First affected version
- 10.5.0 [exec]
- Affected versions
- 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed (unreleased 11.0.0) [exec: the full finder repro fails 4 of 6 on 10.5.0, 10.5.1, 10.5.2 (also with -da) and main (-ea and -da); the 5 row tests fail 3 of 5 on 10.5.0; the reversed-order upstream test fails on 10.5.0, 10.5.2 and main; the independent reproduction's own tests fail on 10.5.0, 10.5.2 and main]; branch_10x and branch_10_6 (10.6.0, released 2026-10-29) carry the same code [read via the contents API, not run]; not affected: 9.1.0, 9.12.3, 10.0.0, 10.3.2, 10.4.0 and the parent commit of #15886, which reject the subset documents (the cache does not exist there) [exec]; 9.0.0 and 8.x not run (the per-field consistency contract starts in 9.0.0); symptom 2 cannot predate 10.5.0 because addBatch did not exist; not fixed upstream as of 2026-10-26 (upstream main head is ea57360912ed; the last IndexingChain.java change on main, branch_10x and branch_10_6 is #16708 of 2026-09-28, which does not touch the cache) [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Alloy, code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, read-only: a scripted prior-report search with 30 GitHub issue/PR queries on apache/lucene (45 planned, capped by GitHub's search rate limit), 3 commit, 5 downstream-repo, 32 mailing-list queries over dev@, java-user@, issues@ and commits@, 6 JIRA-archive queries and web; plus a complete REST enumeration of the only possible window, every apache/lucene issue/PR (1,198), conversation comment (2,554) and review comment (2,301) updated since 2026-03-27, the day #15886 was opened; the changed-file lists of all 412 open PRs, with the patches of the 7 that touch IndexingChain.java, FieldType.java, FieldInfos.java or TestPerFieldConsistency.java read (#16847, #16734, #16269, #16116, #15330, #13525, #13342; none touches the cache); 7 manual downstream searches (Elasticsearch, OpenSearch, Solr; one OpenSearch query hit a rate limit and was not retried); the finder's scripted prior-report search and the independent reproduction's and the intended-behaviour check's own searches likewise found nothing); related prior items, none of them this bug: #15886 (introduced it; its review never discusses fields made of complementary types), #16171 (outside follow-up that fixed cache re-promotion between same-schema types and widened when promotion happens), #15943 / #15946 and #16309 / #16315 (flaky cache tests fixed by forceMerge), #15990 (addBatch; cites #15886 as performance work only), LUCENE-10125 / #11162 (a 2021 committer comment that splitting a field's schema across several Field instances makes the LUCENE-9334 check hard to optimise; context that predates the cache, no defect), #10374 (LUCENE-9334, origin of the contract), #15761 (unrelated merge-thread race with the same message text)
- Lucene commit tested
- main
ea57360912ed(commit 2026-10-24; tested 2026-10-26): the JUnit repro and two regression tests with gradle in a scratch worktree, stock (assertions on and off, two seeds) and with the fix, plus 135 tests of the closest suites and the whole:lucene:coresuite (8,870 tests) with the fix, and the closest suites with a second fix variant (the worktree was removed after the runs); the repro through the repro runner on main (-ea,-da), 10.5.0 (-ea,-da), 10.5.1 and 10.5.2 (-ea), its row tests on 10.4.0, 10.0.0 and 9.12.3, and a six-case outcome probe on main, 10.5.0, 10.5.2, 10.4.0, 9.12.3, the fix and three fix variants (the brief's runs plus fact check A's re-runs); the hunt's release and commit matrix (9.1.0 to 10.5.2, #15886 and its parent). Upstream main, branch_10x and branch_10_6 had the same cache code on 2026-10-26 (read, not run).
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:610-635 (processDocument pass 1: PerField.reset with the first value's type; the field is added to the validation list only when validatedFrozenFieldType is null; multiValueForcesDeoptimize only for a later value of another type; updateDocFieldSchema skipped on the fast path), :683-697 (initAndValidateFields: initializeFieldInfo or assertSameSchema, then trySetValidatedFrozenFieldType), :1798-1801 (PerField comment 'skip schema validation if fields keep using the same frozen field type'), :1821-1843 (reset with resetJustDocId at :1825; multiValueForcesDeoptimize; trySetValidatedFrozenFieldType caches candidateFieldType if it is a frozen FieldType), :2154-2161 (FieldSchema javadoc: 'If there is inconsistency, we raise an error. This ensures that a field has the same data structures across all documents.'), :2199-2204 and :2290-2296 (assertSame, raiseNotSame, assertSameSchema)lucene/core/src/java/org/apache/lucene/document/FieldType.java:95-106 (freeze and isFrozen, the property the cache keys on)lucene/MIGRATE.md:1551-1563 ('Assumption of data consistency between different data-structures sharing the same field name': the numeric sort optimisation relies on points and doc values holding the same data; 'Require consistency between data-structures on a per-field basis': 'all subsequent documents containing this field must also have this field indexed with only doc values and points') and lucene/CHANGES.txt:4707 (LUCENE-9334)lucene/core/src/test/org/apache/lucene/document/TestPerFieldConsistency.java:135-163 (testDocWithMissingSchemaOptionsThrowsError: 'the same segment: indexing a doc with a missing field throws error')lucene/core/src/java/org/apache/lucene/document/StringField.java:22-25 (class javadoc: 'If you also need to sort on this field, separately add a SortedDocValuesField to your document.')
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:611-640, 683-697, 715-783, 1500-1534, 1798-1843, 2154-2161, 2272-2304Lucene main ea57360912ed: lucene/MIGRATE.md:1557-1564; lucene/core/src/java/org/apache/lucene/document/StringField.java:22-26; lucene/core/src/java/org/apache/lucene/document/KeywordField.java:52-62
- Who is affected
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/document/TextField.java:29-43; KnnFloatVectorField.java:70-74; lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2276-2304 (FieldSchema.reset, assertSameSchema)Lucene main ea57360912ed: lucene/MIGRATE.md:1551-1564; lucene/core/src/java/org/apache/lucene/document/StringField.java:22-26; lucene/core/src/java/org/apache/lucene/search/IndexOrDocValuesQuery.java:28-30
- Why it looks unintended
Lucene main ea57360912ed: lucene/MIGRATE.md:1557-1564; lucene/CHANGES.txt:1058 (10.5.0 Optimizations), :4707 (9.0.0)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1798-1801, 2154-2161; lucene/core/src/test/org/apache/lucene/document/TestPerFieldConsistency.java:42-62, 135-181
- Suggested fix
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:625-630, 756-783, 1833-1835
- TestFrozenTypeCacheMultiTypeField.java (JUnit test):
repro/LFV-118/src/org/apache/lucene/index/TestFrozenTypeCacheMultiTypeField.java(27 lines)
The diagram follows the six-case probe: every outcome on it was executed on main ea57360912ed (-ea, -da), 10.5.x, 10.4.0, 9.12.3 and the fix, and line numbers refer to IndexingChain.java at that commit. The PNG is the final summary card.
assets/LFV-118/bug.png(588 KB)