The repeat is caught as intended; what fails is the error message, which decodes the term as UTF-8.
DOCS_AND_CUSTOM_FREQS(new in 10.5.0) indexes a custom score per term instead of a count, so each term may occur only once per document.- IndexWriter fails a bad document in one of two ways. A non-aborting rejection throws
IllegalArgumentExceptionand skips just that document. An aborting failure closes the writer and rolls back to the last commit, because its in-memory state may be damaged.
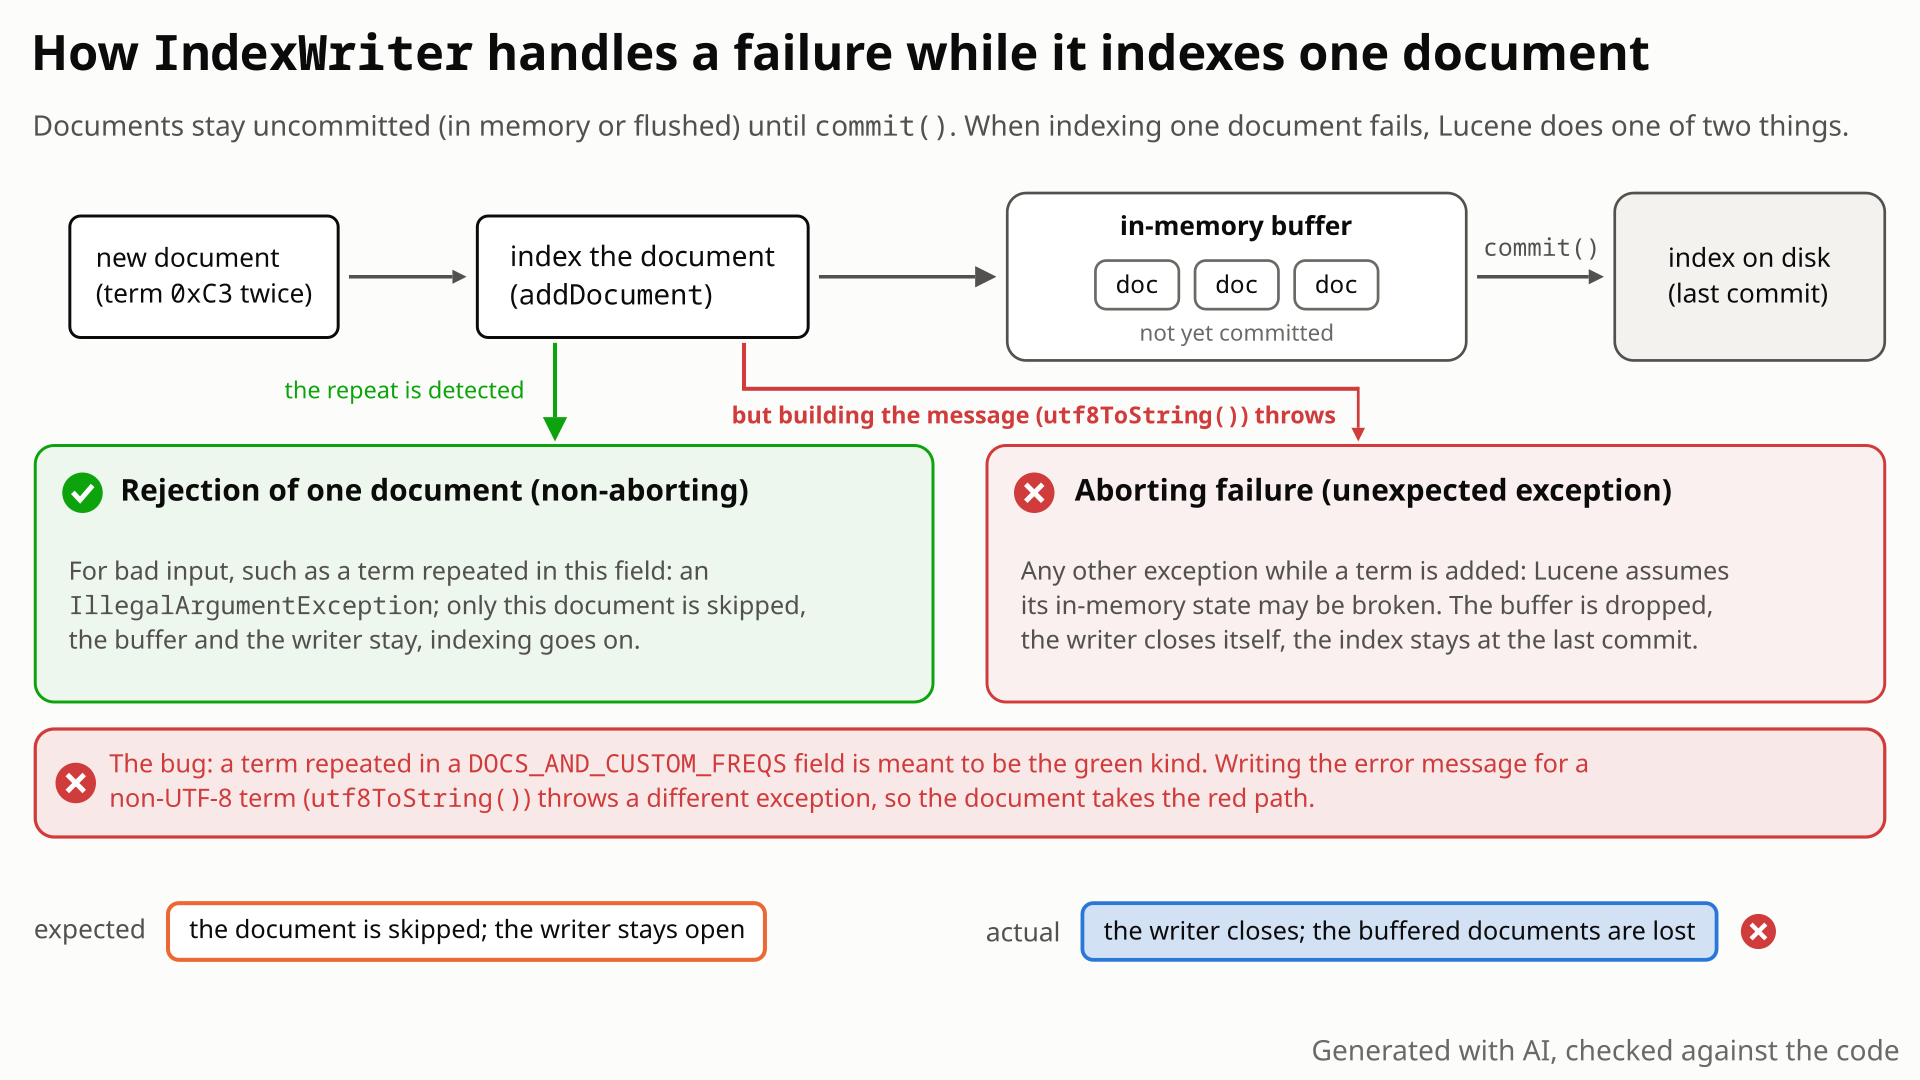
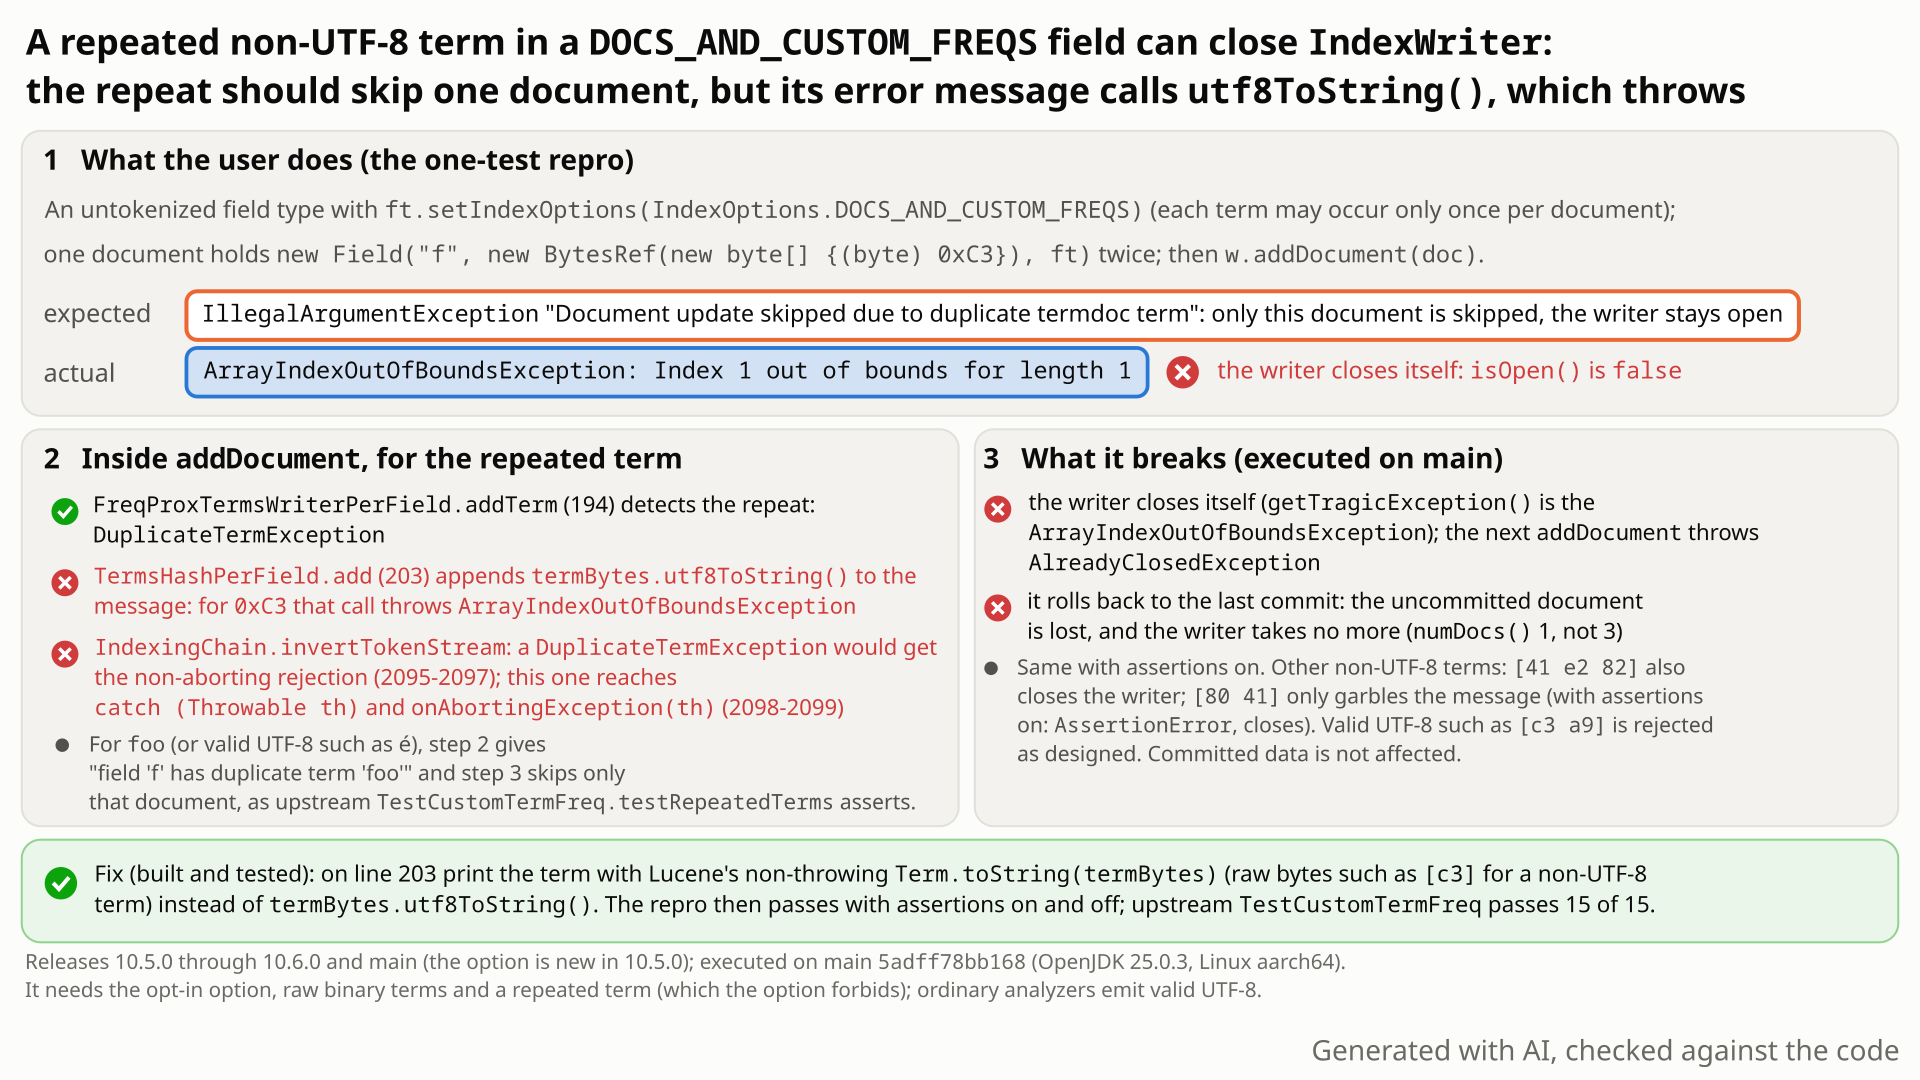
{C3} is caught as a duplicate, but building the error message decodes the term as UTF-8 and throws; the indexing chain then takes the aborting path and the writer closes instead of skipping the document. Select the still to open it at full size. Generated with AI, checked against the code.- You index raw binary terms into a field with
IndexOptions.DOCS_AND_CUSTOM_FREQS, which allows each term once per document. You commit 1 document, add a 2nd, then add a 3rd that holds the one-byte term{0xC3}twice. - You expect what happens when
foois repeated:IllegalArgumentException: Document update skipped due to duplicate termdoc term, the writer stays open, and after the next commit the index holds 2 documents. - Lucene does catch the repeat, but to put the term into the error message it decodes the bytes as UTF-8 (
utf8ToString).0xC3starts a 2-byte character and there is no 2nd byte, so the decoder reads past the 1-byte array:ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1. - That exception is not one the indexing chain treats as a per-document rejection, so IndexWriter closes itself:
isOpen()is false, and the index holds 1 document. The 2nd document, never committed, is lost.
Applications on 10.5.0 to 10.6.0 that opt into DOCS_AND_CUSTOM_FREQS for raw binary terms and pass a document that repeats one ending in a truncated UTF-8 sequence. One such document closes the writer and rolls back all uncommitted documents. Terms built from characters, as ordinary analyzers emit them, are valid UTF-8 and are rejected correctly.
Mechanism, terms and numbers637 words
IndexOptions.DOCS_AND_CUSTOM_FREQS (new in 10.5.0, #15584) stores a custom score per term and allows each term only once per document. When a document repeats a term, #15584 made addDocument reject just that document with the non-aborting IllegalArgumentException("Document update skipped due to duplicate termdoc term"); TestCustomTermFreq.testRepeatedTerms asserts the writer stays open. On the way, TermsHashPerField.add re-throws the internal DuplicateTermException with the term appended through termBytes.utf8ToString() (TermsHashPerField.java:203 at 5adff78bb168). For some binary terms that are not valid UTF-8, such as a BytesRef that holds just the byte 0xC3, that decode throws ArrayIndexOutOfBoundsException. The indexing chain treats DuplicateTermException (like a too-long term) as a per-document rejection and every other exception as aborting, so the writer records the AIOOBE as its tragic exception and closes, and every document added since the last commit is lost. A one-line fix renders the term with Lucene's existing Term.toString(BytesRef), which prints non-UTF-8 terms as bytes.
- The rejection starts as intended. For a term-doc field, a term already seen in this document throws
DuplicateTermException("field 'f' has duplicate term")(index/FreqProxTermsWriterPerField.java:193-195). - The message decoration decodes the term.
TermsHashPerField.addcatches it and re-throwsnew DuplicateTermException(e.getMessage() + " '" + termBytes.utf8ToString() + "'")(index/TermsHashPerField.java:200-204, the call at:203). This is the fix site. utf8ToStringis documented to throw on bad input: "May throw an AssertionError or a RuntimeException if the data is not well-formed UTF-8" (util/BytesRef.java:133-136). For{C3}, a 2-byte lead byte that ends its array,UnicodeUtil.UTF8toUTF16reads past the end of the 1-byte array (util/UnicodeUtil.java:649).- The indexing chain classifies by exception type. Around
termsHashPerField.add(index/IndexingChain.java:2075):MaxBytesLengthExceededExceptionbecomes a non-aborting IAE that prints the term's bytes withArrays.toString(:2076-2094);DuplicateTermExceptionbecomes the non-aborting IAE (:2095-2097); every otherThrowablegoes toonAbortingException(:2098-2100,:176-180). That marks the per-thread writer aborted (index/DocumentsWriterPerThread.java:56-60); itsmaybeAbortdrops the buffered documents and reports a tragic event (:594-605), whichIndexWriterrecords (index/IndexWriter.java:6067-6083); the catch inIndexWriter.updateDocumentsthen callsmaybeCloseOnTragicEvent(:1632-1640), which rolls the writer back and closes it (:6097-6104). - Reach.
Field(String, BytesRef, IndexableFieldType)builds an untokenized binary field (document/Field.java:187-226) that is inverted as a token stream (Field.java:460-461), so it takes this path. A customTokenStreamwith binary terms reaches it too (the devil's-advocate verifier's probe).
- Only some non-UTF-8 terms trigger it. With assertions off, the decode throws only when it runs off an array: a truncated multi-byte sequence at the end of the term's backing array, such as
[c3]or[41 e2 82]. The decoder reads pastBytesRef.length, so the backing array is what counts: a[c3]slice followed by another byte only garbles the message, while a slice that ends in a 4-byte lead byte ([f0]of[f0 90 80 80]) overruns the decoder's output array and closes the writer too. - A lone continuation byte such as
[80 41]gives a garbled message ('\u0080A': an invisible U+0080, thenA) and the writer stays open; with assertions on, that one closes the writer too, through anAssertionError. - An ASCII term (
foo,[41 42]) or a valid UTF-8 term ([c3 a9], "é") repeated the same way gets the intended rejection, and the writer stays open. - Committed data is not affected.
- Not run: the BINARY invert path (
IndexingChain.invertTerm,:2127-2170).StringFieldandKeywordFieldfix their index options toDOCS, but a customIndexableFieldthat returnsInvertableType.BINARY, or an untokenized column of the columnar API (10.6.0), can use this option. By reading,invertTermhas neither the duplicate-term catch nor the aborting catch, so there the caller would get the raw exception instead of the IAE.
Exposure and likelihood175 words
- Who. Code that indexes raw binary terms into a
DOCS_AND_CUSTOM_FREQSfield (no Lucene field class uses the option) and lets a document repeat one of them, which the option forbids. Only some byte patterns trigger it (see Scope above). - Default vs opt-in. An opt-in index option; default
IndexWriterConfigand codec otherwise. - Effect. Loud, not silent:
addDocumentthrows, the writer closes, later calls throwAlreadyClosedExceptionuntil a new writer is opened, and all documents added since the last commit are lost. No corruption was observed: the writer rolls back to the last commit, and committed data stays intact. - Scale. One document, a one-byte term; fixed input, single thread.
- Likelihood. Rare: it needs the new option, raw binary terms, a repeated term (a user error) and a byte pattern that makes the decoder run past the end.
- Text vs bytes.
CharTermAttributeterms are encoded to valid UTF-8 (unpaired surrogates become U+FFFD), so they get the intended rejection; a token stream that emits raw bytes (BytesTermAttribute, "if binary terms should be indexed") can reach the bug.
One JUnit test method on the public API: an untokenized DOCS_AND_CUSTOM_FREQS field type, one document with the one-byte term {0xC3} added twice, addDocument. It expects the IllegalArgumentException and an open writer, so it doubles as the regression test. Fixed input, single thread.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestRepeatedBinaryTermDocTerm extends LuceneTestCase {

  public void testRepeatedNonUtf8TermDoesNotCloseWriter() throws Exception {
    FieldType ft = new FieldType();
    ft.setTokenized(false);
    ft.setIndexOptions(IndexOptions.DOCS_AND_CUSTOM_FREQS);
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      Document doc = new Document();
      doc.add(new Field("f", new BytesRef(new byte[] {(byte) 0xC3}), ft));
      doc.add(new Field("f", new BytesRef(new byte[] {(byte) 0xC3}), ft));
      // Expected: IAE, writer stays open; actual: utf8ToString throws and closes the writer.
      expectThrows(IllegalArgumentException.class, () -> w.addDocument(doc));
      assertTrue(w.isOpen());
    }
  }
}
cp $REPRO/TestRepeatedBinaryTermDocTerm.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestRepeatedBinaryTermDocTerm -Ptests.seed=DEADBEEF
# same failure with -Ptests.asserts=false
- Expected
addDocumentthrowsIllegalArgumentException: Document update skipped due to duplicate termdoc termand the writer stays open.- Observed
addDocumentthrowsArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1fromBytesRef.utf8ToString, and the writer has closed itself.
More files, environment, full output238 words
TestRepeatedBinaryTermDocTerm (one method, extends LuceneTestCase, package org.apache.lucene.index of the lucene/core tests, Apache license header). Its input is fixed (LuceneTestCase still randomizes codec, similarity and locale, so the command pins a seed; an equivalent test also failed with four other seeds) and it passes checkGoogleJavaFormat. It fails the same way with assertions on and off, and passes unchanged with the recommended fix.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): fails; 10.5.0, 10.5.1, 10.5.2, 10.6.0: fail (release jars, assertions off); 10.4.0 and 9.12.3: no such index option |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (only this platform was run) |
cp $REPRO/TestRepeatedBinaryTermDocTerm.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestRepeatedBinaryTermDocTerm -Ptests.seed=DEADBEEF
# gradle, scratch worktree at 5adff78bb168, -Ptests.seed=DEADBEEF (assertions on)
TestRepeatedBinaryTermDocTerm > testRepeatedNonUtf8TermDoesNotCloseWriter FAILED
    junit.framework.AssertionFailedError: Unexpected exception type, expected IllegalArgumentException but got java.lang.ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:48CCA36ED319B27F]:0)
        ...
        Caused by:
        java.lang.ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1
            at org.apache.lucene.util.UnicodeUtil.UTF8toUTF16(UnicodeUtil.java:649)
            at org.apache.lucene.util.BytesRef.utf8ToString(BytesRef.java:139)
            at org.apache.lucene.index.TermsHashPerField.add(TermsHashPerField.java:203)
            at org.apache.lucene.index.IndexingChain$PerField.invertTokenStream(IndexingChain.java:2075)
            ...
            at org.apache.lucene.index.IndexWriter.addDocument(IndexWriter.java:1492)

# same with -Ptests.asserts=false

# control probe (1 committed doc, 1 buffered doc, then the test document; assertions off)
PROBE ASCII 'foo' twice: thrown=java.lang.IllegalArgumentException: Document update skipped due to duplicate termdoc term ... writerOpen=true tragic=null committedNumDocs=2
PROBE binary {C3} once: thrown=none writerOpen=true tragic=null committedNumDocs=3
PROBE binary {C3} twice: thrown=java.lang.ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1 writerOpen=false tragic=java.lang.ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1 committedNumDocs=1- #15584 made this rejection non-aborting on purpose: its handling "merely skips the doc being indexed (same as for a too-large term)".
TestCustomTermFreq.testRepeatedTermsasserts that after a repeated term the writer stays open and only that document is skipped.- The decode only builds a message:
utf8ToStringis documented to throw on non-UTF-8 bytes, andTerm.toStringexists to print such terms safely.
The full argument140 words
- Intent of the feature's author. #15584's author, Michael Sokolov, on 2026-03-23 (https://github.com/apache/lucene/pull/15584#issuecomment-4110154752): "found that the exception I raised for duplicate terms in termdoc fields would cause the writer to crash, so added some exception handling that merely skips the doc being indexed (same as for a too-large term)".
- Test.
TestCustomTermFreq.testRepeatedTerms(lucene/core/src/test/org/apache/lucene/index/TestCustomTermFreq.java:106-135) expects the IAE, the cause message"field 'field' has duplicate term 'foo'", then: "ensure IndexWriter remains open and doc was skipped". - Binary terms are legal on this option. The same
{C3}term once per document is indexed fine;IndexOptions.java:52-56requires each term once per document, not UTF-8 terms. - A safe helper exists.
Term.toString(BytesRef): "If the term is not unicode, the raw bytes will be printed instead" (index/Term.java:104-122). The too-long-term handler in the sametryprints raw bytes and never decodes (IndexingChain.java:2076-2094).
The devil's-advocate check141 words
The case for intended: repeating a term breaks the option's rule ("Each term can only occur once per document", IndexOptions.java:52-56), so any exception is acceptable. Also raised: the @throws line of Field(String, BytesRef, IndexableFieldType) says it throws if the type "is indexed()" (Field.java:196-197), and IndexOptions is @lucene.experimental (IndexOptions.java:24).
Why it fails: the rule justifies rejecting the document, which Lucene already does without closing the writer for every valid UTF-8 term; nothing documents closing the writer for some byte patterns only. The @throws line is stale: the constructor does not throw for an indexed untokenized type, and the bug reproduces without that constructor through a TokenStream. @lucene.experimental means the API may change, not that misuse may close the writer. Two executed cross-model reviews and a devil's-advocate verifier built this case and all rated the bug real.
Recommended Render the term with Term.toString(termBytes) (fix A)
Render the term with Lucene's existing Term.toString(termBytes) instead of termBytes.utf8ToString() in TermsHashPerField.add (one line). Valid UTF-8 terms keep their text; others print as bytes, '[c3]'. The repro passes with assertions on and off, and it and the 3 closest suites (59 tests) pass.
-        throw new DuplicateTermException(e.getMessage() + " '" + termBytes.utf8ToString() + "'");
+        throw new DuplicateTermException(e.getMessage() + " '" + Term.toString(termBytes) + "'");
All options and trade-offs4 options · 412 words
Option A was built and checked through gradle on 5adff78bb168; B passed the finder's test only; C was not built.
In TermsHashPerField.add (TermsHashPerField.java:203), build the message with Term.toString(termBytes), which decodes strictly and falls back to the hex bytes of BytesRef.toString() for anything that is not well-formed UTF-8 (Term.java:104-122, BytesRef.java:145-157). Precedent: #7850 (LUCENE-6792) fixed the same mistake in TermsQuery.toString the same way.
-        throw new DuplicateTermException(e.getMessage() + " '" + termBytes.utf8ToString() + "'");
+        throw new DuplicateTermException(e.getMessage() + " '" + Term.toString(termBytes) + "'");
Trade-offs
- Valid UTF-8 terms keep their text (
'foo'), sotestRepeatedTermspasses unchanged; non-UTF-8 terms print as bytes,'[c3]'and'[41 e2 82]', and the writer stays open (executed in the diagram probe with the fix, assertions on and off). - Malformed input is reported, not guessed:
[80 41]also prints as bytes,'[80 41]', instead of the garbled'\u0080A'(executed). - Cost only on the error path; no hot-path change.
What the checks validated
- gradle in a scratch worktree at
5adff78bb168, seed DEADBEEF: the repro fails without the fix (assertions on and off) and passes with it (on and off). - With the fix: the repro (1),
TestCustomTermFreq(15),TestTermsHashPerField(3) andTestIndexWriterExceptions(40, 3 skipped): 59 tests, 0 failures, 3 skipped.:lucene:core:checkGoogleJavaFormatpasses. The whole core module was not run. - The adjudication's run: the independent reproducer's test passes with the fix (assertions on and off) and
TestCustomTermFreq15 of 15.
Wrap the decode in try { ... } catch (RuntimeException | AssertionError notUtf8) and print the bytes in the catch (the finder's fix).
Trade-offs
Catches AssertionError, which is unusual; with assertions off a malformed term that does not throw ([80 41]) still yields a garbled message. Passes the finder's test with assertions on; not run through gradle.
Drop the decoration from TermsHashPerField.add and add the term, through Term.toString, where IndexingChain.invertTokenStream turns the exception into the IAE (IndexingChain.java:2095-2097).
Trade-offs
Covers the token-stream path, in two files, but not the BINARY path: IndexingChain.invertTerm has no DuplicateTermException catch, so it would need the same handling, which fix A makes unnecessary. Not built.
Throw the original DuplicateTermException unchanged.
Trade-offs
Loses useful context and changes the cause message that testRepeatedTerms asserts.
A product that lets its users supply raw binary terms for such a field could have one malformed, repeated term close its writer; text through an ordinary analyzer becomes valid UTF-8 and cannot trigger it.
A proof-obligation audit of TermsHashPerField.add's contract: a repeated term in a term-doc field must always end in the non-aborting duplicate-term rejection, for every term byte sequence. The message decoration was the one step that can throw for some bytes; a one-test public-API JUnit then witnessed the writer closing.
The method in full124 words
Method: semi-formal (a proof-obligation audit of a class's contract, witnessed by an executable repro).
- The finder stated the obligation for
TermsHashPerField.add: whenpositionStreamSliceraisesDuplicateTermException,addmust raise aDuplicateTermExceptiontoo, whatever the term's bytes, becauseIndexingChainkeeps the writer open only for that type. Discharging it step by step left one step that can throw:termBytes.utf8ToString(), documented to throw on malformed UTF-8. - The finder then wrote a public-API JUnit test that fails on main with assertions on and off, and on 10.6.0 and 10.5.0, plus a control probe (ASCII repeat, binary term once, binary term twice).
- An independent reproducer, two executed cross-model reviews, a devil's-advocate verifier and an adjudication reproduced it with their own tests ("Prior reports, history and checks").
No prior report found in apache/lucene issues, PRs and commits (with the JIRA archive), the dev@, java-user@, issues@ and commits@ lists, downstream trackers or the web (searched 2026-11-03). Background only: #4016 (an old general note that term toString() methods assume UTF-8) and #7850 (the same mistake fixed elsewhere).
Searches3 searches
No public report of this bug was found. Related, not reports: #4016 (LUCENE-2942, open since 2011) says in general that toString() debug methods wrongly assume UTF-8; it predates this code by 15 years and names neither this call site, exception messages nor a closed writer. #7850 (LUCENE-6792) fixed the same mistake in TermsQuery.toString with Term.toString. #15584 (the introducing PR) was read in full; no comment mentions binary or non-UTF-8 terms. #15984 (open) shows the intended rejection for an ASCII term. #16534 and #16269 (open PRs) touch TermsHashPerField.java but not the re-throw. Limits: keyword search; GitHub search does not index review comments; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive), downstream repos | 2026-11-03, re-checked the same day | a 51-query scripted prior-report search (16 issue/PR, 3 commit, 2 downstream, 4 JIRA, 6 web), the finder's 25-query run, about 35 direct searches incl. everything created since 2026-11-01 | no report; #4016, #7850, #15584, #15984 are the nearest items |
| Open PRs | 2026-11-03 | the changed files of all 409 open apache/lucene PRs and of the 22 updated since 2026-11-02 | #16534 and #16269 touch TermsHashPerField.java; neither changes the re-throw |
| Mailing lists (dev@, java-user@, issues@, commits@) | 2026-11-03 | 20 list queries and direct lists.apache.org searches | only the issues@ mirror of #15984 and commit mails |
Introduced with the index option by #15584 (Michael Sokolov, merged 2026-04-24; first release 10.5.0), in the same diff as the non-aborting rejection it defeats. Every release run, 10.5.0 to 10.6.0, and main fail; 10.4.0 and 9.12.3 lack the option. Not fixed upstream.
Versions tested4 rows
Introduced by #15584 "Compute 'length' of fields with custom term frequencies as docFreq" (Michael Sokolov): 5158a52a082 on main, cherry-picked to branch_10x as 3a55cc9ac5e, both 2026-04-24. The same diff added DOCS_AND_CUSTOM_FREQS, the duplicate-term throw, the non-aborting catch and the utf8ToString decoration. First release 10.5.0 (CHANGES: "GITHUB#15584: Add support for termdoc fields that use custom term freqs").
TermsHashPerField.java:199-205 is byte-identical in 10.5.0, 10.6.0 and main; only the throwing line in UnicodeUtil.UTF8toUTF16 moves (647 in 10.5.x, 650 in 10.6.0, 649 on main). Not fixed upstream: on upstream main 1c2072f0284 (2026-11-02) the last commit on TermsHashPerField.java is still 5158a52a082.
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | gradle: fails with assertions on and off; passes with fix A |
| 10.6.0 | affected | fails (-ea, -da), same AIOOBE at UnicodeUtil.java:650; the exact repro fails too (-da) |
| 10.5.0, 10.5.1, 10.5.2 | affected | fail (the exact repro, -da, on all three; the hunt's test with the same input also with -ea on 10.5.0), AIOOBE at UnicodeUtil.java:647 |
| 10.4.0, 9.12.3 | no API | the repro does not compile: IndexOptions.DOCS_AND_CUSTOM_FREQS does not exist |
A finder, an independent reproducer, two executed cross-model reviews (OpenAI GPT-5.6, refute and intended lenses), a devil's-advocate verifier, an adjudication, an audit and a final repro check reproduced it and agree on the root cause. This doc's gradle runs reproduced it on main and validated the fix.
Checks and verdicts383 words
The cross-model reviews ran on main ea57360912ed, where TermsHashPerField, FreqProxTermsWriterPerField, BytesRef, UnicodeUtil, Term and Field are identical to 5adff78bb168 and IndexingChain.java differs only in unrelated columnar vector code (#16734). The other checks on main ran on 5adff78bb168; the release runs used each release's own jars.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Test fails on main (assertions on and off), 10.6.0 and 10.5.0; control probe: foo repeated keeps the writer open, {C3} repeated closes it and the index keeps 1 document. |
| independent reproducer | real | Own test (also asserts the IAE message) fails on main, 10.6.0, 10.5.2 and 10.5.0; controls foo and C3 A9 keep the writer open with both documents. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Own 2-test class fails 1 of 2, controls pass; a direct test sees the tragic close and the rollback; with the fix both pass, as does testRepeatedTerms. |
| cross-model review, intended lens (OpenAI GPT-5.6, executed) | real (high) | The once-per-document rule supports rejecting the document, not closing the writer for malformed UTF-8 only; own test passes with the fix. |
| devil's-advocate verifier | real | Same close through a TokenStream with binary terms ([41 e2 82]); [80 41] aborts only with assertions on; every intended argument fails. |
| adjudication | confirmed, high, Low | Clean re-run fails (assertions off, new seed); fix A passes the reproducer's test (on and off) and TestCustomTermFreq 15 of 15. |
| separate re-run, audit and final repro check | reproduced; confirmed | Re-run and audit: the independent reproducer's equivalent test fails on main with assertions on and off (four seeds), and the re-run's fix check passes (assertions off). Final repro check: the one-test repro fails on main with assertions on and off and passes with fix A. |
| this doc | reproduced; fix A validated | gradle without and with the fix, assertions on and off; with the fix, the repro and the 3 closest suites pass (59 tests, 3 skipped). |
| fact checks (independent; cross-model, OpenAI GPT-5.6) | real, Low; wording fixed | The fact check re-ran the exact test through gradle on main (assertions on and off) and on the 10.5.0 to 10.6.0 release jars, and fix A. Both checks found only wording errors; they are fixed in this doc. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 551 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,461 words
- Registry title
- A term repeated in one document of a DOCS_AND_CUSTOM_FREQS field closes IndexWriter, instead of skipping the document, when the term is a non-UTF-8 binary term such as the single byte 0xC3: the duplicate-term rejection builds its message with utf8ToString, which throws (since 10.5.0)
- Area
- index / IndexingChain inversion, term-doc (DOCS_AND_CUSTOM_FREQS) duplicate-term rejection (TermsHashPerField.add) x aborting-exception classification
- Priority
- Low, rank 673: In an opt-in DOCS_AND_CUSTOM_FREQS field, a document that repeats a binary term whose bytes are not valid UTF-8 (such as the single byte 0xC3) closes the IndexWriter and loses uncommitted documents, where it should skip only that document, in releases 10.5.0 through 10.6.0. It needs the new opt-in index option, raw binary terms and a repeated term (a user error the option forbids), not every malformed term triggers it, and committed data stays intact.
- Impact class
- crash
- Impact note
- Applications on 10.5.0 through 10.6.0 and main that opt into IndexOptions.DOCS_AND_CUSTOM_FREQS (new in 10.5.0; no core field type uses it) for binary terms and pass a document that repeats a term whose bytes make the UTF-8 decoder run past the end of the term's backing array (for example the single byte 0xC3, or a term ending in a truncated multi-byte lead byte): the repeat, which Lucene is designed to reject by skipping only that document, instead closes the IndexWriter as a tragic event, so the uncommitted buffered documents are lost (executed: committed numDocs 1, the buffered document gone) and later calls throw AlreadyClosedException until a new writer is opened; default IndexWriterConfig, -ea and -da, ordinary scale; with -da other malformed bytes only garble the message and the writer stays open, with -ea more of them close the writer through an AssertionError; committed data is unaffected.
- Summary
- You index binary terms into a field with IndexOptions.DOCS_AND_CUSTOM_FREQS, which allows each term only once per document, and one document repeats a term that is not valid UTF-8, for example new BytesRef(new byte[] {(byte) 0xC3}) added twice as an untokenized Field. You expect addDocument to reject only that document with the non-aborting IllegalArgumentException 'Document update skipped due to duplicate termdoc term' and the writer to stay open, as happens for an ASCII or valid UTF-8 term and as the upstream test TestCustomTermFreq.testRepeatedTerms asserts. Instead TermsHashPerField.add builds the rejection message with termBytes.utf8ToString(), which throws ArrayIndexOutOfBoundsException for these bytes; the indexing chain treats that as an aborting failure, so IndexWriter closes itself and every uncommitted document is lost.
- Introduced
- 5158a52a082b842c29918c8b955323d2a0848eb5 on main, 'Added DOCS_AND_CUSTOM_FREQS whose 'length' is docFreq (#15584)' by msokolov (PR #15584, 'Compute 'length' of fields with custom term frequencies as docFreq', milestone 10.5.0), cherry-picked to branch_10x as 3a55cc9ac5e96e39a75e837e326085c5efdc894d; the same diff added IndexOptions.DOCS_AND_CUSTOM_FREQS, the DuplicateTermException throw in FreqProxTermsWriterPerField, the non-aborting DuplicateTermException catch in IndexingChain.invertTokenStream and the termBytes.utf8ToString() message decoration in TermsHashPerField.add, so the bug is as old as the feature [read: git blame of TermsHashPerField.java lines 200-204; git log -S DuplicateTermException returns only this commit; git tag --contains 3a55cc9ac5e9 lists 10.5.0, 10.5.1, 10.5.2 and 10.6.0; exec: 10.4.0 lacks the API, 10.5.0 fails] (2026-04-24 (author date 2026-04-24T13:07:17Z, merged the same minute; the branch_10x cherry-pick was committed 2026-04-24 09:34:18 -0400); first release 10.5.0)
- First affected version
- 10.5.0 [exec: the finder's test fails with -ea and -da]; 10.4.0 and older, all 9.x included, lack the API [exec: the repro does not compile on 10.4.0 and 9.12.3, cannot find symbol IndexOptions.DOCS_AND_CUSTOM_FREQS]
- Affected versions
- 10.5.0, 10.5.1, 10.5.2, 10.6.0 (released 2026-10-29, 4ae946e5a9b) and main 5adff78bb168 (12.0.0-SNAPSHOT) [exec, JDK 25.0.3, Linux aarch64: the finder's test fails on 10.5.0 (-ea, -da), 10.5.1 (-da), 10.5.2 (-da), 10.6.0 (-ea, -da) and main (-ea, -da) in the history runs; the independent reproduction's test fails on main (-ea, -da) and on 10.6.0, 10.5.2 and 10.5.0 (-da); the adjudication's and the re-runs fail on main]; not affected: 10.4.0 and all 9.x, latest 9.12.3 (API absent) [exec: compile error]; TermsHashPerField.java lines 199-205 are byte-identical at 10.5.0, 10.6.0 and main, and only the throwing line in UnicodeUtil.UTF8toUTF16 moves (647 in 10.5.x, 650 in 10.6.0, 649 on main) [read]; not new in 10.6 (10.5.x fails); not fixed upstream as of main 1c2072f0284 (author date 2026-11-02), whose last commit on TermsHashPerField.java is still 5158a52a082 [read, GitHub API 2026-11-03]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (2026-11-03, on top of the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches; rechecked the same day): a scripted prior-report search of 51 queries (16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA-archive and 6 web queries; 331 distinct hits, 0 high) plus the finder's run of 25 queries, about 35 direct GitHub searches over apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr (including everything created since 2026-11-01), PR #15584 read in full (body, comments, reviews, review comments), the changed files of all 409 open apache/lucene PRs and of the 22 open PRs updated since 2026-11-02 (the two open PRs touching TermsHashPerField.java, #16534 and #16269, do not change the rethrow), upstream commits by path, and direct lists.apache.org queries. Related items, none of them this bug: #15584 (introducing PR; its author made the duplicate-term rejection non-aborting on purpose and nobody discussed binary terms), #15984 (open nightly failure showing the intended non-aborting rejection for an ASCII term), #4016 (LUCENE-2942, open since 2011: toString() debug methods wrongly assume UTF-8; it proposes the fallback technique but predates this code by 15 years and names neither this call site, exception messages, IndexWriter nor lost documents), #7850 (LUCENE-6792, the same mistake in TermsQuery.toString, fixed with Term.toString as its own issue), #4400 (LUCENE-3327, a utf8ToString AIOOBE in a verbose FST test).
- Lucene commit tested
- main
5adff78bb168(2026-11-02) through gradle on 2026-11-03 in a scratch worktree, with assertions on and off, without and with the fix (the repro,TestCustomTermFreq,TestTermsHashPerField,TestIndexWriterExceptions,checkGoogleJavaFormat). On the release jars of 10.5.0, 10.5.1, 10.5.2 and 10.6.0 the repro fails (assertions off; the hunt's test with the same input also failed with them on for 10.5.0 and 10.6.0); 10.4.0 and 9.12.3 lack the index option. Only Linux aarch64 with OpenJDK 25.0.3 was run.
- Finding record
lucene/core/src/java/org/apache/lucene/index/TermsHashPerField.java:190-208 (at 5adff78bb168) (add: try positionStreamSlice, catch (DuplicateTermException e) at :202, rethrow new DuplicateTermException(e.getMessage() + " '" + termBytes.utf8ToString() + "'") at :203: fix site)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2074-2100 (at 5adff78bb168) (invertTokenStream: termsHashPerField.add at :2075; MaxBytesLengthExceededException -> IAE that prints the term prefix with Arrays.toString, :2076-2094; DuplicateTermException -> non-aborting IAE 'Document update skipped due to duplicate termdoc term', :2095-2097; any other Throwable -> onAbortingException, :2098-2100)lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:193-195 (at 5adff78bb168) (isTermDoc and the term already in this document -> DuplicateTermException "field '...' has duplicate term")lucene/core/src/java/org/apache/lucene/index/IndexOptions.java:52-56 (at 5adff78bb168) (DOCS_AND_CUSTOM_FREQS: 'Each term can only occur once per document')lucene/core/src/java/org/apache/lucene/util/BytesRef.java:133-141 (at 5adff78bb168) (utf8ToString: 'May throw an AssertionError or a RuntimeException if the data is not well-formed UTF-8')lucene/core/src/java/org/apache/lucene/index/Term.java:104-108 (at 5adff78bb168) (Term.toString(BytesRef): 'If the term is not unicode, the raw bytes will be printed instead')lucene/core/src/test/org/apache/lucene/index/TestCustomTermFreq.java:106-135 (at 5adff78bb168) (testRepeatedTerms: the repeat is rejected with the IAE, its cause is the DuplicateTermException "field 'field' has duplicate term 'foo'", and 'ensure IndexWriter remains open and doc was skipped')
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:193-195 (at 5adff78bb168)lucene/core/src/java/org/apache/lucene/index/TermsHashPerField.java:190-208 (at 5adff78bb168) (add; catch at :202, re-throw with utf8ToString at :203)lucene/core/src/java/org/apache/lucene/util/BytesRef.java:133-141 (at 5adff78bb168) (utf8ToString javadoc and body); util/UnicodeUtil.java:640-650 (UTF8toUTF16)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:176-180 (at 5adff78bb168) (onAbortingException), 2074-2100 (invertTokenStream catches)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:56-60 (at 5adff78bb168) (onAbortingException), 310 and 594-605 (maybeAbort: abort, then the tragic event); index/IndexWriter.java:6067-6083 (onTragicEvent), 1632-1640 (updateDocuments' catch calls maybeCloseOnTragicEvent), 6097-6104 (maybeCloseOnTragicEvent -> rollbackInternal)lucene/core/src/java/org/apache/lucene/document/Field.java:187-226, (at 5adff78bb168) 460-461lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1958-1963 (at 5adff78bb168) (BINARY -> invertTerm), 2127-2170 (invertTerm: only a MaxBytesLengthExceededException catch); document/column/ColumnFieldAdapter.java:245-250 (untokenized columns are BINARY); test lucene/core/src/test/org/apache/lucene/index/TestDocumentWriter.java:431 (a custom BINARY field)
- Who is affected
Lucene main 5adff78bb168 git grep DOCS_AND_CUSTOM_FREQS: in lucene/core/src/java only IndexOptions, FieldInfo and the Lucene94 field-infos format; elsewhere the Lucene90 field-infos format (backward-codecs), the highlighter, luke and the test-framework; no class under lucene/core/src/java/org/apache/lucene/document sets itlucene/core/src/java/org/apache/lucene/analysis/tokenattributes/CharTermAttributeImpl.java:92-93, (at 5adff78bb168) util/UnicodeUtil.java:199-240 (UTF16toUTF8 replaces unpaired surrogates); analysis/tokenattributes/BytesTermAttribute.java:21-23, TermToBytesRefAttribute.java:46-47
- Why it looks unintended
lucene/core/src/test/org/apache/lucene/index/TestCustomTermFreq.java:106-135 (at 5adff78bb168)lucene/core/src/java/org/apache/lucene/index/IndexOptions.java:24, (at 5adff78bb168) 52-56; index/Term.java:104-122; util/BytesRef.java:133-136; document/Field.java:187-226; index/IndexingChain.java:2076-2097
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/Term.java:104-122; (at 5adff78bb168) util/BytesRef.java:145-157; index/IndexingChain.java:2095-2097
- History
lucene/CHANGES.txt:957 (at 5adff78bb168)
- Diagrams
lucene/core/src/java/org/apache/lucene/index/TermsHashPerField.java:200-204; (at 5adff78bb168) index/IndexingChain.java:2074-2100
- TestRepeatedBinaryTermDocTerm.java (lucene/core, package org.apache.lucene.index, 1 test):
repro/LFV-1189/TestRepeatedBinaryTermDocTerm.java(43 lines)
The diagram illustrates the repro's document and the control with an ASCII term (main 5adff78bb168, TermsHashPerField.java:200-204, IndexingChain.java:2074-2100).
assets/LFV-1189/bug.png(551 KB)