The merged enum keeps one slot per segment that has the field but fills only the slots of segments that hold the term. Everything else stops at getNumSubs(); toString() prints every slot, and an unfilled slot has a null slice.
- An index is made of segments. A reader over several segments keeps each segment's postings (the list of documents that contain a term) separately.
MultiTermsmerges them: for one term it returns aMultiPostingsEnumthat walks the postings of each segment that holds the term in turn, adding each segment's starting doc id.
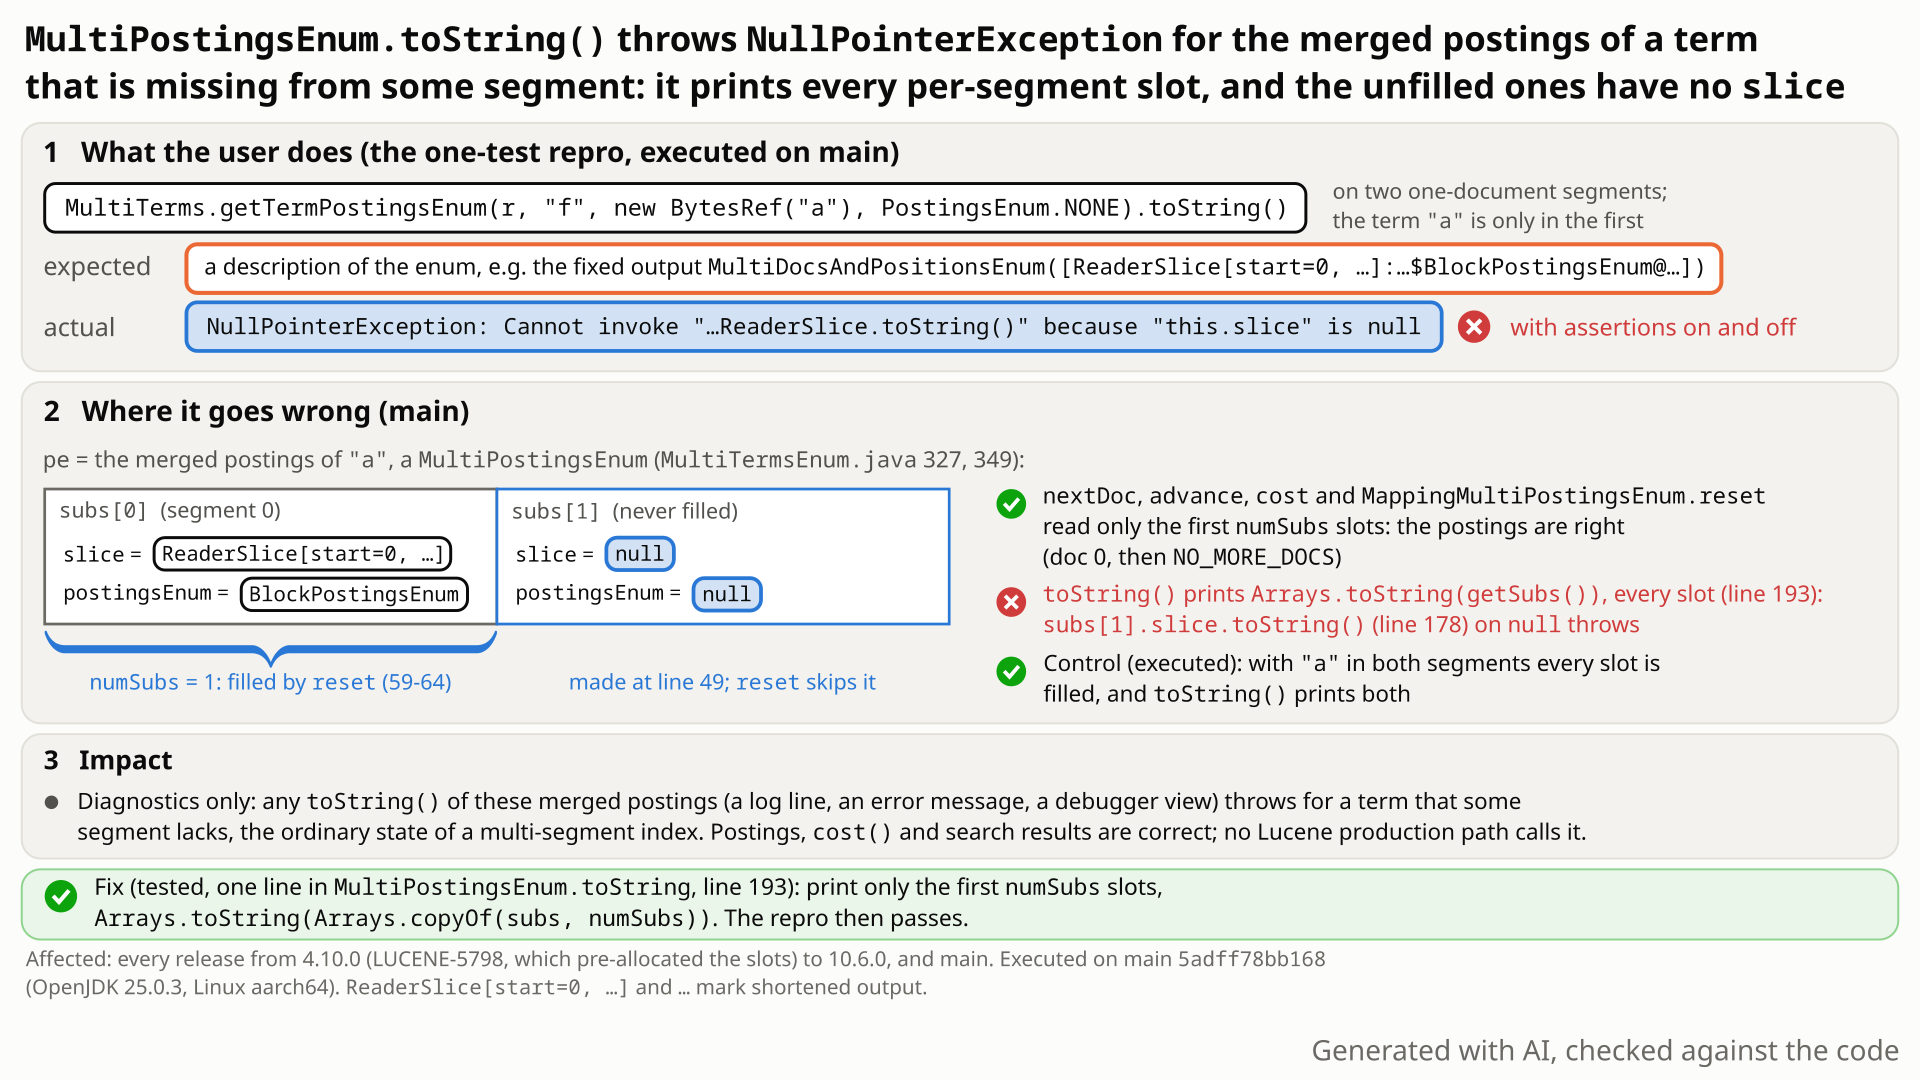
a have one slot per segment. Only slot 0 (segment 0, which holds a) is filled; slot 1 keeps a null slice. Iteration stops at getNumSubs() = 1, but toString() prints both slots and throws on slot 1. Select the still to open it at full size. Generated with AI, checked against the code.- Index 2 documents into 2 segments (
NoMergePolicy, a commit after each): doc 0 hasf:a, doc 1 hasf:b. - Call
MultiTerms.getTermPostingsEnum(reader, "f", new BytesRef("a"), PostingsEnum.NONE). Iterating it gives doc 0, thenNO_MORE_DOCS, which is right. - You expect
toString()to describe the enum, as it does whenais in both segments. - Instead it throws
NullPointerException: Cannot invoke "ReaderSlice.toString()" because "this.slice" is null, with assertions on and off. - Why: the enum has 2 slots, one per segment, but fills only 1 (
getNumSubs() == 1, the segment that holdsa). Iteration stops after slot 0;toString()prints both slots, and slot 1 has no slice.
Code that prints the merged postings of a multi-segment reader: a log line, an error or assertion message, a debugger view. Any term missing from a segment that has the field triggers it, with default settings. Postings, counts and search results stay correct, and no production code in the Lucene source tree calls this toString().
Mechanism, terms and numbers600 words
Reading one term's postings across a multi-segment reader (MultiTerms.getTermPostingsEnum, or MultiTerms.iterator() and postings()) returns a MultiPostingsEnum; a single-segment reader gets the segment's own enum instead (MultiTerms.java:71-73). Unless it is handed a reusable enum, MultiTermsEnum.postings creates it with one slot per segment that has the field (MultiTermsEnum.java:324, :327), and the constructor fills every slot with an empty EnumWithSlice whose slice is null (MultiPostingsEnum.java:44-51 at 5adff78bb168). reset then fills only the first numSubs slots, one per segment that holds the term (:59-69). nextDoc, advance, cost and the only other reader of getSubs() stop at numSubs, but toString() prints the whole array (:193), and EnumWithSlice.toString() calls slice.toString() (:178). So for any term missing from at least one segment that has the field, toString() on a newly created enum (getTermPostingsEnum always creates one) throws NullPointerException, with the default configuration and with assertions on and off, while the postings themselves are correct. A segment without the field gets no slot and does not trigger it. The null slots came with LUCENE-5798 (2014-07-01, first released in 4.10.0), a reuse optimization; before it every slot carried a slice. Every executed release from 4.10.0 to 10.6.0 and main fail; 4.9.0 and 4.9.1 pass. No production code in the Lucene source tree calls this toString(), so the effect is limited to logging, error messages and debuggers. A one-line fix prints only the first numSubs slots. Priority Low.
- One slot per segment. Unless it is handed a reusable enum made by the same
MultiTermsEnum,MultiTermsEnum.postingscreatesnew MultiPostingsEnum(this, subs.length)(MultiTermsEnum.java:316-328::324,:327);subshas one entry per segment that has the field (MultiTerms.java:78-85). The constructor fills every slot with an emptyEnumWithSlice,sliceandpostingsEnumbothnull(MultiPostingsEnum.java:44-51). - Only matching segments are filled.
postingspacks the segments positioned on the term intosubDocs(MultiTermsEnum.java:334-347) and callsreset(subDocs, upto)(:349);resetcopies only the firstnumSubsslots (MultiPostingsEnum.java:59-69). - Everything else honours
numSubs.getNumSubs(): "How many sub-readers we are merging. @see #getSubs" (:71-78);advanceandnextDocstop atnumSubs - 1(:113,:127);costloops tonumSubs(:185);MappingMultiPostingsEnum.reset, the only other reader ofgetSubs(), stops atgetNumSubs()(MappingMultiPostingsEnum.java:67-72). toString()does not (the fix site)."MultiDocsAndPositionsEnum(" + Arrays.toString(getSubs()) + ")"(:193) prints every slot, andEnumWithSlice.toString()isslice.toString() + ":" + postingsEnum(:178), which throws on anullslice.
In the repro, the diagram probe shows getNumSubs() = 1 and getSubs().length = 2; slot 0 holds segment 0's slice and postings, slot 1 has slice = null; cost() is 1 and nextDoc() gives 0, then NO_MORE_DOCS. For the term b (only in segment 1) slot 0 holds segment 1 and slot 1 is again empty: the slots are packed, so slot numbers are not segment numbers. With a in both segments, getNumSubs() = 2 and toString() works. A fact-check probe with a second segment that lacks the field f altogether found 1 slot, getNumSubs() = 1, and a toString() that prints: a segment without the field gets no slot.
A side effect of the same line: reset never clears the tail, so a reused enum prints a slot left over from an earlier term instead of throwing (seen once in the independent reproducer's control). The same fix covers it; it is not a separate claim.
Exposure and likelihood152 words
- Who. Application or test code that calls
toString()on whatMultiTerms.getTermPostingsEnumorMultiTerms.iterator().postings()returns, directly, by string concatenation or through a debugger. No production path in the Lucene source tree calls it; downstream code was not checked. - Default vs opt-in. No special configuration: the diagram probe ran outside the test framework with the default
IndexWriterConfigand codec, and the JUnit runs failed with whatever codec the framework drew from each seed. A term missing from a segment that has the field is the normal state of a multi-segment index; a single-segment reader returns the segment's own enum and is not affected (MultiTerms.java:71-73).MultiPostingsEnumandMultiTermsare@lucene.experimental. - Effect. One unchecked
NullPointerExceptionfromtoString(); no wrong results, no index change, no hang. - Scale. Two one-document segments.
- Likelihood: rare. It needs an explicit
toString()of this enum, and no matching public report was found in the twelve years since 4.10.0.
One JUnit test method on the public API: two one-document segments, the term a only in the first, MultiTerms.getTermPostingsEnum, then toString(). Deterministic and single-threaded; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestMultiPostingsEnumToString extends LuceneTestCase {

  public void testTermMissingFromOneSegment() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
      for (String term : new String[] {"a", "b"}) {
        Document doc = new Document();
        doc.add(new StringField("f", term, Field.Store.NO));
        w.addDocument(doc);
        w.commit();
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        PostingsEnum pe =
            MultiTerms.getTermPostingsEnum(r, "f", new BytesRef("a"), PostingsEnum.NONE);
        // expected: a description of the enum; actual: NullPointerException (unfilled slot's slice is null)
        assertNotNull(pe.toString());
      }
    }
  }
}
cp $REPRO/TestMultiPostingsEnumToString.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestMultiPostingsEnumToString -Ptests.seed=DEADBEEF
# and with -Ptests.asserts=false: the same failure
- Expected
toString()returns a description of the merged enum.- Observed
NullPointerException: Cannot invoke "org.apache.lucene.index.ReaderSlice.toString()" because "this.slice" is nullatMultiPostingsEnum$EnumWithSlice.toString(MultiPostingsEnum.java:178).
More files, environment, full output169 words
TestMultiPostingsEnumToString (one method, extends LuceneTestCase, package org.apache.lucene.index of the lucene/core tests). It uses a ByteBuffersDirectory and new IndexWriterConfig() with NoMergePolicy, so the method itself draws no random values; the framework still picks the default codec, similarity and locale from the seed, and it failed on every recorded seed. About 1 s.
As a regression test the same method fits in TestMultiFields; checkGoogleJavaFormat flags only its 108-character comment line.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): fails; 9.12.3, 10.5.2, 10.6.0: the same or an equivalent test fails; 4.10.0 to 8.11.4 (6 releases): a main() probe fails; 4.9.0, 4.9.1: clean |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestMultiPostingsEnumToString.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestMultiPostingsEnumToString -Ptests.seed=DEADBEEF
# and with -Ptests.asserts=false: the same failure
TestMultiPostingsEnumToString > testTermMissingFromOneSegment FAILED
    java.lang.NullPointerException: Cannot invoke "org.apache.lucene.index.ReaderSlice.toString()" because "this.slice" is null
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1914E18AA0417813]:0)
        at org.apache.lucene.index.MultiPostingsEnum$EnumWithSlice.toString(MultiPostingsEnum.java:178)
        at java.base/java.lang.String.valueOf(String.java:4530)
        at java.base/java.util.Arrays.toString(Arrays.java:4963)
        at org.apache.lucene.index.MultiPostingsEnum.toString(MultiPostingsEnum.java:193)
        at org.apache.lucene.index.TestMultiPostingsEnumToString.testTermMissingFromOneSegment(TestMultiPostingsEnumToString.java:43)
1 test completed, 1 failed

# with -Ptests.asserts=false: the same exception and framesgetNumSubs()is documented as the count forgetSubs();nextDoc,advance,costand the othergetSubs()reader all stop there.toString()is the one outlier.- Until 4.9.1 every slot carried a slice; the null slots came with a 2014 reuse optimization (LUCENE-5798) that never discussed
toString(). - Upstream fixes
toString()exceptions as bugs (LUCENE-8130).
The full argument215 words
- Contract.
getNumSubs(): "How many sub-readers we are merging. @see #getSubs" (MultiPostingsEnum.java:71-75);getSubs(): "Returns sub-readers we are merging." (:80), yet it returns the whole slot array.toString()has no javadoc.MultiTerms.getTermPostingsEnumis a public static helper with no precondition that the term be in every segment (MultiTerms.java:106-124). - History. Today's
MultiPostingsEnumis the oldMultiDocsAndPositionsEnum, renamed by LUCENE-4524 (ad18a0ea95eon branch_5x, first released in 5.1.0;c13216934c5on trunk), which also removed its siblingMultiDocsEnum. Both of itstoString()methods (the enum's andEnumWithSlice's) came with24092aab4cd("add toString for debugging", Robert Muir, 2012-07-21);MultiDocsEnumhad had the same pair since21b7c5bbee1(LUCENE-3584, 2011-11-30). Until 4.9.1,reset()built new slots by copying allsubs.lengthentries ofMultiTermsEnum's array, whose slices are always set (MultiTermsEnum.java:69-74). LUCENE-5798 ("Optimize MultiDocsEnum reuse",489b8e82a8con branch_4x,04ef241474don trunk, Robert Muir, 2014-07-01; #6860; listed under 4.10.0 Optimizations,lucene/CHANGES.txt:11974) pre-allocated empty slots and copied onlynumSubsof them. Its discussion is about garbage, nevertoString(). - Tests. No test under
lucene/namesMultiPostingsEnumorEnumWithSlice, so nothing checks thistoString(). - Precedent. "LUCENE-8130: Fix NullPointerException from TermStates.toString()" is listed under 7.3.0 Bug Fixes (
lucene/CHANGES.txt:7696, #9178); #3600, #2357 and #2323 fixed othertoString()exceptions as bugs.
The devil's-advocate check131 words
The strongest case for "intended": toString() is a debugging aid on an @lucene.experimental class, and it simply dumps the raw slot array.
Why it fails: @lucene.experimental is about API stability, not about a valid call throwing; a dump that throws on the most ordinary state is not a faithful dump; the slots past numSubs belong to no segment of the current term; and the method did not throw before 4.10.0. That getSubs() hands out the whole array does not make the tail meaningful: its javadoc pairs it with getNumSubs(), and its only in-tree caller honours that count. The intended-lens cross-model review rated the "intentionally correct" case weak, and the devil's-advocate verifier rejected it. A maintainer may still call it too minor to fix, a fair outcome for a Low bug.
Recommended Print only the first numSubs slots (fix A)
Print only the filled slots: Arrays.toString(Arrays.copyOf(subs, numSubs)) in toString() (one line). The repro passes with assertions on and off, and 25 tests of the closest suites pass.
return "MultiDocsAndPositionsEnum(" + Arrays.toString(Arrays.copyOf(subs, numSubs)) + ")";All options and trade-offs2 options · 318 words
Fix A was built and checked through gradle on 5adff78bb168; B was not run.
In MultiPostingsEnum.toString() (:193), print a copy of the first numSubs slots, as every other member reads them. The label MultiDocsAndPositionsEnum( is the class's name from before LUCENE-4524 (5.1.0); renaming it to MultiPostingsEnum( in the same line is optional and was not run.
return "MultiDocsAndPositionsEnum(" + Arrays.toString(Arrays.copyOf(subs, numSubs)) + ")";Trade-offs
Copies the first numSubs slot references (one per segment that holds the term) per toString() call, which only diagnostics pay for. It also stops a reused enum from printing a slot left over from an earlier term. On the repro's state the fix's expression, evaluated by the diagram probe through getSubs() and getNumSubs(), gives one entry, segment 0's slot; the gradle fix runs show that toString() no longer throws, not the printed string.
What the checks validated
- Gradle in a scratch worktree at
5adff78bb168, seedDEADBEEF: the repro fails without the fix (assertions on and off) and passes with it (assertions off). - With the fix and assertions on: the repro (1),
TestMultiFields(3),TestLongPostings(2),TestPayloads(7) andTestPostingsOffsets(12): 25 tests, 0 failures.checkGoogleJavaFormatfails (exit 1) on the repro as written, only for its 108-character comment line; the fix line passes. The full core suite was not run, and only OpenJDK 25.0.3 on Linux aarch64 was used. - Earlier: the hunt's runs of the same diff pass the repro with assertions on; the cross-model reviewers' runs pass their own tests and the 3
TestMultiFieldstests.
slice == null ? "<unused>" : slice.toString() + ":" + postingsEnum at :178.
Trade-offs
No exception, but the output still lists slots that belong to no segment of the term, and stale slots after reuse. Not recommended.
What the checks validated
Not run.
Downstream products are affected only where their own code logs or prints this merged postings enum; queries and documents cannot make Lucene call this toString().
A proof-obligation audit of MultiPostingsEnum's contract: toString() over the slot array must be defined in every reachable state. It is not when a term misses a segment, because the slots past getNumSubs() keep a null slice; a public-API JUnit test then witnessed the exception.
The method in full102 words
Method: semi-formal (a proof-obligation audit of a class's contract, witnessed by an executable repro).
- The finder checked each member of
MultiPostingsEnumagainst the slot invariant (slots belownumSubshold the segments of the current term; slots past it belong to no segment of the term: empty on a new enum, stale after reuse) and found that onlytoString()reads pastnumSubs. - The finder then wrote a public-API JUnit test and the one-line fix that makes it pass.
- An independent reproducer, two executed cross-model reviews, a devil's-advocate verifier and an adjudication reproduced it with their own tests ("Prior reports, history and checks").
No matching prior report found in apache/lucene issues, PRs and commits (incl. the JIRA archive), the mailing lists, downstream trackers or the web (searched 2026-11-03). Nearest: #6860 (LUCENE-5798, the introducing change) and #8577 (a design remark).
Searches3 searches
No matching public report was found in the documented searches (116 logged queries). Nearest items, none a report of this bug: #6860 (LUCENE-5798, the introducing change; nobody mentions toString), #8577 (LUCENE-7526, a design remark; its NPE is in a highlighter enum), #6752, #5091, #3797 and #5283 (other work that names getSubs or the old enum classes as context). No open PR changes MultiPostingsEnum.java. Limits: keyword search; GitHub search does not index PR diffs or every review comment; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive) | 2026-11-03, re-checked the same day | a scripted prior-report search (65 queries) and 24 manual searches: class names, the old names MultiDocsEnum and MultiDocsAndPositionsEnum, the JVM message, the last 48 h; 9 JQL queries | no report; #6860 and #8577 are the nearest |
| Open PRs | 2026-11-03 | the changed files of all 409 open apache/lucene PRs | none changes MultiPostingsEnum.java or the slot sizing |
| Mailing lists, downstream, web | 2026-11-03 | dev@, java-user@, issues@ and commits@ (12 archive queries plus the scripted search's), Elasticsearch, OpenSearch and Solr trackers, web queries | nothing about this bug |
Introduced by LUCENE-5798 (489b8e82a8c, 2014-07-01), first released in 4.10.0; 4.9.0 and 4.9.1 pass. Every executed release since fails, through 10.6.0 and main. Not fixed upstream.
Versions tested6 rows
Introduced by LUCENE-5798 "Optimize MultiDocsEnum reuse" (Robert Muir, 2014-07-01): 489b8e82a8c on branch_4x (shipped in 4.10.0) and 04ef241474d on trunk; issue #6860, no pull request (JIRA era). It pre-allocated the enum's slots with null slices and made reset() copy only numSubs of them. The toString() methods are older (24092aab4cd, 2012, in MultiDocsAndPositionsEnum, the class LUCENE-4524 renamed to MultiPostingsEnum in 5.1.0) and printed every slot before too, but then every slot had a slice.
A revert A/B isolates the change: the 4.10.0 jar with the two files from before it passes, the 4.9.0 jar with the two files from it fails. By reading, every release tag from 4.10.0 to 10.6.0 contains it and none up to 4.9.1 does. 4.x to 8.x ran a main() probe in the old API spelling; 9.12.3 and later ran the JUnit test. Upstream main 1c2072f0284 (2026-11-02) still prints Arrays.toString(getSubs()).
| Version or commit | Verdict | Result |
|---|---|---|
| 4.9.0, 4.9.1 | main() probe | pass: the unused slot prints with a slice |
| 4.10.0 with the pre-change files | revert A | pass |
| 4.9.0 with the LUCENE-5798 files | revert B | fails, same NPE |
| 4.10.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4 | main() probe | fails, same NPE |
| 9.12.3, 10.5.2, 10.6.0 | JUnit | fails, same NPE |
| main 5adff78bb168 | JUnit, -ea and -da | fails, same NPE |
A finder, an independent reproducer, two executed cross-model reviews (OpenAI GPT-5.6, real, high), a devil's-advocate verifier, an adjudication, an audit and a final repro check reproduced it. This doc's gradle runs reproduced it on main and validated fix A.
Checks and verdicts260 words
The cross-model reviews ran on the older main ea57360912ed, where the four files involved are byte-identical to 5adff78bb168. Every other check ran on 5adff78bb168 or release jars.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Own test fails on main (assertions on and off), 10.6.0 and 9.12.3; the fix makes it pass. |
| independent reproducer | real | Own test (iterates, then toString()) fails on main (on, off), 10.6.0, 10.5.2 and 9.12.3; its term-in-both-segments control prints fine; the fix makes it pass. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Own test fails with assertions on and off and two more seeds; control passes; the fix passes its tests and the 3 TestMultiFields tests. |
| cross-model review, intended lens (OpenAI GPT-5.6, executed) | real (high); intended argument weak | Own test fails on main, 10.6.0 and 9.12.3; @lucene.experimental is about API compatibility, not correctness. |
| devil's-advocate verifier | real, low severity | "Debug-only" and "raw dump by design" fail: every other member honours numSubs, and the null slots are a side effect of LUCENE-5798. |
| adjudication, separate re-runs, audit and final repro check | confirmed, Low | Fresh-seed re-runs on main and 10.6.0 fail and pass with the fix (they ran an earlier variant of the repro: newDirectory(), a 2-leaves assertion and iteration before toString()); one minimal deterministic test; first affected release corrected from 4.0 to 4.10.0. |
| this doc's fix check | reproduced; fix A validated | Gradle without the fix fails (on, off); with it the repro and 4 closest suites pass, 25 tests. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 449 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,290 words
- Registry title
- MultiPostingsEnum.toString() throws NullPointerException for the merged postings of a term that is missing from some segment (for example MultiTerms.getTermPostingsEnum on a two-segment index), because it prints every sub-reader slot and the unfilled slots have a null slice (since 4.10.0, LUCENE-5798)
- Area
- index / merged multi-segment postings (MultiPostingsEnum.toString, MultiTermsEnum.postings)
- Priority
- Low, rank 706: Calling toString() on the merged multi-segment postings view throws NullPointerException for any term missing from some segment, on default settings in every release since 4.10.0. Postings, counts and search results stay correct and no Lucene production path calls this toString, so only logging, error messages and debuggers are affected.
- Impact class
- minor
- Impact note
- Any code that calls toString() (a log line, an error or assertion message, a debugger view) on the merged postings that MultiTerms.getTermPostingsEnum or MultiTerms.iterator().postings returns for a term that is absent from at least one segment of a multi-segment reader gets a NullPointerException, with the default IndexWriterConfig and codec, -ea and -da, at any scale, in every release from 4.10.0 to 10.6.0 and on main; postings iteration, cost and search results are correct, nothing is written, and no in-tree production path calls this toString, so the effect is diagnostics only.
- Summary
- You index two documents into two segments, with the term 'a' only in the first, and ask MultiTerms.getTermPostingsEnum for the merged postings of 'a'; iterating them correctly gives doc 0 and then NO_MORE_DOCS. You expect toString() to describe the enum, as it does when the term is in every segment. Instead it throws NullPointerException 'Cannot invoke "org.apache.lucene.index.ReaderSlice.toString()" because "this.slice" is null': the enum keeps one slot per segment but fills only the slots of the segments that hold the term, and toString prints every slot, including the unfilled ones whose slice is null.
- Introduced
- 489b8e82a8c65af7d69d8a3e0ad12fa13c26f0b3 (branch_4x, svn r1607055, the commit that shipped in 4.10.0) and its trunk twin 04ef241474d616d196b10ea9798592559dcc71c2 (svn r1607049), both 'LUCENE-5798: Optimize MultiDocsEnum reuse' by Robert Muir (GitHub rmuir); issue LUCENE-5798 'minor optimizations to MultiDocs(AndPositions)Enum.reset()' = #6860 (JIRA era, no pull request; its discussion does not mention toString) [exec: revert A/B on the 4.10.0 and 4.9.0 jars; read: git show, git blame]. It pre-allocated the enum's own slots with null slices and made reset() copy only numSubs of them. Older ingredient: both toString methods date from 24092aab4cd ('add toString for debugging', 2012-07-21); they printed every slot before too, but every slot then carried a slice (2014-07-01 (author and commit date of both commits); first release 4.10.0 (release tag commit 2014-09-02))
- First affected version
- 4.10.0 [exec] (4.9.0 and 4.9.1 pass [exec]: their reset() copied every slot from MultiTermsEnum, each with a slice, so toString printed unused slots without throwing)
- Affected versions
- Every release from 4.10.0 through 10.6.0 (4ae946e5a9b) and main. Executed and reproduced: 4.10.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.12.3, 10.5.2, 10.6.0 and main 5adff78bb168 (-ea and -da) [exec]; the remaining releases contain the change [read: git merge-base --is-ancestor of 489b8e82a8c or 04ef241474d on every release tag 4.10.0..10.6.0 in the history clone, plus a source check of every tag; the clone has no 8.x tags after 8.8.1, and the executed 8.11.4 jar reproduces]. Not affected: 4.0.0-alpha to 4.9.1 (4.9.0 and 4.9.1 executed, pass); before 4.0 the class did not exist. Not fixed upstream: upstream main 1c2072f0284 (author date 2026-11-02) still prints Arrays.toString(getSubs()) [read, 2026-11-03]. Not new in 10.6.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (2026-11-03: 116 logged queries, 65 by a scripted prior-report search over apache/lucene issues and PRs, commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web, plus 24 manual GitHub searches (class names, old names MultiDocsEnum and MultiDocsAndPositionsEnum, the JVM message, the last 48 h), 9 LUCENE and SOLR JQL queries, 12 lists.apache.org queries and 6 GitHub core-API reads; the changed files of all 409 open apache/lucene PRs: none changes MultiPostingsEnum.java, and #16851, #14716, #12295, #681 (MultiTermsEnum.java) and #16847 (MultiTerms.java) do not change the slot sizing or toString; commits by author date on main, branch_10x and branch_10_6: the last change to MultiPostingsEnum.java is #13328, author date 2024-09-10, record accessors only; the finder's pass and the independent reproduction's and the intended-behaviour check's searches agree). Re-checked the same day: 'MultiPostingsEnum' still matches only #8577 and 'EnumWithSlice' only #6860; the issues and PRs created since 2026-11-01 are #16959-#16966, all unrelated; upstream main 1c2072f0284 (author date 2026-11-02) still has 'Arrays.toString(getSubs())' at MultiPostingsEnum.java:193. Nearest items, none of them this bug: #6860 (LUCENE-5798, the introducing change; nobody mentions toString), #8577 (LUCENE-7526, a design remark; its NPE is in a highlighter enum), #6752, #5091, #3797 and #5283 (features or other bugs that name getSubs or MultiDocs*Enum as context); precedents only: #9178 (LUCENE-8130, TermStates.toString NPE), #3600 (LUCENE-2526), #2357 (LUCENE-1280), #2323 (LUCENE-1246), #4908 (LUCENE-3835) and #9222 (LUCENE-8174), toString exceptions in other classes fixed as bugs.
- Lucene commit tested
- main
5adff78bb168(2026-11-02) through gradle on 2026-11-03 in a scratch worktree, seedDEADBEEF: the repro without the fix (assertions on and off: fails) and with fix A (assertions off: passes; assertions on, with 4 closest suites: 25 tests, 0 failures), pluscheckGoogleJavaFormat. The hunt ran the repro or an equivalent JUnit test on main (assertions on and off), 10.6.0, 10.5.2 and 9.12.3 (fail), and amain()probe in the old API spelling on 4.9.0 and 4.9.1 (pass), 4.10.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3 and 8.11.4 (fail), with a revert A/B of LUCENE-5798 on the 4.10.0 and 4.9.0 jars. Upstream main1c2072f0284was read on 2026-11-03. Only Linux aarch64 with OpenJDK 25.0.3 was run.
- Finding record
lucene/core/src/java/org/apache/lucene/index/MultiPostingsEnum.java:23-28 (at 5adff78bb168) (class javadoc, @lucene.experimental), :44-51 (constructor: one EnumWithSlice per sub-reader, slice and postingsEnum null), :59-69 (reset copies only the first numSubs slots), :71-83 (getNumSubs 'How many sub-readers we are merging. @see #getSubs'; getSubs returns the whole slot array), :97 and :124 (advance and nextDoc stop at numSubs - 1, :113 and :127), :176-179 (EnumWithSlice.toString: slice.toString() + ':' + postingsEnum, line 178), :183-189 (cost loops to numSubs), :191-194 (toString: 'MultiDocsAndPositionsEnum(' + Arrays.toString(getSubs()) + ')', line 193)lucene/core/src/java/org/apache/lucene/index/MultiTermsEnum.java:69-73 (at 5adff78bb168) (subDocs pre-filled with slices[i]), :316-350 (postings: new MultiPostingsEnum(this, subs.length) at :324/:327, reset(subDocs, upto) with upto = number of segments that have the term, :349)lucene/core/src/java/org/apache/lucene/index/MultiTerms.java:28 (at 5adff78bb168) (@lucene.experimental), :106-125 (getTermPostingsEnum: public static helper, no precondition about the term being in every segment); MappingMultiPostingsEnum.java:65-72 (reset iterates getSubs() only up to getNumSubs())two Lucene main checkouts: sha1 of MultiPostingsEnum.java (d601fe47368d), MultiTermsEnum.java (85dbf7e0c01b), MultiTerms.java (31eb240b5c32) and MappingMultiPostingsEnum.java (7f987f001aab) identical at ea57360912ed and 5adff78bb168 (checked 2026-11-03)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/MultiPostingsEnum.java:44-51, (at 5adff78bb168) :59-69, :71-83, :113, :127, :176-179, :183-189, :191-194lucene/core/src/java/org/apache/lucene/index/MultiTermsEnum.java:65-76, (at 5adff78bb168) :316-350lucene/core/src/java/org/apache/lucene/index/MultiTerms.java:69-93, (at 5adff78bb168) :106-124lucene/core/src/java/org/apache/lucene/index/MappingMultiPostingsEnum.java:65-72 (at 5adff78bb168)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/MultiTerms.java:28, (at 5adff78bb168) :69-93; MultiPostingsEnum.java:26
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/MultiPostingsEnum.java:23-28, (at 5adff78bb168) :71-83, :191-194; MultiTerms.java:106-124; MultiTermsEnum.java:65-76lucene/CHANGES.txt:7696 (at 5adff78bb168) (LUCENE-8130, 7.3.0 Bug Fixes), :11974 (LUCENE-5798, 4.10.0 Optimizations)grep of a Lucene main checkout lucene/ for MultiPostingsEnum and EnumWithSlice in test sources (no hit)https://github.com/apache/lucene/issues/6860, https://github.com/apache/lucene/issues/9178
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/MultiPostingsEnum.java:176-179, (at 5adff78bb168) :191-194
- Prior reports
https://github.com/apache/lucene/issues/6860, https://github.com/apache/lucene/issues/8577
- Diagrams
lucene/core/src/java/org/apache/lucene/index/MultiPostingsEnum.java:44-69, (at 5adff78bb168) :176-179, :191-194
- TestMultiPostingsEnumToString.java (lucene/core, package org.apache.lucene.index, 1 test):
repro/LFV-1190/TestMultiPostingsEnumToString.java(47 lines)
The diagram follows the repro's index and the slot contents a probe on main prints (MultiPostingsEnum.java:44-69, :178, :193).
assets/LFV-1190/bug.png(449 KB)