HnswBitVectorsFormat indexes byte vectors only and rejects float vectors with IllegalArgumentException. The indexing chain treats some failures as "aborting": the in-memory segment may be broken, so the writer drops it and closes itself. This rejection is raised inside such an aborting step.
IndexWriterbuffers new documents in memory until a flush or commit; a near-real-time (NRT) reader can already see them. Onlycommit()makes them durable.- A bad document normally gets an
IllegalArgumentExceptionfromaddDocument: only that document is dropped and the writer carries on. A vector over the format's dimension limit is rejected this way. - Some failures are "aborting": they can strike while segment files are being written, so Lucene discards the whole in-memory segment and closes the writer as a tragic event, back to the last commit.
- The first time a field appears in a segment, the indexing chain registers the field and then asks the vectors format for a per-field writer (
addField). Any exception from that call is treated as aborting.
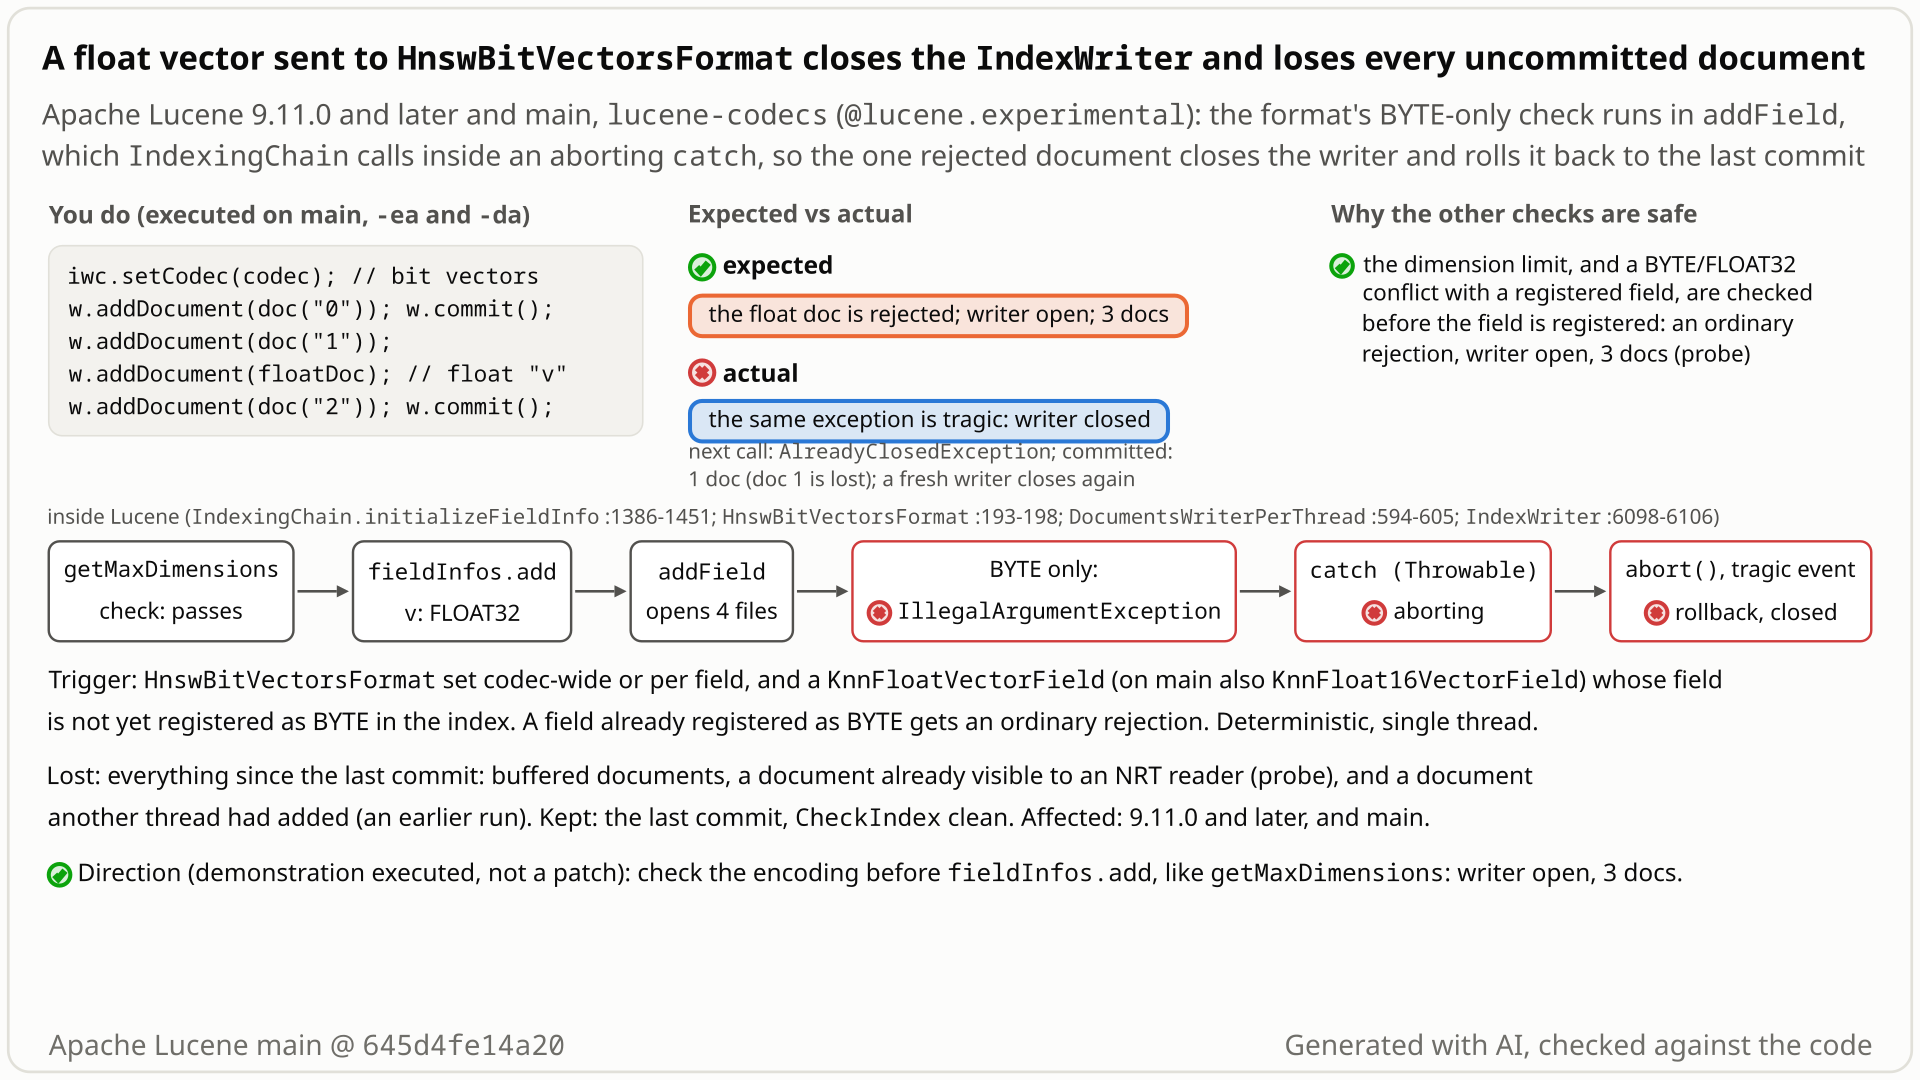
addField step, and the writer rolls back to the last commit. Select the still to open it at full size. Generated with AI, checked against the code.- You route fields named
bits*toHnswBitVectorsFormat, which indexes byte vectors only. You commit doc 1, add doc 2 (an NRT reader now sees 2 documents), then add doc 3 withKnnFloatVectorField("bits_f", {1, 2}), a field the index has not seen yet. - You expect
addDocumentto reject doc 3 and nothing else. The format's own test expects exactly that exception, and a 1025-dimension vector in the same field (over the format's 1024 limit) is rejected that way: doc 4 and a commit then leave 3 documents. - You get the expected
IllegalArgumentException, but it is also the writer's tragic exception:isOpen()isfalse, doc 4 throwsAlreadyClosedException, and the index holds 1 document. Doc 2, already visible to NRT search, is gone.CheckIndexis clean. - Why: the format rejects the field in
addField, whichIndexingChaincalls only after it has registered the field, inside acatch (Throwable)that treats every failure as aborting. The dimension limit is checked before registration, so it does not abort. - It needs a float (on main also float16) field that is not yet registered as BYTE; a field already registered as BYTE gets an ordinary rejection. Affected: all 19 releases from 9.11.0 to 10.6.0, and main.
Only applications that opt in to HnswBitVectorsFormat (lucene-codecs) and send it a float vector by mistake, on a field not yet registered as BYTE. One such document closes the shared writer and discards every caller's uncommitted documents, including NRT-visible ones; re-sending it closes the next writer too. The committed index stays intact.
Mechanism, terms and numbers536 words
HnswBitVectorsFormat (lucene-codecs, @lucene.experimental) indexes byte vectors only. Its writer rejects any other encoding in addField with IllegalArgumentException("HnswBitVectorsFormat only supports BYTE encoding"). IndexingChain#initializeFieldInfo calls addField the first time a vector field appears in a segment, after it has registered the field's FieldInfo, inside catch (Throwable th) { onAbortingException(th); throw th; }. So the per-document rejection is also recorded as an aborting exception: the in-memory segment is aborted, the exception becomes the writer's tragic exception, and IndexWriter rolls back to the last commit and closes itself. The caller receives the IllegalArgumentException it expected; the next addDocument or commit throws AlreadyClosedException. Buffered documents, documents already visible to near-real-time search and documents that other threads added successfully are all lost, and a fresh writer closes again if the application re-sends the document. The committed index stays intact and CheckIndex-clean.
The same format's other per-field limit, getMaxDimensions, is checked before the field is registered and is an ordinary rejection; the format's own test expects only the exception. Since 9.11.0, in all 19 releases that ship the format, and on main. A small pre-registration hook on KnnVectorsFormat fixes it and passes the codecs module's tests.
- Path.
IndexWriter.addDocument(IndexWriter.java:1492) ->updateDocument(:1912-1915, call at:1913) -> the privateupdateDocuments(:1625-1641) ->DocumentsWriter.updateDocuments(DocumentsWriter.java:428) ->DocumentsWriterPerThread.updateDocuments(DocumentsWriterPerThread.java:291) ->IndexingChain.processDocument(:641) ->initAndValidateFields(:685-699): the field is new in this segment, soinitializeFieldInforuns (:693,:1372). - Before registration, not aborting.
validateMaxVectorDimension(..., getMaxDimensions(pf.fieldName))(IndexingChain.java:1386-1391, plain throw at:1625). - Registration.
fieldInfos.add(new FieldInfo(...))(:1392-1413), which also checks the schema against the global field numbers (a field already registered as BYTE fails here, not aborting), thenpf.setFieldInfo(fi)(:1414). - The aborting step.
try { pf.knnFieldVectorsWriter = vectorValuesConsumer.addField(fi); } catch (Throwable th) { onAbortingException(th); throw th; }(:1445-1451).VectorValuesConsumer.addField(:68-71) creates the segment's vectors writer on first use (:52-66);PerFieldKnnVectorsFormat$FieldsWriter.addField(:118-121) picks the field's format, creates its writer on first use and puts the per-field attributes on the registeredFieldInfo(:147-185). For the bit format,fieldsWriter(HnswBitVectorsFormat.java:139-148) builds the HNSW and flat writers, which open their output files. - The throw.
FlatBitVectorsWriter#addFieldrejects any non-BYTE encoding before it delegates (HnswBitVectorsFormat.java:193-198, throw at:195). Executed stack:FlatBitVectorsWriter.addField(:195)<-PerFieldKnnVectorsFormat$FieldsWriter.addField(:120)<-VectorValuesConsumer.addField(:70)<-IndexingChain.initializeFieldInfo(:1447)<-initAndValidateFields(:693). - The close.
IndexingChain.onAbortingException(:176-180) records it in the DWPT (DocumentsWriterPerThread.java:56-60);maybeAbort("updateDocuments", ...)(:310,:594-605) aborts the DWPT and firesonTragicEvent(IndexWriter.java:6068-6084);IndexWriter.updateDocuments' catch (:1632-1640) callsmaybeCloseOnTragicEvent(:6098-6106) ->rollbackInternal(), which closes the writer without committing (rollback()javadoc,:2566-2571). TheIllegalArgumentExceptionis rethrown to the caller.
The aborting catch is defensible for codec failures that may already have changed state: by then the field is registered, the segment's vectors writer may exist with open files, and the FieldInfo carries per-field attributes. The defect is that a deterministic input check, which needs only the field name and its encoding, sits inside that catch instead of next to the dimension check.
Exposure and likelihood321 words
- Who is hit. Applications on 9.11.0 or later that configure
HnswBitVectorsFormat, codec-wide or per field throughPerFieldKnnVectorsFormat, and send it aKnnFloatVectorField(on main also aKnnFloat16VectorField) whose field name is not yet registered as BYTE: a new field, or a field committed as FLOAT32 under another format and routed to the bit format in a later session. The format is opt-in (lucene-codecs, not the default codec) and@lucene.experimental. Any index size; one document. - What goes wrong. Every later indexing or commit call on the writer throws
AlreadyClosedExceptionuntil the application opens a new one (getTragicException(),isOpen(),close()androllback()still answer), and every document since the last commit is lost: buffered documents, documents an NRT reader already showed, and a document that a second thread had added successfully (measured; in-flight documents of a concurrent thread were not measured). The caller'sIllegalArgumentExceptionlooks like an ordinary per-document rejection, so a caller that catches it and moves on finds out only on its next indexing or commit call. - Repeats. The rolled-back segment takes the field registration with it, so re-sending the same document to a fresh writer closes that writer too.
- Not affected. The committed index stays intact and
CheckIndex-clean; nothing is exposed. A field already registered as BYTE (earlier in the session or in a committed segment) gets an ordinary schema rejection and the writer stays open. - How likely. Low: it takes the opt-in, experimental format plus a float field sent to it by mistake, and that mistake usually shows on the first such document in testing. Elasticsearch ships its own bit-vector format; no use of Lucene's class was found in Solr, OpenSearch or the OpenSearch k-NN plugin (code search of default branches, not exhaustive).
- Workaround. Send the format only
KnnByteVectorFieldvalues (check the element type beforeaddDocument). Once the field is committed as BYTE, a float document is an ordinary rejection.
One JUnit test in the codecs module's bitvectors test package, public API only (Lucene plus the test framework's LuceneTestCase and TestUtil): one 2-dimension float vector, the codec pinned to HnswBitVectorsFormat, ByteBuffersDirectory, one thread, no random() in the test body. It fails with assertions on and off and passes with the fix, so it doubles as the regression test.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.bitvectors;

import java.util.List;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestBitVectorsRejectedFloatField extends LuceneTestCase {

  public void testRejectedFloatVectorDoesNotCloseWriter() throws Exception {
    IndexWriterConfig iwc = new IndexWriterConfig();
    iwc.setCodec(TestUtil.alwaysKnnVectorsFormat(new HnswBitVectorsFormat()));
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      expectThrows(
          IllegalArgumentException.class,
          () -> w.addDocument(List.of(new KnnFloatVectorField("v", new float[] {1, 2}))));
      // expected: no tragic exception, writer stays open; actual: the IAE is tragic, writer closed
      assertNull(w.getTragicException());
    }
  }
}
cp $REPRO/TestBitVectorsRejectedFloatField.java $LUCENE/lucene/codecs/src/test/org/apache/lucene/codecs/bitvectors/
cd $LUCENE && ./gradlew :lucene:codecs:test --tests org.apache.lucene.codecs.bitvectors.TestBitVectorsRejectedFloatField -Ptests.seed=DEADBEEF -Ptests.asserts=true
# and once more with -Ptests.asserts=false: it fails both ways
- Expected
addDocumentthrowsIllegalArgumentExceptionandgetTragicException()staysnull: only that document is rejected and the writer stays open.- Observed
getTragicException()is that sameIllegalArgumentException: HnswBitVectorsFormat only supports BYTE encoding: the writer has closed itself.
More files, environment, full output385 words
Copy the test into lucene/codecs/src/test/org/apache/lucene/codecs/bitvectors/ of a Lucene checkout and run the command below. TestUtil.alwaysKnnVectorsFormat sends every vector field to the bit format; the config is the default one. The test asserts the root effect only: after the expected rejection, getTragicException() must be null. The closed writer and the rollback follow from it (the index ends with 1 document instead of the expected 3, an NRT-visible document lost, in the probe numbers above).
Under gradle it fails with -Ptests.asserts=true and false on main and passes with the fix; on the standalone runner it fails on main (seeds DEADBEEF and 5EED1234), 10.5.2 and 10.6.0, with assertions on and off. TestUtil.alwaysKnnVectorsFormat is missing on 9.11.x, 9.12.x and 10.0.0; there a variant with a FilterCodec over the default codec, same body and assertion, fails the same way on 9.11.0, 9.12.3 and 10.0.0 (9.11.1 ran only the study's own portable tests, which fail too).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; also fails on the 10.5.2 and 10.6.0 release jars, and in release-portable form on 9.11.0, 9.11.1, 9.12.3 and 10.0.0; 9.10.0 has no such format |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the only platform it ran on) |
cp $REPRO/TestBitVectorsRejectedFloatField.java $LUCENE/lucene/codecs/src/test/org/apache/lucene/codecs/bitvectors/
cd $LUCENE && ./gradlew :lucene:codecs:test --tests org.apache.lucene.codecs.bitvectors.TestBitVectorsRejectedFloatField -Ptests.seed=DEADBEEF -Ptests.asserts=true
# and once more with -Ptests.asserts=false: it fails both ways
# gradle, fresh worktree at main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (the same with false)
TestBitVectorsRejectedFloatField > testRejectedFloatVectorDoesNotCloseWriter FAILED
    java.lang.AssertionError: expected null, but was:<java.lang.IllegalArgumentException: HnswBitVectorsFormat only supports BYTE encoding>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:B8FD3E78AD3F65BB]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotNull(Assert.java:756)
        at org.junit.Assert.assertNull(Assert.java:738)
        at org.junit.Assert.assertNull(Assert.java:748)
        at org.apache.lucene.codecs.bitvectors.TestBitVectorsRejectedFloatField.testRejectedFloatVectorDoesNotCloseWriter(TestBitVectorsRejectedFloatField.java:39)

# probe without the test framework, abridged (main 645d4fe14a20, -ea and -da; the same on 10.6.0, 10.5.2 and 9.11.0 with -da)
A (claim) float vector {1, 2} in a new field 'bits_f' routed to HnswBitVectorsFormat
    doc 3 addDocument threw: IllegalArgumentException: HnswBitVectorsFormat only supports BYTE encoding
    getTragicException(): IllegalArgumentException: HnswBitVectorsFormat only supports BYTE encoding
    isOpen() after: false
    add doc 4 + commit: AlreadyClosedException
    NRT numDocs before doc 3: 2
    committed numDocs at the end: 1
    CheckIndex clean: true
B (control) float vector of 1025 dims in the same new field 'bits_f' (getMaxDimensions = 1024)
    doc 3 addDocument threw: IllegalArgumentException: Field [bits_f] vector's dimensions must be <= [1024]; got 1025
    getTragicException(): null
    isOpen() after: true
    add doc 4 + commit: ok
committed numDocs at the end: 3- The format's own test,
testFloatVectorFails, expects only anIllegalArgumentExceptionfromaddDocument. - The same format's dimension limit is checked before the field is registered, a placement maintainers chose in #12436, and leaves the writer open.
- LUCENE-5662 fixed this pattern as a bug; Robert Muir's reason: an aborting input check makes you "lose other unrelated documents in IndexWriter's buffer".
The full argument356 words
- The format's test.
TestHnswBitVectorsFormat#testFloatVectorFails(TestHnswBitVectorsFormat.java:54-63) adds a 4-dimensionKnnFloatVectorFieldthroughIndexWriter.addDocumentand expects anIllegalArgumentException. It checks nothing about the writer, and its message check at:61is a no-op (containsis not asserted). - #12436 (2023). jpountz first suggested a dimension check inside
KnnVectorsWriter#addField; mayya-sharipova objected that by then theFieldInfois already in the globalFieldInfos(review comment r1275409313); jpountz then liked "retaining the property that the field info doesn't even get created if its number of dimensions is above the limit" (r1275939419), and uschindler welcomed that the check runs inaddDocument()rather than while indexing or flushing. That thread named the poisoned-FieldInfohazard, not the writer closing, and predates the bit format. - Lucene's tests.
TestIndexWriterExceptions#testNullStoredField(:1592-1614, "test a null string value doesn't abort the entire segment") assertsgetTragicException()isnullafter an inputIllegalArgumentExceptionand that the earlier document survives.BaseKnnVectorsFormatTestCase#testIllegalDimensionTooLarge(:779-795) andTestPerFieldKnnVectorsFormat#testMaxDimensionsPerFieldFormat(:217-244) keep using the writer after a codec's per-field rejection. - Precedent. LUCENE-5662 (#6724, Robert Muir): missing null checks in
Fieldaborted segments, "This is bad because you lose other unrelated documents in IndexWriter's buffer"; fixed under "Bug fixes" in 4.8.1 (CHANGES.txt:12384-12385). LUCENE-5611 made doc-values and term-vector setting errors non-aborting. LUCENE-5987 defines an aborting exception as "an exception that would otherwise cause silent data loss" (CHANGES.txt:11577-11579). - Nothing documents the close. The
IndexWriterclass javadoc names "an Error, or disaster strikes during a checkpoint" (IndexWriter.java:162-165; not a complete list);addDocumentsays that after an Exception "the index will be consistent, but this document may not have been added" (:1465-1466);getTragicExceptiongives "disk full while flushing a new segment" as its example (:6108-6112). No javadoc, comment at the catch, CHANGES or MIGRATE entry says this rejection closes the writer. - History. The aborting catch came with #992 (LUCENE-10592, 2022), with no comment about input checks. In the #13288 review the author said the wrapper writer exists because "it validates only BYTE vectors are written" and jimczi replied "Ah thanks, I missed the addField validation": meant as validation; nobody discussed that it aborts.
The devil's-advocate check243 words
The case (from the cross-model reviewer and the study's devil's advocate): a float vector is outside the domain of a byte-only, experimental format, so this is application misconfiguration. On 2024-06-05, asked on #13288 whether the format "was more a prototype and not intended for production use", its author answered yes. IndexingChain marks every Throwable from addField aborting on purpose, and addDocument promises a consistent index, not an open writer; the commit does survive.
Why it fails: the format answers this input with a deliberate IllegalArgumentException that its own test expects from addDocument, so the input is handled, not undefined; the problem is that the rejection also discards unrelated documents, the case LUCENE-5662 fixed as a bug. It does not merely fail loudly: the bad call gets its exception, but the documents discarded with it were added by calls that had already returned successfully, and those calls never report an error. The aborting catch protects against codec failures that may already have changed state, and the same IndexingChain checks the codec's dimension limit before registration: it was placed there in #12436 so that no FieldInfo is created for a rejected field and so that the check runs in addDocument rather than during indexing or flush, and that placement is why that rejection does not abort. @lucene.experimental marks an unstable API, not permission to lose writes. The argument lowers the impact and makes an "improvement" label likely; it does not make the close intended.
Recommended A pre-registration encoding hook on KnnVectorsFormat, called next to getMaxDimensions
Add a checkVectorEncoding(fieldName, encoding) hook to KnnVectorsFormat (default: accept every encoding), delegate it in PerFieldKnnVectorsFormat, override it in HnswBitVectorsFormat, and call it in IndexingChain next to the dimension check, before the field is registered. The test, the codecs module (694 tests) and core vector suites (807) pass.
// KnnVectorsFormat: the default accepts every encoding
public void checkVectorEncoding(String fieldName, VectorEncoding encoding) {}

// HnswBitVectorsFormat
@Override
public void checkVectorEncoding(String fieldName, VectorEncoding encoding) {
  if (encoding != VectorEncoding.BYTE) {
    throw new IllegalArgumentException("HnswBitVectorsFormat only supports BYTE encoding");
  }
}

// IndexingChain#initializeFieldInfo, right after validateMaxVectorDimension(...)
vectorsFormat.checkVectorEncoding(pf.fieldName, s.vectorEncoding);
All options and trade-offs4 options · 713 words
Four options; A was validated with gradle in a fresh scratch worktree at 645d4fe14a20. B and D were not executed; C is the study's root-cause demonstration, not a patch. With A the caller sees the same exception and message in the bug case; only the writer state changes. For a field already registered as BYTE in an earlier segment, the format's message replaces today's schema-consistency message (cannot change field ... from ... BYTE ... to inconsistent ... FLOAT32 ...); both are non-aborting.
A pre-registration encoding hook on KnnVectorsFormat, called next to getMaxDimensions (validated by the checks) (recommended)
4 files, +31 / -3. KnnVectorsFormat gets public void checkVectorEncoding(String fieldName, VectorEncoding encoding) {} with javadoc (the default accepts every encoding, so no other format changes); PerFieldKnnVectorsFormat delegates it to getKnnVectorsFormatForField(fieldName), like getMaxDimensions; HnswBitVectorsFormat overrides it with the same IllegalArgumentException it throws today; IndexingChain#initializeFieldInfo calls it right after validateMaxVectorDimension, before fieldInfos.add. FlatBitVectorsWriter#addField keeps its check as a backstop.
// KnnVectorsFormat: the default accepts every encoding
public void checkVectorEncoding(String fieldName, VectorEncoding encoding) {}

// HnswBitVectorsFormat
@Override
public void checkVectorEncoding(String fieldName, VectorEncoding encoding) {
  if (encoding != VectorEncoding.BYTE) {
    throw new IllegalArgumentException("HnswBitVectorsFormat only supports BYTE encoding");
  }
}

// IndexingChain#initializeFieldInfo, right after validateMaxVectorDimension(...)
vectorsFormat.checkVectorEncoding(pf.fieldName, s.vectorEncoding);
Trade-offs
- API addition: a new public, non-abstract method on
KnnVectorsFormat; backwards compatible and backportable to 10.x, but the maintainers must want it. Aboolean supportsVectorEncoding(...)would mirrorgetMaxDimensionsmore closely, at the cost of a generic message composed inIndexingChain, which does not know the per-field format's name. - Message: in the bug case the exception type and message stay as today. For a field already registered as BYTE in an earlier segment,
HnswBitVectorsFormat only supports BYTE encodingreplaces today'scannot change field "v" from ... vector encoding=BYTE ... to inconsistent ... vector encoding=FLOAT32 ...; both are non-aborting (fact-check probe, stock and with the fix). - Wrappers: a format that wraps another and delegates
getMaxDimensionsmust delegate this too; in Lucene's main sources that is onlyPerFieldKnnVectorsFormat(AssertingKnnVectorsFormatwraps the default format, which accepts everything). - Indexing path only:
FlatBitVectorsWriter#mergeOneFieldhas no encoding check, soaddIndexesor a merge that brings float segments under the bit format is a separate, untested question. - Future formats: open PR #16092's
PreconditioningKnnVectorsFormatthrows fromaddFieldfor non-FLOAT32 fields (read from the diff); it could override the same hook.
What the checks validated
Gradle in a fresh scratch worktree at 645d4fe14a20 (JDK 25.0.3, -Ptests.seed=DEADBEEF), 2026-10-30:
- without the fix the minimal test fails with
-Ptests.asserts=trueandfalse;git apply fix.diffsucceeds; with it the test passes with assertions on and off; :lucene:codecs:test, the whole module: 27 suites, 694 tests, 78 skipped, 0 failures (TestHnswBitVectorsFormat8 of 8); corecodecs.perfield.*,codecs.lucene99.*,codecs.lucene104.*,TestIndexWriterExceptions*,index.TestKnn*,search.TestKnn*: 24 suites, 807 tests, 34 skipped, 0 failures;checkGoogleJavaFormat(core, codecs),ecjLintMain(core, codecs),ecjLintTest(codecs),forbiddenApisMain(core, codecs) and corerenderJavadocpass;- a one-off scratch check (not a repro): after a rejected float32 and a rejected float16 document in new field
v, the writer is open, aKnnByteVectorFieldinvis accepted, and the commit holds 3 documents withvregistered as BYTE; - after
git apply -Rthe minimal test fails again; the worktree was removed afterwards.
Catch IllegalArgumentException from addField without calling onAbortingException. Not executed; not recommended.
Trade-offs
By then the field is registered as FLOAT32 in the segment and the global field numbers, carries per-field attributes, and the segment's vectors writer may have opened files; later BYTE documents in that field would fail the schema check for the rest of the session (the hazard named in #12436), and a blanket catch could hide real codec failures.
The study's demonstration checks the format name "HnswBitVectorsFormat" next to getMaxDimensions. With it the minimal test passes (assertions on and off) and so do the 8 TestHnswBitVectorsFormat tests.
Trade-offs
Proves the root cause, but core must not know a codecs-module format by name. Not a patch.
A javadoc note on the format. Not executed.
Trade-offs
Honest minimum, but it keeps the data loss and contradicts the format's own test.
No downstream product is known to use Lucene's HnswBitVectorsFormat (Elasticsearch ships its own bit-vector format; none was found in Solr or OpenSearch), but an application that builds float vectors from request content for such a field would let one document discard every caller's uncommitted writes.
Found by reading how IndexingChain classifies exceptions as aborting or not, while modelling its exception paths, then confirmed with a JUnit on the stock jars. No model artifact or formal tool witnessed it. An independent reproducer, cross-model reviews, a devil's advocate, an adjudication and a tie-breaker confirmed it.
The method in full139 words
Method: code reading, then executed tests (the hunt's non-formal tier).
- First signal (2026-10-25). A unit studying
IndexingChain's schema and exception handling read the aborting / non-aborting classification while building the exception-path part of an Alloy model; no model artifact was produced for it and no formal tool witnessed it. A JUnit on the stock main jars confirmed the close and the rollback. - Checks. An independent reproducer with its own test and controls, an executed cross-model works-as-designed review (OpenAI GPT-5.6), an intended-behaviour devil's advocate with 7 scope probes, and an adjudication confirmed it; a follow-up swept the releases, searched for prior reports and measured the scope of the loss; the repro was reduced to one test and one assertion; on 2026-10-30 a tie-breaker re-ran it on main, 10.6.0, 10.5.2 and 9.11.0 with a probe that uses no test framework.
No earlier report found (searched 2026-10-26 and again 2026-10-30: GitHub issues and PRs incl. the JIRA archive, mailing lists, downstream trackers, all open PRs and the web). Closest: #12436, where maintainers kept the dimension check before field registration. Open PR #16092 adds a format with the same addField pattern.
Searches4 searches
Related, not this bug: #13288 / #13316 (introduced the check; the review calls it validation and never discusses the writer closing); #992 (LUCENE-10592, added the aborting catch); open #16092 (a new format whose addField throws for non-FLOAT32 fields; read from the diff); #16211 and #14025 (feature requests that mention the format); LUCENE-5987 #7049, LUCENE-5662 #6724, LUCENE-5611 #6673 (precedents for the aborting contract); #15125, #13353, #15540, #16383, #16902, #13076 (related area, different topic). Tracking issue #16937 and its dev@ thread are not prior art; neither mentions LFV-121.
| Where | When | How | Found |
|---|---|---|---|
| Search tool (GitHub issues, PRs and commits incl. the migrated JIRA archive; dev@, java-user@, issues@, commits@; downstream repositories; web) | 2026-10-26, rerun 2026-10-30 | 51 queries (GitHub 16, commits 3, downstream 2, lists 20, JIRA 4, web 6), among them "only supports BYTE encoding", HnswBitVectorsFormat, FlatBitVectorsWriter, onAbortingException, tragic exception with vectors | 1053 hits, 0 high, 8 medium: no report of this bug |
| GitHub (apache/lucene, Elasticsearch, OpenSearch, OpenSearch k-NN, Solr) | 2026-10-26, 2026-10-30 | 39 direct issue/PR searches in the first pass, 35 in the rerun | only the introducing PRs and the related items above |
| apache/lucene recent activity and open PRs | 2026-10-30 | all 120 issues and PRs updated since 2026-10-25; the changed files of all 408 open PRs, and the patches of the 18 that touch an affected file | only #16092 has the same pattern; nothing reports or fixes this bug |
| Mailing lists and JIRA | 2026-10-26, 2026-10-30 | direct lists.apache.org queries on dev@, java-user@ and issues@; JQL searches | no report |
Introduced in 9.11.0 by #13288 (3d86ff2e6a7, backport d8a81476262, #13316, April 2024), which added the BYTE-only check in addField; the aborting catch around addField dates from #992 (9.4.0). All 19 releases from 9.11.0 to 10.6.0 are affected (6 executed, 13 read) and main; not fixed upstream.
Versions tested7 rows
Introduced by #13288 "Add BitVectors format and make flat vectors format easier to extend" (benwtrent, merged 2024-04-17 as 3d86ff2e6a7 on main; branch_9x backport d8a81476262, #13316, 2024-04-22, which shipped first, in 9.11.0). git log -S 'only supports BYTE encoding' --all finds only these two commits. The other half is older: ba4bc042714 (#992, LUCENE-10592 "Build HNSW Graph on indexing", 2022-07-22; first released in 9.4.0) put addField inside the aborting catch; before 9.11.0 no stock format threw from addField, and a custom format with the same check closes the writer on 9.10.0 too. Upstream main 2f424fd428da (2026-10-30) has the same code.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | fails with assertions on and off (gradle and the standalone runner) |
| 10.6.0, 10.5.2 | affected | fail, -ea and -da (release jars); the probe shows the close and the rollback |
| 10.0.0, 9.12.3, 9.11.1 | portable variant | fail (on 10.0.0 and 9.12.3 a FilterCodec variant of the minimal test; on 9.11.1 the study's own portable tests) |
| 9.11.0 | affected | fails, -ea and -da (portable variant); the probe shows the close |
| 9.12.0-9.12.2, 10.1.0-10.4.0, 10.5.0, 10.5.1 | read | the check and the aborting catch are at each release tag; not run |
| 9.10.0 | not applicable | the format does not exist (the repro does not compile); a custom format with the same addField check closes the writer there too |
fix A (scratch worktree at 645d4fe14a20) | not affected | the minimal test, the codecs module (694 tests) and core vector suites (807 tests) pass |
The finder, an independent reproducer, cross-model reviews, a devil's advocate and an adjudication confirmed it; a follow-up ran the release sweep and measured the loss; a tie-breaker re-ran it on main and three releases. This doc re-ran the test and validated the fix with gradle.
Checks and verdicts298 words
The verifiers and the study's reviews ran on main ea57360912ed; between it and 645d4fe14a20 no commit touches the encoding check or the addField catch.
| Check | Verdict | What it found |
|---|---|---|
| finder (IndexingChain schema unit) | candidate | Code reading of the aborting classification, a JUnit on the stock jars and the root-cause demonstration. |
| cross-model review (OpenAI GPT-5.6, reading only) | real (high) | Root cause agrees, the demonstration fixes it, inputs in contract. |
| independent reproducer | real | Own test: 2 bug cases (codec-wide, per field) fail and 3 controls (dimension limit, byte dimension mismatch, float format) pass on main, 10.5.2, 10.0.0, 9.12.3 and 9.11.1. |
| cross-model review, works-as-designed lens (OpenAI GPT-5.6, executed) | real (high) | Own lifecycle test sees the close and the loss on main and 10.5.2; its controls keep the writer open; intended argument moderate and rebutted. |
| intended-behaviour devil's advocate | real (high) | 7 scope probes: float32, float16 and a re-routed FLOAT32 field close the writer; a BYTE-registered field, a null per-field format and the dimension limit do not. |
| adjudication | confirmed (high), crash | Re-ran the independent reproduction's test with -ea and -da; wording corrections. |
| cross-model review, refute lens (OpenAI GPT-5.6) | no verdict, then not real (medium) without running code | The study run stopped without a verdict; the 2026-10-30 rerun could run nothing, agreed with the root cause and argued works-as-designed, answered in the devil's advocate above. |
| tie-breaker | real | The reviews disagreed on no executed fact; a probe without the test framework shows the close and the rollback on main, 10.6.0, 10.5.2 and 9.11.0, with 3 controls as expected. |
| this doc (2026-10-30) | reproduced, fix validated | Gradle in a fresh 645d4fe14a20 worktree without and with fix A; codecs module and core vector suites; format, lint and javadoc checks; revert check. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 462 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,430 words
- Registry title
- A float vector field routed to HnswBitVectorsFormat is rejected inside an aborting step of the indexing chain, so the one rejected document closes the IndexWriter and rolls back every document added since the last commit
- Area
- codecs / HnswBitVectorsFormat x index / IndexingChain aborting-exception classification
- Priority
- Low, rank 671: Moved down from Medium: one float vector sent to the opt-in, experimental HnswBitVectorsFormat closes the IndexWriter and rolls back every thread's uncommitted docs, severe but loud, caused by an application programming error, and the committed index stays intact.
- Impact class
- crash
- Impact note
- Applications on 9.11.0 and later that use the opt-in, @lucene.experimental HnswBitVectorsFormat from lucene-codecs (codec-wide or per field) and send it a KnnFloatVectorField (on main also a KnnFloat16VectorField) whose field name is not yet registered as BYTE in the index: that one document throws the format's IllegalArgumentException and also closes the IndexWriter as a tragic event, so every document added since the last commit is rolled back (measured: buffered documents, documents already visible to an NRT reader, and a document another thread had added successfully), and a fresh writer closes again on the same document; -ea and -da, ordinary scale; the committed index stays intact and CheckIndex-clean, and a field already registered as BYTE gets an ordinary rejection that leaves the writer open.
- Summary
- You use HnswBitVectorsFormat, which accepts only byte vectors, and by mistake add a document with a float vector field (KnnFloatVectorField) that is new to the index. You expect addDocument to reject that one document with IllegalArgumentException and the writer to stay open, as the format's own test TestHnswBitVectorsFormat#testFloatVectorFails expects the exception and as happens for the same codec's dimension limit and for a vector dimension mismatch. Instead the check sits in KnnVectorsWriter#addField, which IndexingChain calls after registering the field and treats as an aborting step, so the exception also becomes the writer's tragic exception: IndexWriter closes itself, the next call throws AlreadyClosedException, and the documents added since the last commit are gone (the repro ends with 1 committed document instead of 3).
- Introduced
- 3d86ff2e6a72 (#13288 'Add BitVectors format and make flat vectors format easier to extend', by benwtrent; branch_9x backport d8a814762623, #13316), which added FlatBitVectorsWriter#addField with the BYTE-only IllegalArgumentException [read: git log -S 'only supports BYTE encoding' over the full main history returns only this commit; git blame attributes HnswBitVectorsFormat.java:193-198 to it, unchanged since]; the other half of the root cause is older and was latent until then: ba4bc0427146 (#992, LUCENE-10592 'Build HNSW Graph on indexing', by mayya-sharipova; branch_9x a65a41855c7, #1043; first released in 9.4.0) put vectorValuesConsumer.addField after fieldInfos.add inside catch (Throwable) -> onAbortingException [read: git blame IndexingChain.java:1391-1396; exec: a custom format with the same addField check closes the writer on 9.10.0 too (follow-up history control), while the bit-vector repro does not compile there] (2024-04-17 (#13288 merged into main as 3d86ff2e6a72); 2024-04-22 (#13316, branch_9x); the aborting catch dates from 2022-07-22 (#992); 9.11.0 tagged 2024-06-06)
- First affected version
- 9.11.0 [exec]; on the main line 10.0.0 [exec]
- Affected versions
- all 18 releases that ship the format: 9.11.0, 9.11.1, 9.12.0-9.12.3, 10.0.0, 10.1.0, 10.2.0-10.2.2, 10.3.0-10.3.2, 10.4.0, 10.5.0-10.5.2, and main ea57360912ed (unreleased 11.0.0) [exec: the finder repro fails 1/1 on main and on 10.5.2, each with -ea and -da; its release-portable variant fails on 9.11.0 (-ea and -da), 9.11.1, 9.12.3 and 10.0.0; the independent reproduction's own test fails its 2 bug cases (3 controls pass) on main (-ea, -da), 10.5.2, and in portable form on 10.0.0, 9.12.3 and 9.11.1]; the other 13 releases (9.12.0-9.12.2, 10.1.0, 10.2.0-10.2.2, 10.3.0-10.3.2, 10.4.0, 10.5.0, 10.5.1) [read: the addField check and the aborting catch are both present at each release tag, and getMaxDimensions is checked before fieldInfos.add in all of them]; branch_10x (1309534296e) and branch_10_6 (2763db11b0a) have the same code [read, not run]; on main only, VectorEncoding.FLOAT16 (#16383) is a second trigger [exec: the intended-behaviour check's float16 probe]; 9.10.0 and older are not affected because the format does not exist (compile error on 9.10.0 [exec]); not fixed upstream as of main ea57360912ed [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, read-only: two scripted prior-report searches, 51 queries (16 GitHub, 3 commit, 2 downstream, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA-archive, 6 web) and 29 queries (lists, JIRA, commits, downstream); 39 direct GitHub issue/PR searches on apache/lucene; direct searches on Elasticsearch, OpenSearch, OpenSearch k-NN and Solr; 9 direct lists.apache.org queries each on dev@, java-user@ and issues@; 5 JQL searches; 14 web searches; the changed files of 225 of the 413 open apache/lucene PRs (16 touch an affected file, the hunks of the 6 closest read); upstream commits by path; git history and CHANGES.txt; plus the finder's and the independent reproduction's and the intended-behaviour check's searches); related prior items, none of them this bug: #13288 and #13316 (introduced the format and its addField check; the review calls it validation and never discusses the writer closing), #12436 (2023 review thread in which maintainers kept the dimension-limit check ahead of FieldInfo registration because a check in addField would come after registration; design context that predates the bug), #992 (LUCENE-10592, added the aborting catch), #16211 and #14025 (open feature requests that mention the format), #7049 (LUCENE-5987), #6673 (LUCENE-5611), #6724 (LUCENE-5662), #7111 (LUCENE-6049) and #9252 (LUCENE-8205) (aborting/non-aborting design and precedents), #15540, #15125, #16708 and #16383 (different defects or features); downstream: Elasticsearch's own ES815HnswBitVectorsFormat does not use Lucene's class, and no use of HnswBitVectorsFormat was found in Solr, OpenSearch or OpenSearch k-NN (default-branch code search, not exhaustive)
- Lucene commit tested
- main
645d4fe14a20(11.0.0-SNAPSHOT), 2026-10-30: the minimal test with gradle in a fresh scratch worktree (fails with assertions on and off; with fix A it passes, together with the whole codecs module, 694 tests, core vector and writer suites, 807 tests, and the format, lint and javadoc checks; after reverting the fix it fails again). Release jars: 10.6.0 and 10.5.2 fail with assertions on and off; 9.11.0 (on and off), 9.11.1, 9.12.3 and 10.0.0 fail with a release-portable variant; 9.10.0 has no such format. An independent probe without the test framework shows the close and the rollback on main, 10.6.0, 10.5.2 and 9.11.0. JDK 25.0.3, Linux aarch64. The verifiers and cross-model reviews ran on mainea57360912ed; between it and645d4fe14a20no commit touches the encoding check or theaddFieldcatch.
- Finding record
lucene/codecs/src/java/org/apache/lucene/codecs/bitvectors/HnswBitVectorsFormat.java:50-58 (class javadoc, @lucene.experimental at :56) and :193-197 (FlatBitVectorsWriter#addField throws IllegalArgumentException 'HnswBitVectorsFormat only supports BYTE encoding' for any non-BYTE encoding)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1317 (initializeFieldInfo), :1331-1336 (validateMaxVectorDimension with getMaxDimensions, before registration, non-aborting), :1337-1338 (fieldInfos.add), :1390-1397 (vectorValuesConsumer.addField inside catch (Throwable) -> onAbortingException)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:594-603 (maybeAbort: abort() and onTragicEvent)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:162-165 (class javadoc: IndexWriter closes itself on an Error or a checkpoint disaster) and :1465-1466 (addDocument: after an Exception the index is consistent, 'but this document may not have been added')lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:6108-6112 (getTragicException javadoc: closed as a side-effect of a tragic exception, 'e.g. disk full while flushing a new segment')lucene/CHANGES.txt:11544-11546 (LUCENE-5987: IndexWriter forcefully closes itself on an aborting exception, 'an exception that would otherwise cause silent data loss')lucene/core/src/test/org/apache/lucene/index/TestIndexWriterExceptions.java:1592-1613 (testNullStoredField: after an input IllegalArgumentException, assertNull(iw.getTragicException()) and the earlier good document is kept; similar assertions at :1636-:1811) and lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseKnnVectorsFormatTestCase.java:779 (testIllegalDimensionTooLarge)lucene/codecs/src/test/org/apache/lucene/codecs/bitvectors/TestHnswBitVectorsFormat.java:54-63 (testFloatVectorFails expects IllegalArgumentException from addDocument; the message check at :61 is not asserted; writer state is not checked)lucene/codecs/src/resources/META-INF/services/org.apache.lucene.codecs.KnnVectorsFormat:16 (the format is registered for SPI lookup)SECURITY.md:28, 42, 46, 50 (threat model, cited by the security record)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:176-180, (at 645d4fe14a20) :641, :685-699, :1372, :1386-1391, :1392-1414, :1445-1451, :1625lucene/core/src/java/org/apache/lucene/index/VectorValuesConsumer.java:52-66, (at 645d4fe14a20) :68-71; lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldKnnVectorsFormat.java:118-121, :147-185lucene/codecs/src/java/org/apache/lucene/codecs/bitvectors/HnswBitVectorsFormat.java:56, (at 645d4fe14a20) :139-148, :159-162, :192-198lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:56-60, (at 645d4fe14a20) :291, :310, :594-605; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1492, :1625-1641, :2566-2571, :6068-6084, :6098-6106
- Why it looks unintended
lucene/codecs/src/test/org/apache/lucene/codecs/bitvectors/TestHnswBitVectorsFormat.java:54-63 (at 645d4fe14a20)lucene/core/src/test/org/apache/lucene/index/TestIndexWriterExceptions.java:1592-1614; (at 645d4fe14a20) lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseKnnVectorsFormatTestCase.java:779-795; lucene/core/src/test/org/apache/lucene/codecs/perfield/TestPerFieldKnnVectorsFormat.java:217-244lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:162-165, (at 645d4fe14a20) :1465-1466, :6108-6112; lucene/CHANGES.txt:2795-2796, :11577-11579, :12384-12385
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsFormat.java:105-114; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldKnnVectorsFormat.java:93-96; lucene/test-framework/src/java/org/apache/lucene/tests/codecs/asserting/AssertingKnnVectorsFormat.java:51, :67-70
- TestBitVectorsRejectedFloatField.java (lucene/codecs, package org.apache.lucene.codecs.bitvectors, 1 test):
repro/LFV-121/src/org/apache/lucene/codecs/bitvectors/TestBitVectorsRejectedFloatField.java(42 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and the executed probe numbers (1 committed document instead of 3; an NRT-visible document lost).
assets/LFV-121/bug.png(462 KB)