An untokenized value is one token: Field indexes it through a one-token stream, so it can carry a position. The column adapter instead sends every untokenized value down Lucene's single-term BINARY path, which has no positions and throws when the type asks for them.
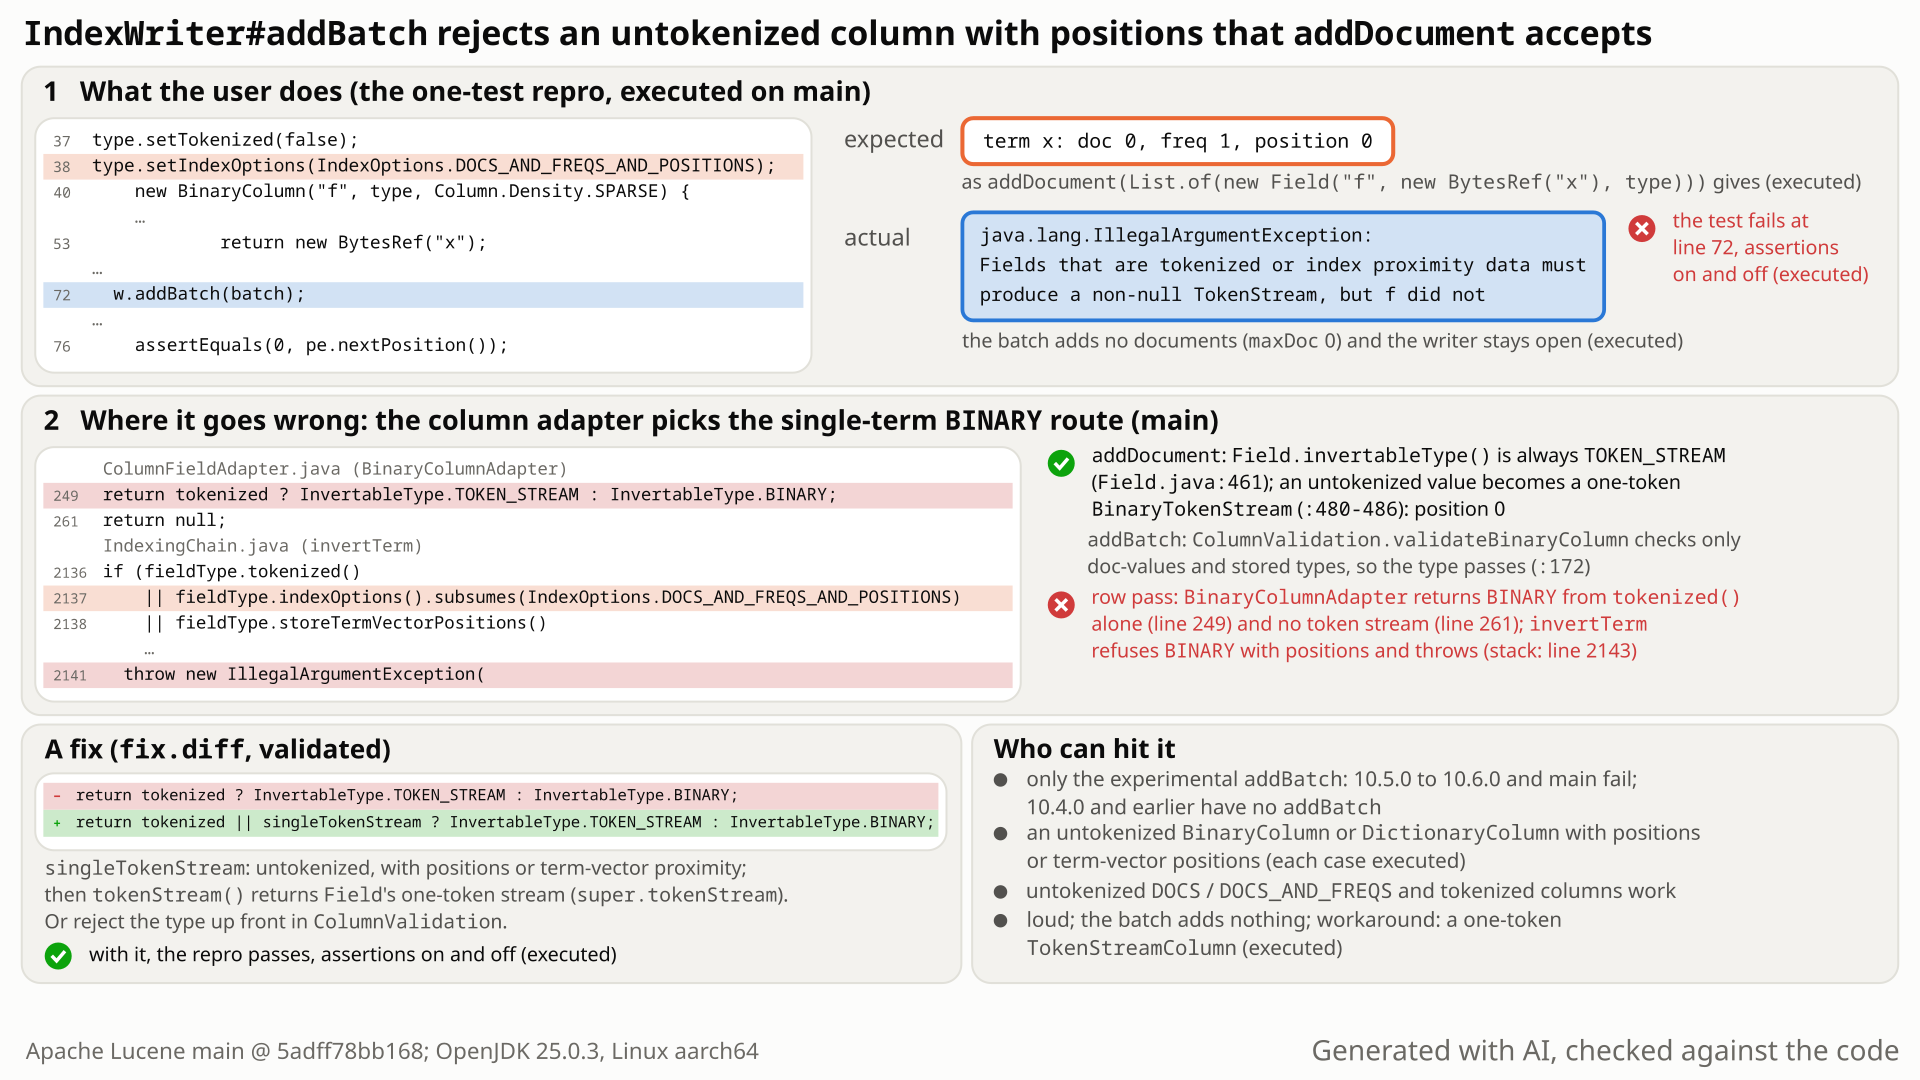
addDocument wraps the untokenized value in a one-token stream and indexes x at position 0; addBatch's column adapter takes the single-term path, whose check rejects positions. Select the still to open it at full size. Generated with AI, checked against the code.- You define an untokenized
FieldTypethat indexes positions (DOCS_AND_FREQS_AND_POSITIONS).addDocument(new Field("f", new BytesRef("x"), type))indexes termxin doc 0, freq 1, position 0. - You index the same value with
addBatch: a one-document batch with aBinaryColumn"f" of that type and valuex. Validation accepts the column. - You expect the same index: term
x, doc 0, position 0. - Instead
addBatchthrowsIllegalArgumentException: Fields that are tokenized or index proximity data must produce a non-null TokenStream, but f did not. Because the type is untokenized, the column adapter took the single-term path, which cannot store positions. - Same for a
DictionaryColumnand for term vectors with positions. The batch adds no documents and the writer stays open.
Only users of the experimental addBatch column API (10.5.0 and later) whose untokenized, keyword-style field indexes positions or term-vector positions. That schema cannot be indexed by column at all. The failure is loud, on the first batch: the writer stays open and the batch adds no visible documents.
Mechanism, terms and numbers417 words
IndexWriter#addBatch (experimental, first in 10.5.0) rejects an untokenized BinaryColumn or DictionaryColumn whose field type indexes positions or term-vector positions. The internal BinaryColumnAdapter picks the single-term InvertableType.BINARY path from tokenized() alone (ColumnFieldAdapter.java:249 on main) and supplies no TokenStream; IndexingChain.invertTerm refuses proximity data on that path (IndexingChain.java:2136-2145). addDocument with new Field(name, BytesRef, sameType) indexes the value as one token at position 0, because Field always wraps an untokenized value in a single-token stream. ColumnValidation accepts the type first, and TokenStreamColumn refuses untokenized types, so no column kind can index it.
- Untokenized field: the whole value is one term, as in
StringField. AFieldTypemay still ask for positions (DOCS_AND_FREQS_AND_POSITIONS) or term vectors with positions;Field(String, BytesRef, IndexableFieldType)accepts that and rejects only offsets and tokenized types (Field.java:209-215on main). - Invertable type: how the indexing chain turns a field into terms.
TOKEN_STREAMreads aTokenStream;BINARYtakesbinaryValue()as a single term with no positions (InvertableType.java:25-32).Fieldis alwaysTOKEN_STREAMand wraps an untokenizedBytesRefin a one-tokenBinaryTokenStream(Field.java:459-487). - Column batch API:
IndexWriter#addBatch(ColumnBatch)(@lucene.experimental, 10.5.0) indexes columns instead of documents.package-info.java:35-43lists term inversion among the uses of bothBinaryColumnandDictionaryColumn, and theDictionaryColumnjavadoc says "term inversion (tokenized or untokenized)" (DictionaryColumn.java:27-32). Internally each becomes aBinaryColumnAdapter(ColumnFieldAdapter.java:51-62), aFieldsubclass.
// ColumnFieldAdapter.java:244-262 (BinaryColumnAdapter)
return tokenized ? InvertableType.TOKEN_STREAM : InvertableType.BINARY;   // :249 looks at tokenized() only
...
return null;                                                              // :261 tokenStream(): none when untokenized

// IndexingChain.java:2136-2145 (invertTerm, the BINARY path)
if (fieldType.tokenized()
    || fieldType.indexOptions().subsumes(IndexOptions.DOCS_AND_FREQS_AND_POSITIONS)
    || fieldType.storeTermVectorPositions() || fieldType.storeTermVectorOffsets()
    || fieldType.storeTermVectorPayloads()) {
  throw new IllegalArgumentException("Fields that are tokenized or index proximity data must produce a non-null TokenStream, but " + ...);
}IndexingChain.processBatchvalidates each column (:730-737).validateBinaryColumnandvalidateDictionaryColumn(ColumnValidation.java:172-249) never look at positions or term-vector options, so the type passes.- The field's options are registered (
initAndValidateFields,:784), then the row pass (:793) creates the adapter. For an untokenized type it answersBINARY(:249). invertTermsees a type that indexes positions and throws (stack traceIndexingChain.java:2143). The message asks for aTokenStream; butTokenStreamColumn, the only column that supplies one, requirestokenized() == true(TokenStreamColumn.java:44-56).
The same happens for a DictionaryColumn (same adapter) and for a DOCS type with term-vector positions. Untokenized DOCS / DOCS_AND_FREQS columns, the common StringField-like case, and tokenized columns work.
Exposure and likelihood146 words
- Who is hit. Applications that index through
IndexWriter#addBatchwith aBinaryColumnorDictionaryColumnwhose untokenized type hasDOCS_AND_FREQS_AND_POSITIONSor term vectors with positions, for example a schema they already index withaddDocument. - Default vs opt-in. Opt-in: the column API is experimental, and most untokenized fields (
StringField,KeywordField) indexDOCSorDOCS_AND_FREQS, which work. - Effect. One
IllegalArgumentExceptionfrom the row pass, after validation accepted the column. The message points at aTokenStreamthe user cannot supply. The writer stays open and the failed batch adds no visible documents (a reader opened afterwards in the probe showsmaxDoc=0). As after any non-aborting failure (a failedaddDocumenttoo), the batch's reserved doc IDs stay buffered as deleted docs and no flush is triggered (DocumentsWriterPerThread.java:339-354,:392-415). - Scale. None: one document, one value, single thread, with assertions on and off.
- Likelihood: rare.
One JUnit test, single thread, deterministic, public API only: a one-document ColumnBatch with a SPARSE BinaryColumn "f" (untokenized, DOCS_AND_FREQS_AND_POSITIONS, value x), then a check that x is at position 0. It fails with assertions on and off on main and passes with fix A.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.document.column;

import java.util.List;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexOptions;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.PostingsEnum;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestBinaryColumnUntokenizedPositions extends LuceneTestCase {

  public void testUntokenizedColumnWithPositions() throws Exception {
    // Expected: indexed like addDocument(new Field("f", new BytesRef("x"), type)); actual: IAE
    FieldType type = new FieldType();
    type.setTokenized(false);
    type.setIndexOptions(IndexOptions.DOCS_AND_FREQS_AND_POSITIONS);
    BinaryColumn column =
        new BinaryColumn("f", type, Column.Density.SPARSE) {
          @Override
          public ObjectTupleCursor<BytesRef> tuples() {
            return new ObjectTupleCursor<>() {
              int doc = -1;

              @Override
              public int nextDoc() {
                return doc = doc == -1 ? 0 : DocIdSetIterator.NO_MORE_DOCS;
              }

              @Override
              public BytesRef value() {
                return new BytesRef("x");
              }
            };
          }
        };
    ColumnBatch batch =
        new ColumnBatch() {
          @Override
          public int numDocs() {
            return 1;
          }

          @Override
          public Iterable<Column> columns() {
            return List.of(column);
          }
        };
    try (Directory dir = newDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      w.addBatch(batch);
      try (DirectoryReader r = DirectoryReader.open(w)) {
        PostingsEnum pe = getOnlyLeafReader(r).postings(new Term("f", "x"), PostingsEnum.POSITIONS);
        assertEquals(0, pe.nextDoc());
        assertEquals(0, pe.nextPosition());
      }
    }
  }
}
cd $LUCENE
cp $REPRO/TestBinaryColumnUntokenizedPositions.java lucene/core/src/test/org/apache/lucene/document/column/
./gradlew :lucene:core:test --tests org.apache.lucene.document.column.TestBinaryColumnUntokenizedPositions -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false
- Expected
addBatchindexes termxin doc 0 at position 0, asaddDocumentdoes with the same type.- Observed
addBatchthrowsIllegalArgumentException: Fields that are tokenized or index proximity data must produce a non-null TokenStream, but f did not(IndexingChain.java:2143).
More files, environment, full output133 words
The test lives in org.apache.lucene.document.column, like the upstream column tests, and makes no random() call of its own; the result does not depend on the seed. It is the minimal test with its one comment line shortened to pass the 100-column format check. It belongs in lucene/core/src/test/org/apache/lucene/document/column/ and passes :lucene:core:check -x test (format, lint, forbidden APIs).
Regression test: this same test (with fix B, the same test with addBatch wrapped in expectThrows).
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
TestBinaryColumnUntokenizedPositions > testUntokenizedColumnWithPositions FAILED
    java.lang.IllegalArgumentException: Fields that are tokenized or index proximity data must produce a non-null TokenStream, but f did not
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:A2908C7053426C4]:0)
        at org.apache.lucene.index.IndexingChain$PerField.invertTerm(IndexingChain.java:2143)
        at org.apache.lucene.index.IndexingChain$PerField.invert(IndexingChain.java:1960)
        at org.apache.lucene.index.IndexingChain.invertAndStore(IndexingChain.java:1483)
        at org.apache.lucene.index.IndexingChain.processRowColumns(IndexingChain.java:916)
        at org.apache.lucene.index.IndexingChain.processBatch(IndexingChain.java:793)
        at org.apache.lucene.index.DocumentsWriterPerThread.updateBatch(DocumentsWriterPerThread.java:343)
        at org.apache.lucene.index.DocumentsWriter.updateBatch(DocumentsWriter.java:469)
        at org.apache.lucene.index.IndexWriter.updateBatch(IndexWriter.java:1580)
        at org.apache.lucene.index.IndexWriter.addBatch(IndexWriter.java:1538)
at org.apache.lucene.document.column.TestBinaryColumnUntokenizedPositions.testUntokenizedColumnWithPositions(TestBinaryColumnUntokenizedPositions.java:72)- The column package docs list term inversion for
BinaryColumnandDictionaryColumn(theDictionaryColumnjavadoc adds "tokenized or untokenized"), and nothing discloses a limit on their index options. - No column kind accepts this legal type:
TokenStreamColumnrequirestokenized() == true, so the requestedTokenStreamcannot be supplied. ColumnValidationrejects other unsupported combinations up front, but not this one.
The full argument170 words
- The contract.
DictionaryColumn.java:27-32: "... for stored binary or string fields, and for term inversion (tokenized or untokenized)."package-info.java:35-43lists "term inversion" forBinaryColumnandDictionaryColumn;BinaryColumn.java:23-29: "stored/indexed binary or text fields". No javadoc, test, CHANGES or MIGRATE entry restricts the index options of untokenized columns. - No column keeps the type untokenized.
TokenStreamColumnrejects untokenized types (TokenStreamColumn.java:44-56;TestColumnBatchTokenStreamColumn.testConstructorRejectsNonTokenized); the workaround works only by changing the type to tokenized. - Validation is the place for rejections.
ColumnValidationalready rejects, for example, aDictionaryColumnwithBINARYdoc values with a specific message (ColumnValidation.java:216-222). - Parity is a stated goal. #16224 (Tim-Brooks): without
TokenStreamColumn"anyone using user provided token streams would need to fall back to the addDocument path"; #16708 (mayya-sharipova) fixed that "addBatch accepted vectors that addDocument would reject". - History. The adapter line is unchanged since #15990 created the column API; its description, 7 comments, 11 reviews and 20 inline review comments never discuss positions on untokenized columns. #16101 lists "inverted tokenized/untokenized fields" among its tested uses.
The devil's-advocate check136 words
The strongest case: InvertableType.BINARY deliberately carries no proximity data, and TestDocumentWriter.testIndexBinaryValueWithoutTokenStream (TestDocumentWriter.java:435, from #12139) asserts that a BINARY field with positions or term-vector positions is illegal ("cannot index positions on a binary field"). Untokenized columns could be meant as plain keywords, with positions left to TokenStreamColumn, and the API is experimental.
Why it fails: that test covers a field that declares BINARY itself; here the user never chooses BINARY, the internal adapter does, from tokenized() alone. Nothing documents a keyword-only reading, and TokenStreamColumn refuses untokenized types, so the workaround (a one-token TokenStreamColumn) means changing the type to tokenized. Even if maintainers decide the type is unsupported, the error belongs in ColumnValidation with a message that says so (fix B). The cross-model reviewer (OpenAI GPT-5.6) rated this defence moderate and not convincing.
Recommended Invert untokenized proximity types through Field's single-token stream
Make BinaryColumnAdapter invert an untokenized type that indexes positions or term-vector proximity through Field's single-token stream, as addDocument does. Validated: the repro passes with assertions on and off, and 182 column-batch and TestDocumentWriter tests pass. Alternative: reject the type up front in ColumnValidation with a clear message.
All options and trade-offs2 options · 569 words
Validated with gradle in a clean scratch worktree of 5adff78bb168 (OpenJDK 25.0.3, seed DEADBEEF, 2026-11-03). The suites: the six TestColumnBatch* classes in org.apache.lucene.document.column, TestColumnBatchIndexing and TestDocumentWriter (182 tests).
Workaround until fixed: a TokenStreamColumn with the same index options but tokenized=true, whose stream emits exactly the value's bytes as one token, gives the same index options, norms setting and postings (doc 0, freq 1, position 0; executed). A TokenStreamColumn is inverted-only (TokenStreamColumn.java:29-33): a stored value, doc values or points go in a separate column with the same name. For a multi-valued document it matches the Field(BytesRef) row path only while the analyzer's position increment gap is 0, the default (read from code, not executed).
Invert untokenized proximity types through Field's single-token stream (validated by the checks) (recommended)
In BinaryColumnAdapter, compute once whether the type is untokenized but indexes positions or term-vector positions, offsets or payloads (the condition invertTerm checks). Then invertableType() returns TOKEN_STREAM and tokenStream() delegates to Field.tokenStream, which wraps binaryValue() in its one-token stream. DOCS / DOCS_AND_FREQS columns keep the BINARY path.
     this.indexed = fieldType.indexOptions() != IndexOptions.NONE;
+    this.singleTokenStream =
+        tokenized == false
+            && (fieldType.indexOptions().subsumes(IndexOptions.DOCS_AND_FREQS_AND_POSITIONS)
+                || fieldType.storeTermVectorPositions()
+                || fieldType.storeTermVectorOffsets()
+                || fieldType.storeTermVectorPayloads());
...
-    return tokenized ? InvertableType.TOKEN_STREAM : InvertableType.BINARY;
+    return tokenized || singleTokenStream ? InvertableType.TOKEN_STREAM : InvertableType.BINARY;
...
+    if (singleTokenStream) {
+      // Field wraps an untokenized binaryValue() in a single-token stream
+      return super.tokenStream(analyzer, reuse);
+    }
Trade-offs
About 15 lines in one internal class; addBatch then indexes what addDocument indexes. It also sends offsets types down the single-token stream, while Field(String, BytesRef, ...) rejects offsets; maintainers may prefer to leave offsets out here and reject them in ColumnValidation with Field's message. Not tested with offsets, nor for a DictionaryColumn, term-vector positions or a DENSE column. Using subsumes, not compareTo, keeps DOCS_AND_CUSTOM_FREQS (which sorts after the positional options) on the BINARY path (IndexOptions.java:36-73).
What the checks validated
Stock 5adff78bb168: the repro fails through gradle with assertions on and off; with fix A it passes, on and off. With fix A, the six TestColumnBatch* classes, TestColumnBatchIndexing and TestDocumentWriter: 182 tests, 0 failures. :lucene:core:check -x test (format, lint, forbidden APIs) with fix A and the test: passes. Earlier, the first version of this change (compareTo instead of subsumes) passed the repro (on, off), 71 column tests, and the repro over the 10.5.0 jars.
In validateBinaryColumn and validateDictionaryColumn, throw when the type is untokenized and indexes positions or term-vector positions, offsets or payloads, with a message that names the column and the alternative, e.g. BinaryColumn "f" is untokenized and cannot index positions, offsets or payloads (indexOptions=DOCS_AND_FREQS_AND_POSITIONS); use a tokenized TokenStreamColumn or addDocument.
Trade-offs
Small, and the error comes from validation, before the field's options are registered, with a message that says what to do. But addBatch still cannot index a type addDocument accepts, so the column javadocs would need to say so. It also rejects such a column when it holds no values, which addBatch accepts today.
What the checks validated
With fix B the repro (assertions on), which asserts indexing, fails as intended for this option: addBatch now throws the new message from ColumnValidation.validateBinaryColumn, called by IndexingChain.processBatch:733 before the row pass. The same 8 suites: 182 tests, 0 failures; :lucene:core:check -x test passes.
Relevant downstream only to products that expose addBatch with user-defined field types; the trigger is the field type (configuration), once its column holds a value; no particular document value or query causes it.
A proof-obligation audit of the column batch API's term-inversion contract compared BinaryColumnAdapter with Field for every field type the column docs allow, and found that untokenized types with positions are routed to a path that refuses them. A public-API JUnit test then witnessed it on main.
The method in full96 words
Method: semi-formal (a proof-obligation audit of a class's contract, witnessed by an executable repro).
- The obligation: for every field type a
BinaryColumnorDictionaryColumnaccepts for term inversion,addBatchinverts the value asFieldwith the same type would.BinaryColumnAdapter.invertableTypedecides fromtokenized()alone, whileinvertTermalso depends on positions and term-vector options, so the obligation fails for untokenized proximity types. - A one-test JUnit witnessed it on main with assertions on and off. An independent reproducer, an executed review by another model family (OpenAI GPT-5.6) and a devil's-advocate verifier each wrote and ran their own test.
No prior report: two scripted prior-art runs (65 queries each, one on the exact error message), 31 manual GitHub searches (the message has 0 hits in GitHub issue and PR search), the mailing lists, JIRA, downstream projects and the web, plus the changed files of all 410 open PRs (2026-11-03), rechecked the same day.
Searches3 searches
No report found in the documented searches says that addBatch rejects an untokenized BinaryColumn or DictionaryColumn with positions, and nothing upstream fixes it. Related, not this bug: #16101 (added DictionaryColumn; its description lists inverted untokenized fields as supported), #16116 (open draft; keeps proximity types on the row pass and uses setTokenized(true) in its positions test), #15990 / #16066 (introduced the adapter), #12139 (created InvertableType.BINARY and the check, for plain keywords), #16224 (TokenStreamColumn requires tokenized types). Limits: keyword search only; GitHub search does not index PR diffs or every review comment.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits; Elasticsearch, OpenSearch, Solr; dev@, java-user@, issues@, commits@; JIRA archive; web | 2026-11-03 | two scripted prior-report search runs (65 queries each), an earlier run (51 queries) re-read, 31 manual GitHub searches, 8 web queries, the dev@ column API thread | only the related items above |
| Open PRs | 2026-11-03 | the changed files of all 410 open apache/lucene PRs | none touches the column package sources; the five touching IndexingChain.java do not change this path |
| Recheck (GitHub) | 2026-11-03 | message, class and method queries; items updated or created since 2026-11-01; upstream file history | nothing new; upstream main 1c2072f0284 still has the line |
Introduced by #15990, which created the column API (3d895681557 on main, 2026-05-14; 3ec3bff01b1 on branch_10x), first released in 10.5.0. Executed: 10.5.0, 10.5.1, 10.5.2, 10.6.0 and main fail; 10.4.0 and 9.12.3 have no column API. Not fixed upstream.
Versions tested5 rows
Introduced by #15990 "Add experimental columnar indexing api" (Tim-Brooks): 3d895681557 on main (author date 2026-05-14) and, the same day, 3ec3bff01b1 on branch_10x (#16066), with an identical ColumnFieldAdapter.java. It wrote invertableType() as tokenized ? TOKEN_STREAM : BINARY; the line is unchanged since. The DictionaryColumn route through the same adapter came with #16101 (e79c6780627, 2026-05-26, also in 10.5.0). The invertTerm check is older and correct on its own (#12139, cce33b07e4f, 2023, first in 9.6.0). The introducing commit's own adapter over the 10.5.0 jars fails the repro; the earlier compareTo version of fix A over the 10.5.0 jars passes. Upstream main 1c2072f0284 and the heads of branch_11x and branch_10_6 still have the line (read, 2026-11-03).
| Version or commit | Verdict | Result |
|---|---|---|
| 9.12.3, 10.4.0 | no API | no column API (the test does not compile) |
| 10.5.0 | first: 10.5.0 | the one-test repro fails with the same IllegalArgumentException |
| 10.5.1, 10.5.2 | affected | fails the same way |
| 10.6.0 | affected | fails the same way |
| main 5adff78bb168 | affected | the one-test repro fails through gradle, assertions on and off; passes with fix A |
An independent reproducer, an executed review by another model family (OpenAI GPT-5.6), a devil's-advocate verifier and an adjudication all rated it real; the adjudication confirmed it (medium confidence, priority Low). This doc's gradle runs reproduced it on main and validated both fixes.
Checks and verdicts264 words
The cross-model review ran on main ea57360912ed, where ColumnFieldAdapter.java, BinaryColumn.java and DictionaryColumn.java equal 5adff78bb168's and the IndexingChain.java and ColumnValidation.java changes in between touch only the vector path; every other check ran on 5adff78bb168 or a release.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | One-test JUnit fails on main (on, off), 10.6.0 and 10.5.0; the adapter fix passes it and 71 column tests; a probe shows the DictionaryColumn and term-vector-positions cases. |
| independent reproducer | real, Low | Own test (doc 0 through addDocument is indexed at position 0; doc 1, the same type and value as a BinaryColumn, is rejected) fails on main (on, off), 10.6.0 and 10.5.2; passes with its own adapter fix. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Own test fails across four seeds while its DOCS-only control passes; with the fix 2 of 2 and 71 of 71 column tests pass; the keyword-only defence rated moderate, not convincing. |
| devil's-advocate verifier | real, Low | The tested BINARY restriction covers fields that choose BINARY themselves; nothing restricts untokenized columns; the TokenStreamColumn workaround gives the same postings. |
| adjudication | confirmed (medium), Low | Re-ran the reproducer's test with a new seed, assertions off: fails. Rated it Low. |
| this doc (gradle) | reproduced; both fixes validated | Gradle in a clean scratch worktree of 5adff78bb168: the repro fails with assertions on and off; it passes with fix A (on, off); with fix B it fails early with the new validation message; with each fix 182 suite tests and :lucene:core:check -x test pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 531 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,404 words
- Registry title
- IndexWriter#addBatch rejects an untokenized BinaryColumn or DictionaryColumn whose FieldType indexes positions or term-vector positions, which addDocument with the same Field type accepts: the column adapter always takes the single-term InvertableType.BINARY path for untokenized values, so the row pass throws 'Fields that are tokenized or index proximity data must produce a non-null TokenStream' after ColumnValidation accepted the type (since 10.5.0)
- Area
- core / document column batch indexing: IndexWriter#addBatch, BinaryColumnAdapter invertable type (experimental column API)
- Priority
- Low, rank 675: The experimental column API IndexWriter#addBatch (10.5.0 to 10.6.0) loudly rejects an untokenized BinaryColumn or DictionaryColumn whose field type indexes positions or term-vector positions, a schema that addDocument accepts. It needs that uncommon keyword-with-positions schema, the batch adds nothing and the writer stays open.
- Impact class
- minor
- Impact note
- Applications that index through the experimental IndexWriter#addBatch column API with an untokenized BinaryColumn or DictionaryColumn whose FieldType indexes positions (DOCS_AND_FREQS_AND_POSITIONS) or term-vector positions get a late IllegalArgumentException that asks for a TokenStream no untokenized column can supply, so that schema cannot be indexed by column at all while addDocument accepts it; any index configuration, -ea and -da, every release from 10.5.0 to 10.6.0 and main; the failure is loud and does not abort the writer, the batch adds no documents, nothing is corrupted, and untokenized DOCS or DOCS_AND_FREQS columns and tokenized columns are unaffected.
- Summary
- You give an untokenized FieldType DOCS_AND_FREQS_AND_POSITIONS (or term vectors with positions) and index the value "x" through IndexWriter#addBatch with a BinaryColumn or DictionaryColumn, and expect what addDocument(new Field("f", new BytesRef("x"), type)) does with the same type: one token at position 0. Instead addBatch throws IllegalArgumentException 'Fields that are tokenized or index proximity data must produce a non-null TokenStream, but f did not' in its row pass, after ColumnValidation accepted the type. The internal BinaryColumnAdapter picks the single-term InvertableType.BINARY path from tokenized() alone and returns no TokenStream, and IndexingChain.invertTerm allows BINARY only without proximity data, whereas Field always wraps an untokenized value in a one-token stream.
- Introduced
- 3d89568155799e2e1efe132f67967d9725f4bd60 'Add experimental columnar indexing api (#15990)' by Tim Brooks on main; release-line copy 3ec3bff01b157ea18e87dd73649abe71089704d9 ('Add experimental columnar indexing api (#15990) (#16066)', branch_10x, same day, identical ColumnFieldAdapter.java blob bf2610aeda6) [read: git blame of ColumnFieldAdapter.java:244-250 on main and at every 10.5.x and 10.6.0 tag, git tag --contains; exec: the introducing commit's ColumnFieldAdapter.java shadowed over the 10.5.0 jars fails the repro (-da), the parents of both commits have no column API]. The commit created the column API and wrote BinaryColumnAdapter.invertableType() as 'tokenized ? TOKEN_STREAM : BINARY' with a null tokenStream() for untokenized values; that code is unchanged since. The DictionaryColumn route through the same adapter came with #16101 (main e79c6780627, branch_10x 8a9e55f254d). The invertTerm guard that throws is older and correct on its own (cce33b07e4f, #12139, Adrien Grand, 2023-02-21, in 9.6.0 and later) (2026-05-14 (author date 2026-05-14T04:12:44-06:00 on main; branch_10x copy 2026-05-14T10:19:30-06:00; DictionaryColumn route 2026-05-26); first release 10.5.0)
- First affected version
- 10.5.0 [exec] (the first release with the column API; 10.4.0 and every earlier release have no IndexWriter#addBatch, so the repro does not compile there [exec on 10.4.0 and 9.12.3])
- Affected versions
- 10.5.0, 10.5.1, 10.5.2, 10.6.0 (4ae946e5a9b) and main 5adff78bb168 (-ea and -da), executed with the finder's one-test repro [exec]; the independent reproduction's own test also fails on 10.6.0 and 10.5.2 [exec]; the same line is at the upstream heads of branch_11x and branch_10_6 [read, contents API, 2026-11-03]. Not affected: 10.4.0 and earlier, all 9.x (API absent; compile error on 10.4.0 and 9.12.3 [exec]). Not fixed upstream: upstream main 1c2072f0284 (author date 2026-11-02) still has 'return tokenized ? InvertableType.TOKEN_STREAM : InvertableType.BINARY;' at ColumnFieldAdapter.java:249 [read, contents API, 2026-11-03]. Not new in 10.6 (already in 10.5.0).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (searched 2026-11-03 and rechecked the same day: two scripted prior-report searches of 65 queries each (the column classes, methods and error-message phrases; the general InvertableType, BinaryTokenStream and untokenized-positions symptom) over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; the finder's earlier run (51 queries) re-read; 31 manual GitHub issue/PR searches, including the error message across all of GitHub (0 hits); the changed files of all 410 open apache/lucene PRs (none touches the column package sources; the five that touch IndexingChain.java, #16116, #16269, #15330, #13525 and #13342, do not change the BINARY check or the adapter); the 47 issues and PRs updated since 2026-11-01; the dev@ thread '[DISCUSS] Column-oriented indexing API for IndexWriter' (9 mails); 8 web queries). Nearest items, not this bug: #16101 (added DictionaryColumn; its description lists inverted tokenized/untokenized fields as supported), #16116 (open draft; leaves proximity types on the row pass and uses setTokenized(true) in its positions test without naming this case), #15990/#16066 (introduced the adapter; no comment or review is about positions), #12139 (created InvertableType.BINARY and the invertTerm check, for plain keywords), #16224 (TokenStreamColumn requires tokenized types). Re-checked 2026-11-03: 'non-null TokenStream' and 'index proximity data' 0 hits; BinaryColumnAdapter, DictionaryColumn and 'addBatch untokenized' match only #16101, #16224, #16225 and #16227; no addBatch issue or PR updated since 2026-11-01; items created since 2026-11-02 are #16962-#16967, none about the column API; newest upstream commits on the fix site by author date are ColumnFieldAdapter.java 70d043335bc (2026-06-15, #16224) and ColumnValidation.java a9779ef3c19 (2026-10-26, #16734, vector validation only). Not fixed upstream (main 1c2072f0284).
- Lucene commit tested
- main
5adff78bb168(the one-test repro through gradle in a clean scratch worktree, unfixed and with fix A, assertions on and off; with fix B, assertions on; with each fix the column-batch suites,TestDocumentWriterand:lucene:core:check -x test); the 10.5.0, 10.5.1, 10.5.2 and 10.6.0 jars (fail); 10.4.0 and 9.12.3 (no column API). The cross-model review ran on mainea57360912ed, whereColumnFieldAdapter.java,BinaryColumn.javaandDictionaryColumn.javaequal5adff78bb168's.
- Finding record
lucene/core/src/java/org/apache/lucene/document/column/ColumnFieldAdapter.java:244-250 (at 5adff78bb168) (BinaryColumnAdapter.invertableType: 'return tokenized ? InvertableType.TOKEN_STREAM : InvertableType.BINARY;' at :249), :253-263 (tokenStream returns null for an untokenized value without a token-stream cursor)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2136-2147 (at 5adff78bb168) (invertTerm: IllegalArgumentException 'Fields that are tokenized or index proximity data must produce a non-null TokenStream' when the type is tokenized or indexes positions or term-vector positions/offsets/payloads; thrown at :2143)lucene/core/src/java/org/apache/lucene/document/Field.java:199-222 (at 5adff78bb168) (Field(String, BytesRef, IndexableFieldType): rejects offsets and tokenized types, accepts an untokenized type with positions) and :459-490 (invertableType always TOKEN_STREAM; an untokenized binaryValue is wrapped in a single-token BinaryTokenStream)lucene/core/src/java/org/apache/lucene/document/column/ColumnValidation.java:172 (at 5adff78bb168) (validateBinaryColumn), :205 (validateDictionaryColumn): no check of positions or term-vector optionslucene/core/src/java/org/apache/lucene/document/column/DictionaryColumn.java:27-32 (at 5adff78bb168) ('... and for term inversion (tokenized or untokenized)'), BinaryColumn.java:23-28 ('stored/indexed binary or text fields'), package-info.java:35-43 (BinaryColumn and DictionaryColumn listed for term inversion), TokenStreamColumn.java:29-53 (requires tokenized() == true)a Lucene main checkout: git diff ea57360912ed 5adff78bb168 is empty for ColumnFieldAdapter.java, BinaryColumn.java and DictionaryColumn.java; the IndexingChain.java and ColumnValidation.java changes in between are on the vector path only (2026-11-03)https://github.com/apache/lucene/pull/15990, https://github.com/apache/lucene/pull/16101, https://github.com/apache/lucene/pull/16116, https://github.com/apache/lucene/pull/12139, https://github.com/apache/lucene/pull/16224
- The finding in 30 seconds
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/document/column/ColumnFieldAdapter.java:48-66 (create: BinaryColumn and DictionaryColumn both become BinaryColumnAdapter), :244-262 (invertableType :249, tokenStream null :261)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:717-793 (processBatch: validation :730-737, initAndValidateFields :784, row pass :793), :1958-1960 (BINARY -> invertTerm), :2127-2145 (invertTerm guard)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/document/Field.java:199-222 (BytesRef constructor), :459-490 (invertableType TOKEN_STREAM, single-token BinaryTokenStream)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/document/InvertableType.java:25-39Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/document/column/ColumnValidation.java:172-249; TokenStreamColumn.java:29-56; DictionaryColumn.java:27-32; BinaryColumn.java:23-29; package-info.java:35-49
- Who is affected
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1528-1538 (addBatch, @lucene.experimental)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:339-354 (updateBatch reserves doc IDs, deleteLastDocs on a non-aborting failure), :392-415 (deleteLastDocs; no flush)
- Why it looks unintended
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/document/column/DictionaryColumn.java:27-32; BinaryColumn.java:23-29; package-info.java:35-43Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/document/column/TokenStreamColumn.java:44-56; ColumnValidation.java:172-249Lucene main 5adff78bb168: lucene/core/src/test/org/apache/lucene/document/column/TestColumnBatchTokenStreamColumn.java:228 (testConstructorRejectsNonTokenized)Lucene main 5adff78bb168: lucene/core/src/test/org/apache/lucene/index/TestDocumentWriter.java:435-475 (testIndexBinaryValueWithoutTokenStream)
- Suggested fix
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/document/Field.java:209-212 (offsets rejected on binary fields)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/IndexOptions.java:30-73 (option order; subsumes treats DOCS_AND_CUSTOM_FREQS as DOCS_AND_FREQS); document/column/TokenStreamColumn.java:29-33 (inverted-only)
- Diagrams
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/document/column/ColumnFieldAdapter.java:244-262; index/IndexingChain.java:2136-2145; document/Field.java:459-490
- TestBinaryColumnUntokenizedPositions.java (one test, lucene/core):
repro/LFV-1229/TestBinaryColumnUntokenizedPositions.java(80 lines)
A picture of the two indexing paths for the same field type, made in parallel with this doc from the code at 5adff78bb168 and the executed repro; the PNG is the summary still.
assets/LFV-1229/bug.png(531 KB)