Lucene reads two scores from fixed positions of the merged hit list: the first hit as the maximum and the last as the lowest, the k-th best when k hits were collected. That is right only while the list is sorted by score, which the hook's javadoc does not require.
- A
KnnFloatVectorQuerysearches each segment's vector graph first.mergeLeafResultsthen merges the per-segment hits into the index-level top k. The default usesTopDocs.merge, which returns them sorted by descending score; subclasses may override it. - The merged hits become a fixed query (
DocAndScoreQuery) that returns each hit with its score and reports a maximum score,getMaxScore. That is an upper bound: top-score pruning, for example in aBooleanQuerydisjunction, skips a clause whose bound cannot make a document competitive. - Since 10.3.0 the search is optimistic: each segment first collects a share of k (38 of k = 50 for 10 equal segments), and a segment is searched again if its lowest hit reaches the merged list's lowest (k-th) score.
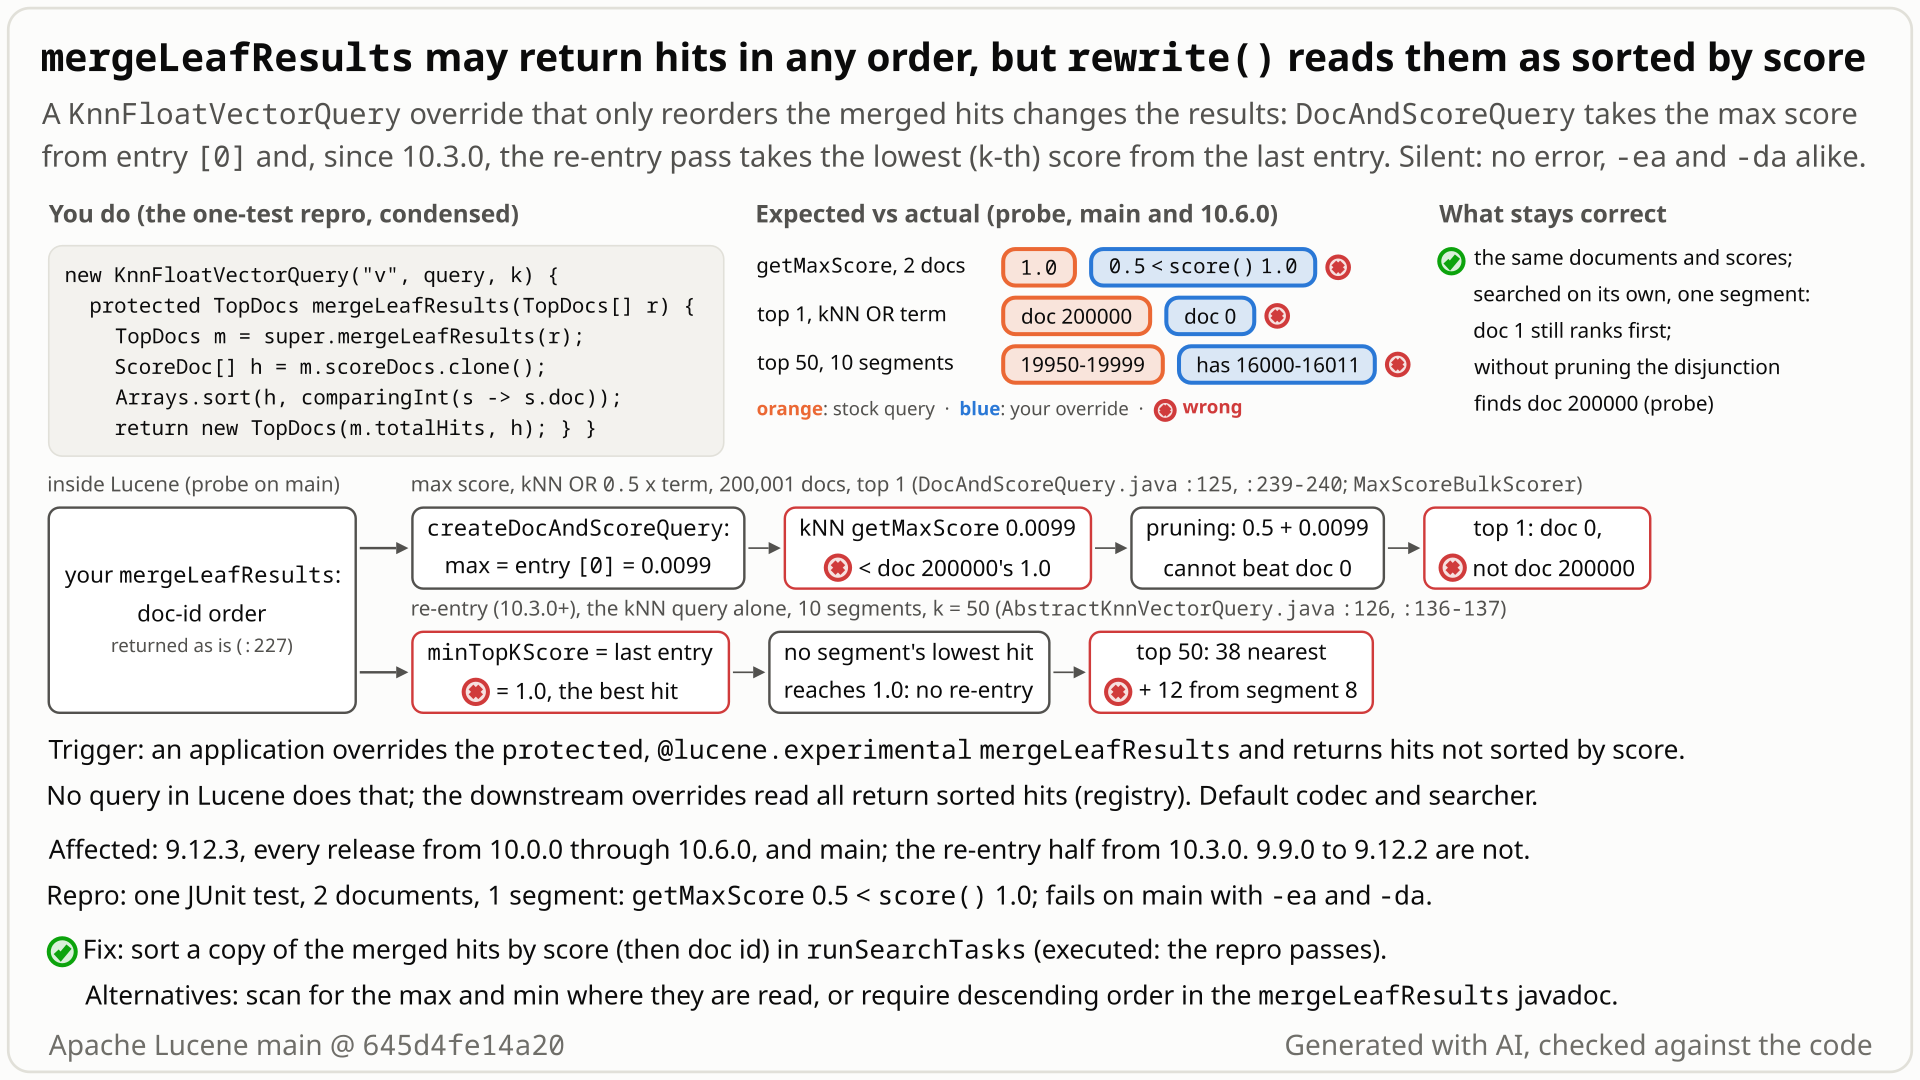
- You subclass
KnnFloatVectorQueryand overridemergeLeafResultsto return the default merged hits sorted by doc id: same documents, same scores. Its javadoc says the result has "no constraint on their ordering". - You index doc 0 at (0, 0) and doc 1 at (1, 0) and search (1, 0) with k = 2. The hits are doc 1 (score 1.0, the exact match) and doc 0 (score 0.5).
- You expect the rewritten query's scorer to report a maximum score (
getMaxScore) of at least 1.0, the best score it returns. - You get 0.5: Lucene takes the maximum from the first hit, now doc 0. Pruning trusts such bounds: over 200,001 documents the reordered kNN clause's bound is its first hit's score, doc 0's 0.0099, so the top-1 of
kNN OR 0.5 x termis doc 0 (0.51) instead of the exact match, doc 200000 (1.0). - From 10.3.0 Lucene also reads the last hit as the lowest (k-th best) score when it decides which segments to search again. On 10 segments with k = 50 it searches none again, and the 50 nearest include a far document, doc 16000. No error is raised.
Only applications that override the protected, experimental mergeLeafResults of KnnFloatVectorQuery or KnnByteVectorQuery and return hits not sorted by descending score, for example re-weighted without re-sorting. Stock queries are fine, and the five downstream overrides read all return sorted hits. Any index size; no error.
Mechanism, terms and numbers649 words
AbstractKnnVectorQuery#mergeLeafResults is a protected, @lucene.experimental hook on the public KnnFloatVectorQuery and KnnByteVectorQuery. Its javadoc says it returns "index-level kNN results (no constraint on their ordering)" and is "useful for reading and / or modifying the final results as needed". rewrite() passes its output unchanged to three readers that assume descending score order: DocAndScoreQuery.createDocAndScoreQuery takes the max score from the first hit, the optimistic re-entry pass (10.3.0 and later) and the no-match explainer take the lowest (k-th) score from the last. An override that returns exactly the default hits in another order therefore gets a rewritten query whose getMaxScore is below scores it returns (0.5 against 1.0 with 2 documents), so top-score pruning in a disjunction can skip the best kNN hit, and on a multi-segment index the second search pass is skipped and farther neighbours come back. Stock queries are not affected. Affected: 9.12.3 and 10.0.0 through 10.6.0, and main; sorting a copy of the hook's output in runSearchTasks fixes it.
- The hook promises freedom of order.
mergeLeafResultssays "@return index-level kNN results (no constraint on their ordering)" and "This method is useful for reading and / or modifying the final results as needed" (AbstractKnnVectorQuery.java:416-430). It is protected and@lucene.experimental, inherited by the public, non-finalKnnFloatVectorQuery(KnnFloatVectorQuery.java:48),KnnByteVectorQuery(KnnByteVectorQuery.java:47) and, on main,KnnFloat16VectorQuery. rewrite()uses its output as is.runSearchTasksreturnsmergeLeafResults(...)unchanged (:227), for the first pass (:118) and the re-entry pass (:150).- Max score from the first hit.
DocAndScoreQuery.createDocAndScoreQuerydoesfloat maxScore = topK.scoreDocs[0].score;(DocAndScoreQuery.java:125) before sorting by doc id (:126), and the scorer'sgetMaxScorereturns it (:238-241), whilescore()returns each hit's own score (:243-246).Scorer#getMaxScoremust bound the scores of the documents in range (Scorer.java:75-79). - Lowest (k-th) score from the last hit. The re-entry pass takes
minTopKScore = topK.scoreDocs[topK.scoreDocs.length - 1].score(AbstractKnnVectorQuery.java:126) and searches a segment again only if its lowest hit reaches it (:136-137). The no-match explainer repeats the read, with the comment "topK is score-descending" (:160-166). A probe on the 10-segment shape below executed both: the stock query re-enters 1 segment and the override 0, andexplainfor doc 0 cites a minimum top-K score of 1.0 with the override against 4.1631973E-4 for the stock query. - Pruning trusts the bound. Under
TOP_SCORESa disjunction is scored byMaxScoreBulkScorer, which treats a clause as non-essential once the minimum competitive score exceeds its bound; the kNN-only best hit is then never scored.
- Minimal repro: 2 documents, doc 0 at (0, 0) and doc 1 at (1, 0), query (1, 0), k = 2, an override that returns the default hits sorted by doc id:
getMaxScore0.5, thenscore()1.0 for doc 1. - Pruned disjunction: 200,001 documents, top-1 of
SHOULD(kNN, k = 5)+SHOULD(0.5-boosted constant-score term), where doc 200000 is the query vector and has no term. In doc-id order the kNN clause's bound is doc 0's score, 1/101 = 0.0099 (the term clause's is 0.5), and the result is doc 0 (0.51) instead of doc 200000 (1.0). With a BM25 term clause over 20,000 documents and the defaultIndexSearcher#search(Query, int): doc 0 (0.32496786) instead of doc 19999 (1.0). - Re-entry (10.3.0 and later): 10 segments of 2,000 documents, k = 50, the nearest neighbours at the end of the last segment. The stock query returns exactly docs 19950-19999. In doc-id order the last hit is the exact match (score 1.0), so no segment is searched again (the stock query re-enters 1), and the result contains doc 16000 from segment 8 (distance 4000). An independent shape (10 x 150 documents, k = 50): 12 of the 50 hits come from other segments.
Every test ran the stock KnnFloatVectorQuery as a control, and it was correct.
Exposure and likelihood326 words
- What goes wrong. Silent, lower-quality results, the same with assertions on and off. (1) The rewritten query breaks the
Scorer#getMaxScoreupper bound, so top-score pruning over it (a scored disjunction underTOP_SCORES, as the defaultIndexSearcher#search(Query, int)runs it) can skip the kNN clause's best hits. (2) From 10.3.0 a kNN query on its own, on a multi-segment index, can return farther neighbours because the second pass is skipped; whether it shows depends on where the neighbours sit. (3) On 10.6.0 and main, explanations of documents that were not collected cite a wrong minimum score (executed on main by a probe). - What the safety probe never saw. 10 runs, 9 random indexes with deletions, vectorless documents, kNN filters, FILTER and MUST_NOT clauses, and five overrides (four pure reorderings and one that re-weights the hits without re-sorting): no deleted, filtered, excluded or vectorless document was returned; for the pure reorderings no score was paired with the wrong document and no rewrite re-entered more segments than the stock query, which also follows from the code (the last entry of a reordering is never below the true minimum). An override that also lowers scores can re-enter more segments; that comes from the score change, not from the order.
- Who is exposed. Subclasses of
KnnFloatVectorQueryorKnnByteVectorQuery(also when wrapped inSeededKnnVectorQueryorPatienceKnnVectorQuery, which delegate the hook) whosemergeLeafResultsreturns hits not sorted by descending score: re-weighted or rescored without re-sorting (an override that multiplies each score by 1 + 3 x doc/N gave score 2.0 abovegetMaxScore1.0), in doc-id order, or concatenated per segment (as an early revision of #12679 did). - Configuration and scale. Default codec,
IndexWriterConfigandIndexSearcher. The bound break shows with 2 documents; the executed top-1 losses used 20,000 and 200,001 documents, enough for pruning to engage. - How likely. Rare. No in-tree query triggers it, and the five downstream overrides read (Elasticsearch, Solr, OpenSearch k-NN, mongot, nrtsearch) return sorted
TopDocs.mergeoutput.
One JUnit class, one method, public API only: 2 documents in one segment, a KnnFloatVectorQuery (k = 2) whose mergeLeafResults returns the default hits sorted by doc id, and an assertion that the rewritten scorer's getMaxScore is at least the score it returns. Deterministic; fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.util.Arrays;
import java.util.Comparator;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestKnnMergeLeafResultsOrder extends LuceneTestCase {

  public void testMaxScoreBoundsScoresWithDocIdOrderedMerge() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      for (int i = 0; i < 2; i++) {
        Document doc = new Document();
        doc.add(new KnnFloatVectorField("v", new float[] {i, 0}));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        Query knn =
            new KnnFloatVectorQuery("v", new float[] {1, 0}, 2) {
              @Override
              protected TopDocs mergeLeafResults(TopDocs[] perLeafResults) {
                TopDocs merged = super.mergeLeafResults(perLeafResults);
                ScoreDoc[] hits = merged.scoreDocs.clone();
                Arrays.sort(hits, Comparator.comparingInt(hit -> hit.doc));
                return new TopDocs(merged.totalHits, hits);
              }
            };
        IndexSearcher searcher = new IndexSearcher(reader);
        Weight weight = searcher.createWeight(searcher.rewrite(knn), ScoreMode.TOP_SCORES, 1f);
        Scorer scorer = weight.scorer(reader.leaves().get(0));
        scorer.advanceShallow(0);
        float maxScore = scorer.getMaxScore(DocIdSetIterator.NO_MORE_DOCS);
        assertEquals(1, scorer.iterator().advance(1));
        float score = scorer.score();
        // doc 1 is the exact match: expected getMaxScore >= its score 1.0, actual 0.5 (doc 0's)
        assertTrue("getMaxScore " + maxScore + " < score " + score, maxScore >= score);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestKnnMergeLeafResultsOrder -Ptests.seed=DEADBEEF
- Expected
getMaxScoreis at least 1.0, the score of doc 1, the exact match.- Observed
getMaxScore 0.5 < score 1.0: the max was taken from the first hit, which is now doc 0.
More files, environment, full output290 words
The class sits in org.apache.lucene.search, next to TestKnnFloatVectorQuery, and uses nothing package-private: a subclass of the public KnnFloatVectorQuery overriding the protected hook, and the public Weight and Scorer API. It pins the default codec and uses ByteBuffersDirectory, a plain IndexWriter and IndexSearcher; its data and oracle are deterministic, while the test harness still randomizes ambient settings (locale, time zone, similarity) that do not enter this result. It compiles on 9.9.0 and later; on 9.8.0 the hook does not exist.
It shows the max-score half only, on purpose. The executed end-to-end repros (a lost top-1 under pruning, farther neighbours on 10 segments) used 20,000 and 200,001 documents, or a 10-segment index; no smaller size was tried. The same fix covers them.
Regression test: this same test, as written. With the recommended fix it passes, together with the core format, ECJ and forbidden-apis checks.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; 10.6.0, 10.5.2, 10.3.0, 10.0.0, 9.12.3: fail (assertions on and off); 9.12.2, 9.9.0: pass; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; plain Java logic) |
cp $REPRO/TestKnnMergeLeafResultsOrder.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestKnnMergeLeafResultsOrder -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false (the recorded runs added --offline --no-daemon)
# gradle, scratch worktree of 645d4fe14a20, seed DEADBEEF, assertions on
TestKnnMergeLeafResultsOrder > testMaxScoreBoundsScoresWithDocIdOrderedMerge FAILED
    java.lang.AssertionError: getMaxScore 0.5 < score 1.0
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:6BAF8CA364470CFD]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.search.TestKnnMergeLeafResultsOrder.testMaxScoreBoundsScoresWithDocIdOrderedMerge(TestKnnMergeLeafResultsOrder.java:61)

# standalone runner, seed DEADBEEF: the same message, 1 of 1 failed each
main 645d4fe14a20 (-ea, -da), 10.6.0, 10.5.2, 10.3.0, 10.0.0, 9.12.3
# passed: 9.12.2, 9.9.0; 9.8.0: does not compile (no mergeLeafResults)
# a later fact check: the same five releases with -da fail the same way- The hook's javadoc says it returns "index-level kNN results (no constraint on their ordering)" and invites "modifying the final results".
- A pure reordering of the default hits (same documents, same scores) breaks
Scorer#getMaxScore, an upper bound on returned scores. - The order-dependent reads predate the hook (#12146) or came later (#14226, #16271); no review discussed ordering.
The full argument194 words
- The contract for overriders says the opposite (
AbstractKnnVectorQuery.java:416-427). No javadoc,MIGRATE.mdorCHANGES.txtentry asks overrides to sort. - The precondition that exists is for another caller. "The entries of topK are expected in descending score order" is on
createDocAndScoreQuery(DocAndScoreQuery.java:109-111, #16686). Lucene makes that call with the override's output; the overrider never calls it, and the order-dependent reads insiderewrite()are undocumented implementation details. - Bound breaks are treated as bugs. #14857 "AbstractKnnVectorQuery breaks shallowAdvance contract, causing chaos" (fixed by #14858) and #16697 "Fix block-max support of DoubleValuesSource" (merged 2026-10-09:
getMaxScorecovered too little of the range). - History. The first-entry read (#12146, 2023-02) was correct when written, because the merge could not be overridden. #12590 (2023-10) made it overridable and documented the order as free without touching that read. The last-entry reads came later (#14226, #16271). No review comment on #12590, #12679, #14226, #16271, #16324 or #16686 discusses the hook's ordering.
- The planned use was unordered. In the first revision of #12679 the hook's author overrode it to concatenate per-segment results: "Results of HNSW searches need not be sorted".
- No test covers it. No upstream test overrides
mergeLeafResultswith unsorted output.
The devil's-advocate check203 words
The strongest case for "intended" (a devil's-advocate verifier, cross-model reviews and the adjudication built it): the hook is @lucene.experimental and custom queries are "an expert level task, so tread carefully" (package-info.java:388-390); in #12590 a reviewer (benwtrent) warned that "It would be very easy to do the wrong thing by allowing sub-classes to override this method for yet another avenue of customization"; every later change (#14226, #16271, #16686) treats the merged result as score-descending, so the 2023 sentence may be a stale doc; the default delegates to TopDocs.merge, whose javadoc says it returns the top hits "sorting by score" and requires sorted input (TopDocs.java:197-198), so score order is the default's convention; and no known deployment is affected.
Why it fails: experimental status allows incompatible API changes, not code that contradicts the API's own javadoc; the default's score order is a convention, but the hook's contract does not ask overrides to keep it and says the opposite; the warning was general and ordering was never raised; the later code never revisited the hook. It does make a javadoc change that requires descending order an acceptable resolution (option C), not "not a bug": today the documented contract and the code disagree.
Recommended Sort a copy of the hook's output in runSearchTasks (recommended, validated)
Sort a copy of the hits mergeLeafResults returns by descending score (then doc id) in AbstractKnnVectorQuery.runSearchTasks, so all three readers see the order they assume (+10/-1, one file). Validated: the repro passes with assertions on and off, and so do 372 core and 39 join kNN tests and the lint checks.
TopDocs merged = mergeLeafResults(perLeafResults.values().toArray(TopDocs[]::new));
// mergeLeafResults may return its hits in any order, but the re-entry pass in rewrite(), the
// no-match explainer and DocAndScoreQuery (max score) read them as score-descending
ScoreDoc[] hits = merged.scoreDocs.clone();
Arrays.sort(
    hits,
    (a, b) ->
        a.score != b.score ? Float.compare(b.score, a.score) : Integer.compare(a.doc, b.doc));
return new TopDocs(merged.totalHits, hits);
All options and trade-offs3 options · 669 words
Two fixes were validated through gradle in a scratch worktree of 645d4fe14a20; the recommended one changes one place and covers every reader. A documentation-only change was not built.
Where rewrite() receives the hook's output, sort a copy by descending score, then ascending doc id. The override's hits and scores are kept; only their order changes, and createDocAndScoreQuery re-sorts by doc id anyway.
TopDocs merged = mergeLeafResults(perLeafResults.values().toArray(TopDocs[]::new));
// mergeLeafResults may return its hits in any order, but the re-entry pass in rewrite(), the
// no-match explainer and DocAndScoreQuery (max score) read them as score-descending
ScoreDoc[] hits = merged.scoreDocs.clone();
Arrays.sort(
    hits,
    (a, b) ->
        a.score != b.score ? Float.compare(b.score, a.score) : Integer.compare(a.doc, b.doc));
return new TopDocs(merged.totalHits, hits);
Trade-offs
- Coverage. Fixes the max-score, re-entry and explainer reads, and any later reader in
rewrite(), at the one place where the order became free. - Cost. One copy of the
ScoreDoc[]and an O(k log k) sort of the merged hits per pass (not benchmarked); the default output is already sorted, so an O(k) check could skip the copy. - Stock results unchanged.
TopDocs.mergeorders by descending score, then shard index (-1 for these hits), then doc id (TopDocs.java:44-45), the same order as the sort (read). - Aliasing. Today
createDocAndScoreQuerysorts the override's own array by doc id in place; with the fix it sorts the copy, so an override that keeps a reference to the array it returned no longer sees it reordered. - Scope. It does not harden the public
createDocAndScoreQueryfor other callers that pass unsorted hits (see the scan option). - Score-changing overrides. The min and max reads become consistent, but the re-entry pass then compares the override's lowest score with raw per-segment scores; the sort does not make such overrides fully consistent.
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, OpenJDK 25.0.3, seed DEADBEEF (2026-10-31). Stock: the repro fails. With the fix: the repro and every kNN, seeded, patience, rescore and vector-similarity query suite in core (18 classes, 372 tests, 5 skipped) and the four parent-join kNN suites (4 classes, 39 tests): 0 failures. - With assertions off: the repro,
TestKnnFloatVectorQueryandTestKnnByteVectorQuery(84 tests) pass;checkGoogleJavaFormat,ecjLintMain,ecjLintTest(with the repro test in place),forbiddenApisMainandforbiddenApisTestpass. - The finder's two end-to-end tests pass with the fix on the
645d4fe14a20jars; earlier the same change passed the independent reproducer's four tests, the cross-model reviewers' tests and 137 and 237 upstream kNN tests.
A private minScore(TopDocs) scan for the re-entry pass (AbstractKnnVectorQuery.java:126) and the explainer (:163), and a max scan in createDocAndScoreQuery (DocAndScoreQuery.java:125), whose javadoc then says the entries "may be in any order" (+19/-7, two files).
float maxScore = Float.NEGATIVE_INFINITY; // DocAndScoreQuery.createDocAndScoreQuery
for (ScoreDoc scoreDoc : topK.scoreDocs) {
  maxScore = Math.max(maxScore, scoreDoc.score);
}
Trade-offs
No reordering, and it also relaxes the public createDocAndScoreQuery precondition, so any caller may pass hits in any order (that also covers RescoreTopNQuery, a separate case found earlier that reaches the same line with heap-ordered hits). It touches three sites, and a future reader in rewrite() must remember to scan. Same score-changing caveat as the sort.
What the checks validated
Gradle on 645d4fe14a20: the same core and join test selection, 372 + 39 tests, 0 failures; checkGoogleJavaFormat and ecjLintMain pass; the finder's two end-to-end tests pass with it on the main jars.
Change the @return line of mergeLeafResults to require hits sorted by descending score, in line with #16686 and the explainer comment; optionally assert the order in runSearchTasks.
Trade-offs
No runtime change and consistent with the later code, but it changes the contract under existing overrides that followed the current javadoc, an assertion fires only with assertions on, and an override that misses the note still gets silently wrong results. Reasonable as a companion to a code fix, weaker alone.
Downstream products that subclass a kNN query to re-rank or re-weight the merged hits must, until this is fixed, return them sorted by descending score or silently lose top hits; the overrides read in Elasticsearch, OpenSearch k-NN, Solr, mongot and nrtsearch already do.
Code reading. While writing the merge step of a TLA+ model of the kNN rewrite, which treats the merged hits as a set and so could not show this, the finder compared rewrite() with the mergeLeafResults javadoc, saw the first- and last-hit reads, and confirmed the effect with a public-API JUnit on the stock jars.
The method in full137 words
Method: non-formal (code reading, then public-API JUnit tests).
- A hunt unit on the kNN query layer was modelling
AbstractKnnVectorQuery.rewritein TLA+ (KnnRewrite.tla). Its merge step is a set (the top k of the union), so the model cannot see an ordering defect. - While writing that step, the finder read the
mergeLeafResultsjavadoc ("no constraint on their ordering") against the code that consumes the result, found the first- and last-entry reads, and confirmed them with a probe and a JUnit with a doc-id-ordered override on the stock main jars (2 of 2 fail with assertions on and off). - A cross-model review, an independent reproducer, a second cross-model review, a devil's-advocate verifier and an adjudication checked it; a follow-up ran it from 9.8.0 to main and probed for safety effects; the repro was minimized to one test.
No prior report found (2026-10-25 and 2026-10-26: GitHub issues, PRs and commits, Elasticsearch, OpenSearch and Solr, four mailing lists, JIRA and the web, 153 queries; GitHub rechecked 2026-10-31). The identifier mergeLeafResults appears in only 4 Lucene items, none about ordering.
Searches2 searches
Verdict new: no issue, PR, commit, list thread, JIRA entry or downstream report describes the ordering assumption. Related, not reports: #16686 (the descending-order precondition on createDocAndScoreQuery, for its direct callers), #16271 (the explainer comment), #14226 (the last-entry read), #12590 / #12575 (the hook), #12146 (the first-entry read), #14857 / #14858 (a 9.x advanceShallow bug whose backport brought the first-entry read to 9.12.3), #12679 (an early revision overrode the hook with unsorted output), #13564, #13131 / #13134, #14009. Nine open PRs touch AbstractKnnVectorQuery.java and none changes these assumptions; #16866 edits the re-entry loop. The max-score half shares createDocAndScoreQuery's first-entry read with a separate case found earlier, RescoreTopNQuery passing its hits in heap order; the fixes differ.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, Elasticsearch, OpenSearch, Solr), the OpenSearch k-NN plugin, open PRs' changed files, dev@, java-user@, issues@, commits@, JIRA, web | 2026-10-25 and 2026-10-26 | a scripted prior-report search in three runs (153 queries), manual code search for mergeLeafResults overrides downstream, all 10 apache/lucene items that mention RescoreTopNQuery, the changed files of all 412 open PRs | no report; related #16686, #16271, #14226, #12590, #12575, #12146, #14857, #14858, #12679 |
| GitHub (recheck) | 2026-10-31 | mergeLeafResults, "no constraint on their ordering", minTopKScore, "DocAndScoreQuery maxScore", "createDocAndScoreQuery descending", "knn getMaxScore first entry"; the two files' commit history on upstream main | no report; the newest commits on both files (#16271, #16686) are already in 645d4fe14a20 |
The hook and its "no constraint on their ordering" javadoc came with #12590 (2474940bffe, 2023-10); the first-entry max read was already there (#12146). First affected releases: 10.0.0 and 9.12.3 (max score); 10.3.0 adds the re-entry read (#14226). 9.9.0 to 9.12.2 scan for the max and pass. Not fixed on main.
Versions tested7 rows
Introduced by #12590, "Allow implementers of AbstractKnnVectorQuery to access final topK results" (kaivalnp; approved by benwtrent and mikemccand; closes #12575): 2474940bffe on main (2023-10-06) and the branch_9x backport b85aeb3a4fa. It added the hook with its javadoc and routed rewrite() through it, but kept maxScore = topK.scoreDocs[0].score, which came with #12146 (8340b01c3cc, 2023-02-16, main only). That is where the contract and the code began to disagree, on main; on 9.x the max was computed by scanning until #14858 (16b9a8725ea, 2025-06-30, a backport of #12146 that fixed #14857) brought the first-entry read to 9.12.3. The last-entry reads came with #14226 (d279af1961f, 2025-05-05, released in 10.3.0) and #16271 (4b982fffe24, 2026-07-09, in 10.6.0).
Swapping only AbstractKnnVectorQuery.java between 9.12.2 and 9.12.3 flips the follow-up's result in both directions; the 10.2.2 to 10.3.0 step for the re-entry half is attributed by code presence. Releases not executed (10.1.0 to 10.5.1 not listed) carry the same code by inspection. Upstream main 2f424fd428da (2026-10-30) is unchanged.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal repro fails with assertions on and off (getMaxScore 0.5 < score 1.0); the finder's end-to-end test fails 2 of 2 |
| 10.6.0 | affected | minimal repro fails (assertions on and off); the finder's end-to-end test fails 2 of 2 (top-1 doc 0 instead of 200000; doc 16000 among the 50 nearest) |
| 10.3.0, 10.5.2 | affected | minimal repro fails (assertions on and off); both halves (max score and re-entry) |
| 10.0.0, 9.12.3 | max-score half | minimal repro fails (assertions on and off); no re-entry pass before 10.3.0 |
| 9.12.2, 9.9.0 | not affected | the hook exists, but the max score is computed by scanning: minimal repro passes |
| 9.8.0 | not affected | no mergeLeafResults: the repro does not compile |
with the sort fix (645d4fe14a20) | not affected | minimal repro and the finder's end-to-end tests pass; 372 core and 39 join kNN tests pass |
A cross-model refute review, an independent reproducer, a cross-model intended-behaviour review and a devil's-advocate verifier all said real; the adjudication confirmed with high confidence. Every stock-query control passed, and the sort fix made the finder's, the reproducer's and both reviewers' tests pass.
Checks and verdicts499 words
Every executing check ran on stock builds of main (ea57360912ed, a9779ef3c193 or 645d4fe14a20, with identical files involved) or on releases.
| Check | Verdict | What it found |
|---|---|---|
| Finder (JUnit) | candidate | Doc-id-ordered override with a stock control: 2 of 2 fail on main with assertions on and off, 20 of 20 over 10 iterations, on 10.3.0, 10.4.0 and 10.5.2; the sort fix passes it and 137 upstream kNN tests. |
| Cross-model review, refute lens (OpenAI GPT-5.6) | real, high | Own reverse-order test fails on 3 seeds and with assertions off (getMaxScore 0.0121951215 while the scorer emitted 1.0; multi-segment hits lost); the descending control passes; the fix passes it and 43 TestKnnFloatVectorQuery tests. Intended argument weak. |
| Independent reproducer | real | Own public-API test in a non-Lucene package, ascending permutation, brute-force or arithmetic oracles: 4 of 4 fail on main (on and off), 40 of 40 over 10 iterations; 10.2.0 3 of 4, 10.0.0 and 9.12.3 2 of 4; passes with the fix. |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real, high | Own reverse-order test fails 2 of 2 on main and 10.5.2 and passes on 10.0.0 and 9.12.3; its own first re-entry shape did not separate stock and reordered, so it reused the finder's shape; the fix passes it and 237 kNN tests. |
| Devil's advocate | real, narrow | Override in an application package that re-weights the hits without re-sorting: score 2.0 above getMaxScore 1.0 and the top-1 lost, on main and 10.5.2; no intended-behaviour argument survives; read five downstream overrides, all sorted. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with seed 7A11D6E5: 4 of 4 fail with assertions on and off. Not the same as the separate RescoreTopNQuery case found earlier. |
| Follow-up (history and safety probe) | affected 9.12.3, 10.0.0 to main | Cross-version repro from 9.8.0 (no hook) to main, with a single-file swap at 9.12.2/9.12.3; a 10-run safety probe found no safety violation while the symptom appeared in every run. |
| Repro minimization | verified | The one-test repro on 645d4fe14a20 with assertions on and off, 10 of 10 with a second seed; passes with the fix shadowed. |
| This doc's runs (2026-10-31) | reproduced, fix validated | The minimal repro on main (assertions on and off) and eight releases (fails on 10.6.0, 10.5.2, 10.3.0, 10.0.0 and 9.12.3; passes on 9.12.2 and 9.9.0; does not compile on 9.8.0), the finder's end-to-end test on 10.6.0, and gradle in a scratch worktree of 645d4fe14a20: stock fails; the sort fix and the scan fix each pass 372 core and 39 join kNN tests and the finder's end-to-end tests. |
| Fact checks of this doc (2026-10-31) | bug holds; text fixes applied | An independent check re-ran the doc's gradle command on a clean copy of 645d4fe14a20 (fails with assertions on and off; passes with the sort fix, 84 tests), the five failing releases with assertions off, and a probe that executed the re-entry skip and the explainer read. A read-only cross-model check (OpenAI GPT-5.6) found wording issues only. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 562 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,577 words
- Registry title
- AbstractKnnVectorQuery#mergeLeafResults is documented to return hits in any order, but rewrite() reads the k-th score from the last entry and DocAndScoreQuery the max score from the first, so an override that only reorders the hits changes the results
- Area
- search / kNN query rewrite (AbstractKnnVectorQuery#mergeLeafResults extension point, optimistic re-entry pass) and DocAndScoreQuery max score
- Priority
- Low, rank 871: A mergeLeafResults override that returns unsorted hits, which the javadoc allows, silently breaks max-score and re-entry results, but no in-tree code or known downstream override does that.
- Impact class
- silent wrong results
- Impact note
- Only applications that subclass KnnFloatVectorQuery or KnnByteVectorQuery (directly, or wrapped in SeededKnnVectorQuery or PatienceKnnVectorQuery, which delegate the hook) and override the protected, @lucene.experimental mergeLeafResults so that it returns hits not sorted by descending score, for example by re-weighting the merged hits without re-sorting them, which its javadoc permits: the rewritten query's getMaxScore then under-reports its own scores (a Scorer contract break), so a top-k disjunction pruned under TOP_SCORES drops the true best kNN hit (since 9.12.3 and 10.0.0), and from 10.3.0 the optimistic multi-segment re-entry reads the wrong k-th score, so even a stand-alone kNN query on a multi-segment index returns farther neighbours; no in-tree query triggers it, and the five downstream overrides read (Elasticsearch, Solr, OpenSearch k-NN, mongot, nrtsearch) all return sorted output; ordinary scale, default codec and searcher, no error, the same under -ea and -da.
- Summary
- You subclass KnnFloatVectorQuery and override mergeLeafResults, whose javadoc says it returns 'index-level kNN results (no constraint on their ordering)' and is 'useful for reading and / or modifying the final results', so that it returns exactly the default merge's hits in another order (same documents, same scores). You expect the same search results as the stock query. Instead rewrite() takes the k-th score from the last entry and DocAndScoreQuery the max score from the first, so with doc-id order a top-1 search for the kNN query OR a 0.5-boosted term returns doc 0 (score 0.51) instead of the exact match, doc 200000 (score 1.0), and on a 10-segment index the k = 50 query re-enters no segment and returns farther documents (first differing doc 16000 instead of 19950).
- Introduced
- 2474940bffe on main (branch_9x backport b85aeb3a4fa), PR #12590 'Allow implementers of AbstractKnnVectorQuery to access final topK results' (kaivalnp; closes #12575): it added the protected @lucene.experimental mergeLeafResults with the javadoc '@return index-level kNN results (no constraint on their ordering)' and routed rewrite() through it, while createRewrittenQuery kept reading the max score from scoreDocs[0] [read: git log -S 'no constraint on their ordering' finds only this commit; git blame at the study base attributes the javadoc and method to it]; the order-dependent reads it exposed: 8340b01c3cc (#12146 'Simplify max score for kNN vector queries', jtibshirani, max score from the first entry, correct when written because the merge could not be overridden; reached 9.x only through 16b9a8725ea, #14858, benwtrent, on branch_9_12), d279af1961f (#14226 'OptimisticKnnVectorQuery', msokolov; branch_10x backport 61424c489e6: minTopKScore from the last entry for the re-entry pass) and 4b982fffe24 (#16271, slow-J: the no-match explainer, new in 10.6.0 (released 2026-10-29); executed on main by a probe of the 2026-10-31 fact check) [read]; exec: 9.12.2 passes and 9.12.3 fails, and swapping only AbstractKnnVectorQuery.java between them flips the result in both directions; the re-entry half first fails on 10.3.0 (10.2.2 passes that test), attributed by code presence; Lucene was not built at the commits themselves (2023-10-05 (#12590 merged on main; commit timestamp 2023-10-06 +0530); the order-dependent reads: 2023-02-16 (#12146, first entry, on main), 2025-06-30 (#14858 merged on branch_9_12), 2025-05-05 (#14226, last entry, on main), 2026-07-09 (#16271, explainer, on main))
- First affected version
- 10.0.0 [exec] on the main line and 9.12.3 [exec] on the 9.x line for the max-score half; 10.3.0 [exec] for the re-entry half (10.2.0 and 10.2.2 pass that test [exec]); 9.9.0-9.12.2 have the hook but compute the max score by scanning and are not affected [exec on 9.9.0 and 9.12.2]
- Affected versions
- max-score half: 9.12.3, 10.0.0, 10.1.0, 10.2.0, 10.2.2, 10.3.0, 10.4.0, 10.5.2 and main ea57360912ed [exec: the follow-up history repro on 9.12.3, 10.0.0, 10.1.0, 10.2.2, 10.3.0, 10.4.0, 10.5.2 and main (the last two also -da); the independent reproduction on 9.12.3, 10.0.0, 10.2.0, 10.3.0, 10.5.2 and main; the intended-behaviour check on 9.12.3 and 10.0.0 (-da), 10.5.2 and main], and 10.2.1, 10.3.1, 10.3.2, 10.5.0 and 10.5.1 by the code present at each tag [read]; re-entry half: 10.3.0, 10.4.0, 10.5.2 and main [exec: finder repro, the independent reproduction, history repro], 10.3.1, 10.3.2, 10.5.0 and 10.5.1 [read]; the no-match explainer's last-entry read: main, branch_10_6 and branch_10x only [read; on main executed by a probe of the 2026-10-31 fact check]. Not affected: 9.9.0 and 9.12.2 [exec, pass; 9.9.1-9.12.1 have the same scan-based code by grep, read]; 9.8.0 and earlier lack the hook [exec: the repro does not compile on 9.8.0]. 10.6.0 (released 2026-10-29) fails [exec: the minimal repro and the finder's end-to-end test, 2026-10-31]; branch_10_6 and the unreleased branch_10x carry the same code [read, upstream refs fetched 2026-10-24; re-read 2026-10-29: AbstractKnnVectorQuery.java and DocAndScoreQuery.java blobs unchanged at branch_10x 657014b3c57 and branch_10_6 4ae946e5a9b]. Not fixed upstream at main 645d4fe14a2 [exec 2026-10-29: finder 2/2, the independent reproduction 4/4, the intended-behaviour check 2/2 and the history repro 3/3 fail, -ea and -da], and no open PR changes the assumptions [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-25 and 2026-10-26: a scripted prior-report search in three runs over GitHub issues, PRs and commits of apache/lucene, the downstream repositories Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web, 153 recorded queries; manual read-only GitHub code search for mergeLeafResults overrides in Elasticsearch, OpenSearch and Solr, and issue search in opensearch-project/k-NN; all 10 apache/lucene items that mention RescoreTopNQuery; the changed-file lists of all 412 open apache/lucene PRs; read-only gh searches by the independent reproduction and the intended-behaviour check); the bare identifier mergeLeafResults matches only 4 apache/lucene items (#14009, #16324, #15676, #12679), none about ordering; related, not this bug: #16686 (merged 2026-09-29: the now-public createDocAndScoreQuery javadoc says 'The entries of topK are expected in descending score order', a precondition for direct callers that does not mention mergeLeafResults), #16271 (explainer comment 'topK is score-descending'), #14226 (introduced the last-entry minimum; overrides never discussed), #12590 / #12575 (added the hook and its 'no constraint on their ordering' javadoc; a reviewer, benwtrent, warned in general terms that another extension point makes it 'very easy to do the wrong thing'; ordering not discussed), #12146 (first-entry max score), #14858 / #14857 (a 9.x advanceShallow bug; its backport brought the first-entry max to 9.12.3), #12679 (an early revision overrode the hook to concatenate unsorted per-segment results), #14009, #13564, #13131 / #13134 and #16324; open PRs #16866, #16847, #16578, #16204, #15613, #13594, #13525, #12819 and #12314 touch AbstractKnnVectorQuery.java and none changes the ordering assumptions (#16866 edits the re-entry loop, so a patch may need a rebase); every downstream override found returns sorted TopDocs.merge output, and no downstream issue reports it
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails through gradle in a scratch worktree and through a standalone runner with assertions on and off, and on 10.6.0, 10.5.2, 10.3.0, 10.0.0 and 9.12.3 (assertions on; a later fact check ran these five with assertions off too: the same failure); it passes on 9.12.2 and 9.9.0 and does not compile on 9.8.0 (no hook). The finder's end-to-end test fails on 10.6.0 and main. The sort fix passes the minimal test, 372 core and 39 join kNN tests through gradle, with assertions on and off, and the core format, ECJ and forbidden-apis checks; the scan fix passes the same tests. The hunt, the verifiers and the adjudication ran mainea57360912ed; the files involved are identical in both commits.
- Finding record
lucene/core/src/java/org/apache/lucene/search/AbstractKnnVectorQuery.java:118 (first runSearchTasks), :120-125 (re-entry gate), :126 (minTopKScore = topK.scoreDocs[length - 1].score), :136-137 (re-enter a leaf whose lowest hit reaches minTopKScore), :150 (second runSearchTasks), :156-157 (createDocAndScoreQuery on the merged hits), :161-163 (no-match explainer, comment 'topK is score-descending'), :227 (runSearchTasks returns mergeLeafResults unchanged), :416-430 (mergeLeafResults javadoc and default TopDocs.merge)lucene/core/src/java/org/apache/lucene/search/DocAndScoreQuery.java:103-120 (createDocAndScoreQuery javadoc: entries expected in descending score order, max score captured from the first entry), :125 (maxScore = topK.scoreDocs[0].score), :126 (sort by doc id), :239-241 (getMaxScore returns maxScore * boost)lucene/core/src/java/org/apache/lucene/search/Scorer.java:75-79 (getMaxScore: 'Return the maximum score that documents ... upTo included'); lucene/core/src/java/org/apache/lucene/search/package-info.java:388-390 ('Custom Queries - Expert Level'); lucene/core/src/java/org/apache/lucene/search/SeededKnnVectorQuery.java:172-173 and PatienceKnnVectorQuery.java:214-215 (the in-tree overrides delegate)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/AbstractKnnVectorQuery.java:118, :126, :136-137, :150, :156-157, :160-166, :227, :343-347, :416-430lucene/core/src/java/org/apache/lucene/search/DocAndScoreQuery.java:109-111, :125-126, :238-246; lucene/core/src/java/org/apache/lucene/search/Scorer.java:75-79lucene/core/src/java/org/apache/lucene/search/KnnFloatVectorQuery.java:48, KnnByteVectorQuery.java:47, KnnFloat16VectorQuery.java:48; lucene/core/src/java/org/apache/lucene/search/knn/TopKnnCollectorManager.java:55-58
- Who is affected
lucene/core/src/java/org/apache/lucene/search/SeededKnnVectorQuery.java:172-173, PatienceKnnVectorQuery.java:214-215
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/AbstractKnnVectorQuery.java:416-427; lucene/core/src/java/org/apache/lucene/search/DocAndScoreQuery.java:109-111; lucene/core/src/java/org/apache/lucene/search/package-info.java:388-390https://github.com/apache/lucene/pull/12590, https://github.com/apache/lucene/pull/12679, https://github.com/apache/lucene/issues/14857, https://github.com/apache/lucene/pull/16697, https://github.com/apache/lucene/pull/16686lucene/core/src/java/org/apache/lucene/search/TopDocs.java:44-45, :197-198
- Prior reports
https://github.com/apache/lucene/pull/16686, https://github.com/apache/lucene/pull/14226, https://github.com/apache/lucene/pull/12590
- TestKnnMergeLeafResultsOrder.java (one test class):
repro/LFV-123/src/org/apache/lucene/search/TestKnnMergeLeafResultsOrder.java(65 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the repro's output; the summary card was re-rendered after the diagram check so that its 'inside Lucene' part shows one labelled row per executed example.
assets/LFV-123/bug.png(562 KB)