IndexWriter starts a flush, of its largest thread's buffered documents, when the heap that all buffered documents and deletes use, summed from each component's ramBytesUsed(), reaches ramBufferSizeMB (16 MB by default); each thread also has a 1945 MB hard limit. For fields with term vectors, the term-vectors writer is one of those components, and it reports its biggest buffers in the wrong unit.
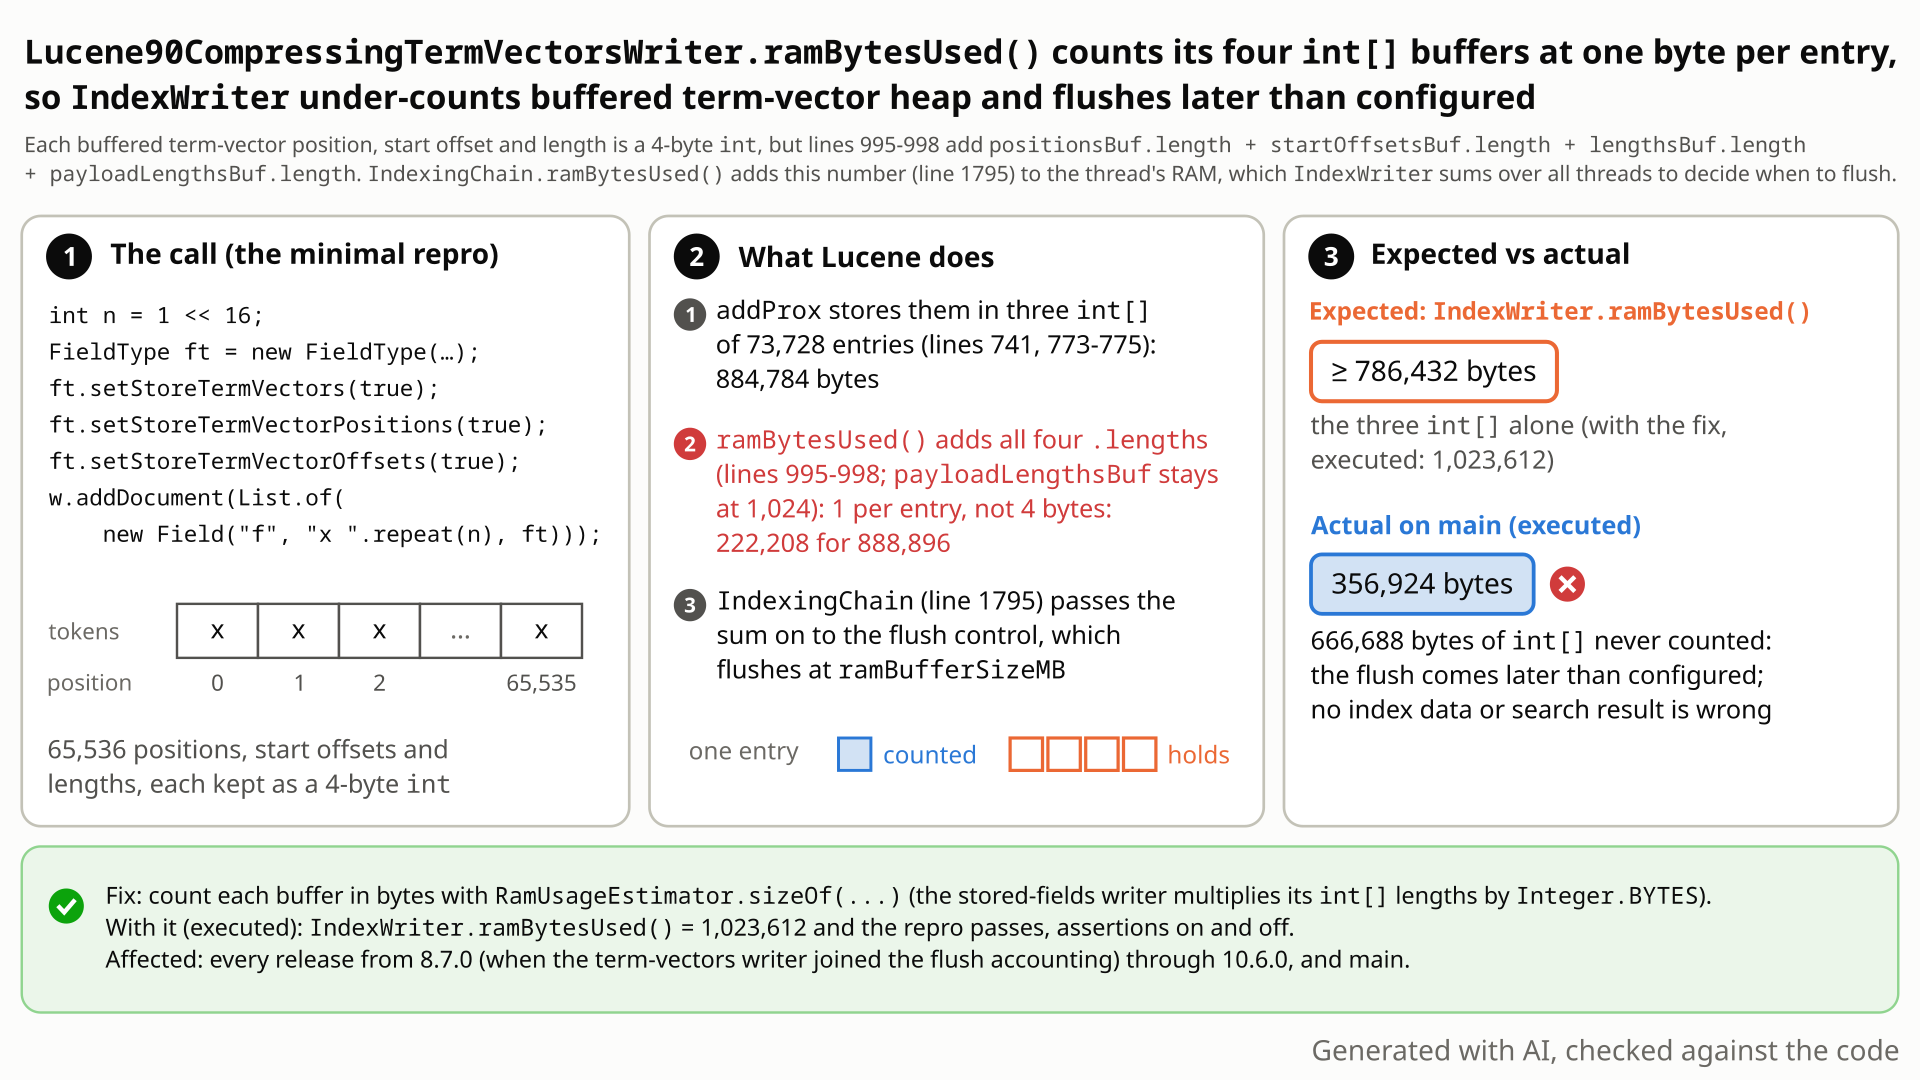
addDocument with 65,536 term-vector positions: the writer's int[] buffers hold 888,896 bytes, but ramBytesUsed() counts their 222,208 entries as bytes, so IndexWriter reports 356,924 in total (1,023,612 with the fix). Select the still to open it at full size. Generated with AI, checked against the code.- Index one document whose field stores term vectors with positions and offsets, text: the word "x" 65,536 times (default codec and
IndexWriterConfig). - The term-vectors writer keeps the not-yet-written positions, start offsets and lengths in
int[]buffers, here 73,728 entries each, 888,896 bytes in all with the payload-length buffer. You expectIndexWriter.ramBytesUsed()to be at least 786,432. - You get 356,924 for the whole IndexWriter. With the fix it reports 1,023,612, so 666,688 bytes were missing.
- Why: the writer's
ramBytesUsed()addspositionsBuf.length + startOffsetsBuf.length + lengthsBuf.length + payloadLengthsBuf.length, array lengths, as if eachinttook one byte. - Effect: IndexWriter decides when to flush from this number, summed over its threads, so flushes come later than
ramBufferSizeMBintends. With about a million positions in one document, 10.6 MB go uncounted. Index data and results stay correct.
Any application with a term-vector field that stores positions or offsets, on the default codec, through plain IndexWriter.addDocument (FastVectorHighlighter needs them). With positions and offsets, about 9 bytes per buffered position go uncounted: about 12 KB per fresh writer, megabytes once a pending chunk holds about 10^5 positions, typically one very long document. Data and results stay correct.
Mechanism, terms and numbers589 words
Since 8.7.0 (LUCENE-9514), IndexWriter adds the term-vectors writer's ramBytesUsed() to each indexing thread's RAM, so that flush and stall decisions see the heap it holds (IndexingChain.java:1792-1797, CHANGES.txt:5627-5629 at 5adff78bb168). The default writer, Lucene90CompressingTermVectorsWriter, keeps the positions, start offsets, lengths and payload lengths of not-yet-written documents in four int[] buffers (:225), but its ramBytesUsed() adds their .length values (:993-1003), as if each int took one byte, so three quarters of that memory is never counted. With one document of 65,536 term-vector positions and offsets, IndexWriter.ramBytesUsed() is 356,924 bytes, below the 786,432 the three position/offset arrays need at minimum; with RamUsageEstimator.sizeOf per buffer it is 1,023,612. The stored-fields writer, added to the same accounting a week earlier, multiplies by Integer.BYTES. No index data or search result is wrong; IndexWriter only flushes later than ramBufferSizeMB and the per-thread hard limit intend.
- Buffers.
Lucene90CompressingTermVectorsWriterdeclaresprivate int[] positionsBuf, startOffsetsBuf, lengthsBuf, payloadLengthsBuf;(:225at5adff78bb168), allocates each asnew int[1024](:295-298) and grows them as positions, start offsets and lengths are buffered, and payload lengths only for fields with payloads (addPosition:194-217,addProx:734-788). Nothing shrinks them until the segment flushes. - A pending chunk keeps all its positions. A chunk is written only once its term suffixes and payload bytes reach 4 KiB (
finishDocumentappends the payload bytes to the suffixes,:323-329) or it holds 128 documents (:379-381;Lucene90TermVectorsFormat.java:170). Until then the positions of all its documents sit in the buffers at once: one long document with few distinct terms is enough, and up to 128 shorter ones add up the same way. Writing a chunk clears the pending documents but keeps the grown buffers (:429-434). - Through IndexWriter.
TermVectorsConsumerPerFieldcallsaddProx(freq, ...)once per term (TermVectorsConsumerPerField.java:119);positionsBufgrows throughArrayUtil.growandstartOffsetsBufandlengthsBufthroughArrayUtil.growExact(..., ArrayUtil.oversize(n, 4)); both giveArrayUtil.oversize(n, 4)= 73,728 entries for n = 65,536. Without payloads,payloadLengthsBufkeeps its 1,024. - The count.
ramBytesUsed()(:993-1003) returnspositionsBuf.length + startOffsetsBuf.length + lengthsBuf.length + payloadLengthsBuf.length + termSuffixes.ramBytesUsed() + payloadBytes.ramBytesUsed() + lastTerm.bytes.length + scratchBuffer.ramBytesUsed(): four element counts ofint[]next to four byte counts. - Where the number goes.
TermVectorsConsumercreates the writer when a thread first indexes a term-vector field and setsaccountable = writer(TermVectorsConsumer.java:103-109);IndexingChain.ramBytesUsed()adds it (IndexingChain.java:1795);DocumentsWriterPerThread.ramBytesUsed()adds the chain (DocumentsWriterPerThread.java:718-723).DocumentsWriterFlushControladds each thread's change toactiveBytes, the RAM of all active threads (DocumentsWriterFlushControl.java:244); the flush policy comparesactiveBytesplus buffered deletes withramBufferSizeMBand marks the largest thread for flushing (FlushByRamOrCountsPolicy.java:45-55,:84); the per-thread hard limit checks the thread's own total (DocumentsWriterFlushControl.java:247).IndexWriter.ramBytesUsed()reports delete bytes plus the committed bytes of all threads (IndexWriter.java:796-799,DocumentsWriter.java:748-750,DocumentsWriterFlushControl.java:513-516): with one thread and no deletes, as here, this thread's total.
| input (one document, one term) | buffer entries (3 arrays + payload) | int[] heap | counted by the writer | IndexWriter.ramBytesUsed() stock | with option A |
|---|---|---|---|---|---|
| fresh writer | 3 x 1,024 + 1,024 | 16,448 | 4,096 | ||
| 65,536 positions and offsets | 3 x 73,728 + 1,024 | 888,896 | 222,208 | 356,924 | 1,023,612 |
| 1,048,576 positions and offsets | 3 x 1,179,648 + 1,024 | 14,159,936 | 3,539,968 | 4,657,724 | 15,277,692 |
The two IndexWriter columns are measured; the differences, 666,688 and 10,619,968 bytes, equal 3 bytes per buffer entry plus four array headers of 16 bytes, exactly as the code predicts. The heap and counted columns follow from the capacities by reading.
Exposure and likelihood262 words
- Reach. The default
Lucene104CodecusesLucene90TermVectorsFormat(Lucene104Codec.java:71). Term-vector positions and offsets are an opt-in field option; the FastVectorHighlighter requires them and advertises itself as "fast for large docs" (vectorhighlight/package-info.java:24,:28). - Effect.
ramBufferSizeMB(default 16 MB,IndexWriterConfig.java:83) is compared with the RAM of all threads, so flushes come later than it intends, and a thread reaches the per-thread hard limit (default 1945 MB,:93) later. With the default buffer, one document of about a million term-vector positions with offsets holds 10.6 MB the flush policy does not see (measured). - Scale. 3 bytes per
intof buffer capacity, for each buffer the field uses: per buffered position about 3 bytes with positions only, 6 with offsets only, 9 with both (about 10 with growth slack), 12 with payloads as well. About 12 KB per term-vectors writer from the start (fourint[1024]counted as 4,096 bytes instead of 16,448); the writer exists once a thread indexes a term-vector field, one per thread's segment. Megabytes once one pending chunk has buffered on the order of 10^5 positions or more: typically one very long document, but many repetitive shorter ones in one chunk do it too (127 documents of 8,192 positions: 9,956,416 bytes uncounted, measured). The gap then lasts until the segment flushes. - Not a cap, before or after the fix.
ramBufferSizeMBstays an indicator of when to flush, and a flush may release only part of the buffer (LiveIndexWriterConfig.java:167-181); the fix makes that indicator count these buffers correctly. - Not affected. Indexed data, segment files and search results.
One JUnit test method on the public API: one IndexWriter.addDocument of a field with term vectors, positions and offsets, holding the word "x" 65,536 times. Deterministic, single-threaded, about a second; it fails with assertions on and off and passes with either fix.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestTermVectorsRamBytesUsed extends LuceneTestCase {

  public void testBufferedTermVectorPositionsAreCounted() throws Exception {
    // Expected: ramBytesUsed() >= the 3 int[n] buffers (positions, start offsets, lengths);
    // actual: their lengths are counted as bytes.
    int n = 1 << 16;
    FieldType ft = new FieldType(TextField.TYPE_NOT_STORED);
    ft.setStoreTermVectors(true);
    ft.setStoreTermVectorPositions(true);
    ft.setStoreTermVectorOffsets(true);
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      w.addDocument(List.of(new Field("f", "x ".repeat(n), ft)));
      long buffered = 3L * n * Integer.BYTES;
      assertTrue(w.ramBytesUsed() + " < " + buffered, w.ramBytesUsed() >= buffered);
    }
  }
}
cp $REPRO/TestTermVectorsRamBytesUsed.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestTermVectorsRamBytesUsed -Ptests.seed=5EED1232 -Ptests.asserts=true
# and with -Ptests.asserts=false (assertions off)
- Expected
IndexWriter.ramBytesUsed()is at least 786,432 bytes, the three bufferedint[]of at least 65,536 entries each (with the fix: 1,023,612).- Observed
AssertionError: 356924 < 786432, with assertions on and off.
More files, environment, full output156 words
The bound is conservative: it counts only three arrays at exactly n entries, ignoring growth slack, the payload-length buffer, array headers and everything else IndexWriter holds. It is a lower bound, not an exact heap count: an unrelated rise in IndexWriter's other accounting could in principle make it pass, so the measured probe values above pin the exact numbers. Pass -Ptests.asserts explicitly; the result depends on neither setting.
As a regression test, the same method fits into the existing lucene/core/src/test/org/apache/lucene/index/TestTermVectorsWriter.java.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): this test fails; earlier tests with the same root cause also fail on 8.7.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2 and 10.6.0 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 (nothing platform-specific) |
TestTermVectorsRamBytesUsed > testBufferedTermVectorPositionsAreCounted FAILED
    java.lang.AssertionError: 356924 < 786432
        at org.apache.lucene.index.TestTermVectorsRamBytesUsed.testBufferedTermVectorPositionsAreCounted(TestTermVectorsRamBytesUsed.java:43)

# main 5adff78bb168, gradle, seed 5EED1232: the same failure with -Ptests.asserts=true and =false
# with option A or option B: BUILD SUCCESSFUL, 1 test, 0 failures, assertions on and offAccountable#ramBytesUsedreturns "an estimate of the JVM heap memory used by this object in bytes"; LUCENE-9514 added this method so IndexWriter's flush and stall decisions count the writer's heap.- The same
returnadds real byte counts next to theint[]lengths. - The stored-fields writer, added a week earlier by the same author, multiplies its
int[]lengths byInteger.BYTES.
The full argument143 words
- Contract. "Returns an estimate of the JVM heap memory used by this object in bytes" (
util/Accountable.java:35). - Purpose. The introducing commit
8f895d90755(LUCENE-9514): "TermVectorsWriter might consume some heap space memory that can have a significant impact on decisions made in the IW if writers should be stalled or DWPTs should be flushed if memory settings are small in IWC and flushes are frequent"; CHANGES, under 8.7.0: "to ensure that it's heap consumption is taken into account when IndexWriter stalls or should flush DWPTs" (CHANGES.txt:5627-5629). - Sibling.
98e55f0ea82(LUCENE-9511, 2020-09-08, same author) counted the stored-fields writer'sint[]aslength * Integer.BYTES; #11923 later widened it to(long) Integer.BYTES(Lucene90CompressingStoredFieldsWriter.java:726-730) and left the term-vectors method alone. - No record of a choice found. We found no comment, test, CHANGES or MIGRATE entry, or review comment on apache/lucene-solr#1847 that mentions counting per element.
The devil's-advocate check171 words
The strongest case for "intended": Accountable is @lucene.internal (Accountable.java:30) and promises only "an estimate", the writer is @lucene.experimental (Lucene90CompressingTermVectorsWriter.java:63), and the RAM-buffer docs say an IndexWriter "can consume a significantly larger amount of memory than the given RAM limit since this limit is just an indicator when to flush" (LiveIndexWriterConfig.java:167-171).
Why it fails: an estimate may skip headers or small objects; counting the dominant owned payload in element units is a 4x unit error. The same javadoc says "the writer will flush whenever buffered documents and deletions use this much RAM" (:162-163). The javadoc does not document this per-element accounting; concurrent and partial flushing (:167-181) separately mean the setting is not a hard heap cap. The tags limit API stability, not the correctness of a number IndexWriter acts on, and the trigger is ordinary IndexWriter.addDocument. The independent reviewer from another model family rated the intended case weak in both its refute and its intended-behaviour pass. Verdict: a real Low bug.
Recommended A. RamUsageEstimator.sizeOf per buffer (validated)
Count each buffer with RamUsageEstimator.sizeOf(positionsBuf) (and the same for the other three) instead of .length: one file, five lines. The repro passes with assertions on and off, and 82 term-vector and flush-policy tests pass. Alternative: length * (long) Integer.BYTES, the stored-fields writer's idiom.
+import org.apache.lucene.util.RamUsageEstimator;
...
-    return positionsBuf.length
-        + startOffsetsBuf.length
-        + lengthsBuf.length
-        + payloadLengthsBuf.length
+    return RamUsageEstimator.sizeOf(positionsBuf)
+        + RamUsageEstimator.sizeOf(startOffsetsBuf)
+        + RamUsageEstimator.sizeOf(lengthsBuf)
+        + RamUsageEstimator.sizeOf(payloadLengthsBuf)
All options and trade-offs2 options · 310 words
Both options were applied in a scratch worktree at 5adff78bb168 and run through gradle; the existing suites were run with option A.
Lucene90CompressingTermVectorsWriter.java:993-1003 plus one import: 1 file, 5 insertions, 4 deletions.
+import org.apache.lucene.util.RamUsageEstimator;
...
-    return positionsBuf.length
-        + startOffsetsBuf.length
-        + lengthsBuf.length
-        + payloadLengthsBuf.length
+    return RamUsageEstimator.sizeOf(positionsBuf)
+        + RamUsageEstimator.sizeOf(startOffsetsBuf)
+        + RamUsageEstimator.sizeOf(lengthsBuf)
+        + RamUsageEstimator.sizeOf(payloadLengthsBuf)
Trade-offs
Counts the array headers too, as Lucene's other accounting does. ramBytesUsed() is called after each document (DocumentsWriterFlushControl.java:216; the change is committed once it is large enough, :218-223); the fix adds four small computations, nothing per position. Writers with many term-vector positions now report more and flush earlier, closer to their configured RAM, which is the point; ramBufferSizeMB stays an indicator, not a heap cap.
What the checks validated
- The repro passes with assertions on and off (gradle, seed
5EED1232). - With the fix,
TestCompressingTermVectorsFormat,TestLucene90TermVectorsFormat,TestTermVectors,TestTermVectorsReader,TestTermVectorsWriter,TestMultiThreadTermVectorsandTestFlushByRamOrCountsPolicypass with assertions on (8 classes with the repro, 82 tests, 0 failures, 0 skipped). :lucene:core:checkGoogleJavaFormatpasses with the fix and the test file.IndexWriter.ramBytesUsed()rises from 356,924 to 1,023,612 for the repro's input, and from 4,657,724 to 15,277,692 at 2^20 positions; the differences equal 3 bytes per buffer entry plus four array headers.
The stored-fields writer's idiom (Lucene90CompressingStoredFieldsWriter.java:728-729): positionsBuf.length * (long) Integer.BYTES and the same for the other three; 4 lines, no import.
-    return positionsBuf.length
+    return positionsBuf.length * (long) Integer.BYTES
-        + startOffsetsBuf.length
+        + startOffsetsBuf.length * (long) Integer.BYTES
-        + lengthsBuf.length
+        + lengthsBuf.length * (long) Integer.BYTES
-        + payloadLengthsBuf.length
+        + payloadLengthsBuf.length * (long) Integer.BYTES
Trade-offs
Omits the four array headers (16 bytes each on this JVM), negligible. The repro passes with assertions on and off; the existing suites were run with option A only.
Products that index very long documents into term-vector fields with positions or offsets, with a heap sized close to the RAM buffer, can use noticeably more heap than their flush settings suggest until it is fixed.
A proof-obligation audit of the term-vectors writer's Accountable#ramBytesUsed contract: the method must report the heap it holds in bytes. Checking each term of its sum against the field types showed four int[] lengths added as bytes. A one-method JUnit test through IndexWriter.addDocument witnessed it.
The method in full71 words
The obligation came from the Accountable#ramBytesUsed javadoc and the purpose stated in LUCENE-9514, checked term by term against the declared types of the summed fields (:225). The first witness drove the writer directly with one term of 2^20 positions (ramBytesUsed()=3217630 while three buffered arrays need at least 12,582,912 bytes, main with assertions on and off and 10.6.0); the minimal repro then showed the same through public IndexWriter API.
No matching report found in the recorded searches of apache/lucene issues, PRs and commits (incl. the JIRA archive), the mailing lists, downstream trackers and the web (2026-11-03). Nearest: #10553, the change that added the method, and #10550, the stored-fields sibling that counts Integer.BYTES.
Searches3 searches
Nearest items, none of them this bug: #10553 (LUCENE-9514, origin; its PR review does not discuss buffer sizing), #10550 (LUCENE-9511, the stored-fields sibling), #10143 (LUCENE-9101, open since 2019: lengthsBuf is redundant, a memory idea that predates the method), #16113 and draft #16114 (open: Accountable ownership semantics, explicitly not bug reports), #15982 and #16405 (the latter fixed by PR #16406; RAM under-count fixes in other classes). No open PR changes this method. Keyword searches cannot see private reports or every review comment.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, comments and commits (apache/lucene incl. the migrated JIRA archive, apache/lucene-solr) | 2026-11-03, re-checked the same day | three scripted prior-report searches (45 executed queries each over GitHub issues and PRs, commits, downstream repositories, the mailing lists and the JIRA archive; their 6 web queries each were not executed by the script) and 30 manual searches: positionsBuf.length, payloadLengthsBuf, CompressingTermVectorsWriter ramBytesUsed, TermVectorsWriter Integer.BYTES, RAM-buffer and flush symptoms; git log -S 'positionsBuf.length' | no report; #10553, #10550, #10143, #16113/#16114 are context |
| Open PRs | 2026-11-03 | the changed files of all 410 open apache/lucene PRs and the 60 most recently updated closed ones | #1003 and #16480 edit the writer and #16269 edits TermVectorsConsumer, but none touches ramBytesUsed or the buffer sizing |
| Mailing lists, downstream, web | 2026-11-03 | dev@, java-user@, issues@, commits@ (11 manual queries); Solr, Elasticsearch, OpenSearch; 11 manual web searches (3 throttled and re-phrased) | nothing about this under-count |
Introduced by LUCENE-9514 (8f895d90755, apache/lucene-solr#1847, 2020), which first made the term-vectors writer count its heap; first released in 8.7.0. 8.7.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2, 10.6.0 and main fail; 8.6.3 lacks the method. Not fixed upstream.
Versions tested4 rows
8f895d90755 "LUCENE-9514: Include TermVectorsWriter in DWPT accounting (#1847)" (Simon Willnauer, 2020-09-14; branch_8x 597d8f69522, released in 8.7.0) made TermVectorsWriter Accountable and wrote the int[] length sum. Later commits only reformatted it (2d6ad2fee6d, LUCENE-9570), renamed the class (f8be421ae1f, LUCENE-9705, 9.0.0) and added scratchBuffer.ramBytesUsed() (873ac5f162a, LUCENE-9907). The body is identical at all 34 9.x and 10.x release tags, and the 8.8.0 and 8.8.1 tags contain the branch_8x commit; 8.8.2 through 8.11.3 are inferred, not run. Before 8.7.0 IndexWriter did not count the term-vectors writer at all, so this is not a regression of working code. Upstream main 1c2072f0284, branch_11x and branch_10_6 still sum the lengths (2026-11-03).
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | gradle: fails with assertions on and off (356,924 < 786,432); passes with either fix |
| 10.6.0, 10.5.2, 9.12.3 | affected | fails (writer level: 3,217,630 reported vs at least 12,582,912 buffered) |
| 9.0.0, 8.11.4, 8.7.0 | affected | fails (3,217,630 on 9.0.0; 3,221,802 on 8.x); 8.7.0 is the first release with the method |
| 8.6.3 | no API | the method does not exist and IndexWriter does not count the term-vectors writer at all (an older, different gap) |
An independent reproducer (real, Low), an executed cross-model review in two passes, refute and intended (an independent reviewer from another model family, OpenAI GPT-5.6; real, high), a devil's-advocate verifier (real, high) and an adjudication (confirmed, Low) agree, and separate re-runs reproduced it. This doc's gradle run reproduced it on main and validated both fixes.
Checks and verdicts318 words
Both passes of the cross-model review ran their Java on main ea57360912ed, where the writer and TermVectorsConsumer files are identical to 5adff78bb168's and the IndexingChain and flush-control changes in between do not touch the per-thread RAM accounting.
| Check | Verdict | What it found |
|---|---|---|
| the audit's own repros | reproduced | Writer-level test: ramBytesUsed()=3217630 while three buffered int[] need at least 12,582,912 bytes, on main (assertions on and off) and 10.6.0; the minimal IndexWriter repro: 356,924 < 786,432; both pass with option A. |
| independent reproducer | real, Low | Own writer-level test fails on main, 10.6.0, 10.5.2 and 9.12.3; own IndexWriter test fails on main; 9,649,750 bytes missing at 2^20 positions (writer level); both pass with the fix. |
| cross-model review, refute and intended passes (an independent reviewer from another model family, OpenAI GPT-5.6, executed) | real (high) | Own tests fail with assertions on and off while a no-positions control passes; through IndexWriter.addDocument with 262,144 positions the writer reports 299,052 bytes, below the 1,048,576 its position array alone needs; with the fix TestCompressingTermVectorsFormat passes 22 of 22; intended case rated weak. |
| devil's-advocate verifier | real, high | Rebutted "only an estimate", "the RAM buffer is just an indicator" and the earlier removal of reader-side accounting (LUCENE-9387, a different side); own probe: at 2^18 positions term vectors add 886,828 bytes to IndexWriter.ramBytesUsed() while their three arrays need at least 3,145,728. |
| adjudication and separate re-runs | confirmed, Low | Re-runs fail on main with assertions on and off and pass with the fix; one minimal deterministic test through public API; silent, default settings, but no wrong data, hence Low. |
| this doc's fix check | reproduced; options A and B validated | Gradle in a scratch worktree at 5adff78bb168: the repro fails without and passes with either option; 82 tests in 8 related classes pass with option A; a probe shows the IndexWriter total rising by exactly the uncounted bytes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 461 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,411 words
- Registry title
- Lucene90CompressingTermVectorsWriter.ramBytesUsed() counts its four int[] position and offset buffers at one byte per entry, so IndexWriter under-counts buffered term-vector heap (about 9.6 MB missing for one pending document with 2^20 term-vector positions and offsets)
- Area
- codecs / term vectors (Lucene90 compressing term-vectors writer; IndexWriter per-thread RAM accounting)
- Priority
- Low, rank 996: Every application that stores term vectors with positions or offsets on the default codec has its per-thread RAM under-counted, so flushes come later than ramBufferSizeMB intends, in every release since 8.7.0. The gap stays small unless one chunk buffers a very long document, and no index data or search result is wrong.
- Impact class
- minor
- Impact note
- Any application that stores term vectors with positions or offsets on the default codec (8.7.0 through 10.6.0 and main) has each indexing thread's RAM under-counted by 3 bytes per int of these buffers, so that thread flushes, and reaches its per-thread hard limit, later than configured; the gap is about 12 KB for a fresh writer and grows to megabytes only after one chunk has buffered a very long document (the buffers never shrink until the segment flushes); no index data or search result is wrong.
- Summary
- You index documents with a field that stores term vectors with positions or offsets (default codec and IndexWriterConfig) and expect IndexWriter's RAM accounting, which since 8.7.0 adds the term-vectors writer's ramBytesUsed() so that flush and stall decisions see its heap, to count the writer's buffered positions and offsets in bytes. Instead Lucene90CompressingTermVectorsWriter.ramBytesUsed() adds the lengths of its four int[] buffers (positions, start offsets, lengths, payload lengths) as if each entry took one byte: with one pending document holding one term with 2^20 positions and offsets, the writer reports 3,217,630 bytes while those three int[] alone take at least 12,582,912 bytes (with the one-line fix it reports 12,867,380). Indexed data and search results are unaffected; IndexWriter only flushes later than ramBufferSizeMB and the per-thread hard limit intend.
- Introduced
- 8f895d90755f474dcad1d4e8b1a1b8763536f5f6 on main ('LUCENE-9514: Include TermVectorsWriter in DWPT accounting (#1847)', Simon Willnauer; issue #10553 = LUCENE-9514, PR apache/lucene-solr#1847); the released code came from the same change on branch_8x, 597d8f69522, first in 8.7.0. It made TermVectorsWriter Accountable and added CompressingTermVectorsWriter.ramBytesUsed() as positionsBuf.length + startOffsetsBuf.length + lengthsBuf.length + payloadLengthsBuf.length + byte counts, where the four buffers are int[]; the only later commits on the method are 2d6ad2fee6d (LUCENE-9570, reformatting) and 873ac5f162a (LUCENE-9907, adds scratchBuffer.ramBytesUsed()), and the 9.0 rename to Lucene90CompressingTermVectorsWriter (f8be421ae1f, LUCENE-9705) kept the body [read: git log -L and git blame of main 5adff78bb168; exec: 8.6.3 lacks the method (compile error) and 8.7.0 fails] (2020-09-14 (author and merge date of 8f895d90755 on main; the branch_8x commit 597d8f69522 has the same author date and commit date 2020-09-14); first release 8.7.0)
- First affected version
- 8.7.0 [exec]; 8.6.3 is the last release without it [exec: TermVectorsWriter is not Accountable there (compile error on ramBytesUsed()) and IndexWriter does not count the term-vectors writer at all, an older and different gap: IndexWriter.ramBytesUsed()=74,088 with at least 12.6 MB buffered]
- Affected versions
- 8.7.0 through 8.11.4, every 9.x release (9.0.0-9.12.3), every 10.x release through 10.6.0 (4ae946e5a9b) and main 5adff78bb168. Executed and failing: 8.7.0, 8.11.4 and 9.0.0 (-ea; 8.x writer reports 3,221,802 bytes, 9.0+ 3,217,630), 9.12.3 (-ea, -da), 10.5.2 (-ea, -da), 10.6.0 (-ea, -da) and main (-ea, -da), with the finder's repro, the independent reproduction's test or the history step's version-adapted copy [exec]; the method body is identical (by hash of the normalized body) at all 34 9.x and 10.x release tags, and the 8.8.0 and 8.8.1 tags contain 597d8f69522 [read]; 8.8.2-8.11.3 are not tagged in the history clone and were not run (inferred affected, as 8.7.0, 8.8.1 and 8.11.4 have it). Not affected: 8.6.3 and older (the method does not exist) [exec 8.6.3]. Not fixed upstream: upstream main 1c2072f0284, branch_11x 6c5889ee89f and branch_10_6 5deb5791f6c still sum the lengths (GitHub contents API, 2026-11-03; main re-checked). Not new in 10.6.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (searched 2026-11-03 and rechecked the same day: three scripted prior-report searches with different specs (the finder's; buffer identifiers and fix vocabulary; flush and OutOfMemoryError symptoms) over apache/lucene issues, PRs, comments and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web (51 queries each; 1,059, 1,067 and 1,291 distinct hits, 1 high hit, unrelated, all medium hits read); 30 manual GitHub issue and commit searches across apache/lucene, apache/lucene-solr, Solr, Elasticsearch and OpenSearch, including items created or updated since 2026-10-25; 11 manual mailing-list queries; the changed files of all 410 open apache/lucene PRs (#1003, #16480 and #16269 touch term-vectors files but not ramBytesUsed or the buffer sizing) and the 60 most recently updated closed PRs; the --follow history of the file; 9 web queries; the independent reproduction's, the intended-behaviour check's and the adjudication's searches agree). Nearest items, not reports of this bug: #10553 (LUCENE-9514, the introducing issue, and the review of apache/lucene-solr#1847, neither discusses buffer sizing), #10550 (LUCENE-9511, the stored-fields sibling, which uses Integer.BYTES), #10143 (LUCENE-9101, open, lengthsBuf redundancy, a memory idea that predates the method), #16113 and draft #16114 (open, Accountable ownership semantics), #15982 and #16405 (RAM under-count fixes in other classes). Re-checked 2026-11-03: no new item.
- Lucene commit tested
- main
5adff78bb168(12.0.0-SNAPSHOT): gradle in a scratch worktree for this doc. The one-test repro fails with assertions on and off (356,924 < 786,432) and passes with option A (RamUsageEstimator.sizeOfper buffer) and with option B (length * (long) Integer.BYTES); with option A, 82 tests in 8 term-vector and flush-policy classes pass and the formatter check passes. A supporting probe measuredIndexWriter.ramBytesUsed()stock and with option A (356,924 / 1,023,612 at 2^16 positions; 4,657,724 / 15,277,692 at 2^20). Earlier tests with the same root cause fail on 8.7.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2 and 10.6.0; 8.6.3 lacks the method.
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:993-1003 (at 5adff78bb168) (ramBytesUsed: positionsBuf.length + startOffsetsBuf.length + lengthsBuf.length + payloadLengthsBuf.length + termSuffixes.ramBytesUsed() + payloadBytes.ramBytesUsed() + lastTerm.bytes.length + scratchBuffer.ramBytesUsed()), :225 (the four fields are int[]), :295-298 (new int[1024] each), :194-215 (addPosition grows them per buffered position, start offset, length and payload length), :379-381 (triggerFlush: a chunk is written only at chunkSize bytes of term suffixes or maxDocsPerChunk documents), :736-778 (addProx grows the same buffers)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsWriter.java:726-730 (at 5adff78bb168) (the stored-fields sibling counts its int[] as length * (long) Integer.BYTES)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1792-1797 (at 5adff78bb168) (ramBytesUsed adds termVectorsWriter.accountable.ramBytesUsed()); index/TermVectorsConsumer.java:104-110 (accountable = writer at :108); index/DocumentsWriterPerThread.java:718-723 (adds indexingChain.ramBytesUsed()); index/DocumentsWriterFlushControl.java:244-251 (activeBytes and the per-thread hard limit check at :247)lucene/core/src/java/org/apache/lucene/util/Accountable.java:30-40 (at 5adff78bb168) (@lucene.internal; 'Returns an estimate of the JVM heap memory used by this object in bytes'); index/LiveIndexWriterConfig.java:162-169 ('the writer will flush whenever buffered documents and deletions use this much RAM'; 'this limit is just an indicator when to flush'); codecs/lucene90/Lucene90TermVectorsFormat.java:76-77 (data accumulates in memory until the term and payload buffer grows beyond 4KB); lucene/CHANGES.txt:5627-5629 (LUCENE-9514 entry)a Lucene main checkout: git diff ea57360912ed 5adff78bb168 leaves Lucene90CompressingTermVectorsWriter.java and TermVectorsConsumer.java unchanged; its IndexingChain.java and DocumentsWriterFlushControl.java changes (2813efa40a3 #16867, a9779ef3c19 #16734) do not touch ramBytesUsed or the term-vectors path (2026-11-03)
- The finding in 30 seconds
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:225, :295-298, :194-217, :734-788, :323-329, :379-381, :429-434, :993-1003Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java:170 (chunk size 1 << 12, 128 docs per chunk)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumerPerField.java:119; index/TermVectorsConsumer.java:103-110; index/IndexingChain.java:1792-1797; index/DocumentsWriterPerThread.java:718-723; index/DocumentsWriterFlushControl.java:244-251, :513-516; index/FlushByRamOrCountsPolicy.java:27-29, :45-55, :84; index/DocumentsWriter.java:748-750; index/IndexWriter.java:796-799Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/ArrayUtil.java (oversize: minTargetSize + minTargetSize >> 3, rounded to even for 4-byte elements)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java:83 (DEFAULT_RAM_BUFFER_SIZE_MB = 16.0)
- Who is affected
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumer.java:103-109; index/LiveIndexWriterConfig.java:167-181; index/FlushByRamOrCountsPolicy.java:45-55Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java:71Lucene main 5adff78bb168: lucene/highlighter/src/java/org/apache/lucene/search/vectorhighlight/package-info.java:24, :28Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java:83, :93
- Why it looks unintended
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/Accountable.java:30, :35Lucene main 5adff78bb168: lucene/CHANGES.txt:5627-5629 (8.7.0, LUCENE-9514)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsWriter.java:726-730Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/LiveIndexWriterConfig.java:162-181Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:63 (@lucene.experimental), :993-1003
- Suggested fix
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/index/DocumentsWriterFlushControl.java:215-233; DocumentsWriterPerThread.java:788-790
- Diagrams
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:993-1003
- TestTermVectorsRamBytesUsed.java (one test, public API):
repro/LFV-1232/TestTermVectorsRamBytesUsed.java(46 lines)
One diagram of the repro's path, made separately; its notes are in the diagram directory.
assets/LFV-1232/bug.png(461 KB)