The fast LZ4 compressor keeps a 16 KB table that remembers where it last saw each 4-byte pattern, relative to the start of the current call. To stay fast on many small inputs it does not clear the table between calls; get() should drop leftovers by checking that a candidate lies before the current position and within 64 KB.
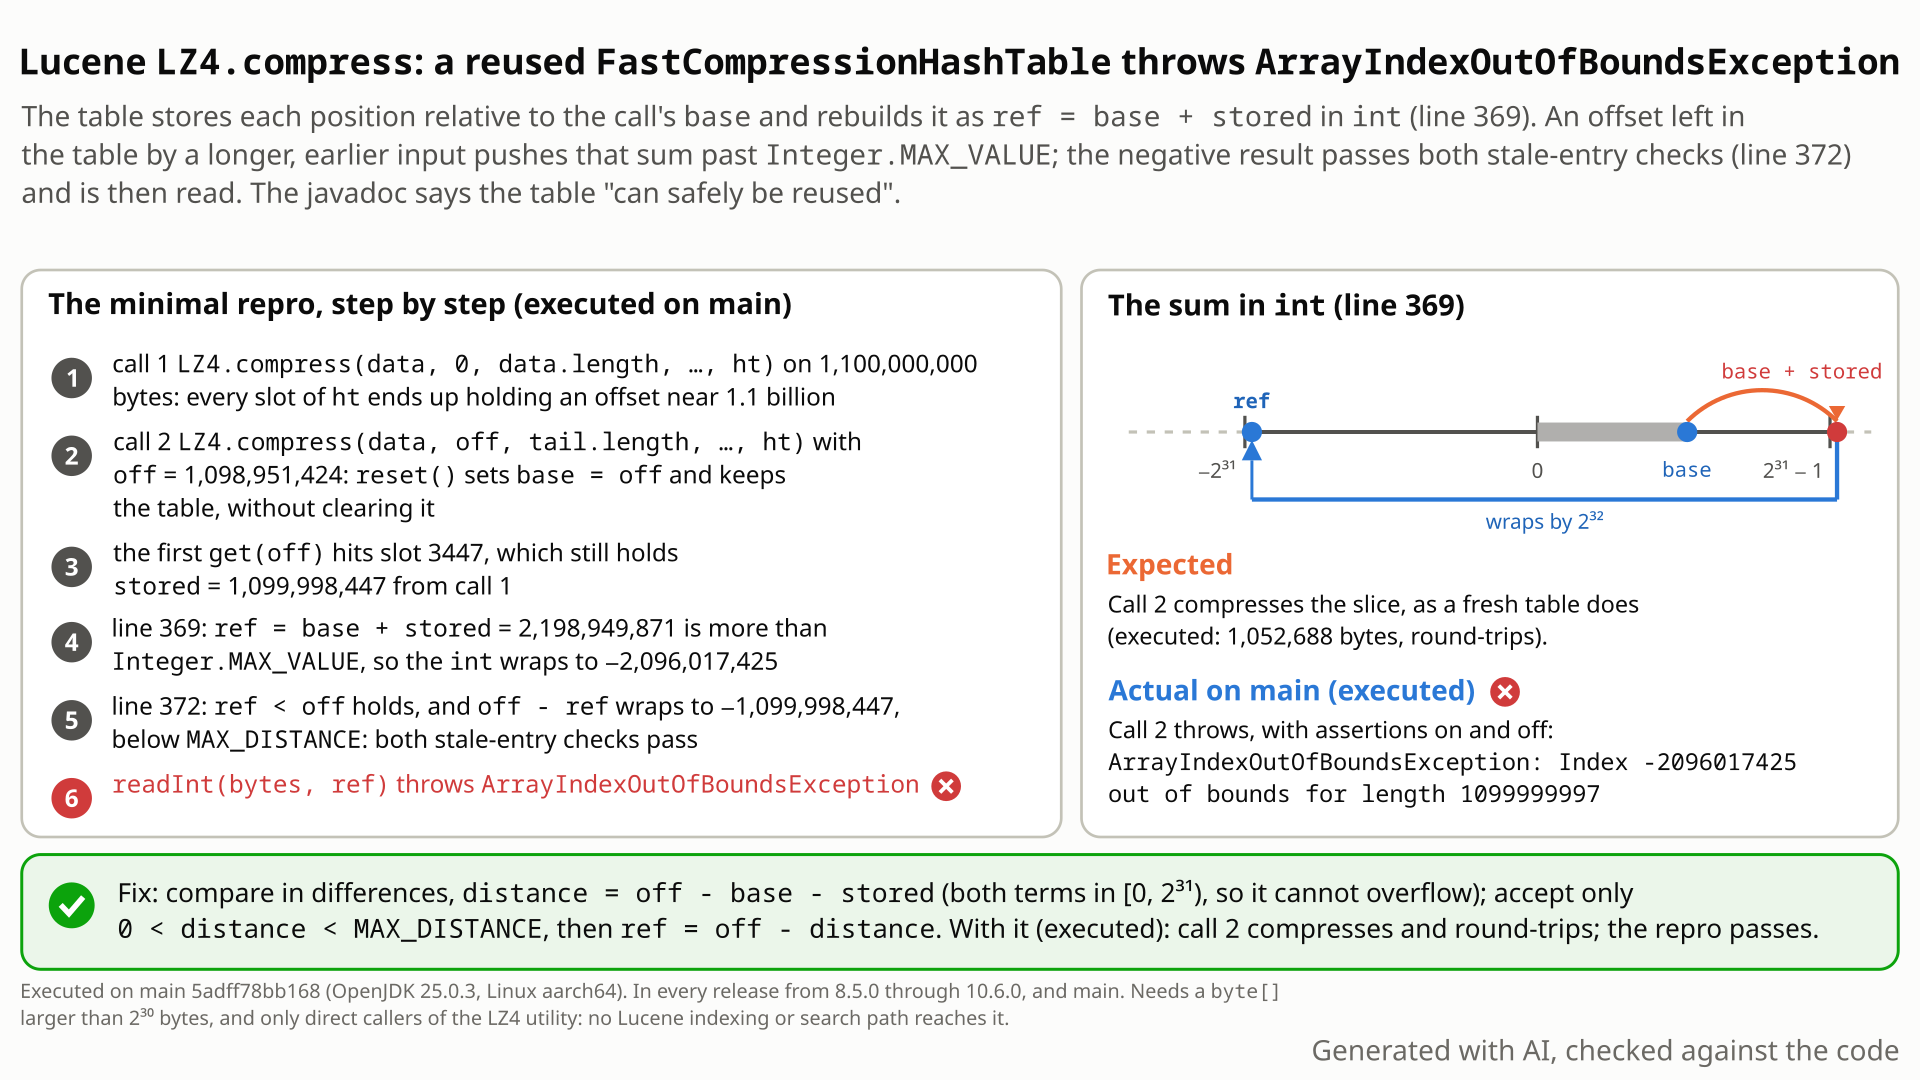
base + stored = 2,198,949,871 passes Integer.MAX_VALUE, wraps to -2,096,017,425, slips past both checks and readInt throws. With the fix, the difference off - base - stored is negative and the leftover is rejected. Select the still to open it at full size. Generated with AI, checked against the code.- Fill a
byte[1_100_000_000]with zeros and put 1,048,576 random bytes at its end, offset 1,098,951,424. With onenew LZ4.FastCompressionHashTable(), compress the whole array from offset 0: that works. - Compress just the last 1 MiB (offset 1,098,951,424) with the same table. You expect it to work: the table "can safely be reused", and with a fresh table this slice compresses to 1,052,688 bytes that decompress back.
- Instead the second call throws
ArrayIndexOutOfBoundsException: Index -2096017425 out of bounds for length 1099999997, with assertions on and off. - Why: the table still holds the first call's positions, such as 1,099,998,447, and
get()adds the new start: 1,098,951,424 + 1,099,998,447 = 2,198,949,871, aboveInteger.MAX_VALUE(2,147,483,647). It wraps to -2,096,017,425, which passes the "earlier position, within 64 KB" checks, and reading there throws.
Only applications that call org.apache.lucene.util.compress.LZ4 directly, reuse one fast table, and start a call at an offset that, plus a position left by an earlier, longer call, exceeds Integer.MAX_VALUE (this needs an array above about 1.07 GB). Lucene's own writers always start at offset 0. The failure is a loud exception; no completed output or index data is wrong.
Mechanism, terms and numbers673 words
LZ4.FastCompressionHashTable remembers, for each hash of 4 bytes, where it last saw them, stored relative to the start (base) of the current call. reset() keeps old entries between calls on purpose and relies on get() to reject stale ones ("get() checks that references are less than the current offset", LZ4.java:344-346 at 5adff78bb168). get() rebuilds a candidate as base + stored in int (:369). After a first call over 1.1e9 bytes, a stored value is about 1.1e9; when the next call on the same table starts at 1,098,951,424, the sum passes Integer.MAX_VALUE and wraps negative, the negative position passes both checks at :372, and readInt throws ArrayIndexOutOfBoundsException. compress and compressWithDictionary both say the table "can safely be reused" (:513-515, :527), and a fresh table compresses the same slice. In general it needs direct calls to the utility where a call's start plus a position left by an earlier, longer call passes Integer.MAX_VALUE, which takes an array above about 1.07 GB; the slice itself may start much lower or lie in a separate, smaller array. Lucene's own writers compress from offset 0, and the failure is always a loud exception, never a completed wrong output. In every release from 8.5.0 to 10.6.0 and on main.
- Stored relative to the call's start.
get(off)hashes the 4 bytes atoff, storesoff - basein that slot and gets back the slot's previous value:final int ref = base + hashTable.getAndSet(h, off - base);(LZ4.java:369at5adff78bb168). - Old entries are kept on purpose.
reset()(:320-349) builds a new table only when the old one is too small or too narrow (:333-335); otherwise: "Avoid calling hashTable.clear(), this makes it costly to compress many short sequences otherwise. Instead, get() checks that references are less than the current offset." (:344-346). A call of at least 65,541 bytes uses a 32-bit table (:326-330), so the second call (2^20 bytes) keeps the 32-bit table the first call filled. - The check.
if (ref < off && off - ref < MAX_DISTANCE && readInt(bytes, ref) == v)(:372), withMAX_DISTANCE= 65,536 (:54). - The numbers. The first call has base 0, so the table holds absolute positions, here 1,099,998,447 (inside the random tail). The second call has base 1,098,951,424:
ref= 1,098,951,424 + 1,099,998,447 = 2,198,949,871 > 2,147,483,647, which wraps to 2,198,949,871 - 2^32 = -2,096,017,425, the index in the exception. Without the overflow,refwould lie pastoffandref < offwould reject it. - Why both checks pass. A wrapped
refis negative, soref < offholds;off - refwraps too and equals(off - base) - stored, a negative number, so it is< MAX_DISTANCE.readInt(:70-73) reads throughBitUtil.VH_NATIVE_INT, a bounds-checked byte-array view (BitUtil.java:109), so it throws before reading anything. The reported length 1,099,999,997 is the array length minus 3, the view's bound for a 4-byte read.
base is below the length of the current call's array and stored below the length of the earlier call, so base + stored > 2^31 - 1 needs at least one array of more than 2^30 bytes (about 1.07 GB). The slice itself can start much lower, or lie in a separate, smaller array: after compressing a whole byte[2_000_000_000] with the table, a 1 MiB slice at offset 150,000,000 of the same array, or of a separate 200,000,000-byte array, throws Index -2144975224 (the first case passes with the fix). For compressWithDictionary the call's start is dictOff (:548). Both terms are in [0, 2^31), so a wrapped sum is always negative and readInt always throws: the failure is loud, never a wrong match. The 16-bit table (calls shorter than 65,541 bytes) has the same sum: two short slices of a 2,147,483,631-byte array (60,000 bytes at offset 0, then 1,000 bytes at its end) throw Index -2147442954.
Exposure and likelihood245 words
- Who is exposed. The package is exported (
module-info.java:47) and itspackage-info.javasays only "Compression utilities.", with no@lucene.internal. Code that reuses oneFastCompressionHashTablecan hit it when a call's start plus a position left by an earlier, longer call passesInteger.MAX_VALUE. That needs some array above about 1.07 GB, but the slice can start well below 1 GB (150,000,000 after a 2,000,000,000-byte call) or lie in a separate, smaller array. - Not reached by Lucene. Every production caller found compresses from offset 0, so
baseis 0 andref = storedcannot overflow:CompressionMode.java:163(fast table) and:185(high-compression table),LZ4WithPresetDictCompressionMode.java:167,Lucene90DocValuesConsumer.java:849,Lucene103BlockTreeTermsWriter.java:902-903(high-compression table), and backward-codecs'Lucene80DocValuesConsumer.java:479-480and:851-852. backward-codecs' legacyCompressionMode(:159) forwards its caller's offset, but only a test calls it. Tests use small non-zero offsets on small arrays. - The other table is fine.
HighCompressionHashTablestores absolute positions and passes the same scenario (an executed cross-model control). - Effect. Deterministic for a given input; the call throws, nothing outside the array is read or written, and no index data is involved. Output already written to the
DataOutputbefore the exception is incomplete and must be discarded. Workaround: a fresh table after compressing an array above 1 GB. - Likelihood. Contrived: a reused table, an array above 1 GB and a later call whose start plus a leftover position passes
Integer.MAX_VALUE; no report was found in the recorded searches since the API appeared in 8.5.0 (2020).
One JUnit test method on the public API: compress a 1.1 GB array, then its last 1 MiB with the same table. Deterministic (Random(0) data), single-threaded, under a second of test time; it was run with a 2 GB test heap (the default 512 MB runs out of memory) and fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.util.compress;

import java.util.Random;
import org.apache.lucene.store.ByteBuffersDataOutput;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestLZ4ReusedTableLargeOffset extends LuceneTestCase {

  public void testReuseAfterLongInput() throws Exception {
    byte[] data = new byte[1_100_000_000];
    byte[] tail = new byte[1 << 20];
    new Random(0).nextBytes(tail);
    int off = data.length - tail.length;
    System.arraycopy(tail, 0, data, off, tail.length);
    LZ4.FastCompressionHashTable ht = new LZ4.FastCompressionHashTable();
    LZ4.compress(data, 0, data.length, new ByteBuffersDataOutput(), ht);
    // expected: the reused table compresses the slice; actual: ArrayIndexOutOfBoundsException
    LZ4.compress(data, off, tail.length, new ByteBuffersDataOutput(), ht);
  }
}
cp $REPRO/TestLZ4ReusedTableLargeOffset.java $LUCENE/lucene/core/src/test/org/apache/lucene/util/compress/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.util.compress.TestLZ4ReusedTableLargeOffset -Ptests.heapsize=2g -Ptests.seed=DEADBEEF -Ptests.asserts=true
# and with -Ptests.asserts=false (assertions off)
- Expected
- The second
compresscall returns normally, as with a fresh table (1,052,688 compressed bytes that decompress back to the slice). - Observed
ArrayIndexOutOfBoundsException: Index -2096017425 out of bounds for length 1099999997atLZ4.java:372, with assertions on and off.
More files, environment, full output224 words
A larger heap is needed: the default test heap is 512m and the test allocates 1.1 GB, so it fails with OutOfMemoryError; -Ptests.heapsize=2g works. Pass -Ptests.asserts explicitly: otherwise Lucene's build picks assertions on or off from the seed.
As an in-tree regression test, the same method would normally carry @Monster, as Lucene's other multi-GB tests do (for example Test2BPoints), so it runs only with -Ptests.monster=true; that is the maintainers' call.
The exact index depends on the seed, because tests randomize the byte order of BitUtil.VH_NATIVE_INT (BitUtil.java:105-106): seed DEADBEEF gives the index shown, seed CAFEBABE (big-endian) gives Index -2096016670.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): this test fails; earlier variants with the same sizes, offset and calls but a different random tail (`Random(42)`) also fail on 10.6.0, 9.12.3, 9.0.0, 8.11.4 and 8.5.0, and an independent reproducer's test on 10.5.2 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 (nothing platform-specific) |
TestLZ4ReusedTableLargeOffset > testReuseAfterLongInput FAILED
    java.lang.ArrayIndexOutOfBoundsException: Index -2096017425 out of bounds for length 1099999997
        at java.base/java.lang.invoke.VarHandleByteArrayAsInts$ArrayHandle.get(VarHandleByteArrayAsInts.java:110)
        at org.apache.lucene.util.compress.LZ4.readInt(LZ4.java:72)
        at org.apache.lucene.util.compress.LZ4$FastCompressionHashTable.get(LZ4.java:372)
        at org.apache.lucene.util.compress.LZ4.compressWithDictionary(LZ4.java:559)
        at org.apache.lucene.util.compress.LZ4.compress(LZ4.java:519)
        at org.apache.lucene.util.compress.TestLZ4ReusedTableLargeOffset.testReuseAfterLongInput(TestLZ4ReusedTableLargeOffset.java:34)

# main 5adff78bb168, gradle, seed DEADBEEF, -Ptests.heapsize=2g: the same failure with -Ptests.asserts=true and =false (the seed frame and JDK precondition frames omitted; line 34 is the second compress call)
# with the fix (compare in differences): BUILD SUCCESSFUL, the test passes, assertions on and offcompressandcompressWithDictionaryboth say the table "can safely be reused", with no offset or size limit.reset()keeps old entries because "get() checks that references are less than the current offset"; the overflow defeats that check.- A fresh table compresses the same slice; before 8.5.0 each call got a new or cleared table.
The full argument194 words
- Contract.
compress: "{@code ht} shouldn't be shared across threads but can safely be reused." (LZ4.java:513-515);compressWithDictionarysays the same (:527). The arguments passObjects.checkFromIndexSize(:321,:532-533). - Design intent. The
reset()comment (:344-346) states the invariant: stale entries stay becauseget()rejects them byref < off. The wrap makes a stale entry pass. - History. Before LUCENE-4702 the package-private predecessor's
reseteither allocated a new table or cleared the old one (hashTable.clear()) on every call (codecs/compressing/LZ4.java:185-192atb283b8df628^); LUCENE-4702 made the class public and droppedclear()as a speed-up for many short inputs. Its review never discusses large offsets. 8.4.1's predecessor passes the same sizes, offset and calls (with aRandom(42)tail). - Tests.
LZ4TestCasetests reuse ("Compress once again with the same hash table to test reuse",:139,:194) on small arrays only; no test, CHANGES or MIGRATE entry mentions a size or offset limit. - Reference implementation. Among its reset conditions, the reference LZ4 C library's
LZ4_prepareTable(lib/lz4.c:937-976at lz4/lz4943cc479c35b) clears a reused 32-bit table once its running offset passes 1 GB (:945-956).
The devil's-advocate check148 words
Strongest case for "intended": LZ4 is a low-level helper written for Lucene's codecs, which always compress from offset 0; reusing one table at non-zero offsets after an array above 1 GB is outside what it was built for, and the failure is loud. The parent package's package-info.java adds that its classes "are generally not intended for direct use by most applications" and that "APIs in this package are primarily internal and may change between releases" (org/apache/lucene/util/package-info.java:22-23, :35). Why it fails: that note is about API stability, not correctness; the compress subpackage is exported with its own unconditional reuse promise, the arguments are legal, a fresh table compresses the same slice, and reset()'s comment shows that get() was meant to reject stale entries. A size limit, if intended, would be documented or checked. The argument is about severity, which is why the priority is Low.
Recommended A. Compare in differences in get() (validated)
In FastCompressionHashTable.get, compare in differences: distance = off - base - stored cannot overflow; accept only 0 < distance < MAX_DISTANCE, then ref = off - distance. The repro passes and all 31 org.apache.lucene.util.compress tests pass, assertions on and off. Alternative: clear the table in reset() for large inputs, as the reference LZ4 C library does.
final int stored = hashTable.getAndSet(h, off - base);
lastOff = off;
// off - base and stored are both in [0, 2^31): this difference cannot overflow
final int distance = off - base - stored;
if (distance > 0 && distance < MAX_DISTANCE) {
  final int ref = off - distance;
  if (readInt(bytes, ref) == v) {
    return ref;
  }
}
return -1;
All options and trade-offs2 options · 433 words
Option A was applied in a scratch worktree at 5adff78bb168 and checked with gradle; option B was not built.
Replace LZ4.java:369-376 so that the stale-entry test works on distance = off - base - stored. Both terms are in [0, 2^31), so the difference cannot wrap; distance > 0 is ref < off and distance < MAX_DISTANCE is the window check. A stale entry gives distance <= 0 and is rejected.
final int stored = hashTable.getAndSet(h, off - base);
lastOff = off;
// off - base and stored are both in [0, 2^31): this difference cannot overflow
final int distance = off - base - stored;
if (distance > 0 && distance < MAX_DISTANCE) {
  final int ref = off - distance;
  if (readInt(bytes, ref) == v) {
    return ref;
  }
}
return -1;
Trade-offs
About as many integer operations on the hot path as before (off - base - stored and two compares, plus off - distance only for an accepted candidate; not benchmarked); keeps the no-clear speed-up for short inputs; covers both table widths, including the 16-bit case (two short slices of a 2,147,483,631-byte array also pass with it).
What the checks validated
- The repro fails without the fix and passes with it, with assertions on and off (gradle, seed
DEADBEEF, 2 GB test heap). - With the fix,
org.apache.lucene.util.compress.*passes: 5 classes, 31 tests, 0 failures (TestFastLZ49,TestHighLZ49,TestDecompressLZ43,TestLowercaseAsciiCompression9 and the repro), with assertions on and, in a separate run, off. :lucene:core:checkGoogleJavaFormatpasses with the fix and the test file.- The 16-bit-table check passes with the fix, with
-eaand-da.
Clear the kept table in reset() (:343-347) when it serves a call of 64 KB or more, as the reference LZ4 C library clears a reused 32-bit table once its offset passes 1 GB. LZ4.Table has no clear method today: it declares only set, getAndSet, getBitsPerValue and size (:224-233), and the hashTable.clear() named in reset()'s comment is left over from the older packed-ints table. So this needs a new Table method (for example an Arrays.fill of the backing array) or a fresh table.
Trade-offs
A 16 KB clear per call is small next to compressing 64 KB or more. But clearing only the 32-bit table leaves the 16-bit case in place, and clearing on every call gives up the speed-up for many short inputs that LUCENE-4702 introduced. Not built or tested.
Downstream code that calls LZ4.compress directly and reuses one table after compressing an array above 1 GB can hit this; a fresh table after such an array avoids it.
A proof-obligation audit of LZ4.FastCompressionHashTable's contract: the "can safely be reused" promise and reset()'s stale-entry comment were checked against get()'s int arithmetic, which showed that base + stored can wrap for a reused table. A one-method JUnit test on the public API then witnessed it.
The method in full102 words
The obligation: for every legal call sequence on one table, get() must return either -1 or an earlier position within 64 KB. reset() keeps entries from earlier calls, so stored is bounded only by the earlier call's length, and base + stored is bounded by the sum of the two calls' array lengths, which can exceed Integer.MAX_VALUE once an array holds more than 2^30 bytes. The witness test (an earlier variant of the repro above, with the same sizes, offset and calls and a different random tail) fails on main with assertions on and off and on the 10.6.0 and 9.12.3 jars.
No prior report found in apache/lucene or apache/lucene-solr issues, PRs and commits (incl. the JIRA archive), the mailing lists, downstream trackers or the web (searched 2026-11-03; GitHub re-checked the same day). Nearest: #5773 (LUCENE-4708, made the tables reusable) and #5767 (LUCENE-4702, the introducing change).
Searches5 searches
Nearest items, none of them this bug: #5773 (LUCENE-4708, 2013: made the tables reusable while reset() still cleared them), #5767 / lucene-solr#1126 (LUCENE-4702: the introducing change; its review never mentions offsets, overflow or stale entries), #16478 (merged 2026-09-29), #6331 (LUCENE-5267) and the LUCENE-4929 threads (decompress side), #14347 (an open preset-dictionary proposal with no code on get()). The open PRs #16746 and #16836, the only LZ4 PRs updated since 2026-11-01, change decompression only.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive, apache/lucene-solr) | 2026-11-03; re-checked the same day | two scripted prior-report searches (51 and 71 queries, e.g. FastCompressionHashTable, Table32, getAndSet, initDictionary, 'int overflow', MAX_DISTANCE, LUCENE-4702) and 18 manual searches ('can safely be reused', LZ4 overflow, LZ4 reused table, LZ4 ArrayIndexOutOfBoundsException) | no report; #5773, #5767, #16478, #14347, #6331 are history or other code |
| open apache/lucene PRs | 2026-11-03 | file-list scan of the 29 open PRs updated since 2026-11-01 | #16746 and #16836 touch LZ4.java, decompression only |
| downstream (Elasticsearch, OpenSearch, Solr, all of GitHub) | 2026-11-03 | the class name and LZ4 overflow terms | code that uses the class, no defect reported |
| mailing lists (dev@, java-user@, issues@, commits@) and the web | 2026-11-03 | the scripted searches' list and web queries plus 6 manual web searches, including the exact reset() comment | nothing on this overflow |
| discussions read in full | 2026-11-03 | LUCENE-4702, LUCENE-7538, LUCENE-10112, LUCENE-10170; review threads of lucene-solr #1126, #1234, #2213 | no discussion of large offsets or overflow |
Introduced by LUCENE-4702 (b283b8df628, 2020), which made the class public and stopped clearing the table; first released in 8.5.0. 8.5.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2, 10.6.0 and main fail; 8.4.1's predecessor passes; not fixed upstream.
Versions tested6 rows
b283b8df628 "LUCENE-4702: Terms dictionary compression. (#1126)" (Adrien Grand, GitHub jpountz, 2020-01-24; branch_8x cherry-pick 33a7af9cbfb) created the public org.apache.lucene.util.compress.LZ4 with FastCompressionHashTable and, in the same change, replaced reset()'s hashTable.clear() with the stale-entry check, keeping the int sum base + stored. LUCENE-9486 (#1793, 8.7.0) moved the first get() out of reset(); LUCENE-10170 (#377, c36ce300ae2, 2021-10-14, 9.0.0) rewrote the line for Table16/Table32 without changing the arithmetic. A source scan of the release tags 8.5.0 to 8.8.1, 9.0.0 to 9.12.3 and 10.0.0 to 10.6.0 finds the sum, the guard and the keep-the-table comment in each; 8.9.0 to 8.11.3 are counted by inference. The version runs used earlier variants of the repro (same sizes, offset and calls, but a Random(42) tail, so they report Index -2096021376, or -2096018720 on 8.x; they also check the round-trip; only LuceneTestCase's package and 8.5/8.6's decompress signature were adapted).
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | gradle: fails with assertions on and off at :372; passes with the fix |
| 10.6.0, 10.5.2 | affected | fails (10.6.0 at get(:372)) |
| 9.12.3, 9.0.0 | affected | fails at get(:365) / get(:362) |
| 8.11.4, 8.5.0 | affected | fails at get(:271) / get(:259) (in 8.5.0 from reset) |
| 8.4.1 | no public API | no org.apache.lucene.util.compress.LZ4; the package-private predecessor, which cleared the table on every reset, passes the same sizes, offset and calls |
| upstream main (2026-11-03) | not fixed | get() unchanged; newest commit on LZ4.java (#16478) and open PRs #16746, #16836 are decompress-side |
An independent reproducer, two executed cross-model reviews (OpenAI GPT-5.6, real, high), a devil's-advocate verifier and an adjudication agree, and separate re-runs reproduced it. This doc's gradle runs reproduced it on main and validated the fix.
Checks and verdicts217 words
The cross-model reviews ran their Java on main ea57360912ed, whose util/compress sources and BitUtil.java are identical to 5adff78bb168's; one reviewer's tests were re-run on 5adff78bb168.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Own test (byte[1_080_000_000], a 2^17-byte random tail, slice at 1,079,868,928) fails on main, 10.6.0, 10.5.2, 9.12.3 and 8.5.0; a fresh-table control round-trips; passes with the fix. |
| cross-model reviews, refute and intended lenses (OpenAI GPT-5.6, executed) | real (high) | Own tests fail; fresh-table and HighCompressionHashTable controls pass; the fix passes their tests and TestFastLZ4. Intended-behaviour argument weak: "The optimization is intended; the overflow crash is not." |
| devil's-advocate verifier | real | Reproduced on main with assertions on and off; the reuse promise is unconditional and no limit is documented; only a severity argument remains. |
| adjudication and separate re-runs | confirmed, Low | Re-runs with a new seed fail at the same frames; the one-test minimal repro fails on main with assertions on and off and passes with the fix. |
| this doc's fix check | reproduced; option A validated | Gradle in a scratch worktree at 5adff78bb168: the repro fails without and passes with option A; all 31 org.apache.lucene.util.compress tests pass; a fresh-table control round-trips; the 16-bit case fails without and passes with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 474 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,610 words
- Registry title
- LZ4.compress throws ArrayIndexOutOfBoundsException when a reused LZ4.FastCompressionHashTable (documented as safe to reuse) compresses a slice whose start offset plus an offset left in the table by a longer earlier input exceeds Integer.MAX_VALUE (for example the last 2^20 bytes at offset 1,098,951,424 after a 1.1e9-byte input), because FastCompressionHashTable.get rebuilds the match position as base + stored in int and the wrapped negative position passes both of its stale-entry checks (since 8.5.0)
- Area
- util / compress (LZ4 fast compression hash table: LZ4.compress, LZ4.compressWithDictionary)
- Priority
- Low, rank 993: A reused LZ4.FastCompressionHashTable throws ArrayIndexOutOfBoundsException when a slice offset plus an offset left by an earlier, longer input exceeds Integer.MAX_VALUE, in every release since 8.5.0. It needs direct use of the LZ4 utility on byte arrays above about 1 GB, which no Lucene path produces, and it fails loudly, so it is contrived.
- Impact class
- minor
- Impact note
- Only applications that call the public org.apache.lucene.util.compress.LZ4 utility directly are hit, when they reuse one FastCompressionHashTable (as both compress methods' javadoc allows) first on a long input and then on a slice whose start offset plus an offset left in the table by that earlier call exceeds Integer.MAX_VALUE, which needs a byte[] of more than about 1.07 GB (executed: a 1.1e9-byte input from offset 0, then its last 2^20 bytes at offset 1,098,951,424): the second call throws ArrayIndexOutOfBoundsException with -ea and -da instead of compressing a slice that a fresh table compresses and round-trips; no Lucene indexing, merge or search path reaches it, because every in-tree LZ4 compress caller starts at offset 0, and the failure is always loud, with no wrong output and no index data touched; in every release from 8.5.0 to 10.6.0 and on main.
- Summary
- You compress a byte array of 1.1e9 bytes with LZ4.compress, reusing one LZ4.FastCompressionHashTable as the javadoc allows ('can safely be reused'): first the whole array from offset 0, then its last 2^20 bytes (offset 1,098,951,424). You expect the second call to compress the slice, as it does with a fresh table. Instead it throws ArrayIndexOutOfBoundsException ('Index -2096021376 out of bounds for length 1099999997'), because FastCompressionHashTable.get rebuilds a candidate match position as base + stored offset in int, an offset left in the table by the longer first call pushes that sum past Integer.MAX_VALUE, and the wrapped negative position passes get()'s 'is this an earlier position within reach' checks and is then read.
- Introduced
- b283b8df628dc9bbdbbb994b4a3653b7eecd7fd9 (main line; LUCENE-4702 'Terms dictionary compression', apache/lucene-solr PR #1126, migrated issue apache/lucene#5767, by Adrien Grand (jpountz), merged 2020-01-24), cherry-picked to branch_8x as 33a7af9cbfb9f668b4aee433906ee93d55e1e709: it created the public org.apache.lucene.util.compress.LZ4 with FastCompressionHashTable and replaced reset()'s hashTable.clear() with keeping the old entries and rejecting stale ones in get() by 'ref < off'; the int sum base + stored and that guard are in the first public version [read: git log --follow, git blame and git show b283b8df628^ in the history clone; exec: 8.4.1's package-private predecessor, which cleared the table on every reset, passes the same input and calls, and 8.5.0 fails]. LUCENE-10170 (#377, c36ce300ae2, 2021-10-14) later rewrote the line as base + hashTable.getAndSet(h, off - base) without changing the arithmetic; git blame in the history clone (whose LZ4.java is byte-identical to 5adff78bb168's) attributes LZ4.java:369 to that rewrite and the guard at :372 to b283b8df628. (2020-01-24 (author date of b283b8df628 on the main line and of its branch_8x cherry-pick 33a7af9cbfb, committed 2020-01-27))
- First affected version
- 8.5.0 [exec: the public-API variant of the repro fails with -da, ArrayIndexOutOfBoundsException at FastCompressionHashTable.get <- reset <- LZ4.compress on the second call; 8.5.0 tagged 2020-03-18]. 8.4.1 has no public org.apache.lucene.util.compress.LZ4 (compile error), and the same input and calls on its package-private predecessor, whose reset() cleared the table, pass [exec]
- Affected versions
- Every release from 8.5.0: 8.5.0 to 8.11.4, every 9.x (9.0.0 to 9.12.3), every 10.x (10.0.0 to 10.6.0, released 2026-10-29, 4ae946e5a9b), and main 5adff78bb168 (12.0.0-SNAPSHOT) [read: git tag --contains on the introducing commits, and a source scan of every release tag in the history clone finds the int sum, the guard and the keep-the-table comment in each; 8.9.0 to 8.11.3 by inference, untagged in the history clone]. [exec] fail: main 5adff78bb168 with -ea and -da (finder, the independent reproduction, a re-run of the GPT intended-lens reviewer's test, the intended-behaviour check, adjudication, re-run), 10.6.0 (-da: finder, the independent reproduction), 10.5.2 (-ea and -da: the independent reproduction), 9.12.3 (-da: finder, the independent reproduction), 9.0.0, 8.11.4 and 8.5.0 (-da: history runs; the independent reproduction also 8.5.0); the GPT refute-lens reviewer's own repro also fails on main ea57360912ed, whose util/compress sources are identical to 5adff78bb168. Not affected: 8.4.1 and earlier (no public API; the package-private predecessor passes [exec]). Not new in 10.6 (10.5.2, 9.12.3 and 8.5.0 fail). Not fixed upstream: get() is unchanged on upstream main (newest commit on LZ4.java is 2a38fffef52, #16478, author date 2026-09-29, decompress side), and the only LZ4 PRs updated since 2026-11-01, #16746 and #16836, change decompression only. All runs used JDK 25.0.3 on Linux aarch64.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: proof-obligation audit
- Upstream and prior reports
- none found (2026-11-03, on top of the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches; rechecked the same day): two scripted prior-report searches (run A, 51 queries: 16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA-archive and 6 web; run B, 71 queries with new terms such as Table32, getAndSet, initDictionary, 'int overflow', MAX_DISTANCE and LUCENE-4702), 18 manual GitHub searches (FastCompressionHashTable in apache/lucene, apache/lucene-solr, Elasticsearch, OpenSearch, Solr and all of GitHub; 'can safely be reused'; LZ4 overflow; LZ4 reused table), a file-list scan of the 29 open apache/lucene PRs updated since 2026-11-01, the commit history of LZ4.java on main, branch_10x, branch_10_6 and branch_9x (author and committer dates), full reads of LUCENE-4702, LUCENE-7538, LUCENE-10112 and LUCENE-10170 and of the review threads of lucene-solr PRs #1126, #1234 and #2213, and 6 manual web searches: no issue, PR, commit, JIRA entry, list thread or downstream report describes the int sum base + stored in FastCompressionHashTable.get overflowing for a reused table, or any offset or size limit on table reuse. Nearest items, not this bug: #5773 (LUCENE-4708, 2013, made the tables reusable while reset() still cleared them), #5767 / lucene-solr#1126 (LUCENE-4702, the introducing change; its review never mentions offsets, overflow or stale entries), #16478 (merged 2026-09-29, a decompress-side match-offset check, the newest commit on LZ4.java), #14347 (open, a preset-dictionary proposal with no code on get()), #6331 (LUCENE-5267) and the 2013 LUCENE-4929 threads (decompress-side exceptions). Not fixed upstream: open PRs #16746 and #16836, the only LZ4 PRs updated since 2026-11-01, change decompression only and leave FastCompressionHashTable.get and reset unchanged; get()'s arithmetic is unchanged since c36ce300ae2 (LUCENE-10170, 2021-10-14).
- Lucene commit tested
- main
5adff78bb168(12.0.0-SNAPSHOT): gradle in a scratch worktree for this doc (the repro fails with assertions on and off, 2 GB test heap; with the difference-based fix it passes and all 31 tests oforg.apache.lucene.util.compresspass, assertions on and off; the formatter check passes); a fresh-table control and a 16-bit-table check as plainmain()runs. Earlier variants of the test (same sizes, offset and calls, with a different random tail,Random(42)) fail on the 8.5.0, 8.11.4, 9.0.0, 9.12.3 and 10.6.0 jars; an independent reproducer's test fails on 10.5.2 too; 8.4.1's package-private predecessor passes.
- Finding record
lucene/core/src/java/org/apache/lucene/util/compress/LZ4.java:70-73 (at 5adff78bb168) (readInt through BitUtil.VH_NATIVE_INT, a bounds-checked byte-array view: a negative index throws), :307-317 (public static final class FastCompressionHashTable, public sole constructor), :320-349 (reset: Objects.checkFromIndexSize; keeps a table that is big and wide enough; :344-346 'Avoid calling hashTable.clear() ... Instead, get() checks that references are less than the current offset'), :362-377 (get: :369 final int ref = base + hashTable.getAndSet(h, off - base), fix site; :372 ref < off && off - ref < MAX_DISTANCE && readInt(bytes, ref) == v), :513-519 (compress javadoc 'ht shouldn't be shared across threads but can safely be reused'; delegates to compressWithDictionary), :522-533 (compressWithDictionary javadoc, the same promise; Objects.checkFromIndexSize on both ranges), :559 (ht.get(off) in the match loop)lucene/core/src/java/module-info.java:47 (at 5adff78bb168) (exports org.apache.lucene.util.compress) and lucene/core/src/java/org/apache/lucene/util/compress/package-info.java ('Compression utilities.', no @lucene.internal)Lucene main 5adff78bb168 in-tree callers, all from offset 0: lucene/core/src/java/org/apache/lucene/codecs/compressing/CompressionMode.java:155/:163 (fast table) and :177/:185 (high-compression table); lucene/core/src/java/org/apache/lucene/codecs/lucene90/LZ4WithPresetDictCompressionMode.java:161/:167; lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:780/:849; lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java:899-903 (high-compression table); lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/compressing/CompressionMode.java:154/:159 passes its caller's off (only a test calls it)
- The finding in 30 seconds
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/compress/LZ4.java:54, :70-73, :307-349 (reset; :326-335 table choice, :344-346 comment), :362-377 (get; :369 the sum, :372 the check)Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/BitUtil.java:109 (VH_NATIVE_INT, a byteArrayViewVarHandle)
- Who is affected
Lucene main 5adff78bb168: lucene/core/src/java/module-info.java:47; lucene/core/src/java/org/apache/lucene/util/compress/package-info.javaLucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/compressing/CompressionMode.java:163, :185; lucene/core/src/java/org/apache/lucene/codecs/lucene90/LZ4WithPresetDictCompressionMode.java:167; lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:849; lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java:902-903; lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/compressing/CompressionMode.java:159; lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene80/Lucene80DocValuesConsumer.java:479-480, :851-852; lucene/core/src/test/org/apache/lucene/util/compress/LZ4TestCase.java:69-82
- Minimal repro
Lucene main 5adff78bb168: build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/TestsAndRandomizationPlugin.java:132 (tests.heapsize default 512m), :286 (tests.monster); lucene/core/src/test/org/apache/lucene/index/Test2BPoints.java:40 (@Monster)
- Why it looks unintended
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/compress/LZ4.java:321, :344-346, :513-515, :527, :532-533Lucene main 5adff78bb168: lucene/core/src/test/org/apache/lucene/util/compress/LZ4TestCase.java:139, :194lz4/lz4 943cc479c35b lib/lz4.c:937-976 (LZ4_prepareTable; :945-956 the reset conditions), read 2026-11-03Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/package-info.java:22-23, :35 (parent package note)
- Suggested fix
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/compress/LZ4.java:224-233, :343-347, :366-377lz4/lz4 943cc479c35b lib/lz4.c:945-956 (LZ4_prepareTable clears a reused byU32 table when currentOffset > 1 GB)
- Diagrams
Lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/compress/LZ4.java:369, :372
- TestLZ4ReusedTableLargeOffset.java (one test, public API):
repro/LFV-1235/TestLZ4ReusedTableLargeOffset.java(36 lines)
One diagram of the repro's two calls, made separately; its notes are in the diagram directory.
assets/LFV-1235/bug.png(474 KB)