The writer keeps one in-memory list of field names and their schemas. addIndexes(Directory...) adds each incoming field to that list before it copies the field's segment; when the call fails later, it deletes the copied files but never takes the fields back off the list.
- Every field name in an index has one schema: indexed or not (index options), doc values type, points, vectors. The first document indexed with a name fixes it; a later document that gives the name another schema is rejected with
IllegalArgumentException. IndexWriterchecks that against an in-memory registry of all names it knows, built from the segments when the writer opens.getFieldNames()returns the registry's names.addIndexes(Directory...)copies whole segments of other indexes into this one. Its javadoc promises that if an exception occurs, "either no indexes will have been added or they all will have been".
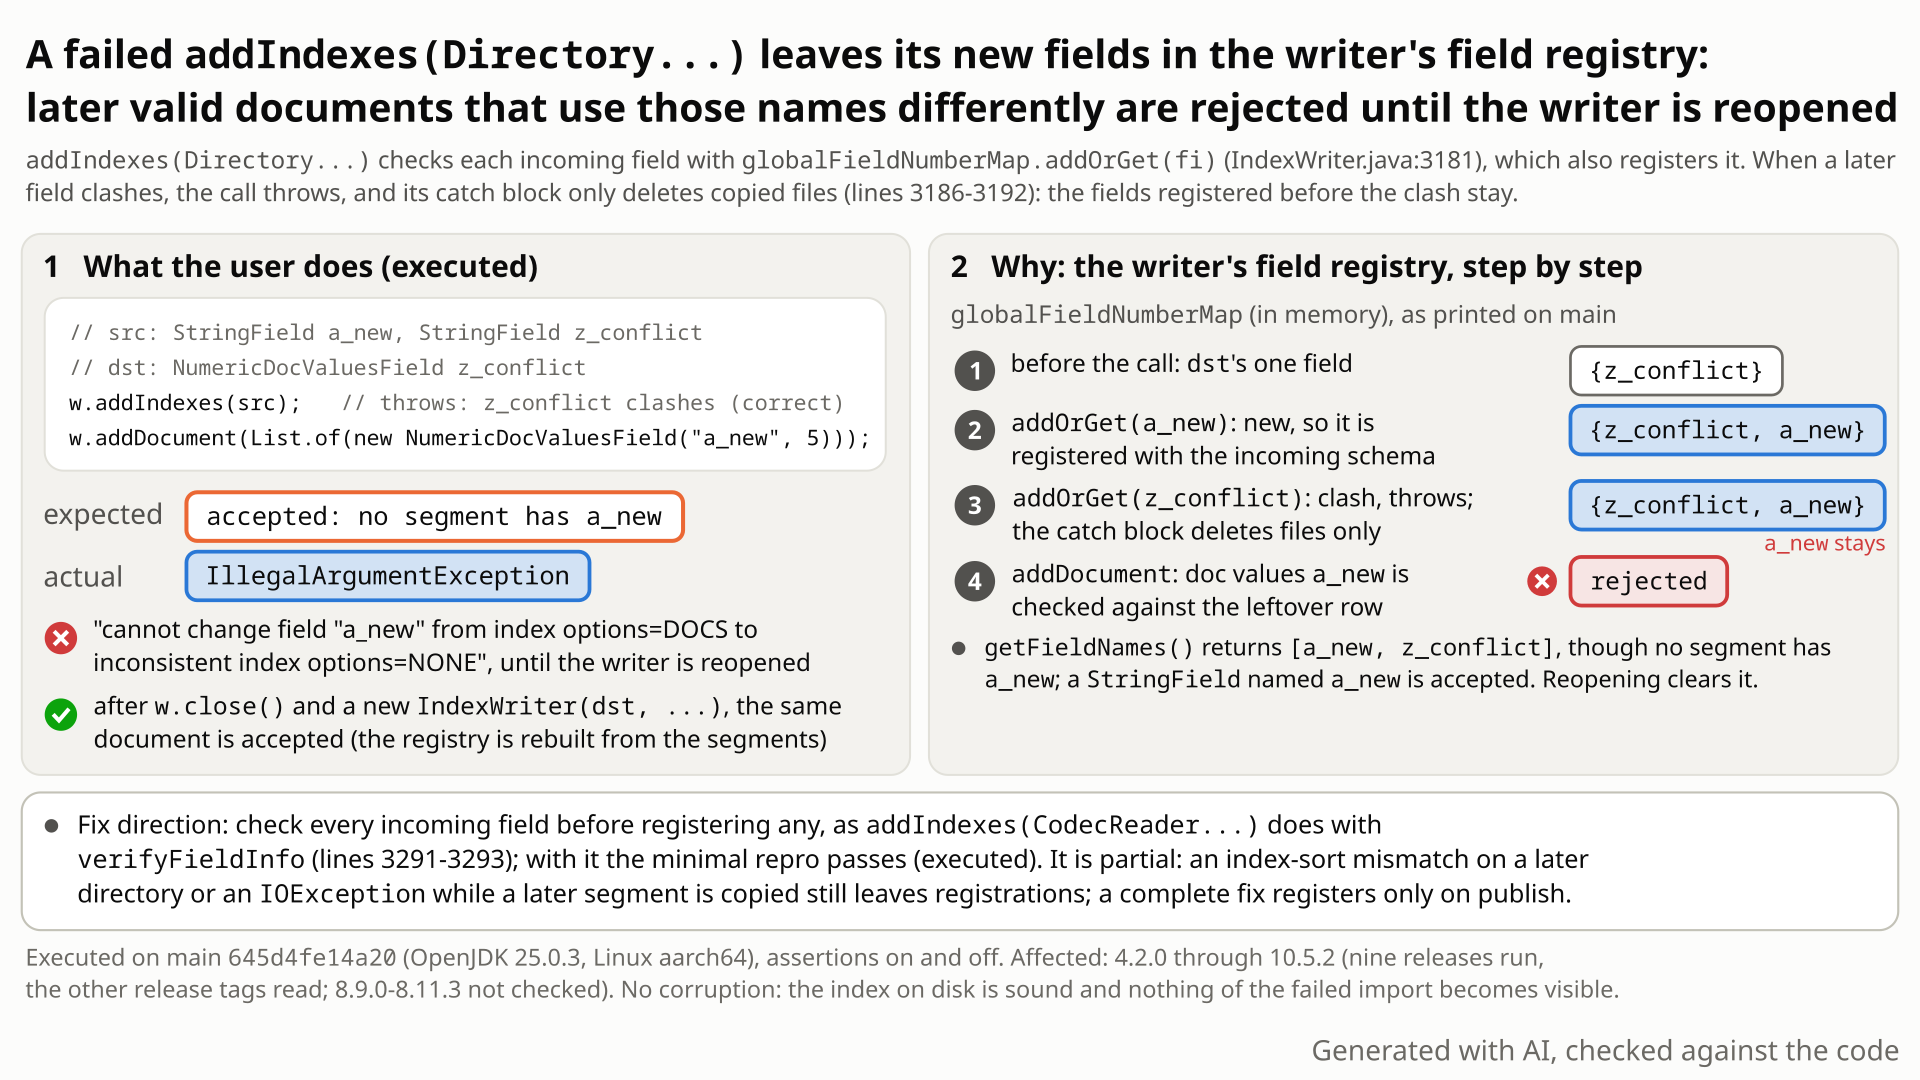
addIndexes(Directory...): a_new stays registered with the incoming schema, so the later a_new document is rejected; after a reopen, or with the fix, it is accepted. Select the still to open it at full size. Generated with AI, checked against the code.- The source index has one document with two indexed
StringFields,a_newandz_conflict. The destination has one document wherez_conflictis aNumericDocValuesField(doc values only). DefaultIndexWriterConfig. w.addIndexes(src)throwsIllegalArgumentException("cannot change field "z_conflict" from index options=NONE to inconsistent index options=DOCS"). That is correct: nothing is added,numDocsstays 1 and the writer stays open.- You expect the writer to be as before:
getFieldNames()=[z_conflict], anda_newstill unused, so a document withNumericDocValuesField("a_new", 5)is accepted, as it is after a reopen. - Instead
getFieldNames()=[a_new, z_conflict]and that document is rejected: "cannot change field "a_new" from index options=DOCS to inconsistent index options=NONE".a_newwas registered beforez_conflictfailed, and nothing takes it back. - It lasts until the writer is reopened; the reopened writer accepts the same document. After commit no segment has
a_new, and nothing of the failed import is visible.
Applications that bulk-import indexes with addIndexes(Directory...) and keep the writer after the call fails: a schema conflict found after a new field, a conflict between two incoming indexes, an index-sort mismatch, or an I/O error such as a full disk while copying. Default config. Later documents that use an imported name differently are rejected until the writer is reopened.
Mechanism, terms and numbers671 words
IndexWriter keeps one in-memory registry of every field name it knows and that field's schema (index options, doc values type, points, vectors), built from the segments when the writer opens, and checks every new document against it. addIndexes(Directory...) walks the incoming segments and, before copying each one, calls globalFieldNumberMap.addOrGet(fi) for every incoming field; addOrGet validates and registers. When the call then fails part-way (a schema conflict on a field visited later, a conflict between two incoming indexes, an index-sort mismatch on a later directory, or an IOException such as a full disk while copying a later segment), the failure path deletes the copied files and rethrows, but nothing removes the registrations. Nothing of the import is added or committed, as the javadoc promises, and the writer stays open; but for the rest of the writer session the incoming names keep the incoming schema: getFieldNames() lists a field that no segment has, and a later document that uses the name with another schema is rejected with IllegalArgumentException. Reopening the writer, or deleteAll(), clears it. The sibling addIndexes(CodecReader...) avoids this for conflicts with the destination's schema by checking every incoming field first, without registering. Every release from 4.2.0 through 10.6.0 is affected, and so are branch_11x and main. Checking up front and registering only when the copied segments are published fixes every executed trigger.
- The registry (
FieldInfos.FieldNumbers) is built once, from the segments, when the writer opens:globalFieldNumberMap = getFieldNumberMap()(IndexWriter.java:1124), which callsaddOrGetfor everyFieldInfoof every segment (:1267-1277). addIndexes(Directory...)(:3103) reads each directory's latest commit (:3126-3141). Inside thetryat:3146, for each incoming segment it checks the index sort (:3152-3159), reads the segment'sFieldInfos(:3177) and callsglobalFieldNumberMap.addOrGet(fi)for every field, with the comment "This will throw exceptions if any of the incoming fields has an illegal schema change" (:3178-3182). Only then does it copy the segment (copySegmentAsIs,:3183).addOrGet(FieldInfos.java:415-457) checks a known name against its registered schema (:421-422) and registers an unknown name with the incoming schema (:423-454). In the example,a_newis field 0 of the incoming segment, so it is registered beforez_conflictfails.- The failure path (
IndexWriter.java:3186-3192) deletes the files of the segments already copied and rethrows. The outercatch(:3212-3221) callstragicEventonly for anError, so after anIllegalArgumentExceptionor anIOExceptionthe writer stays open. Nothing removes the registrations:FieldNumbershas no removal exceptclear()(FieldInfos.java:694-698), which onlydeleteAll()calls (IndexWriter.java:2800). - A later document reaches
FieldInfos.Builder.add(FieldInfos.java:788) ->FieldNumbers.addOrGet->verifySameSchema(:511-548) and is rejected against the leftover schema.getFieldNames()(IndexWriter.java:2135-2137) returns the registry's names (FieldInfos.java:690-692). - The sibling
addIndexes(CodecReader...)runs "Best effort up front validations": the non-mutatingverifyFieldInfofor every incoming field before any merge (IndexWriter.java:3288-3293,FieldInfos.java:401-408). With the same inputs it leaves the registry unchanged.verifyFieldInfodoes not compare two incoming readers with each other; the tested conflict between two incoming readers is caught when theirFieldInfosare merged and leaves no leftover either. It is not fully immune: anIOExceptionduring its merge leaves the same leftover, because the merge registers fields as it goes. - Order matters: the leak needs at least one new incoming field visited before the failure. With the conflicting field first, nothing new is registered and nothing leaks.
| step | stock | with the recommended fix |
|---|---|---|
before the call: getFieldNames() | [z_conflict] | [z_conflict] |
addIndexes(src) | IllegalArgumentException: cannot change field "z_conflict" from index options=NONE to inconsistent index options=DOCS | the same |
after the call: getFieldNames(), numDocs | [a_new, z_conflict], 1 | [z_conflict], 1 |
addDocument(NumericDocValuesField("a_new", 5)) | rejected: cannot change field "a_new" from index options=DOCS to inconsistent index options=NONE | accepted |
| after commit: fields of the committed segments | [z_conflict] | [a_new, z_conflict] (the new document) |
| reopened writer: the same document | accepted | accepted |
Exposure and likelihood280 words
- Who is hit. Applications that use
addIndexes(Directory...), whose javadoc describes building sub-indexes in parallel and merging them with it (IndexWriter.java:3076-3079), and keep using the same writer after the call fails. Then every later document that gives one of the imported names a different schema is rejected. - Triggers that leak (executed on main): a schema conflict with the destination on a field visited after a new one; a conflict only between two incoming indexes; an index-sort mismatch on a later directory ("cannot change index sort from null to <long: "s">"); an
IOExceptionwhile copying a later segment, the javadoc's own "disk full" example ("simulated disk full while copying _1.cfs"). - Default configuration. A default-constructed
IndexWriterConfig(no custom codec or settings);ByteBuffersDirectoryin the repro,FSDirectoryin a reviewer's own test; with assertions on and off. The way in is an explicit bulk-import call that fails, followed by continued use of the writer. - Loud, no data damage. One
IllegalArgumentExceptionper affectedaddDocument; documents without the leftover names are unaffected, and a document that matches the leftover schema is accepted. The index on disk is sound: an NRT reader and the next commit show nothing of the failed import (no documents, stored values orFieldInfos), a pending delete stays applied, no unreferenced files remain, andCheckIndexis clean. An application that logs and drops failed documents loses them. - How long. Until the writer is reopened or
deleteAll()is called. Other threads that use the same writer see the same rejections (one shared, synchronized registry; read from the code, not executed). - Scale. None: one document per index is enough.
- Workaround. Close and reopen the writer after a failed
addIndexes(Directory...).
The test shows that a failed IndexWriter#addIndexes(Directory...) (schema conflict on "z_conflict", nothing added) leaves the incoming field "a_new", checked before the conflict, registered in the writer's schema (default config).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestFailedAddIndexesRegistersField extends LuceneTestCase {

  public void testFailedAddIndexesDoesNotDefineField() throws Exception {
    try (Directory src = new ByteBuffersDirectory();
        Directory dst = new ByteBuffersDirectory()) {
      try (IndexWriter sw = new IndexWriter(src, new IndexWriterConfig())) {
        sw.addDocument(
            List.of(
                new StringField("a_new", "x", Field.Store.NO),
                new StringField("z_conflict", "x", Field.Store.NO)));
      }
      try (IndexWriter w = new IndexWriter(dst, new IndexWriterConfig())) {
        w.addDocument(List.of(new NumericDocValuesField("z_conflict", 1)));
        // "z_conflict" is doc-values only in dst, so nothing from src is added
        expectThrows(IllegalArgumentException.class, () -> w.addIndexes(src));

        try {
          w.addDocument(List.of(new NumericDocValuesField("a_new", 5)));
        } catch (IllegalArgumentException e) {
          fail("expected: the first document with \"a_new\" is accepted; actual: " + e.getMessage());
        }
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-124/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestFailedAddIndexesRegistersField
- Expected vs actual
- Expected the first document of the destination that uses "a_new" (
NumericDocValuesField) to be accepted, as after a reopen; actual:IllegalArgumentException: cannot change field "a_new" from index options=DOCS to inconsistent index options=NONE, with-eaand-da.
More files, environment, full output48 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected: the first document with "a_new" is accepted; actual: cannot change field "a_new" from index options=DOCS to inconsistent index options=NONE
       org.junit.Assert.fail(Assert.java:89)
org.apache.lucene.index.TestFailedAddIndexesRegistersField.testFailedAddIndexesDoesNotDefineField(TestFailedAddIndexesRegistersField.java:46)- The javadoc promises that after an exception "either no indexes will have been added or they all will have been" (
IndexWriter.java:3084-3086); its "disk full" example leaves the same leftover. - A field's schema is set by "the first document indexed" with it (
MIGRATE.md); noa_newdocument was indexed. addIndexes(CodecReader...)checks incoming fields first, without registering, and stays clean for this conflict.
The full argument299 words
- Contract.
addIndexes(Directory...)(IndexWriter.java:3084-3086): "This method is transactional in how Exceptions are handled: it does not commit a new segments_N file until all indexes are added. This means if an Exception occurs (for example disk full), then either no indexes will have been added or they all will have been." After the failed call, part of the incoming index still decides which documents the writer accepts, and the javadoc's own disk-full example leaks the same way. - Schema definition.
MIGRATE.md:1557-1564: "The per field data-structures are implicitly defined by the first document indexed that contains a certain field." No document witha_newwas ever indexed into the destination. - getFieldNames. "all field names as visible from this IndexWriter, across all segments of the index" (
IndexWriter.java:2129-2133,@lucene.experimental); no segment hasa_new. - The sibling overload validates first on purpose.
addIndexes(CodecReader...)checks every incoming field withverifyFieldInfobefore it changes anything (IndexWriter.java:3288-3293); the commit that added it,698f40ad51af(LUCENE-10216, #633), lists "verify field info schemas upfront from incoming readers" and "Keep addIndexes API transactional". The Directory overload never got it. - Precedent.
lucene/CHANGES.txt:20868-20873(LUCENE-846): a failedaddIndexesthat could "corrupt the instance of IndexWriter (but, not the index itself)" was fixed as a bug.:21363-21370(LUCENE-702) is the origin of the transactional contract ("either all indices are merged or none are"); the same change fixedIndexWriter.mergeSegmentsandIndexReader.commit()to "keep the instance state consistent to what's actually in the index". - Tests.
TestIndexOptions.doTestChangeIndexOptionsAddIndexesDirectory(TestIndexOptions.java:125-159) asserts only the exception message, with one field, so nothing can leak there; no upstream test adds a document to, or checks the field names of, the writer after a failedaddIndexes(Directory...)(TestIndexSortingandTestDocValuesIndexing.testMixedTypesViaAddIndexesonly check that a second import of the same input also fails;TestIndexWriterOnDiskFullrolls the writer back).
The devil's-advocate check323 words
The devil's advocate built the strongest case for "accepted limitation"; the cross-model reviews had independently rated its core (the segments_N-only transactionality, the session registry and the experimental getFieldNames) moderate: the transactional sentence is literally about segments_N, and that part holds; the registry is a session registry that only grows by design (the deleteAll javadoc, IndexWriter.java:2735-2741, says only deleteAll clears "internal data structures" such as "doc value types"; #9597 calls field infos "(almost) append-only"); getFieldNames is experimental; a field whose documents are all deleted gives the same listing and rejection with no failure at all (the open #2835), and a rejected addDocument or a failed updateDocValues leaves similar state. In #13369 (the fix of #13353), for failed documents, benwtrent tried "Delaying on setting the field info until document writes are successful" (it "causes weirdness with global field numbers") and reverting the field info when all the docs for a field fail to index ("too sharp to mess with"), and settled on another fix.
Why it fails: no javadoc, test or discussion says that a failed operation may define a field's schema. In the deleted-field and rejected-document cases a document with the field reached the indexing chain; here none ever did. #13369 is about the per-document indexing chain, where delaying caused "weirdness with global field numbers"; here the copied segments keep their own field numbers (copySegmentAsIs copies the files unchanged, IndexWriter.java:3648-3705, and the result of addOrGet is unused, :3181), and the method has a documented all-or-nothing promise that its sibling already keeps by validating first. The trigger is legal public API with the default config, and the writer stays open with no tragic exception, so continuing to use it is not misuse. Our reading: a defect (the devil's advocate stayed at "uncertain"). Residual risk: a maintainer may treat it as one design question with the other entry points ("the registry is never rolled back after a failed operation").
Recommended Check up front, register only when the segments are published (covers every executed trigger, validated)
Check every incoming field up front, as the CodecReader overload does, and register the fields only when the copied segments are published, all at once or not at all. +53/-6 in IndexWriter and FieldInfos; the repro and all 8,898 lucene/core tests pass, and the index-sort and disk-full cases no longer leak.
All options and trade-offs3 options · 690 words
Two fixes were built and validated with gradle; the recommended one covers every executed trigger, the smaller one only schema conflicts. A rollback alternative was not built.
Check up front, register only when the segments are published (covers every executed trigger, validated) (recommended)
Read every incoming segment's FieldInfos before copying anything and check them against the registry and against each other (a new non-mutating FieldNumbers.verifyFieldInfos); drop the addOrGet calls from the copy loop; and register all incoming fields with one synchronized FieldNumbers.addAll (verify all, then register all) inside synchronized (this), just before segmentInfos.addAll(infos). If that last call throws, the reserved document count is released and the copied files are deleted, as for any other failure there. +53/-6 in IndexWriter.java and FieldInfos.java. The core of it:
  // before the copy loop: check, register nothing
  List<FieldInfos> incomingFieldInfos = new ArrayList<>();
  for (SegmentInfos sis : commits) {
    for (SegmentCommitInfo info : sis) {
      incomingFieldInfos.add(readFieldInfos(info));
    }
  }
  globalFieldNumberMap.verifyFieldInfos(incomingFieldInfos);

  // synchronized (this), after reserveDocs(totalMaxDoc), before segmentInfos.addAll(infos)
  try {
    globalFieldNumberMap.addAll(incomingFieldInfos); // all or nothing
  } catch (Throwable t) {
    adjustPendingNumDocs(-totalMaxDoc);
    throw t;
  }
Trade-offs
- The incoming
FieldInfosare read once up front instead of inside the copy loop, and kept until publish (small). - A concurrent document that introduces one of the incoming names with another schema while the files are being copied is now accepted, and the
addIndexescall then fails at publish (all or nothing, files deleted, reservation released); today that document is rejected instead. Either way one schema wins (reasoning; concurrency not executed). - Lock order is
IndexWriter, thenFieldNumbers, as elsewhere; noFieldNumbersmethod calls back into the writer. addIndexes(CodecReader...)'sIOExceptioncase (its merge registers fields as it goes) is a separate path that this change does not touch.
What the checks validated
- Gradle on
645d4fe14a20, fresh scratch worktree, seed DEADBEEF: stock, the test fails with assertions on and off. With the fix: the test plusTestAddIndexes,TestIndexOptions,TestConsistentFieldNumbers,TestFieldInfos,TestIndexSorting,TestIndexWriterOnDiskFull,TestDocValuesIndexingandTestPointValues, 9 suites, 194 tests, 0 failures; the test with assertions off passes; everylucene/coretest: 749 suites, 8,898 tests, 0 failures, 322 skipped. checkGoogleJavaFormatpasses on the final diff and the test. The suites above ran with a first version that differs only in one reflowed javadoc line; with the final diff the test plusTestAddIndexespass again (40 tests).- Standalone runner on the same commit with the patched classes: the test passes (
-ea,-da); the independent reproducer's 5 tests go from 2 failures to 0; the devil's advocate's index-sort and disk-full probes no longer leak (getFieldNames()=[s]and[other], thea_newdocument accepted); the diagnostic probe shows[z_conflict]after the failed call.
The hunt's fix, +16 in IndexWriter.java only: before the copy loop, check every incoming FieldInfo with globalFieldNumberMap.verifyFieldInfo and against the other incoming FieldInfos (FieldInfo.verifySameSchema); the loop keeps its addOrGet calls.
  Map<String, FieldInfo> incomingFields = new HashMap<>();
  for (SegmentInfos sis : commits) {
    for (SegmentCommitInfo info : sis) {
      for (FieldInfo fi : readFieldInfos(info)) {
        globalFieldNumberMap.verifyFieldInfo(fi);
        FieldInfo prev = incomingFields.putIfAbsent(fi.getName(), fi);
        if (prev != null) {
          prev.verifySameSchema(fi);
        }
      }
    }
  }
Trade-offs
Smallest change and mirrors the sibling overload, but it fixes the schema-conflict triggers only: an index-sort mismatch on a later directory and an IOException while copying a later segment (the javadoc's own "disk full" example) still leak with it.
What the checks validated
- Gradle on
645d4fe14a20: the same 9 suites, 194 tests, 0 failures;checkGoogleJavaFormatpasses. - Standalone runner: the test passes; the independent reproducer's 5 tests pass; earlier reviews: the refute-lens reviewer's own test 5/5 plus 6 existing addIndexes and schema tests, and
TestIndexOptions13/13. - The index-sort and disk-full probes still reject the
a_newdocument with it.
Record the names this call newly registered and remove them in the catch.
Trade-offs
Needs a new removal in FieldNumbers, and another thread may start using a name between its registration and the rollback, so removal is unsafe without more bookkeeping; deferral avoids that.
Services that import index directories into a long-lived writer should reopen the writer after a failed import until this is fixed; nothing on disk needs repair.
An Alloy model of the writer's field registry versus the segments' field lists. While writing the model's addIndexes(Directory...) step, code reading showed that the loop registers fields while it iterates; Alloy then produced a counterexample (a failed call leaves a new name registered) and none for the CodecReader overload. A JUnit on the stock jar followed.
The method in full132 words
Method: semi-formal (an Alloy 6.2 temporal model; the first signal was code reading while modelling, then witnessed by the tool).
- The hunt unit modelled the writer-wide field registry (
FieldNumbers) against the segments'FieldInfos, with contracts for schema agreement, transactionaladdIndexesand no phantom names (FieldNumbersTxn.als). - While writing the
addIndexes(Directory...)action, the finder noticed that the loop registers each incoming field before copying its segment. Alloy produced a counterexample toAddIndexesTxnHolds(a failedaddIndexesleaves a new name registered), whileReadersTxn, theCodecReaderoverload, had none in the same 6-step bound. - A JUnit on the stock jar confirmed it, later reduced to the one-test repro. The model has no I/O failures, so it says nothing about the
IOExceptionpaths; those were found by the devil's advocate's probes.
No prior report found: about 140 searches over GitHub issues and PRs, the JIRA archive, the mailing lists and the web (2026-10-26), re-checked on GitHub on 2026-10-31. Closest is the open #2835 (field metadata of fully deleted fields is never removed): the same "only grows" registry, but a different trigger and fix site.
Searches5 searches
The recorded searches found no report, discussion or fix of this bug. The adjudication notes that a maintainer could call it "the same limitation as LUCENE-1761" (#2835). Searches are term-based and best effort.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (GitHub issues/PRs incl. the JIRA archive, commits, downstream, dev@ / java-user@ / issues@ / commits@, JIRA, web) | 2026-10-26 | 45 GitHub issue/PR, 3 commit, 2 downstream, 40 mailing-list, 6 JIRA-archive and 8 web queries | no report |
| GitHub GraphQL: apache/lucene, Elasticsearch, OpenSearch, Solr | 2026-10-26 | 36 searches with bodies read; full threads of more than 25 issues and PRs, 8 JIRA issues and 2 list threads | related items only |
| Open apache/lucene PRs | 2026-10-26 | changed-file lists of all 412 open PRs; the patches of the 19 that touch IndexWriter.java, FieldInfos.java, FieldInfo.java or TestAddIndexes.java grepped | none changes the loop |
| GitHub issue/PR search and branch heads, apache/lucene | 2026-10-31 | addIndexes; getFieldNames; "cannot change field" addIndexes; addIndexes Directory schema failed; addIndexes transactional field; commits touching IndexWriter.java or FieldInfos.java on main since 2026-10-15 | only known items; no new commit |
| Related items (read) | 2026-10-26 | the threads of the closest items | #2835 (LUCENE-1761, open, deleted fields' metadata never removed), #9597 (LUCENE-8551, won't fix, "(almost) append-only"), #13353 / #13369 (failed documents leave registered FieldInfo in the indexing chain; delaying or reverting tried, not adopted), #11253 / #633 / #1051 (LUCENE-10216, up-front check for the CodecReader overload), #11 / #10374 (LUCENE-9334), #1777 (LUCENE-702), #8710 / #9952 / #10719 (getFieldNames), #15683, #11554 |
Introduced in 4.2.0 (2013) by the LUCENE-4547 doc-values work (041ff1140f3f), which added both the schema check and the register-while-copying loop. Executed as failing on 4.2.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.5.2, 10.6.0 and main; 4.1.0 is not affected.
Versions tested8 rows
Introduced by 041ff1140f3f "make DV strongly typed; fix solr" (mikemccand, 2012-11-23, on the lucene4547 branch), which gave the registry a per-name doc-values type and, in the same change, added the register-while-iterating loop to addIndexes(Directory...) with a failure path that only deletes files. It reached trunk as a181dc073539 (2013-02-07) and branch_4x as 5cbaddcbc7ff (2013-02-08), both "LUCENE-4547: DocValues improvements"; no PR (Subversion era), and LUCENE-4547 (#5613) does not discuss addIndexes. Before it, addIndexes(Directory...) neither validated nor registered incoming fields.
Later changes kept the shape: d03662c48bfc (LUCENE-9334, PR #11, 2021) changed the call to addOrGet(fi) and widened the trigger to the whole per-field schema (the "This will throw exceptions ..." comment is older: e5c4ba48df7, LUCENE-6825, 2015, first released in 6.0.0); 0a4a76f0a869 (#14668, 2025) replaced the success flag with catch (Throwable), still deleting files only; 698f40ad51af (LUCENE-10216, #633) gave only the CodecReader overload an up-front check (from 9.4.0).
Trigger width: doc-values type conflicts from 4.2.0; point dimensions from 6.0.0 (read only); a change between two indexed index options from 8.0.0 (LUCENE-8134, read only); the whole per-field schema, including the repro's indexed versus doc-values-only case, from 9.0.0, so the repro's exact input is not a conflict on 8.11.4. The getFieldNames() symptom exists from 6.5.0 (LUCENE-7659). The index-sort and IOException triggers on old releases are from code reading only. The loop was read at every release tag of the history clone from 4.2.0 to 10.5.2; the clone has no 8.9.0-8.11.3 tags, so those releases were neither read nor run (they lie between the read 8.8.1 and the executed 8.11.4).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 (11.0.0-SNAPSHOT) | affected | gradle: the one-test repro fails with assertions on and off; standalone too |
| 10.6.0 | affected | the one-test repro fails on the released jars, with assertions on and off |
main ea57360912ed, 10.5.2, 9.12.3 | affected | the hunt's and the independent reproducer's tests fail (the cross-model reviewers' on main too); the reopen and CodecReader controls pass |
| 9.0.0 | affected | the hunt repro (ported import) and the doc-values-type repro fail |
| 4.2.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4 | doc-values trigger | a version-portable doc-values-type repro fails, each time with its reopen control passing; on 8.11.4 the repro's exact index-options input is not a conflict |
| 4.1.0 | not affected | not reachable: addIndexes(Directory...) neither validated nor registered incoming fields |
branch_11x, branch_10_6, upstream main 2f424fd428da | read | the same loop (IndexWriter.java byte-identical on branch_11x and main), read 2026-10-31 |
fix (645d4fe14a20 + register-at-publish) | not affected | the repro and all 8,898 lucene/core tests pass; index-sort and disk-full probes no longer leak |
Confirmed by an independent reproducer, executing reviews from another model family (OpenAI GPT-5.6), a devil's advocate and an adjudication, each with their own tests and controls. This doc's test was re-run with gradle on main and with the standalone runner on the 10.6.0 jars, and the recommended fix was validated with gradle.
Checks and verdicts334 words
Every executing check wrote or ran its own test on the stock jars, with passing controls (no failed call; reopen; the CodecReader overload; conflict-first ordering). The reviews, the reproducer, the devil's advocate and the adjudication ran on the hunt's earlier main checkout ea57360912ed, where the cited files have the same lines.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Own public-API test, conflict in the mirror direction: fails 2 of 5 on main (-ea, -da), 10.5.2 and 9.12.3; 20 of 50 with 10 iterations (deterministic); 3 controls pass; found that two incoming indexes that conflict only with each other leak too. |
| cross-model review, refute lens | real, high | An independent reviewer from another model family (OpenAI GPT-5.6), executing: own FSDirectory test fails 2 of 5 (-ea, -da); controls pass (conflict-first ordering, CodecReader overload, reopen); the verify-first fix passes 5/5 plus 6 existing tests. |
| cross-model review, works-as-designed lens | real, high | Same reviewer family, executing: rated the "segments_N-only transactionality, session registry, experimental API" reading moderate and rejected it; own test confirms the leftover, the rejection, the clean reopen and the clean CodecReader overload. |
| devil's advocate | uncertain (not not-real) | "Neither intended nor documented, and it is not a misuse"; built the strongest accepted-limitation case; found the index-sort and disk-full triggers, the CodecReader IOException case, and that the verify-first fix is partial. |
| adjudication | confirmed, medium | Re-ran the reproducer's test with a new seed: 2 of 5 fail (-ea, -da), controls pass; recorded the scope and partial-fix caveats. |
| Follow-up | new; not security-sensitive | 18 history runs from 4.1.0 to main (plus one kept compile-error record); a fail-closed security characterization probe; the prior-art search. |
| this doc | reproduces; fix validated | Gradle on 645d4fe14a20 (assertions on and off) and the standalone runner on 10.6.0; the recommended fix with gradle (the repro, 9 suites, all of lucene/core, formatting) and the index-sort and disk-full probes; the smaller fix with gradle (9 suites). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 544 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,633 words
- Registry title
- A failed addIndexes(Directory...) leaves the incoming fields registered in the writer's field schema, so getFieldNames() lists them and later valid documents that use those names differently are rejected until the writer is reopened
- Area
- index / IndexWriter addIndexes(Directory...) and the writer-wide field registry (FieldInfos.FieldNumbers)
- Priority
- Low, rank 840: After a failed addIndexes(Directory...), leftover field registrations reject later documents that use those names differently until the writer is reopened, loud with no corruption, and it needs an app that keeps the writer after the failure.
- Impact class
- crash
- Impact note
- Applications that call IndexWriter#addIndexes(Directory...) and keep using the same writer after the call fails part-way, once at least one new incoming field has been registered (a schema conflict with the destination or between the incoming indexes, an index-sort mismatch on a later directory, or an IOException such as a full disk while a later segment is copied); default IndexWriterConfig, codec and directory, with -ea and -da; every later document that gives one of those field names a schema other than the incoming one is rejected with IllegalArgumentException, and getFieldNames() lists the names although no segment has them, until the writer is reopened (or deleteAll is called); the index on disk is sound, nothing of the failed import becomes visible, documents without those names are unaffected, and an application that logs and drops failed documents loses them; ordinary scale; released 4.2.0-10.6.0.
- Summary
- You call IndexWriter#addIndexes(Directory...) with an index whose first field a_new is new to the destination and whose field z_conflict clashes with the destination's schema; the call correctly throws IllegalArgumentException and adds no segment, as its javadoc promises ('either no indexes will have been added or they all will have been'). You expect the writer to be as it was before the call, so that a later document can use a_new with any schema, as it can after the writer is reopened and after the same failure in addIndexes(CodecReader...). Instead the writer keeps a_new registered with the incoming schema, because addIndexes(Directory...) registers each incoming FieldInfo in the writer-wide FieldNumbers map while it iterates and its failure path only deletes the copied files: getFieldNames() lists a_new although no segment has it, and a document with NumericDocValuesField('a_new') is rejected ('cannot change field "a_new" from index options=DOCS to inconsistent index options=NONE') until the writer is reopened.
- Introduced
- 041ff1140f3f ('make DV strongly typed; fix solr', by mikemccand on the lucene4547 development branch, svn r1412906), which gave FieldInfos.FieldNumbers a per-name doc-values type and added the loop in addIndexes(Directory...) that calls globalFieldNumberMap.addOrGet for every incoming FieldInfo before copySegmentAsIs, with a failure path that only deletes the copied files; it reached trunk as a181dc073539 and branch_4x as 5cbaddcbc7ff (both 'LUCENE-4547: DocValues improvements'); no PR (Subversion era), and LUCENE-4547 (GitHub #5613) does not discuss addIndexes or failure handling; d03662c48bfc (LUCENE-9334, PR #11) later changed the call to addOrGet(fi) with the comment 'This will throw exceptions if any of the incoming fields has an illegal schema change' and widened the trigger to every per-field attribute, and 0a4a76f0a869 (#14668) replaced the success flag with catch (Throwable) and still only deletes files [read: git blame of the loop and the diff of 041ff1140f3f in the full-history clone; the first parent of each landing commit has no addOrGet in addIndexes(Directory...); exec: not reachable on 4.1.0, fails on 4.2.0] (2012-11-23 (041ff1140f3f, lucene4547 branch); landed on trunk 2013-02-07 (a181dc073539) and branch_4x 2013-02-08 (5cbaddcbc7ff); 4.2.0 tagged 2013-03-11)
- First affected version
- 4.2.0 [exec]
- Affected versions
- every release from 4.2.0 through 10.6.0 and main ea57360912ed and 645d4fe14a20 (unreleased 11.0.0) [exec: the one-test repro fails on the 10.6.0 release jars and on main 645d4fe14a20, -ea and -da (2026-10-31); the follow-up's version-portable doc-values-type repro fails on 4.2.0 (-ea and -da), 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.5.2 and main (-ea and -da), each time with its reopen control passing; the hunt repro fails on 9.0.0 (import-only port), 9.12.3, 10.5.2 and main (-ea and -da); the independent reproduction's own repro fails on main (-ea, -da), 10.5.2 (-ea, -da) and 9.12.3; read: a scan of every 4.2.0..8.8.1 and 9.0.0..10.5.2 release tag finds the same register-while-iterating loop with no rollback and no up-front verify]; the hunt repro's exact trigger (an indexed StringField against a doc-values-only field) needs LUCENE-9334 and exists from 9.0.0 on (on 8.11.4 that input is not a conflict) [exec]; the getFieldNames() symptom exists from 6.5.0 (LUCENE-7659) [read; executed from 6.6.6 on]; the point-dimension (6.0+), index-sort and IOException triggers on old releases are from code reading only; 4.1.0 and earlier are not affected: addIndexes(Directory...) neither validated nor registered incoming fields [exec on 4.1.0]; not fixed upstream: the loop is unchanged on main, branch_10x, branch_10_6, branch_10_5 and branch_9_12 [read], IndexWriter.java is byte-identical at 645d4fe14a20 and upstream main 2f424fd428da [read 2026-10-31], and no open PR changes it
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Alloy, code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, read-only: a scripted prior-report search with 45 GitHub issue/PR queries, 3 commit queries, 2 downstream-repo queries, 40 mailing-list queries over dev@, java-user@, issues@ and commits@, 6 JIRA-archive queries and 8 web queries; 36 GitHub GraphQL searches with bodies read, including Elasticsearch, OpenSearch, Solr; the changed-file lists of all 412 open apache/lucene PRs, with the patches of the 19 that touch IndexWriter.java, FieldInfos.java, FieldInfo.java or TestAddIndexes.java grepped; full-thread reads of 30+ issues and PRs, 8 JIRA issues and 2 list threads; the loop on main, branch_10x, branch_10_6, branch_10_5 and branch_9_12; plus the finder's scripted prior-report search and the intended-behaviour check's gh searches); related prior items, none of them this bug: #2835 (LUCENE-1761, open: field metadata of fully deleted fields is never removed; the same 'registry only grows' mechanism, but a persisted case with no failed call and a merge-side fix site), #9597 (LUCENE-8551, won't fix: field infos in the global map are '(almost) append-only'), #13353 / #13369 (a failed document leaves eagerly registered FieldInfo in the indexing chain; reverting registrations was considered and rejected there; not about addIndexes), #11554 (LUCENE-10518: partial FieldInfo after a non-aborting exception treated as a defect), #11253 / #633 / #1051 (LUCENE-10216: up-front verifyFieldInfo for addIndexes(CodecReader...) to keep it transactional; no mention of the Directory overload), #11 / #10374 (LUCENE-9334: strict per-field schema; rewrote the loop to addOrGet(fi)), #1777 (LUCENE-702: origin of the transactional addIndexes contract), #8710 / #9952 / #10719 (getFieldNames added, removed and re-added), #15683 (open: touches the addOrGet loop of getFieldNumberMap, not addIndexes); downstream sepinf-inc/IPED#1007 has the same error text from an application-side race, without addIndexes
- Lucene commit tested
- main
645d4fe14a20(2026-10-28, 11.0.0-SNAPSHOT) with gradle in fresh scratch worktrees: the one-test repro fails with assertions on and off; with the recommended fix it passes, together with 9 addIndexes and field-schema suites (194 tests), everylucene/coretest (8,898 tests, 0 failures) and the formatting check; the smaller fix passes the same 9 suites. The standalone JUnit runner on the same commit and on the released 10.6.0 jars (the repro fails, assertions on and off), and on the same commit with each fix shadowed: the repro, the independent reproducer's 5 tests, the devil's advocate's index-sort and disk-full probes and a diagnostic probe. The hunt's runs on mainea57360912ed(the cited files have the same lines), 10.5.2 and 9.12.3, and the follow-up's runs from 4.1.0 to 10.5.2. Read on 2026-10-31:IndexWriter.javais byte-identical at645d4fe14a20,branch_11xand upstream main2f424fd428da, andbranch_10_6has the same loop.
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3084-3086 (addIndexes(Directory...) javadoc: 'This method is transactional in how Exceptions are handled ... either no indexes will have been added or they all will have been'), :3176-3182 (for each incoming FieldInfo: globalFieldNumberMap.addOrGet(fi), with the comment 'This will throw exceptions if any of the incoming fields has an illegal schema change', before copySegmentAsIs), :3186-3192 (catch (Throwable): deleteNewFiles for the copied segments, then rethrow; no registry rollback), :3288-3293 (addIndexes(CodecReader...): 'Best effort up front validations', globalFieldNumberMap.verifyFieldInfo for every incoming field), :2129-2137 (getFieldNames: 'all field names as visible from this IndexWriter, across all segments of the index', @lucene.experimental, returns globalFieldNumberMap.getFieldNames()), :2735-2741 (deleteAll javadoc: internal data structures such as doc value types are cleared, unlike a delete query), :1266-1277 (getFieldNumberMap builds the registry from the segments when a writer opens)lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:401-407 (FieldNumbers.verifyFieldInfo, non-mutating), :415-457 (FieldNumbers.addOrGet validates and registers a new name), :694 (FieldNumbers.clear, the only removal)lucene/MIGRATE.md:1557-1564 ('Require consistency between data-structures on a per-field basis': the per-field data-structures are implicitly defined by the first document indexed that contains a certain field)lucene/CHANGES.txt:20835-20840 (LUCENE-846: a failed addIndexes that could corrupt 'the instance of IndexWriter (but, not the index itself)' was fixed as a bug) and :21330-21337 (LUCENE-702: addIndexes made transactional, and IndexWriter keeps 'the instance state consistent to what's actually in the index')SECURITY.md:28-34, 42, 50 (index files and caller-supplied directories are trusted; in-scope reports; cited by the security record)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1124, 1267-1277, 2135-2137, 2800, 3103, 3126-3141, 3146-3192, 3212-3221, 3288-3293lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:401-408, 415-457, 511-548, 690-698, 788
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3076-3079 (use case), 2735-2741 and 2800 (deleteAll clears the registry)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:2129-2133, 2735-2741, 3084-3086, 3181, 3288-3293, 3648-3705lucene/MIGRATE.md:1557-1564lucene/CHANGES.txt:20868-20873 (LUCENE-846), 21363-21370 (LUCENE-702)lucene/core/src/test/org/apache/lucene/index/TestIndexOptions.java:125-159
- TestFailedAddIndexesRegistersField.java (JUnit test):
repro/LFV-124/src/org/apache/lucene/index/TestFailedAddIndexesRegistersField.java(51 lines)
A picture of the writer's field registry through the failed call, the rejected document and the reopen. The values come from executed probe runs on main 645d4fe14a20, stock and with a fix.
assets/LFV-124/bug.png(544 KB)