PatienceKnnVectorQuery.rewrite handles a seeded delegate by assigning its own field a new SeededKnnVectorQuery that holds a seed Weight built for the current searcher. The sibling SeededKnnVectorQuery.rewrite builds the same thing into a new query and leaves itself unchanged.
- A
Querydescribes what to find.IndexSearcherfirst rewrites it into simpler queries, then builds aWeightfor that searcher; theWeightholds everything that depends on the searcher and its reader. - So a search does not change the
Queryobject:Weight's javadoc says this is what lets one instance be reused, andBooleanQuerycaches its own hash, computed from its clauses, on that assumption. SeededKnnVectorQuerystarts the HNSW graph search from the top hits of a seed query. To find them in each segment it needs a seedWeightbuilt for the current searcher.PatienceKnnVectorQuerywraps a kNN query, here the seeded one, and stops the graph search early once the top hits stop changing.
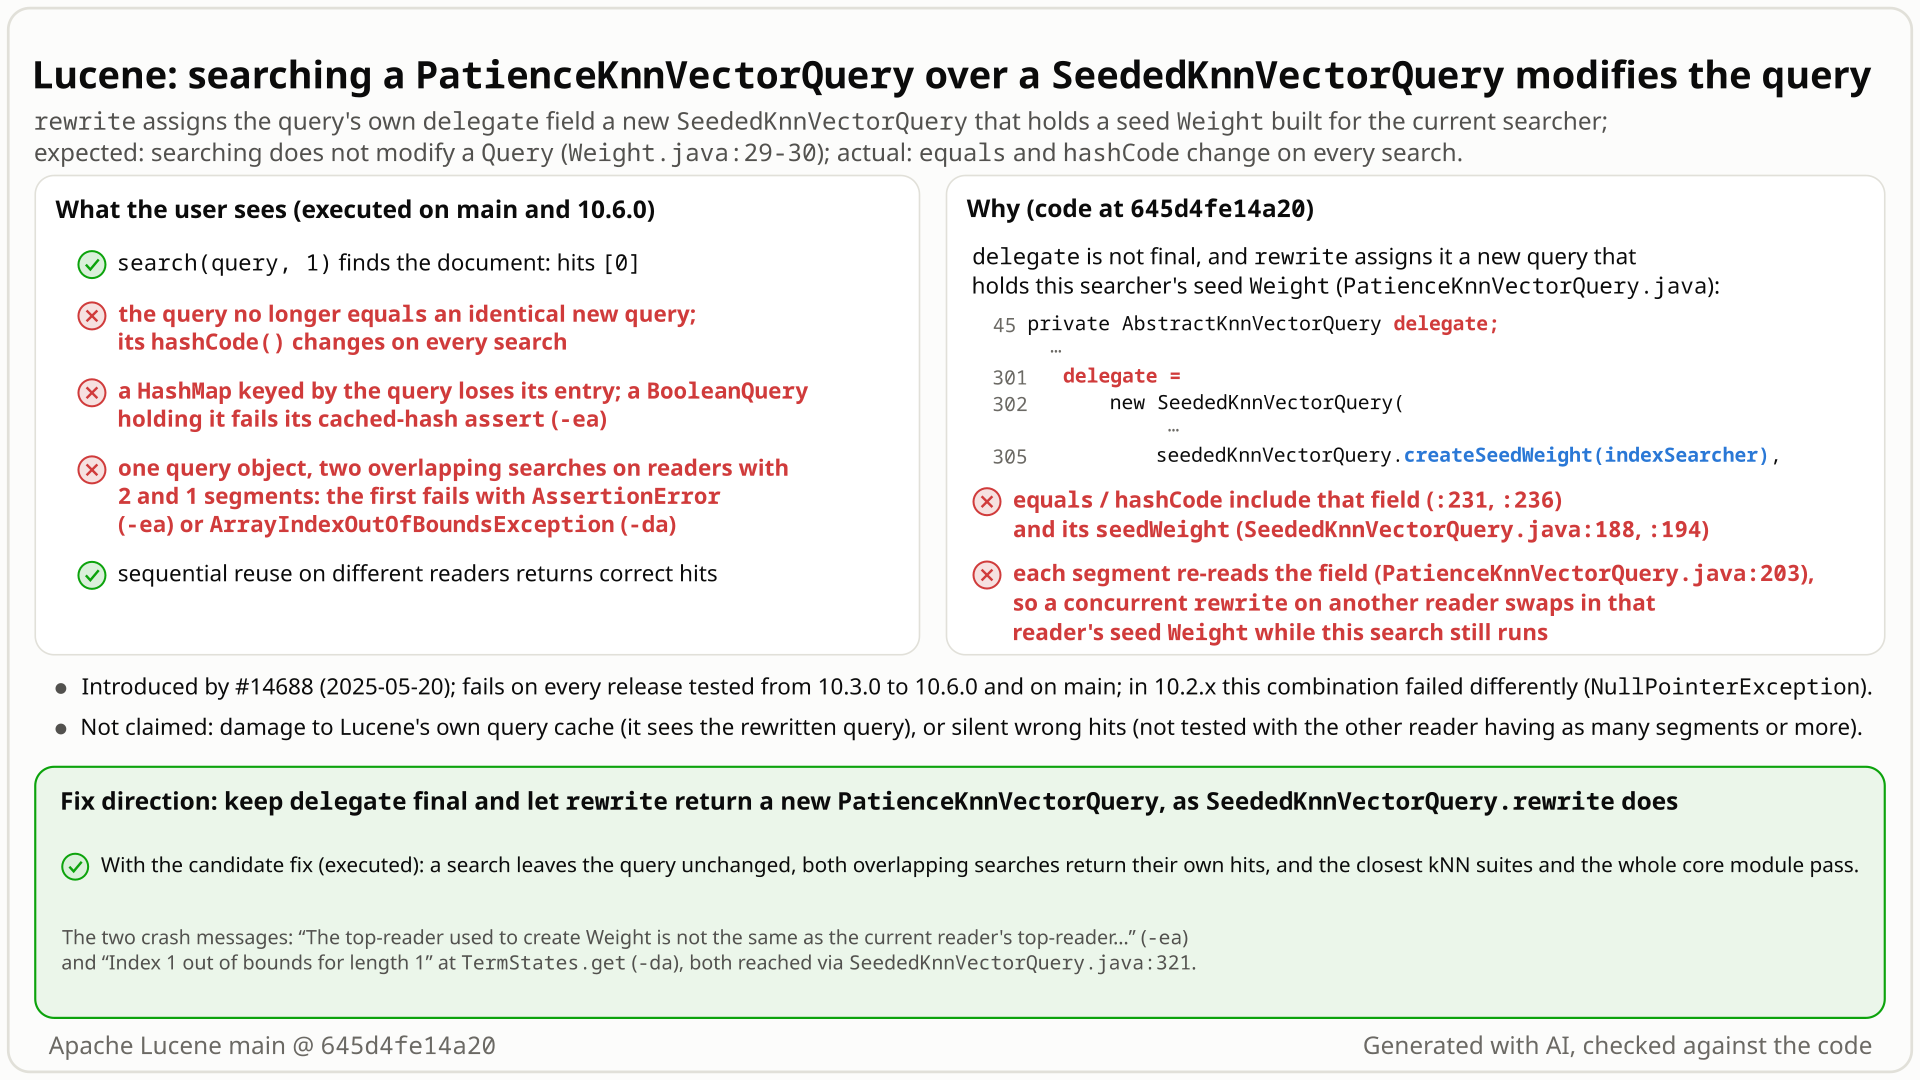
rewrite writes into it, and which seed Weight each segment then runs. Select the still to open it at full size. Generated with AI, checked against the code.- Index one document (
id:0, vector [1, 1]) and buildPatienceKnnVectorQuery.fromSeededQuery(SeededKnnVectorQuery.fromFloatQuery(knn, seed)): a top-1 kNN query that starts its graph search from the hits of the seedTermQuery(id:0)and stops early once the results saturate. - Run
searcher.search(query, 1)once. You expect the query object to be untouched:Weight's javadoc says searching does not modify aQuery, so that one instance can be reused, andIndexSearcheris documented thread-safe. - Instead
rewritestored a seedWeightbuilt for this searcher in the query's owndelegatefield:toStringchanges fromseedWeight=nulltoseedWeight=weight(id:0),hashCodechanges, and the query no longer equals an identical, never-searched copy. - Search one query object from two threads on two different readers at once: the first search picks up the other reader's seed
Weightfor its second segment and fails withAssertionError: The top-reader used to create Weight is not the same as the current reader's top-reader, or with assertions offArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1(run with a 2-segment and a 1-segment reader). - Searching it again later, even on another reader, still returns correct hits, because each rewrite rebuilds the seed
Weight. The damage is the changed identity (maps keyed on the query lose entries; aBooleanQueryholding it fails its cached-hash assertion) and the crash under overlapping searches.
Applications that build PatienceKnnVectorQuery.fromSeededQuery(...) (both classes @lucene.experimental; Solr's DenseVectorField builds this combination). Every search changes the query's identity, which hurts maps or caches keyed on it and a BooleanQuery holding it. The crash needs one query object searched on two different readers at overlapping times.
Mechanism, terms and numbers685 words
PatienceKnnVectorQuery (early termination for HNSW search) can wrap a SeededKnnVectorQuery (HNSW search started from the hits of a seed query); both are @lucene.experimental. A seeded query needs a seed Weight built for the current searcher. SeededKnnVectorQuery.rewrite builds it into a new query, but PatienceKnnVectorQuery.rewrite assigns a new SeededKnnVectorQuery holding it to its own non-final delegate field (PatienceKnnVectorQuery.java:45, :296-312 on main 645d4fe14a20). Because equals/hashCode include that field and the seed Weight, one search changes the query's identity, against Weight's contract that "searching does not modify a Query, so that a Query instance can be reused" (Weight.java:29-32). The field is re-read for every segment, so when one query object is searched on two different readers at overlapping times, a search runs the other reader's seed Weight and fails with an AssertionError (assertions on) or, in the run with a 2-segment and a 1-segment reader, an ArrayIndexOutOfBoundsException (off). Sequential reuse still returns correct hits. #14688 introduced it in 10.3.0 while fixing an NPE on this path; every release from 10.3.0 to 10.6.0 and main are affected. Building the seed Weight into a new query, as SeededKnnVectorQuery.rewrite does, fixes it; the closest kNN suites and the whole core module pass with the fix. It rewrites into a plain PatienceKnnVectorQuery, so a subclass's overrides are skipped for a seeded delegate, and it uses a caller-supplied seed Weight as given (see the fixes).
- The field.
PatienceKnnVectorQuery.java:45:private AbstractKnnVectorQuery delegate;, the class's only non-final field (patienceandsaturationThresholdat:43-44are final). - The assignment.
rewrite(:296-312): ifdelegateis aSeededKnnVectorQuery,:301-309assignsdelegate = new SeededKnnVectorQuery(seededKnnVectorQuery.delegate, seededKnnVectorQuery.seed, seededKnnVectorQuery.createSeedWeight(indexSearcher), delegate.field, delegate.k, delegate.filter, delegate.searchStrategy), thensuper.rewriteruns the per-segment kNN search onthisand returns aDocAndScoreQuery. The caller's object keeps the new delegate.createSeedWeight(SeededKnnVectorQuery.java:136-146) rewritesseed MUST + FieldExistsQuery(field) FILTER(plus the filter) and callsindexSearcher.createWeight(...), so the storedWeightbelongs to this searcher's top-level reader. - Identity.
PatienceKnnVectorQuery.equals/hashCodeincludedelegate(:223-237);SeededKnnVectorQuery.equals/hashCodeincludeseedWeight(SeededKnnVectorQuery.java:181-195);WeightkeepsObjectidentity. So after any search the query no longer equals a fresh twin, and itshashCodeincludes the newWeight's identity hash: in every recorded run it differed from the twin's after one search and changed again after a second one. - Re-read per segment.
approximateSearch(:196-204) callsdelegate.approximateSearch(...)for each segment;SeededKnnVectorQuery.approximateSearch(:148-157) wraps the collector manager, andSeededCollectorManager.newCollectorrunsseedWeight.bulkScorer(ctx)on the caller's segment (:311-321). If another thread's rewrite replaced the field in between, that is the other searcher'sWeight:TermQuery's check that theWeightwas built for this top-level reader (TermQuery.java:120-122) fails under-ea; under-da,TermStates.getindexes the other reader's per-segment states with this segment's ord (TermStates.java:178-181):Index 1 out of bounds for length 1when reader B has one segment (the run). TheTermQuerypath is this data's: every document has a vector, so the seed rewrites to the bareTermQuery; with other data or a kNN filter the seedWeightcan be aBooleanQuery's and the failure can look different (read, not run). - The sibling.
SeededKnnVectorQuery.rewrite(:119-134): whenseedWeightis null it buildsnew SeededKnnVectorQuery(..., createSeedWeight(indexSearcher), ...)and returnsrewritten.rewrite(indexSearcher); the original is untouched.
- One search:
toStringof the delegate goes fromseedWeight=nulltoseedWeight=weight(id:0);equalswith a fresh twin turns false;hashCodechanged (in every recorded run, and again after a second search). - A
HashMapthat stored a value under the query before the search no longer finds it afterwards (getreturns null whilesize()is still 1). - A
BooleanQuerywith the query as a clause, whosehashCodewas computed before the search, searched once, failsassert hashCode == computeHashCode()(BooleanQuery.java:770) under-ea; an unseeded Patience clause passes. - Searching the same object on reader A, then B, then A again returns the same top 5 as fresh queries each time.
Exposure and likelihood322 words
- Who. Code that builds
PatienceKnnVectorQuery.fromSeededQuery(...)ornew PatienceKnnVectorQuery(SeededKnnVectorQuery, ...). Solr'sDenseVectorFieldbuilds this combination when a request asks for a seed query and early termination, and its normal request parsing builds a fresh query object per request (read; Solr's caches and autowarming were not traced). DefaultIndexWriterConfigandIndexSearcher; one document is enough. - On every search (deterministic). The query's
equals/hashCodechange. That matters to code relying on query immutability: maps or caches keyed on the query object (aHashMaplookup executed), and composite queries that cache a hash computed before the search (BooleanQueryasserts under-ea; with-daits cached hash silently goes stale, not asserted). - Under overlapping searches on two different readers. One request fails with an
AssertionError(-ea) or anArrayIndexOutOfBoundsException(-da). Ways to get there: one cached or constant query object run in parallel against several indexes or shards in one JVM, or served by the old and the new searcher at once around an NRT refresh. - Not claimed. Lucene's own
LRUQueryCacheis not affected: kNN queries always rewrite toDocAndScoreQueryorMatchNoDocsQuerybefore caching. Sequential reuse on different readers returns correct hits (executed). Concurrent searches on the same reader should not fail (read, not executed); if their two searchers had different similarities, the seed could be scored with the other searcher's (aTermWeightkeeps its searcher'sSimilarity,TermQuery.java:43-58), which can change the HNSW entry points (read, not executed). The assertions-off runs used a 2-segment search A against a 1-segment search B; readers where the other one has as many segments or more were not run, so there is no silent-wrong-results claim. A searched query keeps the last search's seedWeightuntil the next rewrite; its size was not measured. - Likelihood: rare. The identity change is constant but hurts only callers that depend on it; the crash needs one object shared by overlapping searches on different readers.
One JUnit method on the public API: one document, one IndexSearcher.search(query, 1) with a seeded Patience query, then assertEquals against an identical, never-searched query. Deterministic, single thread; fails the same way with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestPatienceSeededQueryUnchangedBySearch extends LuceneTestCase {

  private static Query newQuery() {
    KnnFloatVectorQuery knn = new KnnFloatVectorQuery("v", new float[] {1, 1}, 1);
    TermQuery seed = new TermQuery(new Term("id", "0"));
    return PatienceKnnVectorQuery.fromSeededQuery(SeededKnnVectorQuery.fromFloatQuery(knn, seed));
  }

  public void testSearchDoesNotModifyQuery() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new StringField("id", "0", Field.Store.NO));
        doc.add(new KnnFloatVectorField("v", new float[] {1, 1}));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        Query query = newQuery();
        new IndexSearcher(reader).search(query, 1);
        // expected: still equal to an unsearched twin; actual: its delegate now holds a seedWeight
        assertEquals(newQuery(), query);
      }
    }
  }
}
cp $REPRO/TestPatienceSeededQueryUnchangedBySearch.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestPatienceSeededQueryUnchangedBySearch -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
- Expected
- After one search the query still equals an identical, never-searched query (
seedWeight=null). - Observed
- It does not: its delegate now prints
seedWeight=weight(id:0), with assertions on and off on main, and on every release from 10.3.0 to 10.6.0 (assertions on; also off on 10.3.0, 10.5.2 and 10.6.0).
More files, environment, full output312 words
The test sits in org.apache.lucene.search, as Lucene's own tests do, but uses only public API: PatienceKnnVectorQuery.fromSeededQuery, SeededKnnVectorQuery.fromFloatQuery, a plain IndexSearcher (not newSearcher), ByteBuffersDirectory and the default IndexWriterConfig. The mutation happens in rewrite, before any per-segment work; the runs used Lucene's normal randomized test environment (seed DEADBEEF for this test).
It shows the root defect only. The crash needs two threads searching one query object on two different readers at overlapping times; the study reproduced it with a latch-driven test (a QueryTimeout that never times out is used only as a pause hook), which fails on stock main and passes with the fix. The printed weight(id:0) and the TermQuery frames below come from this data (every document has a vector, so the seed rewrites to the bare TermQuery).
It compiles against 10.3.0 through 10.6.0 and main. On 10.2.x it fails earlier with a different, already fixed NPE; older releases have no such API.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with the fix: passes. Also fails on the 10.3.0-10.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
cp $REPRO/TestPatienceSeededQueryUnchangedBySearch.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestPatienceSeededQueryUnchangedBySearch -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
TestPatienceSeededQueryUnchangedBySearch > testSearchDoesNotModifyQuery FAILED
    java.lang.AssertionError: expected:<PatienceKnnVectorQuery{saturationThreshold=0.995, patience=7, delegate=SeededKnnVectorQuery{seed=id:0, seedWeight=null, delegate=KnnFloatVectorQuery:v[1.0,...][1]}}> but was:<PatienceKnnVectorQuery{saturationThreshold=0.995, patience=7, delegate=SeededKnnVectorQuery{seed=id:0, seedWeight=weight(id:0), delegate=KnnFloatVectorQuery:v[1.0,...][1]}}>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:929F307F483DC7CE]:0)
        at org.junit.Assert.assertEquals(Assert.java:146)
        at org.apache.lucene.search.TestPatienceSeededQueryUnchangedBySearch.testSearchDoesNotModifyQuery(TestPatienceSeededQueryUnchangedBySearch.java:51)
> Task :lucene:core:test FAILED

# the same with -Ptests.asserts=false

# the study's two-reader test on the same stock build (supporting evidence, not the repro):
#   -ea: Caused by: java.lang.AssertionError: The top-reader used to create Weight is not the same as the current reader's top-reader
#          at org.apache.lucene.search.TermQuery$TermWeight.scorerSupplier(TermQuery.java:122)
#          at org.apache.lucene.search.SeededKnnVectorQuery$SeededCollectorManager.newCollector(SeededKnnVectorQuery.java:321)
#          at org.apache.lucene.search.PatienceKnnVectorQuery.approximateSearch(PatienceKnnVectorQuery.java:203)
#   -da: Caused by: java.lang.ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1
# at org.apache.lucene.index.TermStates.get(TermStates.java:181) (same path)Weight.java:29-32: searching "does not modify a Query, so that a Query instance can be reused"; searcher-dependent state belongs in theWeight.- The sibling
SeededKnnVectorQuery.rewritebuilds the same seedWeightinto a new query and leaves itself unchanged. - #14688 made the field mutable to fix an NPE, never discussing reuse;
BooleanQuery's cached-hash assertion fails on it.
The full argument287 words
- Contract, current javadoc.
Weight.java:29-32: "The purpose of Weight is to ensure searching does not modify a Query, so that a Query instance can be reused. ... IndexSearcher dependent state of the query should reside in the Weight."search/package-info.java:442-445: "Any IndexSearcher dependent state should be stored in the Weight implementation, not in the Query class." - Core code relies on it.
BooleanQuerycaches its hash "since boolean queries are immutable" and asserts the cached value equals a recomputed one (BooleanQuery.java:760-772). - The non-mutating shape exists next door.
SeededKnnVectorQuery.rewrite(SeededKnnVectorQuery.java:119-134, from #14170) returns a new instance. - No decision recorded. #14688 changed
final AbstractKnnVectorQuery delegateinto a mutable field only to create the seedWeight; its body ("This makes sure those queries are tested together and query rewriting works properly") and its one review ("LGTM") never mention mutation, reuse or thread safety. No upstream test checks a query after searching it:TestPatience{Float,Byte}VectorQuery.testToStringassertstoStringon a new query and then rewrites it (:96/:106); with the randomly chosen seeded wrapper that rewrite runs the mutating path, but the test never looks at that object again, so the mutation goes unnoticed rather than being expected. - Upstream treats this class of bug as a bug. #10322 (LUCENE-9282, open,
type:bug): Surround parser queries changehashCode/equalson rewrite. #8041 (LUCENE-6984, fixed 2016): "queries should be considered immutable once created". #11467 (LUCENE-10431, open): Alan Woodward, "BooleanQuery is expecting all its subqueries to be immutable". On LUCENE-6369 (#7429) jpountz closed with "queries should now be immutable". Historical:lucene/CHANGES.txt:22476-22478(1.3 RC1), "Queries are no longer modified during a search. This makes it possible, e.g., to reuse the same query instance with multiple indexes from multiple threads."
The devil's-advocate check126 words
Strongest case: both classes are @lucene.experimental; Query.rewrite's javadoc (Query.java:72-83) never promises the query is left alone; sequential reuse still gives correct hits; so this is an internal detail plus a cache-key nit, and sharing one query object across concurrent searches on different readers is the caller's risk. The cross-model reviewers and the intended-behaviour verifier rated it weak.
Why it fails: the reuse guarantee is stated on Weight and in the package docs, not on rewrite, and it is what BooleanQuery's cached hash relies on; IndexSearcher is documented thread-safe (IndexSearcher.java:69-75), and neither class says its query is single-use or bound to a reader. @lucene.experimental waives API stability, not correctness, and the sibling class shows the non-mutating shape was available.
Recommended Build the seed Weight into a new query, as SeededKnnVectorQuery.rewrite does
Make delegate final; when the seeded delegate has no seed Weight, build one into a new SeededKnnVectorQuery and return a new, rewritten PatienceKnnVectorQuery, as SeededKnnVectorQuery.rewrite does (+9/-5). Both tests, the closest kNN suites and the whole core module pass. Trade-offs: subclass overrides are skipped for a seeded delegate; a caller-supplied seed Weight is used as given (untested).
if (delegate instanceof SeededKnnVectorQuery seededKnnVectorQuery
    && seededKnnVectorQuery.seedWeight == null) {
  SeededKnnVectorQuery withWeight =
      new SeededKnnVectorQuery(
          seededKnnVectorQuery.delegate,
          seededKnnVectorQuery.seed,
          seededKnnVectorQuery.createSeedWeight(indexSearcher),
          delegate.field, delegate.k, delegate.filter, delegate.searchStrategy);
  return new PatienceKnnVectorQuery(
          withWeight, field, k, filter, searchStrategy, saturationThreshold, patience)
      .rewrite(indexSearcher);
}
return super.rewrite(indexSearcher);
All options and trade-offs4 options · 639 words
One fix was built and run in a scratch worktree of 645d4fe14a20 (the study's fix sketch); the alternatives were not built.
Build the seed Weight into a new query, as SeededKnnVectorQuery.rewrite does (validated by the checks) (recommended)
Make delegate final. In rewrite, when delegate is a SeededKnnVectorQuery whose seedWeight is null, build a new SeededKnnVectorQuery with createSeedWeight(indexSearcher) and return a new PatienceKnnVectorQuery around it, rewritten. The original query is never changed.
if (delegate instanceof SeededKnnVectorQuery seededKnnVectorQuery
    && seededKnnVectorQuery.seedWeight == null) {
  SeededKnnVectorQuery withWeight =
      new SeededKnnVectorQuery(
          seededKnnVectorQuery.delegate,
          seededKnnVectorQuery.seed,
          seededKnnVectorQuery.createSeedWeight(indexSearcher),
          delegate.field, delegate.k, delegate.filter, delegate.searchStrategy);
  return new PatienceKnnVectorQuery(
          withWeight, field, k, filter, searchStrategy, saturationThreshold, patience)
      .rewrite(indexSearcher);
}
return super.rewrite(indexSearcher);
Trade-offs
- Same pattern as the sibling, and
finallets the compiler keep it that way. - Caller-supplied seed
Weight. ASeededKnnVectorQuerybuilt with the public constructor that takes aseedWeight(#14838) is now used as given, asSeededKnnVectorQueryalone does; the stock code always replaced it. The caller must then build thatWeighton the searcher that runs the query: one built on another reader fails the same way, and aTermWeightcarries theSimilarityof the searcher that built it (TermQuery.java:43-58). This path was not tested; add a test for it if you propose this fix. The next option keeps "always rebuild". - Subclasses. It rewrites into a plain
new PatienceKnnVectorQuery(...), so for a seeded delegate without a seedWeighta subclass's overrides (getKnnCollectorManager,approximateSearch, ...; possible since #14838 made the constructors public) are no longer used; the stock code ransuper.rewriteon the subclass instance itself. Executed: a probe subclass overridinggetKnnCollectorManagerpasses on stock and fails with this fix.SeededKnnVectorQuery.rewritehas the same limitation for its own subclasses. The weight-per-search option would avoid it (not built). - Cost. One extra small query object per search, as in
SeededKnnVectorQuery.rewrite. No public API change (delegateis private, the 7-argument constructor package-private).
What the checks validated
- Stock: the minimal test fails with assertions on and off; the study's two-reader test file (an identity test and the two-reader test) fails 2 of 2, on and off. With the fix: the minimal test passes 1/1 and that file 2/2, with assertions on and off.
TestPatienceFloatVectorQuery,TestPatienceByteVectorQuery,TestSeededKnnFloatVectorQuery,TestSeededKnnByteVectorQuery,TestKnnFloatVectorQuery,TestKnnByteVectorQuery,TestKnnByteVectorQueryMMapand the new test: 8 classes, 278 tests, 0 failures, with assertions on and off.- The whole core module (
:lucene:core:test, assertions on): 748 classes, 8,897 tests, 0 failures, 322 skipped. checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestpass (with the new test in place).- Not covered: every run builds the seeded delegate without a seed
Weight(fromSeededQuery/fromFloatQuery); the caller-supplied-Weightbranch and subclasses were not tested (see the trade-offs).
Build the new PatienceKnnVectorQuery around a SeededKnnVectorQuery with a fresh seed Weight unconditionally, and run AbstractKnnVectorQuery.rewrite on that new instance through a private helper (calling .rewrite on it would loop).
Trade-offs
Keeps the stock behaviour for a caller-supplied seed Weight; slightly more code; not run. Like the recommended fix, it rewrites into a plain PatienceKnnVectorQuery, so a subclass's overrides are not used for a seeded delegate.
Create the seed Weight per search and pass it down through the per-search collector manager instead of storing it in a SeededKnnVectorQuery.
Trade-offs
Fixes the pattern in both classes, takes seedWeight out of equals and keeps rewrite on the caller's instance (so subclass overrides keep working), but reworks SeededKnnVectorQuery, whose constructors that take a Weight are public since #14838. Larger change; not run.
A javadoc note "not reusable, not thread-safe".
Trade-offs
Contradicts Weight.java:29-32 and BooleanQuery's immutability assumption, and leaves the crash in place.
Solr's normal request parsing builds a fresh query object per request, so a remote client cannot make two searches share one object that way (Solr's caches and autowarming were not traced); the exposed applications are those that cache or share one query object across indexes or across an NRT refresh.
Code reading of PatienceKnnVectorQuery.rewrite in an AI-assisted review of the kNN query classes flagged an assignment to the query's own field. A small TLA+ model of two searches sharing that field gave a 4-state counterexample (one search uses the other's seed Weight), and a latch-driven JUnit reproduced both symptoms on the stock jar.
The method in full130 words
Method: code reading, then TLA+ model checking and JUnit (the study's "non-formal" tier, because the first signal was code reading). In a hunt unit (kNN query layer, 2026-10-25), the finder noticed that rewrite assigns the query's own field. It then wrote SharedDelegate.tla (49 lines): two searches share the field, each assigns its own seed Weight and later uses the field. TLC found the invariant OwnWeightOnly (a search only uses the Weight it built) violated by a 4-state trace (A assigns, B assigns, A uses B's Weight), and no error with the fix (16 distinct states). The finder then bridged it to the stock jar with a public-API JUnit that fixes the interleaving with latches. The minimal one-search test of this doc was cut down from that JUnit's first method.
No prior report found: searched 2026-10-25/26 (169 queries) and again on 2026-10-30 (GitHub issues and PRs, commits, the open PRs' changed files, dev@, java-user@, issues@ and commits@, the JIRA archive, downstream trackers, the web). Not fixed on upstream main 2f424fd428da. The same class of bug exists upstream in other queries.
Searches4 searches
Related, not reports of this bug: #14688 (the introducing change; mutation and reuse not discussed), #14170 (added createSeedWeight and the non-mutating SeededKnnVectorQuery.rewrite), #14838 and #14094 (public constructors; the class itself, with a final delegate then), #14694 (open, a score-tie test failure in the unseeded path), #16952 (open, touches only the bulk-score bound in SeededKnnVectorQuery), #16204, #16847 and #15708 (open, other lines of these files). Same class of bug in other code: #10322 (LUCENE-9282, open, type:bug), #11467 (LUCENE-10431, open), #8041 (LUCENE-6984, fixed 2016), #8134 (LUCENE-7078, open umbrella), LUCENE-7657. Downstream use with no report: SOLR-17813 / solr#3705 and SOLR-17814 / solr#3644 (Solr builds Patience over Seeded), elasticsearch#127223 (Patience only).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, apache/solr, Elasticsearch, OpenSearch, global) | 2026-10-25/26 and 2026-10-30 | scripted prior-report searches (class, method and symptom names; the bug class: rewrite mutates the query, reuse, the assertion and exception text) and 53 manual searches on 2026-10-30; 46 issue/PR queries and 24 manual searches earlier | no report of this bug; the related items above |
| Open apache/lucene PRs | 2026-10-26 and 2026-10-30 | changed files of all 413, then 408, open PRs | none fixes it; #16952, #16204, #16847 and #15708 touch other lines of these files |
| Mailing lists, JIRA archive, web | 2026-10-25/26 and 2026-10-30 | dev@, java-user@, issues@ and commits@ (48 queries, then 40), JIRA (9, then 8 plus 6 REST queries), web (12, then 12) | no report; list hits for the assertion text are commit notifications and a 2016 build failure |
| Upstream code | 2026-10-30 and 2026-10-31 | GitHub contents and commits APIs | main 2f424fd428da, branch_10_6, the 10.6.0 tag and branch_10_5 (2026-10-30), and branch_11x d0c0decc6606 and main again (2026-10-31), still have the mutable field and the assignment |
Introduced by #14688 (merged 2025-05-20, first released in 10.3.0), which made the field mutable while fixing an NPE on this path; in 10.2.x the combination could not be searched at all. Every release from 10.3.0 to 10.6.0 and main is affected; a commit-level shadow of #14688 onto 10.2.2 reproduces it.
Versions tested7 rows
f16e2f35902 (main) / e569483131c (branch_10x cherry-pick), apache/lucene#14688 "Fix patience knn queries to work with seeded knn queries" (tteofili; one review, "LGTM" by ChrisHegarty), changed final AbstractKnnVectorQuery delegate into the mutable private field and added the assigning rewrite; #14838 (2b47cd3cd69) later added constructor arguments to that call without changing the mutation. #14688 has no CHANGES.txt entry of its own. branch_10x was decommissioned by #16911 on 2026-10-29.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle and standalone, assertions on and off); the two-reader test fails |
| 10.6.0 | affected | the minimal test and the two-reader test fail, assertions on and off (release jars) |
| 10.3.0 to 10.5.2 (7 releases) | affected | the minimal test fails on 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1 and 10.5.2; the two-reader test on 10.3.0 (and by the study on 10.3.2 and 10.5.2) |
| 10.2.2 + the two #14688 files | commit-level | shadowing the cherry-pick's two main-source files onto the 10.2.2 jars removes the NPE and makes both tests fail with this bug's symptoms |
| 10.2.0, 10.2.1, 10.2.2 | different bug | the composed query cannot be searched (NPE, seedWeight is null, the bug #14688 fixed); a probe shows the query unchanged by a search |
| 10.1.0 and older, 9.x | no API | the test does not compile (no PatienceKnnVectorQuery) |
main 645d4fe14a20 with the fix | not affected | both tests pass; the closest kNN suites and the whole core module pass |
Cross-model reviews (executed), independent verifiers and an adjudication rate it real; the intended-behaviour case was rated weak each time. This doc's runs: the minimal and two-reader tests on stock main (fail) and with the fix (pass), the closest suites, lint and the whole core module.
Checks and verdicts261 words
Every check re-ran a repro on stock jars; the reviewer from another model family (OpenAI GPT-5.6) executed its own tests in the lenses.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | TLC counterexample (4 states) to OwnWeightOnly; latch-driven JUnit file (an identity test and the two-reader test) 2/2 fail with -ea and -da, 20/20 over 10 iterations; 10.3.0, 10.3.2, 10.5.2 fail; fix passes and 137 upstream tests pass. |
| cross-model refute review | real, high | Own byte-vector identity and two-reader tests fail on main (-ea, -da); unseeded and distinct-query controls pass; fix passes them and 76 Patience tests. |
| Independent reproducer | real | Own 8 tests with a different pause hook: the 2 claims fail, 6 controls pass (incl. sequential reuse on two readers); 20/20 over 20 iterations; 10.5.2 and 10.3.0 fail; fix passes 8/8. |
| Works-as-designed review | real, high | Own test fails 2 of 4 with both controls passing; fix passes; added the BooleanQuery cached-hash check (fails under -ea). |
| Devil's advocate | real | No intended, documented, misuse or unreachable argument survives; re-ran main and 10.5.2; 4/4 bounds and controls pass. |
| adjudication | confirmed, high | The independent reproduction's tests with seed 1CEB00DA: 2 of 8 fail (-ea, -da), 6 controls pass; the finder's 2/2 fail. |
| this doc | real | Gradle in a scratch worktree of 645d4fe14a20: minimal and two-reader tests fail on stock and pass with the fix (assertions on and off); closest suites, lint and the whole core module pass with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 515 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,362 words
- Registry title
- PatienceKnnVectorQuery over a SeededKnnVectorQuery stores a searcher-specific seed Weight in its own field during rewrite, so every search changes the query's equals/hashCode, and searching one query object concurrently on two different readers fails
- Area
- search / kNN query layer (PatienceKnnVectorQuery over SeededKnnVectorQuery)
- Priority
- Low, rank 699: Moved down from Medium: PatienceKnnVectorQuery.fromSeededQuery changes its equals/hashCode on every search and crashes only when one query object is searched on two readers concurrently, mostly a cache and immutability problem in experimental code that Solr's per-request objects avoid.
- Impact class
- crash
- Impact note
- Applications that compose the @lucene.experimental PatienceKnnVectorQuery.fromSeededQuery over a SeededKnnVectorQuery (Solr 10's DenseVectorField builds this when a seed query and early termination are both requested) see every search change the query object's equals/hashCode, with the default codec, IndexWriterConfig and searcher and one segment; the crash (AssertionError with -ea, ArrayIndexOutOfBoundsException at TermStates.get with -da) additionally needs the application to search the same query object on two different readers at overlapping times, while sequential reuse on different readers returns correct hits; no scale is needed, and it is in every release since 10.3.0.
- Summary
- You build PatienceKnnVectorQuery.fromSeededQuery(SeededKnnVectorQuery.fromFloatQuery(knnQuery, seedQuery)) and search it with IndexSearcher. You expect the query object to be unchanged by the search (Weight javadoc: 'searching does not modify a Query, so that a Query instance can be reused'), so it can be compared, cached and reused, including by several threads on different readers. Instead rewrite stores a new SeededKnnVectorQuery holding a seed Weight built for the current searcher in the query's own delegate field: after one search the query's hashCode has changed and it no longer equals an identical unsearched query, and when two searches of the same object on different readers overlap, the first one runs the other searcher's seed Weight on its later segments and fails with 'AssertionError: The top-reader used to create Weight is not the same as the current reader's top-reader' (-ea) or 'ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1' at TermStates.get (-da).
- Introduced
- f16e2f35902 (f16e2f35902d37e9de071cefc61e763d8cbe4249) on main, 10.x cherry-pick e569483131c, apache/lucene#14688 'Fix patience knn queries to work with seeded knn queries' (tteofili; one review, APPROVED 'LGTM' by ChrisHegarty; no general or inline comments): it changed 'final AbstractKnnVectorQuery delegate' to a mutable private field and added the rewrite override that assigns delegate = new SeededKnnVectorQuery(..., createSeedWeight(indexSearcher), ...) [read: git blame at 7cecf79523, file identical on ea57360912ed, puts line 45 and lines 296-304 and 310-312 in f16e2f35902; lines 305-309 (extra constructor arguments) come from #14838, 2b47cd3cd69, which does not change the mutation; git show f16e2f35902; gh pr view 14688; exec: the two main-source files of the cherry-pick (PatienceKnnVectorQuery.java, HnswQueueSaturationCollector.java) shadowed onto the 10.2.2 jars remove the earlier seedWeight-null NPE and make both symptoms appear with -ea and -da] (2025-05-20 (#14688 merged to main 2025-05-20T15:21:37Z))
- First affected version
- 10.3.0 (release tag 2025-09-13) [exec: the follow-up probe's identity check passes on 10.2.0 and 10.2.2 and fails on 10.3.0; read: git tag --contains e569483131c lists 10.3.0 as the first release]
- Affected versions
- 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 and main through ea57360912ed [exec: the finder repro fails 2/2 with the bug's own symptoms on each with -ea; -da also run on 10.3.0, 10.5.2 and main; the independent reproduction re-ran 10.5.2 (-ea, -da) and 10.3.0, the intended-behaviour check re-ran 10.5.2]; upstream main, branch_10x, branch_10_6 (10.6.0, released 2026-10-29) and branch_10_5 still declare the mutable field and assign it in rewrite on 2026-10-26 [read: GitHub contents API], so 10.6.0 (released 2026-10-29) has it, and 11.0.0 ships it unless fixed; not affected: 10.2.0, 10.2.1, 10.2.2 [exec: a search leaves the query unchanged there, but Patience over Seeded cannot be searched at all: NullPointerException 'seedWeight is null', the different bug that #14688 fixed, so the finder repro fails on 10.2.x for that other reason]; the API does not exist in 10.1.0 and older or in any 9.x release [exec: compile error on 9.12.3; read: no such files in the 10.1.0, 10.0.0 and 9.12.3 tags]; executed variants: float vectors (finder, the independent reproduction, the cross-model review, the intended-behaviour check, adjudication) and byte vectors (identity and concurrent tests, by the refute-lens cross-model reviewer only)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by TLA+/TLC
- Upstream and prior reports
- none found (searched 2026-10-25 by the finder, 2026-10-26 by the independent reproduction, the intended-behaviour check and the adjudication, and 2026-10-26 for the follow-up, read-only: scripted prior-report searches A and B with 46 GitHub issue/PR, 9 commit, 9 downstream-repo, 48 mailing-list (dev@, java-user@, issues@, commits@), 9 JIRA-archive and 12 web queries; 24 manual gh issue/PR searches, 4 gh code searches and 4 gh api reads covering apache/lucene, apache/solr, elastic/elasticsearch and opensearch-project; 4 Solr JIRA searches; the changed-file lists of all 413 open apache/lucene PRs; the full threads of #14688, #14838, #14094, #14226, #14170, #14197, #14084, #14195 and #14694; git history): no issue, PR, JIRA ticket, list thread or downstream report describes this defect, and no open PR fixes it (the only open PR touching PatienceKnnVectorQuery.java, draft #16204, adds a constructor comment); the code is unchanged on upstream main, branch_10x, branch_10_6 and branch_10_5 on 2026-10-26. Related, not this bug: #14688 (introducing change; mutation and thread safety not discussed), #14838, #14170 (introduced SeededKnnVectorQuery's non-mutating rewrite), #14094, #14226, #14694 (open, a different symptom in the unseeded path), #14195, #16847, #15708. Same bug class in other code (precedents with a different fix): #10322 (LUCENE-9282, open, type:bug: Surround parser queries change hashCode/equals on rewrite), #8041 (LUCENE-6984, fixed 2016), #8134 (LUCENE-7078, open umbrella from 2016 that predates the class), LUCENE-7657. Downstream use with no report: SOLR-17813/solr#3705 and SOLR-17814/solr#3644 (Solr's DenseVectorField builds Patience over Seeded), elasticsearch#127223 (Patience only). Limits: GitHub search is phrase-like and its code search was unreliable for elastic/elasticsearch; not finding a report is not proof
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner, and passes with the recommended fix; with the fix the study's two-reader test, the closest kNN suites, lint and the whole core module pass too. The minimal test also fails on the 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 and 10.6.0 release jars. Upstream main2f424fd428da(2026-10-30) has the same code (read). The study's earlier runs (finder, verifiers, adjudication) used mainea57360912ed, wherePatienceKnnVectorQuery.javais identical.
- Finding record
lucene/core/src/java/org/apache/lucene/search/PatienceKnnVectorQuery.java:45 (non-final delegate field), :197-204 (approximateSearch reads the field for every leaf), :224-237 (equals/hashCode include delegate), :296-311 (rewrite assigns delegate = new SeededKnnVectorQuery(..., createSeedWeight(indexSearcher), ...))lucene/core/src/java/org/apache/lucene/search/SeededKnnVectorQuery.java:119-134 (its own rewrite returns a new instance), :186-194 (equals/hashCode include seedWeight), :321 (seedWeight.bulkScorer on the caller's leaf)lucene/core/src/java/org/apache/lucene/search/Weight.java:28-31 and search/package-info.java:442-445 (contract: searching does not modify a Query; IndexSearcher-dependent state belongs in the Weight); BooleanQuery.java:760-772 (cached hash 'ok since boolean queries are immutable', asserted equal to the recomputed hash); IndexSearcher.java:69-73 (thread safety); lucene/CHANGES.txt:22441-22443 (historical 1.3 RC1 statement on query reuse across indexes and threads)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/PatienceKnnVectorQuery.java:43-45, :108-123, :196-204, :223-237, :296-312a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/SeededKnnVectorQuery.java:119-146, :148-157, :181-195, :311-321a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TermQuery.java:120-124; lucene/core/src/java/org/apache/lucene/index/TermStates.java:178-181a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/Weight.java:29-32; BooleanQuery.java:760-772
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/Weight.java:29-32; package-info.java:442-445; BooleanQuery.java:760-772; Query.java:72-83; IndexSearcher.java:69-75a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/SeededKnnVectorQuery.java:119-134a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/search/TestPatienceFloatVectorQuery.java:81-111 (testToString; rewrite at :96), TestPatienceByteVectorQuery.java:91-121 (rewrite at :106)a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:22476-22478
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/SeededKnnVectorQuery.java:85-105 (public constructors taking a seedWeight), :119-134; PatienceKnnVectorQuery.java:125-137 (package-private constructor)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TermQuery.java:43-58 (TermWeight keeps its searcher's Similarity)
- TestPatienceSeededQueryUnchangedBySearch.java (one test, public API):
repro/LFV-125/src/org/apache/lucene/search/TestPatienceSeededQueryUnchangedBySearch.java(55 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed probes.
assets/LFV-125/bug.png(515 KB)