Lucene skips the per-field schema check for a frozen FieldType instance that already passed it. A rejected document leaves its type as the next candidate for that cache, and addBatch, after validating its own column, caches that candidate. Until the next flush, documents with the rejected type skip the check.
- Per-field schema. The first document with a field fixes its data structures: vector dimension and similarity, doc-values type, points. A later document with different ones is rejected with
IllegalArgumentException, and the writer stays open. - Frozen-type cache (10.5.0). To save work, Lucene remembers a frozen
FieldTypeinstance once a document using it passed that check, and skips the check when the next document uses the same instance. addBatch(10.5.0, experimental).IndexWriter#addBatchindexes aColumnBatchcolumn by column instead of document by document, and validates each column against the field's schema too.
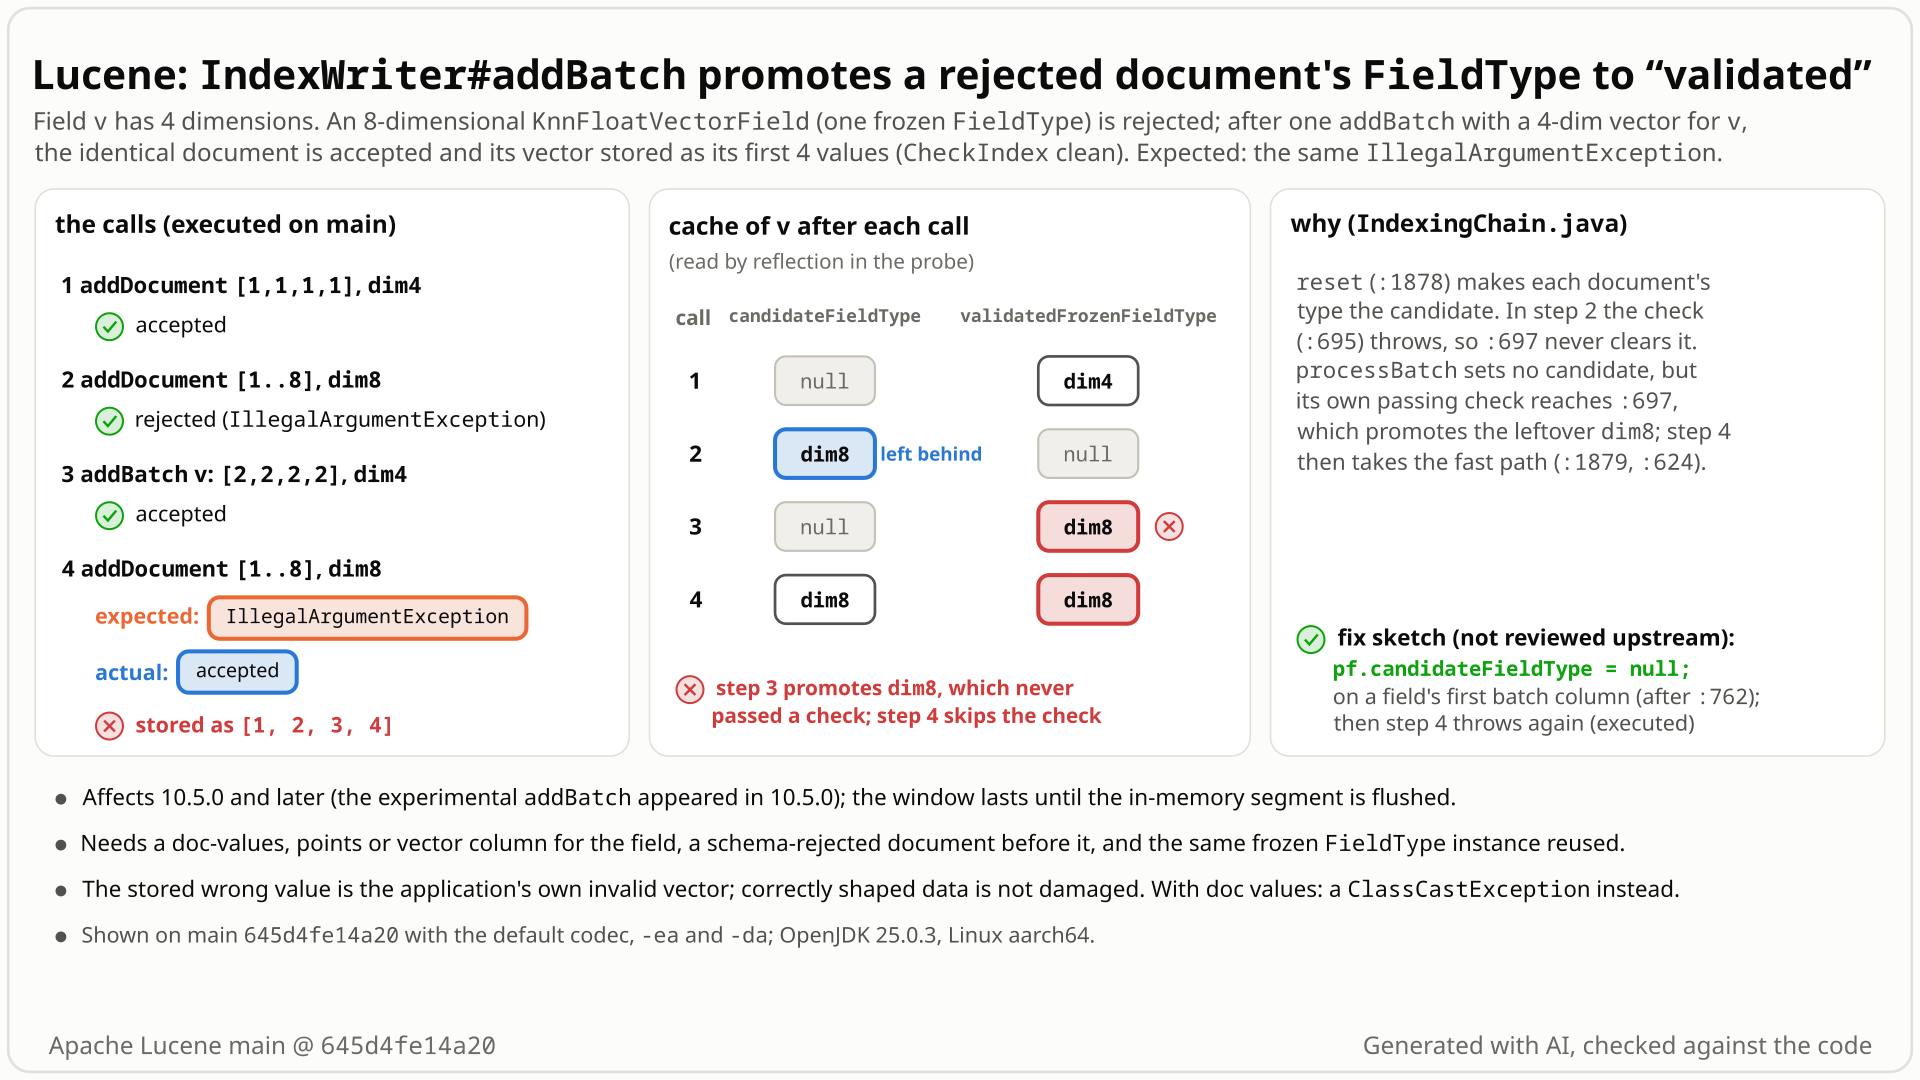
addBatch, and what the next document with that type stores. Select the still to open it at full size. Generated with AI, checked against the code.- Field
vholds 4-dimensional vectors. You add a document whoseKnnFloatVectorFielduses one shared 8-dimensional type,KnnFloatVectorField.createFieldType(8, EUCLIDEAN). Lucene rejects it:vector dimension: expected '4', but it has '8'. - You index an
addBatchwith one valid 4-dimensional vector forv, then add the same 8-dimensional document again. You expect the sameIllegalArgumentException. - Instead it is accepted: an input of
[1, 2, 3, 4, 5, 6, 7, 8](in the study's longer tests) is stored as[1, 2, 3, 4]andCheckIndexfinds no problem. Every document with that type is let through until the next flush. - Why: Lucene skips the check for a frozen
FieldTypeit has already validated. The rejected document left its type as the cache's candidate, and the batch, after validating its own column, cached that candidate. - Doc values too: a
SortedDocValuesFieldon a NUMERIC field then fails withClassCastExceptioninstead of the schema error. Clearing the candidate inaddBatch(3 lines) fixes both.
Applications on 10.5.0 and later that use the experimental addBatch with a doc-values, points or vector column for a field they also fill with addDocument, keep indexing after a schema-mismatch rejection, and reuse the rejected frozen FieldType (a cached createFieldType result, or the stock *DocValuesField.TYPE constants) before the next flush. Default config and codec.
Mechanism, terms and numbers886 words
Since 10.5.0 Lucene skips the per-field schema check for a document whose field uses a frozen FieldType instance that already passed the check in the current in-memory segment. A document that fails the check leaves its type behind as the cache's candidate, and the experimental IndexWriter#addBatch, which sets no candidate of its own before that point, promotes it after validating its own column for that field. From then until the next flush, every document with the rejected type instance skips the check: with the default codec an 8-dimensional vector is accepted into a 4-dimensional field and stored as its first 4 values, with CheckIndex clean, and a SortedDocValuesField on a NUMERIC field fails with ClassCastException instead of the schema IllegalArgumentException. The root cause came with the columnar API (#15990); the reported form needs #16219 and #16171; all ship in 10.5.0, 10.5.1, 10.5.2 and 10.6.0 and are on main. A 3-line fix in processBatch was validated.
- The cache. Each
PerFieldkeepsvalidatedFrozenFieldTypeandcandidateFieldType(IndexingChain.java:1853-1859).PerField.reset(:1876-1886), called for each field of each document (:623), first setscandidateFieldType = fieldType(:1878); for a type other than the cached one it clears the cache and the per-document schema (:1879-1885). - The check. A field without a cached type is collected for validation (
:624-626) and its per-document schema is built (:635-637).initAndValidateFields(:685-699) runsassertSameSchemaagainst the field'sFieldInfo(:695; vector dimension at:2354) and only thentrySetValidatedFrozenFieldType(:697), which caches the candidate if it is a frozenFieldTypeand clears it (:1892-1898). - The leftover. For the 8-dimensional document
assertSameSchemathrows,:697is not reached, and the rejected type stays as the candidate. On the row path that is harmless: the next document'sresetoverwrites it before anything is promoted. - The promotion.
processBatch(:717), on a field's first column (:758-765), resets the field's schema (:763) but not the candidate, builds the schema from the column's type (:779) and callsinitAndValidateFields(:784). The valid 4-dimensional column passesassertSameSchema, and:697caches the leftover 8-dimensional type. The batch sets no candidate of its own before this promotion (with a stored or inverted column, its row pass sets one at:914, afterwards; the repro's batch has none). - The skipped check. The next document with that instance matches the cache in
reset(:1879), is not collected for validation (:624) and builds no schema (:635).processField(:1456-1470) dispatches on the document's own type:indexVectorValue(:1765-1779) passes the 8 values to the writer made for the 4-dimensional field, and the flat vectors writer copies the firstdimof them (Lucene99HnswVectorsWriter.java:832,Lucene99FlatVectorsWriter.java:498,ArrayUtil.copyOfSubArray(value, 0, dim)at:468). For doc values,indexDocValuecasts the NUMERIC writer toSortedDocValuesWriter(:1746). - How long. Until the in-memory segment is flushed (commit, NRT reopen or flush): a new segment starts with fresh
PerFieldstate.
A one-off copy of the minimal test that adds [1..8] and reads the vectors back prints stored: [0.0, 0.0, 0.0, 0.0][0.0, 0.0, 0.0, 0.0][1.0, 2.0, 3.0, 4.0] on 645d4fe14a20. The finder's test, re-run there through gradle: 8-dimensional vector accepted into a 4-dimensional field (seqNo=3); stored vectors: [1.0, 1.0, 1.0, 1.0] [2.0, 2.0, 2.0, 2.0] [1.0, 2.0, 3.0, 4.0] for the input [1..8]; an independent reproducer's own test found CheckIndex clean=true; FieldInfo dim=4 (on ea57360912ed). The doc-values form: ClassCastException: class org.apache.lucene.index.NumericDocValuesWriter cannot be cast to class org.apache.lucene.index.SortedDocValuesWriter, with the stock static SortedDocValuesField.TYPE; the writer stays open and has no tragic exception (the independent reproduction and the adjudication).
Controls (independent reproducers): without the addBatch, with an addBatch on another field, or with an addBatch but no earlier rejected document, the 8-dimensional document is rejected every time; after a commit it is rejected again.
- New segment. The rejected document can be the first document after a commit; the 8-dimensional vector is still accepted and truncated.
- Partial schema. A document rejected because of another field, before
fhas aFieldInfo, leavesf's type as the candidate; the firstaddBatchforf(points + SORTED_NUMERIC) caches it, and a later SORTED_NUMERIC-only document is accepted into the points + SORTED_NUMERIC field. This form exists since #15990. - Every per-field check is skipped, not just the dimension: in the follow-up's probe an exact zero vector with a EUCLIDEAN type was accepted into a COSINE field.
- Not reachable this way: a stored or inverted column for the field in the batch re-runs
PerField.resetin the row pass (:912-915), after the promotion at:784; for a column type that is a different instance from the promoted one,resetdrops the just-promoted cache again (:1879-1885,validatedFrozenFieldType = nullat:1883). The probe's term-vector mismatch stayed rejected.
The study's bounded-exhaustive harness (123,424 document/addBatch/document triples on ea57360912ed) found 1,384 mismatching sequences on stock. This fix alone removes all 816 wrong-exception sequences and 56 of the 276 accepted-although-invalid ones; the other 512 go with two sibling defects in the same validation state (LFV-116 and LFV-118), and 0 remain with all three fixes.
Exposure and likelihood389 words
- Who. Applications on 10.5.0 and later that use the experimental
IndexWriter#addBatch(orupdateDocuments(Term, ColumnBatch), which reaches the sameprocessBatchby code reading; not run) with a doc-values, points or vector column for a field they also fill throughaddDocument; that keep indexing after Lucene rejects a document for a per-field schema mismatch on that field (a mis-sized embedding, a vector with the wrong similarity, a mixed-up doc-values class) while its field uses a reused frozenFieldTypeinstance (a cachedKnnFloatVectorField.createFieldTyperesult, or the stock staticNumericDocValuesField.TYPE/SortedDocValuesField.TYPE); and that reuse the instance before the next flush. - Not hit.
KnnFloatVectorField(name, vector, similarity)makes a new type for every field, so it never matches the cache. Releases before 10.5.0 have noaddBatch. - What it costs. With the default codec a larger wrong-dimension vector is stored as its first
dimvalues, withCheckIndexclean; a smaller one is rejected withArrayIndexOutOfBoundsExceptioninstead of the schema error. Scalar-quantized vector formats (2 of the 3 probed) reject both withArrayIndexOutOfBoundsException. Doc values: aClassCastExceptioninstead of the schemaIllegalArgumentException; the document is still rejected and the writer stays open. (In the harness, an indexedStringFieldtype promoted into a doc-values-only field failed with aNullPointerExceptioninstead.) - Other documents. Stored vectors of other documents never changed and the writer never closed with assertions off (probe: 300 later documents, commit, a second segment,
forceMerge(1), 3 vector formats). But the similarity check is skipped too: an exact zero vector with a EUCLIDEAN type reached a COSINE field, and 19 of 100 kNN self-queries for other documents of that segment missed with the default codec (100 of 100, and aCheckIndexfailure, with the scalar-quantized HNSW format). With assertions on, that format's next flush can fail with anAssertionErrorthat closes the writer as a tragic event (test configuration only). LFV-046 (tiny-norm COSINE vectors) reaches the same effect without these preconditions. - Conditions. Default
IndexWriterConfigand codec, assertions on and off, ordinary scale: one rejected document and one one-document batch suffice. Only single-threaded runs. - How likely: rare. It needs the experimental API on the same field as
addDocument, a schema-mismatch rejection the application survives, and the same type instance again before a flush. Mapping layers that check dimensions before Lucene make the rejection itself unusual (Elasticsearch does, by code reading).
One JUnit test, one method, single thread, deterministic, public API: give field v 4 dimensions, have an 8-dimensional document rejected, run a one-document addBatch with a 4-dimensional vector column, then add the 8-dimensional document again; it must be rejected again.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.document.column.Column;
import org.apache.lucene.document.column.ColumnBatch;
import org.apache.lucene.document.column.ObjectTupleCursor;
import org.apache.lucene.document.column.VectorColumn;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestAddBatchRejectedFrozenType extends LuceneTestCase {

  public void testWrongDimensionStaysRejectedAfterAddBatch() throws Exception {
    FieldType dim4 = KnnFloatVectorField.createFieldType(4, VectorSimilarityFunction.EUCLIDEAN);
    FieldType dim8 = KnnFloatVectorField.createFieldType(8, VectorSimilarityFunction.EUCLIDEAN);
    List<KnnFloatVectorField> bad = List.of(new KnnFloatVectorField("v", new float[8], dim8));
    ColumnBatch oneDim4Vector =
        new ColumnBatch() {
          @Override
          public int numDocs() {
            return 1;
          }

          @Override
          public Iterable<Column> columns() {
            return List.of(
                new VectorColumn<float[]>("v", dim4, Column.Density.SPARSE) {
                  @Override
                  public ObjectTupleCursor<float[]> tuples() {
                    return new ObjectTupleCursor<>() {
                      int doc = -1;

                      @Override
                      public int nextDoc() {
                        return ++doc == 0 ? 0 : DocIdSetIterator.NO_MORE_DOCS;
                      }

                      @Override
                      public float[] value() {
                        return new float[4];
                      }
                    };
                  }
                });
          }
        };
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      w.addDocument(List.of(new KnnFloatVectorField("v", new float[4], dim4)));
      expectThrows(IllegalArgumentException.class, () -> w.addDocument(bad));
      w.addBatch(oneDim4Vector);
      // expected: the 8-dim document is rejected again; actual: it is accepted (stored truncated)
      expectThrows(IllegalArgumentException.class, () -> w.addDocument(bad));
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests TestAddBatchRejectedFrozenType -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- The second
addDocument(bad)throwsIllegalArgumentException(vector dimension: expected '4', but it has '8'), like the first. - Observed
- It is accepted:
AssertionFailedError: Expected exception IllegalArgumentException but no exception was thrownat line 75, with assertions on and off.
More files, environment, full output305 words
The test sits in org.apache.lucene.index, as Lucene's own tests do, but uses no package-private API. The batch is a small anonymous ColumnBatch with one sparse VectorColumn; the codec is pinned to the default codec and the directory is a ByteBuffersDirectory, so the outcome does not depend on the seed. Line 72 (the first expectThrows, before the batch) passes; only line 75 fails.
The stored-value check ([1..8] stored as [1, 2, 3, 4], CheckIndex clean) and the doc-values form are shown by the study's longer tests (in the collapsed explanation above); they are not part of this repro.
Regression test: this same test; it passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with the fix: passes. Also fails on the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
cp $REPRO/TestAddBatchRejectedFrozenType.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestAddBatchRejectedFrozenType -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed; -Ptests.asserts=false identical)
TestAddBatchRejectedFrozenType > testWrongDimensionStaysRejectedAfterAddBatch FAILED
    junit.framework.AssertionFailedError: Expected exception IllegalArgumentException but no exception was thrown
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:AAAE0EF6A92D1D49]:0)
        at app//org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1432)
        at app//org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1418)
        at app//org.apache.lucene.index.TestAddBatchRejectedFrozenType.testWrongDimensionStaysRejectedAfterAddBatch(TestAddBatchRejectedFrozenType.java:75)
1 test completed, 1 failed

# the study's longer tests on the same stock build (gradle, seed DEADBEEF): 7 tests completed, 5 failed, both controls pass
TestAddBatchCachesRejectedFieldType > testVectorOfWrongDimensionAcceptedAndTruncated
    java.lang.AssertionError: 8-dimensional vector accepted into a 4-dimensional field (seqNo=3); stored vectors: [1.0, 1.0, 1.0, 1.0] [2.0, 2.0, 2.0, 2.0] [1.0, 2.0, 3.0, 4.0]
TestAddBatchCachesRejectedFieldType > testDocValuesTypeMismatchNotReportedAsSchemaError
    junit.framework.AssertionFailedError: Unexpected exception type, expected IllegalArgumentException but got java.lang.ClassCastException: class org.apache.lucene.index.NumericDocValuesWriter cannot be cast to class org.apache.lucene.index.SortedDocValuesWriter
TestAddBatchStaleCandidateNewSegment > testVectorRejectedInNewSegmentThenBatch     same vector message (seqNo=5)
TestAddBatchStaleCandidateNewSegment > testDocValuesRejectedInNewSegmentThenBatch  same ClassCastException
TestAddBatchPromotesCandidateOfUninitializedField > testCandidateOfRejectedDocumentPromotedByFirstBatch
java.lang.AssertionError: ACCEPTED: a SORTED_NUMERIC-only document was accepted into a points+SORTED_NUMERIC field- The same writer rejects the identical document one call earlier; the
FieldSchemajavadoc says "If there is inconsistency, we raise an error." - The cache (#15886) exists to "skip redundant schema validation" and promotes a type only "if it is frozen and valid"; this one failed validation.
- Upstream tests expect
IllegalArgumentExceptionfor exactly these changes (testIllegalDimChangeTwoDocs,testFrozenFieldTypeTransitionAcrossDocuments).
The full argument213 words
- One call earlier it is rejected. The repro's first
expectThrows(before the batch) passes; only the batch in between changes the outcome. - The contract. The
FieldSchemajavadoc: "If there is inconsistency, we raise an error. This ensures that a field has the same data structures across all documents." (IndexingChain.java:2208-2216).MIGRATE.md:1557-1564: "The per field data-structures are implicitly defined by the first document indexed that contains a certain field. Once defined, the per field data-structures are not changeable for the whole index." TheKnnFloatVectorFieldjavadoc: "Vectors of a single field share the same dimension and similarity function". - The cache was meant to skip only redundant work.
CHANGES.txt(10.5.0): "Cache frozen FieldType to skip redundant schema validation" (#15886). That commit's comment on the candidate: "This will be promoted in trySetValidatedFrozenFieldType if it is frozen and valid". A type that failed validation is neither. - Upstream tests.
BaseKnnVectorsFormatTestCase.testIllegalDimChangeTwoDocs(same segment) andTestIndexOptions.testFrozenFieldTypeTransitionAcrossDocuments(two frozen types) expectIllegalArgumentException. None of the frozen-type tests callsaddBatch. - Precedent. #16708 ("Validate vector values in columnar addBatch", merged 2026-09-28; CHANGES 10.6.0, Improvements) closed an earlier gap where
addBatchaccepted vectors thataddDocumentrejects, by adding the same checks to the column path. No discussion on #15886, #16171, #16219 or #15990 mentions rejected documents or promotion from a batch.
The devil's-advocate check113 words
The strongest case: addBatch is @lucene.experimental, the wrong-dimension document is the application's own mistake, and the cache trusts type identity, so reusing a type Lucene rejected is misuse.
Why it fails: @lucene.experimental is about API stability ("This API is experimental and might change in incompatible ways in the next release"), not about relaxing checks for later addDocument calls. Lucene enforces the rule itself and rejects the identical document one call before the batch, so the input is outside what the API accepts. The doc-values form triggers with Lucene's own static TYPE constants, which every application reuses. The checkers who argued this side (a GPT-5.6 reviewer and a devil's-advocate verifier) rated it weak.
Recommended Drop any pending candidate on a field's first column in processBatch (validated)
In IndexingChain.processBatch, set pf.candidateFieldType = null on a field's first column (3 lines): the batch sets no candidate of its own before it validates and promotes, so it can no longer cache one a failed document left behind. The repro, the study's longer tests, the closest suites and the whole core module pass.
        pf.fieldGen = batchGen;
        pf.columnFeatures = (byte) columnFeatures;
        // a column's type is not a candidate for the frozen-type cache; drop any candidate left
        // behind by an earlier document that never reached (or failed) validation
        pf.candidateFieldType = null;
        pf.schema.reset(baseDocID);
All options and trade-offs3 options · 541 words
Option A was built and run. B and C are alternatives from the verifiers' notes and this brief; they were not run.
Right where processBatch starts a fresh schema for a field (IndexingChain.java:758-765), clear the cache candidate before the batch validates and promotes. This is the finder's fix, rebased onto 645d4fe14a20 with a 2-line offset.
        pf.fieldGen = batchGen;
        pf.columnFeatures = (byte) columnFeatures;
        // a column's type is not a candidate for the frozen-type cache; drop any candidate left
        // behind by an earlier document that never reached (or failed) validation
        pf.candidateFieldType = null;
        pf.schema.reset(baseDocID);
Trade-offs
- Local. One line in
processBatch, which promotes without having set a candidate (the other promotion call, for the reserved parent field, never sees a candidate:resetis never called on it, and documents and batches cannot use that field). It covers the same-segment, new-segment and partial-schema forms. - No change on the happy path, apart from at most one lost cache hit. A candidate still pending when a batch starts a field is the leftover of a document that did not pass validation, a type that is already cached, or the column type that an earlier batch's row pass recorded (a stored or inverted column,
IndexingChain.java:914->:1878), which on stock the next batch for that field promotes at:697. Clearing it leavesvalidatedFrozenFieldTypeas it was; in the last case the next valid document with that type is checked once and then cached, as today. - The stale state itself stays. A failed document still leaves its candidate behind; any future caller of
trySetValidatedFrozenFieldTypethat does not set a candidate first needs the same care (options B and C).
What the checks validated
Applied to a scratch worktree of 645d4fe14a20 and run through gradle with OpenJDK 25.0.3, seed DEADBEEF (2026-10-30):
- stock: the minimal test fails with assertions on and off; the study's three longer test classes fail 5 of 7 (both controls pass);
- with the fix: the minimal test passes with assertions on and off; the three longer classes pass 7 of 7 with assertions on and off;
- the closest suites
TestIndexOptions,TestColumnBatchIndexingand the sixorg.apache.lucene.document.columntest classes pass (180 tests, 0 failures); - the whole
:lucene:core:testpasses (748 classes, 8,897 tests, 0 failures, 322 skipped);checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainfor core pass.
In processDocument, on any exception from the first pass or initAndValidateFields (IndexingChain.java:611-642), set candidateFieldType = null on every PerField the document touched.
Trade-offs
Removes the stale state at its source, so future callers are safe too; but it must cover every throw site of the first pass (reserved field name, updateDocFieldSchema, initializeFieldInfo, assertSameSchema), including the partial-schema case where the failing field is not the poisoned one.
Pass the type that processDocument just validated to the promotion (or record the candidate only after validation), and let processBatch validate without promoting.
Trade-offs
Removes the hidden coupling between reset and the promotion that this bug came from; a larger change to code #16171 tuned for performance, so it would want a benchmark.
Downstream relevance only: an application that picks a document's Lucene field type from submitted content (for example a vector type by vector length) and leaves the mismatch check to Lucene could let a submitter store a truncated vector, or a zero vector that degrades kNN on a COSINE field; Elasticsearch checks dimensions before Lucene (code reading).
While extending an Alloy 6.2 model of the per-segment frozen-type cache, the finder read that processBatch calls the promotion without setting a candidate. The Alloy check BatchStaleCandidate gave a 3-step counterexample (a rejected document, an addBatch, the same document accepted); a bounded-exhaustive harness on the real jar and a public-API JUnit confirmed it.
The method in full188 words
Method: semi-formal (the finder tagged it formal): a hypothesis from code reading, witnessed by a model checker and then by executed tests.
- First signal. Extending the unit's Alloy 6.2 model of the
FieldSchema/PerFieldfrozen-type cache with theprocessBatchstep, the finder noticed in the code thatprocessBatchcallstrySetValidatedFrozenFieldTypewithout settingcandidateFieldTypefirst. - Alloy. The check
BatchStaleCandidate(the row-path fixes on, the batch fix off) is satisfiable in the full and the small universe: a 3-step counterexample, a rejected document, anaddBatchfor the same field, then the same document accepted. With all three fixes of the unit,FixedLocalis unsatisfiable in the small universe (3 FieldTypes, 3 documents, 4 states); the same check in the full universe and a deeper small-universe bound timed out at 3000 s. - Real jar. A bounded-exhaustive differential harness ran every (document,
addBatchwith a NUMERIC column, document) triple, 123,424 sequences, and found 1,384 mismatches on stock. - JUnit. The finder's public-API test showed the silent vector truncation and the doc-values
ClassCastException; independent verifiers wrote their own tests; the minimal repro above is the vector case cut down to one assertion.
None found: no issue, PR, list thread or downstream report describes a rejected document's type being cached through addBatch (searched 2026-10-25/26, re-checked 2026-10-30). Closest: #16171, a different (performance) defect in the same cache whose fix widened when promotion happens, and #15886, which added the cache.
Searches3 searches
- #15886 (merged 2026-04-07): added the cache; describes it as skipping redundant validation; failed documents and
addBatchare not discussed. - #16171 (merged 2026-06-13): a different, performance defect in the same cache (it never re-cached after a type switch). Its fix records the candidate for every document and promotes after every successful check, which this trigger uses.
- #16219, #15990 / #16066: the batch validation call; their reviews do not mention the cache candidate.
- #16708 / #16732: precedent, an
addBatch/addDocumentvalidation gap that was closed (CHANGES 10.6.0, Improvements; a different gap). - #15125, #16553: other state left behind by a failed document (different state, both fixed).
- #16734 (merged 2026-10-26): the bulk vector path of
addBatch; does not touch the cache, and the bug reproduces after it. - Same family in the registry: LFV-116 (a rejected document's skip-index type stays in the per-document schema) and LFV-118 (the cache keys a multi-type field on its first value's type): same validation state, different fix sites.
- Limits: GitHub's search rate limit capped some tool runs, GitHub search reads only the first page per query, and private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Elasticsearch, OpenSearch, Solr) | 2026-10-25 and 2026-10-26 | a scripted prior-report search in 5 runs (identifiers, symptoms, failure framing, hand-written phrasings) and 142 manual searches (41 phrasings on apache/lucene, 10 on each downstream project, issues and PRs); the conversations and inline review comments of #15886, #16171, #16219, #15990, #16118, #16708, #16734, #16553 and #15125; the changed files of all 412 open PRs and of the 434 PRs closed since 2026-06-13 | related items only (#15886, #16171, #16219, #15990, #16708, #15125, #16553, #16734); none the same bug |
| Mailing lists (dev@, java-user@, issues@, commits@), JIRA archive, web | 2026-10-25 and 2026-10-26 | 20 list queries per tool run plus direct queries on dev@ and java-user@ over a year; the 9-mail dev@ design thread of the column API; JQL queries; 26 web queries | no report |
| Re-check (apache/lucene) | 2026-10-30 | gh search issues and prs for candidateFieldType, validatedFrozenFieldType, trySetValidatedFrozenFieldType, "frozen FieldType", addBatch, ColumnBatch; commits to IndexingChain.java on main and branch_10_6 | no new item; no IndexingChain.java commit after #16734 |
Root cause in #15990 (3d895681557, 2026-05-14), the columnar API; the reported form first fails at #16219 (1a6f4040dc6, 2026-06-14) and needs #16171. All shipped first in 10.5.0. Fails on 10.5.0 to 10.6.0 and main; releases before 10.5.0 have no addBatch.
Versions tested7 rows
Root cause: 3d895681557 "Add experimental columnar indexing api (#15990)" (Tim Brooks, merged 2026-05-14; 10.x backport #16066, 3ec3bff01b1): its processBatch already called trySetValidatedFrozenFieldType without setting a candidate. At that commit only the partial-schema form is reachable (the follow-up's probe fails there, and passes with a commit-local fix); the finder's test does not reach the bug there, because its batch after the rejected document is itself rejected.
Reported form: first fails at 1a6f4040dc6 "Allow multiple addBatch columns per field name (#16219)" (Tim Brooks, merged 2026-06-14; 10.x ae74896dd37), which made processBatch reset the field's schema and validate through initAndValidateFields. It also needs 3ca085e1c77 (#16171, neoremind, merged 2026-06-13; 10.x eccb3394382), which made reset record a candidate for every document and initAndValidateFields promote after every successful check: 1a6f4040dc6 with #16171's IndexingChain hunks reverted (a counterfactual) passes the finder's test. The new-segment form needs only #15990's promotion and #16219's schema reset: it still fails in that counterfactual.
The cache itself: 9e1c6a37c6e (#15886, Tim Brooks, 2026-04-07); not affected without addBatch (code reading).
Not fixed: upstream main 2f424fd428da (2026-10-30) has no commit to IndexingChain.java after #16734 (2026-10-26), which the tested commit contains; branch_10_6's last is #16732 (2026-09-28).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, assertions on and off (gradle and standalone); the study's longer tests fail 5 of 7; all pass with the fix |
| 10.6.0 | affected | minimal test fails, assertions on and off (release jars) |
| 10.5.2 | affected | minimal test and the finder's test fail, assertions on and off |
| 10.5.0, 10.5.1 | first affected | the finder's test fails 2 of 2 (10.5.0 also with assertions off) |
main 1a6f4040dc6 (#16219) | bisect | the reported form first fails here; with #16171 reverted it passes |
main 3d895681557 (#15990) | root cause | only the partial-schema form fails; in the finder's test the second batch is itself rejected (the minimal test was not run here) |
| 10.4.0, 9.12.3, parent of #15990 | no such API | the tests do not compile: no addBatch |
Reproduced by independent reproducers with their own tests, a GPT-5.6 reviewer that ran its own regression test, an adjudication with a new seed, a re-run after #16734 and this doc's gradle runs; every check's controls pass and every fix check passes. No checker made a case that it is intended.
Checks and verdicts318 words
Each check ran its own tests or re-ran an earlier one on stock jars; a cross-model review could only read code.
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | Alloy counterexample BatchStaleCandidate; 123,424-sequence harness; its JUnit fails 2 of 2 on main, 10.5.0 and 10.5.2 with assertions on and off; its fix passes. |
| review (OpenAI GPT-5.6, refute lens, reading only) | real (high) | Agrees with the root cause and the fix. Two executed refute attempts gave no verdict . |
| Independent reproducer | real | Own test from the claim: 2 claim tests fail, 3 controls pass, 10 of 10 iterations, on main, 10.5.0 and 10.5.2; [1..8] stored as [1,2,3,4], CheckIndex clean; its own fix passes. |
| Works-as-designed lens (OpenAI GPT-5.6, executed) | real (high) | Intended argument weak; its own regression test fails on main and passes with the fix; 177 focused existing tests pass with the fix. |
| Intended-behaviour devil's advocate | real | Intended argument weak; its own test fails on main and 10.5.2, including the stock doc-values TYPE constants; controls: no bug with addDocument in between, none after a commit. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test with seed 5EEDA11: 2 of 5 fail with assertions on and off, the 3 controls pass; the fix passes 5 of 5. |
| Re-verification after #16734 | still reproduces | The finder's test fails 2 of 2 on a9779ef3c193; the independent reproduction's and the intended-behaviour check's dense-column tests needed an API adaptation and then fail as before. |
| Minimal repro on 645d4fe14a20 | verified | 1 of 1 fails with assertions on and off and two seeds; the fix passes. |
| This doc's fix validation | real; fix validated | Gradle in a scratch worktree of 645d4fe14a20: stock fails; the fix passes the repro, the longer tests, the closest suites and the whole core module. The minimal test also fails on the 10.6.0 and 10.5.2 release jars. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 431 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,377 words
- Registry title
- IndexWriter#addBatch marks the frozen FieldType of an earlier rejected document as validated, so later documents with that type skip the per-field schema check (a wrong-dimension vector is stored truncated)
- Area
- index / IndexingChain per-field schema validation (frozen-FieldType cache) x columnar addBatch
- Priority
- Low, rank 712: After a schema-rejected document, the experimental addBatch lets a reused frozen FieldType skip validation, so the application's own wrong-dimension vector is stored truncated (the credibility audit downgraded it); it is silent but harms only data that was already invalid.
- Impact class
- silent wrong results
- Impact note
- Applications on 10.5.0 and later that use the experimental IndexWriter#addBatch (updateDocuments with a ColumnBatch takes the same path by code reading) with a doc-values, points or vector column for a field that they also fill through addDocument, keep indexing after Lucene rejects a document for a per-field schema mismatch while that document's field uses a reused frozen FieldType instance (a cached KnnFloatVectorField.createFieldType result, or the stock static *DocValuesField.TYPE constants), and reuse that instance before the next flush; default IndexWriterConfig and codec, -ea or -da, ordinary scale (one rejected document and one batch suffice): the application's wrong-dimension vector is then persisted truncated with CheckIndex clean (scalar-quantized formats throw an unrelated ArrayIndexOutOfBoundsException instead), correctly shaped data is not damaged, and the doc-values form is only a wrong exception type.
- Summary
- You add a document whose 8-dimensional KnnFloatVectorField (built from one shared frozen FieldType) does not match the field's 4 dimensions, and Lucene correctly rejects it; you then index an IndexWriter#addBatch with a 4-dimensional vector column for the same field and add the same kind of 8-dimensional document again. You expect the same IllegalArgumentException, because Lucene requires a field to keep the same data structures in every document and checks each document against them. Instead the batch marks the rejected document's FieldType as already validated, so until the next flush every document with that FieldType instance skips the check: the 8-dimensional vector is accepted and stored as its first 4 values (CheckIndex clean), and a SORTED value for a NUMERIC doc-values field fails with ClassCastException instead of the schema error.
- Introduced
- 3d895681557 (#15990 'Add experimental columnar indexing api', by Tim-Brooks, merged 2026-05-14; 10.x backport #16066, 3ec3bff01b1): its processBatch calls PerField.trySetValidatedFrozenFieldType although it never sets candidateFieldType, so it promotes a candidate that an earlier rejected document left behind [exec: a partial-schema probe fails at 3d895681557 with -ea and -da and passes there with a commit-local fix; the candidate repro does not compile at its parent 227255fdb08]. The reported same-segment form first fails at 1a6f4040dc6 (#16219 'Allow multiple addBatch columns per field name', by Tim-Brooks, 2026-06-14; 10.x ae74896dd37), which made processBatch reset the field schema and validate through initAndValidateFields, on top of 3ca085e1c77 (#16171 'Address frozen FieldType cache never recovering after type switch', by neoremind, 2026-06-13; 10.x eccb3394382), which made PerField.reset record a candidate for every document and promote it after every successful check [exec: the candidate repro fails at 1a6f4040dc6 with -ea and -da, does not reach the bug at 87e60ad4905, 8a77a334aea or 3d895681557 (there the valid second addBatch is rejected instead), and passes at 1a6f4040dc6 with the #16171 IndexingChain hunks reverted (a counterfactual, not a real commit); read: git log -S and git blame]. The cache itself is 9e1c6a37c6e (#15886, 2026-04-07) and is not affected without addBatch [read]. (2026-05-14 (root cause, #15990); 2026-06-14 (reported same-segment form, #16219, after #16171 on 2026-06-13); 10.5.0 is the first release and contains all four commits)
- First affected version
- 10.5.0 [exec, -ea and -da]
- Affected versions
- 10.5.0, 10.5.1 and 10.5.2 (latest 10.5.x release) [exec: the candidate repro fails 2 of 2 on each, 10.5.0 and 10.5.2 also with -da; the new-segment variant and the partial-schema probe fail on 10.5.0 and 10.5.2]; main from 3d895681557 (narrow form) or 1a6f4040dc6 (reported form) through ea57360912ed, the upstream main head on 2026-10-26 [exec at the commits and at the head, -ea and -da]; the unreleased branch_10x and branch_10_5, and branch_10_6 (10.6.0, released 2026-10-29), carry the same code [read via the GitHub contents API, 2026-10-26], so 10.6.0 has it; not applicable: every release before 10.5.0, including 10.4.0 and 9.12.3, where addBatch does not exist (compile error) [exec]; not fixed upstream as of 2026-10-26 (the last IndexingChain.java change on main is #16708, 2026-09-28, which does not touch the cache) [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Alloy, exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, read-only: a scripted prior-report search in 5 runs (the finder's and runs A-D) over GitHub issues, PRs and commits of apache/lucene, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 142 manual gh searches (41 phrasings on apache/lucene and 10 on each of Elasticsearch, OpenSearch and Solr, each against issues and PRs); the conversations and inline review comments of #15886, #16171, #16219, #15990, #16118, #16708, #16734, #16553 and #15125 read directly; the changed-file lists of all 412 open PRs (the 6 that touch IndexingChain.java were read and none touches the cache) and of the 434 PRs closed since 2026-06-13; the 9-mail dev@ design thread of the column API; limits: GitHub's search rate limit capped some tool runs, GitHub search reads only the first page per query, private channels cannot be searched); related prior items, none of them this bug: #15886 (added the cache and describes it as skipping only redundant validation), #16171 (a different, performance defect in the same cache, whose fix records the candidate for every document and promotes it after every successful check, which this trigger uses), #16219 and #15990/#16066 (addBatch and its validation call), #16708/#16732 (precedent: an addBatch/addDocument validation gap fixed as a bug; a different gap), #15125 and #16553 (state left behind by a failed document; different state, both fixed), #15943 and #16309 (cache test flakes), #16734 (merged 2026-10-26 as a9779ef3c19; on main and branch_11x, not on branch_10_6; touches processVectorColumn, not the cache)
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner; with the recommended fix it passes, together with the study's three longer test classes, the closest suites and the whole core module. The minimal test also fails on the 10.6.0 and 10.5.2 release jars. The follow-up's version sweep and commit bisection ran on mainea57360912edand the 9.12.3 to 10.5.2 releases. Upstream main2f424fd428da(2026-10-30) has no later commit toIndexingChain.java.
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:619-640 (fast path), 683-697 (initAndValidateFields), 750-783 (processBatch), 1710-1723 (indexVectorValue), 1821-1831 (PerField.reset), 1837-1843 (trySetValidatedFrozenFieldType), 2154-2161 (FieldSchema javadoc); lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99FlatVectorsWriter.java:457 (copyOfSubArray(value, 0, dim)); lucene/core/src/java/org/apache/lucene/document/KnnFloatVectorField.java:92, 124; lucene/MIGRATE.md:1557-1563; lucene/CHANGES.txt:1058 (GITHUB#15886); lucene/core/src/test/org/apache/lucene/index/TestIndexOptions.java:246; lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseKnnVectorsFormatTestCase.java:190
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:611-642 (at 645d4fe14a20) (:623, :624-626, :635-637, :640-642), :685-699 (:695, :697), :717-785 (:758-765, :763, :779, :784), :912-915, :1456-1470, :1730-1747 (:1746), :1765-1779, :1853-1859, :1876-1886 (:1878, :1879-1885, :1883), :1892-1898, :2345-2359 (:2354)lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java:825-832; (at 645d4fe14a20) Lucene99FlatVectorsWriter.java:466-469 (:468), :487-498
- Who is affected
lucene/core/src/java/org/apache/lucene/document/KnnFloatVectorField.java:42-60 (at 645d4fe14a20) (createType), :70-76 (createFieldType, freeze at :74), :102-106; NumericDocValuesField.java:37-43; SortedDocValuesField.java:43lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1528-1556 (at 645d4fe14a20) (addBatch, @lucene.experimental at :1535; updateDocuments(Term, ColumnBatch))
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2208-2216 (at 645d4fe14a20)lucene/MIGRATE.md:1557-1564; (at 645d4fe14a20) lucene/CHANGES.txt:1091 (GITHUB#15886, 10.5.0 section :898-1297)lucene/core/src/java/org/apache/lucene/document/KnnFloatVectorField.java:92, (at 645d4fe14a20) :124lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseKnnVectorsFormatTestCase.java:190-206; (at 645d4fe14a20) lucene/core/src/test/org/apache/lucene/index/TestIndexOptions.java:246-272lucene/CHANGES.txt:537 (at 645d4fe14a20) (GITHUB#16708 under 10.6.0 Improvements, heading :529); build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:502 (meaning of @lucene.experimental)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:611-642 (at 645d4fe14a20) (:616-620 reserved parent field), :685-699, :758-765, :825-828 (parent field promotion), :912-915 (row-pass reset), :1876-1898
- Prior reports
GitHub API, read-only, 2026-10-30: repos/apache/lucene/commits?path=lucene/core/src/java/org/apache/lucene/index/IndexingChain.java (main: a9779ef3c193 #16734 2026-10-26; branch_10_6: 1408ee0f0238 #16732 2026-09-28); gh search issues/prs (this brief's re-check)
- History
lucene/CHANGES.txt:928, (at 645d4fe14a20) :1091, :1169, :1292 (all in the 10.5.0 section, :898-1297)
- TestAddBatchRejectedFrozenType.java (one test, public API):
repro/LFV-127/src/org/apache/lucene/index/TestAddBatchRejectedFrozenType.java(78 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and the study's executed tests.
assets/LFV-127/bug.png(431 KB)