FixedBitSet.ensureCapacity computes the grown length as words × 64 in an int. From 2^25 words, reached at bit 1,908,874,241 after one jump, the length wraps negative. DocsWithFieldSet, which records the documents that have a doc value or norm, grows its bit set this way, and a set with a negative length iterates nothing.
- While a segment is in memory, each doc-values or norms field keeps a
DocsWithFieldSet. As long as documents 0, 1, 2, ... all have a value, it only counts them. - At the first gap it switches to a
FixedBitSet, one bit per document ID, and grows it withFixedBitSet.ensureCapacityas higher doc IDs arrive (with about 1/8 headroom each time). - At flush, the writer walks that bit set's iterator and writes one value per document it returns; a document the iterator skips is written as having no value.
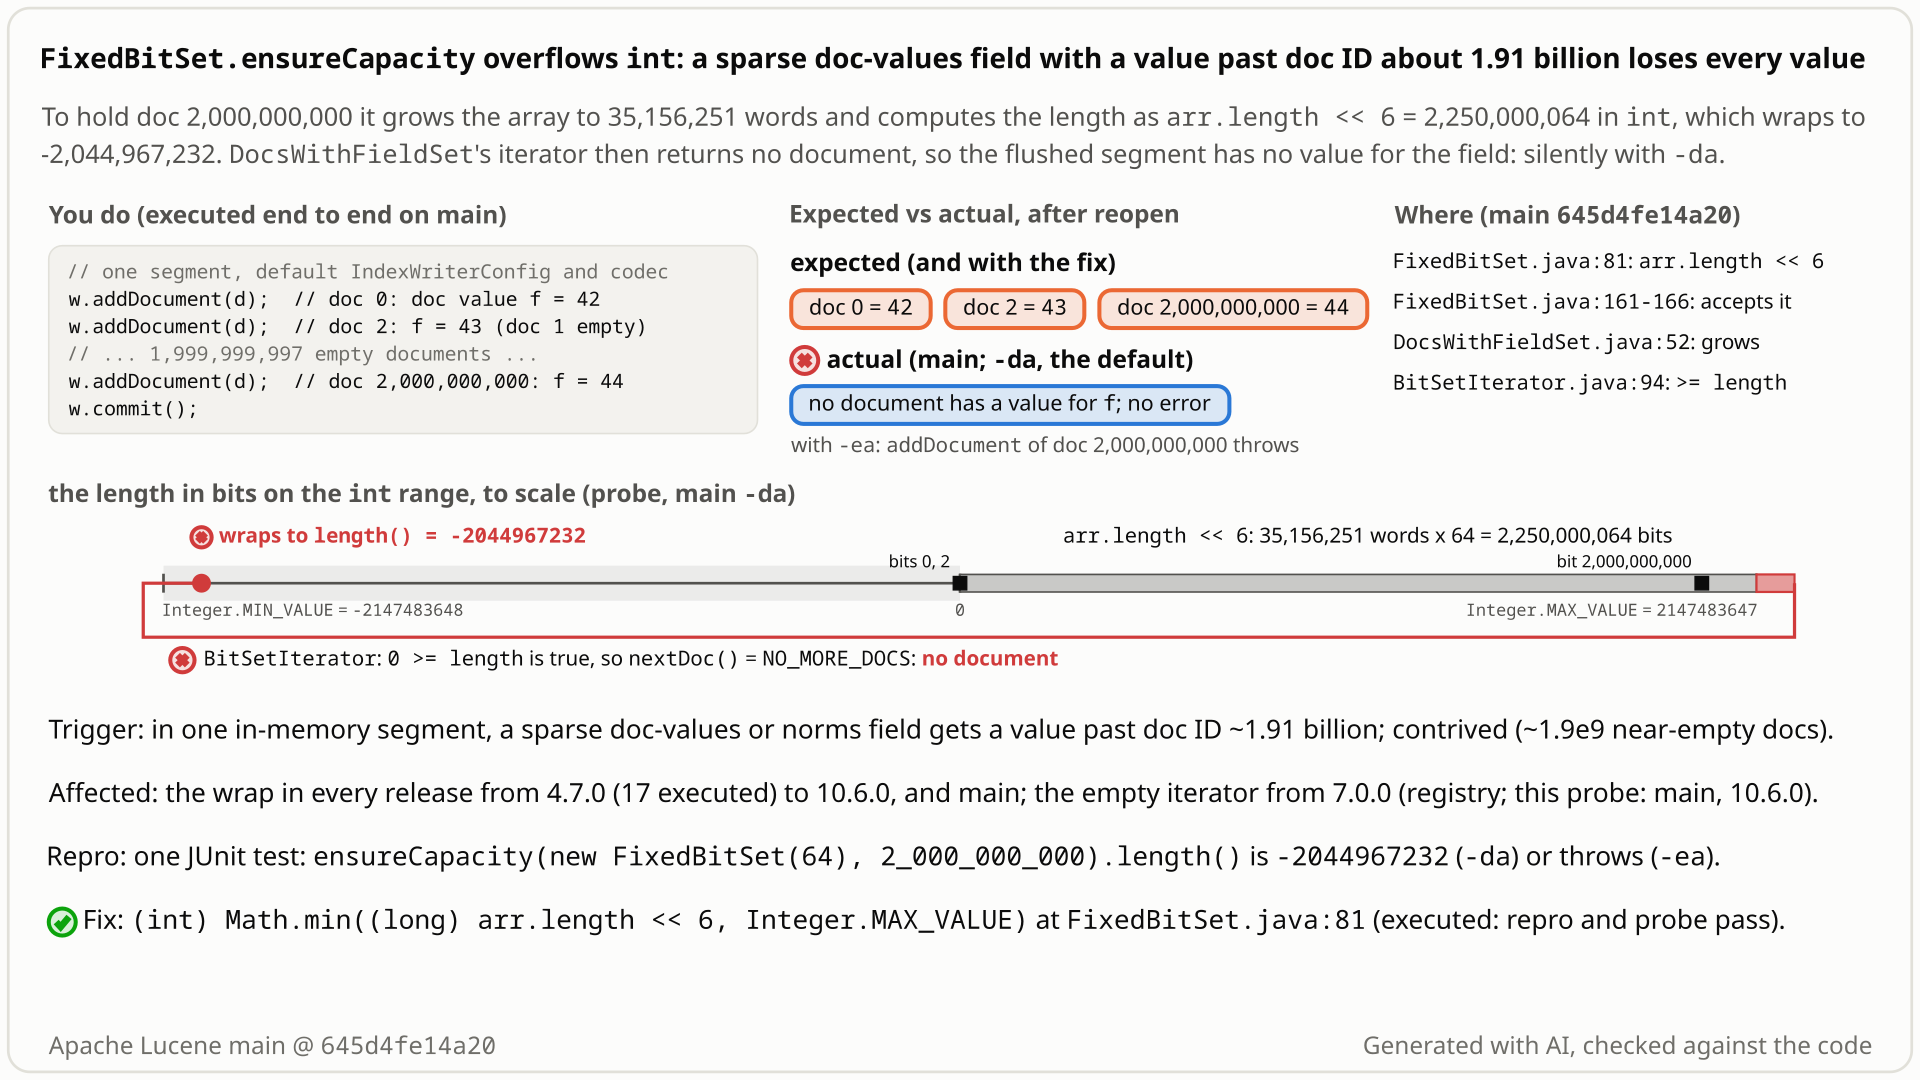
int to -2,044,967,232, and why the flush then finds no document with a value. Select the still to open it at full size. Generated with AI, checked against the code.- You index into one segment a field that only a few documents have, for example a
NumericDocValuesFieldon docs 0, 2 and 2,000,000,000 with empty documents in between (doc IDs up to 2,147,483,518 are legal), and commit. - Lucene remembers which documents have the field in a bit set. For doc 2,000,000,000 it grows the set to 35,156,251 64-bit words and computes the new length as 35,156,251 × 64 in an
int. - You expect 2,250,000,064 bits. An
intholds at most 2,147,483,647, so the length wraps to -2,044,967,232. - The set's iterator stops at once when the length is negative, so the flush writes the field with no documents: after reopening, doc 0 has no value. With assertions off (the default) there is no error; with them on,
addDocumentthrows for that one document. - Reaching it takes about 1.9 billion nearly empty documents in one in-memory segment, so it is rare; every release since 4.7.0 has the line.
An application whose one in-memory segment has a sparse doc-values or norms field that then gets a value past doc about 1.91 billion; default settings suffice. In practice that takes about 1.9 billion nearly empty documents with no flush in between, so it is contrived. With assertions off the values vanish silently; the postings stay intact.
Mechanism, terms and numbers835 words
FixedBitSet.ensureCapacity(bits, desiredBit) grows the backing long[] with about 1/8 headroom and returns new FixedBitSet(arr, arr.length << 6). The shift is int arithmetic, so once the array has 2^25 words the length wraps negative: asking for bit 2,000,000,000 from a small set gives 35,156,251 words and length() = -2,044,967,232, and the first failing bit after one jump is 1,908,874,241. The constructor accepts the negative length; with assertions on, its ghost-bits check throws ArrayIndexOutOfBoundsException.
DocsWithFieldSet, which the doc-values and norms writers use to remember which documents have a value, grows its bit set this way once a field is sparse, and its iterator stops at once for a negative length. So, with assertions off, once a sparse field gets a value past doc about 1.91 billion (below IndexWriter.MAX_DOCS = 2,147,483,519) and its bit set grows there, the flushed segment silently has no value for that field on any document; executed for numeric doc values, sorted doc values and norms, with the postings intact. It needs about 1.9 billion nearly empty documents in one in-memory segment, so the priority is low. The sibling LongBitSet had the same overflow and was fixed in 2015 (LUCENE-6409); casting to long and capping at Integer.MAX_VALUE fixes FixedBitSet too.
- The growth.
util/FixedBitSet.java:62-83(ensureCapacityInternal, shared byensureCapacity:49-51andensureCapacityAndClear:58-60):numWords = bits2words(desiredBit)(:72),arr = ArrayUtil.grow(arr, numWords + 1)(:76;ArrayUtil.oversizeaddsminTargetSize >> 3,util/ArrayUtil.java:157,:166), thenreturn new FixedBitSet(arr, arr.length << 6);(:81), anintshift. - The numbers.
desiredBit2,000,000,000: 31,250,000 words needed, grown to 35,156,251 words (281 MB); 35,156,251 × 64 = 2,250,000,064 wraps to -2,044,967,232. Threshold after one jump from a small set: 1,908,874,241 needs 29,826,161 words and grows to 29,826,162 + 3,728,270 = 33,554,432 = 2^25 words, whose × 64 is 2^31, i.e.Integer.MIN_VALUE; 1,908,874,240 still gives 2,147,483,584. The grown size depends only ondesiredBit, so every growth step to a bit of 1,908,874,241 or more wraps and every lower one does not (exhaustive sweep over allintvalues); when a growth happens depends on the set's history: growth in 1M-bit steps first fails at 2,105,000,003. Both are belowIndexWriter.MAX_DOCS= 2,147,483,519 (index/IndexWriter.java:208). - No rejection. The constructor
FixedBitSet(long[], int)(util/FixedBitSet.java:160-170) computesnumWords = bits2words(numBits)(((numBits - 1) >> 6) + 1,:86-90). For the 2e9 witness that is -31,952,613, so its "too small" check passes. With assertions on,assert verifyGhostBitsClear()(:169) readsbits[-31952613](:184-185) and throwsArrayIndexOutOfBoundsException.Integer.MIN_VALUEis the special case:numBits - 1wraps toInteger.MAX_VALUE, so the word count is +2^25, exactly the array size, the check passes andlength()isInteger.MIN_VALUEin both modes. Later calls never restore a valid length:desiredBit < numBits(:64) is never true, and for any doc ID the array is already big enough, so the call keeps the same negative length; only a request for bit 2,147,483,584 or more (beyond any doc ID) can grow a 2^25-word set again, and that length wraps too. - The consumer.
index/DocsWithFieldSet.java: the first gap createsnew FixedBitSet(docID + 1)(:54-58); every later add grows it withFixedBitSet.ensureCapacity(set, docID)(:52;addRange:84). So the field must already be sparse when a value arrives that grows the set past bit 1,908,874,241; if the first gap is itself that high, the direct constructor is fine and only a later value takes the bad path.iterator()returnsnew BitSetIterator(set, cardinality)(:103), which cacheslength = bits.length()(util/BitSetIterator.java:72) and returnsNO_MORE_DOCSwhenevertarget >= length(:94-95): at once for a negative length.DocsWithFieldSet.cardinality(), a separate counter, still counts every add. A probe on the stock jar shows the three bits are set (get(2000000000)is true), yet the bit set's owncardinality()is 0 and the iterator returnsNO_MORE_DOCSat once. - The writers.
NumericDocValuesWriterflushes throughdocsWithField.iterator()(index/NumericDocValuesWriter.java:134-142,:167), and so doNormValuesWriter(:70,:93) andSortedDocValuesWriter(:249-256,:286); the binary, sorted-numeric and sorted-set writers use the same class (code reading). So the codec writes the field with no documents. - Merges and vectors. Doc-values and norms merges do not use
DocsWithFieldSet, so for them the loss is on the flush path. By code reading only, vectors use it on both paths: at flush,Lucene99FlatVectorsWriter's field writer adds every document with a vector (codecs/lucene99/Lucene99FlatVectorsWriter.java:499,:529) andwriteMeta(:335-354) passes the set toOrdToDocDISIReaderConfiguration.writeStoredMeta; at merge,writeVectorData(:377-391) builds one over the merged doc IDs. So a sparse vector field that gets a value past doc 1.91e9, or is merged into a segment of 1.91e9+ documents, reaches the same growth; with a non-zero count and an empty iterator,DirectMonotonicWriter.finish()should then throwIllegalStateException(codecs/lucene95/OrdToDocDISIReaderConfiguration.java:86-111,util/packed/DirectMonotonicWriter.java:137-141), a loud failure (not executed).
Exposure and likelihood373 words
- Who can be hit. A doc-values or norms field in a single in-memory segment (one
DocumentsWriterPerThread) that is already sparse (an earlier document lacks it, so itsDocsWithFieldSetuses a bit set) and then gets a value whose doc ID makes that bit set grow past bit 1,908,874,241. A sparse field with no value that high is not affected. Executed end to end for numeric doc values, sorted doc values and norms; binary, sorted-numeric and sorted-set doc values use the same class (code reading). - Defaults. An otherwise default
IndexWriterConfigpinned to the default codec (Lucene104Codec, throughTestUtil.getDefaultCodec(), since the test framework randomizes the codec) and anFSDirectoryreproduce it. There is no per-segment document cap belowIndexWriter.MAX_DOCS(DocumentsWriterPerThread.reserveOneDocchecks only the index-wide limit), andmaxBufferedDocsis off by default. - Silent. With assertions off (the JVM default) the field's values vanish with no error.
CheckIndexreports nothing for the numeric field and the norms, and flags the sorted field only as "reports wrong maxOrd=2 but this is not the case: -1". The postings are intact (docFreq3), so the documents are still found; they only lose the field's values (sorting, faceting, norms-based scoring,FieldExistsQuery). With assertions on,addDocumentthrows a non-abortingArrayIndexOutOfBoundsExceptionfor that one document and the writer stays open. - Scale. The field's bit set counts toward the RAM buffer, so with values spread out the default 16 MB buffer would flush long before doc 1.9e9 (code reading). The executed trigger therefore uses about 1.9 billion empty documents and one commit (344-913 s per run). The RAM limits cannot stop the final jump, though (code reading): the writer updates its RAM accounting only after
DocsWithFieldSet.addreturns, so the growth to 281 MB and the wrap happen before any flush can react, and the 281 MB set stays below the default per-thread hard limit of 1,945 MiB. The vector routes (a sparse vector field at flush or at merge) are code reading only and likely fail loudly. - Other callers (code reading only):
SloppyPhraseMatcher,FieldUpdatesBuffer,ReadersAndUpdatesandHnswGraphSearcher(ensureCapacityAndClear) and the misc module'sMemoryAccountingBitsetCollectorwould get the same negative length for a bit of about 1.91e9 or more; none was run at that size.
One JUnit test: ensureCapacity(new FixedBitSet(64), 2_000_000_000) must return a set longer than 2,000,000,000 bits. Deterministic, single thread, about 2 seconds and a 281 MB array. The end-to-end loss (about 2 billion documents) is described, not part of the repro.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.util;

import org.apache.lucene.tests.util.LuceneTestCase;

public class TestFixedBitSetEnsureCapacityOverflow extends LuceneTestCase {

  public void testEnsureCapacityTo2BillionBits() {
    // Expected: length() > 2,000,000,000; actual: negative (-da), or AIOOBE from the -ea check.
    FixedBitSet bits;
    try {
      bits = FixedBitSet.ensureCapacity(new FixedBitSet(64), 2_000_000_000);
    } catch (ArrayIndexOutOfBoundsException e) {
      throw new AssertionError("ensureCapacity(bits, 2000000000) threw " + e, e);
    }
    assertTrue(
        "expected length() > 2000000000 but was " + bits.length(), bits.length() > 2_000_000_000);
  }
}
cd $LUCENE   # an apache/lucene checkout at 645d4fe14a20
cp $REPRO/TestFixedBitSetEnsureCapacityOverflow.java lucene/core/src/test/org/apache/lucene/util/
./gradlew :lucene:core:test --tests org.apache.lucene.util.TestFixedBitSetEnsureCapacityOverflow
# assertions off (the silent negative length): add -Ptests.asserts=false
- Expected
ensureCapacity(new FixedBitSet(64), 2_000_000_000).length()is greater than 2,000,000,000.- Observed
length()is -2,044,967,232 (assertions off); with assertions on,ensureCapacitythrowsArrayIndexOutOfBoundsException: Index -31952613 out of bounds for length 35156251.
More files, environment, full output389 words
The test sits in org.apache.lucene.util, next to TestFixedBitSet, and calls the public static FixedBitSet.ensureCapacity (the class is marked @lucene.internal). The try/catch only turns the assertions-on ArrayIndexOutOfBoundsException, thrown inside ensureCapacity by the constructor's ghost-bits check, into a failure that names the call.
As a regression test it is the same test, for example as TestFixedBitSet.testHugeCapacity next to TestLongBitSet.testHugeCapacity; it fails on stock and passes with the fix. It needs a 281 MB array and passed under gradle's default 512 MB test heap; the LongBitSet sibling is tagged @Monster("needs hundreds of MB of heap") and so does not run by default, and maintainers may want the same tag.
The end-to-end consequence (a NumericDocValuesField on docs 0, 2 and 2,000,000,000 with empty documents in between, one commit: "doc 0 lost its value" with assertions off, ArrayIndexOutOfBoundsException inside addDocument with assertions on) takes about 2 billion addDocument calls and 6-15 minutes, so it is deliberately not part of the repro.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the same failure on 10.6.0 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 (64-bit JVM) |
# gradle, main 645d4fe14a20, seed DEADBEEF, assertions on
TestFixedBitSetEnsureCapacityOverflow > testEnsureCapacityTo2BillionBits FAILED
    java.lang.AssertionError: ensureCapacity(bits, 2000000000) threw java.lang.ArrayIndexOutOfBoundsException: Index -31952613 out of bounds for length 35156251
        Caused by:
        java.lang.ArrayIndexOutOfBoundsException: Index -31952613 out of bounds for length 35156251
            at org.apache.lucene.util.FixedBitSet.verifyGhostBitsClear(FixedBitSet.java:185)
            at org.apache.lucene.util.FixedBitSet.<init>(FixedBitSet.java:169)
            at org.apache.lucene.util.FixedBitSet.ensureCapacityInternal(FixedBitSet.java:81)
            at org.apache.lucene.util.FixedBitSet.ensureCapacity(FixedBitSet.java:50)

# assertions off (-Ptests.asserts=false)
TestFixedBitSetEnsureCapacityOverflow > testEnsureCapacityTo2BillionBits FAILED
    java.lang.AssertionError: expected length() > 2000000000 but was -2044967232

# 10.6.0 release jars: the same two failures (FixedBitSet.java:187 <- :171 <- :83 <- :52 with assertions on)

# with the fix (gradle, seed DEADBEEF): the test passes with assertions on and off

# end to end, stock main jar, assertions off (independent reproducer, 344 s)
numeric doc values lost: expected docs [1, 3, 1950000000]
sorted doc values lost: expected docs [1, 3, 1950000000]
norms lost: expected docs [1, 3, 1950000000]
maxDoc=1950000001 numDocs=1950000001 leaves=1
numeric docs with value: []
sorted docs with value: [] valueCount=3
norms docs with value: []
docFreq(t:hello)=3
CheckIndex: dv for field: s reports wrong maxOrd=2 but this is not the case: -1 (nothing reported for the numeric field or the norms)

# end to end, assertions on (665 s)
addDocument(doc 1950000000) threw java.lang.ArrayIndexOutOfBoundsException: Index -32831520 out of bounds for length 34277344
writer open after that: true, tragic=null; docs 1 and 3 keep their values- The javadoc promises the result "can store a value at
desiredBitindex", with no bound; the class sends users toLongBitSetonly above 2.1B bits, andnew FixedBitSet(Integer.MAX_VALUE)works. - The class's own assertion rejects the result, and doc IDs up to 2,147,483,518 (below
IndexWriter.MAX_DOCS) are legal. - The identical overflow in
LongBitSet.ensureCapacitywas fixed as a bug in 2015 (LUCENE-6409).
The full argument256 words
- The contract. "Ensure the given
bitscan store a value atdesiredBitindex. If the current [#length()] is sufficient,bitsis simply returned. Otherwise, a new, larger bitset is allocated, with contents ofbitscopied." (FixedBitSet.java:44-46). A set whoselength()is negative cannot store bit 2,000,000,000. - The class's own limit is higher. "accessed with an int index ... If you need to manage more than 2.1B bits, use LongBitSet" (
FixedBitSet.java:24-27). The failing requests start at 1,908,874,241, andnew FixedBitSet(Integer.MAX_VALUE)works (executed), so the failure depends only on how the set grew. - Its own invariant check. With assertions on, the constructor's
assert verifyGhostBitsClear()throws on the result (:169,:184-185). - Legal input.
IndexWriter.MAX_DOCS = Integer.MAX_VALUE - 128is the only document cap (a count, so doc IDs run to 2,147,483,518).DocsWithFieldSetis public (since 9.1.0) with no@lucene.internaltag; its javadoc states no limit on doc IDs, andaddonly rejects out-of-order IDs. - Intent and precedent. The method was added in LUCENE-5440 (2014) at a reviewer's request so the doc-values writers could grow their docs-with-field set by doc ID. The same commit gave
LongBitSet.ensureCapacitythe same shift; LUCENE-6409 (#7469, 5.2.0, "Fixed integer overflow in LongBitSet.ensureCapacity") cast it tolongand addedTestLongBitSet.testHugeCapacity. That commit editedFixedBitSet.javabut not this line; a comment in #7469 quotes theFixedBitSetline only about over-allocation.TestFixedBitSet.testEnsureCapacityuses sets of at most 384 bits (literal sizes 5, 8 and 72; growth makes them 320 and 384 bits, and the reuse call asks for bit 318).
The devil's-advocate check191 words
The strongest case for "intended": FixedBitSet is @lucene.internal, the workload is absurd (one in-memory segment of about 1.9 billion nearly empty documents; with ordinary documents the 16 MB RAM buffer and the 1,945 MiB per-thread hard limit flush long before), and the upstream 2B monster tests use only dense fields, so sparse fields in near-2B segments were never meant to be supported.
Why it fails: the path is reached through public API (IndexWriter.addDocument and the public DocsWithFieldSet) with inputs inside every documented limit; no document says sparse fields stop working below MAX_DOCS; the RAM limits make the trigger rare but cannot prevent it, since the jump happens inside one add before any flush can react; the result breaks the method's own javadoc and assertion; and upstream treated the identical LongBitSet overflow as a bug. Internal status and scale lower the priority, not the validity. The reviews by another model family rated the intended-behaviour case weak (a later review by the same family rated it moderate, citing the RAM limits, and still found it defeated), and the intended-behaviour checker found no limit in javadoc, CHANGES, MIGRATE or tests.
Recommended Compute the length in long and cap it at Integer.MAX_VALUE
Compute the length in long and cap it at Integer.MAX_VALUE, one line in FixedBitSet.ensureCapacityInternal. Validated through gradle: the repro passes with assertions on and off, the closest suites (81 tests), the util package plus the doc-values and norms tests (1,327 tests) and check -x test pass.
-      return new FixedBitSet(arr, arr.length << 6);
+      return new FixedBitSet(arr, (int) Math.min((long) arr.length << 6, Integer.MAX_VALUE));
All options and trade-offs4 options · 447 words
The hunt's one-line fix (without its comment line) was run through gradle in a scratch worktree of 645d4fe14a20 (OpenJDK 25.0.3, seed DEADBEEF); the worktree was removed afterwards.
In FixedBitSet.ensureCapacityInternal (:81). Below 2^25 words nothing changes. From 2^25 words the length is Integer.MAX_VALUE, which holds every bit index up to 2,147,483,646, so every doc ID below MAX_DOCS; bits2words(Integer.MAX_VALUE) = 2^25 words fits the array, the extra words are zero, and the top bit of the last word can never have been set, so the ghost-bits invariant holds. A Z3 query proves the capped length is greater than desiredBit and fits the array for one growth step from a set of 1 to 64 bits and every desiredBit up to 2^31 - 2. No int-length FixedBitSet can hold bit index Integer.MAX_VALUE itself; that is NO_MORE_DOCS, not a doc ID.
-      return new FixedBitSet(arr, arr.length << 6);
+      return new FixedBitSet(arr, (int) Math.min((long) arr.length << 6, Integer.MAX_VALUE));
Trade-offs
One long shift and a min on the growth path only; set and get are unchanged. A request for bit 2e9 still allocates 35,156,251 words (281 MB), of which 33,554,432 are addressable.
What the checks validated
- The repro fails on stock (assertions on and off) and passes with the fix in both modes.
- Closest suites (
TestFixedBitSet,TestLongBitSet,TestSparseFixedBitSet,TestBitSetIterator,TestDocsWithFieldSet): 5 classes, 81 tests, 0 failures (1 skipped). org.apache.lucene.util.*plusindex.*DocValues*,index.*Norms*andTestDocsWithFieldSet: 144 classes, 1,327 tests, 0 failures (36 skipped).:lucene:core:check -x test(formatting, ecj lint, forbidden APIs) passes with the fix and the test in place.- Earlier, with the class shadowed: the hunt's and the checkers' tests and 40 upstream
TestFixedBitSetandTestDocsWithFieldSettests pass.
Cap the grown size at bits2words(Integer.MAX_VALUE) words, with an exact allocation on both the preserving and the clearing path.
Trade-offs
Saves up to about 12.8 MB at this size (35,156,251 versus 33,554,432 words), at the cost of more code for a size nobody reaches today; a possible follow-up.
Return new FixedBitSet(arr, desiredBit + 1).
Trade-offs
Callers rely on the length covering the whole array (TestFixedBitSet.testEnsureCapacity reuses up to length() - 2), and every later DocsWithFieldSet.add past that length would allocate a new FixedBitSet object.
Fail loudly when the length does not fit.
Trade-offs
Turns silent loss into a loud failure, but rejects doc IDs that IndexWriter accepts (below MAX_DOCS).
Downstream: an application that excludes documents by such a field (a MUST_NOT clause or a negated FieldExistsQuery) would let the affected documents through, because their values are gone.
Semi-formal: while listing int-overflow risks in Lucene's bit sets, an AI tool read FixedBitSet.ensureCapacity and saw the int shift where LongBitSet casts to long. A Z3 bit-vector query found the smallest failing bit, 1,908,874,241, and proved the capped fix; unit tests and an end-to-end indexing run on the stock jar confirmed it.
The method in full137 words
Method: semi-formal (code reading, then an SMT solver, then executed tests), a hunt unit on bit sets, live docs and accept docs.
- The unit wrote int-overflow obligations for the bit-set code; the 2026-10-22 study's overflow inventory had not covered
FixedBitSet. - A Z3 bit-vector model of the growth found a counterexample, the smallest failing
desiredBitfrom a 64-bit set (1,908,874,241), proved the method correct below it, found failing doc IDs belowMAX_DOCSfrom larger earlier arrays too, and proved the saturating long-shift fix. - JUnit tests on the stock main jar confirmed the negative length and the empty
DocsWithFieldSetiterator in both assertion modes, and an end-to-end test (2,000,000,001 documents, one commit) showed the lost value. - An independent verifier then wrote its own tests from the claim, including its own end-to-end run with numeric, sorted and norms fields.
No prior report: 105 search-tool queries and 68 GitHub GraphQL queries over issues, PRs, commits, four mailing lists, the JIRA archive, downstream projects and the web, plus the changed files of all 413 open PRs (2026-10-26); re-checked on GitHub on 2026-10-31. The closest item is the fixed LongBitSet twin, LUCENE-6409.
Searches6 searches
Closest items, none a report of this bug: #7469 (LUCENE-6409, the same overflow in LongBitSet.ensureCapacity, fixed in 5.2.0; a comment quotes the FixedBitSet line only about over-allocation); #7486 (LUCENE-6427, the ghost-bits assertion); #6503 (LUCENE-5440, where the line came in); #8596 (LUCENE-7545, DocsWithFieldSet); #15582 (the ensureCapacityAndClear refactor); #11910 and #11921 (error-prone int-overflow passes that did not flag it); #16847 (long global doc IDs, does not touch bit-set growth). Keyword search cannot prove nobody has noticed it.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-25 and 2026-10-26 | the hunt's search tool (32 issue/PR and 6 commit queries) and 48 GraphQL queries: FixedBitSet ensureCapacity, arr.length << 6, FixedBitSet negative length, DocsWithFieldSet 2 billion, bits2words, sparse doc values lost; 63 items fetched in full (62 in the main pass plus #16566) | no report; #7469 (precedent), #7486, #6503, #8596, #15582 |
| Open PRs | 2026-10-26; re-checked 2026-10-31 | changed files of all 413 open PRs (13 touch the involved files, their diffs grepped); on 2026-10-31 the open PRs matching FixedBitSet | none changes the shift or bits2words |
| Mailing lists (dev@, java-user@, issues@, commits@) | 2026-10-26 | 40 tool queries | no report; the 2014 dev@ notification of the pull request later filed as LUCENE-6409 names the overflow for LongBitSet only |
| JIRA archive | 2026-10-26 | 8 tool queries and read-only REST queries | LUCENE-6409, LUCENE-6427, LUCENE-5440 only |
| Elasticsearch, OpenSearch, Solr; web | 2026-10-26 | 4 downstream-repository and 20 GraphQL queries; 15 web queries | no report |
| GitHub re-check | 2026-10-31 | FixedBitSet ensureCapacity, FixedBitSet overflow, FixedBitSet negative length, DocsWithFieldSet, ensureCapacity overflow, arr.length << 6, bitset integer overflow, ensureCapacityInternal (issues and PRs); the diffs of the 8 open PRs matching FixedBitSet grepped for the shift | only the items above; no open PR changes the line |
In the method's first version: LUCENE-5440 (2014-02-10), first released in 4.7.0. An equivalent unit test fails on 26 releases from 4.7.0 to 10.6.0 (every 8.8.2-8.11.4 release, which the history clone has no tags for, included) and on main; the lost-values path needs DocsWithFieldSet (7.0.0). LUCENE-6409 fixed the LongBitSet twin in 5.2.0 but left this line. Not fixed upstream.
Versions tested9 rows
Introduced by b872f4b5c3c5 (LUCENE-5440, migrated as #6503, 2014-02-10; same-day branch_4x backport bc1797f526ae). ensureCapacity was added in that review so the doc-values writers could grow their docs-with-field bit set; the overflowing line is in its first version, so it is not a regression. Found by git blame and git log -S over the full history; not bisected at commit level.
Later: LUCENE-6409 (69af3beaed8; in 5.2.0 through the backport 84820b04187) cast the LongBitSet shift to long and edited FixedBitSet.java without touching this line. LUCENE-6427 (5.2.0) added the ghost-bits assertion, so from 5.2.0 assertions-on runs throw; before it the negative length was silent in both modes. LUCENE-7545 (7.0.0) added DocsWithFieldSet, which grows through this method. #15582 (10.4.0) moved the line into ensureCapacityInternal, so ensureCapacityAndClear shares it.
Not fixed upstream (2026-10-31): main 2f424fd428d, branch_11x, branch_10_6 and the 10.6.0 tag still compute arr.length << 6; branch_9x was not checked. The history clone has no 8.8.2-8.11.4 tags; those nine releases were executed instead. What a 4.7.0-6.6.6 flush does at this scale was not executed.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test: length -2,044,967,232 with assertions off, ArrayIndexOutOfBoundsException with assertions on (gradle and the standalone runner) |
| 10.6.0 | affected | the minimal test fails the same way with assertions on and off |
main ea57360912ed | end to end | one segment of 1,950,000,001 docs lost every numeric, sorted and norms value (assertions off); 2,000,000,001 docs: doc 0 lost its value |
| 7.0.0, 7.7.3, 8.11.4, 9.12.3, 10.5.2 | affected | DocsWithFieldSet with docs 0, 2 and 2,000,000,000: cardinality 3, the iterator returns no document |
| 5.2.0 through 10.5.2 (13 releases run) | affected | ensureCapacity to bit 2e9: 35,156,251 words, length -2,044,967,232 (assertions off); with assertions on it throws (run on 5.2.0, 8.11.4, 9.12.3 and 10.5.2) |
| 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0, 8.11.1, 8.11.2, 8.11.3 | affected | ensureCapacity to bit 2e9: 35,156,251 words, length -2,044,967,232 (assertions off); the history clone has no tags for these releases, so they were run on the release jars (2026-10-31) |
| 4.7.0, 4.10.4, 5.0.0, 5.1.0 | affected | the same negative length; silent even with assertions on (run on 4.7.0 and 5.1.0; no ghost-bits assertion yet) |
| 4.6.1 | not affected | no FixedBitSet.ensureCapacity (compile error) |
LongBitSet twin: 4.7.0, 5.1.0 vs 5.2.0, main | sibling class | the same overflow fails on 4.7.0 and 5.1.0 and is fixed from 5.2.0 (LUCENE-6409) |
Confirmed with high confidence by the study's judge after an independent reproducer, an intended-behaviour devil's advocate and reviews by another model family (OpenAI GPT-5.6), with no dissent; re-run on 645d4fe14a20 and the 10.6.0 jars, and the fix validated through gradle.
Checks and verdicts320 words
Each checker that executed wrote its own test from the claim; the adjudication re-ran the finder's and the independent reproducer's tests with a new seed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Z3: smallest failing bit 1,908,874,241, correct below it, the capped fix proved. Unit tests fail with assertions on and off on main, 9.12.3 and 10.5.2; the end-to-end flush loses the value (assertions off) or throws in addDocument (on). |
| refute review (OpenAI GPT-5.6) | real, high | Its own probe fails at exactly 1,908,874,241 (Integer.MIN_VALUE) and its DocsWithFieldSet probe iterates nothing for cardinality 3; both pass with the fix, and 40 upstream tests pass. |
| Independent reproducer | real | Its own tests fail on main, 9.12.3 and 10.5.2 in both modes with the exact boundary; its own end-to-end run lost all numeric, sorted and norms values of a 1,950,000,001-document segment with the postings intact. |
| Works-as-designed review (OpenAI GPT-5.6) | real, high | Its own 6-test class fails 2 on main in both modes while 4 controls pass; intended-behaviour argument weak. |
| Intended-behaviour devil's advocate | real, high | No documented limit below 2.1B bits; gradual growth fails from 2,105,000,003; new FixedBitSet(Integer.MAX_VALUE) works. |
| adjudication | confirmed, high | Re-ran the finder's tests and the independent reproduction's tests with seed 7A11E5ED in both modes, and the independent reproduction's tests with the fix (all pass); read the independent reproduction's end-to-end output instead of re-running 2 billion documents. |
| re-verification | still reproduces | Same failures on main a9779ef3c193 (2026-10-26); the one-test repro fails on 645d4fe14a20 and passes with the fix shadowed (2026-10-29). |
| this doc (2026-10-31) | real, fix validated | The minimal test on the 10.6.0 jars (fails, both modes) and on main through gradle; the fix through gradle with the closest suites, the util package, the doc-values and norms tests and check. Also on 2026-10-31: the 8.8.2-8.11.3 releases, a probe of the statements on this page and the prior-report re-check. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 453 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,569 words
- Registry title
- FixedBitSet.ensureCapacity computes the grown length as int arr.length << 6, which wraps negative once the requested bit reaches about 1.91 billion, so DocsWithFieldSet iterates no documents and a flushed segment silently drops every value of its sparse doc-values and norms fields
- Area
- util / FixedBitSet growth (ensureCapacity) and index / DocsWithFieldSet (doc-values and norms flush)
- Priority
- Low, rank 985: FixedBitSet.ensureCapacity wraps, so flush silently drops every value of sparse doc-values and norms fields; severe, but it takes one in-memory segment of about 1.9 billion nearly empty documents with no flush, so it is contrived.
- Impact class
- data corruption
- Impact note
- Hits an application whose single in-memory segment reaches doc IDs of about 1.91e9 or more (still below IndexWriter.MAX_DOCS = 2^31-129) while a doc-values or norms field is sparse, with the default IndexWriterConfig, codec and directory: with assertions disabled (the production default) the committed segment silently has no value for that field on any document (executed for numeric doc values, sorted doc values and norms; postings stay intact; CheckIndex flags only the sorted field), while with -ea addDocument throws a non-aborting ArrayIndexOutOfBoundsException for that one document; the executed trigger needs about 1.9 billion nearly empty documents with no flush in between, so it is extreme-scale and contrived; a sparse vector field merged into a segment of 1.91e9+ docs reaches the same growth by code reading only (not executed); released since 4.7.0.
- Summary
- You index into one segment until doc IDs pass about 1.91 billion (legal: IndexWriter.MAX_DOCS is 2^31-129) with a doc-values or norms field that only some documents have, then commit; you expect every indexed value to be in the segment. Instead, when the field's DocsWithFieldSet grows its FixedBitSet to the new doc ID, FixedBitSet.ensureCapacity computes the new length as arr.length << 6 in int arithmetic, which wraps negative once the backing array has 2^25 words, so the set's iterator returns no document although cardinality() counts them, and the flushed segment has no document with a value for that field (with -da; with -ea addDocument throws ArrayIndexOutOfBoundsException for that document). The same call on a small set, ensureCapacity(new FixedBitSet(64), 2_000_000_000), returns a set with length() = -2,044,967,232; the twin LongBitSet.ensureCapacity had the identical overflow and was fixed in 2015 (LUCENE-6409), but FixedBitSet was not.
- Introduced
- b872f4b5c3c5 (LUCENE-5440, migrated as apache/lucene#6503 'Add LongFixedBitSet and replace usage of OpenBitSet', by shaie, svn r1566662 on trunk; same-day branch_4x backport bc1797f526ae, svn r1566670) added FixedBitSet.ensureCapacity with the line 'return new FixedBitSet(arr, arr.length << 6);' during review (mikemccand asked for an ensureCapacity so the doc-values writers could grow a FixedBitSet; the same commit switched NumericDocValuesWriter and BinaryDocValuesWriter to it) [read: git blame attributes FixedBitSet.java:81 at main to b872f4b5c3c and git log -S/-G on the line over all refs finds no other commit that adds or changes it, in the history clone; release-level execution only: 4.6.1 has no such method (compile error), 4.7.0 fails; no commit-level bisect]; later commits kept the shift: 69af3beaed8 / 84820b04187 (LUCENE-6409, #7469, 2015-04-13, fixed the same overflow in LongBitSet and touched FixedBitSet.bits2words only), 701b7ddf3a2 / 8ea0408615c (LUCENE-6427, #7486, 2015-04-28, added the ghost-bit assertion that throws under -ea), 59df9e799ce (#15582, 2026-01-16, moved the line into ensureCapacityInternal, shared with the new ensureCapacityAndClear) (2014-02-10 (LUCENE-5440 committed on trunk and backported to branch_4x the same day))
- First affected version
- 4.7.0 [exec]; 4.6.1 and older have no FixedBitSet.ensureCapacity (compile error) [exec]
- Affected versions
- every release from 4.7.0 through 10.6.0 and main ea57360912ed. The unit witness (ensureCapacity(new FixedBitSet(64), 2e9) returns length() = -2044967232 under -da; the 1.9e9 control passes) is executed and failing on 4.7.0, 4.10.4, 5.0.0, 5.1.0, 5.2.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main [exec]; all 110 release tags from 4.7.0 to 10.5.2 in the history clone carry the identical line (the clone lacks the 8.8.2-8.11.4 tags; 8.11.4 executed, and 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0, 8.11.1, 8.11.2 and 8.11.3 executed on the release jars on 2026-10-31, -da) [read]. The DocsWithFieldSet symptom (cardinality 3, empty iterator) needs DocsWithFieldSet (7.0.0, LUCENE-7545) and is executed on 7.0.0, 7.7.3, 8.11.4, 9.12.3, 10.5.2 and main [exec]; whether a 4.7.0-6.6.6 flush at this scale loses values was not executed and is not claimed. The end-to-end silent loss is executed on main only. Under -ea, 4.7.0-5.1.0 return the negative length silently; from 5.2.0 the ghost-bit assertion (LUCENE-6427) throws ArrayIndexOutOfBoundsException [exec]. Upstream main, branch_10x, branch_10_6 and branch_9_12 still have the line (2026-10-26) [read], and on 10.6.0 (released 2026-10-29) the minimal test fails on the release jars (SHA-1 checked against Maven Central) with -ea and -da [exec 2026-10-31]; branch_9x not checked; not fixed upstream [read]; executed on aarch64 Linux with JDK 25 (64-bit JVM) only
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3, code reading
- Upstream and prior reports
- none found (2026-10-25 and 2026-10-26: follow-up scripted prior-report searches with 105 queries (32 GitHub issue/PR, 6 commit, 4 downstream-repo, 40 mailing-list (dev@, java-user@, issues@, commits@), 8 JIRA and 15 web), 68 GitHub GraphQL queries (48 on apache/lucene, 20 on Elasticsearch, OpenSearch, Solr, the archived lucene-solr and all of GitHub), 62 items fetched in full and searched for overflow terms, read-only JIRA REST queries, the changed-file lists of all 413 open apache/lucene PRs (13 touch the involved files; none changes ensureCapacity, the shift or bits2words), FixedBitSet.java on upstream main, branch_10x, branch_10_6 and branch_9_12 read (line present on all four), git history; the finder's earlier 51-query run, the intended-behaviour check's 27-query run and the adjudication's read-only gh searches also found nothing; gaps: branch_9x returned 404 for the file, and the reused 2014-2015 lucene-solr PR numbers were read through the JIRA mirror and the dev@ notification); related prior items, none a report of this bug: #7469 (LUCENE-6409, the identical int-shift overflow in LongBitSet.ensureCapacity, fixed in 5.2.0 by 69af3beaed8, which edited FixedBitSet.java but not its shift; a comment there quotes the FixedBitSet line only about over-allocation), #7486 (LUCENE-6427, ghost-bit assertion), #6503 (LUCENE-5440, introduction of the line), #8596 (LUCENE-7545, DocsWithFieldSet), #15582 (ensureCapacityAndClear refactor), #11910/#11921 (error-prone int-overflow passes that did not flag it), LUCENE-7791 (a different DV-flush AIOOBE), #16847 (long global doc IDs; does not touch bit-set growth)
- Lucene commit tested
- main
645d4fe14a20(gradle and the standalone runner, assertions on and off; the fix through gradle in a scratch worktree of the same commit); the minimal test on the 10.6.0 release jars (fails with assertions on and off); the checkers' equivalent tests on 17 releases from 4.7.0 to 10.5.2 and on mainea57360912ed, where the involved files are identical, and the same check on the eight releases 8.8.2 to 8.11.3, which the history clone has no tags for (assertions off); the end-to-end runs (about 2 billion documents) on mainea57360912edonly. All runs on Linux aarch64 with OpenJDK 25.0.3 (64-bit JVM). Upstream main2f424fd428d(2026-10-30),branch_11x,branch_10_6and the 10.6.0 tag have the same line.
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/FixedBitSet.java:24-29 (class javadoc: 'accessed with an int index ... If you need to manage more than 2.1B bits, use LongBitSet', @lucene.internal), :44-51 (ensureCapacity javadoc 'Ensure the given bits can store a value at desiredBit index ... a new, larger bitset is allocated'), :53-60 (ensureCapacityAndClear), :62-83 (ensureCapacityInternal; :76-78 ArrayUtil.grow / oversize; :81 'return new FixedBitSet(arr, arr.length << 6);'), :160-170 (FixedBitSet(long[], int): 'too small' check passes for a negative numBits; :169 assert verifyGhostBitsClear()), :184 (ghost-bit loop that reads bits[-31952613] under -ea)a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/LongBitSet.java:55 ('return new LongBitSet(arr, (long) arr.length << 6);'); lucene/core/src/test/org/apache/lucene/util/TestLongBitSet.java:355-365 (testHugeCapacity asserts length() >= the requested size); lucene/core/src/test/org/apache/lucene/util/TestFixedBitSet.java:381 (testEnsureCapacity, small sizes only)a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/DocsWithFieldSet.java:25-29 (public final class, 'Accumulator for documents that have a value for a field', no @lucene.internal), :46-61 (add; :52 FixedBitSet.ensureCapacity(set, docID)), :70-94 (addRange; :84 ensureCapacity), :102-103 (iterator: new BitSetIterator(set, cardinality))a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/BitSetIterator.java:72 (length = bits.length()), :93-98 (advance returns NO_MORE_DOCS when target >= length)a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:44, :60, :107 (DocsWithFieldSet add and flush through docsWithField.iterator()); NormValuesWriter.java:38, :55, :79, :93; IndexWriter.java:208 (MAX_DOCS = Integer.MAX_VALUE - 128)
- The finding in 30 seconds
a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/FixedBitSet.java:24-29, :44-90, :160-198a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/ArrayUtil.java:133-200, :409-414a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/DocsWithFieldSet.java:25-109a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/BitSetIterator.java:67-98a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:60, :134-167; NormValuesWriter.java:55, :70-93; SortedDocValuesWriter.java:93, :249-286; IndexWriter.java:208a Lucene main checkout lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99FlatVectorsWriter.java:300-391, :487-532; codecs/lucene95/OrdToDocDISIReaderConfiguration.java:68-111; util/packed/DirectMonotonicWriter.java:137-141 (code reading)
- Who is affected
a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:211-237; IndexWriterConfig.java:78, :83, :92-93; DocumentsWriterFlushControl.java:239-243; NumericDocValuesWriter.java:60-62, :96-100; DocsWithFieldSet.java:51-58; lucene/test-framework/src/java/org/apache/lucene/tests/util/TestUtil.java:1330-1332a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/SloppyPhraseMatcher.java:331; index/FieldUpdatesBuffer.java:172; index/ReadersAndUpdates.java:754; util/hnsw/HnswGraphSearcher.java:372; lucene/misc/src/java/org/apache/lucene/misc/search/MemoryAccountingBitsetCollector.java:57
- Minimal repro
a Lucene main checkout lucene/core/src/test/org/apache/lucene/util/TestLongBitSet.java:354 (@Monster); build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/TestsAndRandomizationPlugin.java:132 (tests.heapsize 512m)
- Why it looks unintended
a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/FixedBitSet.java:24-29, :44-60, :169, :183-193a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/DocsWithFieldSet.java:25-50; IndexWriter.java:202-208; DocumentsWriterPerThread.java:211-218
- Suggested fix
a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/FixedBitSet.java:62-90, :183-193; lucene/core/src/test/org/apache/lucene/util/TestFixedBitSet.java:381-401
- History
a Lucene clone: git show 2f424fd428d, origin/branch_11x, origin/branch_10_6 and releases/lucene/10.6.0 of FixedBitSet.java (read, 2026-10-31)
- TestFixedBitSetEnsureCapacityOverflow.java (one test):
repro/LFV-137/src/org/apache/lucene/util/TestFixedBitSetEnsureCapacityOverflow.java(34 lines)
Made in parallel with this doc, from the code at 645d4fe14a20 and its probe runs on the stock main and 10.6.0 jars and with the fix.
assets/LFV-137/bug.png(453 KB)