The merged view remembers nextLeaf, the segment its nextDoc() reads next. advance() jumps to the target's segment; when that segment has no norms, it returns nextDoc() before setting nextLeaf, so nextDoc() resumes at the stale nextLeaf and can return a document from an earlier segment. The numeric and binary views of the same class set nextLeaf first.
- Norms are a small per-document number (a length factor) that Lucene stores for each text field. A segment in which no document has the field has no norms for it:
getNormValuesreturns null there. - Norms are read with an iterator:
nextDoc()moves to the next document that has a norm, andadvance(target)must return the first such document at or aftertarget, never one before it. - Lucene reads norms per segment.
MultiDocValues.getNormValuesinstead stitches all segments into one iterator, and the merged reader thatIndexWriterpasses toOneMerge#reorderuses it for its norms.
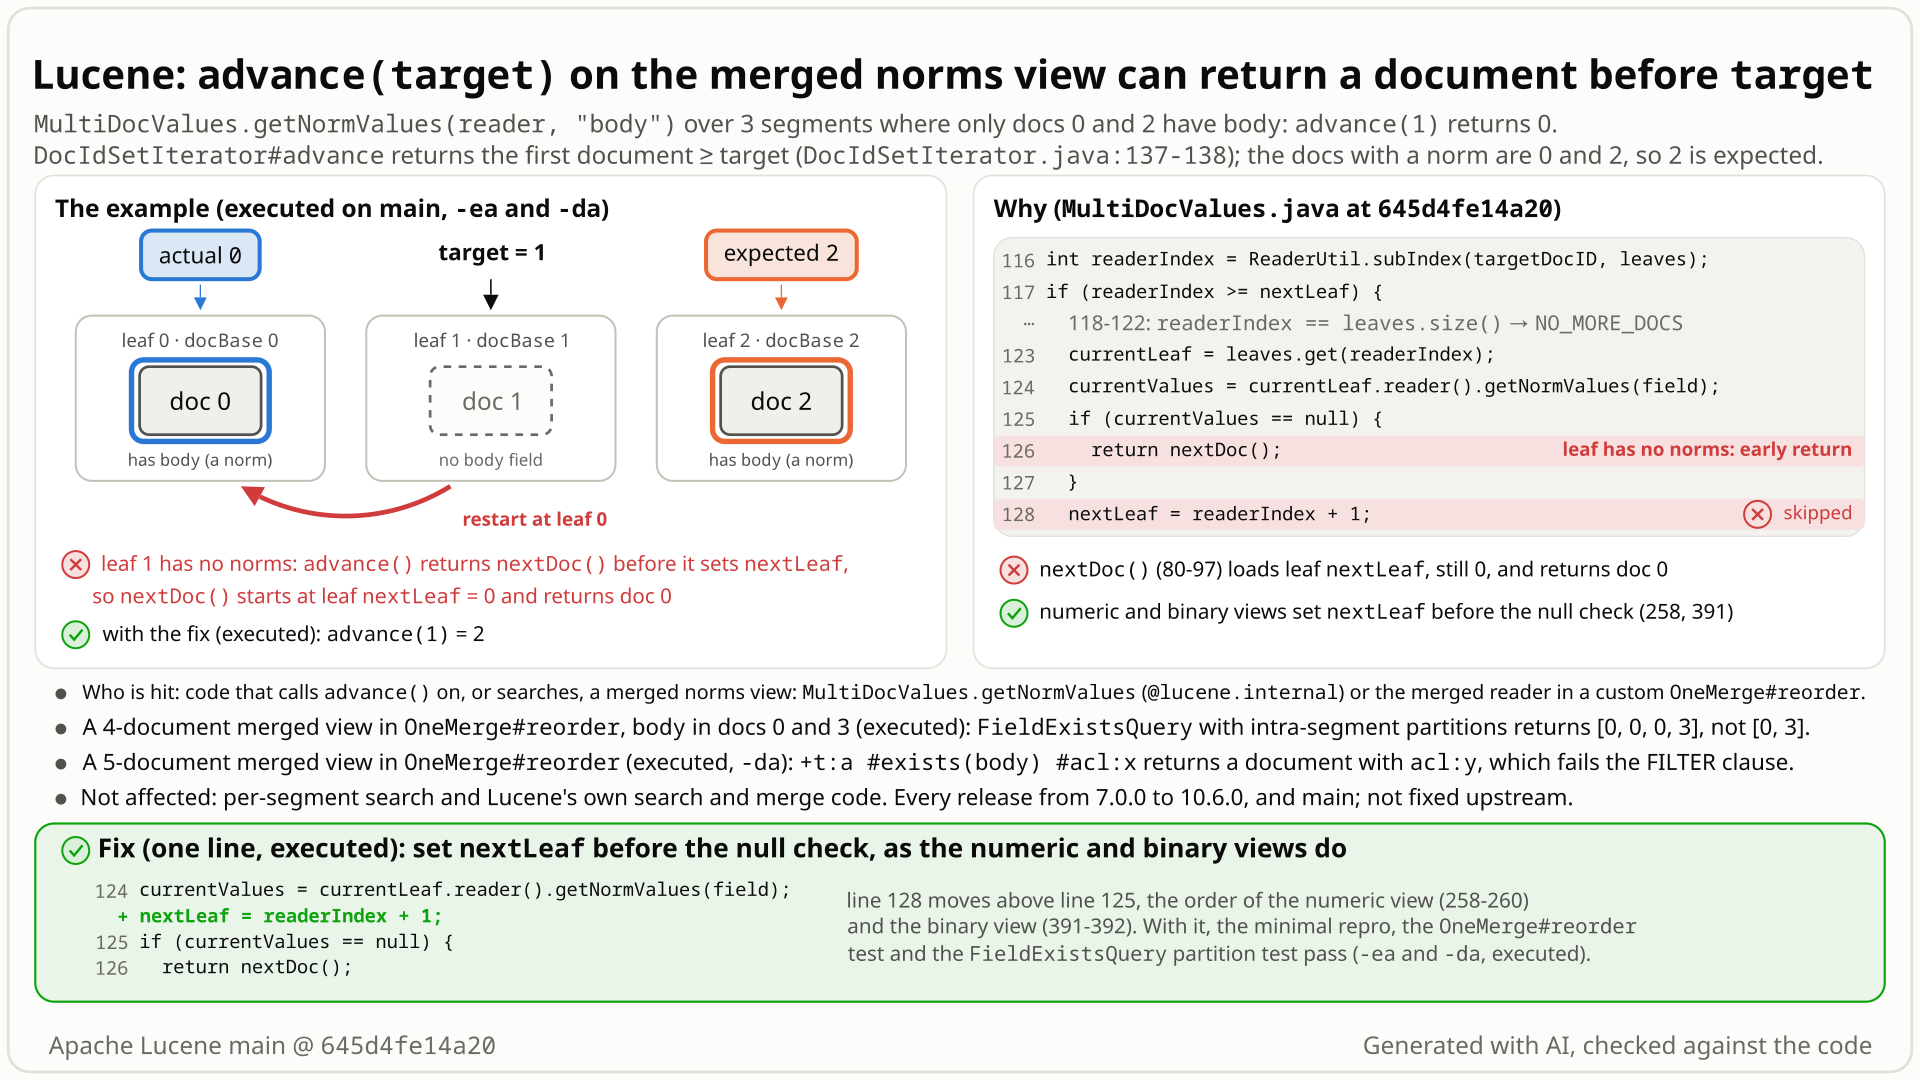
advance(1) should land versus where it lands. Select the still to open it at full size. Generated with AI, checked against the code.- Index three documents, one segment each: doc 0 and doc 2 have the text field
body, doc 1 has no fields. Read the norms of the whole index as one iterator withMultiDocValues.getNormValues(reader, "body"); a customOneMerge#reordergets the same view from the merged reader'sgetNormValues. - Call
advance(1)on the fresh iterator. You expect 2, the first document at or after 1 that has a norm: that is theDocIdSetIterator#advancecontract, and the merged numeric doc-values view returns 2 on the same layout. advance(1)jumps to doc 1's segment, finds no norms there and falls back tonextDoc()before it records that the next segment to read is segment 2. SonextDoc()starts again from segment 0.- You get 0, a document before the target, with no error, with assertions on or off. Searches over the view inherit the step back: on a four-document merged reader in
OneMerge#reorder(docs 0 and 3 havebody),FieldExistsQuery("body")with intra-segment partitions returns [0, 0, 0, 3] instead of [0, 3].
Only code that reads norms through the merged view: direct callers of MultiDocValues.getNormValues (@lucene.internal), custom OneMerge#reorder hooks (@lucene.experimental, 9.9+) that call advance() on norms or search the merged reader, and downstream wrappers built on it. A segment without the field, after one that has it, triggers it. Lucene's own search and merges are unaffected.
Mechanism, terms and numbers862 words
MultiDocValues.getNormValues(reader, field) (@lucene.experimental, @lucene.internal) presents the norms of a multi-segment reader as one NumericDocValues; the same view is the norms of the merged CodecReader that IndexWriter passes to MergePolicy.OneMerge#reorder (@lucene.experimental, since 9.9.0). The view keeps nextLeaf, the segment its nextDoc() reads next. advance(target) jumps to the target's segment, and when that segment has no norms for the field it returns nextDoc() before it sets nextLeaf = readerIndex + 1. nextDoc() then resumes from the stale nextLeaf (segment 0 for a fresh iterator) and, when a segment from there up to the target's holds a document with a norm, returns that document, below the target, against the DocIdSetIterator#advance contract. Three documents in three segments suffice: advance(1) returns 0 instead of 2, with the default codec and with assertions on or off. The numeric and binary views, written in the same 2016 commit, set nextLeaf first, so only the norms view is affected. Lucene's own search works per segment and its merges read these norms with nextDoc() only, so only application code that calls advance() on the view, or searches it, is hit. The fix moves one line, to the order the sibling views use; the test and 11 suites around the view pass with it.
- The view.
getNormValuesreturns the segment's own iterator for a single-segment reader (MultiDocValues.java:53-55) and null when no segment has norms for the field (:57-69); otherwise an anonymous view withnextLeaf= 0,currentValues,currentLeafanddocID= -1 (:71-75). nextDoc()(:77-100): whilecurrentValuesis null it loadsleaves.get(nextLeaf)and incrementsnextLeaf(:80-88); a segment without norms yields null and is skipped.advance(target)(:108-138):
   int readerIndex = ReaderUtil.subIndex(targetDocID, leaves);   // :116
   if (readerIndex >= nextLeaf) {                                 // :117
     ...
     currentLeaf = leaves.get(readerIndex);                       // :123
     currentValues = currentLeaf.reader().getNormValues(field);   // :124
     if (currentValues == null) {
       return nextDoc();                                          // :126, nextLeaf not yet updated
     }
     nextLeaf = readerIndex + 1;                                  // :128
   }
A segment in which no document has the field has no FieldInfo for it, so CodecReader#getNormValues returns null (CodecReader.java:213-217), which LeafReader#getNormValues allows ("or null if no NumericDocValues were indexed", LeafReader.java:202-206). It also returns null when the field's FieldInfo has no norms (not indexed, or norms omitted); within one index IndexWriter's global field numbers keep a field's index options and omitNorms the same in every segment (FieldInfos.java:511-521), so there the trigger is a segment in which no document has the field. Direct MultiDocValues use over an arbitrary composite reader (for example leaves of separately built indexes, or wrapped leaves) has no such guarantee: there a segment's norms can also be null because the field is present but omits norms or is not indexed, and any such segment is a trigger (code reading; not run).
- The siblings. The numeric view sets
nextLeaf = readerIndex + 1;(:258) beforeif (currentValues == null) return nextDoc();(:259-261), the binary view too (:391, then:392-394), and so does the norms view's ownadvanceExact()(:156, then:159). The sorted views substitute empty iterators for segments without the field (:467,:613,:659). - The merged reader.
IndexWriterwraps the segments of a merge (IndexWriter.java:5557-5558) or ofaddIndexes(CodecReader...)(:3561-3562) inSlowCompositeCodecReaderWrapperand passes it toOneMerge#reorder; its norms producer returnsMultiDocValues.getNormValues(...)(SlowCompositeCodecReaderWrapper.java:289-292).
Fresh view, nextLeaf = 0. advance(1): subIndex(1) = 1 (segment 1), and 1 >= 0, so segment 1 is loaded; its getNormValues("body") is null, so the method returns nextDoc() with nextLeaf still 0. nextDoc() loads segment 0, sets nextLeaf = 1 and returns doc 0. Expected 2.
The target's segment has null norms and lies strictly after the stale nextLeaf, and some segment from nextLeaf up to the target's holds a document with a norm; on a fresh iterator (nextLeaf = 0) that means an earlier segment has the field. When the target's segment is nextLeaf itself, or no segment from nextLeaf up to it has a norm, nextDoc() skips ahead and the result is right: [(T)(F)(T)] nextDoc() = 0 then advance(1) = 2; [(F)(F)(T)] fresh advance(1) = 2; [(T)(F)(F)(T)] nextDoc() = 0 then advance(2) = 3 (fact-check probe).
- Target in a last segment without norms: [doc 0: body] [doc 1: none],
advance(1)returns 0 instead ofNO_MORE_DOCS; the same for a target at or pastmaxDoc. - Merged reader inside
OneMerge#reorder, [doc 0: body] [docs 1-2: none] [doc 3: body]:reader.getNormValues("body")givesadvance(1)= 0 andadvance(2)= 0, each on a fresh iterator, expected 3 (main and 10.6.0). - A fresh iterator can also land inside an earlier segment, not only at doc 0: [(F,T)(F)(F,T)] (docs 1 and 4 have the field),
advance(2)returns 1, expected 4. - After earlier calls: [(T)(T)(F)(T)],
nextDoc()= 0 and thenadvance(2)returns 1, expected 3; [(F)(T)(F)],advanceExact(0)and thenadvance(2)returns 1, expectedNO_MORE_DOCS. - Not affected: the numeric, binary and sorted views (0 such mismatches in the bounded-exhaustive check).
Exposure and likelihood336 words
- Who is exposed. Direct callers of
MultiDocValues.getNormValues(its javadoc: "This is a slow way to access normalization values"); customMergePolicy.OneMerge#reorderimplementations that read the merged reader's norms withadvance()or run queries over it; downstream single-leaf wrappers that delegate to it, such as Solr'sSlowCompositeReaderWrapper#getNormValues(apache/solr main9ba1a7d42e4b, lines 323-326; code reading only; no Solr request path that searches it was found; Elasticsearch and OpenSearch not checked). - Trigger. The default codec, no special settings, and an ordinary sparse text field: on a fresh iterator, a target in a segment in which no document has the field, after one that has it (the general condition is under "When exactly" above). Deterministic.
- Effect.
advance()can return a document below the target, silently. Code that searches the view inherits the step back.FieldExistsQueryuses the norms iterator as its own iterator, and with intra-segment partitionsDefaultBulkScoreradvances it to each partition start, so earlier documents are collected again: [0, 0, 0, 3] instead of [0, 3]. The view reportscost()= 0 andConjunctionBulkScorerorders its iterators by cost, so the view can become the lead (it does in the executed witness); a lead that steps back can make a conjunction accept a document on which another required clause was never re-checked (with assertions off; with assertions on, Lucene's conjunction assertions fire). Some query shapes throwArrayIndexOutOfBoundsExceptionorIllegalArgumentExceptionat once. No hang or index corruption was observed. - Not affected. Lucene's own search, which works per segment (the probe's per-segment control was exact in all 3,667 layouts); Lucene's merges, which read the merged view through
SortingCodecReader, which copies norms withnextDoc()only; Luke (advanceExact); the in-tree reorderers, which read no norms (BPReorderingMergePolicy: postings and vectors; the test-onlyMockRandomMergePolicy: the parent-field doc values); the test framework's comparisons (nextDoc()). - Scale. Not a scale issue: three documents suffice. The defect is in the view's segment bookkeeping, which does not depend on segment size (code reading); no size-dependent behaviour was observed in the runs.
The test shows that MultiDocValues.getNormValues(reader, field).advance(target) returns a document before the target when the target's segment has no norms for the field (3 segments: doc 0 has the field, doc 1 does not, doc 2 has it).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestMultiDocValuesNormsAdvance extends LuceneTestCase {

  public void testNormsAdvanceIntoSegmentWithoutNorms() throws Exception {
    IndexWriterConfig iwc =
        new IndexWriterConfig()
            .setCodec(TestUtil.getDefaultCodec())
            .setMergePolicy(NoMergePolicy.INSTANCE);
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      Document withBody = new Document();
      withBody.add(new TextField("body", "text", Field.Store.NO));
      w.addDocument(withBody);
      w.flush();
      w.addDocument(new Document());
      w.flush();
      w.addDocument(withBody);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        NumericDocValues norms = MultiDocValues.getNormValues(reader, "body");
        // expected: advance(1) returns doc 2, the first doc >= 1 with a norm; actual: doc 0
        assertEquals(2, norms.advance(1));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-142/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestMultiDocValuesNormsAdvance
- Expected vs actual
- Expected
advance(1)to return 2, the first document >= 1 with a norm; actual: 0 (expected:<2> but was:<0>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<2> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.junit.Assert.assertEquals(Assert.java:633)
org.apache.lucene.index.TestMultiDocValuesNormsAdvance.testNormsAdvanceIntoSegmentWithoutNorms(TestMultiDocValuesNormsAdvance.java:46)DocIdSetIterator#advancemust return the first document at or after the target; nothing documents an exception for this view, and segments without norms are explicitly allowed.- The numeric and binary views of the same commit set
nextLeafbefore the null check; only the norms view sets it after. - The test framework asserts
docID >= targeton every norms iterator.
The full argument213 words
- Contract. "Advances to the first beyond the current whose document number is greater than or equal to target, and returns the document number itself. Exhausts the iterator and returns NO_MORE_DOCS if target is greater than the highest document number in the set" (
DocIdSetIterator.java:137-139).NumericDocValuesinherits it. - Legal trigger. A fresh iterator,
target>docID()and <maxDoc, the default codec, otherwise default settings exceptNoMergePolicy(which only keeps the segments apart), and a segment without the field, whichLeafReader#getNormValuesallows ("or null"). - Test framework.
AssertingLeafReader#getNormValueswraps every norms iterator inAssertingNumericDocValues(AssertingLeafReader.java:1838-1845), whoseadvance()assertsdocID >= target(:790-797). The repro's reader is not wrapped, so the test sees the raw value. - History. In the introducing commit (LUCENE-7407) the numeric and binary views put
nextLeaf = readerIndex+1;before the null check and the norms view after it; nothing in that issue's discussion (42 comments in the JIRA record, 41 in the migrated GitHub issue #8460), the javadoc,CHANGES.txt,MIGRATE.mdor later commits calls the order a choice. - Why tests missed it.
TestMultiDocValueschecksadvance()on the numeric, binary and sorted views only; no upstream test callsadvance()onMultiDocValues.getNormValues. - Precedent. LUCENE-7529 (#8580, 2016) fixed another iterator-contract violation in these views (the
advanceExactargument check).
The devil's-advocate check161 words
Strongest case (the refute-lens reviewer, the intended-behaviour checker and the credibility audit): MultiDocValues is @lucene.internal and @lucene.experimental and calls itself "very costly"; the merged wrapper says "This view is primarily targeted at merging, not searching"; no Lucene search or merge path calls advance() on it. So this is an internal view used outside its purpose.
Why it fails: the build defines @lucene.internal as "This API is for internal purposes only and might change in incompatible ways in the next release", an API-stability note, not a licence to break DocIdSetIterator; the merged reader is a public CodecReader handed to user code by a public hook whose javadoc puts no limit on how it is read, and advance() on norms is a plain reader operation, not a search; the sibling views show the intended order; and the fix moves one line. What the argument does establish, and strongly, is narrow reach, which is why the bug is rated minor and low priority.
Recommended Set nextLeaf before the early return
Move nextLeaf = readerIndex + 1; above the if (currentValues == null) return nextDoc(); early return in the norms view's advance(), the order the numeric and binary views already use. The test and 11 suites around the view (97 tests) pass with assertions on and off, and check -x test passes.
           currentLeaf = leaves.get(readerIndex);
           currentValues = currentLeaf.reader().getNormValues(field);
+          nextLeaf = readerIndex + 1;
           if (currentValues == null) {
             return nextDoc();
           }
-          nextLeaf = readerIndex + 1;
         }
All options and trade-offs3 options · 492 words
One fix was built and run in a scratch worktree of 645d4fe14a20. Two broader options are listed: fixing the sibling LFV-136 in the same change, and replacing the null per-segment iterators.
In MultiDocValues.getNormValues(...)'s advance(), record that the segment just loaded is consumed before falling back to nextDoc() (one line moved, MultiDocValues.java:128 to above :125). The finder and an independent verifier wrote the same change.
           currentLeaf = leaves.get(readerIndex);
           currentValues = currentLeaf.reader().getNormValues(field);
+          nextLeaf = readerIndex + 1;
           if (currentValues == null) {
             return nextDoc();
           }
-          nextLeaf = readerIndex + 1;
         }
Trade-offs
- The order of the numeric and binary views and of the norms view's own
advanceExact(); the segment just loaded is consumed, sonextDoc()must continue with the next one. - No material cost expected (a line moved); no benchmark was run.
- Does not fix the sibling LFV-136 (a
NullPointerExceptionfromadvance()afteradvanceExact()).
What the checks validated
- Stock + test: fails through gradle with assertions on and off (
expected:<2> but was:<0>); + fix: passes. - + fix: 11 suites (the test,
TestMultiDocValues, the sevenlucene/coretest classes that callMultiDocValues.getNormValues,TestSortingCodecReader,TestAddIndexes): 97 tests, 0 failures, 0 skipped, with assertions on and off, in two separate gradle runs (the second on 2026-10-30, which also showed the test failing again once the fix was removed);:lucene:core:check -x testpasses. - In the hunt: with this fix the bounded-exhaustive check loses exactly the two norms advance-return buckets, and the verifiers', the cross-model reviewers' and the probe's tests pass.
- Not run: the full Lucene test suite, the nightly tests, any benchmark, and the other direct callers:
lucene/memory'sTestMemoryIndexAgainstDirectory, the norms-format tests built onBaseNormsFormatTestCaseand the test framework's own comparisons (LuceneTestCaseParent), which read the view withnextDoc()only, and Luke'sDocumentField, which usesadvanceExact()on a fresh view.
In the numeric, binary and norms views, add an else if (currentValues == null) return nextDoc(); branch to the if (readerIndex >= nextLeaf) block, for a target in the segment that advanceExact() left without values (+3 lines per view).
Trade-offs
Fixes both iterator bugs of these views in one PR. Each fix alone removes only its own mismatches; with both, the bounded-exhaustive check finds none.
What the checks validated
- Bounded-exhaustive check with both changes in all three views: no mismatches at sequence length up to 3 on 1-3 segments and up to 4 on 2 segments.
- Not run through gradle here; LFV-136 has its own repro.
As the sorted views do, use an empty per-segment iterator instead of null.
Trade-offs
Would remove the null branch that both this bug and LFV-136 depend on, but touches nextDoc(), advance() and advanceExact() of three views. Not built or run.
Code that searches the merged view, such as a custom OneMerge#reorder or a downstream single-leaf wrapper, can see a FieldExistsQuery conjunction return a document that fails another required clause (with assertions off), which matters only where that clause serves as an access filter.
A code-reading hypothesis (the norms view orders its bookkeeping differently from the numeric view), checked by a bounded-exhaustive harness: every short sequence of nextDoc, advance and advanceExact calls on tiny 1-3 segment indexes, compared with the per-segment iterators. Only the norms view's advance() returned a document below the target; a JUnit followed.
The method in full115 words
Method: semi-formal (a code-reading hypothesis witnessed by bounded-exhaustive translation validation), a hunt unit (callers of ReaderUtil.subIndex), 2026-10-26. The harness compares every MultiDocValues view with the concatenation of the per-segment iterators over every legal nextDoc/advance/advanceExact sequence: length up to 3 on 1-3 segments (258 index layouts, 423,972 sequences) and length up to 4 on up to 2 segments (64,740 sequences), on the stock jar with -ea and -da. Norms advance-return mismatches: 732 (pure) and 504 (mixed) at length 3; minimal witness segments [(1)(0)], advance(1) returns 0 instead of NO_MORE_DOCS. The numeric, binary and sorted views had no advance-return mismatch. The same harness found the sibling LFV-136 (a NullPointerException bucket).
No prior report found in the recorded searches (GitHub issues, PRs and commits of Lucene, Elasticsearch, OpenSearch and Solr; the Lucene mailing lists; the JIRA archive; the web), run 2026-10-26 and refreshed 2026-10-30; novelty new. Closest: LUCENE-7529 (#8580), a different contract fix in the same views (2016). Open PRs #14475 and #16847 keep the defect.
Searches6 searches
Context, not reports: #9565 / LUCENE-8519 (#902, #898; the only upstream item about this method, a speed change to its preamble, 9.3.0); #8460 / LUCENE-7407 (introducing); #12622 (added the merged wrapper and OneMerge#reorder); #12859 (a similar "segment lacks the field" fix for points in the same wrapper); #11038 / LUCENE-9999 and #10794 / LUCENE-9755 (the same trigger shape in other classes). Open PR #14475 copies the norms advance() body verbatim and #16847 edits lines in it; both keep the defect; #13948 changes only the binary view. Novelty follows the hunt's rule: only a public GitHub issue or PR, including the migrated JIRA archive, would make it known. Search limits: keyword search only; GitHub search does not index PR diffs (open PRs were checked by changed files) or old JIRA attachments; part of the refresh hit the shared search rate limit.
| Where | When | How | Found |
|---|---|---|---|
| GitHub (apache/lucene issues, PRs, commits; Elasticsearch, OpenSearch, Solr) | 2026-10-26 | a scripted prior-report search in three term sets (identifiers; symptom and public path; assertion and stack-trace phrasing; 56 + 56 + 32 queries) and 48 manual GitHub searches; full discussions of #898, #902, #12622, #12859, #13128 and #14092 | no report; only related items (above) |
| Open apache/lucene PRs and commit history | 2026-10-26 | changed files of all 413 open PRs (the MultiDocValues.java diffs of #13948, #14475 and #16847 read); git blame and log of the block | no fix; #14475 and #16847 keep the defect |
| Mailing lists, JIRA archive, web | 2026-10-26 | dev@, java-user@, issues@, commits@; LUCENE-7407, -7462, -7495, -7529 and -8519 read in full; 11 web queries | no report |
| Refresh | 2026-10-30 | upstream heads and the file's commits on main, branch_10_6 and branch_10x; 14 searches with nine distinct queries (five as issue and as PR searches, four over issues and PRs: class names, getNormValues advance, nextLeaf, the merged view and reorder, anything since 2026-10-20); two more hit the rate limit | no new item; MultiDocValues.java unchanged since 2023 on main and branch_10_6 |
| Second refresh | 2026-10-30 | upstream main head and the file's newest commit on main and branch_10_6; state of #14475, #16847 and #13948; GitHub searches for MultiDocValues updated since 2026-10-20, getNormValues advance, nextLeaf | no new item: 0, 1 (#9802, unrelated) and 0 hits; the three PRs still open; branch_10x decommissioned on 2026-10-29 (#16911) |
| Third refresh | 2026-10-30 | upstream main head and the file's newest commit on main and branch_10_6; state of #14475 and #16847; GitHub searches for getNormValues advance and MultiDocValues updated since 2026-10-30 (a nextLeaf search hit the rate limit) | no new item: 1 hit (the same count as earlier, when the hit was #9802, unrelated; not re-fetched) and 0 hits; both PRs still open; MultiDocValues.java unchanged since 2023 |
Introduced by LUCENE-7407 (f7aa200d406, 2016-09-21), the switch of doc values to iterators; unchanged since except a reformat. Fails on every release tested from 7.0.0 to 10.6.0 and on main; 6.x has no iterator API.
Versions tested7 rows
f7aa200d406 "LUCENE-7407: switch doc values usage to an iterator API" (Mike McCandless, 2016-09-21; JIRA LUCENE-7407, migrated as #8460; patch workflow, no GitHub PR) wrote the iterator-based views; the norms view's advance() had the defective order from the start. The only later edit to the block is the whitespace-only reformat 2d6ad2fee6d (LUCENE-9570). The public OneMerge#reorder path exists from 9.9.0 (#12622; a two-argument hook in 9.9-9.11, not run). MultiDocValues.java is identical in 10.6.0 (4ae946e5a9b) and 645d4fe14a20. 8.8.2-8.11.3 are not tagged in the history clone and are inferred affected.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the test fails, assertions on and off (gradle and standalone) |
upstream main 2f424fd428da, branch_10_6 head | read | same code; MultiDocValues.java last changed in 2023 (formatting), read 2026-10-30 |
10.6.0 (4ae946e5a9b) | affected | the test fails (release jars, assertions off); the merged-reader test fails too |
| 10.5.2 | affected | the test fails; the earlier 4-document test fails with -ea and -da |
| 10.0.0, 9.12.3, 9.3.0, 9.0.0, 8.11.4, 8.0.0, 7.7.3, 7.0.0 | affected | the hunt's 4-document test fails (advance(1) = 0 instead of 3) |
| 6.6.6, 6.2.1 | API absent | the test does not compile: doc values had no iterator API |
with the fix (main 645d4fe14a20) | not affected | the test and 11 suites pass |
The finder, verifiers, cross-model reviews (OpenAI GPT-5.6, with code execution) and an adjudication looked at it; all rate it real except one review that objected to scope only. A credibility audit downgraded it to minor. This doc's runs reproduced it and validated the fix.
Checks and verdicts449 words
Every hunt check re-ran a repro on stock jars. The hunt's checks ran on main ea57360912ed, whose MultiDocValues.java is identical to 645d4fe14a20's; the main refresh to a9779ef3c193 and this doc's runs on 645d4fe14a20 gave the same failures.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | Bounded-exhaustive check: norms advance-return mismatches only; JUnit fails on main with -ea and -da, on the public reorder path and on releases back to 7.0.0; the fix passes. |
| cross-model review, refute lens (OpenAI GPT-5.6) | not real, high, on scope only | Reproduced it and agreed on the root cause and the fix; objected only that MultiDocValues is @lucene.internal, before the public-path repro existed. |
| cross-model review, intended lens (OpenAI GPT-5.6) | real, high | Own direct and OneMerge#reorder tests fail; the fix passes; the intended-behaviour argument is weak. |
| Independent reproducer | real | Own tests from the claim only fail 4 of 6 on main (-ea, -da), 10.5.2 and 9.12.3; controls pass; its own identical fix passes. |
| Cross-model review, root-cause lens (OpenAI GPT-5.6) | real, high | A trace shows nextLeaf still 0 when nextDoc loads segment 0; 54 existing tests pass with the fix; separated out LFV-136. |
| Devil's advocate | real | No intended-behaviour argument survives; added the FieldExistsQuery partition test ([0, 0, 0, 3] instead of [0, 3]). |
| adjudication | confirmed, high | Re-ran the independent reproduction's direct and reorder tests and the intended-behaviour check's search test: all fail; the independent reproduction's direct test passes with the fix. |
| credibility audit | downgraded to minor (score 20) | Reproduced on main; "a real one-line contract fix"; advised leading with the contract violation and keeping the search effects as an illustration. |
| this doc's runs | reproduced, fix validated | Gradle on 645d4fe14a20 (assertions on and off), the standalone runner, 10.6.0 and 10.5.2 release jars; the fix with 11 suites and check -x test, the 11 suites re-run once more on 2026-10-30. |
| independent fact checks of the doc (two rounds) | real; no factual errors left | Round 1: a Claude check in its own worktree re-ran the test, the fix, the 11 suites and the variants on 645d4fe14a20 and 10.6.0, and a read-only OpenAI GPT-5.6 check compared the text with the code and the saved runs; their corrections went into the revision. Round 2 on that revision: the Claude check re-ran the gradle test (assertions on and off), the fix with the 11 suites (97 tests, 0 failures), the standalone runs and its own probe of every variant, and found no factual errors; the read-only GPT-5.6 check found none either and listed 3 overclaims and 3 missing caveats. Their wording points are applied in this version. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 522 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,753 words
- Registry title
- MultiDocValues norms view (also the merged reader passed to MergePolicy.OneMerge#reorder): advance(target) returns a document before target when target's segment has no norms for the field, so queries over that view can return duplicate or non-matching hits
- Area
- index / MultiDocValues merged norms view (also the merged reader passed to MergePolicy.OneMerge#reorder)
- Priority
- Low, rank 595: Advance() on the MultiDocValues norms view steps backwards, so queries over it return duplicate or non-matching hits (even a FILTER bypass), but only custom code on the internal view or a custom OneMerge#reorder reaches it, and Lucene's own search and merge paths never do.
- Impact class
- minor
- Impact note
- Only application code that calls advance() on, or runs queries over, a merged norms view is hit: MultiDocValues.getNormValues itself (a class tagged @lucene.experimental and @lucene.internal), the merged CodecReader that IndexWriter passes to a custom MergePolicy.OneMerge#reorder (@lucene.experimental, since 9.9.0), or a downstream single-leaf wrapper that delegates to it (Solr's SlowCompositeReaderWrapper, code reading only); with the default codec and config, -ea or -da, and ordinary data (a segment in which no document has the text field, after a segment that has it), advance() returns a document below the target, and stock queries over that view return duplicate hits with intra-segment partitions or, with assertions disabled, documents that fail another required clause such as a FILTER restriction; Lucene's own search and merge paths never use the view this way (per-segment search is exact, SortingCodecReader reads the merged norms with nextDoc only, no in-tree reorderer reads norms); released 7.0.0 through 10.6.0.
- Summary
- You read the norms of a multi-segment index as one merged iterator (MultiDocValues.getNormValues(reader, "body"), or LeafReader#getNormValues on the merged reader that IndexWriter hands to a custom OneMerge#reorder), where doc 0's segment has the text field "body", docs 1-2 sit in a segment without it and doc 3's segment has it again, and call advance(1) on a fresh iterator. You expect 3, the first document at or after the target that has a norm, as the DocIdSetIterator#advance contract says and as the merged numeric doc-values view of the same index returns. Instead advance(1) returns 0, a document before the target, because advance() falls back to nextDoc() before it records which segment comes next, so nextDoc() restarts from the first segment; queries over that view inherit the backward step (FieldExistsQuery with intra-segment partitions returns [0, 0, 0, 3] instead of [0, 3], and a conjunction can return a document that fails one of its FILTER clauses).
- Introduced
- f7aa200d406 (f7aa200d406dbd05a35d6116198302d90b92cb29) 'LUCENE-7407: switch doc values usage to an iterator API, based on DocIdSetIterator, instead of random acces, freeing codecs for future improvements' by mikemccand (JIRA LUCENE-7407, migrated as apache/lucene#8460; JIRA patch workflow, no GitHub PR): in the norms view's new advance() the assignment 'nextLeaf = readerIndex+1' comes after the early 'if (currentValues == null) return nextDoc();', while the numeric and binary views written in the same commit assign it before the null check; not a regression [read: git blame and git log -L on the norms advance() block list only f7aa200d406 and the whitespace-only reformat 2d6ad2fee6d (LUCENE-9570); exec: release-level bracketing only (6.2.1 and 6.6.6 have no iterator API, 7.0.0 fails); the introducing commit and its parent were not built] (2016-09-21)
- First affected version
- 7.0.0 [exec: fails 3 run / 2 failed; 6.2.1 and 6.6.6 do not compile the repro because doc values had no iterator API, only get(int)]; public OneMerge#reorder path from 9.9.0 [read: javap shows the two-argument hook in 9.9.0-9.11.x and the three-argument one from 9.12.0; exec from 9.12.3]
- Affected versions
- every release 7.0.0 through 10.6.0 (7.x, 8.x, 9.x, 10.x; the 10.6.0 release jars fail with -da [exec]) and main ea57360912ed; never fixed. Direct test executed failing: 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.3.0, 9.12.3 (-ea and -da), 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da) [exec, finder and the version-history runs]; independently re-run by the independent reproduction on main (-ea and -da), 10.5.2 and 9.12.3 [exec]; 8.8.2-8.11.3 are not tagged in the history clone and are inferred affected between 8.8.1 (contains the commit) and 8.11.4 (fails) [read]; other releases by unchanged code (git tag --contains lists all 65 release tags 7.0.0-10.5.2) [read]. Public OneMerge#reorder path: 9.12.3, 10.5.2 and main (-ea and -da) fail [exec]; 9.9.0-9.11.x (two-argument hook) not executed [read]; absent before 9.9.0. Search-level effects: FieldExistsQuery duplicates with intra-segment partitions on main (-ea and -da) and 10.5.2 [exec, the intended-behaviour check]; FILTER-restriction bypass on main and 10.5.2 with -da [exec, security probe]. Not affected: 6.x and older (no doc-values iterator API) [exec: compile error]. Upstream main and branch_10x still have the code (MultiDocValues.java last changed 2023-10-11, formatting only) [read, 2026-10-26]; open PRs #14475 and #16847 keep the ordering [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, read-only: the finder's scripted prior-report search (16 GitHub issue/PR, 2 commit, 3 JIRA-archive and 2 list queries, 251 hits, none the same bug); the follow-up step: a scripted prior-report search in three term sets (identifiers; symptom and public path; assertion and stack-trace phrasing; 56 + 56 + 32 queries over apache/lucene issues and PRs, commits, the Elasticsearch, OpenSearch and Solr repos, dev@, java-user@, issues@ and commits@, the JIRA archive, and 11 web queries) plus two lists+JIRA pre-runs, 48 manual GitHub GraphQL searches, the changed-file lists of all 413 open apache/lucene PRs (the MultiDocValues.java diffs of #13948, #14475 and #16847 read), full reads of LUCENE-7407, -7462, -7495, -7529 and -8519 and of the discussions of #898, #902, #12622, #12859, #13128 and #14092, and git history; the independent reproduction's and the intended-behaviour check's own gh searches): no issue, PR, JIRA ticket, list post or downstream report describes this bug and nothing fixes it. Related, not this bug: #9565 / LUCENE-8519 with PRs #902 and #898 (the only upstream item about MultiDocValues.getNormValues, a speed change in its preamble, fixed in 9.3.0), #8580 / LUCENE-7529 (a different iterator-contract bug in the advanceExact argument check of the same views, fixed in 2016; the precedent), #8460 / LUCENE-7407 (introducing), #8514 / LUCENE-7462, #8546 / LUCENE-7495, #12622 (added SlowCompositeCodecReaderWrapper and OneMerge#reorder), #12859 (a similar 'segment lacks the field' fix for points in the same wrapper), #13128, #14092, #11038 / LUCENE-9999 and #10794 / LUCENE-9755 (same trigger shape in other classes), #7232, #6873, #7127, #13798 (other MultiDocValues failures), elastic/elasticsearch#27131 (a per-segment norms failure). Open PRs #14475 (refactor, copies the norms advance() body verbatim) and #16847 (int casts in the same block) keep the defect; #13948 changes only the binary view. Limits: GitHub full-text search tokenizes code loosely and does not search attachments or old JIRA patch files; scripted prior-report search C was capped at 6 GitHub queries by GitHub's search rate limit; private security reports cannot be searched
- Lucene commit tested
- main
645d4fe14a20(11.0.0-SNAPSHOT, commit of 2026-10-28): the repro test through gradle in a scratch worktree (assertions on and off), stock and with the fix, plus 11 suites with the fix (assertions on and off) and:lucene:core:check -x test; the standalone runner with-ea,-daand the fix shadowed. Release jars 10.6.0 (4ae946e5a9b) and 10.5.2 with the same test; the hunt's merged-reader (OneMerge#reorder) test on645d4fe14a20and 10.6.0 and itsFieldExistsQuerypartition test on645d4fe14a20(on 10.6.0 too in the fact check's probe). The fix and the 11 suites were run again through gradle on 2026-10-30 (assertions on and off), and the test failed again with the fix removed. Two rounds of independent fact checks: in each, one check re-ran the test, the fix and the variants in its own worktree on645d4fe14a20and 10.6.0, and a second, read-only one checked the text against the code and the saved run records. Earlier, on mainea57360912ed: the finder, the verifiers, the adjudication and the follow-up (releases 7.0.0 to 10.5.2). Upstream main (716d6f216f52,208608f75307, then2f424fd428da) and branch_10_6 were read on 2026-10-30:MultiDocValues.javalast changed in 2023 (formatting). Only the default codec, Linux aarch64 and OpenJDK 25.0.3 were run.
- Finding record
lucene/core/src/java/org/apache/lucene/index/MultiDocValues.java:24-35 (class javadoc: very costly, @lucene.experimental, @lucene.internal), :77-100 (norms nextDoc resumes from nextLeaf), :108-137 (norms advance; the early 'return nextDoc()' at :125-127 precedes 'nextLeaf = readerIndex + 1' at :128), :171-174 (cost() returns 0, TODO), :256-261 (numeric advance assigns nextLeaf before the null check)lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:136-139 (advance: first document >= target; NO_MORE_DOCS beyond the last)lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:289-291 (getNorms returns MultiDocValues.getNormValues)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3561-3562 (addIndexes(CodecReader...) passes the merged view to reorder) and :5557-5558 (merges)lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:311-325 (OneMerge#reorder, @lucene.experimental, receives the merged view)lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:179-180 (the norms iterator is the query's iterator) and search/Weight.java:265-270 (DefaultBulkScorer advances to each partition start)lucene/test-framework/src/java/org/apache/lucene/tests/index/AssertingLeafReader.java:791-797 (AssertingNumericDocValues.advance asserts docID >= target) and :1839-1845 (norms are wrapped in it)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/MultiDocValues.java:24-35, :41-176 (norms view: :53-55, :57-69, :71-75, :77-100, :108-138, :140-163), :241-271 (numeric advance, :256-261), :389-394 (binary), :467, :613, :659 (sorted: empty iterators)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/CodecReader.java:211-220; index/LeafReader.java:202-206a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:43-58, :289-292; index/IndexWriter.java:3561-3562, :5557-5558a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:511-521 (global field schema: index options and omitNorms)
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/MultiDocValues.java:31-34, :44-45 (very costly, @lucene.experimental, @lucene.internal; 'slow way'), :171-174 (cost() = 0)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:311-328 (OneMerge#reorder, @lucene.experimental)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:179-180; search/Weight.java:265-270a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:5575-5576; index/SortingCodecReader.java:686-690, :793-804a Lucene main checkout (645d4fe14a20) lucene/luke/src/java/org/apache/lucene/luke/models/documents/DocumentField.java:81-82; lucene/test-framework/src/java/org/apache/lucene/tests/util/LuceneTestCaseParent.java:771-774, :993-1007a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/ConjunctionBulkScorer.java:54 (iterators sorted by cost); lucene/test-framework/src/java/org/apache/lucene/tests/index/MockRandomMergePolicy.java:240-273
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:136-142a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/LeafReader.java:202-206a Lucene main checkout (645d4fe14a20) lucene/test-framework/src/java/org/apache/lucene/tests/index/AssertingLeafReader.java:790-797, :1838-1845a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:43-46; build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:506https://github.com/apache/lucene/issues/8580 (LUCENE-7529)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/MultiDocValues.java:467, :613, :659 (sorted views: empty iterators)
- History
a Lucene clone: git diff --stat 4ae946e5a9b 645d4fe14a20 -- lucene/core/src/java/org/apache/lucene/index/MultiDocValues.java (empty)
- TestMultiDocValuesNormsAdvance.java (JUnit test):
repro/LFV-142/src/org/apache/lucene/index/TestMultiDocValuesNormsAdvance.java(50 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and runs executed for the diagram; the diagram folder's README lists the source of every on-screen fact.
assets/LFV-142/bug.png(522 KB)